pods
In Sheffield we created a suite of software tools for ‘Open Data Science.’ Open data science is an approach to sharing code, models and data that should make it easier for companies, health professionals and scientists to gain access to data science techniques.
You can also check this blog post on Open Data Science.
The software can be installed using
import importlib.utilcmd = install_command('pods')%system {cmd}from the command prompt where you can access your python installation.
The code is also available on GitHub: https://github.com/lawrennd/ods
Once pods is installed, it can be imported in the usual manner.
import podsnotutils
This small package is a helper package for various notebook utilities used below.
The software can be installed using
cmd = install_command('notutils')%system {cmd}from the command prompt where you can access your python installation.
The code is also available on GitHub: https://github.com/lawrennd/notutils
Once notutils is installed, it can be imported in the usual manner.
import notutilsmlai
The mlai software is a suite of helper functions for teaching and demonstrating machine learning algorithms. It was first used in the Machine Learning and Adaptive Intelligence course in Sheffield in 2013.
The software can be installed using
cmd = install_command('mlai')%system {cmd}from the command prompt where you can access your python installation.
The code is also available on GitHub: https://github.com/lawrennd/mlai
Once mlai is installed, it can be imported in the usual manner.
import mlai
+from mlai import plot
Quadratic Loss and Linear System
We will consider a simplified system, to remind us of some of the linear algebra involved, and introduce some of the fundamental issues.
Expected Loss
Our objective function so far has been the negative log likelihood, which we have minimized (via the sum of squares error) to obtain our model. However, there is an alternative perspective on an objective function, that of a loss function. A loss function is a cost function associated with the penalty you might need to pay for a particular incorrect decision. One approach to machine learning involves specifying a loss function and considering how much a particular model is likely to cost us across its lifetime. We can represent this with an expectation. If our loss function is given as \(L(y, x, \mathbf{ w})\) for a particular model that predicts \(y\) given \(x\) and \(\mathbf{ w}\) then we are interested in minimizing the expected loss under the likely distribution of \(y\) and \(x\). To understand this formally we define the true distribution of the data samples, \(y\), \(x\). This is a particular distribution that we don’t typically have access to. To represent it we define a variant of the letter ‘P,’ \(\mathbb{P}(y, x)\). If we genuinely pay \(L(y, x, \mathbf{ w})\) for every mistake we make, and the future test data is genuinely drawn from \(\mathbb{P}(y, x)\) then we can define our expected loss, or risk, to be, \[ R(\mathbf{ w}) = \int L(y, x, \mathbf{ w}) \mathbb{P}(y, x) \text{d}y \text{d}x. -\] Of course, in practice, this value can’t be computed but it serves as a reminder of what it is we are aiming to minimise and under certain circumstances it can be approximated.
-Here we have used \(L(\cdot)\) as our notation for the loss function. The cost we expect to pay for making errors. This is a different interpretation of the objective function, \(E(\cdot)\), fromt he idea of negative log likelihood we see in Gauss’s probabilistic approach.
-Sample-Based Approximations
-A sample-based approximation to an expectation involves replacing the true expectation with a sum over samples from the distribution. \[ +\] Of course, in practice, this value can’t be computed but it serves as a reminder of what it is we are aiming to minimise and under certain circumstances it can be approximated.
Here we have used \(L(\cdot)\) as our notation for the loss function. The cost we expect to pay for making errors. This is a different interpretation of the objective function, \(E(\cdot)\), fromt he idea of negative log likelihood we see in Gauss’s probabilistic approach.
Sample-Based Approximations
A sample-based approximation to an expectation involves replacing the true expectation with a sum over samples from the distribution. \[ \int f(z) p(z) \text{d}z\approx \frac{1}{s}\sum_{i=1}^s f(z_i). -\] if \(\{z_i\}_{i=1}^s\) are a set of \(s\) independent and identically distributed samples from the distribution \(p(z)\). This approximation becomes better for larger \(s\), although the rate of convergence to the true integral will be very dependent on the distribution \(p(z)\) and the function \(f(z)\).
-That said, this means we can approximate our true integral with the sum, \[ +\] if \(\{z_i\}_{i=1}^s\) are a set of \(s\) independent and identically distributed samples from the distribution \(p(z)\). This approximation becomes better for larger \(s\), although the rate of convergence to the true integral will be very dependent on the distribution \(p(z)\) and the function \(f(z)\).
That said, this means we can approximate our true integral with the sum, \[ R(\mathbf{ w}) \approx \frac{1}{n}\sum_{i=1}^{n} L(y_i, x_i, \mathbf{ w}). -\]
-Laplace’s Idea
- -Laplace had the idea to augment the observations by noise, that is equivalent to considering a probability density whose mean is given by the prediction function \[p\left(y_i|x_i\right)=\frac{1}{\sqrt{2\pi\sigma^2}}\exp\left(-\frac{\left(y_i-f\left(x_i\right)\right)^{2}}{2\sigma^2}\right).\]
-This is known as stochastic process. It is a function that is corrupted by noise. Laplace didn’t suggest the Gaussian density for that purpose, that was an innovation from Carl Friederich Gauss, which is what gives the Gaussian density its name.
-Height as a Function of Weight
-In the standard Gaussian, parameterized by mean and variance, make the mean a linear function of an input.
-This leads to a regression model. \[ +\]
Laplace’s Idea
Laplace had the idea to augment the observations by noise, that is equivalent to considering a probability density whose mean is given by the prediction function \[p\left(y_i|x_i\right)=\frac{1}{\sqrt{2\pi\sigma^2}}\exp\left(-\frac{\left(y_i-f\left(x_i\right)\right)^{2}}{2\sigma^2}\right).\]
This is known as stochastic process. It is a function that is corrupted by noise. Laplace didn’t suggest the Gaussian density for that purpose, that was an innovation from Carl Friederich Gauss, which is what gives the Gaussian density its name.
Height as a Function of Weight
In the standard Gaussian, parameterized by mean and variance, make the mean a linear function of an input.
This leads to a regression model. \[ \begin{align*} y_i=&f\left(x_i\right)+\epsilon_i,\\ \epsilon_i \sim & \mathscr{N}\left(0,\sigma^2\right). \end{align*} -\]
-Assume \(y_i\) is height and \(x_i\) is weight.
-Olympic Marathon Data
- --
-
- Gold medal times for Olympic Marathon since 1896. -
- Marathons before 1924 didn’t have a standardized distance. -
- Present results using pace per km. -
- In 1904 Marathon was badly organized leading to very slow times. -
 -
Image from Wikimedia Commons
-The Olympic Marathon data is a standard dataset for regression modelling. The data consists of the pace of Olympic Gold Medal Marathon winners for the Olympics from 1896 to present. Let’s load in the data and plot.
-cmd = install_command('pods')%system {cmd}import numpy as np
-import podsdata = pods.datasets.olympic_marathon_men()
-x = data['X']
-y = data['Y']
-
-offset = y.mean()
-scale = np.sqrt(y.var())
-yhat = (y - offset)/scale -
Figure: Olympic marathon pace times since 1896.
-Things to notice about the data include the outlier in 1904, in that year the Olympics was in St Louis, USA. Organizational problems and challenges with dust kicked up by the cars following the race meant that participants got lost, and only very few participants completed. More recent years see more consistently quick marathons.
-Running Example: Olympic Marathons
- -Note that x and y are not pandas data frames for this example, they are just arrays of dimensionality \(n\times 1\), where \(n\) is the number of data.
The aim of this lab is to have you coding linear regression in python. We will do it in two ways, once using iterative updates (coordinate ascent) and then using linear algebra. The linear algebra approach will not only work much better, it is also easy to extend to multiple input linear regression and non-linear regression using basis functions.
-Maximum Likelihood: Iterative Solution
-Now we will take the maximum likelihood approach we derived in the lecture to fit a line, \(y_i=mx_i + c\), to the data you’ve plotted. We are trying to minimize the error function, \[ +\]
Assume \(y_i\) is height and \(x_i\) is weight.
Olympic Marathon Data
- Gold medal times for Olympic Marathon since 1896.
- Marathons before 1924 didn’t have a standardized distance.
- Present results using pace per km.
- In 1904 Marathon was badly organized leading to very slow times.
Image from Wikimedia Commons
The Olympic Marathon data is a standard dataset for regression modelling. The data consists of the pace of Olympic Gold Medal Marathon winners for the Olympics from 1896 to present. Let’s load in the data and plot.
cmd = install_command('pods')%system {cmd}import numpy as np
+import podsdata = pods.datasets.olympic_marathon_men()
+x = data['X']
+y = data['Y']
+
+offset = y.mean()
+scale = np.sqrt(y.var())
+yhat = (y - offset)/scaleFigure: Olympic marathon pace times since 1896.
Things to notice about the data include the outlier in 1904, in that year the Olympics was in St Louis, USA. Organizational problems and challenges with dust kicked up by the cars following the race meant that participants got lost, and only very few participants completed. More recent years see more consistently quick marathons.
Running Example: Olympic Marathons
Note that x and y are not pandas data frames for this example, they are just arrays of dimensionality \(n\times 1\), where \(n\) is the number of data.
The aim of this lab is to have you coding linear regression in python. We will do it in two ways, once using iterative updates (coordinate ascent) and then using linear algebra. The linear algebra approach will not only work much better, it is also easy to extend to multiple input linear regression and non-linear regression using basis functions.
Maximum Likelihood: Iterative Solution
Now we will take the maximum likelihood approach we derived in the lecture to fit a line, \(y_i=mx_i + c\), to the data you’ve plotted. We are trying to minimize the error function, \[ L(m, c) = \sum_{i=1}^n(y_i-mx_i-c)^2, -\] with respect to \(m\), \(c\) and \(\sigma^2\). We can start with an initial guess for \(m\),
-m = -0.4
-c = 80Then we use the maximum likelihood update to find an estimate for the offset, \(c\).
-Quadratic Loss
- -Now we’ve identified the empirical risk with the loss, we’ll use \(L(\mathbf{ w})\) to represent our objective function. \[ +\] with respect to \(m\), \(c\) and \(\sigma^2\). We can start with an initial guess for \(m\),
m = -0.4
+c = 80Then we use the maximum likelihood update to find an estimate for the offset, \(c\).
Quadratic Loss
Now we’ve identified the empirical risk with the loss, we’ll use \(L(\mathbf{ w})\) to represent our objective function. \[ L(\mathbf{ w}) = \sum_{i=1}^n\left(y_i - f(\mathbf{ x}_i, \mathbf{ w})\right)^2 -\] gives us our objective.
-In the case of the linear prediction function, we can substitute \(f(\mathbf{ x}_i, \mathbf{ w}) = \mathbf{ w}^\top \mathbf{ x}_i\). \[ +\] gives us our objective.
In the case of the linear prediction function, we can substitute \(f(\mathbf{ x}_i, \mathbf{ w}) = \mathbf{ w}^\top \mathbf{ x}_i\). \[ L(\mathbf{ w}) = \sum_{i=1}^n\left(y_i - \mathbf{ w}^\top \mathbf{ x}_i\right)^2 -\] To compute the gradient of the objective, we first expand the brackets.
-Bracket Expansion
-\[ +\] To compute the gradient of the objective, we first expand the brackets.
Bracket Expansion
\[
\begin{align*}
L(\mathbf{ w},\sigma^2) = & \sum
_{i=1}^{n}y_i^{2}- 2\sum
@@ -193,39 +71,28 @@ Bracket Expansion
\mathbf{ w}^{\top}\left[\sum
_{i=1}^{n}\mathbf{ x}_i\mathbf{ x}_i^{\top}\right]\mathbf{ w}.
\end{align*}
-\]
Solution with Linear Algebra
-In this section we’re going compute the minimum of the quadratic loss with respect to the parameters. When we do this, we’ll also review linear algebra. We will represent all our errors and functions in the form of matrices and vectors.
-Linear algebra is just a shorthand for performing lots of multiplications and additions simultaneously. What does it have to do with our system then? Well, the first thing to note is that the classic linear function we fit for a one-dimensional regression has the form: \[ +\]
Solution with Linear Algebra
In this section we’re going compute the minimum of the quadratic loss with respect to the parameters. When we do this, we’ll also review linear algebra. We will represent all our errors and functions in the form of matrices and vectors.
Linear algebra is just a shorthand for performing lots of multiplications and additions simultaneously. What does it have to do with our system then? Well, the first thing to note is that the classic linear function we fit for a one-dimensional regression has the form: \[ f(x) = mx + c -\] the classical form for a straight line. From a linear algebraic perspective, we are looking for multiplications and additions. We are also looking to separate our parameters from our data. The data is the givens. In French the word is données literally translated means givens that’s great, because we don’t need to change the data, what we need to change are the parameters (or variables) of the model. In this function the data comes in through \(x\), and the parameters are \(m\) and \(c\).
-What we’d like to create is a vector of parameters and a vector of data. Then we could represent the system with vectors that represent the data, and vectors that represent the parameters.
-We look to turn the multiplications and additions into a linear algebraic form, we have one multiplication (\(m\times c\)) and one addition (\(mx + c\)). But we can turn this into an inner product by writing it in the following way, \[ +\] the classical form for a straight line. From a linear algebraic perspective, we are looking for multiplications and additions. We are also looking to separate our parameters from our data. The data is the givens. In French the word is données literally translated means givens that’s great, because we don’t need to change the data, what we need to change are the parameters (or variables) of the model. In this function the data comes in through \(x\), and the parameters are \(m\) and \(c\).
What we’d like to create is a vector of parameters and a vector of data. Then we could represent the system with vectors that represent the data, and vectors that represent the parameters.
We look to turn the multiplications and additions into a linear algebraic form, we have one multiplication (\(m\times c\)) and one addition (\(mx + c\)). But we can turn this into an inner product by writing it in the following way, \[ f(x) = m \times x + c \times 1, \] in other words, we’ve extracted the unit value from the offset, \(c\). We can think of this unit value like an extra item of data, because it is always given to us, and it is always set to 1 (unlike regular data, which is likely to vary!). We can therefore write each input data location, \(\mathbf{ x}\), as a vector \[ \mathbf{ x}= \begin{bmatrix} 1\\ x\end{bmatrix}. -\]
-Now we choose to also turn our parameters into a vector. The parameter vector will be defined to contain \[ +\]
Now we choose to also turn our parameters into a vector. The parameter vector will be defined to contain \[
\mathbf{ w}= \begin{bmatrix} c \\ m\end{bmatrix}
\] because if we now take the inner product between these two vectors we recover \[
\mathbf{ x}\cdot\mathbf{ w}= 1 \times c + x \times m = mx + c
-\] In numpy we can define this vector as follows
import numpy as np# define the vector w
-w = np.zeros(shape=(2, 1))
-w[0] = m
-w[1] = cThis gives us the equivalence between original operation and an operation in vector space. Whilst the notation here isn’t a lot shorter, the beauty is that we will be able to add as many features as we like and keep the same representation. In general, we are now moving to a system where each of our predictions is given by an inner product. When we want to represent a linear product in linear algebra, we tend to do it with the transpose operation, so since we have \(\mathbf{a}\cdot\mathbf{b} = \mathbf{a}^\top\mathbf{b}\) we can write \[
+\] In numpy we can define this vector as follows
import numpy as np# define the vector w
+w = np.zeros(shape=(2, 1))
+w[0] = m
+w[1] = cThis gives us the equivalence between original operation and an operation in vector space. Whilst the notation here isn’t a lot shorter, the beauty is that we will be able to add as many features as we like and keep the same representation. In general, we are now moving to a system where each of our predictions is given by an inner product. When we want to represent a linear product in linear algebra, we tend to do it with the transpose operation, so since we have \(\mathbf{a}\cdot\mathbf{b} = \mathbf{a}^\top\mathbf{b}\) we can write \[ f(\mathbf{ x}_i) = \mathbf{ x}_i^\top\mathbf{ w}. \] Where we’ve assumed that each data point, \(\mathbf{ x}_i\), is now written by appending a 1 onto the original vector \[ \mathbf{ x}_i = \begin{bmatrix} 1 \\ x_i \end{bmatrix} -\]
-Design Matrix
-We can do this for the entire data set to form a design matrix \(\boldsymbol{ \Phi}\), \[ +\]
Design Matrix
We can do this for the entire data set to form a design matrix \(\boldsymbol{ \Phi}\), \[
\boldsymbol{ \Phi}
= \begin{bmatrix}
\mathbf{ x}_1^\top \\\
@@ -239,12 +106,8 @@ Design Matrix
& \vdots \\\
1 & x_n
\end{bmatrix},
-\] which in numpy can be done with the following commands:
import numpy as npPhi = np.hstack((np.ones_like(x), x))
-print(Phi)Writing the Objective with Linear Algebra
-When we think of the objective function, we can think of it as the errors where the error is defined in a similar way to what it was in Legendre’s day \(y_i - f(\mathbf{ x}_i)\), in statistics these errors are also sometimes called residuals. So, we can think as the objective and the prediction function as two separate parts, first we have, \[
+\] which in numpy can be done with the following commands:
import numpy as npPhi = np.hstack((np.ones_like(x), x))
+print(Phi)Writing the Objective with Linear Algebra
When we think of the objective function, we can think of it as the errors where the error is defined in a similar way to what it was in Legendre’s day \(y_i - f(\mathbf{ x}_i)\), in statistics these errors are also sometimes called residuals. So, we can think as the objective and the prediction function as two separate parts, first we have, \[
L(\mathbf{ w}) = \sum_{i=1}^n(y_i - f(\mathbf{ x}_i; \mathbf{ w}))^2,
\] where we’ve made the function \(f(\cdot)\)’s dependence on the parameters \(\mathbf{ w}\) explicit in this equation. Then we have the definition of the function itself, \[
f(\mathbf{ x}_i; \mathbf{ w}) = \mathbf{ x}_i^\top \mathbf{ w}.
@@ -263,8 +126,7 @@ Writing the Objective with Li
f_i = \mathbf{ x}_i^\top\mathbf{ w}.
\]
This operation tells us that each element of the vector \(\mathbf{ f}\) (our vector valued function) is given by an inner product between \(\mathbf{ x}_i\) and \(\mathbf{ w}\). In other words, it is a series of inner products. Let’s look at the definition of matrix multiplication, it takes the form \[
\mathbf{c} = \mathbf{B}\mathbf{a},
-\] where \(\mathbf{c}\) might be a \(k\) dimensional vector (which we can interpret as a \(k\times 1\) dimensional matrix), and \(\mathbf{B}\) is a \(k\times k\) dimensional matrix and \(\mathbf{a}\) is a \(k\) dimensional vector (\(k\times 1\) dimensional matrix).
The result of this multiplication is of the form \[ +\] where \(\mathbf{c}\) might be a \(k\) dimensional vector (which we can interpret as a \(k\times 1\) dimensional matrix), and \(\mathbf{B}\) is a \(k\times k\) dimensional matrix and \(\mathbf{a}\) is a \(k\) dimensional vector (\(k\times 1\) dimensional matrix).
The result of this multiplication is of the form \[
\begin{bmatrix}c_1\\c_2 \\ \vdots \\
a_k\end{bmatrix} =
\begin{bmatrix} b_{1,1} & b_{1, 2} & \dots & b_{1, k} \\
@@ -276,31 +138,16 @@ Writing the Objective with Li
b_{2, 1}a_1 + b_{2, 2}a_2 + \dots + b_{2, k}a_k \\
\vdots\\
b_{k, 1}a_1 + b_{k, 2}a_2 + \dots + b_{k, k}a_k\end{bmatrix}.
-\]
We see that each element of the result, \(\mathbf{a}\) is simply the inner product between each row of \(\mathbf{B}\) and the vector \(\mathbf{c}\). Because we have defined each element of \(\mathbf{ f}\) to be given by the inner product between each row of the design matrix and the vector \(\mathbf{ w}\) we now can write the full operation in one matrix multiplication,
\[ +\] We see that each element of the result, \(\mathbf{a}\) is simply the inner product between each row of \(\mathbf{B}\) and the vector \(\mathbf{c}\). Because we have defined each element of \(\mathbf{ f}\) to be given by the inner product between each row of the design matrix and the vector \(\mathbf{ w}\) we now can write the full operation in one matrix multiplication,
\[ \mathbf{ f}= \boldsymbol{ \Phi}\mathbf{ w}. -\]
-import numpy as npf = Phi@w # The @ sign performs matrix multiplicationCombining this result with our objective function, \[ +\]
import numpy as npf = Phi@w # The @ sign performs matrix multiplicationCombining this result with our objective function, \[ L(\mathbf{ w}) = (\mathbf{ y}- \mathbf{ f})^\top(\mathbf{ y}- \mathbf{ f}) -\] we find we have defined the model with two equations. One equation tells us the form of our predictive function and how it depends on its parameters, the other tells us the form of our objective function.
-resid = (y-f)
-E = np.dot(resid.T, resid) # matrix multiplication on a single vector is equivalent to a dot product.
-print("Error function is:", E)Objective Optimization
- -Our model has now been defined with two equations: the prediction function and the objective function. Now we will use multivariate calculus to define an algorithm to fit the model. The separation between model and algorithm is important and is often overlooked. Our model contains a function that shows how it will be used for prediction, and a function that describes the objective function we need to optimize to obtain a good set of parameters.
-The model linear regression model we have described is still the same as the one we fitted above with a coordinate ascent algorithm. We have only played with the notation to obtain the same model in a matrix and vector notation. However, we will now fit this model with a different algorithm, one that is much faster. It is such a widely used algorithm that from the end user’s perspective it doesn’t even look like an algorithm, it just appears to be a single operation (or function). However, underneath the computer calls an algorithm to find the solution. Further, the algorithm we obtain is very widely used, and because of this it turns out to be highly optimized.
-Once again, we are going to try and find the stationary points of our objective by finding the stationary points. However, the stationary points of a multivariate function, are a little bit more complex to find. As before we need to find the point at which the gradient is zero, but now we need to use multivariate calculus to find it. This involves learning a few additional rules of differentiation (that allow you to do the derivatives of a function with respect to vector), but in the end it makes things quite a bit easier. We define vectorial derivatives as follows, \[ +\] we find we have defined the model with two equations. One equation tells us the form of our predictive function and how it depends on its parameters, the other tells us the form of our objective function.
resid = (y-f)
+E = np.dot(resid.T, resid) # matrix multiplication on a single vector is equivalent to a dot product.
+print("Error function is:", E)Objective Optimization
Our model has now been defined with two equations: the prediction function and the objective function. Now we will use multivariate calculus to define an algorithm to fit the model. The separation between model and algorithm is important and is often overlooked. Our model contains a function that shows how it will be used for prediction, and a function that describes the objective function we need to optimize to obtain a good set of parameters.
The model linear regression model we have described is still the same as the one we fitted above with a coordinate ascent algorithm. We have only played with the notation to obtain the same model in a matrix and vector notation. However, we will now fit this model with a different algorithm, one that is much faster. It is such a widely used algorithm that from the end user’s perspective it doesn’t even look like an algorithm, it just appears to be a single operation (or function). However, underneath the computer calls an algorithm to find the solution. Further, the algorithm we obtain is very widely used, and because of this it turns out to be highly optimized.
Once again, we are going to try and find the stationary points of our objective by finding the stationary points. However, the stationary points of a multivariate function, are a little bit more complex to find. As before we need to find the point at which the gradient is zero, but now we need to use multivariate calculus to find it. This involves learning a few additional rules of differentiation (that allow you to do the derivatives of a function with respect to vector), but in the end it makes things quite a bit easier. We define vectorial derivatives as follows, \[ \frac{\text{d}L(\mathbf{ w})}{\text{d}\mathbf{ w}} = \begin{bmatrix}\frac{\text{d}L(\mathbf{ w})}{\text{d}w_1}\\\frac{\text{d}L(\mathbf{ w})}{\text{d}w_2}\end{bmatrix}. -\] where \(\frac{\text{d}L(\mathbf{ w})}{\text{d}w_1}\) is the partial derivative of the error function with respect to \(w_1\).
-Differentiation through multiplications and additions is relatively straightforward, and since linear algebra is just multiplication and addition, then its rules of differentiation are quite straightforward too, but slightly more complex than regular derivatives.
-Multivariate Derivatives
-We will need two rules of multivariate or matrix differentiation. The first is differentiation of an inner product. By remembering that the inner product is made up of multiplication and addition, we can hope that its derivative is quite straightforward, and so it proves to be. We can start by thinking about the definition of the inner product, \[ +\] where \(\frac{\text{d}L(\mathbf{ w})}{\text{d}w_1}\) is the partial derivative of the error function with respect to \(w_1\).
Differentiation through multiplications and additions is relatively straightforward, and since linear algebra is just multiplication and addition, then its rules of differentiation are quite straightforward too, but slightly more complex than regular derivatives.
Multivariate Derivatives
We will need two rules of multivariate or matrix differentiation. The first is differentiation of an inner product. By remembering that the inner product is made up of multiplication and addition, we can hope that its derivative is quite straightforward, and so it proves to be. We can start by thinking about the definition of the inner product, \[
\mathbf{a}^\top\mathbf{z} = \sum_{i} a_i
z_i,
\] which if we were to take the derivative with respect to \(z_k\) would simply return the gradient of the one term in the sum for which the derivative was non-zero, that of \(a_k\), so we know that \[
@@ -308,15 +155,12 @@ Multivariate Derivatives
\] and by our definition for multivariate derivatives, we can simply stack all the partial derivatives of this form in a vector to obtain the result that \[
\frac{\text{d}}{\text{d}\mathbf{z}}
\mathbf{a}^\top \mathbf{z} = \mathbf{a}.
-\] The second rule that’s required is differentiation of a ‘matrix quadratic.’ A scalar quadratic in \(z\) with coefficient \(c\) has the form \(cz^2\). If \(\mathbf{z}\) is a \(k\times 1\) vector and \(\mathbf{C}\) is a \(k \times k\) matrix of coefficients then the matrix quadratic form is written as \(\mathbf{z}^\top \mathbf{C}\mathbf{z}\), which is itself a scalar quantity, but it is a function of a vector.
Matching Dimensions in Matrix Multiplications
-There’s a trick for telling a multiplication leads to a scalar result. When you are doing mathematics with matrices, it’s always worth pausing to perform a quick sanity check on the dimensions. Matrix multplication only works when the dimensions match. To be precise, the ‘inner’ dimension of the matrix must match. What is the inner dimension? If we multiply two matrices \(\mathbf{A}\) and \(\mathbf{B}\), the first of which has \(k\) rows and \(\ell\) columns and the second of which has \(p\) rows and \(q\) columns, then we can check whether the multiplication works by writing the dimensionalities next to each other, \[ +\] The second rule that’s required is differentiation of a ‘matrix quadratic.’ A scalar quadratic in \(z\) with coefficient \(c\) has the form \(cz^2\). If \(\mathbf{z}\) is a \(k\times 1\) vector and \(\mathbf{C}\) is a \(k \times k\) matrix of coefficients then the matrix quadratic form is written as \(\mathbf{z}^\top \mathbf{C}\mathbf{z}\), which is itself a scalar quantity, but it is a function of a vector.
Matching Dimensions in Matrix Multiplications
There’s a trick for telling a multiplication leads to a scalar result. When you are doing mathematics with matrices, it’s always worth pausing to perform a quick sanity check on the dimensions. Matrix multplication only works when the dimensions match. To be precise, the ‘inner’ dimension of the matrix must match. What is the inner dimension? If we multiply two matrices \(\mathbf{A}\) and \(\mathbf{B}\), the first of which has \(k\) rows and \(\ell\) columns and the second of which has \(p\) rows and \(q\) columns, then we can check whether the multiplication works by writing the dimensionalities next to each other, \[ \mathbf{A} \mathbf{B} \rightarrow (k \times \underbrace{\ell)(p}_\text{inner dimensions} \times q) \rightarrow (k\times q). \] The inner dimensions are the two inside dimensions, \(\ell\) and \(p\). The multiplication will only work if \(\ell=p\). The result of the multiplication will then be a \(k\times q\) matrix: this dimensionality comes from the ‘outer dimensions.’ Note that matrix multiplication is not commutative. And if you change the order of the multiplication, \[ \mathbf{B} \mathbf{A} \rightarrow (\ell \times \underbrace{k)(q}_\text{inner dimensions} \times p) \rightarrow (\ell \times p). -\] Firstly, it may no longer even work, because now the condition is that \(k=q\), and secondly the result could be of a different dimensionality. An exception is if the matrices are square matrices (e.g., same number of rows as columns) and they are both symmetric. A symmetric matrix is one for which \(\mathbf{A}=\mathbf{A}^\top\), or equivalently, \(a_{i,j} = a_{j,i}\) for all \(i\) and \(j\).
-For applying and developing machine learning algorithms you should get familiar with working with matrices and vectors. You should have come across them before, but you may not have used them as extensively as we are doing now. It’s worth getting used to using this trick to check your work and ensure you know what the dimension of an output matrix should be. For our matrix quadratic form, it turns out that we can see it as a special type of inner product. \[ +\] Firstly, it may no longer even work, because now the condition is that \(k=q\), and secondly the result could be of a different dimensionality. An exception is if the matrices are square matrices (e.g., same number of rows as columns) and they are both symmetric. A symmetric matrix is one for which \(\mathbf{A}=\mathbf{A}^\top\), or equivalently, \(a_{i,j} = a_{j,i}\) for all \(i\) and \(j\).
For applying and developing machine learning algorithms you should get familiar with working with matrices and vectors. You should have come across them before, but you may not have used them as extensively as we are doing now. It’s worth getting used to using this trick to check your work and ensure you know what the dimension of an output matrix should be. For our matrix quadratic form, it turns out that we can see it as a special type of inner product. \[
\mathbf{z}^\top\mathbf{C}\mathbf{z} \rightarrow (1\times
\underbrace{k) (k}_\text{inner dimensions}\times k) (k\times 1) \rightarrow
\mathbf{b}^\top\mathbf{z}
@@ -324,17 +168,14 @@ Matching Dimensions in Ma
\mathbf{b}^\top\mathbf{z} \rightarrow
(1\times \underbrace{k) (k}_\text{inner dimensions}\times 1) \rightarrow
(1\times 1)
-\]
where a \((1\times 1)\) matrix is recognised as a scalar.
This implies that we should be able to differentiate this form, and indeed the rule for its differentiation is slightly more complex than the inner product, but still quite simple, \[ +\] where a \((1\times 1)\) matrix is recognised as a scalar.
This implies that we should be able to differentiate this form, and indeed the rule for its differentiation is slightly more complex than the inner product, but still quite simple, \[ \frac{\text{d}}{\text{d}\mathbf{z}} \mathbf{z}^\top\mathbf{C}\mathbf{z}= \mathbf{C}\mathbf{z} + \mathbf{C}^\top \mathbf{z}. \] Note that in the special case where \(\mathbf{C}\) is symmetric then we have \(\mathbf{C} = \mathbf{C}^\top\) and the derivative simplifies to \[ \frac{\text{d}}{\text{d}\mathbf{z}} \mathbf{z}^\top\mathbf{C}\mathbf{z}= 2\mathbf{C}\mathbf{z}. -\]
-Differentiate the Objective
-First, we need to compute the full objective by substituting our prediction function into the objective function to obtain the objective in terms of \(\mathbf{ w}\). Doing this we obtain \[ +\]
Differentiate the Objective
First, we need to compute the full objective by substituting our prediction function into the objective function to obtain the objective in terms of \(\mathbf{ w}\). Doing this we obtain \[
L(\mathbf{ w})= (\mathbf{ y}- \boldsymbol{ \Phi}\mathbf{ w})^\top (\mathbf{ y}- \boldsymbol{ \Phi}\mathbf{ w}).
\] We now need to differentiate this quadratic form to find the minimum. We differentiate with respect to the vector \(\mathbf{ w}\). But before we do that, we’ll expand the brackets in the quadratic form to obtain a series of scalar terms. The rules for bracket expansion across the vectors are similar to those for the scalar system giving, \[
(\mathbf{a} - \mathbf{b})^\top
@@ -344,143 +185,38 @@ Differentiate the Objective
L(\mathbf{ w})=
\mathbf{ y}^\top\mathbf{ y}- 2\mathbf{ y}^\top\boldsymbol{ \Phi}\mathbf{ w}+
\mathbf{ w}^\top\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\mathbf{ w}
-\] where we used the fact that \(\mathbf{ y}^\top\boldsymbol{ \Phi}\mathbf{ w}=\mathbf{ w}^\top\boldsymbol{ \Phi}^\top\mathbf{ y}\).
Now we can use our rules of differentiation to compute the derivative of this form, which is, \[ +\] where we used the fact that \(\mathbf{ y}^\top\boldsymbol{ \Phi}\mathbf{ w}=\mathbf{ w}^\top\boldsymbol{ \Phi}^\top\mathbf{ y}\).
Now we can use our rules of differentiation to compute the derivative of this form, which is, \[ \frac{\text{d}}{\text{d}\mathbf{ w}}L(\mathbf{ w})=- 2\boldsymbol{ \Phi}^\top \mathbf{ y}+ 2\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\mathbf{ w}, -\] where we have exploited the fact that \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\) is symmetric to obtain this result.
-Exercise 1
-Use the equivalence between our vector and our matrix formulations of linear regression, alongside our definition of vector derivates, to match the gradients we’ve computed directly for \(\frac{\text{d}L(c, m)}{\text{d}c}\) and \(\frac{\text{d}L(c, m)}{\text{d}m}\) to those for \(\frac{\text{d}L(\mathbf{ w})}{\text{d}\mathbf{ w}}\).
-Update Equation for Global Optimum
-We need to find the minimum of our objective function. Using our objective function, we can minimize for our parameter vector \(\mathbf{ w}\). Firstly, we seek stationary points by find parameter vectors that solve for when the gradients are zero, \[ +\] where we have exploited the fact that \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\) is symmetric to obtain this result.
Exercise 1
Use the equivalence between our vector and our matrix formulations of linear regression, alongside our definition of vector derivates, to match the gradients we’ve computed directly for \(\frac{\text{d}L(c, m)}{\text{d}c}\) and \(\frac{\text{d}L(c, m)}{\text{d}m}\) to those for \(\frac{\text{d}L(\mathbf{ w})}{\text{d}\mathbf{ w}}\).
Update Equation for Global Optimum
We need to find the minimum of our objective function. Using our objective function, we can minimize for our parameter vector \(\mathbf{ w}\). Firstly, we seek stationary points by find parameter vectors that solve for when the gradients are zero, \[ \mathbf{0}=- 2\boldsymbol{ \Phi}^\top \mathbf{ y}+ 2\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\mathbf{ w}, \] where \(\mathbf{0}\) is a vector of zeros. Rearranging this equation, we find the solution to be \[ \boldsymbol{ \Phi}^\top \boldsymbol{ \Phi}\mathbf{ w}= \boldsymbol{ \Phi}^\top \mathbf{ y} -\] which is a matrix equation of the familiar form \(\mathbf{A}\mathbf{x} = \mathbf{b}\).
-Solving the Multivariate System
-The solution for \(\mathbf{ w}\) can be written mathematically in terms of a matrix inverse of \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\), but computation of a matrix inverse requires an algorithm to resolve it. You’ll know this if you had to invert, by hand, a \(3\times 3\) matrix in high school. From a numerical stability perspective, it is also best not to compute the matrix inverse directly, but rather to ask the computer to solve the system of linear equations given by \[ +\] which is a matrix equation of the familiar form \(\mathbf{A}\mathbf{x} = \mathbf{b}\).
Solving the Multivariate System
The solution for \(\mathbf{ w}\) can be written mathematically in terms of a matrix inverse of \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\), but computation of a matrix inverse requires an algorithm to resolve it. You’ll know this if you had to invert, by hand, a \(3\times 3\) matrix in high school. From a numerical stability perspective, it is also best not to compute the matrix inverse directly, but rather to ask the computer to solve the system of linear equations given by \[ \boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\mathbf{ w}= \boldsymbol{ \Phi}^\top\mathbf{ y} -\] for \(\mathbf{ w}\).
-Multivariate Linear Regression
-A major advantage of the new system is that we can build a linear regression on a multivariate system. The matrix calculus didn’t specify what the length of the vector \(\mathbf{ x}\) should be, or equivalently the size of the design matrix.
-Hessian Matrix
- -We can also compute the Hessian matrix, the curvature of the loss function. To do this we take the second derivative of the loss function with respect to the parameter vector, \[ +\] for \(\mathbf{ w}\).
Multivariate Linear Regression
A major advantage of the new system is that we can build a linear regression on a multivariate system. The matrix calculus didn’t specify what the length of the vector \(\mathbf{ x}\) should be, or equivalently the size of the design matrix.
Hessian Matrix
We can also compute the Hessian matrix, the curvature of the loss function. To do this we take the second derivative of the loss function with respect to the parameter vector, \[ \frac{\text{d}^2}{\text{d}\mathbf{ w}\text{d}\mathbf{ w}^\top} L(\mathbf{ w}) = 2\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}. -\] So, we see that the curvature is only dependent on the design matrix.
-Note that for this linear model the curvature is not dependent on the values of the parameter vector, \(\mathbf{ w}\), or indeed on the response variables, \(\mathbf{ y}\). This is unusual, in general the curvature will depend on the parameters and the response variables. The linear model with quadratic loss is a special case because the overall loss function has a quadratic form which is the unique form with constant curvature across the whole space.
-This is one reason why linear models are so easy to work with.
-Because the curvature is constant everywhere, we know that the curvature at the minimum is given by \(2\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\).
-From univariate calculus you might recall that the optimum is a maximum if the curvature is negative, and a minimum if the curvature is positive. A similar theorem holds for multivariate calculus, but now the curvature must be positive definite for the point to be a minimum. The constant curvature also shows us also that the minimum is unique.
-Positive definite means that for any two vectors, \(\mathbf{u}\) of unit length \(\mathbf{u}^\top\mathbf{u}\) we have that, \[ +\] So, we see that the curvature is only dependent on the design matrix.
Note that for this linear model the curvature is not dependent on the values of the parameter vector, \(\mathbf{ w}\), or indeed on the response variables, \(\mathbf{ y}\). This is unusual, in general the curvature will depend on the parameters and the response variables. The linear model with quadratic loss is a special case because the overall loss function has a quadratic form which is the unique form with constant curvature across the whole space.
This is one reason why linear models are so easy to work with.
Because the curvature is constant everywhere, we know that the curvature at the minimum is given by \(2\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\).
From univariate calculus you might recall that the optimum is a maximum if the curvature is negative, and a minimum if the curvature is positive. A similar theorem holds for multivariate calculus, but now the curvature must be positive definite for the point to be a minimum. The constant curvature also shows us also that the minimum is unique.
Positive definite means that for any two vectors, \(\mathbf{u}\) of unit length \(\mathbf{u}^\top\mathbf{u}\) we have that, \[ \mathbf{u}^\top\mathbf{A} \mathbf{u} > 0 \quad \forall \quad \mathbf{u} \quad \text{with}\quad \mathbf{u}^\top\mathbf{u}=1 -\] The matrix \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\) (where we’ve dropped the 2) will satisfy this condition as long as the columns of \(\boldsymbol{ \Phi}\) are linearly independent and the number of basis functions is less or equal to the number of data points.
-Eigendecomposition of Hessian
-Applying a vector \(\mathbf{u}\) to the Hessian matrix gives us the curvature in a particular direction. So we can use this to look at the shape of the minimum by projecting onto the different directions, \(\mathbf{u}\).
-Recall the eigendecomposition of a matrix, \[ +\] The matrix \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\) (where we’ve dropped the 2) will satisfy this condition as long as the columns of \(\boldsymbol{ \Phi}\) are linearly independent and the number of basis functions is less or equal to the number of data points.
Eigendecomposition of Hessian
Applying a vector \(\mathbf{u}\) to the Hessian matrix gives us the curvature in a particular direction. So we can use this to look at the shape of the minimum by projecting onto the different directions, \(\mathbf{u}\).
Recall the eigendecomposition of a matrix, \[ \mathbf{A}\mathbf{u} = \lambda\mathbf{u} \] If we allow \(\mathbf{u}_i\) to be an eigenvector of \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\mathbf{ w}\) then the curvature in that direction is given by the corresponding eigenvalue, \(\lambda_i\). \[ \boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\mathbf{u}_i = \lambda_i \mathbf{u}_i. -\]
-The eigendecomposition of the Hessian is a convenient representation of the nature of these minima. The principal eigenvector (the one associated with the largest eigenvalue), \(\mathbf{u}_1\) is associated with the direction of highest curvature. While the minor eigenvector shows us the flattest direction, where the curvature is smallest.
-Nigeria NMIS Data
- -As an example data set we will use Nigerian Millennium Development Goals Information System Health Facility (The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) and Columbia University, 2014). It can be found here https://energydata.info/dataset/nigeria-nmis-education-facility-data-2014.
-Taking from the information on the site,
---The Nigeria MDG (Millennium Development Goals) Information System – NMIS health facility data is collected by the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) in partner with the Sustainable Engineering Lab at Columbia University. A rigorous, geo-referenced baseline facility inventory across Nigeria is created spanning from 2009 to 2011 with an additional survey effort to increase coverage in 2014, to build Nigeria’s first nation-wide inventory of health facility. The database includes 34,139 health facilities info in Nigeria.
-The goal of this database is to make the data collected available to planners, government officials, and the public, to be used to make strategic decisions for planning relevant interventions.
-For data inquiry, please contact Ms. Funlola Osinupebi, Performance Monitoring & Communications, Advisory Power Team, Office of the Vice President at funlola.osinupebi@aptovp.org
-To learn more, please visit http://csd.columbia.edu/2014/03/10/the-nigeria-mdg-information-system-nmis-takes-open-data-further/
-Suggested citation: Nigeria NMIS facility database (2014), the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) & Columbia University
-
For ease of use we’ve packaged this data set in the pods library
data = pods.datasets.nigeria_nmis()['Y']
-data.head()Alternatively, you can access the data directly with the following commands.
-import urllib.request
-urllib.request.urlretrieve('https://energydata.info/dataset/f85d1796-e7f2-4630-be84-79420174e3bd/resource/6e640a13-cab4-457b-b9e6-0336051bac27/download/healthmopupandbaselinenmisfacility.csv', 'healthmopupandbaselinenmisfacility.csv')
-
-import pandas as pd
-data = pd.read_csv('healthmopupandbaselinenmisfacility.csv')Once it is loaded in the data can be summarized using the describe method in pandas.
data.describe()We can also find out the dimensions of the dataset using the shape property.
data.shapeDataframes have different functions that you can use to explore and understand your data. In python and the Jupyter notebook it is possible to see a list of all possible functions and attributes by typing the name of the object followed by .<Tab> for example in the above case if we type data.<Tab> it show the columns available (these are attributes in pandas dataframes) such as num_nurses_fulltime, and also functions, such as .describe().
For functions we can also see the documentation about the function by following the name with a question mark. This will open a box with documentation at the bottom which can be closed with the x button.
-data.describe?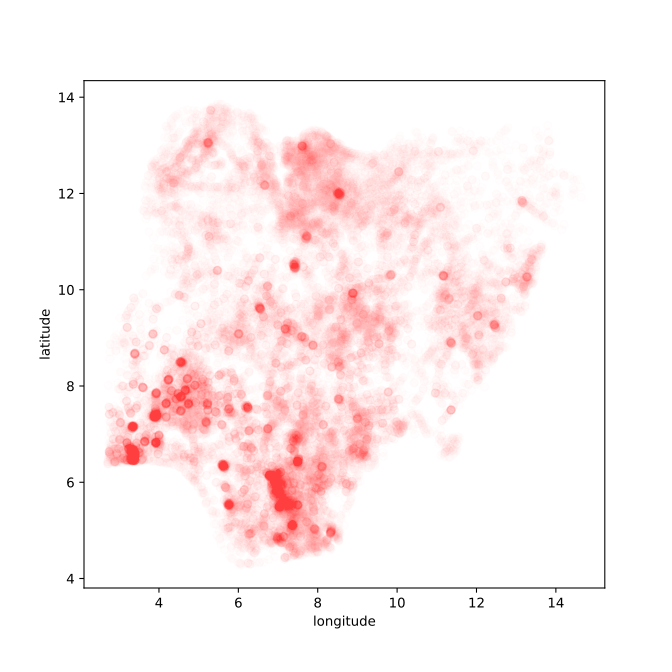 -
-
Figure: Location of the over thirty-four thousand health facilities registered in the NMIS data across Nigeria. Each facility plotted according to its latitude and longitude.
-Multivariate Regression on Nigeria NMIS Data
- -Now we will build a design matrix based on the numeric features that include the number of nurses, and the number of midwives, the latitude and longitude. These are our covariates. The response variable will be the number of doctors. We build the design matrix as follows:
-Bias as an additional feature.
-First we select the covariates and response variables and drop any rows where there are missing values using the pandas dropna method.
covariates = ['num_nurses_fulltime', 'num_nursemidwives_fulltime', 'latitude', 'longitude']
-response = ['num_doctors_fulltime']
-data_without_missing = data[covariates + response].dropna()We can see how many rows we have dropped and have a quick sanity check on our new data frame with len.
print(len(data) - len(data_without_missing))We see that 2,735 of the entries had missing values in one of our variables of interest.
-You may also want to use describe or other functions to explore the new data frame.
Now let’s perform a linear regression. But this time, we will create a pandas data frame for the result so we can store it in a form that we can visualize easily.
-Phi = data_without_missing[covariates]
-Phi['Eins'] = 1 # add a column for the offset
-y = data_without_missing[response]import pandas as pdw = pd.DataFrame(data=np.linalg.solve(Phi.T@Phi, Phi.T@y), # solve linear regression here
- index = Phi.columns, # columns of Phi become rows of w
- columns=['regression_coefficient']) # the column of Phi is the value of regression coefficientWe can check the residuals to see how good our estimates are. First we create a pandas data frame containing the predictions and use it to compute the residuals.
-ypred = pd.DataFrame(data=(Phi@w).values, columns=['num_doctors_fulltime'])
-resid = y-ypredLet’s look at the residuals. We can use describe to get a summary.
resid.describe()We can see that while the standard deviation of our residuals is around 3, (this is equivalent to a root mean square error). The smallest and largest residual sow there are some significant outliers that our regression isn’t picking up.
-
-Figure: Residual values for the ratings from the prediction of the movie rating given the data from the film.
-Which shows our model hasn’t yet done a great job of representation, because the spread of values is large. We can check what the rating is dominated by in terms of regression coefficients.
-wChecking our regression coefficients, we see that the number of doctors is positively influenced by the number of nurses and the number of midwives. The latitude and longitude have a smaller effect. The bias term (‘eins’) is a small positive offset.
-Aside
-Just for informational purposes, the actual approach used in software for fitting a linear model should be a QR decomposition.
-Solution with QR Decomposition
- -Performing a solve instead of a matrix inverse is the more numerically stable approach, but we can do even better.
-The problems can arise with very large data sets, where computing \(\boldsymbol{ \Phi}^\top \boldsymbol{ \Phi}\) can lead to a very poorly conditioned matrix. Instead, we can compute the solution without having to compute the matrix. The trick is to use a QR decomposition.
-A QR-decomposition of a matrix factorizes it into a matrix which is an orthogonal matrix \(\mathbf{Q}\), so that \(\mathbf{Q}^\top \mathbf{Q} = \mathbf{I}\). And a matrix which is upper triangular, \(\mathbf{R}\). \[ +\]
The eigendecomposition of the Hessian is a convenient representation of the nature of these minima. The principal eigenvector (the one associated with the largest eigenvalue), \(\mathbf{u}_1\) is associated with the direction of highest curvature. While the minor eigenvector shows us the flattest direction, where the curvature is smallest.
Nigeria NMIS Data
As an example data set we will use Nigerian Millennium Development Goals Information System Health Facility (The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) and Columbia University, 2014). It can be found here https://energydata.info/dataset/nigeria-nmis-education-facility-data-2014.
Taking from the information on the site,
The Nigeria MDG (Millennium Development Goals) Information System – NMIS health facility data is collected by the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) in partner with the Sustainable Engineering Lab at Columbia University. A rigorous, geo-referenced baseline facility inventory across Nigeria is created spanning from 2009 to 2011 with an additional survey effort to increase coverage in 2014, to build Nigeria’s first nation-wide inventory of health facility. The database includes 34,139 health facilities info in Nigeria.
The goal of this database is to make the data collected available to planners, government officials, and the public, to be used to make strategic decisions for planning relevant interventions.
For data inquiry, please contact Ms. Funlola Osinupebi, Performance Monitoring & Communications, Advisory Power Team, Office of the Vice President at funlola.osinupebi@aptovp.org
To learn more, please visit http://csd.columbia.edu/2014/03/10/the-nigeria-mdg-information-system-nmis-takes-open-data-further/
Suggested citation: Nigeria NMIS facility database (2014), the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) & Columbia University
For ease of use we’ve packaged this data set in the pods library
data = pods.datasets.nigeria_nmis()['Y']
+data.head()Alternatively, you can access the data directly with the following commands.
import urllib.request
+urllib.request.urlretrieve('https://energydata.info/dataset/f85d1796-e7f2-4630-be84-79420174e3bd/resource/6e640a13-cab4-457b-b9e6-0336051bac27/download/healthmopupandbaselinenmisfacility.csv', 'healthmopupandbaselinenmisfacility.csv')
+
+import pandas as pd
+data = pd.read_csv('healthmopupandbaselinenmisfacility.csv')Once it is loaded in the data can be summarized using the describe method in pandas.
data.describe()We can also find out the dimensions of the dataset using the shape property.
data.shapeDataframes have different functions that you can use to explore and understand your data. In python and the Jupyter notebook it is possible to see a list of all possible functions and attributes by typing the name of the object followed by .<Tab> for example in the above case if we type data.<Tab> it show the columns available (these are attributes in pandas dataframes) such as num_nurses_fulltime, and also functions, such as .describe().
For functions we can also see the documentation about the function by following the name with a question mark. This will open a box with documentation at the bottom which can be closed with the x button.
data.describe?Figure: Location of the over thirty-four thousand health facilities registered in the NMIS data across Nigeria. Each facility plotted according to its latitude and longitude.
Multivariate Regression on Nigeria NMIS Data
Now we will build a design matrix based on the numeric features that include the number of nurses, and the number of midwives, the latitude and longitude. These are our covariates. The response variable will be the number of doctors. We build the design matrix as follows:
Bias as an additional feature.
First we select the covariates and response variables and drop any rows where there are missing values using the pandas dropna method.
covariates = ['num_nurses_fulltime', 'num_nursemidwives_fulltime', 'latitude', 'longitude']
+response = ['num_doctors_fulltime']
+data_without_missing = data[covariates + response].dropna()We can see how many rows we have dropped and have a quick sanity check on our new data frame with len.
print(len(data) - len(data_without_missing))We see that 2,735 of the entries had missing values in one of our variables of interest.
You may also want to use describe or other functions to explore the new data frame.
Now let’s perform a linear regression. But this time, we will create a pandas data frame for the result so we can store it in a form that we can visualize easily.
Phi = data_without_missing[covariates]
+Phi['Eins'] = 1 # add a column for the offset
+y = data_without_missing[response]import pandas as pdw = pd.DataFrame(data=np.linalg.solve(Phi.T@Phi, Phi.T@y), # solve linear regression here
+ index = Phi.columns, # columns of Phi become rows of w
+ columns=['regression_coefficient']) # the column of Phi is the value of regression coefficientWe can check the residuals to see how good our estimates are. First we create a pandas data frame containing the predictions and use it to compute the residuals.
ypred = pd.DataFrame(data=(Phi@w).values, columns=['num_doctors_fulltime'])
+resid = y-ypredLet’s look at the residuals. We can use describe to get a summary.
resid.describe()We can see that while the standard deviation of our residuals is around 3, (this is equivalent to a root mean square error). The smallest and largest residual sow there are some significant outliers that our regression isn’t picking up.
Figure: Residual values for the ratings from the prediction of the movie rating given the data from the film.
Which shows our model hasn’t yet done a great job of representation, because the spread of values is large. We can check what the rating is dominated by in terms of regression coefficients.
wChecking our regression coefficients, we see that the number of doctors is positively influenced by the number of nurses and the number of midwives. The latitude and longitude have a smaller effect. The bias term (‘eins’) is a small positive offset.
Aside
Just for informational purposes, the actual approach used in software for fitting a linear model should be a QR decomposition.
Solution with QR Decomposition
Performing a solve instead of a matrix inverse is the more numerically stable approach, but we can do even better.
The problems can arise with very large data sets, where computing \(\boldsymbol{ \Phi}^\top \boldsymbol{ \Phi}\) can lead to a very poorly conditioned matrix. Instead, we can compute the solution without having to compute the matrix. The trick is to use a QR decomposition.
A QR-decomposition of a matrix factorizes it into a matrix which is an orthogonal matrix \(\mathbf{Q}\), so that \(\mathbf{Q}^\top \mathbf{Q} = \mathbf{I}\). And a matrix which is upper triangular, \(\mathbf{R}\). \[
\boldsymbol{ \Phi}^\top \boldsymbol{ \Phi}\boldsymbol{\beta} =
\boldsymbol{ \Phi}^\top \mathbf{ y}
\] and we substitute \(\boldsymbol{ \Phi}= \mathbf{Q}\mathbf{R}\) so we have \[
@@ -490,631 +226,146 @@ Solution with QR Decomposition
\] \[
\mathbf{R}^\top (\mathbf{Q}^\top \mathbf{Q}) \mathbf{R}
\boldsymbol{\beta} = \mathbf{R}^\top \mathbf{Q}^\top \mathbf{ y}
-\]
\[ +\]
\[ \mathbf{R}^\top \mathbf{R} \boldsymbol{\beta} = \mathbf{R}^\top \mathbf{Q}^\top \mathbf{ y} \] \[ \mathbf{R} \boldsymbol{\beta} = \mathbf{Q}^\top \mathbf{ y} -\] which leaves us with a lower triangular system to solve.
-This is a more numerically stable solution because it removes the need to compute \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\) as an intermediate. Computing \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\) is a bad idea because it involves squaring all the elements of \(\boldsymbol{ \Phi}\) and thereby potentially reducing the numerical precision with which we can represent the solution. Operating on \(\boldsymbol{ \Phi}\) directly preserves the numerical precision of the model.
-This can be more particularly seen when we begin to work with basis functions in the next session. Some systems that can be resolved with the QR decomposition cannot be resolved by using solve directly.
-import scipy as spQ, R = np.linalg.qr(Phi)
-w = sp.linalg.solve_triangular(R, Q.T@y)
-w = pd.DataFrame(w, index=Phi.columns)
-wBasis Function Models
-We are reviewing models that are linear in the parameters. Very often we are interested in non-linear predictions. We can make models that are linear in the parameters and given non-linear predictions by introducing non-linear basis functions. A common example is the polynomial basis.
-Polynomial Basis
- -The polynomial basis combines higher order polynomials together to create the function. For example, the fourth order polynomial has five components to its basis function. \[ +\] which leaves us with a lower triangular system to solve.
This is a more numerically stable solution because it removes the need to compute \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\) as an intermediate. Computing \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\) is a bad idea because it involves squaring all the elements of \(\boldsymbol{ \Phi}\) and thereby potentially reducing the numerical precision with which we can represent the solution. Operating on \(\boldsymbol{ \Phi}\) directly preserves the numerical precision of the model.
This can be more particularly seen when we begin to work with basis functions in the next session. Some systems that can be resolved with the QR decomposition cannot be resolved by using solve directly.
import scipy as spQ, R = np.linalg.qr(Phi)
+w = sp.linalg.solve_triangular(R, Q.T@y)
+w = pd.DataFrame(w, index=getattr(Phi, "columns", None))
+wBasis Function Models
We are reviewing models that are linear in the parameters. Very often we are interested in non-linear predictions. We can make models that are linear in the parameters and given non-linear predictions by introducing non-linear basis functions. A common example is the polynomial basis.
Polynomial Basis
The polynomial basis combines higher order polynomials together to create the function. For example, the fourth order polynomial has five components to its basis function. \[ \phi_j(x) = x^j -\]
-import numpy as npfrom mlai import polynomialFigure: The set of functions which are combined to form a polynomial basis.
-Functions Derived from Polynomial Basis
-\[ +\]
import numpy as npfrom mlai import polynomialFigure: The set of functions which are combined to form a polynomial basis.
Functions Derived from Polynomial Basis
\[ f(x) = {\color{red}{w_0}} + {\color{magenta}{w_1 x}} + {\color{blue}{w_2 x^2}} + {\color{green}{w_3 x^3}} + {\color{cyan}{w_4 x^4}} -\]
-
-Figure: A random combination of functions from the polynomial basis.
-The predictions from this model, \[ +\]
Figure: A random combination of functions from the polynomial basis.
The predictions from this model, \[ f(x) = w_0 + w_1 x+ w_2 x^2 + w_3 x^3 + w_4 x^4 -\] are linear in the parameters, \(\mathbf{ w}\), but non-linear in the input \(x^3\). Here we are showing a polynomial basis for a 1-dimensional input, \(x\), but basis functions can also be constructed for multidimensional inputs, \(\mathbf{ x}\).}
-In the neural network models, the “RELU function” is normally used as a basis function, but for illustration we will continue with the polynomial basis for these linear models.
-Olympic Marathon Data
- --
-
- Gold medal times for Olympic Marathon since 1896. -
- Marathons before 1924 didn’t have a standardized distance. -
- Present results using pace per km. -
- In 1904 Marathon was badly organized leading to very slow times. -
-Image from Wikimedia Commons
-The Olympic Marathon data is a standard dataset for regression modelling. The data consists of the pace of Olympic Gold Medal Marathon winners for the Olympics from 1896 to present. Let’s load in the data and plot.
-import numpy as np
-import podsdata = pods.datasets.olympic_marathon_men()
-x = data['X']
-y = data['Y']
-
-offset = y.mean()
-scale = np.sqrt(y.var())
-yhat = (y - offset)/scaleFigure: Olympic marathon pace times since 1896.
-Things to notice about the data include the outlier in 1904, in that year the Olympics was in St Louis, USA. Organizational problems and challenges with dust kicked up by the cars following the race meant that participants got lost, and only very few participants completed. More recent years see more consistently quick marathons.
-Polynomial Fits to Olympic Marthon Data
- -import numpy as np
-import scipy as spDefine the polynomial basis function.
-from mlai import polynomialNow we include the solution for the linear regression through QR-decomposition.
-def basis_fit(Phi, y):
- "Use QR decomposition to fit the basis."""
- Q, R = np.linalg.qr(Phi)
- return sp.linalg.solve_triangular(R, Q.T@y) Linear Fit
-poly_args = {'num_basis':2, # two basis functions (1 and x)
- 'data_limits':xlim}
-Phi = mlai.polynomial(x, **poly_args)
-w = basis_fit(Phi, y)Now we make some predictions for the fit.
-x_pred = np.linspace(xlim[0], xlim[1], 400)[:, np.newaxis]
-Phi_pred = mlai.polynomial(x_pred, **poly_args)
-f_pred = Phi_pred@wFigure: Fit of a 1-degree polynomial (a linear model) to the Olympic marathon data.
-Cubic Fit
-poly_args = {'num_basis':4, # four basis: 1, x, x^2, x^3
+\] are linear in the parameters, \(\mathbf{ w}\), but non-linear in the input \(x^3\). Here we are showing a polynomial basis for a 1-dimensional input, \(x\), but basis functions can also be constructed for multidimensional inputs, \(\mathbf{ x}\).}In the neural network models, the “RELU function” is normally used as a basis function, but for illustration we will continue with the polynomial basis for these linear models.
Olympic Marathon Data
- Gold medal times for Olympic Marathon since 1896.
- Marathons before 1924 didn’t have a standardized distance.
- Present results using pace per km.
- In 1904 Marathon was badly organized leading to very slow times.
Image from Wikimedia Commons
The Olympic Marathon data is a standard dataset for regression modelling. The data consists of the pace of Olympic Gold Medal Marathon winners for the Olympics from 1896 to present. Let’s load in the data and plot.
import numpy as np
+import pods
data = pods.datasets.olympic_marathon_men()
+x = data['X']
+y = data['Y']
+
+offset = y.mean()
+scale = np.sqrt(y.var())
+yhat = (y - offset)/scale
Figure: Olympic marathon pace times since 1896.
Things to notice about the data include the outlier in 1904, in that year the Olympics was in St Louis, USA. Organizational problems and challenges with dust kicked up by the cars following the race meant that participants got lost, and only very few participants completed. More recent years see more consistently quick marathons.
Polynomial Fits to Olympic Marthon Data
import numpy as np
+import scipy as sp
Define the polynomial basis function.
from mlai import polynomial
Now we include the solution for the linear regression through QR-decomposition.
def basis_fit(Phi, y):
+ "Use QR decomposition to fit the basis."""
+ Q, R = np.linalg.qr(Phi)
+ return sp.linalg.solve_triangular(R, Q.T@y)
Linear Fit
poly_args = {'num_basis':2, # two basis functions (1 and x)
'data_limits':xlim}
Phi = mlai.polynomial(x, **poly_args)
-w = basis_fit(Phi, y)
-Phi_pred = mlai.polynomial(x_pred, **poly_args)
-f_pred = Phi_pred@w
-
-
-
-
-
-
-
-
-Figure: Fit of a 3-degree polynomial (a cubic model) to the Olympic marathon data.
-
-
-9th Degree Polynomial Fit
-Now we’ll try a 9th degree polynomial fit to the data.
-poly_args = {'num_basis':10, # basis up to x^9
+w = basis_fit(Phi, y)
Now we make some predictions for the fit.
x_pred = np.linspace(xlim[0], xlim[1], 400)[:, np.newaxis]
+Phi_pred = mlai.polynomial(x_pred, **poly_args)
+f_pred = Phi_pred@w
Figure: Fit of a 1-degree polynomial (a linear model) to the Olympic marathon data.
Cubic Fit
poly_args = {'num_basis':4, # four basis: 1, x, x^2, x^3
'data_limits':xlim}
Phi = mlai.polynomial(x, **poly_args)
-w = basis_fit(Phi, y)
-Phi_pred = mlai.polynomial(x_pred, **poly_args)
-f_pred = Phi_pred@w
-
-
-
-
-
-
-
-
-Figure: Fit of a 9-degree polynomial to the Olympic marathon data.
-
-
-16th Degree Polynomial Fit
-Now we’ll try a 16th degree polynomial fit to the data.
-poly_args = {'num_basis':17, # basis up to x^16
+w = basis_fit(Phi, y)
Phi_pred = mlai.polynomial(x_pred, **poly_args)
+f_pred = Phi_pred@w
Figure: Fit of a 3-degree polynomial (a cubic model) to the Olympic marathon data.
9th Degree Polynomial Fit
Now we’ll try a 9th degree polynomial fit to the data.
poly_args = {'num_basis':10, # basis up to x^9
'data_limits':xlim}
Phi = mlai.polynomial(x, **poly_args)
-w = basis_fit(Phi, y)
-Phi_pred = mlai.polynomial(x_pred, **poly_args)
-f_pred = Phi_pred@w
-
-
-
-
-
-
-
-
-Figure: Fit of a 16-degree polynomial to the Olympic marathon data.
-
-
-28th Degree Polynomial Fit
-Now we’ll try a 28th degree polynomial fit to the data.
-poly_args = {'num_basis':29, # basis up to x^28
+w = basis_fit(Phi, y)
Phi_pred = mlai.polynomial(x_pred, **poly_args)
+f_pred = Phi_pred@w
Figure: Fit of a 9-degree polynomial to the Olympic marathon data.
16th Degree Polynomial Fit
Now we’ll try a 16th degree polynomial fit to the data.
poly_args = {'num_basis':17, # basis up to x^16
'data_limits':xlim}
Phi = mlai.polynomial(x, **poly_args)
-w = basis_fit(Phi, y)
-Phi_pred = mlai.polynomial(x_pred, **poly_args)
-f_pred = Phi_pred@w
-
-
-
-
-
-
-
-
-Figure: Fit of a 28-degree polynomial to the Olympic marathon data.
-
-
-The Bootstrap
-
-Bootstrap sampling (Efron, 1979) is an approach to assessing the sensitivity of the model to different variations on a data set. In an ideal world, we’d like to be able to look at different realisations from the original data generating distribution \(\mathbb{P}(y, \mathbf{ x})\), but this is not available to us.
-In bootstrap sampling, we take the sample we have, \[
+w = basis_fit(Phi, y)
Phi_pred = mlai.polynomial(x_pred, **poly_args)
+f_pred = Phi_pred@wFigure: Fit of a 16-degree polynomial to the Olympic marathon data.
28th Degree Polynomial Fit
Now we’ll try a 28th degree polynomial fit to the data.
poly_args = {'num_basis':29, # basis up to x^28
+             'data_limits':xlim}
+Phi = mlai.polynomial(x, **poly_args)
+w = basis_fit(Phi, y)
Phi_pred = mlai.polynomial(x_pred, **poly_args)
+f_pred = Phi_pred@wFigure: Fit of a 28-degree polynomial to the Olympic marathon data.
The Bootstrap
Bootstrap sampling (Efron, 1979) is an approach to assessing the sensitivity of the model to different variations on a data set. In an ideal world, we’d like to be able to look at different realisations from the original data generating distribution \(\mathbb{P}(y, \mathbf{ x})\), but this is not available to us.
In bootstrap sampling, we take the sample we have, \[ \mathbf{ y}, \mathbf{X}\sim \mathbb{P}(y, \mathbf{ x}) -\] and resample from that data, rather than from the true distribution. So, we have a new data set, \(\hat{\mathbf{ y}}\), \(\hat{\mathbf{X}}\) which is sampled from the original with replacement.
-import numpy as npdef bootstrap(X):
- "Return a bootstrap sample from a data set."
- n = X.shape[0]
- ind = np.random.choice(n, n, replace=True) # Sample randomly with replacement.
- return X[ind, :] Bootstrap and Olympic Marathon Data
- -First we define a function to bootstrap resample our dataset.
-import numpy as npdef bootstrap(X, y):
+\] and resample from that data, rather than from the true distribution. So, we have a new data set, \(\hat{\mathbf{ y}}\), \(\hat{\mathbf{X}}\) which is sampled from the original with replacement.import numpy as np
def bootstrap(X):
"Return a bootstrap sample from a data set."
n = X.shape[0]
ind = np.random.choice(n, n, replace=True) # Sample randomly with replacement.
- return X[ind, :], y[ind, :]
-num_bootstraps = 10
-def bootstrap_fit(Phi, y, size):
- W = np.zeros((Phi.shape[1], size))
- for i in range(size):
- Phi_hat, y_hat = bootstrap(Phi, y)
- W[:, i:i+1] = basis_fit(Phi_hat, y_hat)
- return W
-Linear Fit
-poly_args = {'num_basis':2, # two basis functions (1 and x)
- 'data_limits':xlim}
-Phi = mlai.polynomial(x, **poly_args)
-W_hat = bootstrap_fit(Phi, y, num_bootstraps)
-Now we make some predictions for the fit.
-x_pred = np.linspace(xlim[0], xlim[1], 400)[:, np.newaxis]
-Phi_pred = mlai.polynomial(x_pred, **poly_args)
-f_pred = Phi_pred@W_hat
-
-
-
-
-
-
-
-
-Figure: Fit of a 1 degree polynomial (a linear model) to the olympic marathon data.
-
-
-Cubic Fit
-poly_args = {'num_basis':4, # four basis: 1, x, x^2, x^3
+ return X[ind, :]
Bootstrap and Olympic Marathon Data
First we define a function to bootstrap resample our dataset.
import numpy as np
def bootstrap(X, y):
+ "Return a bootstrap sample from a data set."
+ n = X.shape[0]
+ ind = np.random.choice(n, n, replace=True) # Sample randomly with replacement.
+ return X[ind, :], y[ind, :]
num_bootstraps = 10
def bootstrap_fit(Phi, y, size):
+ W = np.zeros((Phi.shape[1], size))
+ for i in range(size):
+ Phi_hat, y_hat = bootstrap(Phi, y)
+ W[:, i:i+1] = basis_fit(Phi_hat, y_hat)
+ return W
Linear Fit
poly_args = {'num_basis':2, # two basis functions (1 and x)
'data_limits':xlim}
Phi = mlai.polynomial(x, **poly_args)
-W_hat = bootstrap_fit(Phi, y, num_bootstraps)
-Phi_pred = mlai.polynomial(x_pred, **poly_args)
-f_pred = Phi_pred@W_hat
-
-
-
-
-
-
-
-
-Figure: Fit of a 3 degree polynomial (a cubic model) to the olympic marathon data.
-
-
-9th Degree Polynomial Fit
-Now we’ll try a 9th degree polynomial fit to the data.
-poly_args = {'num_basis':10, # basis up to x^9
+W_hat = bootstrap_fit(Phi, y, num_bootstraps)
Now we make some predictions for the fit.
x_pred = np.linspace(xlim[0], xlim[1], 400)[:, np.newaxis]
+Phi_pred = mlai.polynomial(x_pred, **poly_args)
+f_pred = Phi_pred@W_hat
Figure: Fit of a 1 degree polynomial (a linear model) to the olympic marathon data.
Cubic Fit
poly_args = {'num_basis':4, # four basis: 1, x, x^2, x^3
'data_limits':xlim}
Phi = mlai.polynomial(x, **poly_args)
-W_hat = bootstrap_fit(Phi, y, num_bootstraps)
-Phi_pred = mlai.polynomial(x_pred, **poly_args)
-f_pred = Phi_pred@W_hat
-
-
-
-
-
-
-
-
-Figure: Fit of a 9 degree polynomial to the olympic marathon data.
-
-
-16th Degree Polynomial Fit
-Now we’ll try a 16th degree polynomial fit to the data.
-poly_args = {'num_basis':17, # basis up to x^16
+W_hat = bootstrap_fit(Phi, y, num_bootstraps)
Phi_pred = mlai.polynomial(x_pred, **poly_args)
+f_pred = Phi_pred@W_hat
Figure: Fit of a 3 degree polynomial (a cubic model) to the olympic marathon data.
9th Degree Polynomial Fit
Now we’ll try a 9th degree polynomial fit to the data.
poly_args = {'num_basis':10, # basis up to x^9
'data_limits':xlim}
Phi = mlai.polynomial(x, **poly_args)
-W_hat = bootstrap_fit(Phi, y, num_bootstraps)
-Phi_pred = mlai.polynomial(x_pred, **poly_args)
-f_pred = Phi_pred@W_hat
-
-
-
-
-
-
-
-
-Figure: Fit of a 16 degree polynomial to the olympic marathon data.
-
-
-Bootstrap Confidence Intervals
-We can also use the bootstrap to create confidence intervals for our predictions, showing the uncertainty in our model.
-def plot_polynomial_bootstrap_confidence(x, y, x_pred, degree=3, num_bootstraps=50):
- """Plot bootstrap confidence intervals for polynomial fit.
-
- :param x: training inputs
- :param y: training outputs
- :param x_pred: prediction points
- :param degree: polynomial degree
- :param num_bootstraps: number of bootstrap samples
- """
- poly_args = {'num_basis': degree + 1, 'data_limits': xlim}
- Phi = mlai.polynomial(x, **poly_args)
- W_hat = bootstrap_fit(Phi, y, num_bootstraps)
-
- Phi_pred = mlai.polynomial(x_pred, **poly_args)
- f_pred_bootstrap = Phi_pred @ W_hat # Shape: (n_pred_points, n_bootstrap_samples)
-
- # Transpose to get shape (n_bootstrap_samples, n_pred_points)
- f_pred_bootstrap = f_pred_bootstrap.T
-
- # Compute confidence intervals
- f_mean = np.mean(f_pred_bootstrap, axis=0) # Mean across bootstrap samples
- f_std = np.std(f_pred_bootstrap, axis=0) # Std across bootstrap samples
-
- # Ensure all arrays have the right shape
- if f_mean.ndim > 1:
- f_mean = f_mean.flatten()
- if f_std.ndim > 1:
- f_std = f_std.flatten()
-
- f_lower = f_mean - 1.96 * f_std # 95% confidence interval
- f_upper = f_mean + 1.96 * f_std
-
- return f_mean, f_lower, f_upper, f_pred_bootstrap
-f_mean, f_lower, f_upper, f_pred_bootstrap = plot_polynomial_bootstrap_confidence(x, y, x_pred, degree=3)
-
-
-
-
-
-
-
-
-Figure: Bootstrap confidence intervals for a cubic polynomial fit to Olympic marathon data. The shaded region shows the 95% confidence interval, and individual bootstrap fits are shown in light green.
-
-
-The confidence intervals show the uncertainty in our predictions. The width of the confidence interval reflects the variance of the model - wider intervals indicate higher variance. This visualization helps us understand not just the point predictions but also the reliability of those predictions.
-The bootstrap method provides a powerful way to estimate bias and variance without needing to know the true underlying function. By resampling from our training data, we can approximate how our model would perform on different samples from the same distribution, giving us insights into the bias-variance tradeoff.
-This analysis is particularly valuable for model selection - we can choose the polynomial degree that minimizes the total error (bias + variance) rather than just the training error.
-Bias Variance Decomposition
-
-One of Breiman’s ideas for improving predictive performance is known as bagging (Breiman, 1996). The idea is to train a number of models on the data such that they overfit (high variance). Then average the predictions of these models. The models are trained on different bootstrap samples (Efron, 1979) and their predictions are aggregated giving us the acronym, Bagging. By combining decision trees with bagging, we recover random forests (Breiman, 2001).
-Bias and variance can also be estimated through Efron’s bootstrap (Efron, 1979), and the traditional view has been that there’s a form of Goldilocks effect, where the best predictions are given by the model that is ‘just right’ for the amount of data available. Not to simple, not too complex. The idea is that bias decreases with increasing model complexity and variance increases with increasing model complexity. Typically plots begin with the Mummy bear on the left (too much bias) end with the Daddy bear on the right (too much variance) and show a dip in the middle where the Baby bear (just) right finds themselves.
-The Daddy bear is typically positioned at the point where the model can exactly interpolate the data. For a generalized linear model (McCullagh and Nelder, 1989), this is the point at which the number of parameters is equal to the number of data1.
-The bias-variance decomposition (Geman et al., 1992) considers the expected test error for different variations of the training data sampled from, \(\mathbb{P}(\mathbf{ x}, y)\) \[\begin{align*}
+W_hat = bootstrap_fit(Phi, y, num_bootstraps)
Phi_pred = mlai.polynomial(x_pred, **poly_args)
+f_pred = Phi_pred@W_hatFigure: Fit of a 9 degree polynomial to the olympic marathon data.
16th Degree Polynomial Fit
Now we’ll try a 16th degree polynomial fit to the data.
poly_args = {'num_basis':17, # basis up to x^16
+             'data_limits':xlim}
+Phi = mlai.polynomial(x, **poly_args)
+W_hat = bootstrap_fit(Phi, y, num_bootstraps)
Phi_pred = mlai.polynomial(x_pred, **poly_args)
+f_pred = Phi_pred@W_hatFigure: Fit of a 16 degree polynomial to the olympic marathon data.
Bootstrap Confidence Intervals
We can also use the bootstrap to create confidence intervals for our predictions, showing the uncertainty in our model.
def plot_polynomial_bootstrap_confidence(x, y, x_pred, degree=3, num_bootstraps=50):
+    """Plot bootstrap confidence intervals for polynomial fit.
+
+    :param x: training inputs
+    :param y: training outputs
+    :param x_pred: prediction points
+    :param degree: polynomial degree
+    :param num_bootstraps: number of bootstrap samples
+    """
+    poly_args = {'num_basis': degree + 1, 'data_limits': xlim}
+    Phi = mlai.polynomial(x, **poly_args)
+    W_hat = bootstrap_fit(Phi, y, num_bootstraps)
+
+    Phi_pred = mlai.polynomial(x_pred, **poly_args)
+    f_pred_bootstrap = Phi_pred @ W_hat  # Shape: (n_pred_points, n_bootstrap_samples)
+
+    # Transpose to get shape (n_bootstrap_samples, n_pred_points)
+    f_pred_bootstrap = f_pred_bootstrap.T
+
+    # Compute confidence intervals
+    f_mean = np.mean(f_pred_bootstrap, axis=0)  # Mean across bootstrap samples
+    f_std = np.std(f_pred_bootstrap, axis=0)    # Std across bootstrap samples
+
+    # Ensure all arrays have the right shape
+    if f_mean.ndim > 1:
+        f_mean = f_mean.flatten()
+    if f_std.ndim > 1:
+        f_std = f_std.flatten()
+
+    f_lower = f_mean - 1.96 * f_std  # 95% confidence interval
+    f_upper = f_mean + 1.96 * f_std
+
+    return f_mean, f_lower, f_upper, f_pred_bootstrap
f_mean, f_lower, f_upper, f_pred_bootstrap = plot_polynomial_bootstrap_confidence(x, y, x_pred, degree=3)Figure: Bootstrap confidence intervals for a cubic polynomial fit to Olympic marathon data. The shaded region shows the 95% confidence interval, and individual bootstrap fits are shown in light green.
The confidence intervals show the uncertainty in our predictions. The width of the confidence interval reflects the variance of the model - wider intervals indicate higher variance. This visualization helps us understand not just the point predictions but also the reliability of those predictions.
The bootstrap method provides a powerful way to estimate bias and variance without needing to know the true underlying function. By resampling from our training data, we can approximate how our model would perform on different samples from the same distribution, giving us insights into the bias-variance tradeoff.
This analysis is particularly valuable for model selection - we can choose the polynomial degree that minimizes the total error (bias + variance) rather than just the training error.
Bias Variance Decomposition
One of Breiman’s ideas for improving predictive performance is known as bagging (Breiman, 1996). The idea is to train a number of models on the data such that they overfit (high variance). Then average the predictions of these models. The models are trained on different bootstrap samples (Efron, 1979) and their predictions are aggregated giving us the acronym, Bagging. By combining decision trees with bagging, we recover random forests (Breiman, 2001).
Bias and variance can also be estimated through Efron’s bootstrap (Efron, 1979), and the traditional view has been that there’s a form of Goldilocks effect, where the best predictions are given by the model that is ‘just right’ for the amount of data available. Not to simple, not too complex. The idea is that bias decreases with increasing model complexity and variance increases with increasing model complexity. Typically plots begin with the Mummy bear on the left (too much bias) end with the Daddy bear on the right (too much variance) and show a dip in the middle where the Baby bear (just) right finds themselves.
The Daddy bear is typically positioned at the point where the model can exactly interpolate the data. For a generalized linear model (McCullagh and Nelder, 1989), this is the point at which the number of parameters is equal to the number of data1.
The bias-variance decomposition (Geman et al., 1992) considers the expected test error for different variations of the training data sampled from, \(\mathbb{P}(\mathbf{ x}, y)\) \[\begin{align*} R(\mathbf{ w}) = & \int \left(y- f^*(\mathbf{ x})\right)^2 \mathbb{P}(y, \mathbf{ x}) \text{d}y\text{d}\mathbf{ x}\\ & \triangleq \mathbb{E}\left[ \left(y- f^*(\mathbf{ x})\right)^2 \right]. -\end{align*}\]
-This can be decomposed into two parts, \[ +\end{align*}\]
This can be decomposed into two parts, \[ \begin{align*} \mathbb{E}\left[ \left(y- f(\mathbf{ x})\right)^2 \right] = & \text{bias}\left[f^*(\mathbf{ x})\right]^2 + \text{variance}\left[f^*(\mathbf{ x})\right] +\sigma^2, \end{align*} \] where the bias is given by \[ \text{bias}\left[f^*(\mathbf{ x})\right] = \mathbb{E}\left[f^*(\mathbf{ x})\right] - f(\mathbf{ x}) -\] and it summarizes error that arises from the model’s inability to represent the underlying complexity of the data. For example, if we were to model the marathon pace of the winning runner from the Olympics by computing the average pace across time, then that model would exhibit bias error because the reality of Olympic marathon pace is it is changing (typically getting faster).
-The variance term is given by \[ +\] and it summarizes error that arises from the model’s inability to represent the underlying complexity of the data. For example, if we were to model the marathon pace of the winning runner from the Olympics by computing the average pace across time, then that model would exhibit bias error because the reality of Olympic marathon pace is it is changing (typically getting faster).
The variance term is given by \[ \text{variance}\left[f^*(\mathbf{ x})\right] = \mathbb{E}\left[\left(f^*(\mathbf{ x}) - \mathbb{E}\left[f^*(\mathbf{ x})\right]\right)^2\right]. - \] The variance term is often described as arising from a model that is too complex, but we must be careful with this idea. Is the model really too complex relative to the real world that generates the data? The real world is a complex place, and it is rare that we are constructing mathematical models that are more complex than the world around us. Rather, the ‘too complex’ refers to ability to estimate the parameters of the model given the data we have. Slight variations in the training set cause changes in prediction.
-Models that exhibit high variance are sometimes said to ‘overfit’ the data whereas models that exhibit high bias are sometimes described as ‘underfitting’ the data.
-Also related on generalization error is the so called ‘no free lunch theorem,’ which refers to our inability to decide what a better learning algorithm is without making assumptions about the data (Wolpert, 1996) (see also Wolpert (2002)).
-Regularisation
- -The solution to the linear system is given by solving, \[ + \] The variance term is often described as arising from a model that is too complex, but we must be careful with this idea. Is the model really too complex relative to the real world that generates the data? The real world is a complex place, and it is rare that we are constructing mathematical models that are more complex than the world around us. Rather, the ‘too complex’ refers to ability to estimate the parameters of the model given the data we have. Slight variations in the training set cause changes in prediction.
Models that exhibit high variance are sometimes said to ‘overfit’ the data whereas models that exhibit high bias are sometimes described as ‘underfitting’ the data.
Also related on generalization error is the so called ‘no free lunch theorem,’ which refers to our inability to decide what a better learning algorithm is without making assumptions about the data (Wolpert, 1996) (see also Wolpert (2002)).
Regularisation
The solution to the linear system is given by solving, \[ \boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\mathbf{ w}= \boldsymbol{ \Phi}^\top\mathbf{ y} -\] for \(\mathbf{ w}\).
-But if \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\) is not full rank, this system cannot be solved. This is reflective of an underdetermined system of equations. There are infinite solutions. This happens when there are more basis functions than data points, in effect the number of data we have is not enough to determine the parameters.
-Thinking about this in terms of the Hessian, if \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\) is not full rank, then we are no longer at a minimum. We are in a trough, because not full rank implies that there are fewer eigenvectors than dimensions, in effect for those dimensions where there is no eigenvector, the objective function is ‘flat.’ It is ambivalent to changes in parameters. This implies there are infinite valid solutions.
-One solution to this problem is to regularise the system.
-Coefficient Shrinkage
-Coefficient shrinkage is a technique where the parameters of the of the model are ‘encouraged’ to be small. In practice this is normally done by augmenting the objective function with a term that keeps the parameters low, typically by penalizing a norm.
-Tikhonov Regularisation
-In neural network models this approach is sometimes called ‘weight decay.’ At every gradient step we reduce the value of the weight a little. This idea comes from an approach called Tikhonov regularization (Tikhonov and Arsenin, 1977), where the objective function is augmented by the L2 norm of the weights, \[ +\] for \(\mathbf{ w}\).
But if \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\) is not full rank, this system cannot be solved. This is reflective of an underdetermined system of equations. There are infinite solutions. This happens when there are more basis functions than data points, in effect the number of data we have is not enough to determine the parameters.
Thinking about this in terms of the Hessian, if \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\) is not full rank, then we are no longer at a minimum. We are in a trough, because not full rank implies that there are fewer eigenvectors than dimensions, in effect for those dimensions where there is no eigenvector, the objective function is ‘flat.’ It is ambivalent to changes in parameters. This implies there are infinite valid solutions.
One solution to this problem is to regularise the system.
Coefficient Shrinkage
Coefficient shrinkage is a technique where the parameters of the of the model are ‘encouraged’ to be small. In practice this is normally done by augmenting the objective function with a term that keeps the parameters low, typically by penalizing a norm.
Tikhonov Regularisation
In neural network models this approach is sometimes called ‘weight decay.’ At every gradient step we reduce the value of the weight a little. This idea comes from an approach called Tikhonov regularization (Tikhonov and Arsenin, 1977), where the objective function is augmented by the L2 norm of the weights, \[ L(\mathbf{ w}) = (\mathbf{ y}- \mathbf{ f})^\top(\mathbf{ y}- \mathbf{ f}) + \alpha\left\Vert \mathbf{W} \right\Vert_2^2 \] with some weighting \(\alpha >0\). This has the effect of changing the Hessian at the minimum to \[ \boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}+ \alpha \mathbf{I} -\] Which is always full rank. The minimal eigenvalues are now given by \(\alpha\).
-Lasso
-Other techniques for regularization based on a norm of the parameters include the Lasso (Tibshirani, 1996), which is an L1 norm of the parameters
-Splines, Functions, Hilbert Kernels
-Regularisation of the parameters has the desired effect of making the solution viable, but it can sometimes be difficult to interpret, particularly if the parameters don’t have any inherent meaning (like in a neural network). An alternative approach is to regularize the function, \(\mathbf{ f}\), directly, (see e.g., Kimeldorf and Wahba (1970) and Wahba (1990)). This is the approach taken by spline models which use energy-based regularisation for \(f(\cdot)\) and also kernel methods such as the support vector machine (Schölkopf and Smola, 2001).
-Training with Noise
- -In practice, and across the last two waves of neural networks, other techniques for regularization have been used which can be seen as perturbing the neural network in some way. For example, in dropout (Srivastava et al., 2014), different basis functions are eliminated from the gradient computation at each gradient update.
-Many of these perturbations have some form of regularizing effect. The exact nature of the effect is not always easy to characterize, but in some cases, we can assess how these manipulations effect the model. For example, Bishop (1995) analyzed training with ‘noisy inputs’ and showed conditions under which it’s equivalent to Tikhonov regularization.
-But in general, these approaches can have different interpretations and they’ve also been related to ensemble learning (e.g. related to bagging or Bayesian approaches).
- -Shallow and Deep Learning
-So far, we have been talking about linear models or shallow learning as we might think of it. Let’s pause for a moment and consider a fully connected deep neural network model to relate the two ideas.
-Deep Neural Network
- -
-Figure: A deep neural network
-
-Figure: A deep neural network. Input nodes are shown at the bottom. Each hidden layer is the result of applying an affine transformation to the previous layer and placing through an activation function.
-Mathematically, each layer of a neural network is given through computing the activation function, \(\phi(\cdot)\), contingent on the previous layer, or the inputs. In this way the activation functions, are composed to generate more complex interactions than would be possible with any single layer. \[ +\] Which is always full rank. The minimal eigenvalues are now given by \(\alpha\).
Lasso
Other techniques for regularization based on a norm of the parameters include the Lasso (Tibshirani, 1996), which is an L1 norm of the parameters
Splines, Functions, Hilbert Kernels
Regularisation of the parameters has the desired effect of making the solution viable, but it can sometimes be difficult to interpret, particularly if the parameters don’t have any inherent meaning (like in a neural network). An alternative approach is to regularize the function, \(\mathbf{ f}\), directly, (see e.g., Kimeldorf and Wahba (1970) and Wahba (1990)). This is the approach taken by spline models which use energy-based regularisation for \(f(\cdot)\) and also kernel methods such as the support vector machine (Schölkopf and Smola, 2001).
Training with Noise
In practice, and across the last two waves of neural networks, other techniques for regularization have been used which can be seen as perturbing the neural network in some way. For example, in dropout (Srivastava et al., 2014), different basis functions are eliminated from the gradient computation at each gradient update.
Many of these perturbations have some form of regularizing effect. The exact nature of the effect is not always easy to characterize, but in some cases, we can assess how these manipulations effect the model. For example, Bishop (1995) analyzed training with ‘noisy inputs’ and showed conditions under which it’s equivalent to Tikhonov regularization.
But in general, these approaches can have different interpretations and they’ve also been related to ensemble learning (e.g. related to bagging or Bayesian approaches).
Shallow and Deep Learning
So far, we have been talking about linear models or shallow learning as we might think of it. Let’s pause for a moment and consider a fully connected deep neural network model to relate the two ideas.
Deep Neural Network
Figure: A deep neural network
Figure: A deep neural network. Input nodes are shown at the bottom. Each hidden layer is the result of applying an affine transformation to the previous layer and placing through an activation function.
Mathematically, each layer of a neural network is given through computing the activation function, \(\phi(\cdot)\), contingent on the previous layer, or the inputs. In this way the activation functions, are composed to generate more complex interactions than would be possible with any single layer. \[ \begin{align*} \mathbf{ h}_{1} &= \phi\left(\mathbf{W}_1 \mathbf{ x}\right)\\ \mathbf{ h}_{2} &= \phi\left(\mathbf{W}_2\mathbf{ h}_{1}\right)\\ \mathbf{ h}_{3} &= \phi\left(\mathbf{W}_3 \mathbf{ h}_{2}\right)\\ f&= \mathbf{ w}_4 ^\top\mathbf{ h}_{3} \end{align*} -\]
-Under our basis function perspective, we can see that our deep neural network is mathematical composition of basis function models. Each layer contains a separate basis function set, so \[ +\]
Under our basis function perspective, we can see that our deep neural network is mathematical composition of basis function models. Each layer contains a separate basis function set, so \[ f(\mathbf{ x}; \mathbf{W}) = \mathbf{ w}_4 ^\top\phi\left(\mathbf{W}_3 \phi\left(\mathbf{W}_2\phi\left(\mathbf{W}_1 \mathbf{ x}\right)\right)\right). -\]
-In this course there are two reasons for looking at the shallow model. Firstly, it is easier to introduce the concepts of regularisation in the linear model regime. Secondly, the matrix forms we see, e.g., expressions like \(\boldsymbol{ \Phi}^\top \boldsymbol{ \Phi}\), appear in both models.
-For deep learning, we can no longer optimize the parameters of the model through solving a linear system2. Instead, we need to turn to non-linear optimization algorithms. For deep learning, that’s typically stochastic gradient descent.
-While it’s possible to compute the Hessian in a neural network, Bishop (1992), we also find that it varies across the parameter space and will not normally be positive definite. In practice, the number of parameters is normally so large that storing the Hessian is impossible (it has quadratic cost in the number of weights/parameters) due to memory constraints.
-This means that while the theory of minima in optimization is well understood, empirical experiments with large neural networks are hard and the lessons of small models do not all translate to the very large systems.
-We can stay within the framework of linear models but take a step closer to neural network models by introducing functions that are non-linear in the inputs, \(\mathbf{ x}\), known as basis functions.
-Overparameterised Systems
-If we could examine the Hessian of a neural network at its minimum, we can speculate about what we would find. In particular, we would find that it would have very many low (or negative) eigenvalues in many directions. This is indicative of the parameters being badly determined because of the neural network model being heavily overparameterized. So how does it generalize?
-Simply put, there is not enough regularization encoded in the objective function of the neural network models we are using to explain the generalization performance. There must be something in the algorithms we are using that causes these highly overparameterized models to generalise well.
-Double Descent
- - -
-
Figure: Left traditional perspective on generalization. There is a sweet spot of operation where the training error is still non-zero. Overfitting occurs when the variance increases. Right The double descent phenomenon, the modern models operate in an interpolation regime where they reconstruct the training data fully but are well regularized in their interpolations for test data. Figure from Belkin et al. (2019).
-But the modern empirical finding is that when we move beyond Daddy bear, into the dark forest of the massively overparameterized model we can achieve good generalization. Indeed, recent work is showing that large language models are even memorizing data (Carlini et al., 2020) like non-parametric models do.
-As Zhang et al. (2017) starkly illustrated with their random labels experiment, within the dark forest there are some terrible places, big bad wolves of overfitting that will gobble up your model. But as empirical evidence shows there is also a safe and hospitable Grandma’s house where these highly overparameterized models are safely consumed. Fundamentally, it must be about the route you take through the forest, and the precautions you take to ensure the wolf doesn’t see where you’re going and beat you to the door.
-There are two implications of this empirical result. Firstly, that there is a great deal of new theory that needs to be developed. Secondly, that theory is now obliged to conflate two aspects to modelling that we generally like to keep separate: the model and the algorithm.
-Classical statistical theory around predictive generalization focusses specifically on the class of models that is being used for data fitting. Historically, whether that theory follows a Fisher-aligned estimation approach (see e.g., Vapnik (1998)) or model-based Bayesian approach (see e.g., Ghahramani (2015)), neither is fully equipped to deal with these new circumstances because, to continue our rather tortured analogy, these theories provide us with a characterization of the destination of the algorithm, and seek to ensure that we reach that destination. Modern machine learning requires theories of the journey and what our route through the forest should be.
-Crucially, the destination is always associated with 100% accuracy on the training set. An objective that is always achievable for the overparameterized model.
-Intuitively, it seems that a highly overparameterized model places Grandma’s house on the edge of the dark forest. Making it easily and quickly accessible to the algorithm. The larger the model, the more exposed Grandma’s house becomes. Perhaps this is due to some form of blessing of dimensionality brings Grandma’s house closer to the edge of the forest in a high dimensional setting. Really, we should think of Grandma’s house as a low dimensional manifold of destinations that are safe. A path through the forest where the wolf of overfitting doesn’t venture. In the GLM case, we know already that when the number of parameters matches the number of data there is precisely one location in parameter space where accuracy on the training data is 100%. Our previous misunderstanding of generalization stemmed from the fact that (seemingly) it is highly unlikely that this single point is a good place to be from the perspective of generalization. Additionally, it is often difficult to find. Finding the precise polynomial coefficients in a least squares regression to exactly fit the basis to a small data set such as the Olympic marathon data requires careful consideration of the numerical properties and an orthogonalization of the design matrix (Lawson and Hanson, 1995).
-It seems that with a highly overparameterized model, these locations become easier to find and they provide good generalization properties. In machine learning this is known as the “double descent phenomenon” (see e.g., Belkin et al. (2019)).
- -See also this talk by Misha Belkin: http://www.ipam.ucla.edu/abstract/?tid=15552&pcode=GLWS4 and these related papers https://www.pnas.org/content/116/32/15849.short, https://www.pnas.org/content/117/20/10625
-Neural Tangent Kernel
- -Another approach to analysis exploits the fact that optimization is occurring in a very high dimensional parameter space. By considering initializations that involve small random weights (known as the NTK initialization) and noting that small updates in the learning mean that the model doesn’t move far from this initialization (Jacot et al., 2018).
-For very wide neural networks, when these conditions are fulfilled, the network can be approximately represented by a kernel known as the neural tangent kernel. A kernel is a regularizer that operates in function space rather than feature space.
-Regularization in Optimization
- -Another interesting theoretical direction is to study the path that neural network algorithms take when finding the optima. For certain simple linear systems, you can analytically study the ‘gradient flow.’
-Neural networks are normally trained by (stochastic) gradient descent. This is a discrete optimization algorithm where at each point, a step in the direction of the (approximate) gradient is taken.
-Gradient flow replaces this discrete update with a differential equation, where the step at any point is an exact gradient update. As a result, the path of the optimization can be studied as a differential equation.
-By making assumptions about the initialization, the optimum that gradient flow will find can be characterised. For a highly overparameterized linear model, Gunasekar et al. (2017) show in matrix factorization, that for particular initializations, the optimum will be a global optimum of the objective that minimizes the L2-norm.
-By reparameterizing the linear model so that each \(w_i = u_i^2 - v_i^2\) and optimising in the space defined by \(\mathbf{u}\) and \(\mathbf{v}\) Woodworth et al. (2020) show that the L1 norm is found.
-Other papers have looked at deep linear models (Arora et al., 2019) where \[ +\]
In this course there are two reasons for looking at the shallow model. Firstly, it is easier to introduce the concepts of regularisation in the linear model regime. Secondly, the matrix forms we see, e.g., expressions like \(\boldsymbol{ \Phi}^\top \boldsymbol{ \Phi}\), appear in both models.
For deep learning, we can no longer optimize the parameters of the model through solving a linear system2. Instead, we need to turn to non-linear optimization algorithms. For deep learning, that’s typically stochastic gradient descent.
While it’s possible to compute the Hessian in a neural network, Bishop (1992), we also find that it varies across the parameter space and will not normally be positive definite. In practice, the number of parameters is normally so large that storing the Hessian is impossible (it has quadratic cost in the number of weights/parameters) due to memory constraints.
This means that while the theory of minima in optimization is well understood, empirical experiments with large neural networks are hard and the lessons of small models do not all translate to the very large systems.
We can stay within the framework of linear models but take a step closer to neural network models by introducing functions that are non-linear in the inputs, \(\mathbf{ x}\), known as basis functions.
Overparameterised Systems
If we could examine the Hessian of a neural network at its minimum, we can speculate about what we would find. In particular, we would find that it would have very many low (or negative) eigenvalues in many directions. This is indicative of the parameters being badly determined because of the neural network model being heavily overparameterized. So how does it generalize?
Simply put, there is not enough regularization encoded in the objective function of the neural network models we are using to explain the generalization performance. There must be something in the algorithms we are using that causes these highly overparameterized models to generalise well.
Double Descent
Figure: Left traditional perspective on generalization. There is a sweet spot of operation where the training error is still non-zero. Overfitting occurs when the variance increases. Right The double descent phenomenon, the modern models operate in an interpolation regime where they reconstruct the training data fully but are well regularized in their interpolations for test data. Figure from Belkin et al. (2019).
But the modern empirical finding is that when we move beyond Daddy bear, into the dark forest of the massively overparameterized model we can achieve good generalization. Indeed, recent work is showing that large language models are even memorizing data (Carlini et al., 2020) like non-parametric models do.
As Zhang et al. (2017) starkly illustrated with their random labels experiment, within the dark forest there are some terrible places, big bad wolves of overfitting that will gobble up your model. But as empirical evidence shows there is also a safe and hospitable Grandma’s house where these highly overparameterized models are safely consumed. Fundamentally, it must be about the route you take through the forest, and the precautions you take to ensure the wolf doesn’t see where you’re going and beat you to the door.
There are two implications of this empirical result. Firstly, that there is a great deal of new theory that needs to be developed. Secondly, that theory is now obliged to conflate two aspects to modelling that we generally like to keep separate: the model and the algorithm.
Classical statistical theory around predictive generalization focusses specifically on the class of models that is being used for data fitting. Historically, whether that theory follows a Fisher-aligned estimation approach (see e.g., Vapnik (1998)) or model-based Bayesian approach (see e.g., Ghahramani (2015)), neither is fully equipped to deal with these new circumstances because, to continue our rather tortured analogy, these theories provide us with a characterization of the destination of the algorithm, and seek to ensure that we reach that destination. Modern machine learning requires theories of the journey and what our route through the forest should be.
Crucially, the destination is always associated with 100% accuracy on the training set. An objective that is always achievable for the overparameterized model.
Intuitively, it seems that a highly overparameterized model places Grandma’s house on the edge of the dark forest. Making it easily and quickly accessible to the algorithm. The larger the model, the more exposed Grandma’s house becomes. Perhaps this is due to some form of blessing of dimensionality brings Grandma’s house closer to the edge of the forest in a high dimensional setting. Really, we should think of Grandma’s house as a low dimensional manifold of destinations that are safe. A path through the forest where the wolf of overfitting doesn’t venture. In the GLM case, we know already that when the number of parameters matches the number of data there is precisely one location in parameter space where accuracy on the training data is 100%. Our previous misunderstanding of generalization stemmed from the fact that (seemingly) it is highly unlikely that this single point is a good place to be from the perspective of generalization. Additionally, it is often difficult to find. Finding the precise polynomial coefficients in a least squares regression to exactly fit the basis to a small data set such as the Olympic marathon data requires careful consideration of the numerical properties and an orthogonalization of the design matrix (Lawson and Hanson, 1995).
It seems that with a highly overparameterized model, these locations become easier to find and they provide good generalization properties. In machine learning this is known as the “double descent phenomenon” (see e.g., Belkin et al. (2019)).
See also this talk by Misha Belkin: http://www.ipam.ucla.edu/abstract/?tid=15552&pcode=GLWS4 and these related papers https://www.pnas.org/content/116/32/15849.short, https://www.pnas.org/content/117/20/10625
Neural Tangent Kernel
Another approach to analysis exploits the fact that optimization is occurring in a very high dimensional parameter space. By considering initializations that involve small random weights (known as the NTK initialization) and noting that small updates in the learning mean that the model doesn’t move far from this initialization (Jacot et al., 2018).
For very wide neural networks, when these conditions are fulfilled, the network can be approximately represented by a kernel known as the neural tangent kernel. A kernel is a regularizer that operates in function space rather than feature space.
Regularization in Optimization
Another interesting theoretical direction is to study the path that neural network algorithms take when finding the optima. For certain simple linear systems, you can analytically study the ‘gradient flow.’
Neural networks are normally trained by (stochastic) gradient descent. This is a discrete optimization algorithm where at each point, a step in the direction of the (approximate) gradient is taken.
Gradient flow replaces this discrete update with a differential equation, where the step at any point is an exact gradient update. As a result, the path of the optimization can be studied as a differential equation.
By making assumptions about the initialization, the optimum that gradient flow will find can be characterised. For a highly overparameterized linear model, Gunasekar et al. (2017) show in matrix factorization, that for particular initializations, the optimum will be a global optimum of the objective that minimizes the L2-norm.
By reparameterizing the linear model so that each \(w_i = u_i^2 - v_i^2\) and optimising in the space defined by \(\mathbf{u}\) and \(\mathbf{v}\) Woodworth et al. (2020) show that the L1 norm is found.
Other papers have looked at deep linear models (Arora et al., 2019) where \[ f(\mathbf{ x}; \mathbf{W}) = \mathbf{W}_4 \mathbf{W}_3 \mathbf{W}_2 \mathbf{W}_1 \mathbf{ x}. \] In these models, a gradient flow analysis shows that the model finds solutions where the linear mapping, \[ \mathbf{W}= \mathbf{W}_4 \mathbf{W}_3 \mathbf{W}_2 \mathbf{W}_1 -\] is very low rank. This is highly suggestive of another type of regularization that could be occurring in deep neural networks. Low rank parameter matrices mean that the effective capacity of the neural network is reduced. Indeed, empirical observations of the rank of deep nets trained on data suggest that they may be finding such solutions.
-Thanks!
-For more information on these subjects and more you might want to check the following resources.
--
-
- company: Trent AI -
- book: The Atomic Human -
- twitter: @lawrennd -
- podcast: The Talking Machines -
- newspaper: Guardian Profile Page -
- blog: http://inverseprobability.com -
References
-bootstrap
-David Hogg’s lecture https://speakerdeck.com/dwhgg/linear-regression-with-huge-numbers-of-parameters
-The Deep Bootstrap https://twitter.com/PreetumNakkiran/status/1318007088321335297?s=20
-Aki Vehtari on Leave One Out Uncertainty: https://arxiv.org/abs/2008.10296 (check for his references).
-- -
 \n",
+ "
 \n",
"\n",
"Figure: A deep neural network\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: A deep neural network. Input nodes are shown at the bottom.\n",
"Each hidden layer is the result of applying an affine transformation to\n",
@@ -3367,8 +3392,6 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "::: {.cell .markdown}\n",
- "\n",
"## References\n",
"\n",
"bootstrap\n",
diff --git a/requirements-smoke.txt b/requirements-smoke.txt
new file mode 100644
index 0000000..fb9c4ad
--- /dev/null
+++ b/requirements-smoke.txt
@@ -0,0 +1,28 @@
+# Runtime + execution harness for lecture notebook smoke tests.
+# Install: pip install -r requirements-smoke.txt
+
+# Notebook execution
+nbclient>=0.10,<1
+nbformat>=5.10,<6
+ipykernel>=6.29
+ipywidgets>=8.1
+ipython>=8.0
+
+# Teaching stack (match lecture %pip install cells)
+GPy>=1.13
+git+https://github.com/lawrennd/mlai.git#egg=mlai
+git+https://github.com/lawrennd/ods.git#egg=pods
+git+https://github.com/lawrennd/notutils.git#egg=notutils
+
+# Used by lecture notebooks
+matplotlib>=3.8
+numpy>=1.26
+scipy>=1.11
+pandas>=2.0
+scikit-learn>=1.3
+scikit-image>=0.22
+Pillow>=10.0
+PyYAML>=6.0
+plotly>=5.0
+requests>=2.31
+daft-pgm>=0.1
diff --git a/scripts/smoke.yml b/scripts/smoke.yml
new file mode 100644
index 0000000..d61e393
--- /dev/null
+++ b/scripts/smoke.yml
@@ -0,0 +1,14 @@
+# Course-specific notebook smoke defaults (scripts/smoke_notebooks.py).
+# skip: filename prefixes to omit. plot_dirs: extra dirs created under _notebooks.
+# timeout_by_prefix: optional per-prefix cell timeouts in seconds.
+skip:
+ - 01-02-tmp # leftover compile artefact
+ - 01-02-01-background # orphan split; not in lectures.csv
+ - 01-02-02-background # orphan split; not in lectures.csv
+ - 01-02-03-background # orphan split; not in lectures.csv
+ - 02-01-automatic-differentiation # needs jax, not in the shared smoke env
+ - 03-02-assignment # student assignment; needs torch
+ - 05-02-assignment # student assignment; needs torch
+plot_dirs: []
+timeout: 900
+timeout_by_prefix: {}
diff --git a/scripts/smoke_notebooks.py b/scripts/smoke_notebooks.py
new file mode 100755
index 0000000..786edef
--- /dev/null
+++ b/scripts/smoke_notebooks.py
@@ -0,0 +1,568 @@
+#!/usr/bin/env python3
+"""Execute lecture notebooks end-to-end for smoke testing.
+
+Shared runner for mlatcl courses. Course-specific defaults live in
+``scripts/smoke.yml`` (skip list, extra plot dirs, per-prefix timeouts).
+
+Always-on CI behaviour (each patch is try/except, so unused stacks are fine):
+ - matplotlib Agg backend
+ - mock stdin
+ - short-circuit ipywidgets.interact / notutils.display_plots
+ - cap GPy / DeepGP optimize iterations
+ - execute ``%load -n module.attr`` by importing the name
+ - fill student name / live-rating placeholders
+ - blank incomplete exercise cells that are not valid Python
+
+Usage (from repo root)::
+
+ python scripts/smoke_notebooks.py
+ python scripts/smoke_notebooks.py --only 01
+ python scripts/smoke_notebooks.py --skip 03-02 05-02
+"""
+
+from __future__ import annotations
+
+import argparse
+import ast
+import json
+import os
+import re
+import sys
+import time
+import traceback
+from copy import deepcopy
+from pathlib import Path
+
+import nbformat
+from nbclient import NotebookClient
+from nbclient.exceptions import CellExecutionError
+
+DEFAULT_CONFIG = Path("scripts/smoke.yml")
+
+# Created relative to the notebooks directory. Extra dirs can be listed in smoke.yml.
+DEFAULT_PLOT_DIRS = (
+ "./datasets",
+ "./data-science",
+ "./dimred",
+ "./gp",
+ "./gplvm",
+ "./kern",
+ "./ml",
+ "./mlai",
+ "./deepgp",
+ "./deepnn",
+ "./nn",
+ "./cnn",
+ "./simulation",
+ "./uq",
+ "./iei",
+ "./dsa",
+)
+
+_LOAD_MAGIC = re.compile(r"^%load\s+-n\s+([\w.]+)\s*$")
+
+
+def _plot_dirs_literal(dirs: list[str]) -> str:
+ items = ",\n ".join(repr(d) for d in dirs)
+ return f"(\n {items},\n)"
+
+
+def build_prelude(plot_dirs: list[str]) -> str:
+ return f'''
+import builtins
+import numpy as np
+import pandas as pd
+import scipy as sp
+
+if not hasattr(np, "NaN"):
+ np.NaN = np.nan
+if not hasattr(np, "trapz") and hasattr(np, "trapezoid"):
+ np.trapz = np.trapezoid
+
+
+def _mock_input(prompt=""):
+ p = str(prompt).lower()
+ if "distance" in p:
+ print(f"[mock input] {{prompt!r}} -> 50.0")
+ return "50.0"
+ if (
+ (not prompt)
+ or ("yes" in p)
+ or ("proceed" in p)
+ or ("continue" in p)
+ or ("[y/n]" in p)
+ or ("[yes/no]" in p)
+ ):
+ print(f"[mock input] {{prompt!r}} -> y")
+ return "y"
+ print(f"[mock input] {{prompt!r}} -> 1.0")
+ return "1.0"
+
+
+builtins.input = _mock_input
+try:
+ ip = get_ipython()
+ if ip is not None and getattr(ip, "kernel", None) is not None:
+ ip.kernel._allow_stdin = True
+ ip.kernel.raw_input = _mock_input
+except Exception as e:
+ print("stdin patch skipped", e)
+
+import matplotlib
+
+matplotlib.use("Agg")
+
+from pathlib import Path as _Path
+
+for _d in {_plot_dirs_literal(plot_dirs)}:
+ _Path(_d).mkdir(parents=True, exist_ok=True)
+
+
+def _once_interact(func=None, **kwargs):
+ if func is None:
+ return lambda f: _once_interact(f, **kwargs)
+ call = {{}}
+ for k, v in kwargs.items():
+ if hasattr(v, "value"):
+ call[k] = v.value
+ elif (
+ isinstance(v, tuple)
+ and len(v) >= 2
+ and all(isinstance(x, (int, float)) for x in v[:3] if not isinstance(x, bool))
+ ):
+ call[k] = v[0]
+ else:
+ call[k] = v
+ try:
+ return func(**call)
+ except Exception as e:
+ print("[smoke] interact once failed:", e)
+
+
+try:
+ import ipywidgets
+
+ ipywidgets.interact = _once_interact
+ ipywidgets.interact_manual = _once_interact
+except Exception as e:
+ print("ipywidgets patch skipped", e)
+
+try:
+ import notutils
+
+ notutils.display_plots = lambda *a, **k: print(
+ "[smoke] skip display_plots", a[:1] if a else ""
+ )
+ if hasattr(notutils, "display_prediction"):
+
+ def _skip_pred(*a, **k):
+ print("[smoke] skip display_prediction")
+
+ notutils.display_prediction = _skip_pred
+except Exception as e:
+ print("notutils patch skipped", e)
+
+try:
+ import pods
+
+ def _skip_pods_method(name):
+ def _skip(*a, **k):
+ print(f"[smoke] skip pods.notebook.{{name}}", a[:1] if a else "")
+
+ return _skip
+
+ class _PodsNotebook:
+ def __getattr__(self, name):
+ return _skip_pods_method(name)
+
+ if getattr(pods, "notebook", None) is None:
+ pods.notebook = _PodsNotebook()
+ else:
+ for _name in (
+ "display_plots",
+ "display_prediction",
+ "display_google_book",
+ ):
+ setattr(pods.notebook, _name, _skip_pods_method(_name))
+except Exception as e:
+ print("pods.notebook patch skipped", e)
+
+
+def _cap_optimize(cls, method_name="optimize", max_iters=40):
+ if not hasattr(cls, method_name):
+ return
+ orig = getattr(cls, method_name)
+
+ def wrapped(self, *args, **kwargs):
+ if "max_iters" in kwargs and kwargs["max_iters"] is not None:
+ kwargs["max_iters"] = min(int(kwargs["max_iters"]), max_iters)
+ else:
+ kwargs["max_iters"] = max_iters
+ if "messages" in kwargs:
+ kwargs["messages"] = False
+ if "max_f_eval" in kwargs and kwargs["max_f_eval"] is not None:
+ kwargs["max_f_eval"] = min(int(kwargs["max_f_eval"]), max_iters)
+ return orig(self, *args, **kwargs)
+
+ setattr(cls, method_name, wrapped)
+
+
+try:
+ import GPy
+
+ _cap_optimize(GPy.core.gp.GP, "optimize", 40)
+except Exception as e:
+ print("GPy patch skipped", e)
+
+try:
+ import deepgp
+
+ if hasattr(deepgp, "DeepGP"):
+ _cap_optimize(deepgp.DeepGP, "optimize", 25)
+ if hasattr(deepgp.DeepGP, "staged_optimize"):
+ orig = deepgp.DeepGP.staged_optimize
+
+ def staged(self, *args, **kwargs):
+ kwargs["messages"] = False
+ if "iters" in kwargs:
+ it = kwargs["iters"]
+ if isinstance(it, (list, tuple)):
+ kwargs["iters"] = tuple(min(int(x), 15) for x in it)
+ return orig(self, *args, **kwargs)
+
+ deepgp.DeepGP.staged_optimize = staged
+except Exception as e:
+ print("deepgp patch skipped", e)
+
+try:
+ import sys as _sys
+ from pathlib import Path as _Cwd
+
+ _here = str(_Cwd.cwd().resolve())
+ _cwd_entries = [
+ p
+ for p in _sys.path
+ if p in ("", ".") or str(_Cwd(p).resolve()) == _here
+ ]
+ # Vendored _notebooks/mlai.py otherwise shadows the installed package.
+ _sys.path = [p for p in _sys.path if p not in _cwd_entries]
+ import mlai
+ _sys.path[:0] = _cwd_entries or [""]
+ from mlai import linear_models as _lm
+
+ for _name in ("relu", "hyperbolic_tangent"):
+ if not hasattr(mlai, _name) and hasattr(_lm, _name):
+ setattr(mlai, _name, getattr(_lm, _name))
+ print(f"[smoke] attached mlai.{{_name}} from linear_models")
+
+ _write_figure = mlai.write_figure
+
+ def _write_figure_diagrams(filename, figure=None, directory=None, frameon=None, **kwargs):
+ if directory is None:
+ directory = kwargs.pop("diagrams", None)
+ else:
+ kwargs.pop("diagrams", None)
+ return _write_figure(
+ filename, figure=figure, directory=directory, frameon=frameon, **kwargs
+ )
+
+ mlai.write_figure = _write_figure_diagrams
+except Exception as e:
+ print("mlai basis attach skipped", e)
+
+try:
+ import plotly.io as pio
+
+ pio.renderers.default = "json"
+except Exception as e:
+ print("plotly renderer patch skipped", e)
+'''
+
+
+def load_config(path: Path) -> dict:
+ if not path.is_file():
+ return {}
+ try:
+ import yaml
+ except ImportError:
+ print(f"PyYAML missing; ignoring {path}", file=sys.stderr)
+ return {}
+ data = yaml.safe_load(path.read_text()) or {}
+ if not isinstance(data, dict):
+ raise SystemExit(f"smoke config must be a mapping: {path}")
+ return data
+
+
+def _cell_source(cell) -> str:
+ src = cell.get("source", "")
+ if isinstance(src, list):
+ src = "".join(src)
+ return src
+
+
+def expand_load_magics(nb: nbformat.NotebookNode) -> None:
+ """Execute `%load -n module.attr` by importing the name."""
+ for cell in nb.cells:
+ if cell.get("cell_type") != "code":
+ continue
+ lines = [
+ ln
+ for ln in _cell_source(cell).strip().splitlines()
+ if ln.strip() and not ln.strip().startswith("#")
+ ]
+ if len(lines) != 1:
+ continue
+ match = _LOAD_MAGIC.match(lines[0].strip())
+ if not match:
+ continue
+ target = match.group(1)
+ if "." not in target:
+ continue
+ mod_name, attr = target.rsplit(".", 1)
+ cell["source"] = (
+ f"# smoke: execute `%load -n {target}`\n"
+ f"from {mod_name} import {attr}\n"
+ )
+
+
+def patch_student_placeholders(nb: nbformat.NotebookNode) -> None:
+ dummy_ratings = (
+ "Y = pd.DataFrame({\n"
+ " 'user': ['smoke-a', 'smoke-a', 'smoke-b', 'smoke-b', 'smoke-c', 'smoke-c'],\n"
+ " 'film': ['Inception', 'Avatar', 'Inception', 'Titanic', 'Avatar', 'Titanic'],\n"
+ " 'rating': [8, 7, 9, 6, 5, 8],\n"
+ "})\n"
+ )
+ for cell in nb.cells:
+ if cell.get("cell_type") != "code":
+ continue
+ src = _cell_source(cell)
+ changed = False
+ if re.search(r"assert\s+name\s*!=\s*['\"]todo['\"]", src):
+ src = re.sub(r"name\s*=\s*['\"]todo['\"]", "name = 'smoke-test'", src, count=1)
+ src = re.sub(
+ r"assert\s+name\s*!=\s*['\"]todo['\"]",
+ "pass # smoke: student name placeholder",
+ src,
+ count=1,
+ )
+ changed = True
+ if re.search(r"^Y\s*=\s*responses\(\)\s*$", src, re.M):
+ src = re.sub(
+ r"^Y\s*=\s*responses\(\)\s*$",
+ dummy_ratings.rstrip(),
+ src,
+ count=1,
+ flags=re.M,
+ )
+ changed = True
+ if changed:
+ cell["source"] = src
+
+
+def blank_incomplete_exercises(nb: nbformat.NotebookNode) -> None:
+ for cell in nb.cells:
+ if cell.get("cell_type") != "code":
+ continue
+ src = _cell_source(cell)
+ if "Write code for you answer" not in src and "Write your answer to Exercise" not in src:
+ continue
+ try:
+ ast.parse(src)
+ except SyntaxError:
+ if "w_cov" in src and "w_mean" in src:
+ cell["source"] = (
+ "# smoke: Bayesian linear-model posterior from lecture formulae\n"
+ "sigma2 = 0.01\n"
+ "w_cov = np.linalg.inv(Phi.T @ Phi / sigma2 + np.eye(Phi.shape[1]) / alpha)\n"
+ "w_mean = w_cov @ (Phi.T @ y) / sigma2\n"
+ )
+ else:
+ cell["source"] = "# skipped incomplete exercise cell for smoke test\npass\n"
+
+
+def prepare(nb: nbformat.NotebookNode, plot_dirs: list[str]) -> nbformat.NotebookNode:
+ nb = deepcopy(nb)
+ blank_incomplete_exercises(nb)
+ expand_load_magics(nb)
+ patch_student_placeholders(nb)
+ nb.cells.insert(0, nbformat.v4.new_code_cell(build_prelude(plot_dirs)))
+ return nb
+
+
+def _matches_token(name: str, token: str) -> bool:
+ token = token.strip()
+ return bool(token) and (name.startswith(token) or name == token)
+
+
+def list_notebooks(nb_dir: Path, only: list[str] | None, skip: list[str] | None) -> list[str]:
+ names = sorted(p.name for p in nb_dir.glob("[0-9][0-9]-*.ipynb"))
+ if only:
+ selected = []
+ for token in only:
+ matches = [n for n in names if _matches_token(n, token)]
+ if not matches:
+ raise SystemExit(f"No notebook matches --only {token!r} under {nb_dir}")
+ for m in matches:
+ if m not in selected:
+ selected.append(m)
+ else:
+ selected = names
+ skip = skip or []
+ kept = []
+ for name in selected:
+ skipped = next((tok for tok in skip if _matches_token(name, tok)), None)
+ if skipped is not None:
+ print(f"[smoke] skip {name} (--skip {skipped})", flush=True)
+ continue
+ kept.append(name)
+ return kept
+
+
+def timeout_for(name: str, default: int, by_prefix: dict[str, int]) -> int:
+ best_key = ""
+ best_val = default
+ for prefix, value in by_prefix.items():
+ if name.startswith(str(prefix)) and len(str(prefix)) >= len(best_key):
+ best_key = str(prefix)
+ best_val = int(value)
+ return best_val
+
+
+def run_one(
+ name: str,
+ nb_dir: Path,
+ out_dir: Path,
+ timeout: int,
+ plot_dirs: list[str],
+) -> dict:
+ path = nb_dir / name
+ print(f"\n======== {name} ========", flush=True)
+ t0 = time.time()
+ try:
+ nb = nbformat.read(path, as_version=4)
+ nb = prepare(nb, plot_dirs)
+ client = NotebookClient(
+ nb,
+ timeout=timeout,
+ kernel_name="python3",
+ resources={"metadata": {"path": str(nb_dir)}},
+ allow_errors=False,
+ allow_stdin=True,
+ )
+ client.execute()
+ elapsed = time.time() - t0
+ print(f"OK ({elapsed:.1f}s)", flush=True)
+ (out_dir / f"{name}.ok").write_text(f"OK {elapsed:.1f}s\n")
+ fail = out_dir / f"{name}.fail"
+ if fail.exists():
+ fail.unlink()
+ return {"name": name, "status": "OK", "elapsed": elapsed, "error": ""}
+ except CellExecutionError as e:
+ elapsed = time.time() - t0
+ msg = str(e)
+ print(f"FAIL ({elapsed:.1f}s)\n{msg[:4000]}", flush=True)
+ (out_dir / f"{name}.fail").write_text(msg)
+ return {"name": name, "status": "FAIL", "elapsed": elapsed, "error": msg}
+ except Exception:
+ elapsed = time.time() - t0
+ msg = traceback.format_exc()
+ print(f"ERROR ({elapsed:.1f}s)\n{msg[:4000]}", flush=True)
+ (out_dir / f"{name}.fail").write_text(msg)
+ return {"name": name, "status": "ERROR", "elapsed": elapsed, "error": msg}
+
+
+def main(argv: list[str] | None = None) -> int:
+ parser = argparse.ArgumentParser(description=__doc__)
+ parser.add_argument(
+ "--config",
+ type=Path,
+ default=DEFAULT_CONFIG,
+ help="YAML with skip / plot_dirs / timeout_by_prefix (default: scripts/smoke.yml)",
+ )
+ parser.add_argument(
+ "--notebooks-dir",
+ type=Path,
+ default=Path("_notebooks"),
+ help="Directory containing NN-*.ipynb lecture notebooks",
+ )
+ parser.add_argument(
+ "--results-dir",
+ type=Path,
+ default=Path("_notebooks/test-results"),
+ help="Where to write .ok/.fail markers and summary JSON",
+ )
+ parser.add_argument(
+ "--only",
+ nargs="+",
+ default=None,
+ help="Restrict to notebooks whose names start with these prefixes (e.g. 01 12)",
+ )
+ parser.add_argument(
+ "--skip",
+ nargs="*",
+ default=None,
+ help="Skip notebooks whose names start with these prefixes. "
+ "Default comes from scripts/smoke.yml. Pass --skip with no values to run all.",
+ )
+ parser.add_argument(
+ "--timeout",
+ type=int,
+ default=None,
+ help="Per-notebook cell execution timeout in seconds (default 900, or smoke.yml)",
+ )
+ parser.add_argument(
+ "--summary-name",
+ default="summary.json",
+ help="Summary JSON filename under --results-dir",
+ )
+ args = parser.parse_args(argv)
+
+ cfg = load_config(args.config)
+ skip = args.skip if args.skip is not None else list(cfg.get("skip") or [])
+ timeout = args.timeout if args.timeout is not None else int(cfg.get("timeout") or 900)
+ extra_dirs = [str(d) for d in (cfg.get("plot_dirs") or [])]
+ plot_dirs = list(dict.fromkeys([*DEFAULT_PLOT_DIRS, *extra_dirs]))
+ by_prefix = {str(k): int(v) for k, v in (cfg.get("timeout_by_prefix") or {}).items()}
+
+ repo_root = Path.cwd()
+ nb_dir = (repo_root / args.notebooks_dir).resolve()
+ out_dir = (repo_root / args.results_dir).resolve()
+ out_dir.mkdir(parents=True, exist_ok=True)
+
+ mpl_dir = out_dir / "mpl"
+ mpl_dir.mkdir(parents=True, exist_ok=True)
+ os.environ.setdefault("MPLBACKEND", "Agg")
+ os.environ.setdefault("JUPYTER_PLATFORM_DIRS", "1")
+ os.environ.setdefault("MPLCONFIGDIR", str(mpl_dir))
+
+ if not nb_dir.is_dir():
+ print(f"Notebooks directory not found: {nb_dir}", file=sys.stderr)
+ return 2
+
+ print(f"[smoke] config={args.config} skip={skip} timeout={timeout}", flush=True)
+ order = list_notebooks(nb_dir, args.only, skip)
+ print("Notebooks:", order, flush=True)
+
+ results = []
+ for name in order:
+ result = run_one(
+ name,
+ nb_dir,
+ out_dir,
+ timeout_for(name, timeout, by_prefix),
+ plot_dirs,
+ )
+ results.append(result)
+ (out_dir / args.summary_name).write_text(json.dumps(results, indent=2) + "\n")
+
+ print("\n==== SUMMARY ====")
+ for r in results:
+ print(f"{r['status']:5} {r['elapsed']:7.1f}s {r['name']}")
+ n_ok = sum(r["status"] == "OK" for r in results)
+ print(f"{n_ok}/{len(results)} passed")
+ return 0 if n_ok == len(results) and results else 1
+
+
+if __name__ == "__main__":
+ raise SystemExit(main())
diff --git a/slides/01-02-generalisation-and-neural-networks.slides.html b/slides/01-02-generalisation-and-neural-networks.slides.html
index a442a58..3b26f67 100644
--- a/slides/01-02-generalisation-and-neural-networks.slides.html
+++ b/slides/01-02-generalisation-and-neural-networks.slides.html
@@ -91,8 +91,10 @@
code span.vs { color: #4070a0; } /* VerbatimString */
code span.wa { color: #60a0b0; font-weight: bold; font-style: italic; } /* Warning */
-
-
+
+
+
+
-
-
-
+ }
+ function bind() {
+ if (bound) return typeof Reveal !== "undefined";
+ if (typeof Reveal === "undefined" || typeof Reveal.addEventListener !== "function") return false;
+ Reveal.addEventListener("ready", syncSlideScale);
+ window.addEventListener("resize", function () {
+ setTimeout(syncSlideScale, 0);
+ setTimeout(syncSlideScale, 50);
+ });
+ bound = true;
+ return true;
+ }
+ var n = 0;
+ var t = setInterval(function () {
+ bind();
+ /* Keep polling until getScale() works — Reveal exists before initialize. */
+ if (syncSlideScale() || ++n > 200) clearInterval(t);
+ }, 50);
+ })();
+
+
