Figure: Data Science Africa https://datascienceafrica.org is a ground up initiative for capacity building around data science, machine learning and artificial intelligence on the African continent.
Figure: Data Science Africa https://datascienceafrica.org is a ground up initiative for capacity building around data science, machine learning and artificial intelligence on the African continent.
Figure: Data Science Africa meetings held up to October 2021.
Data Science Africa is a bottom up initiative for capacity building in data science, machine learning and artificial intelligence on the African continent.
As of June 2025 there have been thirteen workshops and schools, located in seven different countries: Nyeri, Kenya (three times); Kampala, Uganda; Arusha, Tanzania (twice); Abuja, Nigeria; Addis Ababa, Ethiopia; Accra, Ghana; Kampala, Uganda and Kimberley, South Africa (virtual), Kigali, Rwanda and Ibadan, Nigeria.
Figure: Organiser’s video from Data Science Africa held in Ibadan, Nigeria from 2nd to 6th June 2025
The main notion is end-to-end data science. For example, going from data collection in the farmer’s field to decision making in the Ministry of Agriculture. Or going from malaria disease counts in health centers to medicine distribution.
The philosophy is laid out in (Lawrence, 2015). The key idea is that the modern information infrastructure presents new solutions to old problems. Modes of development change because less capital investment is required to take advantage of this infrastructure. The philosophy is that local capacity building is the right way to leverage these challenges in addressing data science problems in the African context.
Data Science Africa is now a non-govermental organization registered in Kenya. The organising board of the meeting is entirely made up of scientists and academics based on the African continent.
Figure: The lack of existing physical infrastructure on the African continent makes it a particularly interesting environment for deploying solutions based on the information infrastructure. The idea is explored more in this Guardian op-ed on Guardian article on How African can benefit from the data revolution.
Guardian article on Data Science Africa
As an example of using Gaussian process models within the full pipeline from data to decsion, we’ll consider the prediction of Malaria incidence in Uganda. For the purposes of this study malaria reports come in two forms, HMIS reports from health centres and Sentinel data, which is curated by the WHO. There are limited sentinel sites and many HMIS sites.
The work is from Ricardo Andrade Pacheco’s PhD thesis, completed in collaboration with John Quinn and Martin Mubangizi (Andrade-Pacheco et al., 2014; Mubangizi et al., 2014). John and Martin were initally from the AI-DEV group from the University of Makerere in Kampala and more latterly they were based at UN Global Pulse in Kampala. You can see the work summarized on the UN Global Pulse disease outbreaks project site here.
Malaria data is spatial data. Uganda is split into districts, and health reports can be found for each district. This suggests that models such as conditional random fields could be used for spatial modelling, but there are two complexities with this. First of all, occasionally districts split into two. Secondly, sentinel sites are a specific location within a district, such as Nagongera which is a sentinel site based in the Tororo district.
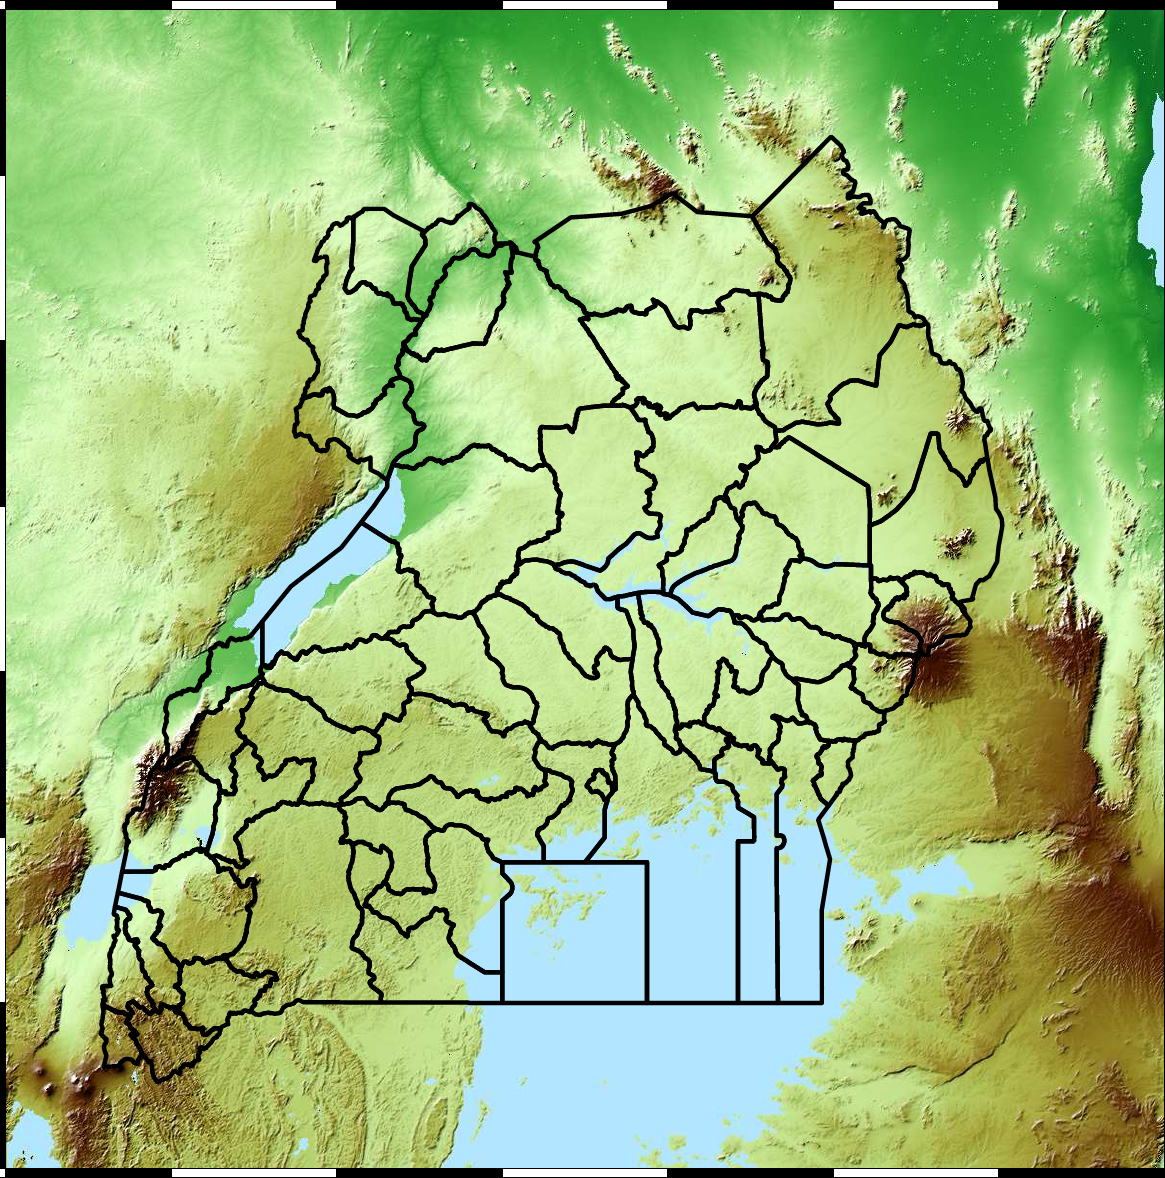
Figure: Ugandan districts. Data SRTM/NASA from https://dds.cr.usgs.gov/srtm/version2_1.
The common standard for collecting health data on the African continent is from the Health management information systems (HMIS). However, this data suffers from missing values (Gething et al., 2006) and diagnosis of diseases like typhoid and malaria may be confounded.
Figure: The Tororo district, where the sentinel site, Nagongera, is located.
World Health Organization Sentinel Surveillance systems are set up “when high-quality data are needed about a particular disease that cannot be obtained through a passive system.” Several sentinel sites give accurate assessment of malaria disease levels in Uganda, including a site in Nagongera.
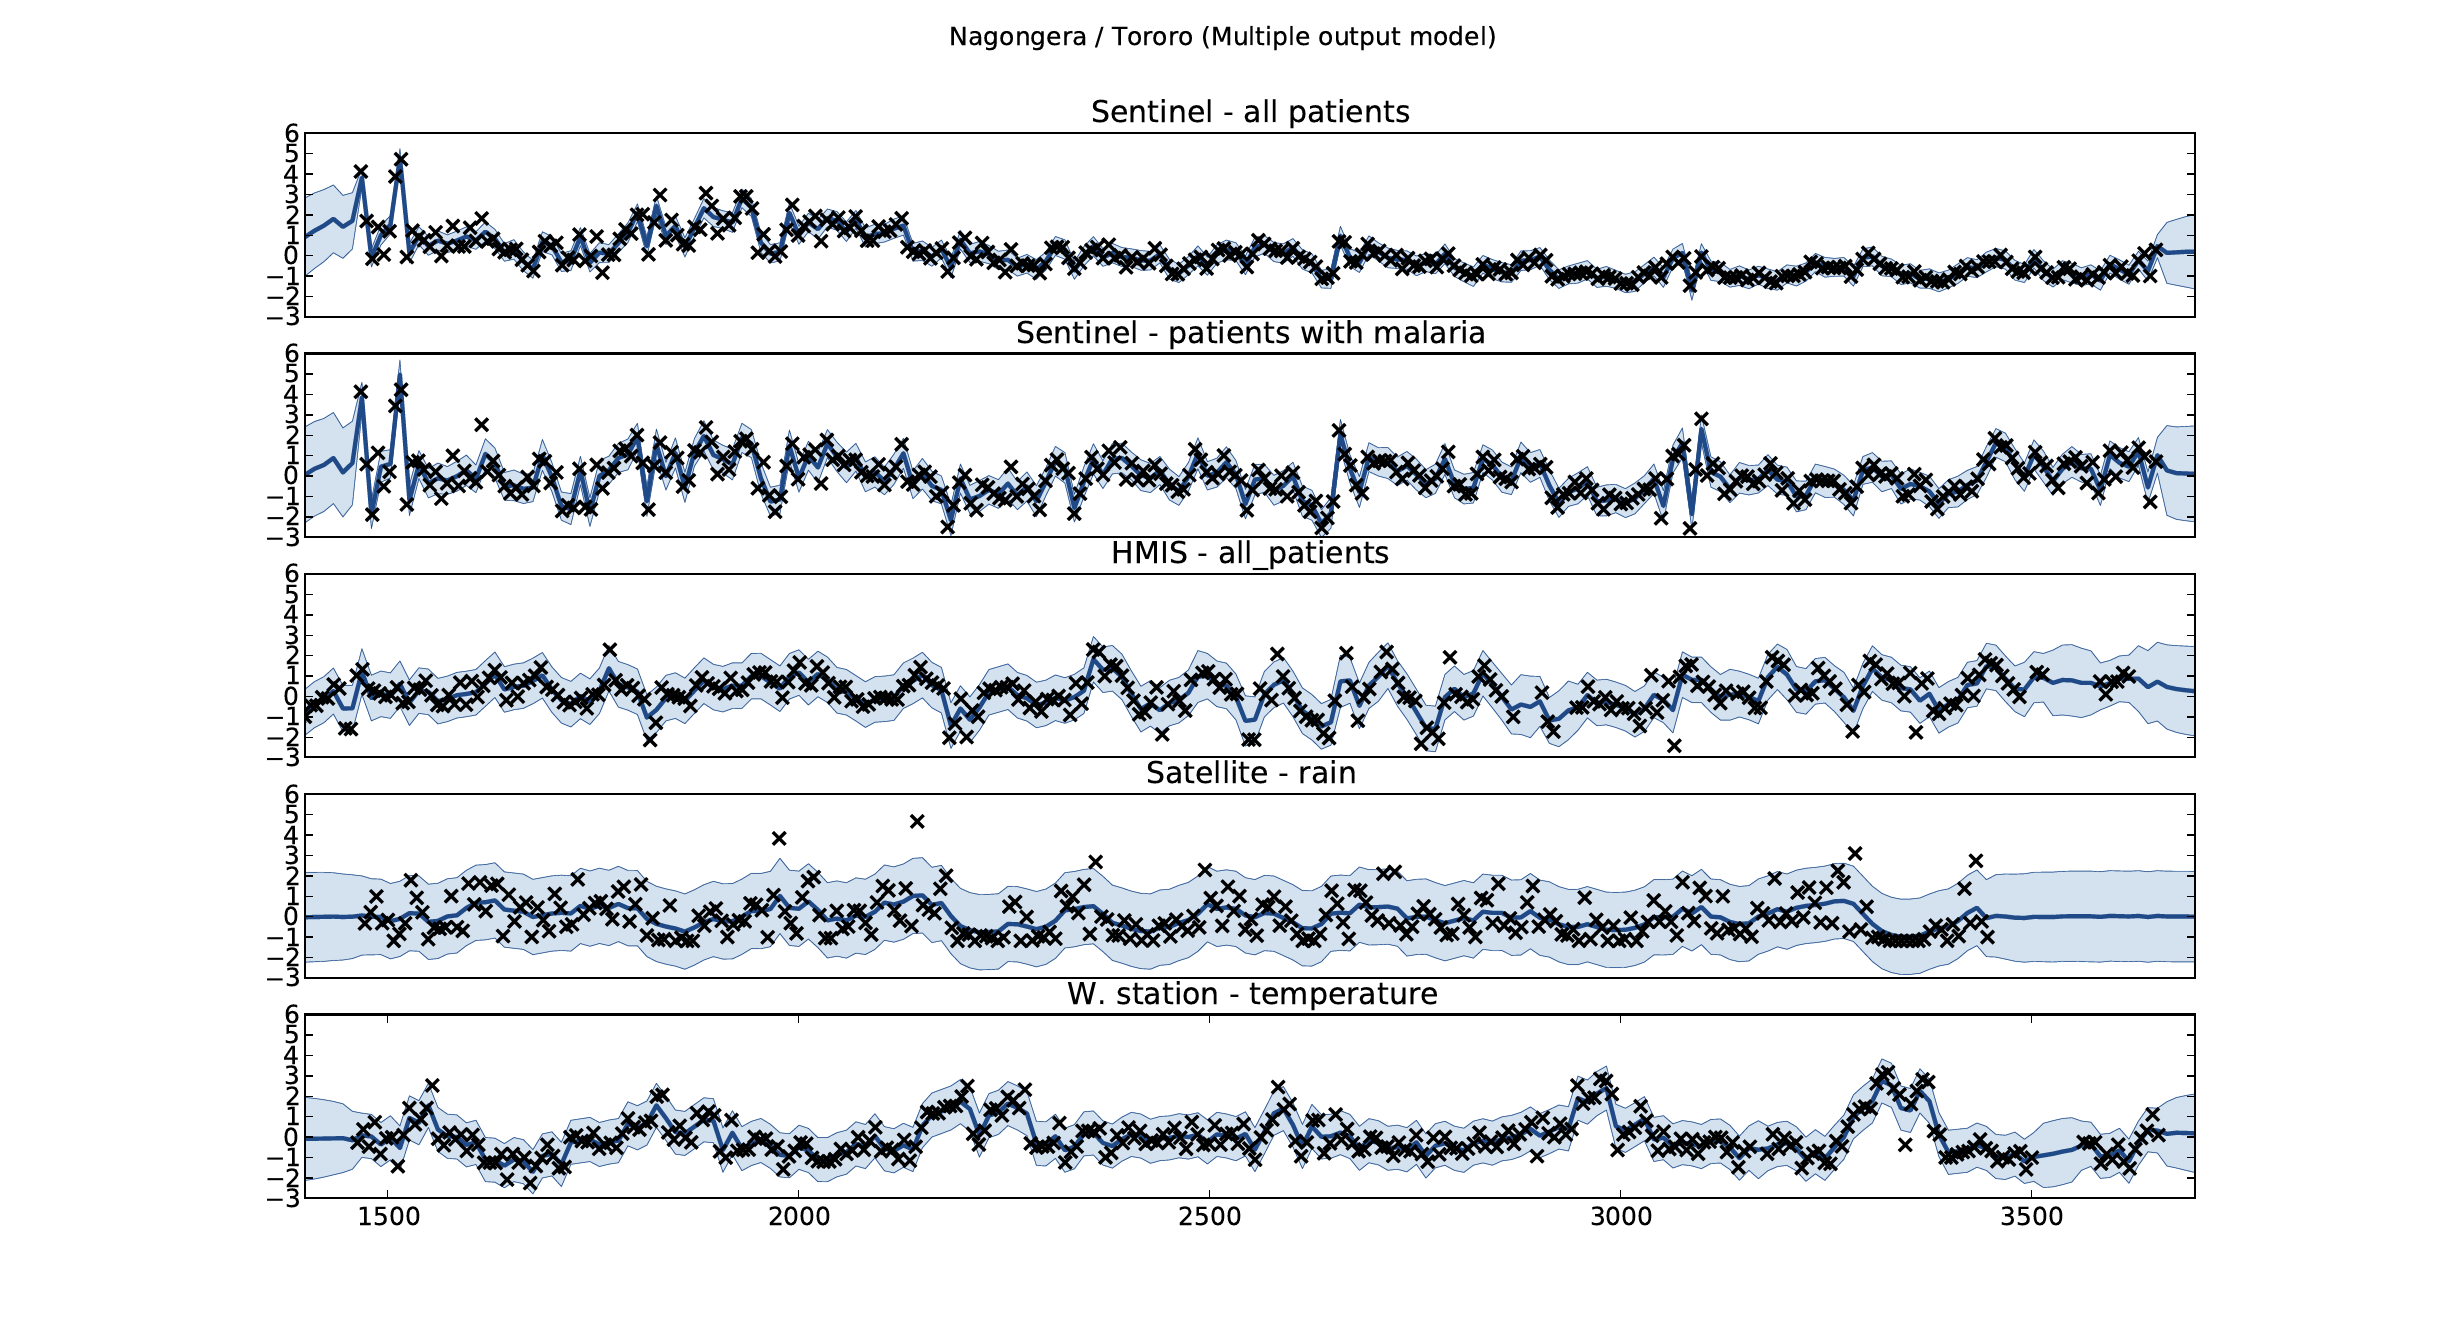
Figure: Sentinel and HMIS data along with rainfall and temperature for the Nagongera sentinel station in the Tororo district.
In collaboration with the AI Research Group at Makerere we chose to investigate whether Gaussian process models could be used to assimilate information from these two different sources of disease informaton. Further, we were interested in whether local information on rainfall and temperature could be used to improve malaria estimates.
The aim of the project was to use WHO Sentinel sites, alongside rainfall and temperature, to improve predictions from HMIS data of levels of malaria.
Figure: The Mubende District.
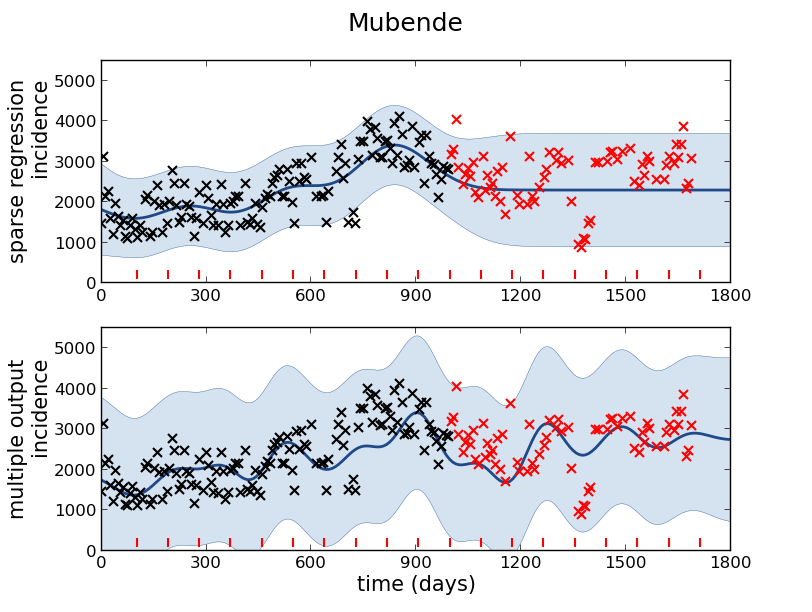
Figure: Prediction of malaria incidence in Mubende.
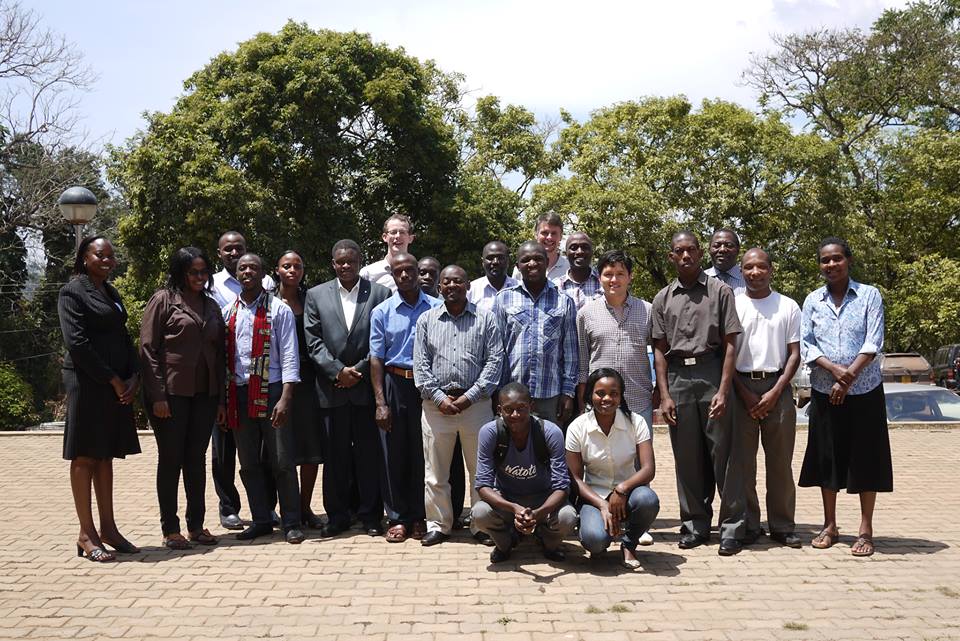
Figure: The project arose out of the Gaussian process summer school held at Makerere in Kampala in 2013. The school led, in turn, to the Data Science Africa initiative.
Figure: The Kabarole district in Uganda.
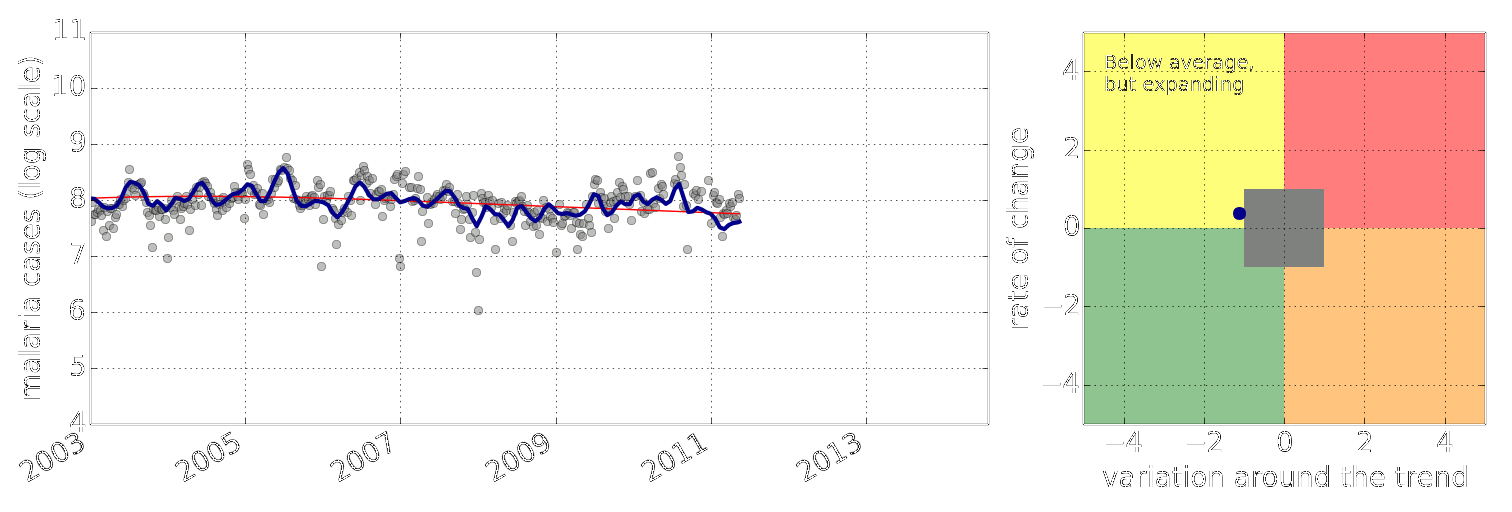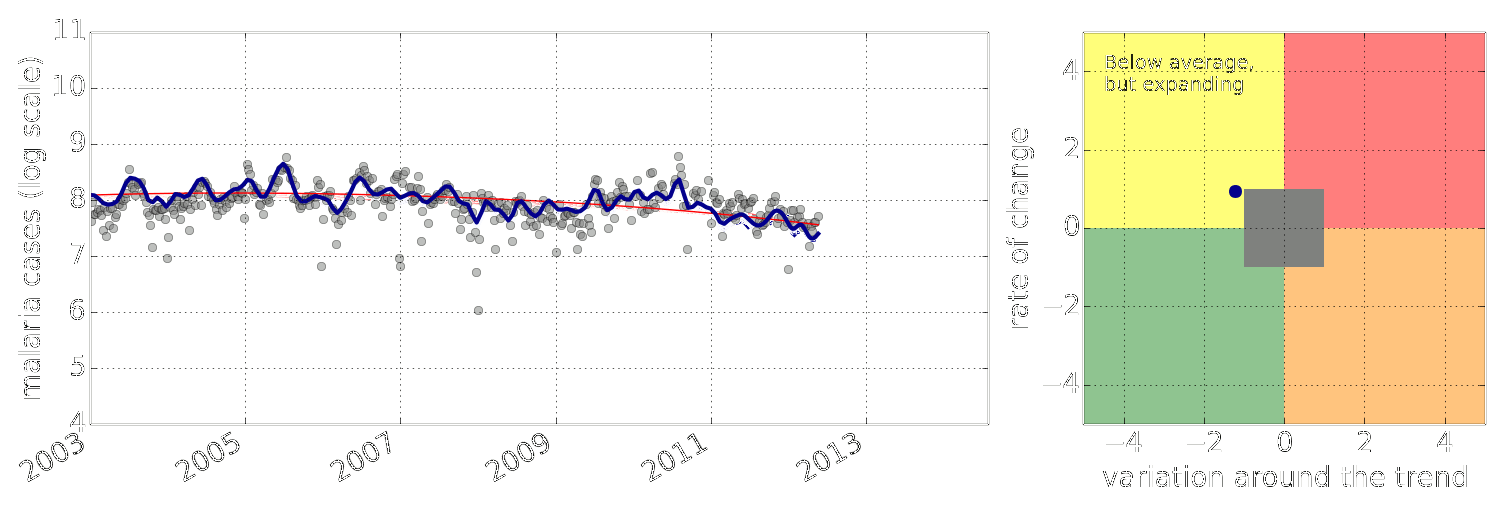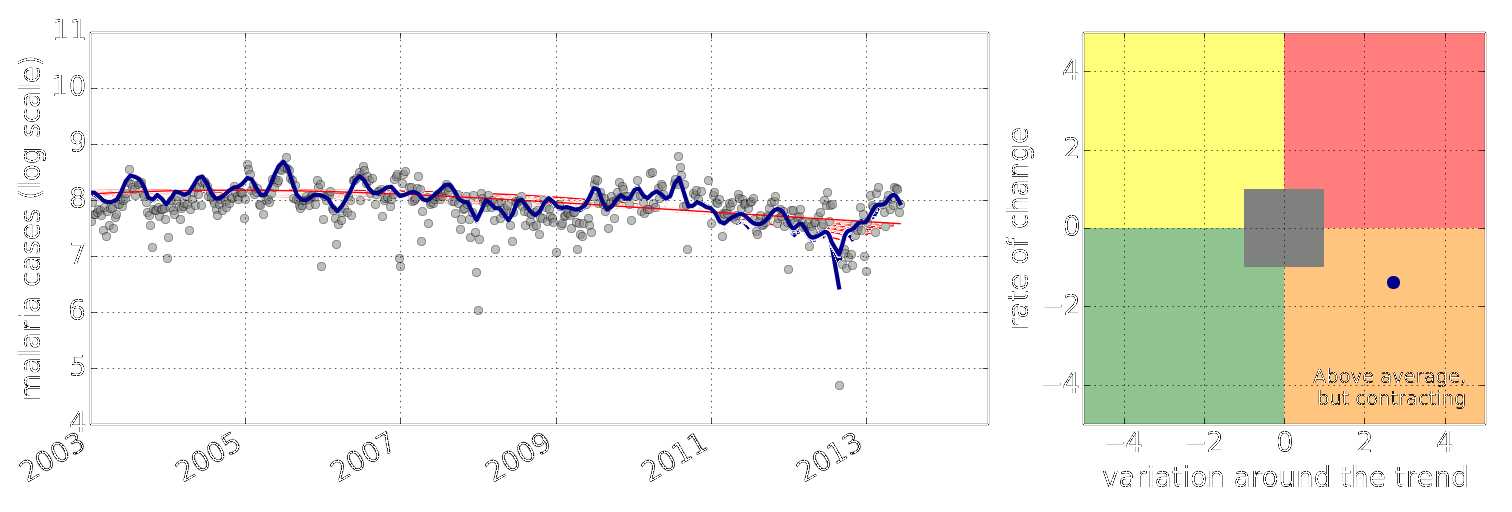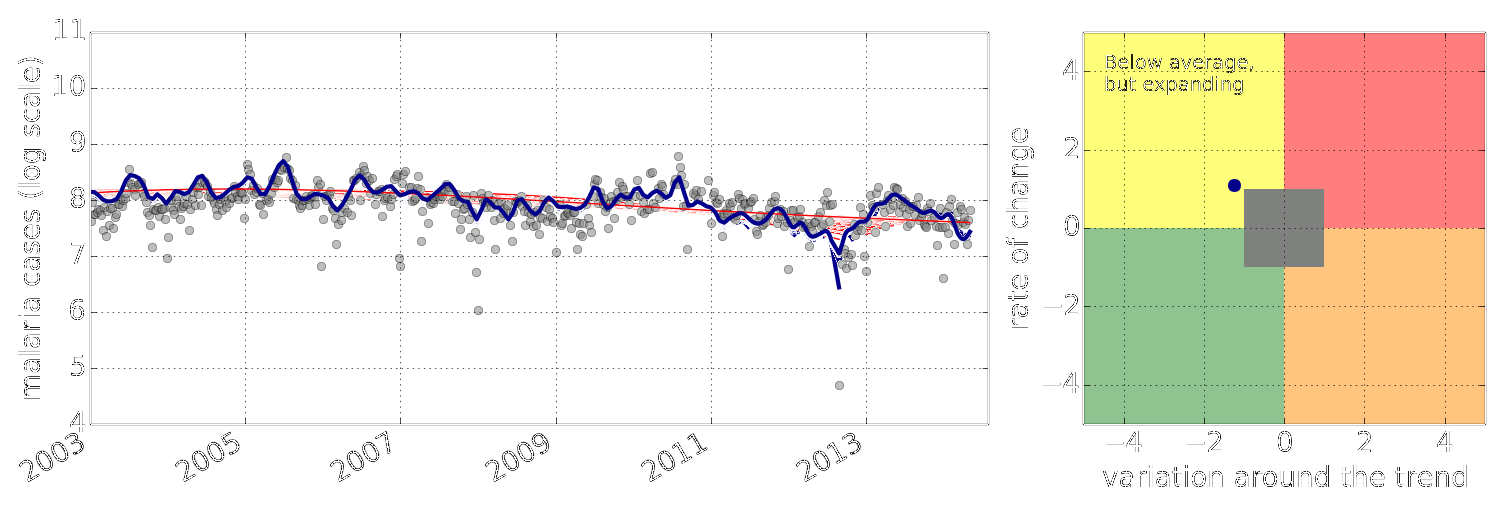
Figure: Estimate of the current disease situation in the Kabarole district over time. Estimate is constructed with a Gaussian process with an additive covariance funciton.
Health monitoring system for the Kabarole district. Here we have fitted the reports with a Gaussian process with an additive covariance function. It has two components, one is a long time scale component (in red above) the other is a short time scale component (in blue).
Monitoring proceeds by considering two aspects of the curve. Is the blue line (the short term report signal) above the red (which represents the long term trend? If so we have higher than expected reports. If this is the case and the gradient is still positive (i.e. reports are going up) we encode this with a red color. If it is the case and the gradient of the blue line is negative (i.e. reports are going down) we encode this with an amber color. Conversely, if the blue line is below the red and decreasing, we color green. On the other hand if it is below red but increasing, we color yellow.
This gives us an early warning system for disease. Red is a bad situation getting worse, amber is bad, but improving. Green is good and getting better and yellow good but degrading.
Finally, there is a gray region which represents when the scale of the effect is small.
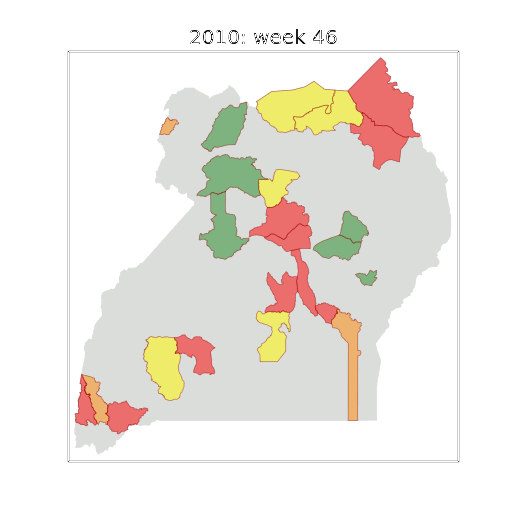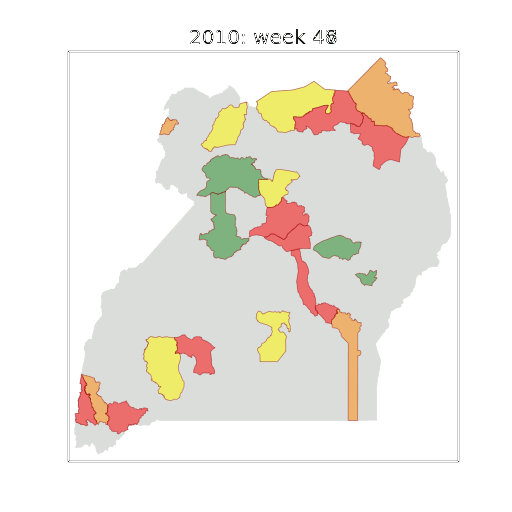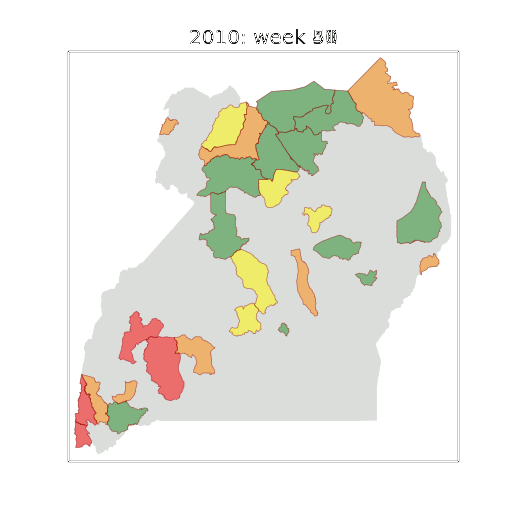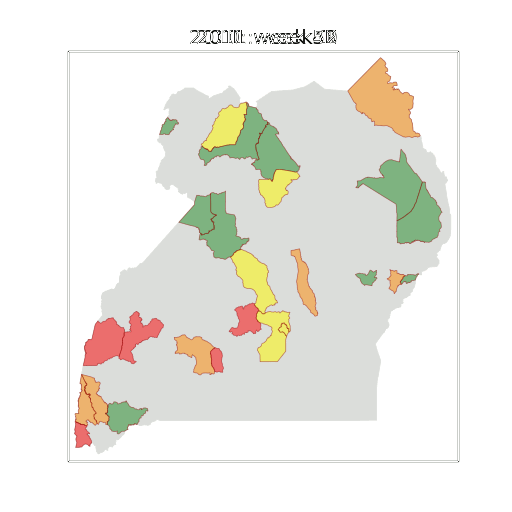
Figure: The map of Ugandan districts with an overview of the Malaria situation in each district.
These colors can now be observed directly on a spatial map of the districts to give an immediate impression of the current status of the disease across the country.
This talk is a general introduction to machine learning, we will highlight the technical challenges and the current solutions. We will give an overview of what is machine learning and why it is important.
Machine learning is the combination of data and models, through computation, to make predictions. \[
+-->
+ Figure: Data Science Africa https://datascienceafrica.org is a ground up initiative for capacity building around data science, machine learning and artificial intelligence on the African continent. Figure: Data Science Africa meetings held up to October 2021. Data Science Africa is a bottom up initiative for capacity building in data science, machine learning and artificial intelligence on the African continent. As of June 2025 there have been thirteen workshops and schools, located in seven different countries: Nyeri, Kenya (three times); Kampala, Uganda; Arusha, Tanzania (twice); Abuja, Nigeria; Addis Ababa, Ethiopia; Accra, Ghana; Kampala, Uganda and Kimberley, South Africa (virtual), Kigali, Rwanda and Ibadan, Nigeria. Figure: Organiser’s video from Data Science Africa held in Ibadan, Nigeria from 2nd to 6th June 2025 The main notion is end-to-end data science. For example, going from data collection in the farmer’s field to decision making in the Ministry of Agriculture. Or going from malaria disease counts in health centers to medicine distribution. The philosophy is laid out in (Lawrence, 2015). The key idea is that the modern information infrastructure presents new solutions to old problems. Modes of development change because less capital investment is required to take advantage of this infrastructure. The philosophy is that local capacity building is the right way to leverage these challenges in addressing data science problems in the African context. Data Science Africa is now a non-govermental organization registered in Kenya. The organising board of the meeting is entirely made up of scientists and academics based on the African continent. Figure: The lack of existing physical infrastructure on the African continent makes it a particularly interesting environment for deploying solutions based on the information infrastructure. The idea is explored more in this Guardian op-ed on Guardian article on How African can benefit from the data revolution. Guardian article on Data Science Africa As an example of using Gaussian process models within the full pipeline from data to decsion, we’ll consider the prediction of Malaria incidence in Uganda. For the purposes of this study malaria reports come in two forms, HMIS reports from health centres and Sentinel data, which is curated by the WHO. There are limited sentinel sites and many HMIS sites. The work is from Ricardo Andrade Pacheco’s PhD thesis, completed in collaboration with John Quinn and Martin Mubangizi (Andrade-Pacheco et al., 2014; Mubangizi et al., 2014). John and Martin were initally from the AI-DEV group from the University of Makerere in Kampala and more latterly they were based at UN Global Pulse in Kampala. You can see the work summarized on the UN Global Pulse disease outbreaks project site here. Malaria data is spatial data. Uganda is split into districts, and health reports can be found for each district. This suggests that models such as conditional random fields could be used for spatial modelling, but there are two complexities with this. First of all, occasionally districts split into two. Secondly, sentinel sites are a specific location within a district, such as Nagongera which is a sentinel site based in the Tororo district. Figure: Ugandan districts. Data SRTM/NASA from https://dds.cr.usgs.gov/srtm/version2_1. The common standard for collecting health data on the African continent is from the Health management information systems (HMIS). However, this data suffers from missing values (Gething et al., 2006) and diagnosis of diseases like typhoid and malaria may be confounded. Figure: The Tororo district, where the sentinel site, Nagongera, is located. World Health Organization Sentinel Surveillance systems are set up “when high-quality data are needed about a particular disease that cannot be obtained through a passive system”. Several sentinel sites give accurate assessment of malaria disease levels in Uganda, including a site in Nagongera. Figure: Sentinel and HMIS data along with rainfall and temperature for the Nagongera sentinel station in the Tororo district. In collaboration with the AI Research Group at Makerere we chose to investigate whether Gaussian process models could be used to assimilate information from these two different sources of disease informaton. Further, we were interested in whether local information on rainfall and temperature could be used to improve malaria estimates. The aim of the project was to use WHO Sentinel sites, alongside rainfall and temperature, to improve predictions from HMIS data of levels of malaria. Figure: The Mubende District. Figure: Prediction of malaria incidence in Mubende. Figure: The project arose out of the Gaussian process summer school held at Makerere in Kampala in 2013. The school led, in turn, to the Data Science Africa initiative. Figure: The Kabarole district in Uganda. Figure: Estimate of the current disease situation in the Kabarole district over time. Estimate is constructed with a Gaussian process with an additive covariance funciton. Health monitoring system for the Kabarole district. Here we have fitted the reports with a Gaussian process with an additive covariance function. It has two components, one is a long time scale component (in red above) the other is a short time scale component (in blue). Monitoring proceeds by considering two aspects of the curve. Is the blue line (the short term report signal) above the red (which represents the long term trend? If so we have higher than expected reports. If this is the case and the gradient is still positive (i.e. reports are going up) we encode this with a red color. If it is the case and the gradient of the blue line is negative (i.e. reports are going down) we encode this with an amber color. Conversely, if the blue line is below the red and decreasing, we color green. On the other hand if it is below red but increasing, we color yellow. This gives us an early warning system for disease. Red is a bad situation getting worse, amber is bad, but improving. Green is good and getting better and yellow good but degrading. Finally, there is a gray region which represents when the scale of the effect is small. Figure: The map of Ugandan districts with an overview of the Malaria situation in each district. These colors can now be observed directly on a spatial map of the districts to give an immediate impression of the current status of the disease across the country. This talk is a general introduction to machine learning, we will highlight the technical challenges and the current solutions. We will give an overview of what is machine learning and why it is important. Machine learning is the combination of data and models, through computation, to make predictions. \[
\text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}
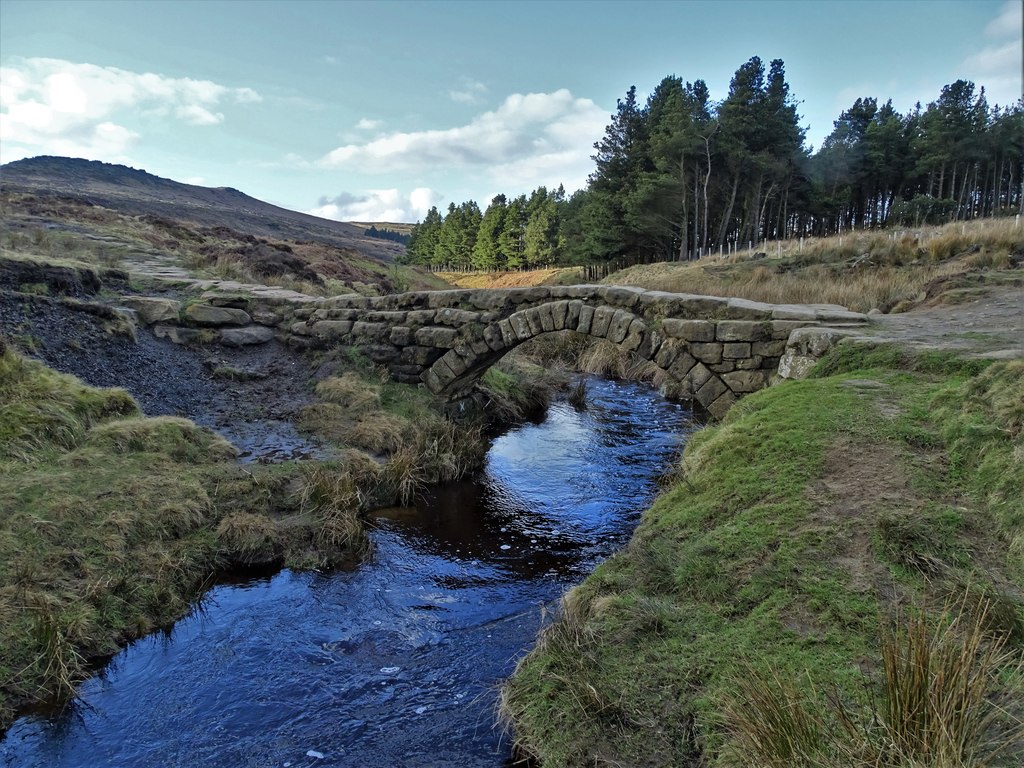
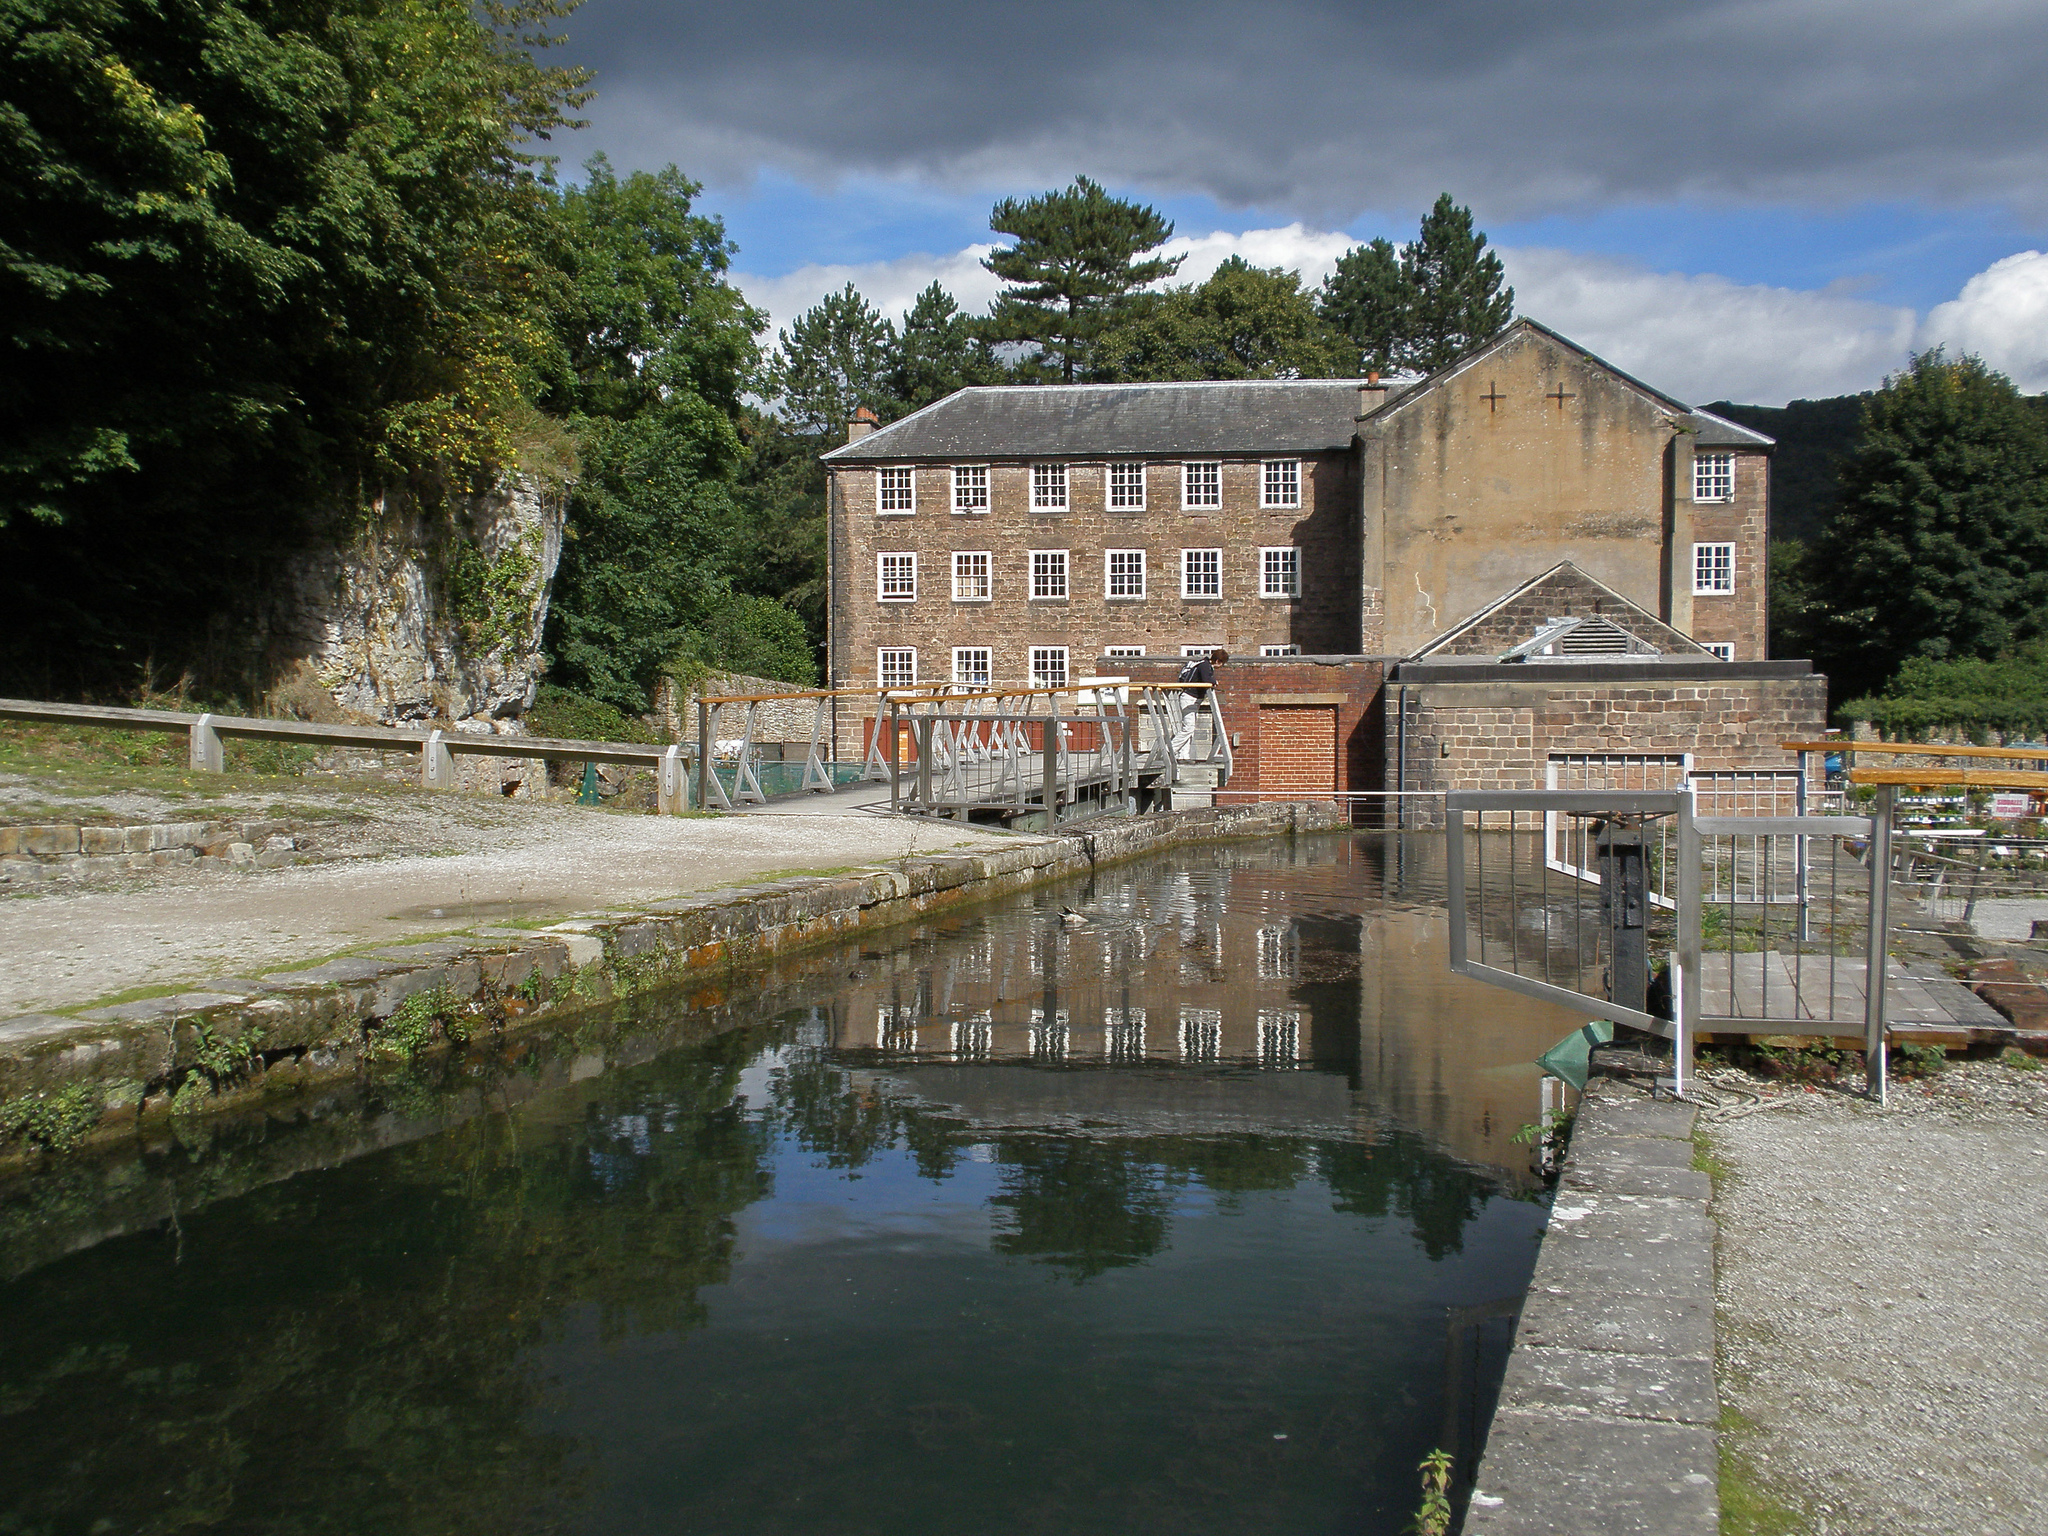
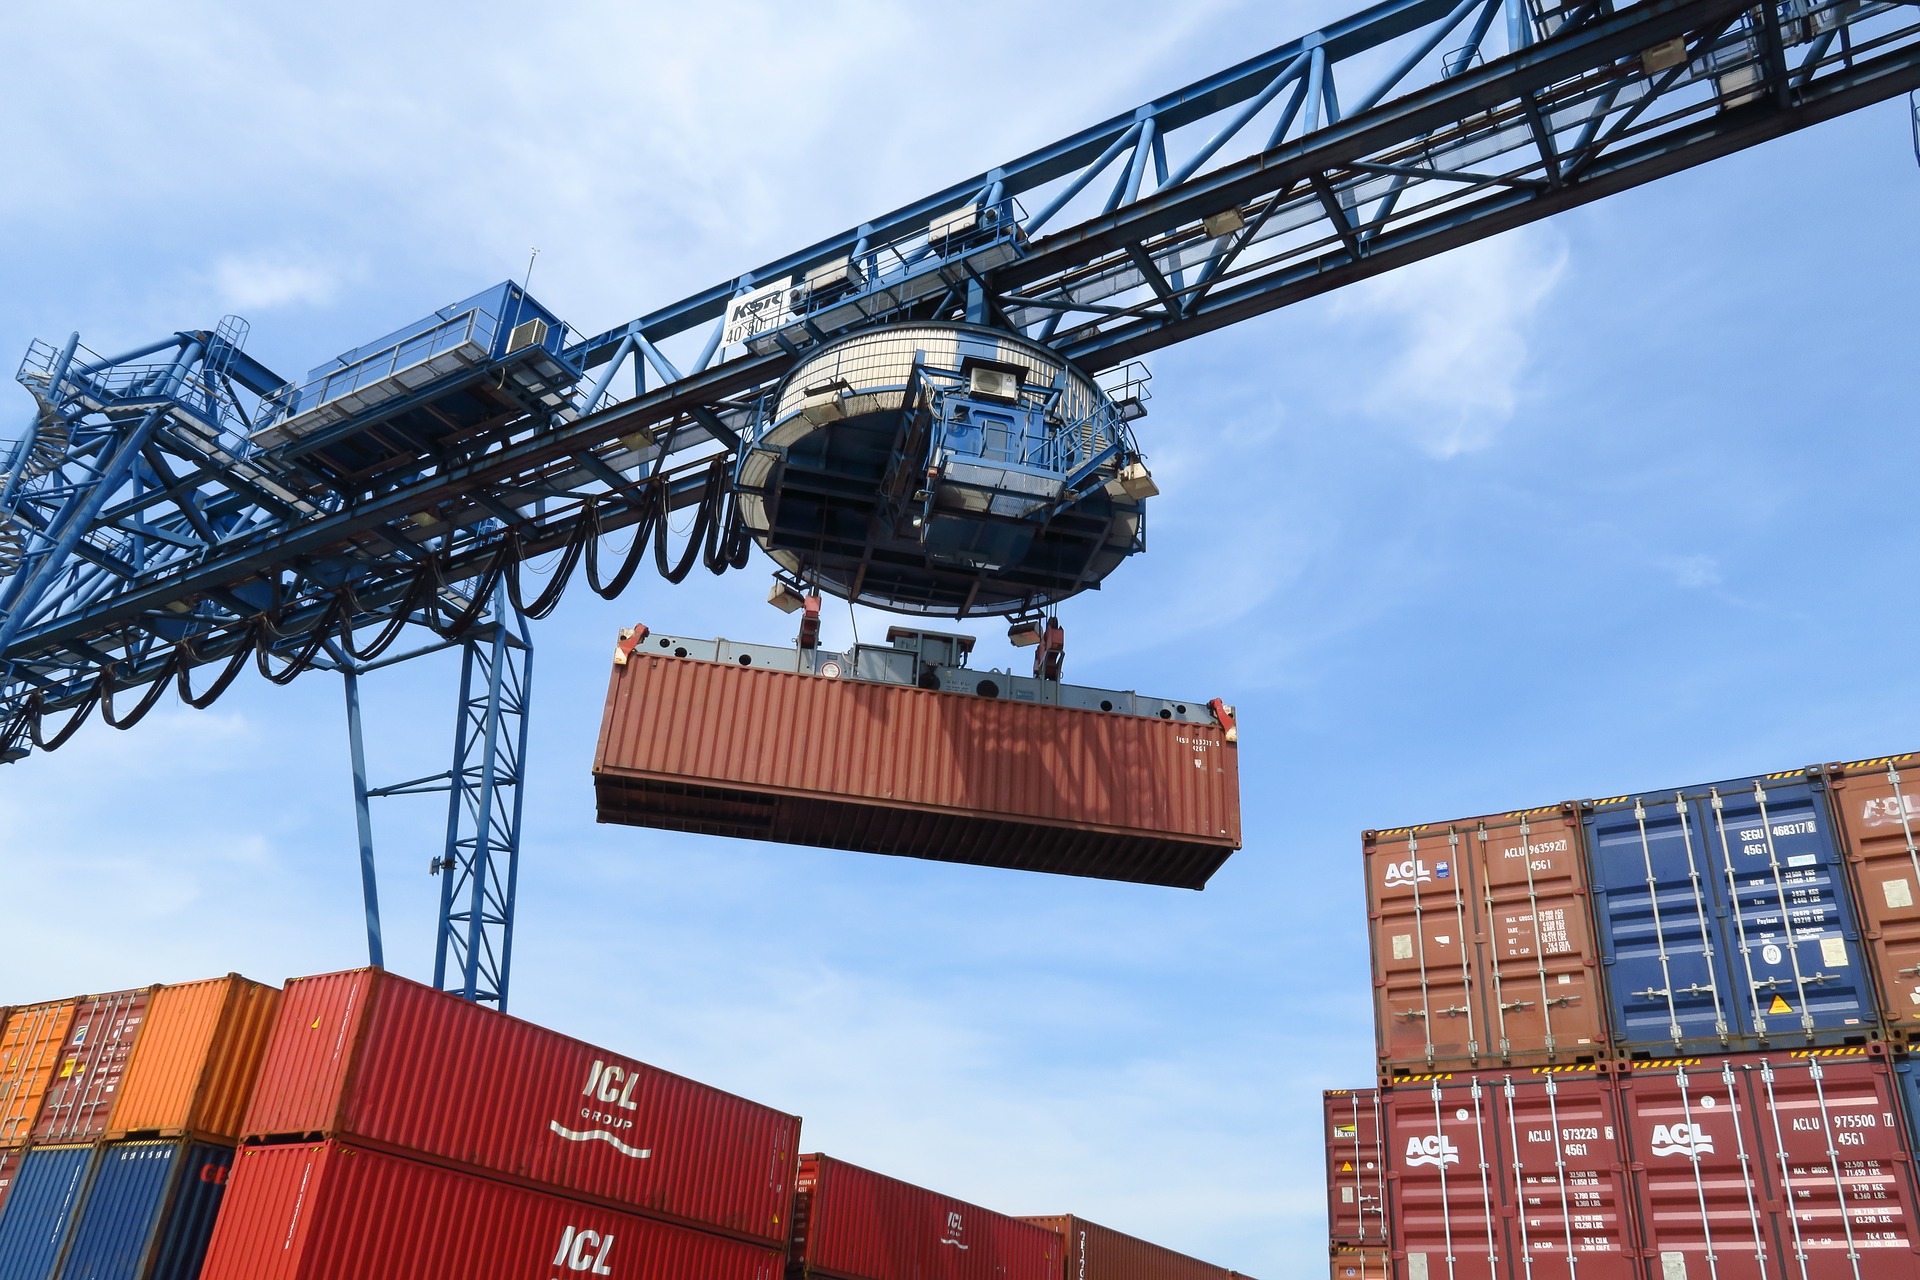
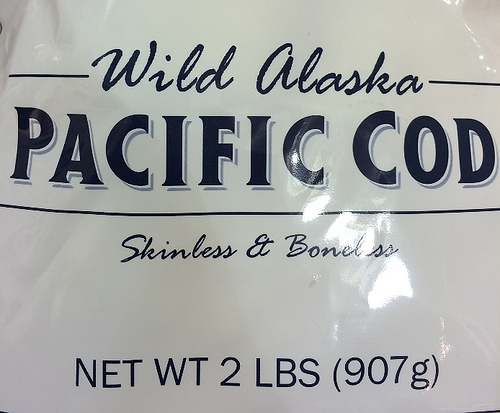
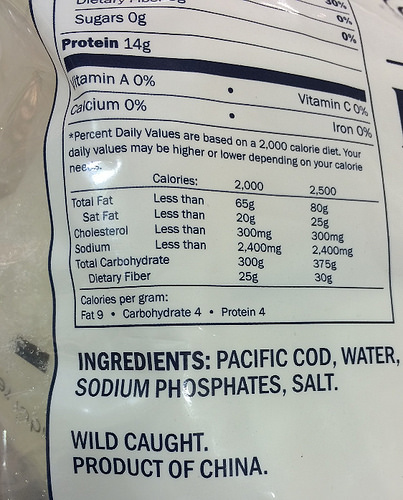
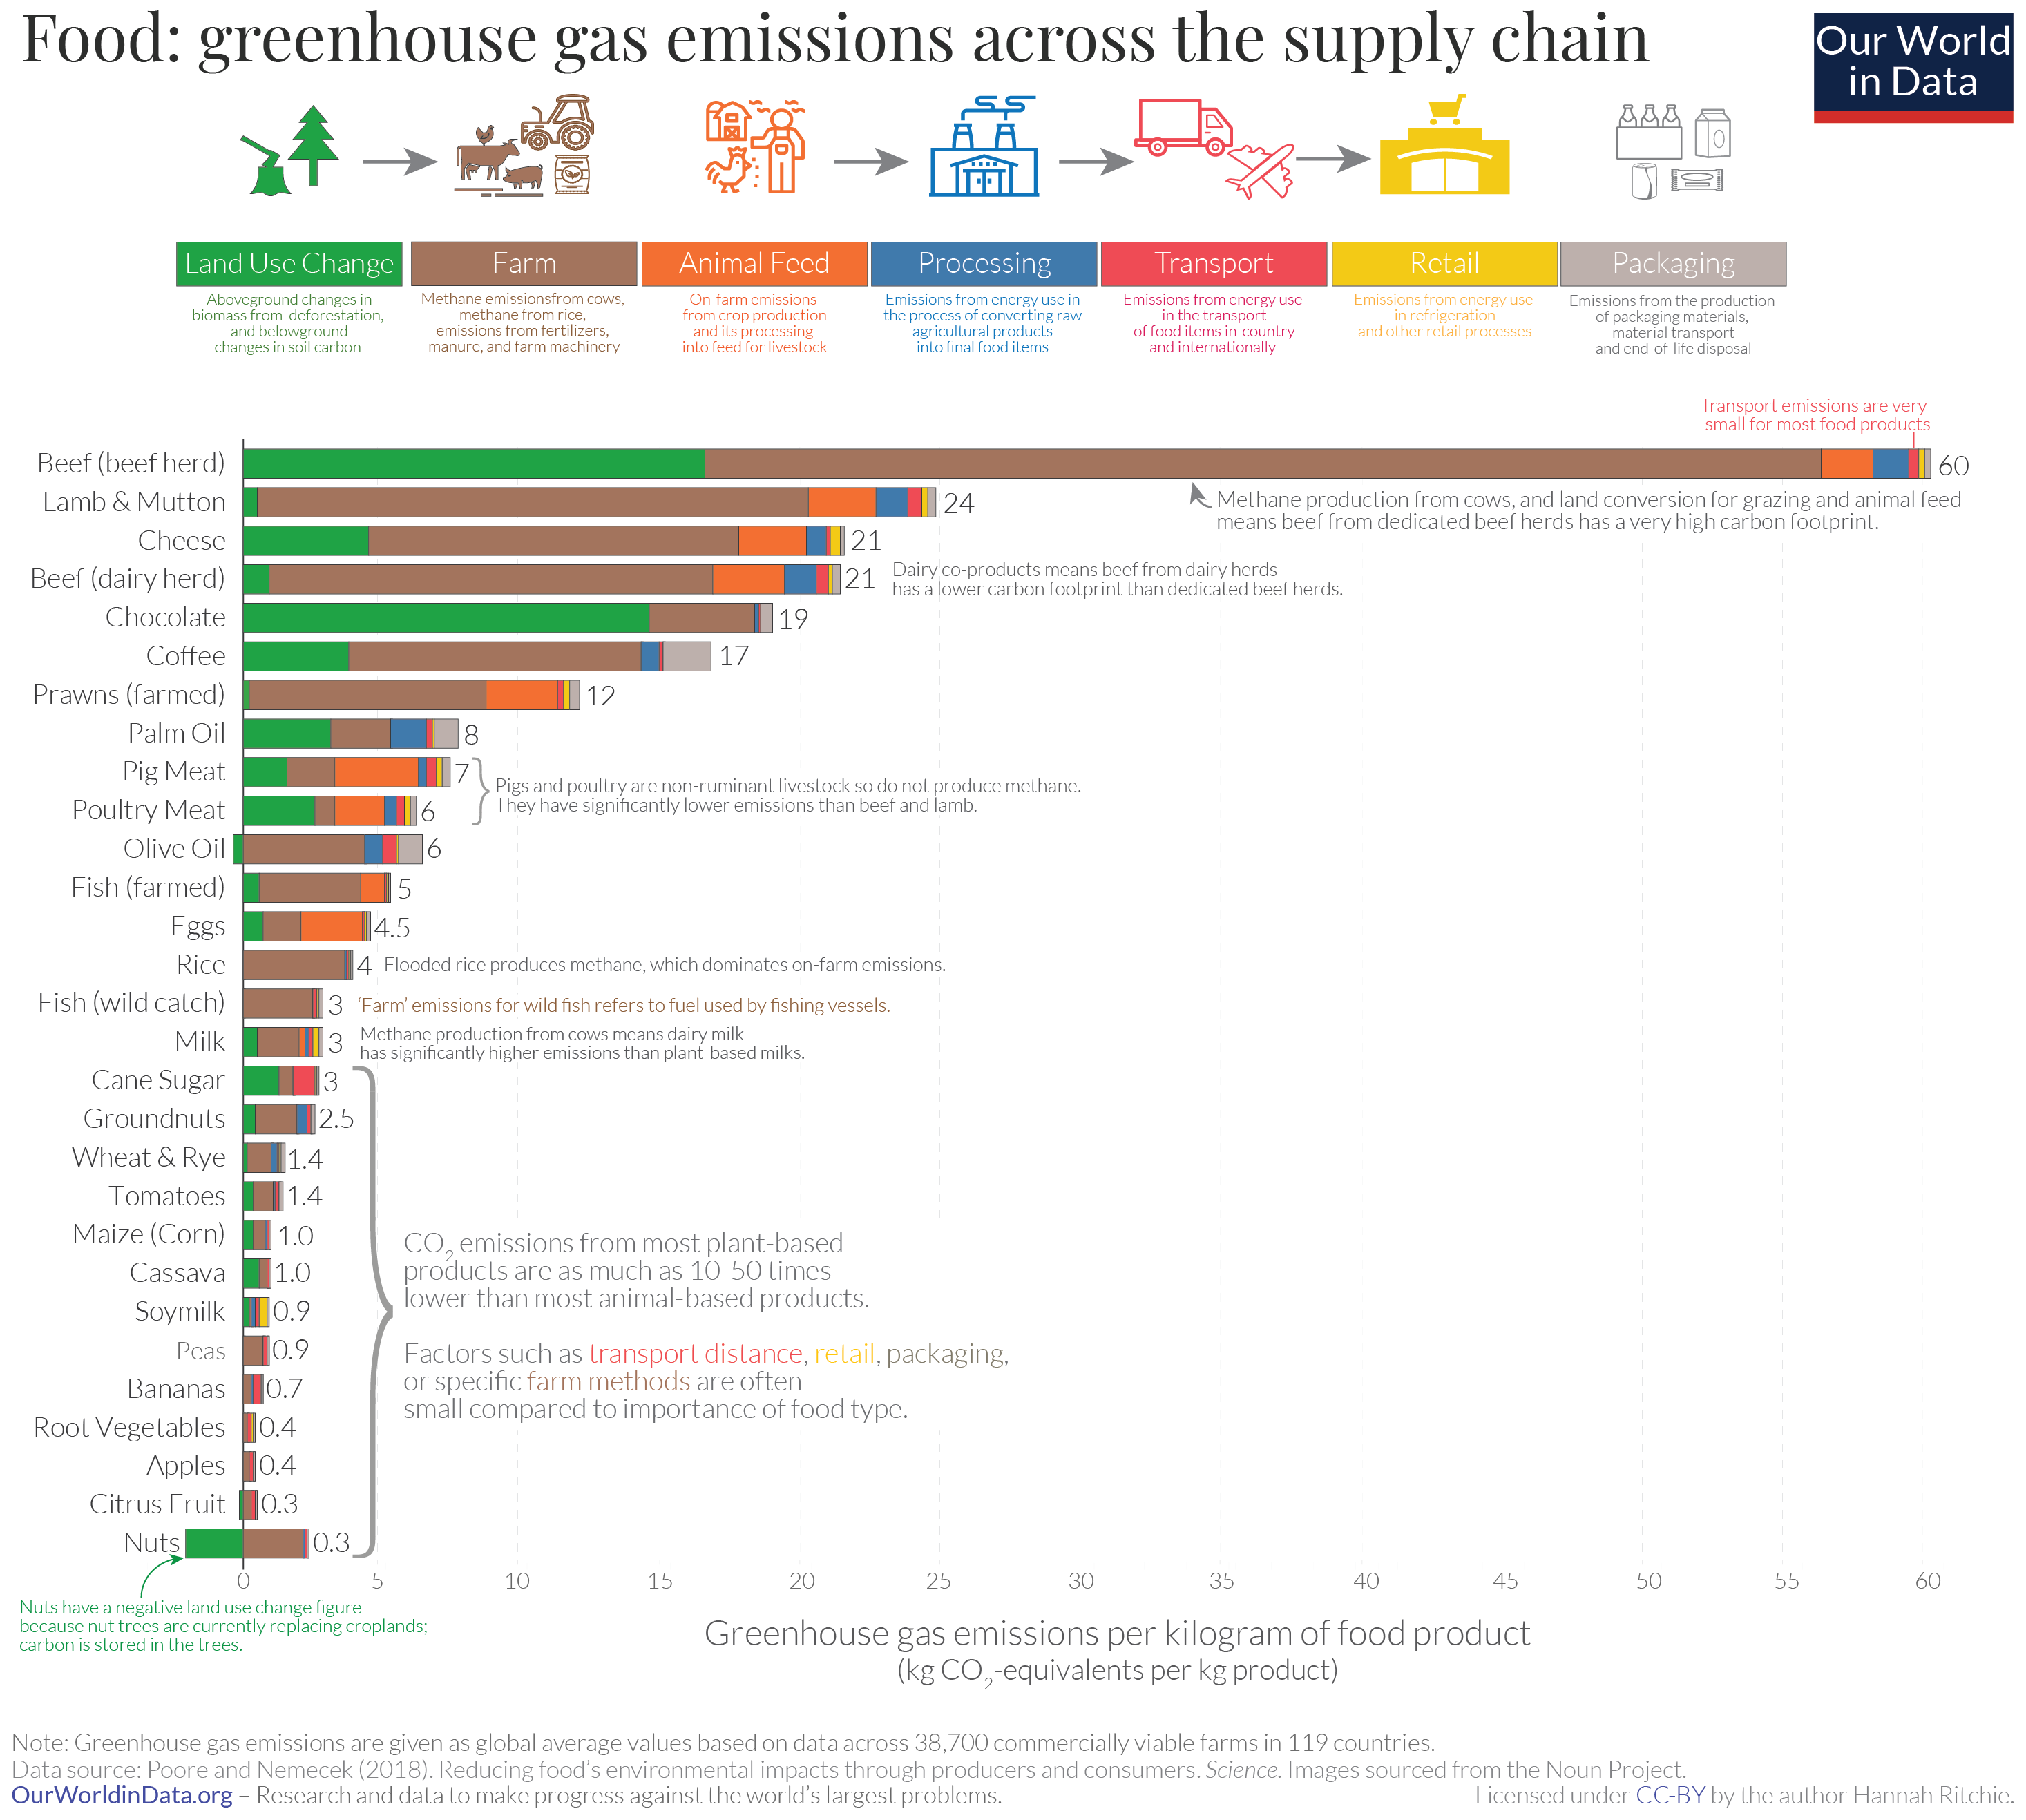
-\] Figure: Large amounts of data and high interconnection bandwidth mean that we receive much of our information about the world around us through computers. Figure: Packhorse Bridge under Burbage Edge. This packhorse route climbs steeply out of Hathersage and heads towards Sheffield. Packhorses were the main route for transporting goods across the Peak District. The high cost of transport is one driver of the ‘smith’ model, where there is a local skilled person responsible for assembling or creating goods (e.g. a blacksmith). On Sunday mornings in Sheffield, I often used to run across Packhorse Bridge in Burbage valley. The bridge is part of an ancient network of trails crossing the Pennines that, before Turnpike roads arrived in the 18th century, was the main way in which goods were moved. Given that the moors around Sheffield were home to sand quarries, tin mines, lead mines and the villages in the Derwent valley were known for nail and pin manufacture, this wasn’t simply movement of agricultural goods, but it was the infrastructure for industrial transport. The profession of leading the horses was known as a Jagger and leading out of the village of Hathersage is Jagger’s Lane, a trail that headed underneath Stanage Edge and into Sheffield. The movement of goods from regions of supply to areas of demand is fundamental to our society. The physical infrastructure of supply chain has evolved a great deal over the last 300 years. Figure: Richard Arkwright is regarded of the founder of the modern factory system. Factories exploit distribution networks to centralize production of goods. Arkwright located his factory in Cromford due to proximity to Nottingham Weavers (his market) and availability of water power from the tributaries of the Derwent river. When he first arrived there was almost no transportation network. Over the following 200 years The Cromford Canal (1790s), a Turnpike (now the A6, 1816-18) and the High Peak Railway (now closed, 1820s) were all constructed to improve transportation access as the factory blossomed. Richard Arkwright is known as the father of the modern factory system. In 1771 he set up a Mill for spinning cotton yarn in the village of Cromford, in the Derwent Valley. The Derwent valley is relatively inaccessible. Raw cotton arrived in Liverpool from the US and India. It needed to be transported on packhorse across the bridleways of the Pennines. But Cromford was a good location due to proximity to Nottingham, where weavers where consuming the finished thread, and the availability of water power from small tributaries of the Derwent river for Arkwright’s water frames which automated the production of yarn from raw cotton. By 1794 the Cromford Canal was opened to bring coal in to Cromford and give better transport to Nottingham. The construction of the canals was driven by the need to improve the transport infrastructure, facilitating the movement of goods across the UK. Canals, roads and railways were initially constructed by the economic need for moving goods. To improve supply chain. The A6 now does pass through Cromford, but at the time he moved there there was merely a track. The High Peak Railway was opened in 1832, it is now converted to the High Peak Trail, but it remains the highest railway built in Britain. Cooper (1991) Figure: The container is one of the major drivers of globalization, and arguably the largest agent of social change in the last 100 years. It reduces the cost of transportation, significantly changing the appropriate topology of distribution networks. The container makes it possible to ship goods halfway around the world for cheaper than it costs to process those goods, leading to an extended distribution topology. Containerization has had a dramatic effect on global economics, placing many people in the developing world at the end of the supply chain. Figure: Wild Alaskan Cod, being solid in the Pacific Northwest, that is a product of China. It is cheaper to ship the deep frozen fish thousands of kilometers for processing than to process locally. For example, you can buy Wild Alaskan Cod fished from Alaska, processed in China, sold in North America. This is driven by the low cost of transport for frozen cod vs the higher relative cost of cod processing in the US versus China. Similarly, Scottish prawns are also processed in China for sale in the UK. Figure: The transport cost of most foods is a very small portion of the total cost. The exception is if foods are air freighted. Source: https://ourworldindata.org/food-choice-vs-eating-local by Hannah Ritche CC-BY This effect on cost of transport vs cost of processing is the main driver of the topology of the modern supply chain and the associated effect of globalization. If transport is much cheaper than processing, then processing will tend to agglomerate in places where processing costs can be minimized. Large scale global economic change has principally been driven by changes in the technology that drives supply chain. Supply chain is a large-scale automated decision making network. Our aim is to make decisions not only based on our models of customer behavior (as observed through data), but also by accounting for the structure of our fulfilment center, and delivery network. Many of the most important questions in supply chain take the form of counterfactuals. E.g. “What would happen if we opened a manufacturing facility in Cambridge?” A counter factual is a question that implies a mechanistic understanding of a system. It goes beyond simple smoothness assumptions or translation invariants. It requires a physical, or mechanistic understanding of the supply chain network. For this reason, the type of models we deploy in supply chain often involve simulations or more mechanistic understanding of the network. In supply chain Machine Learning alone is not enough, we need to bridge between models that contain real mechanisms and models that are entirely data driven. This is challenging, because as we introduce more mechanism to the models we use, it becomes harder to develop efficient algorithms to match those models to data. There is a large opportunity because infrastructures around automation are moving from physical infrastructure towards information infrastructures. How can African countries benefit from a modern information infrastructure? The aim of Data Science Africa is to answer this question, with the answers coming from the attendees. Machine learning aims to replicate processes through the direct use of data. When deployed in the domain of ‘artificial intelligence,’ the processes that it is replicating, or emulating, are cognitive processes. The first trick in machine learning is to convert the process itself into a mathematical function. That function has a set of parameters which control its behaviour. What we call learning is the adaption of these parameters to change the behavior of the function. The choice of mathematical function we use is a vital component of the model. Figure: The Kapchorwa District, home district of Stephen Kiprotich. Stephen Kiprotich, the 2012 gold medal winner from the London Olympics, comes from Kapchorwa district, in eastern Uganda, near the border with Kenya. Image from Wikimedia Commons The Olympic Marathon data is a standard dataset for regression modelling. The data consists of the pace of Olympic Gold Medal Marathon winners for the Olympics from 1896 to present. Let’s load in the data and plot. Figure: Large amounts of data and high interconnection bandwidth mean that we receive much of our information about the world around us through computers. Figure: Packhorse Bridge under Burbage Edge. This packhorse route climbs steeply out of Hathersage and heads towards Sheffield. Packhorses were the main route for transporting goods across the Peak District. The high cost of transport is one driver of the ‘smith’ model, where there is a local skilled person responsible for assembling or creating goods (e.g. a blacksmith). On Sunday mornings in Sheffield, I often used to run across Packhorse Bridge in Burbage valley. The bridge is part of an ancient network of trails crossing the Pennines that, before Turnpike roads arrived in the 18th century, was the main way in which goods were moved. Given that the moors around Sheffield were home to sand quarries, tin mines, lead mines and the villages in the Derwent valley were known for nail and pin manufacture, this wasn’t simply movement of agricultural goods, but it was the infrastructure for industrial transport. The profession of leading the horses was known as a Jagger and leading out of the village of Hathersage is Jagger’s Lane, a trail that headed underneath Stanage Edge and into Sheffield. The movement of goods from regions of supply to areas of demand is fundamental to our society. The physical infrastructure of supply chain has evolved a great deal over the last 300 years. Figure: Richard Arkwright is regarded of the founder of the modern factory system. Factories exploit distribution networks to centralize production of goods. Arkwright located his factory in Cromford due to proximity to Nottingham Weavers (his market) and availability of water power from the tributaries of the Derwent river. When he first arrived there was almost no transportation network. Over the following 200 years The Cromford Canal (1790s), a Turnpike (now the A6, 1816-18) and the High Peak Railway (now closed, 1820s) were all constructed to improve transportation access as the factory blossomed. Richard Arkwright is known as the father of the modern factory system. In 1771 he set up a Mill for spinning cotton yarn in the village of Cromford, in the Derwent Valley. The Derwent valley is relatively inaccessible. Raw cotton arrived in Liverpool from the US and India. It needed to be transported on packhorse across the bridleways of the Pennines. But Cromford was a good location due to proximity to Nottingham, where weavers where consuming the finished thread, and the availability of water power from small tributaries of the Derwent river for Arkwright’s water frames which automated the production of yarn from raw cotton. By 1794 the Cromford Canal was opened to bring coal in to Cromford and give better transport to Nottingham. The construction of the canals was driven by the need to improve the transport infrastructure, facilitating the movement of goods across the UK. Canals, roads and railways were initially constructed by the economic need for moving goods. To improve supply chain. The A6 now does pass through Cromford, but at the time he moved there there was merely a track. The High Peak Railway was opened in 1832, it is now converted to the High Peak Trail, but it remains the highest railway built in Britain. Cooper (1991) Figure: The container is one of the major drivers of globalization, and arguably the largest agent of social change in the last 100 years. It reduces the cost of transportation, significantly changing the appropriate topology of distribution networks. The container makes it possible to ship goods halfway around the world for cheaper than it costs to process those goods, leading to an extended distribution topology. Containerization has had a dramatic effect on global economics, placing many people in the developing world at the end of the supply chain. Figure: Wild Alaskan Cod, being solid in the Pacific Northwest, that is a product of China. It is cheaper to ship the deep frozen fish thousands of kilometers for processing than to process locally. For example, you can buy Wild Alaskan Cod fished from Alaska, processed in China, sold in North America. This is driven by the low cost of transport for frozen cod vs the higher relative cost of cod processing in the US versus China. Similarly, Scottish prawns are also processed in China for sale in the UK. Figure: The transport cost of most foods is a very small portion of the total cost. The exception is if foods are air freighted. Source: https://ourworldindata.org/food-choice-vs-eating-local by Hannah Ritche CC-BY This effect on cost of transport vs cost of processing is the main driver of the topology of the modern supply chain and the associated effect of globalization. If transport is much cheaper than processing, then processing will tend to agglomerate in places where processing costs can be minimized. Large scale global economic change has principally been driven by changes in the technology that drives supply chain. Supply chain is a large-scale automated decision making network. Our aim is to make decisions not only based on our models of customer behavior (as observed through data), but also by accounting for the structure of our fulfilment center, and delivery network. Many of the most important questions in supply chain take the form of counterfactuals. E.g. “What would happen if we opened a manufacturing facility in Cambridge?” A counter factual is a question that implies a mechanistic understanding of a system. It goes beyond simple smoothness assumptions or translation invariants. It requires a physical, or mechanistic understanding of the supply chain network. For this reason, the type of models we deploy in supply chain often involve simulations or more mechanistic understanding of the network. In supply chain Machine Learning alone is not enough, we need to bridge between models that contain real mechanisms and models that are entirely data driven. This is challenging, because as we introduce more mechanism to the models we use, it becomes harder to develop efficient algorithms to match those models to data. There is a large opportunity because infrastructures around automation are moving from physical infrastructure towards information infrastructures. How can African countries benefit from a modern information infrastructure? The aim of Data Science Africa is to answer this question, with the answers coming from the attendees. Machine learning aims to replicate processes through the direct use of data. When deployed in the domain of ‘artificial intelligence’, the processes that it is replicating, or emulating, are cognitive processes. The first trick in machine learning is to convert the process itself into a mathematical function. That function has a set of parameters which control its behaviour. What we call learning is the adaption of these parameters to change the behavior of the function. The choice of mathematical function we use is a vital component of the model. Figure: The Kapchorwa District, home district of Stephen Kiprotich. Stephen Kiprotich, the 2012 gold medal winner from the London Olympics, comes from Kapchorwa district, in eastern Uganda, near the border with Kenya. Image from Wikimedia Commons The Olympic Marathon data is a standard dataset for regression modelling. The data consists of the pace of Olympic Gold Medal Marathon winners for the Olympics from 1896 to present. Let’s load in the data and plot. Figure: Olympic marathon pace times since 1896. Things to notice about the data include the outlier in 1904, in that year the Olympics was in St Louis, USA. Organizational problems and challenges with dust kicked up by the cars following the race meant that participants got lost, and only very few participants completed. More recent years see more consistently quick marathons. Define the polynomial basis function. Now we include the solution for the linear regression through QR-decomposition. Figure: Olympic marathon pace times since 1896. Things to notice about the data include the outlier in 1904, in that year the Olympics was in St Louis, USA. Organizational problems and challenges with dust kicked up by the cars following the race meant that participants got lost, and only very few participants completed. More recent years see more consistently quick marathons. Define the polynomial basis function. Now we include the solution for the linear regression through QR-decomposition. Now we make some predictions for the fit. Now we make some predictions for the fit. Figure: Fit of a 1-degree polynomial (a linear model) to the Olympic marathon data. Figure: Fit of a 1-degree polynomial (a linear model) to the Olympic marathon data. Figure: Fit of a 3-degree polynomial (a cubic model) to the Olympic marathon data. Now we’ll try a 9th degree polynomial fit to the data. Figure: Fit of a 3-degree polynomial (a cubic model) to the Olympic marathon data. Now we’ll try a 9th degree polynomial fit to the data. Figure: Fit of a 9-degree polynomial to the Olympic marathon data. Now we’ll try a 16th degree polynomial fit to the data. Figure: Fit of a 9-degree polynomial to the Olympic marathon data. Now we’ll try a 16th degree polynomial fit to the data. Figure: Fit of a 16-degree polynomial to the Olympic marathon data. Now we’ll try a 28th degree polynomial fit to the data. Figure: Fit of a 16-degree polynomial to the Olympic marathon data. Now we’ll try a 28th degree polynomial fit to the data. Figure: Fit of a 28-degree polynomial to the Olympic marathon data. Any process of automation allows us to scale what we do by codifying a process in some way that makes it efficient and repeatable. Machine learning automates by emulating human (or other actions) found in data. Machine learning codifies in the form of a mathematical function that is learnt by a computer. If we can create these mathematical functions in ways in which they can interconnect, then we can also build systems. Machine learning works through codifying a prediction of interest into a mathematical function. For example, we can try and predict the probability that a customer wants to by a jersey given knowledge of their age, and the latitude where they live. The technique known as logistic regression estimates the odds that someone will by a jumper as a linear weighted sum of the features of interest. \[ \text{odds} = \frac{p(\text{bought})}{p(\text{not bought})} \] \[ \log \text{odds} = w_0 + w_1 \text{age} + w_2 \text{latitude}.\] Here \(w_0\), \(w_1\) and \(w_2\) are the parameters of the model. If \(w_1\) and \(w_2\) are both positive, then the log-odds that someone will buy a jumper increase with increasing latitude and age, so the further north you are and the older you are the more likely you are to buy a jumper. The parameter \(w_0\) is an offset parameter and gives the log-odds of buying a jumper at zero age and on the equator. It is likely to be negative1 indicating that the purchase is odds-against. This is also a classical statistical model, and models like logistic regression are widely used to estimate probabilities from ad-click prediction to disease risk. This is called a generalized linear model, we can also think of it as estimating the probability of a purchase as a nonlinear function of the features (age, latitude) and the parameters (the \(w\) values). The function is known as the sigmoid or logistic function, thus the name logistic regression. Figure: The logistic function. The function has this characeristic ‘s’-shape (from where the term sigmoid, as in sigma, comes from). It also takes the input from the entire real line and ‘squashes’ it into an output that is between zero and one. For this reason it is sometimes also called a ‘squashing function.’ The sigmoid comes from the inverting the odds ratio, \[
+w = basis_fit(Phi, y) Figure: Fit of a 28-degree polynomial to the Olympic marathon data. Any process of automation allows us to scale what we do by codifying a process in some way that makes it efficient and repeatable. Machine learning automates by emulating human (or other actions) found in data. Machine learning codifies in the form of a mathematical function that is learnt by a computer. If we can create these mathematical functions in ways in which they can interconnect, then we can also build systems. Machine learning works through codifying a prediction of interest into a mathematical function. For example, we can try and predict the probability that a customer wants to by a jersey given knowledge of their age, and the latitude where they live. The technique known as logistic regression estimates the odds that someone will by a jumper as a linear weighted sum of the features of interest. \[ \text{odds} = \frac{p(\text{bought})}{p(\text{not bought})} \] \[ \log \text{odds} = w_0 + w_1 \text{age} + w_2 \text{latitude}.\] Here \(w_0\), \(w_1\) and \(w_2\) are the parameters of the model. If \(w_1\) and \(w_2\) are both positive, then the log-odds that someone will buy a jumper increase with increasing latitude and age, so the further north you are and the older you are the more likely you are to buy a jumper. The parameter \(w_0\) is an offset parameter and gives the log-odds of buying a jumper at zero age and on the equator. It is likely to be negative1 indicating that the purchase is odds-against. This is also a classical statistical model, and models like logistic regression are widely used to estimate probabilities from ad-click prediction to disease risk. This is called a generalized linear model, we can also think of it as estimating the probability of a purchase as a nonlinear function of the features (age, latitude) and the parameters (the \(w\) values). The function is known as the sigmoid or logistic function, thus the name logistic regression. Figure: The logistic function. The function has this characeristic ‘s’-shape (from where the term sigmoid, as in sigma, comes from). It also takes the input from the entire real line and ‘squashes’ it into an output that is between zero and one. For this reason it is sometimes also called a ‘squashing function’. The sigmoid comes from the inverting the odds ratio, \[
\frac{\pi}{(1-\pi)}
-\] where \(\pi\) is the probability of a positive outcome and \(1-\pi\) is the probability of a negative outcome \[ p(\text{bought}) = \sigma\left(w_0 + w_1 \text{age} + w_2 \text{latitude}\right).\] In the case where we have features to help us predict, we sometimes denote such features as a vector, \(\mathbf{ x}\), and we then use an inner product between the features and the parameters, \(\mathbf{ w}^\top \mathbf{ x}= w_1 x_1 + w_2 x_2 + w_3 x_3 ...\), to represent the argument of the sigmoid. \[ p(\text{bought}) = \sigma\left(\mathbf{ w}^\top \mathbf{ x}\right).\] More generally, we aim to predict some aspect of our data, \(y\), by relating it through a mathematical function, \(f(\cdot)\), to the parameters, \(\mathbf{ w}\) and the data, \(\mathbf{ x}\). \[ y= f\left(\mathbf{ x}, \mathbf{ w}\right).\] We call \(f(\cdot)\) the prediction function. To obtain the fit to data, we use a separate function called the objective function that gives us a mathematical representation of the difference between our predictions and the real data. \[E(\mathbf{ w}, \mathbf{Y}, \mathbf{X})\] A commonly used examples (for example in a regression problem) is least squares, \[E(\mathbf{ w}, \mathbf{Y}, \mathbf{X}) = \sum_{i=1}^n\left(y_i - f(\mathbf{ x}_i, \mathbf{ w})\right)^2.\] If a linear prediction function is combined with the least squares objective function, then that gives us a classical linear regression, another classical statistical model. Statistics often focusses on linear models because it makes interpretation of the model easier. Interpretation is key in statistics because the aim is normally to validate questions by analysis of data. Machine learning has typically focused more on the prediction function itself and worried less about the interpretation of parameters. In statistics, where interpretation is typically more important than prediction, parameters are normally denoted by \(\boldsymbol{\beta}\) instead of \(\mathbf{ w}\). A key difference between statistics and machine learning, is that (traditionally) machine learning has focussed on predictive capability and statistics has focussed on interpretability. That means that in a statistics class far more emphasis will be placed on interpretation of the parameters. In machine learning, the parameters, $, are just a means to an end. But in statistics, when we denote the parameters by \(\boldsymbol{\beta}\), we often use the parameters to tell us something about the disease. So we move between \[ p(\text{bought}) = \sigma\left(w_0 + w_1 \text{age} + w_2 \text{latitude}\right).\] to denote the emphasis is on predictive power to \[ p(\text{bought}) = \sigma\left(\beta_0 + \beta_1 \text{age} + \beta_2 \text{latitude}\right).\] to denote the emphasis is on interpretation of the parameters. Another effect of the focus on prediction in machine learning is that non-linear approaches, which can be harder to interpret, are more widely deployedin machine learning – they tend to improve quality of predictions at the expense of interpretability. Machine learning allows us to extract knowledge from data to form a prediction. \[\text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}\] A machine learning prediction is made by combining a model with data to form the prediction. The manner in which this is done gives us the machine learning algorithm. Machine learning models are mathematical models which make weak assumptions about data, e.g. smoothness assumptions. By combining these assumptions with the data, we observe we can interpolate between data points or, occasionally, extrapolate into the future. Machine learning is a technology which strongly overlaps with the methodology of statistics. From a historical/philosophical view point, machine learning differs from statistics in that the focus in the machine learning community has been primarily on accuracy of prediction, whereas the focus in statistics is typically on the interpretability of a model and/or validating a hypothesis through data collection. The rapid increase in the availability of compute and data has led to the increased prominence of machine learning. This prominence is surfacing in two different but overlapping domains: data science and artificial intelligence. The real challenge, however, is end-to-end decision making. Taking information from the environment and using it to drive decision making to achieve goals. Artificial intelligence has the objective of endowing computers with human-like intelligent capabilities. For example, understanding an image (computer vision) or the contents of some speech (speech recognition), the meaning of a sentence (natural language processing) or the translation of a sentence (machine translation). The machine learning approach to artificial intelligence is to collect and annotate a large data set from humans. The problem is characterized by input data (e.g. a particular image) and a label (e.g. is there a car in the image yes/no). The machine learning algorithm fits a mathematical function (I call this the prediction function) to map from the input image to the label. The parameters of the prediction function are set by minimizing an error between the function’s predictions and the true data. This mathematical function that encapsulates this error is known as the objective function. This approach to machine learning is known as supervised learning. Various approaches to supervised learning use different prediction functions, objective functions or different optimization algorithms to fit them. For example, deep learning makes use of neural networks to form the predictions. A neural network is a particular type of mathematical function that allows the algorithm designer to introduce invariances into the function. An invariance is an important way of including prior understanding in a machine learning model. For example, in an image, a car is still a car regardless of whether it’s in the upper left or lower right corner of the image. This is known as translation invariance. A neural network encodes translation invariance in convolutional layers. Convolutional neural networks are widely used in image recognition tasks. An alternative structure is known as a recurrent neural network (RNN). RNNs neural networks encode temporal structure. They use auto regressive connections in their hidden layers, they can be seen as time series models which have non-linear auto-regressive basis functions. They are widely used in speech recognition and machine translation. Machine learning has been deployed in Speech Recognition (e.g. Alexa, deep neural networks, convolutional neural networks for speech recognition), in computer vision (e.g. Amazon Go, convolutional neural networks for person recognition and pose detection). The field of data science is related to AI, but philosophically different. It arises because we are increasingly creating large amounts of data through happenstance rather than active collection. In the modern era data is laid down by almost all our activities. The objective of data science is to extract insights from this data. Classically, in the field of statistics, data analysis proceeds by assuming that the question (or scientific hypothesis) comes before the data is created. E.g., if I want to determine the effectiveness of a particular drug, I perform a design for my data collection. I use foundational approaches such as randomization to account for confounders. This made a lot of sense in an era where data had to be actively collected. The reduction in cost of data collection and storage now means that many data sets are available which weren’t collected with a particular question in mind. This is a challenge because bias in the way data was acquired can corrupt the insights we derive. We can perform randomized control trials (or A/B tests) to verify our conclusions, but the opportunity is to use data science techniques to better guide our question selection or even answer a question without the expense of a full randomized control trial (referred to as A/B testing in modern internet parlance). Neural networks are adaptive non-linear function models. Originally, they were studied (by McCulloch and Pitts (McCulloch and Pitts, 1943)) as simple models for neurons, but over the last decade they have become popular because they are a flexible approach to modelling complex data. A particular characteristic of neural network models is that they can be composed to form highly complex functions which encode many of our expectations of the real world. They allow us to encode our assumptions about how the world works. We will return to composition later, but for the moment, let’s focus on a one hidden layer neural network. We are interested in the prediction function, so we’ll ignore the objective function (which is often called an error function) for the moment, and just describe the mathematical object of interest \[
+\] where \(\pi\) is the probability of a positive outcome and \(1-\pi\) is the probability of a negative outcome \[ p(\text{bought}) = \sigma\left(w_0 + w_1 \text{age} + w_2 \text{latitude}\right).\] In the case where we have features to help us predict, we sometimes denote such features as a vector, \(\mathbf{ x}\), and we then use an inner product between the features and the parameters, \(\mathbf{ w}^\top \mathbf{ x}= w_1 x_1 + w_2 x_2 + w_3 x_3 ...\), to represent the argument of the sigmoid. \[ p(\text{bought}) = \sigma\left(\mathbf{ w}^\top \mathbf{ x}\right).\] More generally, we aim to predict some aspect of our data, \(y\), by relating it through a mathematical function, \(f(\cdot)\), to the parameters, \(\mathbf{ w}\) and the data, \(\mathbf{ x}\). \[ y= f\left(\mathbf{ x}, \mathbf{ w}\right).\] We call \(f(\cdot)\) the prediction function. To obtain the fit to data, we use a separate function called the objective function that gives us a mathematical representation of the difference between our predictions and the real data. \[E(\mathbf{ w}, \mathbf{Y}, \mathbf{X})\] A commonly used examples (for example in a regression problem) is least squares, \[E(\mathbf{ w}, \mathbf{Y}, \mathbf{X}) = \sum_{i=1}^n\left(y_i - f(\mathbf{ x}_i, \mathbf{ w})\right)^2.\] If a linear prediction function is combined with the least squares objective function, then that gives us a classical linear regression, another classical statistical model. Statistics often focusses on linear models because it makes interpretation of the model easier. Interpretation is key in statistics because the aim is normally to validate questions by analysis of data. Machine learning has typically focused more on the prediction function itself and worried less about the interpretation of parameters. In statistics, where interpretation is typically more important than prediction, parameters are normally denoted by \(\boldsymbol{\beta}\) instead of \(\mathbf{ w}\). A key difference between statistics and machine learning, is that (traditionally) machine learning has focussed on predictive capability and statistics has focussed on interpretability. That means that in a statistics class far more emphasis will be placed on interpretation of the parameters. In machine learning, the parameters, $, are just a means to an end. But in statistics, when we denote the parameters by \(\boldsymbol{\beta}\), we often use the parameters to tell us something about the disease. So we move between \[ p(\text{bought}) = \sigma\left(w_0 + w_1 \text{age} + w_2 \text{latitude}\right).\] to denote the emphasis is on predictive power to \[ p(\text{bought}) = \sigma\left(\beta_0 + \beta_1 \text{age} + \beta_2 \text{latitude}\right).\] to denote the emphasis is on interpretation of the parameters. Another effect of the focus on prediction in machine learning is that non-linear approaches, which can be harder to interpret, are more widely deployedin machine learning – they tend to improve quality of predictions at the expense of interpretability. Machine learning allows us to extract knowledge from data to form a prediction. \[\text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}\] A machine learning prediction is made by combining a model with data to form the prediction. The manner in which this is done gives us the machine learning algorithm. Machine learning models are mathematical models which make weak assumptions about data, e.g. smoothness assumptions. By combining these assumptions with the data, we observe we can interpolate between data points or, occasionally, extrapolate into the future. Machine learning is a technology which strongly overlaps with the methodology of statistics. From a historical/philosophical view point, machine learning differs from statistics in that the focus in the machine learning community has been primarily on accuracy of prediction, whereas the focus in statistics is typically on the interpretability of a model and/or validating a hypothesis through data collection. The rapid increase in the availability of compute and data has led to the increased prominence of machine learning. This prominence is surfacing in two different but overlapping domains: data science and artificial intelligence. The real challenge, however, is end-to-end decision making. Taking information from the environment and using it to drive decision making to achieve goals. Artificial intelligence has the objective of endowing computers with human-like intelligent capabilities. For example, understanding an image (computer vision) or the contents of some speech (speech recognition), the meaning of a sentence (natural language processing) or the translation of a sentence (machine translation). The machine learning approach to artificial intelligence is to collect and annotate a large data set from humans. The problem is characterized by input data (e.g. a particular image) and a label (e.g. is there a car in the image yes/no). The machine learning algorithm fits a mathematical function (I call this the prediction function) to map from the input image to the label. The parameters of the prediction function are set by minimizing an error between the function’s predictions and the true data. This mathematical function that encapsulates this error is known as the objective function. This approach to machine learning is known as supervised learning. Various approaches to supervised learning use different prediction functions, objective functions or different optimization algorithms to fit them. For example, deep learning makes use of neural networks to form the predictions. A neural network is a particular type of mathematical function that allows the algorithm designer to introduce invariances into the function. An invariance is an important way of including prior understanding in a machine learning model. For example, in an image, a car is still a car regardless of whether it’s in the upper left or lower right corner of the image. This is known as translation invariance. A neural network encodes translation invariance in convolutional layers. Convolutional neural networks are widely used in image recognition tasks. An alternative structure is known as a recurrent neural network (RNN). RNNs neural networks encode temporal structure. They use auto regressive connections in their hidden layers, they can be seen as time series models which have non-linear auto-regressive basis functions. They are widely used in speech recognition and machine translation. Machine learning has been deployed in Speech Recognition (e.g. Alexa, deep neural networks, convolutional neural networks for speech recognition), in computer vision (e.g. Amazon Go, convolutional neural networks for person recognition and pose detection). The field of data science is related to AI, but philosophically different. It arises because we are increasingly creating large amounts of data through happenstance rather than active collection. In the modern era data is laid down by almost all our activities. The objective of data science is to extract insights from this data. Classically, in the field of statistics, data analysis proceeds by assuming that the question (or scientific hypothesis) comes before the data is created. E.g., if I want to determine the effectiveness of a particular drug, I perform a design for my data collection. I use foundational approaches such as randomization to account for confounders. This made a lot of sense in an era where data had to be actively collected. The reduction in cost of data collection and storage now means that many data sets are available which weren’t collected with a particular question in mind. This is a challenge because bias in the way data was acquired can corrupt the insights we derive. We can perform randomized control trials (or A/B tests) to verify our conclusions, but the opportunity is to use data science techniques to better guide our question selection or even answer a question without the expense of a full randomized control trial (referred to as A/B testing in modern internet parlance). Neural networks are adaptive non-linear function models. Originally, they were studied (by McCulloch and Pitts (McCulloch and Pitts, 1943)) as simple models for neurons, but over the last decade they have become popular because they are a flexible approach to modelling complex data. A particular characteristic of neural network models is that they can be composed to form highly complex functions which encode many of our expectations of the real world. They allow us to encode our assumptions about how the world works. We will return to composition later, but for the moment, let’s focus on a one hidden layer neural network. We are interested in the prediction function, so we’ll ignore the objective function (which is often called an error function) for the moment, and just describe the mathematical object of interest \[
f(\mathbf{ x}) = \mathbf{W}^\top \boldsymbol{ \phi}(\mathbf{V}, \mathbf{ x})
-\] Where in this case \(f(\cdot)\) is a scalar function with vector inputs, and \(\boldsymbol{ \phi}(\cdot)\) is a vector function with vector inputs. The dimensionality of the vector function is known as the number of hidden units, or the number of neurons. The elements of this vector function are known as the activation function of the neural network and \(\mathbf{V}\) are the parameters of the activation functions. In statistics activation functions are traditionally known as basis functions. And we would think of this as a linear model. It’s doesn’t make linear predictions, but it’s linear because in statistics estimation focuses on the parameters, \(\mathbf{W}\), not the parameters, \(\mathbf{V}\). The linear model terminology refers to the fact that the model is linear in the parameters, but it is not linear in the data unless the activation functions are chosen to be linear. The first difference in the (early) neural network literature to the classical statistical literature is the decision to optimize these parameters, \(\mathbf{V}\), as well as the parameters, \(\mathbf{W}\) (which would normally be denoted in statistics by \(\boldsymbol{\beta}\))2. The key idea in machine learning is to observe the system in practice, and then emulate its behavior with mathematics. That leads to a design challenge as to where to place the mathematical function. The placement of the mathematical function leads to the different domains of machine learning. Supervised learning is one of the most widely deployed machine learning technologies, and a particular domain of success has been classification. Classification is the process of taking an input (which might be an image) and categorizing it into one of a number of different classes (e.g. dog or cat). This simple idea underpins a lot of machine learning. By scanning across the image we can also determine where the animal is in the image. Classification is perhaps the technique most closely assocated with machine learning. In the speech based agents, on-device classifiers are used to determine when the wake word is used. A wake word is a word that wakes up the device. For the Amazon Echo it is “Alexa,” for Siri it is “Hey Siri.” Once the wake word detected with a classifier, the speech can be uploaded to the cloud for full processing, the speech recognition stages. This isn’t just useful for intelligent agents, the UN global pulse project on public discussion on radio also uses wake word detection for recording radio conversations. A major breakthrough in image classification came in 2012 with the ImageNet result of Alex Krizhevsky, Ilya Sutskever and Geoff Hinton from the University of Toronto. ImageNet is a large data base of 14 million images with many thousands of classes. The data is used in a community-wide challenge for object categorization. Krizhevsky et al used convolutional neural networks to outperform all previous approaches on the challenge. They formed a company which was purchased shortly after by Google. This challenge, known as object categorisation, was a major obstacle for practical computer vision systems. Modern object categorization systems are close to human performance. Machine learning problems normally involve a prediction function and an objective function. Regression is the case where the prediction function iss over the real numbers, so the codomain of the functions, \(f(\mathbf{X})\) was the real numbers or sometimes real vectors. The classification problem consists of predicting whether or not a particular example is a member of a particular class. So we may want to know if a particular image represents a digit 6 or if a particular user will click on a given advert. These are classification problems, and they require us to map to yes or no answers. That makes them naturally discrete mappings. In classification we are given an input vector, \(\mathbf{ x}\), and an associated label, \(y\) which either takes the value \(-1\) to represent no or \(1\) to represent yes. In supervised learning the inputs, \(\mathbf{ x}\), are mapped to a label, \(y\), through a function \(f(\cdot)\) that is dependent on a set of parameters, \(\mathbf{ w}\), \[
+\] Where in this case \(f(\cdot)\) is a scalar function with vector inputs, and \(\boldsymbol{ \phi}(\cdot)\) is a vector function with vector inputs. The dimensionality of the vector function is known as the number of hidden units, or the number of neurons. The elements of this vector function are known as the activation function of the neural network and \(\mathbf{V}\) are the parameters of the activation functions. In statistics activation functions are traditionally known as basis functions. And we would think of this as a linear model. It’s doesn’t make linear predictions, but it’s linear because in statistics estimation focuses on the parameters, \(\mathbf{W}\), not the parameters, \(\mathbf{V}\). The linear model terminology refers to the fact that the model is linear in the parameters, but it is not linear in the data unless the activation functions are chosen to be linear. The first difference in the (early) neural network literature to the classical statistical literature is the decision to optimize these parameters, \(\mathbf{V}\), as well as the parameters, \(\mathbf{W}\) (which would normally be denoted in statistics by \(\boldsymbol{\beta}\))2. The key idea in machine learning is to observe the system in practice, and then emulate its behavior with mathematics. That leads to a design challenge as to where to place the mathematical function. The placement of the mathematical function leads to the different domains of machine learning. Supervised learning is one of the most widely deployed machine learning technologies, and a particular domain of success has been classification. Classification is the process of taking an input (which might be an image) and categorizing it into one of a number of different classes (e.g. dog or cat). This simple idea underpins a lot of machine learning. By scanning across the image we can also determine where the animal is in the image. Classification is perhaps the technique most closely assocated with machine learning. In the speech based agents, on-device classifiers are used to determine when the wake word is used. A wake word is a word that wakes up the device. For the Amazon Echo it is “Alexa”, for Siri it is “Hey Siri”. Once the wake word detected with a classifier, the speech can be uploaded to the cloud for full processing, the speech recognition stages. This isn’t just useful for intelligent agents, the UN global pulse project on public discussion on radio also uses wake word detection for recording radio conversations. A major breakthrough in image classification came in 2012 with the ImageNet result of Alex Krizhevsky, Ilya Sutskever and Geoff Hinton from the University of Toronto. ImageNet is a large data base of 14 million images with many thousands of classes. The data is used in a community-wide challenge for object categorization. Krizhevsky et al used convolutional neural networks to outperform all previous approaches on the challenge. They formed a company which was purchased shortly after by Google. This challenge, known as object categorisation, was a major obstacle for practical computer vision systems. Modern object categorization systems are close to human performance. Machine learning problems normally involve a prediction function and an objective function. Regression is the case where the prediction function iss over the real numbers, so the codomain of the functions, \(f(\mathbf{X})\) was the real numbers or sometimes real vectors. The classification problem consists of predicting whether or not a particular example is a member of a particular class. So we may want to know if a particular image represents a digit 6 or if a particular user will click on a given advert. These are classification problems, and they require us to map to yes or no answers. That makes them naturally discrete mappings. In classification we are given an input vector, \(\mathbf{ x}\), and an associated label, \(y\) which either takes the value \(-1\) to represent no or \(1\) to represent yes. In supervised learning the inputs, \(\mathbf{ x}\), are mapped to a label, \(y\), through a function \(f(\cdot)\) that is dependent on a set of parameters, \(\mathbf{ w}\), \[
y= f(\mathbf{ x}; \mathbf{ w}).
-\] The function \(f(\cdot)\) is known as the prediction function. The key challenges are (1) choosing which features, \(\mathbf{ x}\), are relevant in the prediction, (2) defining the appropriate class of function, \(f(\cdot)\), to use and (3) selecting the right parameters, \(\mathbf{ w}\). There are many difference examples of classification problems. One of theoldest is the classification of hand written digits from binary images. The MNIST data was for a long time considered one of the most difficult data sets. When we download this data we are making use of open source code, through the scikit learn project, and the OpenML project which provides open access to data. This reflects a tradition of openness in machine learning that has enabled the tools to be deployed. We will look at a sub-sample of the MNIST digit data set. THE MNIST DATABASE of handwritten digits was created by Yann LeCun, Corinna Cortes and Christopher J. C. Burges. More details can be found at Yann’s site http://yann.lecun.com/exdb/mnist/ The data is a modified version of a data set from the US National Institute of Standards and Technology (NIST. First load in the MNIST data set from scikit learn. This can take a little while because it’s large to download. Sub-sample the dataset to make the training faster. There are many difference examples of classification problems. One of theoldest is the classification of hand written digits from binary images. The MNIST data was for a long time considered one of the most difficult data sets. When we download this data we are making use of open source code, through the scikit learn project, and the OpenML project which provides open access to data. This reflects a tradition of openness in machine learning that has enabled the tools to be deployed. We will look at a sub-sample of the MNIST digit data set. THE MNIST DATABASE of handwritten digits was created by Yann LeCun, Corinna Cortes and Christopher J. C. Burges. More details can be found at Yann’s site http://yann.lecun.com/exdb/mnist/ The data is a modified version of a data set from the US National Institute of Standards and Technology (NIST. First load in the MNIST data set from scikit learn. This can take a little while because it’s large to download. Sub-sample the dataset to make the training faster. Now let’s visualise some examples from our subsampled dataset to get a sense of what the data looks like. Figure: Examples of MNIST digits 0-4 from our subsampled dataset, showing 5 examples of each digit. The visualization shows the variety in handwritten digits even within the same class. Each row represents a different digit (0 through 4), and each column shows a different example of that digit. While the MNIST data doesn’t capture all the nuances of the challenges we face in modern machine learning. It has been an important benchmark data set for and can still be a useful data set for learning about classfication algorithms. A logistic regression is an approach to classification which extends the linear regression models we’ve already explored. Rather than modeling the output of the function directly the assumption is that we model the log-odds with the basis functions. The odds are defined as the ratio of the probability of a positive outcome, to the probability of a negative outcome. Just as we saw in our jumper (sweater) example where \[
-\log \frac{p(\text{bought})}{p(\text{not bought})} = w_0 + w_1 \text{age} + w_2 \text{latitude}
-\] If the probability of a positive outcome is denoted by \(\pi\), then the odds are computed as \(\frac{\pi}{1-\pi}\). Odds are widely used by bookmakers in gambling, although a bookmakers odds won’t normalise: i.e. if you look at the equivalent probabilities, and sum over the probability of all outcomes the bookmakers are considering, then you won’t get one. This is how the bookmaker makes a profit. Because a probability is always between zero and one, the odds are always between \(0\) and \(\infty\). If the positive outcome is unlikely the odds are close to zero, if it is very likely then the odds become close to infinite. Taking the logarithm of the odds maps the odds from the positive half space to being across the entire real line. Odds that were between 0 and 1 (where the negative outcome was more likely) are mapped to the range between \(-\infty\) and \(0\). Odds that are greater than 1 are mapped to the range between \(0\) and \(\infty\). Considering the log odds therefore takes a number between 0 and 1 (the probability of positive outcome) and maps it to the entire real line. The function that does this is known as the logit function, \(g(p_i) = \log\frac{p_i}{1-p_i}\). This function is known as a link function. For a standard regression we take, \[
+Y /= 255 Now let’s visualise some examples from our subsampled dataset to get a sense of what the data looks like. Figure: Examples of MNIST digits 0-4 from our subsampled dataset, showing 5 examples of each digit. The visualization shows the variety in handwritten digits even within the same class. Each row represents a different digit (0 through 4), and each column shows a different example of that digit. While the MNIST data doesn’t capture all the nuances of the challenges we face in modern machine learning. It has been an important benchmark data set for and can still be a useful data set for learning about classfication algorithms. A logistic regression is an approach to classification which extends the linear regression models we’ve already explored. Rather than modeling the output of the function directly the assumption is that we model the log-odds with the basis functions. The odds are defined as the ratio of the probability of a positive outcome, to the probability of a negative outcome. Just as we saw in our jumper (sweater) example where \[
+\log \frac{p(\text{bought})}{p(\text{not bought})} = w_0 + w_1 \text{age} + w_2 \text{latitude}
+\] If the probability of a positive outcome is denoted by \(\pi\), then the odds are computed as \(\frac{\pi}{1-\pi}\). Odds are widely used by bookmakers in gambling, although a bookmakers odds won’t normalise: i.e. if you look at the equivalent probabilities, and sum over the probability of all outcomes the bookmakers are considering, then you won’t get one. This is how the bookmaker makes a profit. Because a probability is always between zero and one, the odds are always between \(0\) and \(\infty\). If the positive outcome is unlikely the odds are close to zero, if it is very likely then the odds become close to infinite. Taking the logarithm of the odds maps the odds from the positive half space to being across the entire real line. Odds that were between 0 and 1 (where the negative outcome was more likely) are mapped to the range between \(-\infty\) and \(0\). Odds that are greater than 1 are mapped to the range between \(0\) and \(\infty\). Considering the log odds therefore takes a number between 0 and 1 (the probability of positive outcome) and maps it to the entire real line. The function that does this is known as the logit function, \(g(p_i) = \log\frac{p_i}{1-p_i}\). This function is known as a link function. For a standard regression we take, \[
f(\mathbf{ x}) = \mathbf{ w}^\top
\boldsymbol{ \phi}(\mathbf{ x}),
\] if we want to perform classification we perform a logistic regression. \[
@@ -97,22 +825,47 @@
\] we can write \(\pi\) in terms of the inverse link function, \(h(\cdot)\) as \[
\pi = h(\mathbf{ w}^\top
\boldsymbol{ \phi}(\mathbf{ x})).
-\] We’ll define our prediction, objective and gradient functions below. But before we start, we need to define a basis function for our model. Let’s start with the linear basis. Given class scores \(f_k(\mathbf{ x})=\mathbf{ w}_k^\top\boldsymbol{ \phi}(\mathbf{ x})\), the softmax maps scores to probabilities: \(\pi_k = \frac{\exp(f_k)}{\sum_{j=1}^K \exp(f_j)}\). Now we have the basis function let’s define the prediction function. We’ll define our prediction, objective and gradient functions below. But before we start, we need to define a basis function for our model. Let’s start with the linear basis. Given class scores \(f_k(\mathbf{ x})=\mathbf{ w}_k^\top\boldsymbol{ \phi}(\mathbf{ x})\), the softmax maps scores to probabilities: \(\pi_k = \frac{\exp(f_k)}{\sum_{j=1}^K \exp(f_j)}\). Now we have the basis function let’s define the prediction function. This inverse of the link function is known as the logistic (thus the name logistic regression) or sometimes it is called the sigmoid function. For a particular value of the input to the link function, \(f_i = \mathbf{ w}^\top \boldsymbol{ \phi}(\mathbf{ x}_i)\) we can plot the value of the inverse link function as below. By replacing the inverse link with the sigmoid we can write \(\pi\) as a function of the input and the parameter vector as, \[
+ return 1./(1+np.exp(-f)), Phi This inverse of the link function is known as the logistic (thus the name logistic regression) or sometimes it is called the sigmoid function. For a particular value of the input to the link function, \(f_i = \mathbf{ w}^\top \boldsymbol{ \phi}(\mathbf{ x}_i)\) we can plot the value of the inverse link function as below. By replacing the inverse link with the sigmoid we can write \(\pi\) as a function of the input and the parameter vector as, \[
\pi(\mathbf{ x},\mathbf{ w}) = \frac{1}{1+\exp\left(-\mathbf{ w}^\top \boldsymbol{ \phi}(\mathbf{ x})\right)}.
-\] The process for logistic regression is as follows. Compute the output of a standard linear basis function composition (\(\mathbf{ w}^\top \boldsymbol{ \phi}(\mathbf{ x})\), as we did for linear regression) and then apply the inverse link function, \(g(\mathbf{ w}^\top \boldsymbol{ \phi}(\mathbf{ x}))\). In logistic regression this involves squashing it with the logistic (or sigmoid) function. Use this value, which now has an interpretation as a probability in a Bernoulli distribution to form the likelihood. Then we can assume conditional independence of each data point given the parameters and develop a likelihod for the entire data set. The Bernoulli likelihood is of the form, \[
+\] The process for logistic regression is as follows. Compute the output of a standard linear basis function composition (\(\mathbf{ w}^\top \boldsymbol{ \phi}(\mathbf{ x})\), as we did for linear regression) and then apply the inverse link function, \(g(\mathbf{ w}^\top \boldsymbol{ \phi}(\mathbf{ x}))\). In logistic regression this involves squashing it with the logistic (or sigmoid) function. Use this value, which now has an interpretation as a probability in a Bernoulli distribution to form the likelihood. Then we can assume conditional independence of each data point given the parameters and develop a likelihod for the entire data set. The Bernoulli likelihood is of the form, \[
P(y_i|\mathbf{ w}, \mathbf{ x}) =
\pi_i^{y_i} (1-\pi_i)^{1-y_i}
-\] which we can think of as clever trick for mathematically switching between two probabilities if we were to write it as code it would be better described as but writing it mathematically makes it easier to write our objective function within a single mathematical equation. To obtain the parameters of the model, we need to maximise the likelihood, or minimise the objective function, normally taken to be the negative log likelihood. With a data conditional independence assumption the likelihood has the form, \[
+ return 1-pi(x) but writing it mathematically makes it easier to write our objective function within a single mathematical equation. To obtain the parameters of the model, we need to maximise the likelihood, or minimise the objective function, normally taken to be the negative log likelihood. With a data conditional independence assumption the likelihood has the form, \[
P(\mathbf{ y}|\mathbf{ w},
-\mathbf{X}) = \prod_{i=1}^nP(y_i|\mathbf{ w}, \mathbf{ x}_i).
+\mathbf{X}) = \prod_{i=1}^nP(y_i|\mathbf{ w}, \mathbf{ x}_i).
\] which can be written as a log likelihood in the form \[
\log P(\mathbf{ y}|\mathbf{ w},
\mathbf{X}) = \sum_{i=1}^n\log P(y_i|\mathbf{ w}, \mathbf{ x}_i) = \sum_{i=1}^n
@@ -124,12 +877,19 @@
h\left(\mathbf{ w}^\top \boldsymbol{ \phi}(\mathbf{ x}_i)\right) -
\sum_{i=1}^n(1-y_i)\log \left(1-h\left(\mathbf{ w}^\top
\boldsymbol{ \phi}(\mathbf{ x}_i)\right)\right).
-\] As normal, we would like to minimise this objective. This can be done by differentiating with respect to the parameters of our prediction function, \(\pi(\mathbf{ x};\mathbf{ w})\), for optimisation. The gradient of the likelihood with respect to \(\pi(\mathbf{ x};\mathbf{ w})\) is of the form, \[
+ return -np.log(h[posind, :]).sum() - np.log(1-h[negind, :]).sum() As normal, we would like to minimise this objective. This can be done by differentiating with respect to the parameters of our prediction function, \(\pi(\mathbf{ x};\mathbf{ w})\), for optimisation. The gradient of the likelihood with respect to \(\pi(\mathbf{ x};\mathbf{ w})\) is of the form, \[
\frac{\text{d}E(\mathbf{ w})}{\text{d}\mathbf{ w}} = -\sum_{i=1}^n
\frac{y_i}{h\left(\mathbf{ w}^\top
\boldsymbol{ \phi}(\mathbf{ x})\right)}\frac{\text{d}h(f_i)}{\text{d}f_i}
@@ -137,41 +897,108 @@
\frac{1-y_i}{1-h\left(\mathbf{ w}^\top
\boldsymbol{ \phi}(\mathbf{ x})\right)}\frac{\text{d}h(f_i)}{\text{d}f_i}
\boldsymbol{ \phi}(\mathbf{ x}_i)
-\] where we used the chain rule to develop the derivative in terms of \(\frac{\text{d}h(f_i)}{\text{d}f_i}\), which is the gradient of the inverse link function (in our case the gradient of the sigmoid function). So the objective function now depends on the gradient of the inverse link function, as well as the likelihood depends on the gradient of the inverse link function, as well as the gradient of the log likelihood, and naturally the gradient of the argument of the inverse link function with respect to the parameters, which is simply \(\boldsymbol{ \phi}(\mathbf{ x}_i)\).Introduction
+Data Science Africa
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+DSA Ibadan, Nigeria
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Example: Prediction of Malaria Incidence in Uganda
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+(Andrade-Pacheco et al., 2014; Mubangizi et al., 2014)
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Early Warning Systems
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Machine Learning
+Rise of Machine Learning
+Data Revolution
Machine learning has risen in prominence due to the rise in data availability, and its interconnection with computers. The high bandwidth connection between data and computer leads to a new interaction between us and data via the computer. It is that channel that is being mediated by machine learning techniques.Supply Chain
Burbage Bridge
Cromford
Containerization
For Africa
Olympic Marathon Data
import importlib.utilcmd = install_command('pods')%system {cmd}import numpy as np
-import pods
+data = pods.datasets.olympic_marathon_men()
+\]
+Data Revolution
+Machine learning has risen in prominence due to the rise in data availability, and its interconnection with computers. The high bandwidth connection between data and computer leads to a new interaction between us and data via the computer. It is that channel that is being mediated by machine learning techniques.
+
+
+
+
+
+
+
+
+
+
+Supply Chain
+
+Burbage Bridge
+
+
+
+
+
+
+
+
+
+
+
+
+
+Cromford
+
+
+
+
+
+
+
+
+
+
+
+
+
+Containerization
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+For Africa
+
+
+
+
+
+
+
+
+
+
+
+Olympic Marathon Data
+
+
+
+
+
+
+
+
+
+
+
+
+
+import importlib.util
+cmd = install_command('pods')
+%system {cmd}
+import numpy as np
+import podsdata = pods.datasets.olympic_marathon_men()
x = data['X']
y = data['Y']
offset = y.mean()
scale = np.sqrt(y.var())
-yhat = (y - offset)/scalePolynomial Fits to Olympic Marthon Data
import numpy as np
-import scipy as spfrom mlai import polynomial
+def basis_fit(Phi, y):
+yhat = (y - offset)/scale
+
+
+
+
+
+
+
+
+
+Polynomial Fits to Olympic Marthon Data
+
+
+import numpy as np
+import scipy as sp
+from mlai import polynomialdef basis_fit(Phi, y):
"Use QR decomposition to fit the basis."""
Q, R = np.linalg.qr(Phi)
- return sp.linalg.solve_triangular(R, Q.T@y) Linear Fit
+poly_args = {'num_basis':2, # two basis functions (1 and x)
+ return sp.linalg.solve_triangular(R, Q.T@y) Linear Fit
+poly_args = {'num_basis':2, # two basis functions (1 and x)
'data_limits':xlim}
Phi = mlai.polynomial(x, **poly_args)
-w = basis_fit(Phi, y)
+x_pred = np.linspace(xlim[0], xlim[1], 400)[:, np.newaxis]
+w = basis_fit(Phi, y)x_pred = np.linspace(xlim[0], xlim[1], 400)[:, np.newaxis]
Phi_pred = mlai.polynomial(x_pred, **poly_args)
-f_pred = Phi_pred@wCubic Fit
+poly_args = {'num_basis':4, # four basis: 1, x, x^2, x^3
+f_pred = Phi_pred@w
+
+
+
+
+
+
+
+
+
+Cubic Fit
+poly_args = {'num_basis':4, # four basis: 1, x, x^2, x^3
'data_limits':xlim}
Phi = mlai.polynomial(x, **poly_args)
-w = basis_fit(Phi, y)Phi_pred = mlai.polynomial(x_pred, **poly_args)
-f_pred = Phi_pred@w9th Degree Polynomial Fit
+poly_args = {'num_basis':10, # basis up to x^9
+w = basis_fit(Phi, y)
+Phi_pred = mlai.polynomial(x_pred, **poly_args)
+f_pred = Phi_pred@w
+
+
+
+
+
+
+
+
+
+9th Degree Polynomial Fit
+poly_args = {'num_basis':10, # basis up to x^9
'data_limits':xlim}
Phi = mlai.polynomial(x, **poly_args)
-w = basis_fit(Phi, y)Phi_pred = mlai.polynomial(x_pred, **poly_args)
-f_pred = Phi_pred@w16th Degree Polynomial Fit
+poly_args = {'num_basis':17, # basis up to x^16
+w = basis_fit(Phi, y)
+Phi_pred = mlai.polynomial(x_pred, **poly_args)
+f_pred = Phi_pred@w
+
+
+
+
+
+
+
+
+
+16th Degree Polynomial Fit
+poly_args = {'num_basis':17, # basis up to x^16
'data_limits':xlim}
Phi = mlai.polynomial(x, **poly_args)
-w = basis_fit(Phi, y)Phi_pred = mlai.polynomial(x_pred, **poly_args)
-f_pred = Phi_pred@w28th Degree Polynomial Fit
+poly_args = {'num_basis':29, # basis up to x^28
+w = basis_fit(Phi, y)
+Phi_pred = mlai.polynomial(x_pred, **poly_args)
+f_pred = Phi_pred@w
+
+
+
+
+
+
+
+
+
+28th Degree Polynomial Fit
+poly_args = {'num_basis':29, # basis up to x^28
'data_limits':xlim}
Phi = mlai.polynomial(x, **poly_args)
-w = basis_fit(Phi, y)Phi_pred = mlai.polynomial(x_pred, **poly_args)
-f_pred = Phi_pred@wWhat does Machine Learning do?
Sigmoid Function
+Phi_pred = mlai.polynomial(x_pred, **poly_args)
+f_pred = Phi_pred@w
+
+
+
+
+
+
+
+
+
+What does Machine Learning do?
+
+Sigmoid Function
+
+
+
+
+
+
+
+
+
+
+
+What is Machine Learning?
From Model to Decision
Artificial Intelligence and Data Science
Supervised Learning for AI
Neural Networks and Prediction Functions
What is Machine Learning?
+
+From Model to Decision
+
+Artificial Intelligence and Data Science
+
+Supervised Learning for AI
+Neural Networks and Prediction Functions
+
+Relations with Classical Statistics
Adaptive Basis Functions
Machine Learning
Supervised Learning
Introduction to Classification
Relations with Classical Statistics
+Adaptive Basis Functions
+Machine Learning
+
+
+Supervised Learning
+
+Introduction to Classification
+
+Classification Examples
Subsample of the MNIST Data
from sklearn.datasets import fetch_openmlmnist = fetch_openml('mnist_784', version=1, as_frame=False, parser='liac-arff')import numpy as np
+np.random.seed(0)
+\] The function \(f(\cdot)\) is known as the prediction function. The key challenges are (1) choosing which features, \(\mathbf{ x}\), are relevant in the prediction, (2) defining the appropriate class of function, \(f(\cdot)\), to use and (3) selecting the right parameters, \(\mathbf{ w}\).
+Classification Examples
+
+Subsample of the MNIST Data
+
+
+from sklearn.datasets import fetch_openml
+mnist = fetch_openml('mnist_784', version=1, as_frame=False, parser='liac-arff')
+import numpy as npnp.random.seed(0)
digits = [0,1,2,3,4]
N_per_digit = 100
Y = []
@@ -81,9 +780,38 @@
labels.append(np.ones(N_per_digit)*d)
Y = np.vstack(Y).astype(np.float64)
labels = np.hstack(labels)
-Y /= 255MNIST Digit Examples
Logistic Regression
MNIST Digit Examples
+
+
+
+
+
+
+
+
+
+
+
+Logistic Regression
+
+import numpy as npfrom mlai import linearSoft Arg Max (Softmax) Function
Prediction Function
import numpy as np
+def predict(w, x, basis=mlai.linear, **kwargs):
+\]
+
+import numpy as np
+from mlai import linearSoft Arg Max (Softmax) Function
+
+Prediction Function
+
+
+import numpy as npdef predict(w, x, basis=mlai.linear, **kwargs):
"Generates the prediction function and the basis matrix."
Phi = basis(x, **kwargs)
f = np.dot(Phi, w)
- return 1./(1+np.exp(-f)), Phi
+def bernoulli(x, y, pi):
+\] which we can think of as clever trick for mathematically switching between two probabilities if we were to write it as code it would be better described as
+def bernoulli(x, y, pi):
if y == 1:
return pi(x)
else:
- return 1-pi(x)Maximum Likelihood
Maximum Likelihood
+
+Negative Log Likelihood
import numpy as np
+def objective(h, y):
+\]
+Negative Log Likelihood
+
+
+import numpy as npdef objective(h, y):
"Computes the objective function."
labs = np.asarray(y, dtype=float).flatten()
posind = np.where(labs==1)
negind = np.where(labs==0)
- return -np.log(h[posind, :]).sum() - np.log(1-h[negind, :]).sum()
So the objective function now depends on the gradient of the inverse link function, as well as the likelihood depends on the gradient of the inverse link function, as well as the gradient of the log likelihood, and naturally the gradient of the argument of the inverse link function with respect to the parameters, which is simply \(\boldsymbol{ \phi}(\mathbf{ x}_i)\).
+The only missing term is the gradient of the inverse link function. For the sigmoid squashing function we have, +\[\begin{aligned} +\transformationFunction(\mappingFunction_i) &= \frac{1}{1+\exp(-\mappingFunction_i)}\\ +&=(1+\exp(-\mappingFunction_i))^{-1} \end{align*}$$ and the gradient can be computed as $$\begin{align*} -\frac{\text{d}h(f_i)}{\text{d} f_i} & = -\exp(-f_i)(1+\exp(-f_i))^{-2}\\ -& = \frac{1}{1+\exp(-f_i)} -\frac{\exp(-f_i)}{1+\exp(-f_i)} \\ -& = h(f_i) (1-g(f_i)) -\end{aligned}\]so the full gradient can be written down as \[ +\frac{\text{d}\transformationFunction(\mappingFunction_i)}{\text{d} \mappingFunction_i} & = +\exp(-\mappingFunction_i)(1+\exp(-\mappingFunction_i))^{-2}\\ +& = \frac{1}{1+\exp(-\mappingFunction_i)} +\frac{\exp(-\mappingFunction_i)}{1+\exp(-\mappingFunction_i)} \\ +& = \transformationFunction(\mappingFunction_i) (1-g(\mappingFunction_i)) +\end{aligned}\] +
so the full gradient can be written down as \[ \frac{\text{d}E(\mathbf{ w})}{\text{d}\mathbf{ w}} = -\sum_{i=1}^n y_i\left(1-h\left(\mathbf{ w}^\top \boldsymbol{ \phi}(\mathbf{ x})\right)\right) \boldsymbol{ \phi}(\mathbf{ x}_i) + \sum_{i=1}^n (1-y_i)\left(h\left(\mathbf{ w}^\top \boldsymbol{ \phi}(\mathbf{ x})\right)\right) \boldsymbol{ \phi}(\mathbf{ x}_i). -\]
import numpy as npdef gradient(h, Phi, y):
+\]
+import numpy as np
+def gradient(h, Phi, y):
"Generates the gradient of the parameter vector."
labs = np.asarray(y, dtype=float).flatten()
posind = np.where(labs==1)
dw = -(Phi[posind]*(1-h[posind])).sum(0)
negind = np.where(labs==0 )
dw += (Phi[negind]*h[negind]).sum(0)
- return dw[:, None]
Optimisation of the Function
Reorganising the gradient to find a stationary point of the function with respect to the parameters \(\mathbf{ w}\) turns out to be impossible. Optimisation has to proceed by numerical methods. Options include the multidimensional variant of Newton’s method or gradient based optimisation methods like we used for optimising matrix factorisation for the movie recommender system. We recall from matrix factorisation that, for large data, stochastic gradient descent or the Robbins Munro (Robbins and Monro, 1951) optimisation procedure worked best for function minimisation.
Multiplying everything out leads to \[
-\begin{aligned}
-\frac{\text{d}E(\mathbf{ w})}{\text{d}\mathbf{ w}} = & -\sum_{i=1}^n
-y_i- h\left(\mathbf{ w}^\top \boldsymbol{ \phi}(\mathbf{ x})\boldsymbol{ \phi}(\mathbf{ x}_i).
-\]
Nigeria NMIS Data
As an example data set we will use Nigerian Millennium Development Goals Information System Health Facility (The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) and Columbia University, 2014). It can be found here https://energydata.info/dataset/nigeria-nmis-education-facility-data-2014.
Taking from the information on the site,
The Nigeria MDG (Millennium Development Goals) Information System – NMIS health facility data is collected by the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) in partner with the Sustainable Engineering Lab at Columbia University. A rigorous, geo-referenced baseline facility inventory across Nigeria is created spanning from 2009 to 2011 with an additional survey effort to increase coverage in 2014, to build Nigeria’s first nation-wide inventory of health facility. The database includes 34,139 health facilities info in Nigeria.
The goal of this database is to make the data collected available to planners, government officials, and the public, to be used to make strategic decisions for planning relevant interventions.
For data inquiry, please contact Ms. Funlola Osinupebi, Performance Monitoring & Communications, Advisory Power Team, Office of the Vice President at funlola.osinupebi@aptovp.org
To learn more, please visit http://csd.columbia.edu/2014/03/10/the-nigeria-mdg-information-system-nmis-takes-open-data-further/
Suggested citation: Nigeria NMIS facility database (2014), the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) & Columbia University
For ease of use we’ve packaged this data set in the pods library
pods
In Sheffield we created a suite of software tools for ‘Open Data Science.’ Open data science is an approach to sharing code, models and data that should make it easier for companies, health professionals and scientists to gain access to data science techniques.
You can also check this blog post on Open Data Science.
The software can be installed using
cmd = install_command('pods')
%system {cmd}
from the command prompt where you can access your python installation.
The code is also available on GitHub: https://github.com/lawrennd/ods
Once pods is installed, it can be imported in the usual manner.
import pods
data = pods.datasets.nigeria_nmis()['Y']
-data.head()
Alternatively, you can access the data directly with the following commands.
import urllib.request
+ return dw[:, None]
+Optimisation of the Function
+Reorganising the gradient to find a stationary point of the function with respect to the parameters \(\mathbf{ w}\) turns out to be impossible. Optimisation has to proceed by numerical methods. Options include the multidimensional variant of Newton’s method or gradient based optimisation methods like we used for optimising matrix factorisation for the movie recommender system. We recall from matrix factorisation that, for large data, stochastic gradient descent or the Robbins Munro (Robbins and Monro, 1951) optimisation procedure worked best for function minimisation.
+Multiplying everything out leads to \[
+\frac{\text{d}E(\mathbf{ w})}{\text{d}\mathbf{ w}} = -\sum_{i=1}^n\left(y_i - h\left(\mathbf{ w}^\top \boldsymbol{ \phi}(\mathbf{ x}_i)\right)\right)\boldsymbol{ \phi}(\mathbf{ x}_i).
+\]
+Nigeria NMIS Data
+
+As an example data set we will use Nigerian Millennium Development Goals Information System Health Facility (The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) and Columbia University, 2014). It can be found here https://energydata.info/dataset/nigeria-nmis-education-facility-data-2014.
+Taking from the information on the site,
+
+The Nigeria MDG (Millennium Development Goals) Information System – NMIS health facility data is collected by the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) in partner with the Sustainable Engineering Lab at Columbia University. A rigorous, geo-referenced baseline facility inventory across Nigeria is created spanning from 2009 to 2011 with an additional survey effort to increase coverage in 2014, to build Nigeria’s first nation-wide inventory of health facility. The database includes 34,139 health facilities info in Nigeria.
+The goal of this database is to make the data collected available to planners, government officials, and the public, to be used to make strategic decisions for planning relevant interventions.
+For data inquiry, please contact Ms. Funlola Osinupebi, Performance Monitoring & Communications, Advisory Power Team, Office of the Vice President at funlola.osinupebi@aptovp.org
+To learn more, please visit http://csd.columbia.edu/2014/03/10/the-nigeria-mdg-information-system-nmis-takes-open-data-further/
+Suggested citation: Nigeria NMIS facility database (2014), the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) & Columbia University
+
+For ease of use we’ve packaged this data set in the pods library
+pods
+
+In Sheffield we created a suite of software tools for ‘Open Data Science’. Open data science is an approach to sharing code, models and data that should make it easier for companies, health professionals and scientists to gain access to data science techniques.
+You can also check this blog post on Open Data Science.
+The software can be installed using
+cmd = install_command('pods')
+%system {cmd}
+from the command prompt where you can access your python installation.
+The code is also available on GitHub: https://github.com/lawrennd/ods
+Once pods is installed, it can be imported in the usual manner.
+import pods
+data = pods.datasets.nigeria_nmis()['Y']
+data.head()
+Alternatively, you can access the data directly with the following commands.
+import urllib.request
urllib.request.urlretrieve('https://energydata.info/dataset/f85d1796-e7f2-4630-be84-79420174e3bd/resource/6e640a13-cab4-457b-b9e6-0336051bac27/download/healthmopupandbaselinenmisfacility.csv', 'healthmopupandbaselinenmisfacility.csv')
import pandas as pd
-data = pd.read_csv('healthmopupandbaselinenmisfacility.csv')
Once it is loaded in the data can be summarized using the describe method in pandas.
data.describe()
We can also find out the dimensions of the dataset using the shape property.
data.shape
Dataframes have different functions that you can use to explore and understand your data. In python and the Jupyter notebook it is possible to see a list of all possible functions and attributes by typing the name of the object followed by .<Tab> for example in the above case if we type data.<Tab> it show the columns available (these are attributes in pandas dataframes) such as num_nurses_fulltime, and also functions, such as .describe().
For functions we can also see the documentation about the function by following the name with a question mark. This will open a box with documentation at the bottom which can be closed with the x button.
data.describe?
Figure: Location of the over thirty-four thousand health facilities registered in the NMIS data across Nigeria. Each facility plotted according to its latitude and longitude.
Nigeria NMIS Data Classification
Our aim will be to predict whether a center has maternal health delivery services given the attributes in the data. We will predict of the number of nurses, the number of doctors, location etc.
Now we will convert this data into a form which we can use as inputs X, and labels y.
import pandas as pd
-import numpy as np
data = data[~pd.isnull(data['maternal_health_delivery_services'])]
+data = pd.read_csv('healthmopupandbaselinenmisfacility.csv')
+Once it is loaded in the data can be summarized using the describe method in pandas.
+data.describe()
+We can also find out the dimensions of the dataset using the shape property.
+data.shape
+Dataframes have different functions that you can use to explore and understand your data. In python and the Jupyter notebook it is possible to see a list of all possible functions and attributes by typing the name of the object followed by .<Tab> for example in the above case if we type data.<Tab> it show the columns available (these are attributes in pandas dataframes) such as num_nurses_fulltime, and also functions, such as .describe().
+For functions we can also see the documentation about the function by following the name with a question mark. This will open a box with documentation at the bottom which can be closed with the x button.
+data.describe?
+
+
+
+
+
+
+
+
+
+
+Figure: Location of the over thirty-four thousand health facilities registered in the NMIS data across Nigeria. Each facility plotted according to its latitude and longitude.
+
+
+Nigeria NMIS Data Classification
+
+Our aim will be to predict whether a center has maternal health delivery services given the attributes in the data. We will predict of the number of nurses, the number of doctors, location etc.
+Now we will convert this data into a form which we can use as inputs X, and labels y.
+import pandas as pd
+import numpy as np
+data = data[~pd.isnull(data['maternal_health_delivery_services'])]
data = data.dropna() # Remove entries with missing values
X = data[['emergency_transport',
'num_chews_fulltime',
@@ -201,7 +1028,15 @@
type_col=htype.replace(' ', '_').replace('/','-').lower()
type_names.append(type_col)
X.loc[:, type_col] = 0.0
- X.loc[index, type_col] = 1.0
This has given us a new data frame X which contains the different facility types in different columns.
X.describe()
Batch Gradient Descent
We will need to define some initial random values for our vector and then minimize the objective by descending the gradient.
# Separate train and test
+ X.loc[index, type_col] = 1.0
+This has given us a new data frame X which contains the different facility types in different columns.
+X.describe()
+Batch Gradient Descent
+
+We will need to define some initial random values for our vector and then minimize the objective by descending the gradient.
+# Separate train and test
indices = np.random.permutation(X.shape[0])
num_train = int(np.ceil(X.shape[0]/2))
train_indices = indices[:num_train]
@@ -217,7 +1052,9 @@
y_test = y.iloc[test_indices]==True
else:
y_train = np.asarray(y).flatten()[train_indices]==True
- y_test = np.asarray(y).flatten()[test_indices]==True
import numpy as np
# gradient descent algorithm
+ y_test = np.asarray(y).flatten()[test_indices]==True
+import numpy as np
+# gradient descent algorithm
w_vals = np.random.normal(size=(X.shape[1]+1, 1), scale = 0.001)
# Convert weights to a pandas DataFrame with column names
if type(X_train) is pd.DataFrame:
@@ -233,7 +1070,10 @@
g, Phi = predict(w, X_train, mlai.linear)
w -= eta*gradient(g, Phi, y_train) + 0.001*w
if not i % 100:
- print("Iter", i, "Objective", objective(g, y_train))
Let’s look at the weights and how they relate to the inputs.
import matplotlib.pyplot as plt
# Plot a histogram of the weights
+ print("Iter", i, "Objective", objective(g, y_train))
+Let’s look at the weights and how they relate to the inputs.
+import matplotlib.pyplot as plt
+# Plot a histogram of the weights
plt.figure(figsize=(10, 6))
if type(w) is pd.DataFrame:
plt.bar(w.index, w['weight'])
@@ -244,18 +1084,267 @@
plt.ylabel('Weight Value')
plt.title('Histogram of Model Weights')
plt.tight_layout()
-mlai.write_figure('nmis-logistic-regression-weights.svg', directory='./ml')
Exercise 1
What does the magnitude of the weight vectors tell you about the different parameters and their influence on outcome? Are the weights of roughly the same size, if not, how might you fix this?
g_test, Phi_test = predict(w, X_test, mlai.linear)
-np.sum(g_test[y_test]>0.5)
Stochastic Gradient Descent
Exercise 2
Now construct a stochastic gradient descent algorithm and run it on the data. Is it faster or slower than batch gradient descent? What can you do to improve convergence speed?
Regression
Classification is the case where our prediction function gives a discrete valued output, normally associated with a ‘class.’ Regression is an alternative approach where the aim is to predict a continuous output.
The name is a historical accident, it would be better to call regression ‘curve fitting,’ or even split it into two parts ‘interpolation,’ which is the practice of predicting a function value between existing data, and ‘extrapolation,’ which is the practice of predicting a function value beyond the regime where we have data.
Regression Examples
Regression involves predicting a real value, \(y_i\), given an input vector, \(\mathbf{ x}_i\). For example, the Tecator data involves predicting the quality of meat given spectral measurements. Or in radiocarbon dating, the C14 calibration curve maps from radiocarbon age to age measured through a back-trace of tree rings. Regression has also been used to predict the quality of board game moves given expert rated training data.
Supervised Learning Challenges
There are three principal challenges in constructing a problem for supervised learning.
- choosing which features, \(\mathbf{ x}\), are relevant in the prediction
- defining the appropriate class of function, \(f(\cdot)\).
- selecting the right parameters, \(\mathbf{ w}\).
Feature Selection
Feature selection is a critical stage in the algorithm design process. In the Olympic prediction example above we’re only using time to predict the the pace of the runners. In practice we might also want to use characteristics of the course: how hilly it is, what the temperature was when the race was run. In 1904 the runners actually got lost during the race. Should we include ‘lost’ as a feature? It would certainly help explain the particularly slow time in 1904. The features we select should be ones we expect to correlate with the prediction. In statistics, these features are even called predictors which highlights their role in developing the prediction function. For Facebook newsfeed, we might use features that include how close your friendship is with the poster, or how often you react to that poster, or whether a photo is included in the post.
Sometimes we use feature selection algorithms, algorithms that automate the process of finding the features that we need. Classification is often used to rank search results, to decide which adverts to serve or, at Facebook, to determine what appears at the top of your newsfeed. In the Facebook example features might include how many likes a post has had, whether it has an image in it, whether you regularly interact with the friend who has posted. A good newsfeed ranking algorithm is critical to Facebook’s success, just as good ad serving choice is critical to Google’s success. These algorithms are in turn highly dependent on the feature sets used. Facebook in particular has made heavy investments in machine learning pipelines for evaluation of the feature utility.
Class of Function, \(f(\cdot)\)
By class of function we mean, what are the characteristics of the mapping between \(\mathbf{x}\) and \(y\). Often, we might choose it to be a smooth function. Sometimes we will choose it to be a linear function. If the prediction is a forecast, for example the demand of a particular product, then the function would need some periodic components to reflect seasonal or weekly effects.
Analysis of US Birth Rates
\akiVehtariPicture{15%}
Figure: This is a retrospective analysis of US births by Aki Vehtari. The challenges of forecasting. Even with seasonal and weekly effects removed there are significant effects on holidays, weekends, etc.
There’s a nice analysis of US birth rates by Gaussian processes with additive covariances in Gelman et al. (2013). A combination of covariance functions are used to take account of weekly and yearly trends. The analysis is summarized on the cover of the book.
Figure: Two different editions of Bayesian Data Analysis (Gelman et al., 2013).
In the ImageNet challenge the input, \(\mathbf{ x}\), was in the form of an image. And the form of the prediction function was a convolutional neural network (more on this later). A convolutional neural network introduces invariances into the function that are particular to image classification. An invariance is a transformation of the input that we don’t want to affect the output. For example, a cat in an image is still a cat no matter where it’s located in the image (translation). The cat is also a cat regardless of how large it is (scale), or whether it’s upside-down (rotation). Convolutional neural networks encode these invariances: scale invariance, rotation invariance and translation invariance; in the mathematical function.
Encoding invariance in the prediction function is like encoding knowledge in the model. If we don’t specify these invariances, then the model must learn them. This will require a lot more data to achieve the same performance, making the model less data efficient. Note that one invariance that is not encoded in a convolutional network is invariance to camera type. As a result, practitioners need to be careful to ensure that their training data is representative of the type of cameras that will be used when the model is deployed.
In general the prediction function could be any set of parameterized functions. In the Olympic marathon data example above we used a polynomial fit, \[
+mlai.write_figure('nmis-logistic-regression-weights.svg', directory='./ml')
What does the magnitude of the weight vectors tell you about the different parameters and their influence on outcome? Are the weights of roughly the same size, if not, how might you fix this?
+g_test, Phi_test = predict(w, X_test, mlai.linear)
+np.sum(g_test[y_test]>0.5)Now construct a stochastic gradient descent algorithm and run it on the data. Is it faster or slower than batch gradient descent? What can you do to improve convergence speed?
+Classification is the case where our prediction function gives a discrete valued output, normally associated with a ‘class’. Regression is an alternative approach where the aim is to predict a continuous output.
+The name is a historical accident, it would be better to call regression ‘curve fitting’, or even split it into two parts ‘interpolation’, which is the practice of predicting a function value between existing data, and ‘extrapolation’, which is the practice of predicting a function value beyond the regime where we have data.
+Regression involves predicting a real value, \(y_i\), given an input vector, \(\mathbf{ x}_i\). For example, the Tecator data involves predicting the quality of meat given spectral measurements. Or in radiocarbon dating, the C14 calibration curve maps from radiocarbon age to age measured through a back-trace of tree rings. Regression has also been used to predict the quality of board game moves given expert rated training data.
+There are three principal challenges in constructing a problem for supervised learning.
+Feature selection is a critical stage in the algorithm design process. In the Olympic prediction example above we’re only using time to predict the the pace of the runners. In practice we might also want to use characteristics of the course: how hilly it is, what the temperature was when the race was run. In 1904 the runners actually got lost during the race. Should we include ‘lost’ as a feature? It would certainly help explain the particularly slow time in 1904. The features we select should be ones we expect to correlate with the prediction. In statistics, these features are even called predictors which highlights their role in developing the prediction function. For Facebook newsfeed, we might use features that include how close your friendship is with the poster, or how often you react to that poster, or whether a photo is included in the post.
+Sometimes we use feature selection algorithms, algorithms that automate the process of finding the features that we need. Classification is often used to rank search results, to decide which adverts to serve or, at Facebook, to determine what appears at the top of your newsfeed. In the Facebook example features might include how many likes a post has had, whether it has an image in it, whether you regularly interact with the friend who has posted. A good newsfeed ranking algorithm is critical to Facebook’s success, just as good ad serving choice is critical to Google’s success. These algorithms are in turn highly dependent on the feature sets used. Facebook in particular has made heavy investments in machine learning pipelines for evaluation of the feature utility.
+By class of function we mean, what are the characteristics of the mapping between \(\mathbf{x}\) and \(y\). Often, we might choose it to be a smooth function. Sometimes we will choose it to be a linear function. If the prediction is a forecast, for example the demand of a particular product, then the function would need some periodic components to reflect seasonal or weekly effects.
+
+Figure: This is a retrospective analysis of US births by Aki Vehtari. The challenges of forecasting. Even with seasonal and weekly effects removed there are significant effects on holidays, weekends, etc.
+There’s a nice analysis of US birth rates by Gaussian processes with additive covariances in Gelman et al. (2013). A combination of covariance functions are used to take account of weekly and yearly trends. The analysis is summarized on the cover of the book.
+
+
+Figure: Two different editions of Bayesian Data Analysis (Gelman et al., 2013).
+In the ImageNet challenge the input, \(\mathbf{ x}\), was in the form of an image. And the form of the prediction function was a convolutional neural network (more on this later). A convolutional neural network introduces invariances into the function that are particular to image classification. An invariance is a transformation of the input that we don’t want to affect the output. For example, a cat in an image is still a cat no matter where it’s located in the image (translation). The cat is also a cat regardless of how large it is (scale), or whether it’s upside-down (rotation). Convolutional neural networks encode these invariances: scale invariance, rotation invariance and translation invariance; in the mathematical function.
+Encoding invariance in the prediction function is like encoding knowledge in the model. If we don’t specify these invariances, then the model must learn them. This will require a lot more data to achieve the same performance, making the model less data efficient. Note that one invariance that is not encoded in a convolutional network is invariance to camera type. As a result, practitioners need to be careful to ensure that their training data is representative of the type of cameras that will be used when the model is deployed.
+In general the prediction function could be any set of parameterized functions. In the Olympic marathon data example above we used a polynomial fit, \[ f(x) = w_0 + w_1 x+ w_2 x^2 + w_3 x^3 + w_4 x^4. -\] The Olympic example is also a supervised learning challenge. But it is a regression problem. A regression problem is one where the output is a continuous value (such as the pace in the marathon). In classification the output is constrained to be discrete. For example, classifying whether or not an image contains a dog implies the output is binary. An early example of a regression problem used in machine learning was the Tecator data, where the fat, water and protein content of meat samples was predicted as a function of the absorption of infrared light.
One class of function that has become popular recently is neural network functions, in particular deep neural networks. The ImageNet challenge uses convolutional neural networks which introduce a translation invariance to the prediction function.
It’s impressive that only this additional invariance is enough to improve performance so much, particularly when we know that rotational invariances and scale invariances are also applicable for object detection in images.
Classical statistical models and simple machine learning models have a great deal in common. The main difference between the fields is philosophical. Machine learning practitioners are typically more concerned with the quality of prediciton (e.g. measured by ROC curve) while statisticians tend to focus more on the interpretability of the model and the validity of any decisions drawn from that interpretation. For example, a statistical model may be used to validate whether a large scale intervention (such as the mass provision of mosquito nets) has had a long term effect on disease (such as malaria). In this case one of the covariates is likely to be the provision level of nets in a particular region. The response variable would be the rate of malaria disease in the region. The parmaeter, \(\beta_1\) associated with that covariate will demonstrate a positive or negative effect which would be validated in answering the question. The focus in statistics would be less on the accuracy of the response variable and more on the validity of the interpretation of the effect variable, \(\beta_1\).
A machine learning practitioner on the other hand would typically denote the parameter \(w_1\), instead of \(\beta_1\) and would only be interested in the output of the prediction function, \(f(\cdot)\) rather than the parameter itself. The general formalism of the prediction function allows for non-linear models. In machine learning, the emphasis on prediction over interpretability means that non-linear models are often used. The parameters, \(\mathbf{w}\), are a means to an end (good prediction) rather than an end in themselves (interpretable).
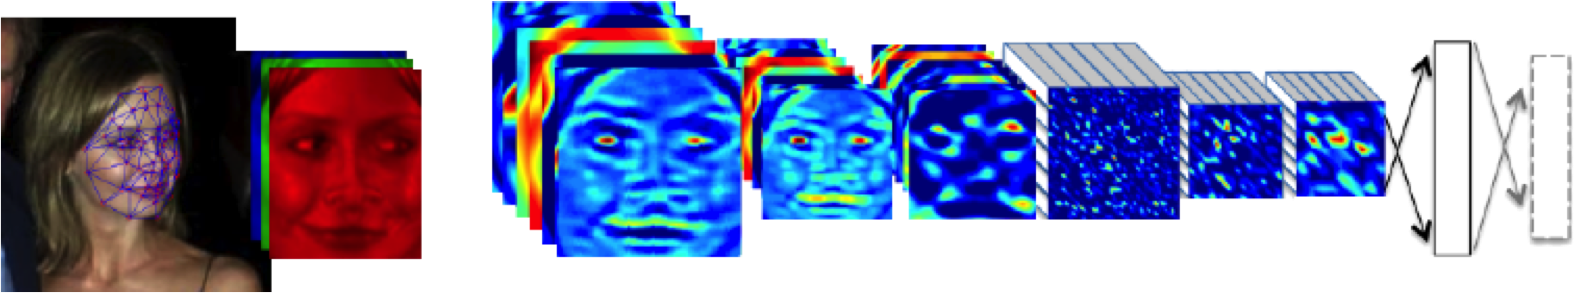
Figure: The DeepFace architecture (Taigman et al., 2014), visualized through colors to represent the functional mappings at each layer. There are 120 million parameters in the model.
The DeepFace architecture (Taigman et al., 2014) consists of layers that deal with translation invariances, known as convolutional layers. These layers are followed by three locally-connected layers and two fully-connected layers. Color illustrates feature maps produced at each layer. The neural network includes more than 120 million parameters, where more than 95% come from the local and fully connected layers.
Figure: Deep learning models are composition of simple functions. We can think of a pinball machine as an analogy. Each layer of pins corresponds to one of the layers of functions in the model. Input data is represented by the location of the ball from left to right when it is dropped in from the top. Output class comes from the position of the ball as it leaves the pins at the bottom.
Sometimes deep learning models are described as being like the brain, or too complex to understand, but one analogy I find useful to help the gist of these models is to think of them as being similar to early pin ball machines.
In a deep neural network, we input a number (or numbers), whereas in pinball, we input a ball.
Think of the location of the ball on the left-right axis as a single number. Our simple pinball machine can only take one number at a time. As the ball falls through the machine, each layer of pins can be thought of as a different layer of ‘neurons.’ Each layer acts to move the ball from left to right.
In a pinball machine, when the ball gets to the bottom it might fall into a hole defining a score, in a neural network, that is equivalent to the decision: a classification of the input object.
An image has more than one number associated with it, so it is like playing pinball in a hyper-space.
Figure: At initialization, the pins, which represent the parameters of the function, aren’t in the right place to bring the balls to the correct decisions.
Figure: After learning the pins are now in the right place to bring the balls to the correct decisions.
Learning involves moving all the pins to be in the correct position, so that the ball ends up in the right place when it’s fallen through the machine. But moving all these pins in hyperspace can be difficult.
In a hyper-space you have to put a lot of data through the machine for to explore the positions of all the pins. Even when you feed many millions of data points through the machine, there are likely to be regions in the hyper-space where no ball has passed. When future test data passes through the machine in a new route unusual things can happen.
Adversarial examples exploit this high dimensional space. If you have access to the pinball machine, you can use gradient methods to find a position for the ball in the hyper space where the image looks like one thing, but will be classified as another.
Probabilistic methods explore more of the space by considering a range of possible paths for the ball through the machine. This helps to make them more data efficient and gives some robustness to adversarial examples.
Knowledge that is not encoded in the prediction function must be learned through data. So any unspecified invariance (such as rotational or scale invariances) must be learned through the data. This means that learning would require a lot more data than otherwise would be necessary and results in less data efficient algorithms.
The choice of predication funciton and invariances is therefore a critical stage in designing your machine learning algorithm. Unfortunately many invariances are non-trivial to incorporate and many machine learning algorithms focus on simpler concepts such as linearity or smoothness.
Once we have a set of features, and the class of functions we use is determined, we need to find the parameters of the model.
The parameters of the model, \(\mathbf{ w}\), are estimated by specifying an objective function. The objective function specifies the quality of the match between the prediction function and the training data. In supervised learning the objective function incorporates both the input data (in the ImageNet data the image, in the Olympic marathon data the year of the marathon) and a label.
The label is where the term supervised learning comes from. The idea being that a supervisor, or annotator, has already looked at the data and given it labels. For regression problem, a typical objective function is the squared error, \[ +\] The Olympic example is also a supervised learning challenge. But it is a regression problem. A regression problem is one where the output is a continuous value (such as the pace in the marathon). In classification the output is constrained to be discrete. For example, classifying whether or not an image contains a dog implies the output is binary. An early example of a regression problem used in machine learning was the Tecator data, where the fat, water and protein content of meat samples was predicted as a function of the absorption of infrared light.
+One class of function that has become popular recently is neural network functions, in particular deep neural networks. The ImageNet challenge uses convolutional neural networks which introduce a translation invariance to the prediction function.
+It’s impressive that only this additional invariance is enough to improve performance so much, particularly when we know that rotational invariances and scale invariances are also applicable for object detection in images.
+Classical statistical models and simple machine learning models have a great deal in common. The main difference between the fields is philosophical. Machine learning practitioners are typically more concerned with the quality of prediciton (e.g. measured by ROC curve) while statisticians tend to focus more on the interpretability of the model and the validity of any decisions drawn from that interpretation. For example, a statistical model may be used to validate whether a large scale intervention (such as the mass provision of mosquito nets) has had a long term effect on disease (such as malaria). In this case one of the covariates is likely to be the provision level of nets in a particular region. The response variable would be the rate of malaria disease in the region. The parmaeter, \(\beta_1\) associated with that covariate will demonstrate a positive or negative effect which would be validated in answering the question. The focus in statistics would be less on the accuracy of the response variable and more on the validity of the interpretation of the effect variable, \(\beta_1\).
+A machine learning practitioner on the other hand would typically denote the parameter \(w_1\), instead of \(\beta_1\) and would only be interested in the output of the prediction function, \(f(\cdot)\) rather than the parameter itself. The general formalism of the prediction function allows for non-linear models. In machine learning, the emphasis on prediction over interpretability means that non-linear models are often used. The parameters, \(\mathbf{w}\), are a means to an end (good prediction) rather than an end in themselves (interpretable).
+ +
+Figure: The DeepFace architecture (Taigman et al., 2014), visualized through colors to represent the functional mappings at each layer. There are 120 million parameters in the model.
+The DeepFace architecture (Taigman et al., 2014) consists of layers that deal with translation invariances, known as convolutional layers. These layers are followed by three locally-connected layers and two fully-connected layers. Color illustrates feature maps produced at each layer. The neural network includes more than 120 million parameters, where more than 95% come from the local and fully connected layers.
+
+Figure: Deep learning models are composition of simple functions. We can think of a pinball machine as an analogy. Each layer of pins corresponds to one of the layers of functions in the model. Input data is represented by the location of the ball from left to right when it is dropped in from the top. Output class comes from the position of the ball as it leaves the pins at the bottom.
+Sometimes deep learning models are described as being like the brain, or too complex to understand, but one analogy I find useful to help the gist of these models is to think of them as being similar to early pin ball machines.
+In a deep neural network, we input a number (or numbers), whereas in pinball, we input a ball.
+Think of the location of the ball on the left-right axis as a single number. Our simple pinball machine can only take one number at a time. As the ball falls through the machine, each layer of pins can be thought of as a different layer of ‘neurons’. Each layer acts to move the ball from left to right.
+In a pinball machine, when the ball gets to the bottom it might fall into a hole defining a score, in a neural network, that is equivalent to the decision: a classification of the input object.
+An image has more than one number associated with it, so it is like playing pinball in a hyper-space.
+Figure: At initialization, the pins, which represent the parameters of the function, aren’t in the right place to bring the balls to the correct decisions.
+Figure: After learning the pins are now in the right place to bring the balls to the correct decisions.
+Learning involves moving all the pins to be in the correct position, so that the ball ends up in the right place when it’s fallen through the machine. But moving all these pins in hyperspace can be difficult.
+In a hyper-space you have to put a lot of data through the machine for to explore the positions of all the pins. Even when you feed many millions of data points through the machine, there are likely to be regions in the hyper-space where no ball has passed. When future test data passes through the machine in a new route unusual things can happen.
+Adversarial examples exploit this high dimensional space. If you have access to the pinball machine, you can use gradient methods to find a position for the ball in the hyper space where the image looks like one thing, but will be classified as another.
+Probabilistic methods explore more of the space by considering a range of possible paths for the ball through the machine. This helps to make them more data efficient and gives some robustness to adversarial examples.
+Knowledge that is not encoded in the prediction function must be learned through data. So any unspecified invariance (such as rotational or scale invariances) must be learned through the data. This means that learning would require a lot more data than otherwise would be necessary and results in less data efficient algorithms.
+The choice of predication funciton and invariances is therefore a critical stage in designing your machine learning algorithm. Unfortunately many invariances are non-trivial to incorporate and many machine learning algorithms focus on simpler concepts such as linearity or smoothness.
+Once we have a set of features, and the class of functions we use is determined, we need to find the parameters of the model.
+The parameters of the model, \(\mathbf{ w}\), are estimated by specifying an objective function. The objective function specifies the quality of the match between the prediction function and the training data. In supervised learning the objective function incorporates both the input data (in the ImageNet data the image, in the Olympic marathon data the year of the marathon) and a label.
+The label is where the term supervised learning comes from. The idea being that a supervisor, or annotator, has already looked at the data and given it labels. For regression problem, a typical objective function is the squared error, \[ E(\mathbf{ w}) = \sum_{i=1}^n(y_i - f(\mathbf{ x}_i))^2 -\] where the data is provided to us as a set of \(n\) inputs, \(\mathbf{ x}_1\), \(\mathbf{ x}_2\), \(\mathbf{ x}_3\), \(\dots\), \(\mathbf{ x}_n\) each one with an associated label, \(y_1\), \(y_2\), \(y_3\), \(\dots\), \(y_n\). Sometimes the label is cheap to acquire. For example, in Newsfeed ranking Facebook are acquiring a label each time a user clicks on a post in their Newsfeed. Similarly, in ad-click prediction labels are obtained whenever an advert is clicked. More generally though, we have to employ human annotators to label the data. For example, ImageNet, the breakthrough deep learning result was annotated using Amazon’s Mechanical Turk. Without such large scale human input, we would not have the breakthrough results on image categorization we have today.
Some tasks are easier to annotate than others. For example, in the Tecator data, to acquire the actual values of water, protein and fat content in the meat samples further experiments may be required. It is not simply a matter of human labelling. Even if the task is easy for humans to solve there can be problems. For example, humans will extrapolate the context of an image. A colleague mentioned once to me a challenge where humans were labelling images as containing swimming pools, even though none was visible, because they could infer there must be a pool nearby, perhaps because there are kids wearing bathing suits. But there is no swimming pool in the image for the computer to find. The quality of any machine learning solution is very sensitive to the quality of annotated data we have. Investing in processes and tools to improve annotation of data is therefore priority for improving the quality of machine learning solutions.
There can also be significant problems with misrepresentation in the data set. If data isn’t collected carefully, then it can reflect biases about the population that we don’t want our models to have. For example, if we design a face detector using Californians may not perform well when deployed in Kampala, Uganda.
Once a supervised learning system is trained it can be placed in a sequential pipeline to automate a process that used to be done manually.
Supervised learning is one of the dominant approaches to learning. But the cost and time associated with labeling data is a major bottleneck for deploying machine learning systems. The process for creating training data requires significant human intervention. For example, internationalization of a speech recognition system would require large speech corpora in new languages.
An important distinction in machine learning is the separation between training data and test data (or production data). Training data is the data that was used to find the model parameters. Test data (or production data) is the data that is used with the live system. The ability of a machine learning system to predict well on production systems given only its training data is known as its generalization ability. This is the system’s ability to predict in areas where it hasn’t previously seen data.
import numpy as np
-import pods
data = pods.datasets.olympic_marathon_men()
+\] where the data is provided to us as a set of \(n\) inputs, \(\mathbf{ x}_1\), \(\mathbf{ x}_2\), \(\mathbf{ x}_3\), \(\dots\), \(\mathbf{ x}_n\) each one with an associated label, \(y_1\), \(y_2\), \(y_3\), \(\dots\), \(y_n\). Sometimes the label is cheap to acquire. For example, in Newsfeed ranking Facebook are acquiring a label each time a user clicks on a post in their Newsfeed. Similarly, in ad-click prediction labels are obtained whenever an advert is clicked. More generally though, we have to employ human annotators to label the data. For example, ImageNet, the breakthrough deep learning result was annotated using Amazon’s Mechanical Turk. Without such large scale human input, we would not have the breakthrough results on image categorization we have today.
+Some tasks are easier to annotate than others. For example, in the Tecator data, to acquire the actual values of water, protein and fat content in the meat samples further experiments may be required. It is not simply a matter of human labelling. Even if the task is easy for humans to solve there can be problems. For example, humans will extrapolate the context of an image. A colleague mentioned once to me a challenge where humans were labelling images as containing swimming pools, even though none was visible, because they could infer there must be a pool nearby, perhaps because there are kids wearing bathing suits. But there is no swimming pool in the image for the computer to find. The quality of any machine learning solution is very sensitive to the quality of annotated data we have. Investing in processes and tools to improve annotation of data is therefore priority for improving the quality of machine learning solutions.
+There can also be significant problems with misrepresentation in the data set. If data isn’t collected carefully, then it can reflect biases about the population that we don’t want our models to have. For example, if we design a face detector using Californians may not perform well when deployed in Kampala, Uganda.
+Generalization and Overfitting
+
+Once a supervised learning system is trained it can be placed in a sequential pipeline to automate a process that used to be done manually.
+Supervised learning is one of the dominant approaches to learning. But the cost and time associated with labeling data is a major bottleneck for deploying machine learning systems. The process for creating training data requires significant human intervention. For example, internationalization of a speech recognition system would require large speech corpora in new languages.
+An important distinction in machine learning is the separation between training data and test data (or production data). Training data is the data that was used to find the model parameters. Test data (or production data) is the data that is used with the live system. The ability of a machine learning system to predict well on production systems given only its training data is known as its generalization ability. This is the system’s ability to predict in areas where it hasn’t previously seen data.
+import numpy as np
+import pods
+data = pods.datasets.olympic_marathon_men()
x = data['X']
y = data['Y']
offset = y.mean()
scale = np.sqrt(y.var())
-yhat = (y - offset)/scale
Hold Out Validation on Olympic Marathon Data
Figure: Olympic marathon data with validation error for extrapolation.
Extrapolation
Interpolation
Figure: Olympic marathon data with validation error for interpolation.
Choice of Validation Set
Hold Out Data
You have a conclusion as to which model fits best under the training error, but how do the two models perform in terms of validation? In this section we consider hold out validation. In hold out validation we remove a portion of the training data for validating the model on. The remaining data is used for fitting the model (training). Because this is a time series prediction, it makes sense for us to hold out data at the end of the time series. This means that we are validating on future predictions. We will hold out data from after 1980 and fit the model to the data before 1980.
# select indices of data to 'hold out'
+yhat = (y - offset)/scale
+Hold Out Validation on Olympic Marathon Data
+
+
+
+
+
+
+
+
+
+Figure: Olympic marathon data with validation error for extrapolation.
+
+
+Extrapolation
+Interpolation
+
+
+
+
+
+
+
+
+Figure: Olympic marathon data with validation error for interpolation.
+
+
+Choice of Validation Set
+Hold Out Data
+You have a conclusion as to which model fits best under the training error, but how do the two models perform in terms of validation? In this section we consider hold out validation. In hold out validation we remove a portion of the training data for validating the model on. The remaining data is used for fitting the model (training). Because this is a time series prediction, it makes sense for us to hold out data at the end of the time series. This means that we are validating on future predictions. We will hold out data from after 1980 and fit the model to the data before 1980.
+# select indices of data to 'hold out'
indices_hold_out = np.flatnonzero(x>1980)
# Create a training set
@@ -264,27 +1353,58 @@
# Create a hold out set
x_valid = np.take(x, indices_hold_out, axis=0)
-y_valid = np.take(y, indices_hold_out, axis=0)
Exercise 3
For both the linear and quadratic models, fit the model to the data up until 1980 and then compute the error on the held out data (from 1980 onwards). Which model performs better on the validation data?
Richer Basis Set
Now we have an approach for deciding which model to retain, we can consider the entire family of polynomial bases, with arbitrary degrees.
Exercise 4
Now we are going to build a more sophisticated form of basis function, one that can accept arguments to its inputs (similar to those we used in this lab). Here we will start with a polynomial basis.
def polynomial(x, degree, loc, scale):
+y_valid = np.take(y, indices_hold_out, axis=0)
For both the linear and quadratic models, fit the model to the data up until 1980 and then compute the error on the held out data (from 1980 onwards). Which model performs better on the validation data?
+Now we have an approach for deciding which model to retain, we can consider the entire family of polynomial bases, with arbitrary degrees.
+Now we are going to build a more sophisticated form of basis function, one that can accept arguments to its inputs (similar to those we used in this lab). Here we will start with a polynomial basis.
+def polynomial(x, degree, loc, scale):
degrees =np.arange(degree+1)
- return ((x-loc)/scale)**degreesThe basis as we’ve defined it has three arguments as well as the input. The degree of the polynomial, the scale of the polynomial and the offset. These arguments need to be passed to the basis functions whenever they are called. Modify your code to pass these additional arguments to the python function for creating the basis. Do this for each of your functions predict, fit and objective. You will find *args (or **kwargs) useful.
Write code that tries to fit different models to the data with polynomial basis. Use a maximum degree for your basis from 0 to 17. For each polynomial store the hold out validation error and the training error. When you have finished the computation plot the hold out error for your models and the training error for your p. When computing your polynomial basis use offset=1956. and scale=120. to ensure that the data is mapped (roughly) to the -1, 1 range.
Which polynomial has the minimum training error? Which polynomial has the minimum validation error?
One of Breiman’s ideas for improving predictive performance is known as bagging (Breiman, 1996). The idea is to train a number of models on the data such that they overfit (high variance). Then average the predictions of these models. The models are trained on different bootstrap samples (Efron, 1979) and their predictions are aggregated giving us the acronym, Bagging. By combining decision trees with bagging, we recover random forests (Breiman, 2001).
Bias and variance can also be estimated through Efron’s bootstrap (Efron, 1979), and the traditional view has been that there’s a form of Goldilocks effect, where the best predictions are given by the model that is ‘just right’ for the amount of data available. Not to simple, not too complex. The idea is that bias decreases with increasing model complexity and variance increases with increasing model complexity. Typically plots begin with the Mummy bear on the left (too much bias) end with the Daddy bear on the right (too much variance) and show a dip in the middle where the Baby bear (just) right finds themselves.
The Daddy bear is typically positioned at the point where the model can exactly interpolate the data. For a generalized linear model (McCullagh and Nelder, 1989), this is the point at which the number of parameters is equal to the number of data3.
The bias-variance decomposition (Geman et al., 1992) considers the expected test error for different variations of the training data sampled from, \(\mathbb{P}(\mathbf{ x}, y)\) \[\begin{align*}
+ return ((x-loc)/scale)**degrees
+ The basis as we’ve defined it has three arguments as well as the input. The degree of the polynomial, the scale of the polynomial and the offset. These arguments need to be passed to the basis functions whenever they are called. Modify your code to pass these additional arguments to the python function for creating the basis. Do this for each of your functions Write code that tries to fit different models to the data with polynomial basis. Use a maximum degree for your basis from 0 to 17. For each polynomial store the hold out validation error and the training error. When you have finished the computation plot the hold out error for your models and the training error for your p. When computing your polynomial basis use Which polynomial has the minimum training error? Which polynomial has the minimum validation error? One of Breiman’s ideas for improving predictive performance is known as bagging (Breiman, 1996). The idea is to train a number of models on the data such that they overfit (high variance). Then average the predictions of these models. The models are trained on different bootstrap samples (Efron, 1979) and their predictions are aggregated giving us the acronym, Bagging. By combining decision trees with bagging, we recover random forests (Breiman, 2001). Bias and variance can also be estimated through Efron’s bootstrap (Efron, 1979), and the traditional view has been that there’s a form of Goldilocks effect, where the best predictions are given by the model that is ‘just right’ for the amount of data available. Not to simple, not too complex. The idea is that bias decreases with increasing model complexity and variance increases with increasing model complexity. Typically plots begin with the Mummy bear on the left (too much bias) end with the Daddy bear on the right (too much variance) and show a dip in the middle where the Baby bear (just) right finds themselves. The Daddy bear is typically positioned at the point where the model can exactly interpolate the data. For a generalized linear model (McCullagh and Nelder, 1989), this is the point at which the number of parameters is equal to the number of data3. The bias-variance decomposition (Geman et al., 1992) considers the expected test error for different variations of the training data sampled from, \(\mathbb{P}(\mathbf{ x}, y)\) \[\begin{align*}
R(\mathbf{ w}) = & \int \left(y- f^*(\mathbf{ x})\right)^2 \mathbb{P}(y, \mathbf{ x}) \text{d}y\text{d}\mathbf{ x}\\
& \triangleq \mathbb{E}\left[ \left(y- f^*(\mathbf{ x})\right)^2 \right].
-\end{align*}\] This can be decomposed into two parts, \[
+\end{align*}\] This can be decomposed into two parts, \[
\begin{align*}
\mathbb{E}\left[ \left(y- f(\mathbf{ x})\right)^2 \right] = & \text{bias}\left[f^*(\mathbf{ x})\right]^2 + \text{variance}\left[f^*(\mathbf{ x})\right] +\sigma^2,
\end{align*}
\] where the bias is given by \[
\text{bias}\left[f^*(\mathbf{ x})\right] =
\mathbb{E}\left[f^*(\mathbf{ x})\right] - f(\mathbf{ x})
-\] and it summarizes error that arises from the model’s inability to represent the underlying complexity of the data. For example, if we were to model the marathon pace of the winning runner from the Olympics by computing the average pace across time, then that model would exhibit bias error because the reality of Olympic marathon pace is it is changing (typically getting faster). The variance term is given by \[
+\] and it summarizes error that arises from the model’s inability to represent the underlying complexity of the data. For example, if we were to model the marathon pace of the winning runner from the Olympics by computing the average pace across time, then that model would exhibit bias error because the reality of Olympic marathon pace is it is changing (typically getting faster). The variance term is given by \[
\text{variance}\left[f^*(\mathbf{ x})\right] = \mathbb{E}\left[\left(f^*(\mathbf{ x}) - \mathbb{E}\left[f^*(\mathbf{ x})\right]\right)^2\right].
- \] The variance term is often described as arising from a model that is too complex, but we must be careful with this idea. Is the model really too complex relative to the real world that generates the data? The real world is a complex place, and it is rare that we are constructing mathematical models that are more complex than the world around us. Rather, the ‘too complex’ refers to ability to estimate the parameters of the model given the data we have. Slight variations in the training set cause changes in prediction. Models that exhibit high variance are sometimes said to ‘overfit’ the data whereas models that exhibit high bias are sometimes described as ‘underfitting’ the data. Helper function for sampling data from two different classes. Helper function for plotting the decision boundary of the SVM. Models that exhibit high variance are sometimes said to ‘overfit’ the data whereas models that exhibit high bias are sometimes described as ‘underfitting’ the data. Helper function for sampling data from two different classes. Helper function for plotting the decision boundary of the SVM. Figure: In each figure the simpler model is on the left, and the more complex model is on the right. Each fit is done to a different version of the data set. The simpler model is more consistent in its errors (bias error), whereas the more complex model is varying in its errors (variance error). Figure: Alex Ihler discusses polynomials and overfitting. We can easily develop a simple prediction function that reconstructs the training data exactly, you can just use a look up table. But how would the lookup table predict between the training data, where examples haven’t been seen before? The choice of the class of prediction functions is critical in ensuring that the model generalizes well. The generalization error is normally estimated by applying the objective function to a set of data that the model wasn’t trained on, the test data. To ensure good performance we normally want a model that gives us a low generalization error. If we weren’t sure of the right prediction function to use, then we could try 1,000 different prediction functions. Then we could use the one that gives us the lowest error on the test data. But you have to be careful. Selecting a model in this way is like a further stage of training where you are using the test data in the training.4 So when this is done, the data used for this is not known as test data, it is known as validation data. And the associated error is the validation error. Using the validation error for model selection is a standard machine learning technique, but it can be misleading about the final generalization error. Almost all machine learning practitioners know not to use the test data in your training procedure, but sometimes people forget that when validation data is used for model selection that validation error cannot be used as an unbiased estimate of the generalization performance. Figure: In each figure the simpler model is on the left, and the more complex model is on the right. Each fit is done to a different version of the data set. The simpler model is more consistent in its errors (bias error), whereas the more complex model is varying in its errors (variance error). Figure: Alex Ihler discusses polynomials and overfitting. We can easily develop a simple prediction function that reconstructs the training data exactly, you can just use a look up table. But how would the lookup table predict between the training data, where examples haven’t been seen before? The choice of the class of prediction functions is critical in ensuring that the model generalizes well. The generalization error is normally estimated by applying the objective function to a set of data that the model wasn’t trained on, the test data. To ensure good performance we normally want a model that gives us a low generalization error. If we weren’t sure of the right prediction function to use, then we could try 1,000 different prediction functions. Then we could use the one that gives us the lowest error on the test data. But you have to be careful. Selecting a model in this way is like a further stage of training where you are using the test data in the training.4 So when this is done, the data used for this is not known as test data, it is known as validation data. And the associated error is the validation error. Using the validation error for model selection is a standard machine learning technique, but it can be misleading about the final generalization error. Almost all machine learning practitioners know not to use the test data in your training procedure, but sometimes people forget that when validation data is used for model selection that validation error cannot be used as an unbiased estimate of the generalization performance. Five fold cross validation tests the ability of the model to interpolate. Figure: Bayesian fit with 26th degree polynomial and negative marginal log likelihood. For the polynomial fit, we will now look at hold out validation, where we are holding out some of the most recent points. This tests the abilit of our model to extrapolate. Figure: Bayesian fit with 29th degree polynomial and hold out validation scores. Five fold cross validation tests the ability of the model to interpolate. Figure: Bayesian fit with 29th degree polynomial and five fold cross validation scores. The logarithm of a number less than one is negative, for a number greater than one the logarithm is positive. So if odds are greater than evens (odds-on) the log-odds are positive, if the odds are less than evens (odds-against) the log-odds will be negative.↩︎ In classical statistics we often interpret these parameters, \(\beta\), whereas in machine learning we are normally more interested in the result of the prediction, and less in the prediction. Although this is changing with more need for accountability. In honour of this I normally use \(\boldsymbol{\beta}\) when I care about the value of these parameters, and \(\mathbf{ w}\) when I care more about the quality of the prediction.↩︎ Assuming we are ignoring parameters in the link function and the distribution function.↩︎ Using the test data in your training procedure is a major error in any machine learning procedure. It is extremely dangerous as it gives a misleading assessment of the model performance. The Baidu ImageNet scandal was an example of a team competing in the ImageNet challenge which did this. The team had announced via the publication pre-print server Arxiv that they had a world-leading performance on the ImageNet challenge. This was reported in the mainstream media. Two weeks later the challenge organizers revealed that the team had created multiple accounts for checking their test performance more times than was permitted by the challenge rules. This was then reported as “AI’s first doping scandal.” The team lead was fired by Baidu.↩︎ Five fold cross validation tests the ability of the model to interpolate. Figure: Bayesian fit with 26th degree polynomial and negative marginal log likelihood. For the polynomial fit, we will now look at hold out validation, where we are holding out some of the most recent points. This tests the abilit of our model to extrapolate. Figure: Bayesian fit with 29th degree polynomial and hold out validation scores. Five fold cross validation tests the ability of the model to interpolate. Figure: Bayesian fit with 29th degree polynomial and five fold cross validation scores. Supervised learning is when your data is provided with labels. Now we are going to turn to a different form of learning, commonly known as unsupervised learning. In unsupervised learning our data isn’t necessarily labelled in any form, but we want models that give us a better understanding of the data. We’ve actually seen an example of this already with , which we introduces in the context of objective functions. Now we will introduce a more probabilistic approach to such models, specifically we are interested in latent variable modelling. In unsupervised learning you have data, \(\mathbf{ x}\), but no labels \(y\). The aim in unsupervised learning is to extract structure from data. The type of structure you are interested in is dependent on the broader context of the task. In supervised learning that context is very much driven by the labels. Supervised learning algorithms try and focus on the aspects of the data which are relevant to predicting the labels. But in unsupervised learning there are no labels. Humans can easily sort a number of objects into objects that share similar characteristics. We easily categorize animals or vehicles. But if the data is very large this is too slow. Even for smaller data, it may be that it is presented in a form that is unintelligible for humans. We are good at dealing with high dimensional data when it’s presented in images, but if it’s presented as a series of numbers, we find it hard to interpret. In unsupervised learning we want the computer to do the sorting for us. For example, an e-commerce company might need an algorithm that can go through its entire list of products and automatically sort them into groups such that similar products are located together. Supervised learning is broadly divided into classification: i.e. wake word classification in the Amazon Echo, and regression, e.g. shelf life prediction for perishable goods. Similarly, unsupervised learning can be broadly split into methods that cluster the data (i.e. provide a discrete label) and methods that represent the data as a continuous value. Clustering is a common approach to data analysis, though we will not cover it in great depth in this course. The fundamental idea is to associate each data point \(\mathbf{ y}_{i, :}\) with one of \(k\) different discrete groups. This approach raises interesting questions - for instance, when clustering animals into groups, we might ask whether animal traits are truly discrete or continuous in nature. Similar questions arise when clustering political affiliations. Humans seem to have a natural affinity for discrete clustering approaches. This makes clustering particularly useful when collaborating with biologists, who often think in terms of discrete categories. However, we should be mindful that this preference for discrete categories may sometimes oversimplify continuous variations in data. There is a subtle but important distinction between clustering and vector quantisation. In true clustering, we typically expect to see reductions in data density between natural groups - essentially, gaps in the data that separate different clusters. This definition isn’t universally applied though, and vector quantization may partition data without requiring such density gaps. For our current discussion, we’ll treat them similarly, focusing on the common challenges they share: how to allocate points to groups and, more challengingly, how to determine the optimal number of groups. Clustering methods associate data points with different labels that are allocated by the computer rather than provided by human annotators. This process is quite intuitive for humans - we naturally cluster our observations of the real world. For example, we cluster animals into groups like birds, mammals, and insects. While these labels can be provided by humans, they were originally invented through a clustering process. With computational clustering, we want to recreate that process of label invention. When thinking about ideas, the Greek philosopher Plato considered the concept of Platonic ideals - the most quintessential version of a thing, like the most bird-like bird or chair-like chair. In clustering, we aim to define different categories by finding their Platonic ideals (cluster centers) and allocating each data point to its nearest center. This allows computers to form categorizations of data at scales too large for human processing. To implement clustering computationally, we need to mathematically represent both our objects and cluster centres as vectors (\(\mathbf{ x}_i\) and \(\boldsymbol{ \mu}_j\) respectively) and define a notion of either similarity or distance between them. The distance function \(d_{ij} = f(\mathbf{ x}_i, \boldsymbol{ \mu}_j)\) measures how far each object is from potential cluster centres. For example, we might cluster customers by representing them through their purchase history and measuring their distance to different customer archetypes. A commonly used distance metric is the squared distance: \(d_{ij} = (\mathbf{ x}_i - \boldsymbol{ \mu}_j)^2\). This metric appears frequently in machine learning - we saw it earlier measuring prediction errors in regression, and here it measures dissimilarity between data points and cluster centres. Once we have decided on the distance or similarity function, we can decide a number of cluster centres, \(K\). We find their location by allocating each center to a sub-set of the points and minimizing the sum of the squared errors, \[
+E(\mathbf{M}) = \sum_{i \in \mathbf{i}_j} (\mathbf{ x}_i - \boldsymbol{ \mu}_j)^2
+\] where the notation \(\mathbf{i}_j\) represents all the indices of each data point which has been allocated to the \(j\)th cluster represented by the center \(\boldsymbol{ \mu}_j\). One approach to minimizing this objective function is known as \(k\)-means clustering. It is simple and relatively quick to implement, but it is an initialization sensitive algorithm. Initialization is the process of choosing an initial set of parameters before optimization. For \(k\)-means clustering you need to choose an initial set of centres. In \(k\)-means clustering your final set of clusters is very sensitive to the initial choice of centres. For more technical details on \(k\)-means clustering you can watch a video of Alex Ihler introducing the algorithm here. The \(k\)-means algorithm provides a straightforward approach to clustering data. It requires two key elements: a set of \(k\) cluster centres and a way to assign each data point to a cluster. The algorithm follows a simple iterative process: This process is intuitive and relatively easy to implement, though it comes with certain limitations. The \(k\)-means algorithm works by minimizing an objective function that measures the sum of squared Euclidean distances between each point and its assigned cluster center. This objective function can be written mathematically as shown above, where \(\boldsymbol{ \mu}_{j, :}\) represents the mean of cluster \(j\). It’s important to understand that while this algorithm will always converge to a minimum, this minimum is not guaranteed to be either global or unique. The optimization problem is non-convex, meaning there can be multiple local minima. Different initializations of the cluster centres can lead to different final solutions, which is one of the key challenges in applying \(k\)-means clustering in practice. Figure: Clustering with the \(k\)-means clustering algorithm. Hierarchical clustering builds a tree structure by iteratively merging the closest clusters. Unlike \(k\)-means, we don’t need to specify the number of clusters in advance. Instead, we start with each point as its own cluster and merge the closest pairs until we have one cluster containing all points. The result is a dendrogram - a tree that shows the complete merge history and allows us to extract any number of clusters by cutting the tree at different heights. The choice of linkage criterion determines how we measure distance between clusters. Single linkage uses the minimum distance between any two points in different clusters, making it sensitive to outliers. Complete linkage uses the maximum distance, creating more compact clusters. Average linkage provides a balance, while Ward linkage minimizes the increase in within-cluster variance, often producing more balanced cluster sizes. Ward’s criterion minimises the increase in within-cluster sum of squares (\(E(\mathbf{M})\)) when merging two clusters. The selection criterion for merging is \[
+\Delta_{i,j} = \frac{n_i n_j}{n_i + n_j} \|\boldsymbol{ \mu}_i - \boldsymbol{ \mu}_j\|^2,
+\] where \(\boldsymbol{ \mu}_i\) and \(\boldsymbol{ \mu}_j\) are the centroids of clusters \(i\) and \(j\), and \(n_i, n_j\) are their sizes. This formula comes from greedy minimisation of the within cluster variance. The normalisation by \(n_i\) and \(n_j\) ensures that the distance between cluster centroids with their sizes - larger clusters are penalized more heavily for being far apart, encouraging the formation of compact, well-separated groups. Ward’s method chooses the merge that result in the smallest possible increase in total within-cluster variance. This means that at each step, we’re making the locally optimal choice that preserves the most information about our data structure. The method is particularly effective when the underlying clusters are roughly spherical and well-separated. It creates compact, convex clusters. The weighting by cluster size (\(\frac{n_i n_j}{n_i + n_j}\)) ensures that we don’t prematurely merge large clusters with small outliers, leading to more balanced and interpretable results. We can show that Ward’s method is optimal for spherical clusters. We can derive the relationship between cluster merging and within-cluster variance. The within-cluster sum of squares (\(E(\mathbf{M})\)) measures the total squared distance from each point to its cluster centroid, \[
+E(\mathbf{M}) = \sum_{i=1}^k \sum_{\mathbf{ x}\in C_i} \|\mathbf{ x}- \boldsymbol{ \mu}_i\|^2.
+\] This is the same objective function that \(k\)-means clustering minimises. When we merge two clusters, we want to minimise the increase in this total variance. Consider two clusters \(C_i\) and \(C_j\) with \(n_i\) and \(n_j\) points respectively, and centroids \(\boldsymbol{ \mu}_i\) and \(\boldsymbol{ \mu}_j\). When we merge them, the new centroid becomes \(\boldsymbol{ \mu}_{ij} = \frac{n_i \boldsymbol{ \mu}_i + n_j \boldsymbol{ \mu}_j}{n_i + n_j}\). The increase in \(E(\mathbf{M})\) is \(\Delta_{i,j} = E(\mathbf{M})_{\text{new}} - E(\mathbf{M})_{\text{original}}\). Let’s expand this step by step. For the new cluster, we have: Using the identity \(\|\mathbf{ x}- \boldsymbol{ \mu}_{ij}\|^2 = \|\mathbf{ x}- \boldsymbol{ \mu}_i\|^2 + \|\boldsymbol{ \mu}_i - \boldsymbol{ \mu}_{ij}\|^2 + 2(\mathbf{ x}- \boldsymbol{ \mu}_i)^T(\boldsymbol{ \mu}_i - \boldsymbol{ \mu}_{ij})\), we can expand the new \(E(\mathbf{M})\). The cross-term \(2(\mathbf{ x}- \boldsymbol{ \mu}_i)^T(\boldsymbol{ \mu}_i - \boldsymbol{ \mu}_{ij})\) sums to zero because \(\sum_{\mathbf{ x}\in C_i} (\mathbf{ x}- \boldsymbol{ \mu}_i) = 0\) by definition of centroid. We can manipulate to find that \[
+\Delta_{i,j} = n_i \|\boldsymbol{ \mu}_i - \boldsymbol{ \mu}_{ij}\|^2 + n_j \|\boldsymbol{ \mu}_j - \boldsymbol{ \mu}_{ij}\|^2$. Substituting $\boldsymbol{ \mu}_{ij} = \frac{n_i \boldsymbol{ \mu}_i + n_j \boldsymbol{ \mu}_j}{n_i + n_j}
+\] and simplifying, we get the Ward distance formula \[
+\Delta_{i,j} = \frac{n_i n_j}{n_i + n_j} \|\boldsymbol{ \mu}_i - \boldsymbol{ \mu}_j\|^2.
+\] For spherical clusters, the \(E(\mathbf{M})\) is minimised when points are as close as possible to their centroid. Ward’s method makes locally optimal choices by always choosing the merge that results in the smallest possible increase in total variance. However, this is greedy optimal, it makes the best choice at each step without considering the global consequences. The weighting factor we derived, \(\frac{n_i n_j}{n_i + n_j}\), ensures that merging two large clusters is penalised more heavily than merging small clusters, preventing the algorithm from prematurely combining large, well-separated groups. While Ward’s method is not guaranteed to find the globally optimal hierarchical clustering, it often produces good results for spherical cluster structures. The agglomerative hierarchical clustering algorithm follows a simple iterative process. We start with each data point as its own cluster, then repeatedly find the two closest clusters and merge them. After each merge, we update our distance matrix to reflect the new cluster structure. This process continues until all points belong to a single cluster, creating a complete merge history that we can visualize as a dendrogram. Figure: Hierarchical clustering of some artificial data. On the left we have an artificially generated data set containing three clusters. On the right we can see the dendogram formed by clustering using Ward’s criterion. Note that the hierarchical clustering here doesn’t always imply that the data was hierarchical in origin. It’s a visualisation of distances between points and clusters. The longer lenghts in the dendogram imply larger distances. Next We’ll demonstrate agglomerative clustering on the oil flow data set, which contains measurements from a multiphase flow facility. This data set is from a physics-based simulation of oil flow in a pipeline. The data was generated as part of a project to determine the fraction of oil, water and gas in North Sea oil pipes (Bishop and James, 1993). The data consists of 1000 12-dimensional observations of simulated oil flow in a pipeline. Each observation is labelled according to the multi-phase flow configuration (homogeneous, annular or laminar). The data is returned as a dictionary containing training and test inputs (‘X’, ‘Xtst’), training and test labels (‘Y’, ‘Ytst’), and the names of the features. Figure: Visualization of the first two dimensions of the oil flow data from Bishop and James (1993) As normal we include the citation information for the data. And extra information about the data is included, as standard, under the keys In this example, we’ll apply hierarchical clustering to the oil flow data set. The data contains measurements from different flow regimes in a multiphase flow facility. The dendrogram shows how measurements naturally cluster into different flow types. Ward’s linkage method is used as it tends to create compact, evenly-sized clusters. Figure: Hierarchical clustering applied to oil flow data. The dendrogram shows how different flow regimes are grouped based on their measurement similarities. The three main flow regimes (homogeneous, annular, and laminar) should form distinct clusters. A powerful application of hierarchical clustering is in constructing phylogenetic trees from genetic sequence data. By comparing DNA/RNA sequences across species, we can reconstruct their evolutionary relationships and estimate when species diverged from common ancestors.5 The resulting tree structure, called a phylogeny, maps out the evolutionary history and relationships between organisms. These phylogenetic methods go beyond simple linkage methods based on distance, they incorporate models of genetic mutation and molecular evolution. These models can estimate not just the structure of relationships, but also the timing of evolutionary divergence events based on mutation rates. This has important applications in tracking the origins and spread of rapidly evolving pathogens like Covid19, HIV and influenza viruses. Understanding viral phylogenies helps epidemiologists trace outbreak sources, track transmission patterns, and develop targeted containment strategies. An e-commerce company could apply hierarchical clustering to organize their product catalog into a taxonomy tree. Products would be grouped into increasingly specific categories - for example, Electronics might split into Phones, Computers, etc., with Phones further dividing into Smartphones, Feature Phones, and so on. This creates an intuitive hierarchical organization. However, many products naturally belong in multiple categories - for instance, running shoes could reasonably be classified as both sporting equipment and footwear. The strict tree structure of hierarchical clustering doesn’t allow for this kind of multiple categorization, which is a key limitation for product organization. Our psychological ability to form categories is far more sophisticated than hierarchical trees. Research in cognitive science has revealed that humans naturally form overlapping categories and learn abstract principles that guide classification. Josh Tenenbaum’s work (see e.g. Lake et al. (2018)) demonstrates how human concept learning combines multiple forms of inference through hierarchical Bayesian models that integrate similarity-based clustering with theory-based reasoning. In practice the simple methods we use for agglomerative clustering to merge clusters care often used for visualisation of the cluster structure even when we don’t expect a hieararchy to be present (like the oil flow data and the artificial data above. Dimensionality reduction methods compress the data by replacing the original data with a reduced number of continuous variables. One way of thinking of these methods is to imagine a marionette. Figure: Thinking of dimensionality reduction as a marionette. We observe the high dimensional pose of the puppet, \(\mathbf{ x}\), but the movement of the puppeteer’s hand, \(\mathbf{ z}\) remains hidden to us. Dimensionality reduction aims to recover those hidden movements which generated the observations. The position of each body part of a marionette could be thought of as our data, \(\mathbf{ x}_i\). So, each data point consists of the 3-D co-ordinates of all the different body parts of the marionette. Let’s say there are 13 different body parts (2 each of feet, knees, hips, hands, elbows, shoulders, one head). Each body part has an x, y, z position in Cartesian coordinates. So that’s 39 numbers associated with each observation. The movement of these 39 parts is determined by the puppeteer via strings. Let’s assume it’s a very simple puppet, with just one stick to control it. The puppeteer can move the stick up and down, left and right. And they can twist it. This gives three parameters in the puppeteers control. This implies that the 39 variables we see moving are controlled by only 3 variables. These 3 variables are often called the hidden or latent variables. Dimensionality reduction assumes something similar for real world data. It assumes that the data we observe is generated from some lower dimensional underlying process. It then seeks to recover the values associated with this low dimensional process. Dimensionality reduction techniques underpin a lot of psychological scoring tests such as IQ tests or personality tests. An IQ test can involve several hundred questions, potentially giving a rich, high dimensional, characterization of some aspects of your intelligence. It is then summarized by a single number. Similarly, the Myers-Briggs personality test involves answering questions about preferences which are reduced to a set of numbers reflecting personality. These tests are assuming that our intelligence is implicitly one-dimensional and that our personality is implicitly four dimensional. Other examples include political belief which is typically represented on a left to right scale. A one-dimensional distillation of an entire philosophy about how a country should be run. Our own leadership principles imply that our decisions have a fourteen-dimensional space underlying them. Each decision could be characterized by judging to what extent it embodies each of the principles. Political belief, personality, intelligence, leadership. None of these exist as a directly measurable quantity in the real world, rather they are inferred based on measurables. Dimensionality reduction is the process of allowing the computer to automatically find such underlying dimensions. This automatically allowing us to characterize each data point according to those explanatory variables. Each of these characteristics can be scored, and individuals can then be turned into vectors. This doesn’t only apply to individuals, in recent years work on language modeling has taken a similar approach to words. The word2vec algorithm performed a dimensionality reduction on words, now you can take any word and map it to a latent space where similar words exhibit similar characteristics. A ‘personality space’ for words. Principal component analysis (PCA) is arguably the queen of dimensionality reduction techniques. PCA was developed as an approach to dimensionality reduction in 1930s by Hotelling as a method for the social sciences. In Hotelling’s formulation of PCA it was assumed that any data point, \(\mathbf{x}\) could be represented as a weighted sum of the latent factors of interest, so that Hotelling described prediction functions (like in regression and classification above), only the regression is now multiple output. And instead of predicting a label, \(y_i\), we now try and force the regression to predict the observed feature vector, \(\mathbf{ y}_i\). So, for example, on an IQ test we would try and predict subject \(i\)’s answer to the \(j\)th question with the following function \[
+y_{ij} = f_j(z_i; \mathbf{ w}).
+\] Here \(z_i\) would be the IQ of subject \(i\) and \(f_j(\cdot)\) would be a function representing the relationship between the subject’s IQ and their score on the answer to question \(j\). This function is the same for all subjects, but the subject’s IQ is assumed to differ leading to different scores for each subject. Figure: Visualization of the first two principal components of an artificial data set. The data was generated by taking an image of a handwritten digit, 6, and rotating it 360 times, one degree each time. The first two principal components have been extracted in the diagram. The underlying circular shape is derived from the rotation of the data. Each image in the data set is projected on to the location its projected to in the latent space. In Hotelling’s formulation he assumed that the function was a linear function. This idea is taken from a wider field known as factor analysis, so Hotelling described the challenge as \[
+f_j(z_i; \mathbf{ w}) = w_j z_i
+\] so the answer to the \(j\)th question is predicted to be a scaling of the subject’s IQ. The scale factor is given by \(w_j\). If there are more latent dimensions then a matrix of parameters, \(\mathbf{W}\) is used, for example if there were two latent dimensions, we’d have \[
+f_j(\mathbf{z}_i; \mathbf{W}) = w_{1j} z_{1i} + w_{2j} z_{2i}
+\] where, if this were a personality test, then \(z_{1i}\) might represent the spectrum over a subject’s extrovert/introvert and \(z_{2i}\) might represent where the subject was on the rational/perceptual scale. The function would make a prediction about the subjects answer to a particular question on the test (e.g. preference for office job vs preference for outdoor job). In factor analysis the parameters \(\mathbf{W}\) are known as the factor loadings and in PCA they are known as the principal components. Fitting the model involves finding estimates for the loadings, \(\mathbf{W}\), and latent variables, \(\mathbf{Z}\). There are different approaches including least squares. The least squares approach is used, for example, in recommender systems. In recommender systems this method is called matrix factorization. The customer characteristics, \(\mathbf{ y}_i\) is the customer rating for each different product (or item) and the latent variables can be seen as a space of customer preferences. In the recommender system case, the loadings matrix also has an interpretation as product similarities.6 Recommender systems have a particular characteristic in that most of the entries of the vector \(\mathbf{ y}_i\) are missing most of the time. In PCA and factor analysis the unknown latent factors are dealt with through a probability distribution. They are each assumed to be drawn from a zero mean, unit variance normal distribution. This leaves the factor loadings to be estimated. For PCA the maximum likelihood solution for the factor loadings can be shown to be given by the eigenvalue decomposition of the data covariance matrix. This is algorithmically simple and convenient, although slow to compute for very large data sets with many features and many subjects. The eigenvalue problem can also be derived from many other starting points: e.g. the directions of maximum variance in the data or finding a latent space that best preserves inter-point distances between the data, or the optimal linear compression of the data given a linear reconstruction. These many and varied justifications for the eigenvalue decomposition may account for the popularity of PCA. Indeed, there is even an interpretation for Google’s original PageRank algorithm (which computed the smallest eigenvector of the internet’s linkage matrix) as seeking the dominant principal component of the web.7 Characterizing users according to past buying behavior and combining this with characteristics about products, is key to making good recommendations and returning useful search results. Further advances can be made if we understand the context of a particular session. For example, if a user is buying Christmas presents and searches for a dress, then it could be the case that the user is willing to spend a little more on the dress than in normal circumstances. Characterizing these effects requires more data and more complex algorithms. However, in domains such a search we are normally constrained by the speed with which we need to return results. Accounting for each of these factors while returning results with acceptable latency is a particular challenge. The final domain of learning we will review is known as reinforcement learning. The domain of reinforcement learning is one that many researchers seem to believe is offering a route to general intelligence. The idea of general intelligence is to develop algorithms that are adaptable to many different circumstances. Supervised learning algorithms are designed to resolve particular challenges. Data is annotated with those challenges in mind. Unsupervised attempts to build representations without any context. But normally the algorithm designer has an understanding of what the broader objective is and designs the algorithms accordingly (for example, characterizing users). In reinforcement learning some context is given, in the form of a reward, but the reward is normally delayed. There may have been many actions that affected the outcome, but which actions had a positive effect and which a negative effect? In reinforcement learning some context is given, in the form of a reward. But it is often delayed Credit allocation problem: many actions that affected the outcome, but which actions had a positive effect and which a negative effect? One issue for many companies is that the best way of testing the customer experience, A/B testing, prioritizes short term reward. The internet is currently being driven by short term rewards which make it distracting in the short term, but perhaps less useful in the long term. Click-bait is an example, but there are more subtle effects. The success of Facebook is driven by its ability to draw us in when likely we should be doing something else. This is driven by large scale A/B testing. One open question is how to drive non-visual interfaces through equivalents to A/B testing. Speech interfaces, such as those used in intelligent agents, are less amenable to A/B testing when determining the quality of the interface. Improving interaction with them is therefore less exact science than the visual interface. Data efficient reinforcement learning methods are likely to be key to improving these agent’s ability to interact with the user and understand intent. However, they are not yet mature enough to be deployed in this application. An area where reinforcement learning methods have been deployed with high profile success is game play. In game play the reward is delayed to the end of the game, and it comes in the form of victory or defeat. A significant advantage of game play as an application area is that, through simulation of the game, it is possible to generate as much data as is required to solve the problem. For this reason, many of the recent advances in reinforcement learning have occurred with methods that are not data efficient. The company DeepMind is set up around reinforcement learning as an approach to general intelligence. All their most well-known achievements are centered around artificial intelligence in game play. In reinforcement learning a decision made at any given time have a downstream effect on the result. Whether the effect if beneficial or not is unknown until a future moment. We can think of reinforcement learning as providing a label, but the label is associated with a series of data involving a number of decisions taken. Each decision was taken given the understanding of game play at any given moment. Understanding which of these decisions was important in victory or defeat is a hard problem. In machine learning the process of understanding which decisions were beneficial and which were detrimental is known as the credit allocation problem. You wish to reward decisions that led to success to encourage them, but punish decisions that lead to failure. Broadly speaking, DeepMind uses an approach to Machine Learning where there are two mathematical functions at work. One determines the action to be taken at any given moment, the other estimates the quality of the board position at any given time. These are respectively known as the policy network and the value network.8 DeepMind made use of convolutional neural networks for both these models. The ancient Chinese game of Go was considered a challenge for artificial intelligence for two reasons. Firstly, the game tree has a very high branching factor. The game tree is a discrete representation of the game. Every node in the game tree is associated with a board position. You can move through the game tree by making legal a move on the board to change the position. In Go, there are so many legal moves that the game tree increases exponentially. This challenge in Go was addressed by using stochastic game tree search. Rather than exploring the game tree exhaustively they explored it randomly. Secondly, evaluating the quality of any given board position was deemed to be very hard.9 The value function determines for each player whether they are winning or losing. Skilled Go players can assess a board position, but they do it by instinct, by intuition. Just as early AI researchers struggled to give rules for detecting cancer, it is challenging to give rules to assess a Go board. The machine learning approach that AlphaGo took is to train a value function network to make this assessment. The approach that DeepMind took to conquering Go is a model-free approach known as Q-learning.10 The model-free approach refers to the fact that they don’t directly include a model of how the world evolves in the reinforcement learning algorithm. They make extensive use of the game tree, but they don’t model how it evolves. They do model the expected reward of each position in the game tree (the value function) but that is not the same as modeling how the game will proceed. An alternative approach to reinforcement learning is to use a prediction function to suggest how the world will evolve in response to your actions. To predict how the game tree will evolve. You can then use this prediction to indirectly infer the expected reward associated with any action. This is known as model-based reinforcement learning. This model-based approach is also closer to a control system. A classical control system is one where you give the system a set point. For example, a thermostat in the house. You set the temperature and the boiler switches off when it reaches it. Optimal control is about getting the house to the right temperature as quickly as possible. Classical control is widely used in robotic control and flight control. One interesting crossover between classical control and machine learning arises because classical optimal control can be seen as a form of model-based reinforcement learning. One where the reward is recovered when the set point is reached. In control engineering the prediction function is known as the transfer function. The process of fitting the transfer function in control is known as system identification. There is some exciting work emerging at the interface between the areas of control and reinforcement learning. Results at this interface could be very important for improving the quality of robotic and drone control. As we implied above, reinforcement learning can also used to improve user experience. In that case the reward is gained when the user buys a product from us. This makes it closely allied to the area of optimization. Optimization of our user interfaces can be seen as a reinforcement learning task, but more commonly it is thought about separately in the domains of Bayesian optimization or bandit learning. We use optimization in machine learning to find the parameters of our models. We can do that because we have a mathematical representation of our objective function as a direct function of the parameters. Examples in this form of optimization include, what is the best user interface for presenting adverts? What is the best design for a front wing for an F1 racing car? Which product should I return top of the list in response to this user’s search? Bayesian optimization arises when we can’t directly relate the parameters in the system of interest to our objective through a mathematical function. For example, what is the mathematical function that relates a user’s experience to the probability that they will buy a product? One approach to these problems is to use machine learning methods to develop a surrogate model for the optimization task. The surrogate model is a prediction function that attempts to recreate the process we are finding hard to model. We try to simultaneously fit the surrogate model and optimize the process. Bayesian optimization methods use a surrogate model (normally a specific form of regression model). They use this to predict how the real system will perform. The surrogate model makes a prediction (with an estimate of the uncertainty) of what the response will be to any given input. Parameters to test are chosen by considering this prediction. Similar to reinforcement learning, this can be viewed as a model-based approach because the surrogate model can be seen as a model of the real world. In bandit methods strategies are determined without turning to a model to motivate them. They are model free methods. Because of their different philosophies, if a class of prediction functions is chosen, then a model-based approach might have better average case performance. At least in terms of data efficiency. A model free approach may well have better worst-case performance though, because it makes less assumptions about the nature of the data. To put it another way, making assumptions about the data is helpful if they are right: and if the model is sensible they’ll be right on average. However, it is unhelpful if the model is wrong. Indeed, it could be actively damaging. Since we can’t usually guarantee the model is absolutely right, the worst-case performance of a model-based approach would be poor. We have introduced a range of machine learning approaches by focusing on their use of mathematical functions to replace manually coded systems of rules. The important characteristic of machine learning is that the form of these functions, as dictated by their parameters, is determined by acquiring data from the real world. The methods we have introduced are roughly speaking introduced in order of difficulty of deployment. While supervised learning is more involved in terms of collection of data, it is the most straightforward method to deploy once that data is recovered. For this reason, a major focus with supervised learning should always be on maintaining data quality, increasing the efficiency and accountability11 of the data collection pipeline and the quality of features used. You can also check my blog post on Data Readiness Levels. and my blog post on The 3Ds of Machine Learning Systems Design.. In relation to what AI can and can’t do today Andrew Ng is quoted as saying: If a typical person can do a mental task with less than one second of thought, we can probably automate it using AI either now or in the near future.12 Andrew Ng I would broadly agree with this quote but only in the context of supervised learning. If a human expert takes around that amount of time, then it’s also likely we can acquire the data necessary to build a supervised learning algorithm that can emulate that human’s response. The picture with regard to unsupervised learning and reinforcement learning is more clouded. One observation is that for supervised learning we seem to be moving beyond the era where very deep machine learning expertise is required to deploy methods. A solid understanding of machine learning (say to Masters level) is certainly required, but the quality of the final result is likely more dependent on domain expertise and the quality of the data and the information processing pipeline. This seems part of a wider trend where some of the big successes in machine learning are moving rapidly from the domain of science to that of engineering.13 You can check my blog post on New Directions in Kernels and Gaussian Processes.. So if we can only emulate tasks that humans take around a second to do, how are we managing to deliver on self driving cars? The answer is that we are constructing engineered systems from sub-components, each of which is a machine learning subsystem. But they are tied together as a component based system in line with our traditional engineering approach. This has an advantage that each component in the system can be verified before its inclusion. This is important for debugging and safety. But in practice we can expect these systems to be very brittle. A human adapts the way in which they drive the car across their lifetime. A human can react to other road users. In extreme situations, such as a car jacking, a human can set to one side normal patterns of behavior, and purposely crash their car to draw attention to the situation. Supervised machine learning solutions are normally trained offline. They do not adapt when deployed because this makes them less verifiable. But this compounds the brittleness of our solutions. By deploying our solutions we actually change the environment in which they operate. Therefore, it’s important that they can be quickly updated to reflect changing circumstances. This updating happens offline. For a complex mechanical system, such as a delivery drone, extensive testing of the system may be required when any component is updated. It is therefore imperative that these data processing pipelines are well documented so that they can be redeployed on demand. In practice there can be challenges with the false dichotomy between reproducibility and performance. It is likely that most of our data scientists are caring less about their ability to redeploy their pipelines and only about their ability to produce an algorithm that achieves a particular performance. A key question is how reproducible is that process? There is a false dichotomy because ensuring reproducibility will typically improve performance as it will make it easier to run a rigorous set of explorative experiments. A worry is that, currently, we do not have a way to quantify the scale of this potential problem within companies. Common to all machine learning methods is the initial choice of useful classes of functions. The deep learning revolution is associated with a particular class of mathematical functions that is proving very successful in what were seen to be challenging domains: speech, vision, language. This has meant that significant advances in problems that have been seen as hard have occurred in artificial intelligence. For more information on these subjects and more you might want to check the following resources. In this notebook, we explore the question of health facility distribution in Nigeria, spatially, and in relation to population density. We explore and visualize the question “How does the number of health facilities per capita vary across Nigeria?” Rather than focussing purely on using tools like Machine learning can be summarized as \[
+-->
+ In this notebook, we explore the question of health facility distribution in Nigeria, spatially, and in relation to population density. We explore and visualize the question “How does the number of health facilities per capita vary across Nigeria?” Rather than focussing purely on using tools like Machine learning can be summarized as \[
\text{model} + \text{data} \xrightarrow{\text{compute}} \text{prediction}
-\] and many machine learning courses focus a lot on the model part. But to build a machine learning system in practice, a lot of work must be put into the data part. This notebook gives some pointers on that work and how to think about your machine learning systems design. In this notebook, we download 4 datasets: But joining these data sets together is just an example. As another example, you could think of SafeBoda, a ride-hailing app that’s available in Lagos and Kampala. As well as looking at the health examples, try to imagine how SafeBoda may have had to design their systems to be scalable and reliable for storing and sharing data. First, we’re going to download some particular python libraries for dealing with geospatial data. We’re dowloading This small package is a helper package for various notebook utilities used below. The software can be installed using from the command prompt where you can access your python installation. The code is also available on GitHub: https://github.com/lawrennd/notutils Once In Sheffield we created a suite of software tools for ‘Open Data Science.’ Open data science is an approach to sharing code, models and data that should make it easier for companies, health professionals and scientists to gain access to data science techniques. You can also check this blog post on Open Data Science. The software can be installed using from the command prompt where you can access your python installation. The code is also available on GitHub: https://github.com/lawrennd/ods Once The The software can be installed using from the command prompt where you can access your python installation. The code is also available on GitHub: https://github.com/lawrennd/mlai Once The main idea we will be working with in this practical is the ‘join.’ A join does exactly what it sounds like, it combines two database tables. You may have already started to look at data structures and learning about Pandas is great for the data scientist to analyze data because it makes many operations easier. But it is not so good for building the machine learning system. In a machine learning system, you may have to handle a lot of data. Even if you start with building a system where you only have a few customers, perhaps you build an online taxi system (like SafeBoda) for Kampala. Maybe you will have 50 customers. Then maybe your system can be handled with some python scripts and But what if you are successful? What if everyone in Kampala wants to use your system? There are 1.5 million people in Kampala and maybe 100,000 Boda Boda drivers.1 What if you are even more succesful? What if everyone in Lagos wants to use your system? There are around 20 million people in Lagos … and maybe as many Okada[^okada] drivers as people in Kampala! [^okada] In Lagos the Boda Boda is called an Okada. We want to build safe and reliable machine learning systems. Building them from To build a reliable system, we need to turn to databases. In this notebook we’ll be focusing on SQL databases and how you bring together different streams of data in a Machine Learning System. In a machine learning system, you will need to bring different data sets together. In database terminology this is known as a ‘join.’ You have two different data sets, and you want to join them together. Just like you can join two pieces of metal using a welder, or two pieces of wood with screws. But instead of using a welder or screws to join data, we join it using columns of the data. We can join data together using people’s names. One database may contain where people live, another database may contain where they go to school. If we join these two databases, we can have a database which shows where people live and where they got to school. In the notebook, we will join some data about where the health centers are in Nigeria with data about where there have been cases of Covid19. There are other challenges in the ML System Design that are not going to be covered here. They include how to update the databases and how to control access to the databases from different users (boda boda drivers, riders, administrators etc). As an example data set we will use Nigerian Millennium Development Goals Information System Health Facility (The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) and Columbia University, 2014). It can be found here https://energydata.info/dataset/nigeria-nmis-education-facility-data-2014. Taking from the information on the site, The Nigeria MDG (Millennium Development Goals) Information System – NMIS health facility data is collected by the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) in partner with the Sustainable Engineering Lab at Columbia University. A rigorous, geo-referenced baseline facility inventory across Nigeria is created spanning from 2009 to 2011 with an additional survey effort to increase coverage in 2014, to build Nigeria’s first nation-wide inventory of health facility. The database includes 34,139 health facilities info in Nigeria. The goal of this database is to make the data collected available to planners, government officials, and the public, to be used to make strategic decisions for planning relevant interventions. For data inquiry, please contact Ms. Funlola Osinupebi, Performance Monitoring & Communications, Advisory Power Team, Office of the Vice President at funlola.osinupebi@aptovp.org To learn more, please visit http://csd.columbia.edu/2014/03/10/the-nigeria-mdg-information-system-nmis-takes-open-data-further/ Suggested citation: Nigeria NMIS facility database (2014), the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) & Columbia University For ease of use we’ve packaged this data set in the Alternatively, you can access the data directly with the following commands. This small package is a helper package for various notebook utilities used below. The software can be installed using from the command prompt where you can access your python installation. The code is also available on GitHub: https://github.com/lawrennd/notutils Once In Sheffield we created a suite of software tools for ‘Open Data Science’. Open data science is an approach to sharing code, models and data that should make it easier for companies, health professionals and scientists to gain access to data science techniques. You can also check this blog post on Open Data Science. The software can be installed using from the command prompt where you can access your python installation. The code is also available on GitHub: https://github.com/lawrennd/ods Once The The software can be installed using from the command prompt where you can access your python installation. The code is also available on GitHub: https://github.com/lawrennd/mlai Once The main idea we will be working with in this practical is the ‘join’. A join does exactly what it sounds like, it combines two database tables. You may have already started to look at data structures and learning about Pandas is great for the data scientist to analyze data because it makes many operations easier. But it is not so good for building the machine learning system. In a machine learning system, you may have to handle a lot of data. Even if you start with building a system where you only have a few customers, perhaps you build an online taxi system (like SafeBoda) for Kampala. Maybe you will have 50 customers. Then maybe your system can be handled with some python scripts and But what if you are successful? What if everyone in Kampala wants to use your system? There are 1.5 million people in Kampala and maybe 100,000 Boda Boda drivers.1 What if you are even more succesful? What if everyone in Lagos wants to use your system? There are around 20 million people in Lagos … and maybe as many Okada[^okada] drivers as people in Kampala! [^okada] In Lagos the Boda Boda is called an Okada. We want to build safe and reliable machine learning systems. Building them from To build a reliable system, we need to turn to databases. In this notebook we’ll be focusing on SQL databases and how you bring together different streams of data in a Machine Learning System. In a machine learning system, you will need to bring different data sets together. In database terminology this is known as a ‘join’. You have two different data sets, and you want to join them together. Just like you can join two pieces of metal using a welder, or two pieces of wood with screws. But instead of using a welder or screws to join data, we join it using columns of the data. We can join data together using people’s names. One database may contain where people live, another database may contain where they go to school. If we join these two databases, we can have a database which shows where people live and where they got to school. In the notebook, we will join some data about where the health centers are in Nigeria with data about where there have been cases of Covid19. There are other challenges in the ML System Design that are not going to be covered here. They include how to update the databases and how to control access to the databases from different users (boda boda drivers, riders, administrators etc). As an example data set we will use Nigerian Millennium Development Goals Information System Health Facility (The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) and Columbia University, 2014). It can be found here https://energydata.info/dataset/nigeria-nmis-education-facility-data-2014. Taking from the information on the site, The Nigeria MDG (Millennium Development Goals) Information System – NMIS health facility data is collected by the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) in partner with the Sustainable Engineering Lab at Columbia University. A rigorous, geo-referenced baseline facility inventory across Nigeria is created spanning from 2009 to 2011 with an additional survey effort to increase coverage in 2014, to build Nigeria’s first nation-wide inventory of health facility. The database includes 34,139 health facilities info in Nigeria. The goal of this database is to make the data collected available to planners, government officials, and the public, to be used to make strategic decisions for planning relevant interventions. For data inquiry, please contact Ms. Funlola Osinupebi, Performance Monitoring & Communications, Advisory Power Team, Office of the Vice President at funlola.osinupebi@aptovp.org To learn more, please visit http://csd.columbia.edu/2014/03/10/the-nigeria-mdg-information-system-nmis-takes-open-data-further/ Suggested citation: Nigeria NMIS facility database (2014), the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) & Columbia University For ease of use we’ve packaged this data set in the Alternatively, you can access the data directly with the following commands. Once it is loaded in the data can be summarized using the We can also find out the dimensions of the dataset using the Dataframes have different functions that you can use to explore and understand your data. In python and the Jupyter notebook it is possible to see a list of all possible functions and attributes by typing the name of the object followed by For functions we can also see the documentation about the function by following the name with a question mark. This will open a box with documentation at the bottom which can be closed with the x button. Figure: Location of the over thirty-four thousand health facilities registered in the NMIS data across Nigeria. Each facility plotted according to its latitude and longitude. A very common operation is the need to map from locations in a country to the administrative regions. If we were building a ride sharing app, we might also want to map riders to locations in the city, so that we could know how many riders we had in different city areas. Administrative regions have various names like cities, counties, districts, or states. These conversions for the administrative regions are important for getting the right information to the right people. Of course, if we had a knowledgeable Nigerian, we could ask her about what the right location for each of these health facilities is, which state is it in? But given that we have the latitude and longitude, we should be able to find out automatically what the different states are. This is where “geo” data becomes important. We need to download a dataset that stores the location of the different states in Nigeria. These files are known as ‘outline’ files. Because they draw the different states of different countries in outline. There are special databases for storing this type of information, the database we are using is in the For ease of use we’ve packaged this data set in the Once it is loaded in the data can be summarized using the We can also find out the dimensions of the dataset using the Dataframes have different functions that you can use to explore and understand your data. In python and the Jupyter notebook it is possible to see a list of all possible functions and attributes by typing the name of the object followed by For functions we can also see the documentation about the function by following the name with a question mark. This will open a box with documentation at the bottom which can be closed with the x button. Figure: Location of the over thirty-four thousand health facilities registered in the NMIS data across Nigeria. Each facility plotted according to its latitude and longitude. A very common operation is the need to map from locations in a country to the administrative regions. If we were building a ride sharing app, we might also want to map riders to locations in the city, so that we could know how many riders we had in different city areas. Administrative regions have various names like cities, counties, districts, or states. These conversions for the administrative regions are important for getting the right information to the right people. Of course, if we had a knowledgeable Nigerian, we could ask her about what the right location for each of these health facilities is, which state is it in? But given that we have the latitude and longitude, we should be able to find out automatically what the different states are. This is where “geo” data becomes important. We need to download a dataset that stores the location of the different states in Nigeria. These files are known as ‘outline’ files. Because they draw the different states of different countries in outline. There are special databases for storing this type of information, the database we are using is in the For ease of use we’ve packaged this data set in the Alternatively you can access the data directly with the following commands. Alternatively you can access the data directly with the following commands. Figure: Border locations for the thirty-six different states of Nigeria. Now we have this data of the outlines of the different states in Nigeria. The next thing we need to know is how these health facilities map onto different states in Nigeria. Without “binning” facilities somehow, it’s difficult to effectively see how they are distributed across the country. We do this by finding a “geo” dataset that contains the spatial outlay of Nigerian states by latitude/longitude coordinates. The dataset we use is of the “gdb” (GeoDataBase) type and comes as a zip file. We don’t need to worry much about this datatype for this notebook, only noting that geopandas knows how to load in the dataset, and that it contains different “layers” for the same map. In this case, each layer is a different degree of granularity of the political boundaries, with layer 0 being the whole country, 1 is by state, or 2 is by local government. We’ll go with a state level view for simplicity, but as an excercise you can change it to layer 2 to view the distribution by local government. Once we have these The first database join we’re going to do is a special one, it’s a ‘spatial join.’ We’re going to join the locations of the hospitals with their states. This join is unusual because it requires some mathematics to get right. The outline files give us the borders of the different states in latitude and longitude, the health facilities have given locations in the country. A spatial join involves finding out which state each health facility belongs to. Fortunately, the mathematics you need is already programmed for you in GeoPandas. That means all we need to do is convert our First, we convert the hospital data to a Figure: Border locations for the thirty-six different states of Nigeria. Now we have this data of the outlines of the different states in Nigeria. The next thing we need to know is how these health facilities map onto different states in Nigeria. Without “binning” facilities somehow, it’s difficult to effectively see how they are distributed across the country. We do this by finding a “geo” dataset that contains the spatial outlay of Nigerian states by latitude/longitude coordinates. The dataset we use is of the “gdb” (GeoDataBase) type and comes as a zip file. We don’t need to worry much about this datatype for this notebook, only noting that geopandas knows how to load in the dataset, and that it contains different “layers” for the same map. In this case, each layer is a different degree of granularity of the political boundaries, with layer 0 being the whole country, 1 is by state, or 2 is by local government. We’ll go with a state level view for simplicity, but as an excercise you can change it to layer 2 to view the distribution by local government. Once we have these The first database join we’re going to do is a special one, it’s a ‘spatial join’. We’re going to join the locations of the hospitals with their states. This join is unusual because it requires some mathematics to get right. The outline files give us the borders of the different states in latitude and longitude, the health facilities have given locations in the country. A spatial join involves finding out which state each health facility belongs to. Fortunately, the mathematics you need is already programmed for you in GeoPandas. That means all we need to do is convert our First, we convert the hospital data to a There are some technial details here: the Now we have the data in the There are some technial details here: the Now we have the data in the Figure: The outline of the thirty-six different states of nigeria with the location sof the health centers plotted on the map. We’ve now plotted the different health center locations across the states. You can clearly see that each of the dots falls within a different state. For helping the visualization, we’ve made the dots somewhat transparent (we set the Of course, we can now see by eye, which of the states each of the health centers belongs to. But we want the computer to do our join for us. We have two GeoPandas data frames, We can see that this is the GeoDataFrame containing the information about the hospital. Now let’s have a look at the You can see that this data frame has a different set of columns. It has all the different administrative regions. But there is one column name that overlaps. We can find it by looking for the intersection between the two sets. Here we’ve converted the lists of columns into python ‘sets,’ and then looked for the intersection. The join will occur on the intersection between these columns. It will try and match the geometry of the hospitals (their location) to the geometry of the states (their outlines). This match is done in one line in GeoPandas. We’re having to use GeoPandas because this join is a special one based on geographical locations, if the join was on customer name or some other discrete variable, we could do the join in pandas or directly in SQL. The intersection of the two data frames indicates how the two data frames will be joined (if there’s no intersection, they can’t be joined). It’s like indicating the two holes that would need to be bolted together on two pieces of metal. If the holes don’t match, the join can’t be done. There has to be an intersection. But what will the result look like? Well, the join should be the ‘union’ of the two data frames. We can have a look at what the union should be by (again) converting the columns to sets. That gives a list of all the columns (notice that ‘geometry’ only appears once). Let’s check that’s what the join command did, by looking at the columns of our new data frame, Great! They are all there! We have completed our join. We had two separate data frames with information about states and information about hospitals. But by performing an ‘outer’ or a ‘left’ join, we now have a single data frame with all the information in the same place! Let’s have a look at the first frew entries in the new data frame. Our first join was a special one, because it involved spatial data. That meant using the special To do this, we use the command line utility that comes standard for SQLite database creation. SQLite is a simple database that’s useful for playing with database commands on your local machine. For a real system, you would need to set up a server to run the database. The server is a separate machine with the job of answering database queries. SQLite pretends to be a proper database but doesn’t require us to go to the extra work of setting up a server. Popular SQL server software includes A typical machine learning installation might have you running a database from a cloud service (such as AWS, Azure or Google Cloud Platform). That cloud service would host the database for you, and you would pay according to the number of queries made. Many start-up companies were formed on the back of a If you were designing your own ride hailing app, or any other major commercial software you would want to investigate whether you would need to set up a central SQL server in one of these frameworks. Today though, we’ll just stick to SQLite which gives you a sense of the database without the time and expense of setting it up on the cloud. As well as showing you the SQL commands (which is often what’s used in a production ML system) we’ll also give the equivalent The beautiful thing about SQLite is that it allows us to play with SQL without going to the work of setting up a proper SQL server. Creating a data base in SQLite is as simple as writing a new file. To create the database, we’ll first write our joined data to a CSV file, then we’ll use a little utility to convert our hospital database into a SQLite database. Rather than being installed on a separate server, SQLite simply stores the database locally in a file called In the database there can be several ‘tables.’ Each table can be thought of as like a separate dataframe. The table name we’ve just saved is ‘hospitals_zones_joined.’ Now that we have a SQL database, we can create a connection to it and query it using SQL commands. Let’s try to simply select the data we wrote to it, to make sure it’s the same. Start by making a connection to the database. This will often be done via remote connections, but for this example we’ll connect locally to the database using the filepath directly. To access a data base, the first thing that is made is a connection. Then SQL is used to extract the information required. A typical SQL command is We do this using an Typically, its good software engineering practice to ‘wrap’ the database command in some python code. This allows the commands to be maintained. You will also be asked to do this in your final assessment, including re-writing some of the code - pay attention to the slight syntax differences and multi-statement queries.Below we wrap the SQL command in python code. This SQL command selects the first We can pass the Now that we have a connection, we can write a command and pass it to the database. To access a data base, the first thing that is made is a connection. Then SQL is used to extract the information required. A typical SQL command is The python library, Let’s have a go at calling the command to extract the first three facilities from our health center database. Let’s try creating a function that does the same thing the pandas Figure: The outline of the thirty-six different states of nigeria with the location sof the health centers plotted on the map. We’ve now plotted the different health center locations across the states. You can clearly see that each of the dots falls within a different state. For helping the visualization, we’ve made the dots somewhat transparent (we set the Of course, we can now see by eye, which of the states each of the health centers belongs to. But we want the computer to do our join for us. We have two GeoPandas data frames, We can see that this is the GeoDataFrame containing the information about the hospital. Now let’s have a look at the You can see that this data frame has a different set of columns. It has all the different administrative regions. But there is one column name that overlaps. We can find it by looking for the intersection between the two sets. Here we’ve converted the lists of columns into python ‘sets’, and then looked for the intersection. The join will occur on the intersection between these columns. It will try and match the geometry of the hospitals (their location) to the geometry of the states (their outlines). This match is done in one line in GeoPandas. We’re having to use GeoPandas because this join is a special one based on geographical locations, if the join was on customer name or some other discrete variable, we could do the join in pandas or directly in SQL. The intersection of the two data frames indicates how the two data frames will be joined (if there’s no intersection, they can’t be joined). It’s like indicating the two holes that would need to be bolted together on two pieces of metal. If the holes don’t match, the join can’t be done. There has to be an intersection. But what will the result look like? Well, the join should be the ‘union’ of the two data frames. We can have a look at what the union should be by (again) converting the columns to sets. That gives a list of all the columns (notice that ‘geometry’ only appears once). Let’s check that’s what the join command did, by looking at the columns of our new data frame, Great! They are all there! We have completed our join. We had two separate data frames with information about states and information about hospitals. But by performing an ‘outer’ or a ‘left’ join, we now have a single data frame with all the information in the same place! Let’s have a look at the first frew entries in the new data frame. Our first join was a special one, because it involved spatial data. That meant using the special To do this, we use the command line utility that comes standard for SQLite database creation. SQLite is a simple database that’s useful for playing with database commands on your local machine. For a real system, you would need to set up a server to run the database. The server is a separate machine with the job of answering database queries. SQLite pretends to be a proper database but doesn’t require us to go to the extra work of setting up a server. Popular SQL server software includes A typical machine learning installation might have you running a database from a cloud service (such as AWS, Azure or Google Cloud Platform). That cloud service would host the database for you, and you would pay according to the number of queries made. Many start-up companies were formed on the back of a If you were designing your own ride hailing app, or any other major commercial software you would want to investigate whether you would need to set up a central SQL server in one of these frameworks. Today though, we’ll just stick to SQLite which gives you a sense of the database without the time and expense of setting it up on the cloud. As well as showing you the SQL commands (which is often what’s used in a production ML system) we’ll also give the equivalent The beautiful thing about SQLite is that it allows us to play with SQL without going to the work of setting up a proper SQL server. Creating a data base in SQLite is as simple as writing a new file. To create the database, we’ll first write our joined data to a CSV file, then we’ll use a little utility to convert our hospital database into a SQLite database. Rather than being installed on a separate server, SQLite simply stores the database locally in a file called In the database there can be several ‘tables’. Each table can be thought of as like a separate dataframe. The table name we’ve just saved is ‘hospitals_zones_joined’. Now that we have a SQL database, we can create a connection to it and query it using SQL commands. Let’s try to simply select the data we wrote to it, to make sure it’s the same. Start by making a connection to the database. This will often be done via remote connections, but for this example we’ll connect locally to the database using the filepath directly. To access a data base, the first thing that is made is a connection. Then SQL is used to extract the information required. A typical SQL command is We do this using an Typically, its good software engineering practice to ‘wrap’ the database command in some python code. This allows the commands to be maintained. You will also be asked to do this in your final assessment, including re-writing some of the code - pay attention to the slight syntax differences and multi-statement queries.Below we wrap the SQL command in python code. This SQL command selects the first We can pass the Now that we have a connection, we can write a command and pass it to the database. To access a data base, the first thing that is made is a connection. Then SQL is used to extract the information required. A typical SQL command is The python library, Let’s have a go at calling the command to extract the first three facilities from our health center database. Let’s try creating a function that does the same thing the pandas Great! We now have the database in and some python functions that operate on the data base by wrapping SQL commands. We will return to the SQL command style after download and add the other datasets to the database using a combination of Our next task will be to introduce data on COVID19 so that we can join that to our other data sets. Now we have the health data, we’re going to combine it with data about COVID-19 cases in Nigeria over time. This data is kindly provided by Africa open COVID-19 data working group, which Elaine Nsoesie has been working with. The data is taken from Twitter, and only goes up until May 2020. They provide their data in GitHub. We can access the cases we’re interested in from the following URL. https://raw.githubusercontent.com/dsfsi/covid19africa/master/data/line_lists/line-list-nigeria.csv For convenience, we’ll load the data into pandas first, but our next step will be to create a new SQLite table containing the data. Then we’ll join that table to our existing tables. At the beginning of the COVID-19 outbreak, the Consortium for African COVID-19 Data formed to bring together data from across the African continent on COVID-19 cases (Marivate et al., 2020). These cases are recorded in the following GitHub repository: https://github.com/dsfsi/covid19africa. For ease of use we’ve packaged this data set in the Alternatively, you can access the data directly with the following commands. Great! We now have the database in and some python functions that operate on the data base by wrapping SQL commands. We will return to the SQL command style after download and add the other datasets to the database using a combination of Our next task will be to introduce data on COVID19 so that we can join that to our other data sets. Now we have the health data, we’re going to combine it with data about COVID-19 cases in Nigeria over time. This data is kindly provided by Africa open COVID-19 data working group, which Elaine Nsoesie has been working with. The data is taken from Twitter, and only goes up until May 2020. They provide their data in GitHub. We can access the cases we’re interested in from the following URL. https://raw.githubusercontent.com/dsfsi/covid19africa/master/data/line_lists/line-list-nigeria.csv For convenience, we’ll load the data into pandas first, but our next step will be to create a new SQLite table containing the data. Then we’ll join that table to our existing tables. At the beginning of the COVID-19 outbreak, the Consortium for African COVID-19 Data formed to bring together data from across the African continent on COVID-19 cases (Marivate et al., 2020). These cases are recorded in the following GitHub repository: https://github.com/dsfsi/covid19africa. For ease of use we’ve packaged this data set in the Alternatively, you can access the data directly with the following commands. Once it is loaded in the data can be summarized using the Figure: Evolution of COVID-19 cases in Nigeria. Now we convert this CSV file we’ve downloaded into a new table in the database file. We can do this, again, with the csv-to-sqlite script. Now we have information about COVID cases, and we have information about how many health centers and how many doctors and nurses there are in each health center. But unless we understand how many people there are in each state, then we cannot make decisions about where they may be problems with the disease. If we were running our ride hailing service, we would also need information about how many people there were in different areas, so we could understand what the demand for the boda boda rides might be. To access the number of people we can get population statistics from the Humanitarian Data Exchange. We also want to have population data for each state in Nigeria, so that we can see attributes like whether there are zones of high health facility density but low population density. Once it is loaded in the data can be summarized using the Figure: Evolution of COVID-19 cases in Nigeria. Now we convert this CSV file we’ve downloaded into a new table in the database file. We can do this, again, with the csv-to-sqlite script. Now we have information about COVID cases, and we have information about how many health centers and how many doctors and nurses there are in each health center. But unless we understand how many people there are in each state, then we cannot make decisions about where they may be problems with the disease. If we were running our ride hailing service, we would also need information about how many people there were in different areas, so we could understand what the demand for the boda boda rides might be. To access the number of people we can get population statistics from the Humanitarian Data Exchange. We also want to have population data for each state in Nigeria, so that we can see attributes like whether there are zones of high health facility density but low population density. To do joins with this data, we must first make sure that the columns have the right names. The name should match the same name of the column in our existing data. So we reset the column names, and the name of the index, as follows. To do joins with this data, we must first make sure that the columns have the right names. The name should match the same name of the column in our existing data. So we reset the column names, and the name of the index, as follows. When doing this for real world data, you should also make sure that the names used in the rows are the same across the different data bases. For example, has someone decided to use an abbreviation for ‘Federal Capital Territory’ and set it as ‘FCT.’ The computer won’t understand these are the same states, and if you do a join with such data, you can get duplicate entries or missing entries. This sort of thing happens a lot in real world data and takes a lot of time to sort out. Fortunately, in this case, the data is well curated, and we don’t have these problems. The next step is to add this new CSV file as an additional table in our database. We can load the data into the SQLite database using the script as before. For more information on these subjects and more you might want to check the following resources. Boda Boda is the name for the motorbike taxis found commonly in Kampala.↩︎ When doing this for real world data, you should also make sure that the names used in the rows are the same across the different data bases. For example, has someone decided to use an abbreviation for ‘Federal Capital Territory’ and set it as ‘FCT’. The computer won’t understand these are the same states, and if you do a join with such data, you can get duplicate entries or missing entries. This sort of thing happens a lot in real world data and takes a lot of time to sort out. Fortunately, in this case, the data is well curated, and we don’t have these problems. The next step is to add this new CSV file as an additional table in our database. We can load the data into the SQLite database using the script as before. For more information on these subjects and more you might want to check the following resources. What is machine learning? At its most basic level machine learning is a combination of \[\text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}\] where data is our observations. They can be actively or passively acquired (meta-data). The model contains our assumptions, based on previous experience. That experience can be other data, it can come from transfer learning, or it can merely be our beliefs about the regularities of the universe. In humans our models include our inductive biases. The prediction is an action to be taken or a categorization or a quality score. The reason that machine learning has become a mainstay of artificial intelligence is the importance of predictions in artificial intelligence. The data and the model are combined through computation. In practice we normally perform machine learning using two functions. To combine data with a model we typically make use of: a prediction function it is used to make the predictions. It includes our beliefs about the regularities of the universe, our assumptions about how the world works, e.g., smoothness, spatial similarities, temporal similarities. an objective function it defines the ‘cost’ of misprediction. Typically, it includes knowledge about the world’s generating processes (probabilistic objectives) or the costs we pay for mispredictions (empirical risk minimization). The combination of data and model through the prediction function and the objective function leads to a learning algorithm. The class of prediction functions and objective functions we can make use of is restricted by the algorithms they lead to. If the prediction function or the objective function are too complex, then it can be difficult to find an appropriate learning algorithm. Much of the academic field of machine learning is the quest for new learning algorithms that allow us to bring different types of models and data together. A useful reference for state of the art in machine learning is the UK Royal Society Report, Machine Learning: Power and Promise of Computers that Learn by Example. You can also check my post blog post on What is Machine Learning?. As an example data set we will use Nigerian Millennium Development Goals Information System Health Facility (The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) and Columbia University, 2014). It can be found here https://energydata.info/dataset/nigeria-nmis-education-facility-data-2014. Taking from the information on the site, The Nigeria MDG (Millennium Development Goals) Information System – NMIS health facility data is collected by the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) in partner with the Sustainable Engineering Lab at Columbia University. A rigorous, geo-referenced baseline facility inventory across Nigeria is created spanning from 2009 to 2011 with an additional survey effort to increase coverage in 2014, to build Nigeria’s first nation-wide inventory of health facility. The database includes 34,139 health facilities info in Nigeria. The goal of this database is to make the data collected available to planners, government officials, and the public, to be used to make strategic decisions for planning relevant interventions. For data inquiry, please contact Ms. Funlola Osinupebi, Performance Monitoring & Communications, Advisory Power Team, Office of the Vice President at funlola.osinupebi@aptovp.org To learn more, please visit http://csd.columbia.edu/2014/03/10/the-nigeria-mdg-information-system-nmis-takes-open-data-further/ Suggested citation: Nigeria NMIS facility database (2014), the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) & Columbia University For ease of use we’ve packaged this data set in the In Sheffield we created a suite of software tools for ‘Open Data Science.’ Open data science is an approach to sharing code, models and data that should make it easier for companies, health professionals and scientists to gain access to data science techniques. You can also check this blog post on Open Data Science. The software can be installed using from the command prompt where you can access your python installation. The code is also available on GitHub: https://github.com/lawrennd/ods Once Alternatively, you can access the data directly with the following commands. What is machine learning? At its most basic level machine learning is a combination of \[\text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}\] where data is our observations. They can be actively or passively acquired (meta-data). The model contains our assumptions, based on previous experience. That experience can be other data, it can come from transfer learning, or it can merely be our beliefs about the regularities of the universe. In humans our models include our inductive biases. The prediction is an action to be taken or a categorization or a quality score. The reason that machine learning has become a mainstay of artificial intelligence is the importance of predictions in artificial intelligence. The data and the model are combined through computation. In practice we normally perform machine learning using two functions. To combine data with a model we typically make use of: a prediction function it is used to make the predictions. It includes our beliefs about the regularities of the universe, our assumptions about how the world works, e.g., smoothness, spatial similarities, temporal similarities. an objective function it defines the ‘cost’ of misprediction. Typically, it includes knowledge about the world’s generating processes (probabilistic objectives) or the costs we pay for mispredictions (empirical risk minimization). The combination of data and model through the prediction function and the objective function leads to a learning algorithm. The class of prediction functions and objective functions we can make use of is restricted by the algorithms they lead to. If the prediction function or the objective function are too complex, then it can be difficult to find an appropriate learning algorithm. Much of the academic field of machine learning is the quest for new learning algorithms that allow us to bring different types of models and data together. A useful reference for state of the art in machine learning is the UK Royal Society Report, Machine Learning: Power and Promise of Computers that Learn by Example. You can also check my post blog post on What is Machine Learning?. As an example data set we will use Nigerian Millennium Development Goals Information System Health Facility (The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) and Columbia University, 2014). It can be found here https://energydata.info/dataset/nigeria-nmis-education-facility-data-2014. Taking from the information on the site, The Nigeria MDG (Millennium Development Goals) Information System – NMIS health facility data is collected by the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) in partner with the Sustainable Engineering Lab at Columbia University. A rigorous, geo-referenced baseline facility inventory across Nigeria is created spanning from 2009 to 2011 with an additional survey effort to increase coverage in 2014, to build Nigeria’s first nation-wide inventory of health facility. The database includes 34,139 health facilities info in Nigeria. The goal of this database is to make the data collected available to planners, government officials, and the public, to be used to make strategic decisions for planning relevant interventions. For data inquiry, please contact Ms. Funlola Osinupebi, Performance Monitoring & Communications, Advisory Power Team, Office of the Vice President at funlola.osinupebi@aptovp.org To learn more, please visit http://csd.columbia.edu/2014/03/10/the-nigeria-mdg-information-system-nmis-takes-open-data-further/ Suggested citation: Nigeria NMIS facility database (2014), the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) & Columbia University For ease of use we’ve packaged this data set in the In Sheffield we created a suite of software tools for ‘Open Data Science’. Open data science is an approach to sharing code, models and data that should make it easier for companies, health professionals and scientists to gain access to data science techniques. You can also check this blog post on Open Data Science. The software can be installed using from the command prompt where you can access your python installation. The code is also available on GitHub: https://github.com/lawrennd/ods Once Alternatively, you can access the data directly with the following commands. Once it is loaded in the data can be summarized using the We can also find out the dimensions of the dataset using the Dataframes have different functions that you can use to explore and understand your data. In python and the Jupyter notebook it is possible to see a list of all possible functions and attributes by typing the name of the object followed by For functions we can also see the documentation about the function by following the name with a question mark. This will open a box with documentation at the bottom which can be closed with the x button. Figure: Location of the over thirty-four thousand health facilities registered in the NMIS data across Nigeria. Each facility plotted according to its latitude and longitude. We are now going to do some simple review of probabilities and use this review to explore some aspects of our data. A probability distribution expresses uncertainty about the outcome of an event. We often encode this uncertainty in a variable. So if we are considering the outcome of an event, \(Y\), to be a coin toss, then we might consider \(Y=1\) to be heads and \(Y=0\) to be tails. We represent the probability of a given outcome with the notation: \[
+data = pd.read_csv('healthmopupandbaselinenmisfacility.csv') Once it is loaded in the data can be summarized using the We can also find out the dimensions of the dataset using the Dataframes have different functions that you can use to explore and understand your data. In python and the Jupyter notebook it is possible to see a list of all possible functions and attributes by typing the name of the object followed by For functions we can also see the documentation about the function by following the name with a question mark. This will open a box with documentation at the bottom which can be closed with the x button. Figure: Location of the over thirty-four thousand health facilities registered in the NMIS data across Nigeria. Each facility plotted according to its latitude and longitude. We are now going to do some simple review of probabilities and use this review to explore some aspects of our data. A probability distribution expresses uncertainty about the outcome of an event. We often encode this uncertainty in a variable. So if we are considering the outcome of an event, \(Y\), to be a coin toss, then we might consider \(Y=1\) to be heads and \(Y=0\) to be tails. We represent the probability of a given outcome with the notation: \[
P(Y=1) = 0.5
\] The first rule of probability is that the probability must normalize. The sum of the probability of all events must equal 1. So if the probability of heads (\(Y=1\)) is 0.5, then the probability of tails (the only other possible outcome) is given by \[
P(Y=0) = 1-P(Y=1) = 0.5
-\] Probabilities are often defined as the limit of the ratio between the number of positive outcomes (e.g. heads) given the number of trials. If the number of positive outcomes for event \(y\) is denoted by \(n\) and the number of trials is denoted by \(N\) then this gives the ratio \[
+\] Probabilities are often defined as the limit of the ratio between the number of positive outcomes (e.g. heads) given the number of trials. If the number of positive outcomes for event \(y\) is denoted by \(n\) and the number of trials is denoted by \(N\) then this gives the ratio \[
P(Y=y) = \lim_{N\rightarrow
\infty}\frac{n_y}{N}.
\] In practice we never get to observe an event infinite times, so rather than considering this we often use the following estimate \[
P(Y=y) \approx \frac{n_y}{N}.
-\] The NMIS facility data is stored in an object known as a ‘data frame.’ Data frames come from the statistical family of programming languages based on This shows the number of doctors per facility, number of nurses and number of community health workers (CHEWS). We can plot the number of doctors against the number of nurses as follows. You may be curious what the arguments we give to We immediately note that some facilities have a lot of nurses, which prevent’s us seeing the detail of the main number of facilities. First lets identify the facilities with the most nurses. Here we are using the command We now see that the ‘University of Calabar Teaching Hospital’ is a large outlier with 513 nurses. We can try and determine how much of an outlier by histograming the data. We can’t see very much here. Two things are happening. There are so many facilities with zero or one nurse that we don’t see the histogram for hospitals with many nurses. We can try more bins and using a log scale on the \(y\)-axis. The NMIS facility data is stored in an object known as a ‘data frame’. Data frames come from the statistical family of programming languages based on This shows the number of doctors per facility, number of nurses and number of community health workers (CHEWS). We can plot the number of doctors against the number of nurses as follows. You may be curious what the arguments we give to We immediately note that some facilities have a lot of nurses, which prevent’s us seeing the detail of the main number of facilities. First lets identify the facilities with the most nurses. Here we are using the command We now see that the ‘University of Calabar Teaching Hospital’ is a large outlier with 513 nurses. We can try and determine how much of an outlier by histograming the data. We can’t see very much here. Two things are happening. There are so many facilities with zero or one nurse that we don’t see the histogram for hospitals with many nurses. We can try more bins and using a log scale on the \(y\)-axis. Let’s try and see how the number of nurses relates to the number of doctors. Let’s try and see how the number of nurses relates to the number of doctors. Note a few things. We are interacting with our data. In particular, we are replotting the data according to what we have learned so far. We are using the progamming language as a scripting language to give the computer one command or another, and then the next command we enter is dependent on the result of the previous. This is a very different paradigm to classical software engineering. In classical software engineering we normally write many lines of code (entire object classes or functions) before compiling the code and running it. Our approach is more similar to the approach we take whilst debugging. Historically, researchers interacted with data using a console. A command line window which allowed command entry. The notebook format we are using is slightly different. Each of the code entry boxes acts like a separate console window. We can move up and down the notebook and run each part in a different order. The state of the program is always as we left it after running the previous part. Let’s use the sum rule to compute the estimate the probability that a facility has more than two nurses. Note a few things. We are interacting with our data. In particular, we are replotting the data according to what we have learned so far. We are using the progamming language as a scripting language to give the computer one command or another, and then the next command we enter is dependent on the result of the previous. This is a very different paradigm to classical software engineering. In classical software engineering we normally write many lines of code (entire object classes or functions) before compiling the code and running it. Our approach is more similar to the approach we take whilst debugging. Historically, researchers interacted with data using a console. A command line window which allowed command entry. The notebook format we are using is slightly different. Each of the code entry boxes acts like a separate console window. We can move up and down the notebook and run each part in a different order. The state of the program is always as we left it after running the previous part. Let’s use the sum rule to compute the estimate the probability that a facility has more than two nurses. When predicting whether a coin turns up head or tails, we might think that this event is independent of the year or time of day. If we include an observation such as time, then in a probability this is known as condtioning. We use this notation, \(P(Y=y|X=x)\), to condition the outcome on a second variable (in this case the number of doctors). Or, often, for a shorthand we use \(P(y|x)\) to represent this distribution (the \(Y=\) and \(X=\) being implicit). If two variables are independent then we find that \[
+print("Probability of number of nurses being greather than 2 is:", prob_large) When predicting whether a coin turns up head or tails, we might think that this event is independent of the year or time of day. If we include an observation such as time, then in a probability this is known as condtioning. We use this notation, \(P(Y=y|X=x)\), to condition the outcome on a second variable (in this case the number of doctors). Or, often, for a shorthand we use \(P(y|x)\) to represent this distribution (the \(Y=\) and \(X=\) being implicit). If two variables are independent then we find that \[
P(y|x) = p(y).
-\] However, we might believe that the number of nurses is dependent on the number of doctors. For this we can try estimating \(P(Y>2 | X>1)\) and compare the result, for example to \(P(Y>2|X\leq 1)\) using our empirical estimate of the probability. Write code that prints out the probability of nurses being greater than 2 for different numbers of doctors. Make sure the plot is included in this notebook file (the Jupyter magic command Figure: Diagram representing the different probabilities, joint, marginal and conditional. This diagram was inspired by lectures given by Christopher Bishop. Typically we should write out \(P\left(X=x,Y=y\right)\), but in practice we often shorten this to \(P\left(x,y\right)\). This looks very much like we might write a multivariate function, e.g. \[
+print("Probability of number of nurses being greater than 2 given number of doctors is greater than 1 is:", prob_both_large) Write code that prints out the probability of nurses being greater than 2 for different numbers of doctors. Make sure the plot is included in this notebook file (the Jupyter magic command Figure: Diagram representing the different probabilities, joint, marginal and conditional. This diagram was inspired by lectures given by Christopher Bishop. Typically we should write out \(P\left(X=x,Y=y\right)\), but in practice we often shorten this to \(P\left(x,y\right)\). This looks very much like we might write a multivariate function, e.g. \[
f\left(x,y\right)=\frac{x}{y},
\] but for a multivariate function \[
f\left(x,y\right)\neq f\left(y,x\right).
@@ -78,15 +280,22 @@
P\left(x,y\right)=P\left(y,x\right)
\] because \[
P\left(X=x,Y=y\right)=P\left(Y=y,X=x\right).
-\] Sometimes I think of this as akin to the way in Python we can write ‘keyword arguments’ in functions. If we use keyword arguments, the ordering of arguments doesn’t matter. We’ve now introduced conditioning and independence to the notion of probability and computed some conditional probabilities on a practical example The scatter plot of deaths vs year that we created above can be seen as a joint probability distribution. We represent a joint probability using the notation \(P(Y=y, X=x)\) or \(P(y, x)\) for short. Computing a joint probability is equivalent to answering the simultaneous questions, what’s the probability that the number of nurses was over 2 and the number of doctors was 1? Or any other question that may occur to us. Again we can easily use pandas to ask such questions. We’ve now introduced conditioning and independence to the notion of probability and computed some conditional probabilities on a practical example The scatter plot of deaths vs year that we created above can be seen as a joint probability distribution. We represent a joint probability using the notation \(P(Y=y, X=x)\) or \(P(y, x)\) for short. Computing a joint probability is equivalent to answering the simultaneous questions, what’s the probability that the number of nurses was over 2 and the number of doctors was 1? Or any other question that may occur to us. Again we can easily use pandas to ask such questions. This number is the joint probability, \(P(Y, X)\) which is much smaller than the conditional probability. The number can never be bigger than the conditional probabililty because it is computed using the product rule. \[
+print("Probability of nurses being greater than 2 and number of doctors being", num_doctors, "is:", prob_large) This number is the joint probability, \(P(Y, X)\) which is much smaller than the conditional probability. The number can never be bigger than the conditional probabililty because it is computed using the product rule. \[
p(Y=y, X=x) = p(Y=y|X=x)p(X=x)
-\] and \[p(X=x)\] is a probability distribution, which is equal or less than 1, ensuring the joint distribution is typically smaller than the conditional distribution. The product rule is a fundamental rule of probability, and you must remember it! It gives the relationship between the two questions: 1) What’s the probability that a facility has over two nurses and one doctor? and 2) What’s the probability that a facility has over two nurses given that it has one doctor? In our shorter notation we can write the product rule as \[
+\] and \[p(X=x)\] is a probability distribution, which is equal or less than 1, ensuring the joint distribution is typically smaller than the conditional distribution. The product rule is a fundamental rule of probability, and you must remember it! It gives the relationship between the two questions: 1) What’s the probability that a facility has over two nurses and one doctor? and 2) What’s the probability that a facility has over two nurses given that it has one doctor? In our shorter notation we can write the product rule as \[
p(y, x) = p(y|x)p(x)
-\] We can see the relation working in practice for our data above by computing the different values for \(x=1\). The other fundamental rule of probability is the sum rule this tells us how to get a marginal distribution from the joint distribution. Simply put it says that we need to sum across the value we’d like to remove. \[
+print("P(y,x) is", p_y_and_x) The other fundamental rule of probability is the sum rule this tells us how to get a marginal distribution from the joint distribution. Simply put it says that we need to sum across the value we’d like to remove. \[
P(Y=y) = \sum_{x} P(Y=y, X=x)
\] Or in our shortened notation \[
P(y) = \sum_{x} P(y, x)
-\] Write code that computes \(P(y)\) by adding \(P(y, x)\) for all values of \(x\). Bayes’ rule is a very simple rule, it’s hardly worth the name of a rule at all. It follows directly from the product rule of probability. Because \(P(y, x) = P(y|x)P(x)\) and by symmetry \(P(y,x)=P(x,y)=P(x|y)P(y)\) then by equating these two equations and dividing through by \(P(y)\) we have \[
+\] Write code that computes \(P(y)\) by adding \(P(y, x)\) for all values of \(x\). Bayes’ rule is a very simple rule, it’s hardly worth the name of a rule at all. It follows directly from the product rule of probability. Because \(P(y, x) = P(y|x)P(x)\) and by symmetry \(P(y,x)=P(x,y)=P(x|y)P(y)\) then by equating these two equations and dividing through by \(P(y)\) we have \[
P(x|y) =
\frac{P(y|x)P(x)}{P(y)}
-\] which is known as Bayes’ rule (or Bayes’s rule, it depends how you choose to pronounce it). It’s not difficult to derive, and its importance is more to do with the semantic operation that it enables. Each of these probability distributions represents the answer to a question we have about the world. Bayes rule (via the product rule) tells us how to invert the probability. Figure: Two barrels: Barrel One holds 20 apples and 4 oranges; Barrel Two holds 4 apples and 8 oranges. A barrel is chosen uniformly at random and a single fruit is drawn. Work the numbers on the board if time allows. The same pattern applies to coins, medical tests, or any two-hypothesis discrete update. That last number is Shannon entropy in nats: \(H(p)=\mathbb{E}_{p}[-\log p(y)]=-\sum_y p(y)\log p(y)\). Same arithmetic under another name. What use is all this probability in data science? Let’s think about how we might use the probabilities to do some decision making. Let’s look at the information data. Now we see we have several additional features. Let’s assume we want to predict Using what you’ve learnt about joint, conditional and marginal probabilities, as well as the sum and product rule, how would you formulate the question you want to answer in terms of probabilities? Should you be using a joint or a conditional distribution? If it’s conditional, what should the distribution be over, and what should it be conditioned on? This Bayesian approach is designed to deal with uncertainty arising from fitting our prediction function to the data we have, a reduced data set. The Bayesian approach can be derived from a broader understanding of what our objective is. If we accept that we can jointly represent all things that happen in the world with a probability distribution, then we can interogate that probability to make predictions. So, if we are interested in predictions, \(y_*\) at future points input locations of interest, \(\mathbf{ x}_*\) given previously training data, \(\mathbf{ y}\) and corresponding inputs, \(\mathbf{X}\), then we are really interogating the following probability density, \[
+\] which is known as Bayes’ rule (or Bayes’s rule, it depends how you choose to pronounce it). It’s not difficult to derive, and its importance is more to do with the semantic operation that it enables. Each of these probability distributions represents the answer to a question we have about the world. Bayes rule (via the product rule) tells us how to invert the probability. Figure: Two barrels: Barrel One holds 20 apples and 4 oranges; Barrel Two holds 4 apples and 8 oranges. A barrel is chosen uniformly at random and a single fruit is drawn. Work the numbers on the board if time allows. The same pattern applies to coins, medical tests, or any two-hypothesis discrete update. That last number is Shannon entropy in nats: \(H(p)=\mathbb{E}_{p}[-\log p(y)]=-\sum_y p(y)\log p(y)\). Same arithmetic under another name. What use is all this probability in data science? Let’s think about how we might use the probabilities to do some decision making. Let’s look at the information data. Now we see we have several additional features. Let’s assume we want to predict Using what you’ve learnt about joint, conditional and marginal probabilities, as well as the sum and product rule, how would you formulate the question you want to answer in terms of probabilities? Should you be using a joint or a conditional distribution? If it’s conditional, what should the distribution be over, and what should it be conditioned on? This Bayesian approach is designed to deal with uncertainty arising from fitting our prediction function to the data we have, a reduced data set. The Bayesian approach can be derived from a broader understanding of what our objective is. If we accept that we can jointly represent all things that happen in the world with a probability distribution, then we can interogate that probability to make predictions. So, if we are interested in predictions, \(y_*\) at future points input locations of interest, \(\mathbf{ x}_*\) given previously training data, \(\mathbf{ y}\) and corresponding inputs, \(\mathbf{X}\), then we are really interogating the following probability density, \[
p(y_*|\mathbf{ y}, \mathbf{X}, \mathbf{ x}_*),
-\] there is nothing controversial here, as long as you accept that you have a good joint model of the world around you that relates test data to training data, \(p(y_*, \mathbf{ y}, \mathbf{X}, \mathbf{ x}_*)\) then this conditional distribution can be recovered through standard rules of probability (\(\text{data} + \text{model} \rightarrow \text{prediction}\)). We can construct this joint density through the use of the following decomposition: \[
+\] there is nothing controversial here, as long as you accept that you have a good joint model of the world around you that relates test data to training data, \(p(y_*, \mathbf{ y}, \mathbf{X}, \mathbf{ x}_*)\) then this conditional distribution can be recovered through standard rules of probability (\(\text{data} + \text{model} \rightarrow \text{prediction}\)). We can construct this joint density through the use of the following decomposition: \[
p(y_*|\mathbf{ y}, \mathbf{X}, \mathbf{ x}_*) = \int p(y_*|\mathbf{ x}_*, \mathbf{W}) p(\mathbf{W}| \mathbf{ y}, \mathbf{X}) \text{d} \mathbf{W}
-\] where, for convenience, we are assuming all the parameters of the model are now represented by \(\boldsymbol{ \theta}\) (which contains \(\mathbf{W}\) and \(\mathbf{V}\)) and \(p(\boldsymbol{ \theta}| \mathbf{ y}, \mathbf{X})\) is recognised as the posterior density of the parameters given data and \(p(y_*|\mathbf{ x}_*, \boldsymbol{ \theta})\) is the likelihood of an individual test data point given the parameters. The likelihood of the data is normally assumed to be independent across the parameters, \[
-p(\mathbf{ y}|\mathbf{X}, \mathbf{W}) = \prod_{i=1}^np(y_i|\mathbf{ x}_i, \mathbf{W}),\] and if that is so, it is easy to extend our predictions across all future, potential, locations, \[
+\] where, for convenience, we are assuming all the parameters of the model are now represented by \(\boldsymbol{ \theta}\) (which contains \(\mathbf{W}\) and \(\mathbf{V}\)) and \(p(\boldsymbol{ \theta}| \mathbf{ y}, \mathbf{X})\) is recognised as the posterior density of the parameters given data and \(p(y_*|\mathbf{ x}_*, \boldsymbol{ \theta})\) is the likelihood of an individual test data point given the parameters. The likelihood of the data is normally assumed to be independent across the parameters, \[
+p(\mathbf{ y}|\mathbf{X}, \mathbf{W}) = \prod_{i=1}^np(y_i|\mathbf{ x}_i, \mathbf{W}),\] and if that is so, it is easy to extend our predictions across all future, potential, locations, \[
p(\mathbf{ y}_*|\mathbf{ y}, \mathbf{X}, \mathbf{X}_*) = \int p(\mathbf{ y}_*|\mathbf{X}_*, \boldsymbol{ \theta}) p(\boldsymbol{ \theta}| \mathbf{ y}, \mathbf{X}) \text{d} \boldsymbol{ \theta}.
-\] The likelihood is also where the prediction function is incorporated. For example in the regression case, we consider an objective based around the Gaussian density, \[
+\] The likelihood is also where the prediction function is incorporated. For example in the regression case, we consider an objective based around the Gaussian density, \[
p(y_i | f(\mathbf{ x}_i)) = \frac{1}{\sqrt{2\pi \sigma^2}} \exp\left(-\frac{\left(y_i - f(\mathbf{ x}_i)\right)^2}{2\sigma^2}\right)
-\] In short, that is the classical approach to probabilistic inference, and all approaches to Bayesian neural networks fall within this path. For a deep probabilistic model, we can simply take this one stage further and place a probability distribution over the input locations, \[
+\] In short, that is the classical approach to probabilistic inference, and all approaches to Bayesian neural networks fall within this path. For a deep probabilistic model, we can simply take this one stage further and place a probability distribution over the input locations, \[
p(\mathbf{ y}_*|\mathbf{ y}) = \int p(\mathbf{ y}_*|\mathbf{X}_*, \boldsymbol{ \theta}) p(\boldsymbol{ \theta}| \mathbf{ y}, \mathbf{X}) p(\mathbf{X}) p(\mathbf{X}_*) \text{d} \boldsymbol{ \theta}\text{d} \mathbf{X}\text{d}\mathbf{X}_*
-\] and we have unsupervised learning (from where we can get deep generative models). One way of representing a joint distribution is to consider conditional dependencies between data. Conditional dependencies allow us to factorize the distribution. For example, a Markov chain is a factorization of a distribution into components that represent the conditional relationships between points that are neighboring, often in time or space. It can be decomposed in the following form. \[p(\mathbf{ y}) = p(y_n| y_{n-1}) p(y_{n-1}|y_{n-2}) \dots p(y_{2} | y_{1})\] Figure: A Markov chain is a simple form of probabilistic graphical model providing a particular decomposition of the joint density. By specifying conditional independencies we can reduce the parameterization required for our data, instead of directly specifying the parameters of the joint distribution, we can specify each set of parameters of the conditonal independently. This can also give an advantage in terms of interpretability. Understanding a conditional independence structure gives a structured understanding of data. If developed correctly, according to causal methodology, it can even inform how we should intervene in the system to drive a desired result (Pearl, 1995). However, a challenge arises when the data becomes more complex. Consider the graphical model shown below, used to predict the perioperative risk of C Difficile infection following colon surgery (Steele et al., 2012). Figure: A probabilistic directed graph used to predict the perioperative risk of C Difficile infection following colon surgery. When these models have good predictive performance they are often difficult to interpret. This may be due to the limited representation capability of the conditional densities in the model. To capture the complexity in the interelationship between the data, the graph itself becomes more complex, and less interpretable. Classification is perhaps the technique most closely assocated with machine learning. In the speech based agents, on-device classifiers are used to determine when the wake word is used. A wake word is a word that wakes up the device. For the Amazon Echo it is “Alexa,” for Siri it is “Hey Siri.” Once the wake word detected with a classifier, the speech can be uploaded to the cloud for full processing, the speech recognition stages. This isn’t just useful for intelligent agents, the UN global pulse project on public discussion on radio also uses wake word detection for recording radio conversations. A major breakthrough in image classification came in 2012 with the ImageNet result of Alex Krizhevsky, Ilya Sutskever and Geoff Hinton from the University of Toronto. ImageNet is a large data base of 14 million images with many thousands of classes. The data is used in a community-wide challenge for object categorization. Krizhevsky et al used convolutional neural networks to outperform all previous approaches on the challenge. They formed a company which was purchased shortly after by Google. This challenge, known as object categorisation, was a major obstacle for practical computer vision systems. Modern object categorization systems are close to human performance. Machine learning problems normally involve a prediction function and an objective function. Regression is the case where the prediction function iss over the real numbers, so the codomain of the functions, \(f(\mathbf{X})\) was the real numbers or sometimes real vectors. The classification problem consists of predicting whether or not a particular example is a member of a particular class. So we may want to know if a particular image represents a digit 6 or if a particular user will click on a given advert. These are classification problems, and they require us to map to yes or no answers. That makes them naturally discrete mappings. In classification we are given an input vector, \(\mathbf{ x}\), and an associated label, \(y\) which either takes the value \(-1\) to represent no or \(1\) to represent yes. In supervised learning the inputs, \(\mathbf{ x}\), are mapped to a label, \(y\), through a function \(f(\cdot)\) that is dependent on a set of parameters, \(\mathbf{ w}\), \[
+\] and we have unsupervised learning (from where we can get deep generative models). One way of representing a joint distribution is to consider conditional dependencies between data. Conditional dependencies allow us to factorize the distribution. For example, a Markov chain is a factorization of a distribution into components that represent the conditional relationships between points that are neighboring, often in time or space. It can be decomposed in the following form. \[p(\mathbf{ y}) = p(y_n| y_{n-1}) p(y_{n-1}|y_{n-2}) \dots p(y_{2} | y_{1})\] Figure: A Markov chain is a simple form of probabilistic graphical model providing a particular decomposition of the joint density. By specifying conditional independencies we can reduce the parameterization required for our data, instead of directly specifying the parameters of the joint distribution, we can specify each set of parameters of the conditonal independently. This can also give an advantage in terms of interpretability. Understanding a conditional independence structure gives a structured understanding of data. If developed correctly, according to causal methodology, it can even inform how we should intervene in the system to drive a desired result (Pearl, 1995). However, a challenge arises when the data becomes more complex. Consider the graphical model shown below, used to predict the perioperative risk of C Difficile infection following colon surgery (Steele et al., 2012). Figure: A probabilistic directed graph used to predict the perioperative risk of C Difficile infection following colon surgery. When these models have good predictive performance they are often difficult to interpret. This may be due to the limited representation capability of the conditional densities in the model. To capture the complexity in the interelationship between the data, the graph itself becomes more complex, and less interpretable. Classification is perhaps the technique most closely assocated with machine learning. In the speech based agents, on-device classifiers are used to determine when the wake word is used. A wake word is a word that wakes up the device. For the Amazon Echo it is “Alexa”, for Siri it is “Hey Siri”. Once the wake word detected with a classifier, the speech can be uploaded to the cloud for full processing, the speech recognition stages. This isn’t just useful for intelligent agents, the UN global pulse project on public discussion on radio also uses wake word detection for recording radio conversations. A major breakthrough in image classification came in 2012 with the ImageNet result of Alex Krizhevsky, Ilya Sutskever and Geoff Hinton from the University of Toronto. ImageNet is a large data base of 14 million images with many thousands of classes. The data is used in a community-wide challenge for object categorization. Krizhevsky et al used convolutional neural networks to outperform all previous approaches on the challenge. They formed a company which was purchased shortly after by Google. This challenge, known as object categorisation, was a major obstacle for practical computer vision systems. Modern object categorization systems are close to human performance. Machine learning problems normally involve a prediction function and an objective function. Regression is the case where the prediction function iss over the real numbers, so the codomain of the functions, \(f(\mathbf{X})\) was the real numbers or sometimes real vectors. The classification problem consists of predicting whether or not a particular example is a member of a particular class. So we may want to know if a particular image represents a digit 6 or if a particular user will click on a given advert. These are classification problems, and they require us to map to yes or no answers. That makes them naturally discrete mappings. In classification we are given an input vector, \(\mathbf{ x}\), and an associated label, \(y\) which either takes the value \(-1\) to represent no or \(1\) to represent yes. In supervised learning the inputs, \(\mathbf{ x}\), are mapped to a label, \(y\), through a function \(f(\cdot)\) that is dependent on a set of parameters, \(\mathbf{ w}\), \[
y= f(\mathbf{ x}; \mathbf{ w}).
-\] The function \(f(\cdot)\) is known as the prediction function. The key challenges are (1) choosing which features, \(\mathbf{ x}\), are relevant in the prediction, (2) defining the appropriate class of function, \(f(\cdot)\), to use and (3) selecting the right parameters, \(\mathbf{ w}\). There are many difference examples of classification problems. One of theoldest is the classification of hand written digits from binary images. The MNIST data was for a long time considered one of the most difficult data sets. When we download this data we are making use of open source code, through the scikit learn project, and the OpenML project which provides open access to data. This reflects a tradition of openness in machine learning that has enabled the tools to be deployed. We will look at a sub-sample of the MNIST digit data set. THE MNIST DATABASE of handwritten digits was created by Yann LeCun, Corinna Cortes and Christopher J. C. Burges. More details can be found at Yann’s site http://yann.lecun.com/exdb/mnist/ The data is a modified version of a data set from the US National Institute of Standards and Technology (NIST. First load in the MNIST data set from scikit learn. This can take a little while because it’s large to download. Sub-sample the dataset to make the training faster. There are many difference examples of classification problems. One of theoldest is the classification of hand written digits from binary images. The MNIST data was for a long time considered one of the most difficult data sets. When we download this data we are making use of open source code, through the scikit learn project, and the OpenML project which provides open access to data. This reflects a tradition of openness in machine learning that has enabled the tools to be deployed. We will look at a sub-sample of the MNIST digit data set. THE MNIST DATABASE of handwritten digits was created by Yann LeCun, Corinna Cortes and Christopher J. C. Burges. More details can be found at Yann’s site http://yann.lecun.com/exdb/mnist/ The data is a modified version of a data set from the US National Institute of Standards and Technology (NIST. First load in the MNIST data set from scikit learn. This can take a little while because it’s large to download. Sub-sample the dataset to make the training faster. Now let’s visualise some examples from our subsampled dataset to get a sense of what the data looks like. Figure: Examples of MNIST digits 0-4 from our subsampled dataset, showing 5 examples of each digit. The visualization shows the variety in handwritten digits even within the same class. Each row represents a different digit (0 through 4), and each column shows a different example of that digit. While the MNIST data doesn’t capture all the nuances of the challenges we face in modern machine learning. It has been an important benchmark data set for and can still be a useful data set for learning about classfication algorithms. Our focus has been on models where the objective function is inspired by a probabilistic analysis of the problem. In particular we’ve argued that we answer questions about the data set by placing probability distributions over the various quantities of interest. For the case of binary classification this will normally involve introducing probability distributions for discrete variables. Such probability distributions, are in some senses easier than those for continuous variables, in particular we can represent a probability distribution over \(y\), where \(y\) is binary, with one value. If we specify the probability that \(y=1\) with a number that is between 0 and 1, i.e. let’s say that \(P(y=1) = \pi\) (here we don’t mean \(\pi\) the number, we are setting \(\pi\) to be a variable) then we can specify the probability distribution through a table. Mathematically we can use a trick to implement this same table. We can use the value \(y\) as a mathematical switch and write that \[
+Y /= 255 Now let’s visualise some examples from our subsampled dataset to get a sense of what the data looks like. Figure: Examples of MNIST digits 0-4 from our subsampled dataset, showing 5 examples of each digit. The visualization shows the variety in handwritten digits even within the same class. Each row represents a different digit (0 through 4), and each column shows a different example of that digit. While the MNIST data doesn’t capture all the nuances of the challenges we face in modern machine learning. It has been an important benchmark data set for and can still be a useful data set for learning about classfication algorithms. Our focus has been on models where the objective function is inspired by a probabilistic analysis of the problem. In particular we’ve argued that we answer questions about the data set by placing probability distributions over the various quantities of interest. For the case of binary classification this will normally involve introducing probability distributions for discrete variables. Such probability distributions, are in some senses easier than those for continuous variables, in particular we can represent a probability distribution over \(y\), where \(y\) is binary, with one value. If we specify the probability that \(y=1\) with a number that is between 0 and 1, i.e. let’s say that \(P(y=1) = \pi\) (here we don’t mean \(\pi\) the number, we are setting \(\pi\) to be a variable) then we can specify the probability distribution through a table. Mathematically we can use a trick to implement this same table. We can use the value \(y\) as a mathematical switch and write that \[
P(y) = \pi^y(1-\pi)^{(1-y)}
- \] where our probability distribution is now written as a function of \(y\). This probability distribution is known as the Bernoulli distribution. The Bernoulli distribution is a clever trick for mathematically switching between two probabilities if we were to write it as code it would be better described as If we insert \(y=1\) then the function is equal to \(\pi\), and if we insert \(y=0\) then the function is equal to \(1-\pi\). So the function recreates the table for the distribution given above. The probability distribution is named for Jacob Bernoulli, the swiss mathematician. In his book Ars Conjectandi he considered the distribution and the result of a number of ‘trials’ under the Bernoulli distribution to form the binomial distribution. Below is the page where he considers Pascal’s triangle in forming combinations of the Bernoulli distribution to realise the binomial distribution for the outcome of positive trials. Figure: Jacob Bernoulli described the Bernoulli distribution through an urn in which there are black and red balls. Thomas Bayes also described the Bernoulli distribution, only he didn’t refer to Jacob Bernoulli’s work, so he didn’t call it by that name. He described the distribution in terms of a table (think of a billiard table) and two balls. Bayes suggests that each ball can be rolled across the table such that it comes to rest at a position that is uniformly distributed between the sides of the table. Let’s assume that the first ball is rolled, and that it comes to reset at a position that is \(\pi\) times the width of the table from the left hand side. Now, we roll the second ball. We are interested if the second ball ends up on the left side (+ve result) or the right side (-ve result) of the first ball. We use the Bernoulli distribution to determine this. For this reason in Bayes’s distribution there is considered to be aleatoric uncertainty about the distribution parameter. Figure: Thomas Bayes described the Bernoulli distribution independently of Jacob Bernoulli. He used the analogy of a billiard table. Any ball on the table is given a uniformly random position between the left and right side of the table. The first ball (in the figure) gives the parameter of the Bernoulli distribution. The second ball (in the figure) gives the outcome as either left or right (relative to the first ball). This is the origin of the term Bayesian because the parameter of the distribution is drawn from a probsbility. Maximum likelihood in the Bernoulli distribution is straightforward. Let’s assume we have data, \(\mathbf{ y}\) which consists of a vector of binary values of length \(n\). If we assume each value was sampled independently from the Bernoulli distribution, conditioned on the parameter \(\pi\) then our joint probability density has the form \[
+ return 1-pi If we insert \(y=1\) then the function is equal to \(\pi\), and if we insert \(y=0\) then the function is equal to \(1-\pi\). So the function recreates the table for the distribution given above. The probability distribution is named for Jacob Bernoulli, the swiss mathematician. In his book Ars Conjectandi he considered the distribution and the result of a number of ‘trials’ under the Bernoulli distribution to form the binomial distribution. Below is the page where he considers Pascal’s triangle in forming combinations of the Bernoulli distribution to realise the binomial distribution for the outcome of positive trials. Figure: Jacob Bernoulli described the Bernoulli distribution through an urn in which there are black and red balls. Thomas Bayes also described the Bernoulli distribution, only he didn’t refer to Jacob Bernoulli’s work, so he didn’t call it by that name. He described the distribution in terms of a table (think of a billiard table) and two balls. Bayes suggests that each ball can be rolled across the table such that it comes to rest at a position that is uniformly distributed between the sides of the table. Let’s assume that the first ball is rolled, and that it comes to reset at a position that is \(\pi\) times the width of the table from the left hand side. Now, we roll the second ball. We are interested if the second ball ends up on the left side (+ve result) or the right side (-ve result) of the first ball. We use the Bernoulli distribution to determine this. For this reason in Bayes’s distribution there is considered to be aleatoric uncertainty about the distribution parameter. Figure: Thomas Bayes described the Bernoulli distribution independently of Jacob Bernoulli. He used the analogy of a billiard table. Any ball on the table is given a uniformly random position between the left and right side of the table. The first ball (in the figure) gives the parameter of the Bernoulli distribution. The second ball (in the figure) gives the outcome as either left or right (relative to the first ball). This is the origin of the term Bayesian because the parameter of the distribution is drawn from a probsbility. Maximum likelihood in the Bernoulli distribution is straightforward. Let’s assume we have data, \(\mathbf{ y}\) which consists of a vector of binary values of length \(n\). If we assume each value was sampled independently from the Bernoulli distribution, conditioned on the parameter \(\pi\) then our joint probability density has the form \[
p(\mathbf{ y}|\pi) = \prod_{i=1}^{n} \pi^{y_i} (1-\pi)^{1-y_i}.
\] As normal in maximum likelihood we consider the negative log likelihood as our objective, \[\begin{align*}
- E(\pi)& = -\log p(\mathbf{ y}|\pi)\\
+ E(\pi)& = -\log p(\mathbf{ y}|\pi)\\
& = -\sum_{i=1}^{n} y_i \log \pi - \sum_{i=1}^{n} (1-y_i) \log(1-\pi),
- \end{align*}\] and we can derive the gradient with respect to the parameter \(\pi\). \[\frac{\text{d}E(\pi)}{\text{d}\pi} = -\frac{\sum_{i=1}^{n} y_i}{\pi} + \frac{\sum_{i=1}^{n} (1-y_i)}{1-\pi},\] and as normal we look for a stationary point for the log likelihood by setting this derivative to zero, \[0 = -\frac{\sum_{i=1}^{n} y_i}{\pi} + \frac{\sum_{i=1}^{n} (1-y_i)}{1-\pi},\] rearranging we form \[(1-\pi)\sum_{i=1}^{n} y_i = \pi\sum_{i=1}^{n} (1-y_i),\] which implies \[\sum_{i=1}^{n} y_i = \pi\left(\sum_{i=1}^{n} (1-y_i) + \sum_{i=1}^{n} y_i\right),\] and now we recognise that \(\sum_{i=1}^{n} (1-y_i) + \sum_{i=1}^{n} y_i = n\) so we have \[\pi = \frac{\sum_{i=1}^{n} y_i}{n}\] so in other words we estimate the probability associated with the Bernoulli by setting it to the number of observed positives, divided by the total length of \(y\). This makes intiutive sense. If I asked you to estimate the probability of a coin being heads, and you tossed the coin 100 times, and recovered 47 heads, then the estimate of the probability of heads should be \(\frac{47}{100}\). Show that the maximum likelihood solution we have found is a minimum for our objective. \[
+ \end{align*}\] and we can derive the gradient with respect to the parameter \(\pi\). \[\frac{\text{d}E(\pi)}{\text{d}\pi} = -\frac{\sum_{i=1}^{n} y_i}{\pi} + \frac{\sum_{i=1}^{n} (1-y_i)}{1-\pi},\] and as normal we look for a stationary point for the log likelihood by setting this derivative to zero, \[0 = -\frac{\sum_{i=1}^{n} y_i}{\pi} + \frac{\sum_{i=1}^{n} (1-y_i)}{1-\pi},\] rearranging we form \[(1-\pi)\sum_{i=1}^{n} y_i = \pi\sum_{i=1}^{n} (1-y_i),\] which implies \[\sum_{i=1}^{n} y_i = \pi\left(\sum_{i=1}^{n} (1-y_i) + \sum_{i=1}^{n} y_i\right),\] and now we recognise that \(\sum_{i=1}^{n} (1-y_i) + \sum_{i=1}^{n} y_i = n\) so we have \[\pi = \frac{\sum_{i=1}^{n} y_i}{n}\] so in other words we estimate the probability associated with the Bernoulli by setting it to the number of observed positives, divided by the total length of \(y\). This makes intiutive sense. If I asked you to estimate the probability of a coin being heads, and you tossed the coin 100 times, and recovered 47 heads, then the estimate of the probability of heads should be \(\frac{47}{100}\). Show that the maximum likelihood solution we have found is a minimum for our objective. \[
\text{posterior} =
\frac{\text{likelihood}\times\text{prior}}{\text{marginal likelihood}}
-\] Four components: Note: Everything we do below is possible using standard packages like In probabilistic machine learning we place probability distributions (or densities) over all the variables of interest, our first classification algorithm will do just that. We will consider how to form a classification by making assumptions about the joint density of our observations. We need to make assumptions to reduce the number of parameters we need to optimise. In the ideal world, given label data \(\mathbf{ y}\) and the inputs \(\mathbf{X}\) we should be able to specify the joint density of all potential values of \(\mathbf{ y}\) and \(\mathbf{X}\), \(p(\mathbf{ y}, \mathbf{X})\). If \(\mathbf{X}\) and \(\mathbf{ y}\) are our training data, and we can somehow extend our density to incorporate future test data (by augmenting \(\mathbf{ y}\) with a new observation \(y^*\) and \(\mathbf{X}\) with the corresponding inputs, \(\mathbf{ x}^*\)), then we can answer any given question about a future test point \(y^*\) given its covariates \(\mathbf{ x}^*\) by conditioning on the training variables to recover, \[
+\] Four components: Note: Everything we do below is possible using standard packages like In probabilistic machine learning we place probability distributions (or densities) over all the variables of interest, our first classification algorithm will do just that. We will consider how to form a classification by making assumptions about the joint density of our observations. We need to make assumptions to reduce the number of parameters we need to optimise. In the ideal world, given label data \(\mathbf{ y}\) and the inputs \(\mathbf{X}\) we should be able to specify the joint density of all potential values of \(\mathbf{ y}\) and \(\mathbf{X}\), \(p(\mathbf{ y}, \mathbf{X})\). If \(\mathbf{X}\) and \(\mathbf{ y}\) are our training data, and we can somehow extend our density to incorporate future test data (by augmenting \(\mathbf{ y}\) with a new observation \(y^*\) and \(\mathbf{X}\) with the corresponding inputs, \(\mathbf{ x}^*\)), then we can answer any given question about a future test point \(y^*\) given its covariates \(\mathbf{ x}^*\) by conditioning on the training variables to recover, \[
p(y^*|\mathbf{X}, \mathbf{ y}, \mathbf{ x}^*),
-\] We can compute this distribution using the product and sum rules. However, to specify this density we must give the probability associated with all possible combinations of \(\mathbf{ y}\) and \(\mathbf{X}\). There are \(2^{n}\) possible combinations for the vector \(\mathbf{ y}\) and the probability for each of these combinations must be jointly specified along with the joint density of the matrix \(\mathbf{X}\), as well as being able to extend the density for any chosen test location \(\mathbf{ x}^*\). In naive Bayes we make certain simplifying assumptions that allow us to perform all of the above in practice. If we are given model parameters \(\boldsymbol{ \theta}\) we assume that conditioned on all these parameters that all data points in the model are independent. In other words we have, \[
+\] We can compute this distribution using the product and sum rules. However, to specify this density we must give the probability associated with all possible combinations of \(\mathbf{ y}\) and \(\mathbf{X}\). There are \(2^{n}\) possible combinations for the vector \(\mathbf{ y}\) and the probability for each of these combinations must be jointly specified along with the joint density of the matrix \(\mathbf{X}\), as well as being able to extend the density for any chosen test location \(\mathbf{ x}^*\). In naive Bayes we make certain simplifying assumptions that allow us to perform all of the above in practice. If we are given model parameters \(\boldsymbol{ \theta}\) we assume that conditioned on all these parameters that all data points in the model are independent. In other words we have, \[
p(y^*, \mathbf{ x}^*, \mathbf{ y}, \mathbf{X}|\boldsymbol{ \theta}) = p(y^*, \mathbf{ x}^*|\boldsymbol{ \theta})\prod_{i=1}^{n} p(y_i, \mathbf{ x}_i | \boldsymbol{ \theta}).
- \] This is a conditional independence assumption because we are not assuming our data are purely independent. If we were to assume that, then there would be nothing to learn about our test data given our training data. We are assuming that they are independent given our parameters, \(\boldsymbol{ \theta}\). We made similar assumptions for regression, where our parameter set included \(\mathbf{ w}\) and \(\sigma^2\). Given those parameters we assumed that the density over \(\mathbf{ y}, y^*\) was independent. Here we are going a little further with that assumption because we are assuming the joint density of \(\mathbf{ y}\) and \(\mathbf{X}\) is independent across the data given the parameters. Computing posterior distribution in this case becomes easier, this is known as the ‘Bayes classifier.’ \[
+ \] This is a conditional independence assumption because we are not assuming our data are purely independent. If we were to assume that, then there would be nothing to learn about our test data given our training data. We are assuming that they are independent given our parameters, \(\boldsymbol{ \theta}\). We made similar assumptions for regression, where our parameter set included \(\mathbf{ w}\) and \(\sigma^2\). Given those parameters we assumed that the density over \(\mathbf{ y}, y^*\) was independent. Here we are going a little further with that assumption because we are assuming the joint density of \(\mathbf{ y}\) and \(\mathbf{X}\) is independent across the data given the parameters. Computing posterior distribution in this case becomes easier, this is known as the ‘Bayes classifier’. \[
p(\mathbf{ x}_i | y_i, \boldsymbol{ \theta}) = \prod_{j=1}^{d} p(x_{i,j}|y_i, \boldsymbol{ \theta})
-\] where \(d\) is the dimensionality of our inputs. The assumption that is particular to naive Bayes is to now consider that the features are also conditionally independent, but not only given the parameters. We assume that the features are independent given the parameters and the label. So for each data point we have \[p(\mathbf{ x}_i | y_i, \boldsymbol{ \theta}) = \prod_{j=1}^{d} p(x_{i,j}|y_i,\boldsymbol{ \theta})\] where \(d\) is the dimensionality of our inputs. \[
+\] where \(d\) is the dimensionality of our inputs. The assumption that is particular to naive Bayes is to now consider that the features are also conditionally independent, but not only given the parameters. We assume that the features are independent given the parameters and the label. So for each data point we have \[p(\mathbf{ x}_i | y_i, \boldsymbol{ \theta}) = \prod_{j=1}^{d} p(x_{i,j}|y_i,\boldsymbol{ \theta})\] where \(d\) is the dimensionality of our inputs. \[
p(x_{i,j},y_i| \boldsymbol{ \theta}) = p(x_{i,j}|y_i, \boldsymbol{ \theta})p(y_i).
-\] We now have nearly all of the components we need to specify the full joint density. However, the feature conditional independence doesn’t yet give us the joint density over \(p(y_i, \mathbf{ x}_i)\) which is required to subsitute in to our data conditional independence to give us the full density. To recover the joint density given the conditional distribution of each feature, \(p(x_{i,j}|y_i, \boldsymbol{ \theta})\), we need to make use of the product rule and combine it with a marginal density for \(y_i\), \[p(x_{i,j},y_i| \boldsymbol{ \theta}) = p(x_{i,j}|y_i, \boldsymbol{ \theta})p(y_i).\] Because \(y_i\) is binary the Bernoulli density makes a suitable choice for our prior over \(y_i\), \[p(y_i|\pi) = \pi^{y_i} (1-\pi)^{1-y_i}\] where \(\pi\) now has the interpretation as being the prior probability that the classification should be positive. This allows us to write down the full joint density of the training data, \[
+\] We now have nearly all of the components we need to specify the full joint density. However, the feature conditional independence doesn’t yet give us the joint density over \(p(y_i, \mathbf{ x}_i)\) which is required to subsitute in to our data conditional independence to give us the full density. To recover the joint density given the conditional distribution of each feature, \(p(x_{i,j}|y_i, \boldsymbol{ \theta})\), we need to make use of the product rule and combine it with a marginal density for \(y_i\), \[p(x_{i,j},y_i| \boldsymbol{ \theta}) = p(x_{i,j}|y_i, \boldsymbol{ \theta})p(y_i).\] Because \(y_i\) is binary the Bernoulli density makes a suitable choice for our prior over \(y_i\), \[p(y_i|\pi) = \pi^{y_i} (1-\pi)^{1-y_i}\] where \(\pi\) now has the interpretation as being the prior probability that the classification should be positive. This allows us to write down the full joint density of the training data, \[
p(\mathbf{ y}, \mathbf{X}|\boldsymbol{ \theta}, \pi) = \prod_{i=1}^{n} \prod_{j=1}^{d} p(x_{i,j}|y_i, \boldsymbol{ \theta})p(y_i|\pi)
- \] which can now be fit by maximum likelihood. As normal we form our objective as the negative log likelihood, \[\begin{align*}
+ \] which can now be fit by maximum likelihood. As normal we form our objective as the negative log likelihood, \[\begin{align*}
E(\boldsymbol{ \theta}, \pi)& = -\log p(\mathbf{ y}, \mathbf{X}|\boldsymbol{ \theta}, \pi) \\ &= -\sum_{i=1}^{n} \sum_{j=1}^{d} \log p(x_{i, j}|y_i, \boldsymbol{ \theta}) - \sum_{i=1}^{n} \log p(y_i|\pi),
\end{align*}\] which we note decomposes into two objective functions, one which is dependent on \(\pi\) alone and one which is dependent on \(\boldsymbol{ \theta}\) alone so we have, \[
E(\pi, \boldsymbol{ \theta}) = E(\boldsymbol{ \theta}) + E(\pi).
@@ -159,16 +611,28 @@
E(\pi) = -\sum_{i=1}^{n}\log p(y_i|\pi) = -\sum_{i=1}^{n} y_i \log \pi - \sum_{i=1}^{n} (1-y_i) \log (1-\pi)
\] which we already minimized above recovering \[
\pi = \frac{\sum_{i=1}^{n} y_i}{n}.
-\] We now need to minimize the objective associated with the conditional distributions for the features, \[
+\] We now need to minimize the objective associated with the conditional distributions for the features, \[
E(\boldsymbol{ \theta}) = -\sum_{i=1}^{n} \sum_{j=1}^{d} \log p(x_{i, j} |y_i, \boldsymbol{ \theta}),
\] which necessarily implies making some assumptions about the form of the conditional distributions. The right assumption will depend on the nature of our input data. For example, if we have an input which is real valued, we could use a Gaussian density and we could allow the mean and variance of the Gaussian to be different according to whether the class was positive or negative and according to which feature we were measuring. That would give us the form, \[
p(x_{i, j} | y_i,\boldsymbol{ \theta}) = \frac{1}{\sqrt{2\pi \sigma_{y_i,j}^2}} \exp \left(-\frac{(x_{i,j} - \mu_{y_i, j})^2}{\sigma_{y_i,j}^2}\right),
-\] where \(\sigma_{1, j}^2\) is the variance of the density for the \(j\)th output and the class \(y_i=1\) and \(\sigma_{0, j}^2\) is the variance if the class is 0. The means can vary similarly. Our parameters, \(\boldsymbol{ \theta}\) would consist of all the means and all the variances for the different dimensions. As normal we form our objective as the negative log likelihood, \[
+\] where \(\sigma_{1, j}^2\) is the variance of the density for the \(j\)th output and the class \(y_i=1\) and \(\sigma_{0, j}^2\) is the variance if the class is 0. The means can vary similarly. Our parameters, \(\boldsymbol{ \theta}\) would consist of all the means and all the variances for the different dimensions. As normal we form our objective as the negative log likelihood, \[
E(\boldsymbol{ \theta}, \pi) = -\log p(\mathbf{ y}, \mathbf{X}|\boldsymbol{ \theta}, \pi) = -\sum_{i=1}^{n} \sum_{j=1}^{d} \log p(x_{i, j}|y_i, \boldsymbol{ \theta}) - \sum_{i=1}^{n} \log p(y_i|\pi),
\] which we note decomposes into two objective functions, one which is dependent on \(\pi\) alone and one which is dependent on \(\boldsymbol{ \theta}\) alone so we have, \[
E(\pi, \boldsymbol{ \theta}) = E(\boldsymbol{ \theta}) + E(\pi).
-\] Our aim will be to predict whether a center has maternal health delivery services given the attributes in the data. We will predict of the number of nurses, the number of doctors, location etc. Now we will convert this data into a form which we can use as inputs Our aim will be to predict whether a center has maternal health delivery services given the attributes in the data. We will predict of the number of nurses, the number of doctors, location etc. Now we will convert this data into a form which we can use as inputs This has given us a new data frame We can now specify the naive Bayes model. For the genres we want to model the data as Bernoulli distributed, and for the year and body count we want to model the data as Gaussian distributed. We set up two data frames to contain the parameters for the rows and the columns below. This has given us a new data frame We can now specify the naive Bayes model. For the genres we want to model the data as Bernoulli distributed, and for the year and body count we want to model the data as Gaussian distributed. We set up two data frames to contain the parameters for the rows and the columns below. Now we have the data in a form ready for analysis, let’s construct our data matrix. Now we have the data in a form ready for analysis, let’s construct our data matrix. And we can now train the model. For each feature we can make the fit independently. The fit is given by either counting the number of positives (for binary data) which gives us the maximum likelihood solution for the Bernoulli. Or by computing the empirical mean and variance of the data for the Gaussian, which also gives us the maximum likelihood solution. And we can now train the model. For each feature we can make the fit independently. The fit is given by either counting the number of positives (for binary data) which gives us the maximum likelihood solution for the Bernoulli. Or by computing the empirical mean and variance of the data for the Gaussian, which also gives us the maximum likelihood solution. We can examine the nature of the distributions we’ve fitted to the model by looking at the entries in these data frames. The distributions show the parameters of the independent class conditional probabilities for no maternity services. It is a Bernoulli distribution with the parameter, \(\pi\), given by ( The naive Bayes assumption says that the joint probability for these services is given by the product of each of these Bernoulli distributions. We have modelled the numbers in our table with a Gaussian density. Since several of these numbers are counts, a more appropriate distribution might be the Poisson distribution. But here we can see that the average number of nurses, healthworkers and doctors is higher in the facilities with maternal services ( The final model parameter is the prior probability of the positive class, \(\pi\), which is computed by maximum likelihood. The prior probability tells us that slightly more facilities have maternity services than those that don’t. Naive Bayes has given us the class conditional densities: \(p(\mathbf{ x}_i | y_i, \boldsymbol{ \theta})\). To make predictions with these densities we need to form the distribution given by \[
+ Bernoulli[column]['theta_1'] = X_train[column][y_train].sum()/(y_train).sum() We can examine the nature of the distributions we’ve fitted to the model by looking at the entries in these data frames. The distributions show the parameters of the independent class conditional probabilities for no maternity services. It is a Bernoulli distribution with the parameter, \(\pi\), given by ( The naive Bayes assumption says that the joint probability for these services is given by the product of each of these Bernoulli distributions. We have modelled the numbers in our table with a Gaussian density. Since several of these numbers are counts, a more appropriate distribution might be the Poisson distribution. But here we can see that the average number of nurses, healthworkers and doctors is higher in the facilities with maternal services ( The final model parameter is the prior probability of the positive class, \(\pi\), which is computed by maximum likelihood. The prior probability tells us that slightly more facilities have maternity services than those that don’t. Naive Bayes has given us the class conditional densities: \(p(\mathbf{ x}_i | y_i, \boldsymbol{ \theta})\). To make predictions with these densities we need to form the distribution given by \[
P(y^*| \mathbf{ y}, \mathbf{X}, \mathbf{ x}^*, \boldsymbol{ \theta})
\] This can be computed by using the product rule. We know that \[
P(y^*| \mathbf{ y}, \mathbf{X}, \mathbf{ x}^*, \boldsymbol{ \theta})p(\mathbf{ y}, \mathbf{X}, \mathbf{ x}^*|\boldsymbol{ \theta}) = p(y*, \mathbf{ y}, \mathbf{X}, \mathbf{ x}^*| \boldsymbol{ \theta})
@@ -248,20 +735,32 @@
\] and we notice that all the terms associated with the training data actually cancel, the test prediction is conditionally independent of the training data given the parameters. This is a result of our conditional independence assumptions over the data points. \[
p(y^*| \mathbf{ x}^*, \boldsymbol{ \theta}) = \frac{\prod_{j=1}^{d} p(x^*_{j}|y^*_i,
\boldsymbol{ \theta})p(y^*|\pi)}{\sum_{y^*=0}^1 \prod_{j=1}^{d} p(x^*_{j}|y^*_i, \boldsymbol{ \theta})p(y^*|\pi)}
-\] This formula is also fairly straightforward to implement. First we implement the log probabilities for the Gaussian density. Now for any test point we compute the joint distribution of the Gaussian features by summing their log probabilities. Working in log space can be a considerable advantage over computing the probabilities directly: as the number of features we include goes up, because all the probabilities are less than 1, the joint probability will become smaller and smaller, and may be difficult to represent accurately (or even underflow). Working in log space can ameliorate this problem. We can also compute the log probability for the Bernoulli distribution. Before we proceed, let’s just pause and think for a moment what will happen if Laplace suggests that when computing the probability of an event where a success or failure is rare (he uses an example of the sun rising across the last 5,000 years or 1,826,213 days) that even though only successes have been observed (in the sun rising case) that the odds for tomorrow shouldn’t be given as \[
+\] This formula is also fairly straightforward to implement. First we implement the log probabilities for the Gaussian density. Now for any test point we compute the joint distribution of the Gaussian features by summing their log probabilities. Working in log space can be a considerable advantage over computing the probabilities directly: as the number of features we include goes up, because all the probabilities are less than 1, the joint probability will become smaller and smaller, and may be difficult to represent accurately (or even underflow). Working in log space can ameliorate this problem. We can also compute the log probability for the Bernoulli distribution. Before we proceed, let’s just pause and think for a moment what will happen if Laplace suggests that when computing the probability of an event where a success or failure is rare (he uses an example of the sun rising across the last 5,000 years or 1,826,213 days) that even though only successes have been observed (in the sun rising case) that the odds for tomorrow shouldn’t be given as \[
\frac{1,826,213}{1,826,213} = 1
\] but rather by adding one to the numerator and two to the denominator, \[
\frac{1,826,213 + 1}{1,826,213 + 2} = 0.99999945.
-\] This technique is sometimes called a ‘pseudocount technique’ because it has an intepretation of assuming some observations before you start, it’s as if instead of observing \(\sum_{i}y_i\) successes you have an additional success, \(\sum_{i}y_i + 1\) and instead of having observed \(n\) events you’ve observed \(n+ 2\). So we can think of Laplace’s idea saying (before we start) that we have ‘two observations worth of belief, that the odds are 50/50,’ because before we start (i.e. when \(n=0\)) our estimate is 0.5, yet because the effective \(n\) is only 2, this estimate is quickly overwhelmed by data. Laplace used ideas like this a lot, and it is known as his ‘principle of insufficient reason.’ His idea was that in the absence of knowledge (i.e. before we start) we should assume that all possible outcomes are equally likely. This idea has a modern counterpart, known as the principle of maximum entropy. A lot of the theory of this approach was developed by Ed Jaynes, who according to his erstwhile collaborator and friend, John Skilling, learnt French as an undergraduate by reading the works of Laplace. Although John also related that Jaynes’s spoken French was not up to the standard of his scientific French. For me Ed Jaynes’s work very much carries on the tradition of Laplace into the modern era, in particular his focus on Bayesian approaches. I’m very proud to have met those that knew and worked with him. It turns out that Laplace’s idea also has a Bayesian interpretation (as Laplace understood), it comes from assuming a particular prior density for the parameter \(\pi\), but we won’t explore that interpretation for the moment, and merely choose to estimate the probability as, \[
+\] This technique is sometimes called a ‘pseudocount technique’ because it has an intepretation of assuming some observations before you start, it’s as if instead of observing \(\sum_{i}y_i\) successes you have an additional success, \(\sum_{i}y_i + 1\) and instead of having observed \(n\) events you’ve observed \(n+ 2\). So we can think of Laplace’s idea saying (before we start) that we have ‘two observations worth of belief, that the odds are 50/50’, because before we start (i.e. when \(n=0\)) our estimate is 0.5, yet because the effective \(n\) is only 2, this estimate is quickly overwhelmed by data. Laplace used ideas like this a lot, and it is known as his ‘principle of insufficient reason’. His idea was that in the absence of knowledge (i.e. before we start) we should assume that all possible outcomes are equally likely. This idea has a modern counterpart, known as the principle of maximum entropy. A lot of the theory of this approach was developed by Ed Jaynes, who according to his erstwhile collaborator and friend, John Skilling, learnt French as an undergraduate by reading the works of Laplace. Although John also related that Jaynes’s spoken French was not up to the standard of his scientific French. For me Ed Jaynes’s work very much carries on the tradition of Laplace into the modern era, in particular his focus on Bayesian approaches. I’m very proud to have met those that knew and worked with him. It turns out that Laplace’s idea also has a Bayesian interpretation (as Laplace understood), it comes from assuming a particular prior density for the parameter \(\pi\), but we won’t explore that interpretation for the moment, and merely choose to estimate the probability as, \[
\pi = \frac{\sum_{i=1}^{n} y_i + 1}{n+ 2}
-\] to prevent problems with certainty causing numerical issues and misclassifications. Let’s refit the Bernoulli features now. That places us in a position to write the prediction function. That places us in a position to write the prediction function. Now we are in a position to make the predictions for the test data. We can test the quality of the predictions in the following way. Firstly, we can threshold our probabilities at 0.5, allocating points with greater than 50% probability of membership of the positive class to the positive class. We can then compare to the true values, and see how many of these values we got correct. This is our total number correct. Now we are in a position to make the predictions for the test data. We can test the quality of the predictions in the following way. Firstly, we can threshold our probabilities at 0.5, allocating points with greater than 50% probability of membership of the positive class to the positive class. We can then compare to the true values, and see how many of these values we got correct. This is our total number correct. We can also now plot the confusion matrix. A confusion matrix tells us where we are making mistakes. Along the diagonal it stores the true positives, the points that were positive class that we classified correctly, and the true negatives, the points that were negative class and that we classified correctly. The off diagonal terms contain the false positives and the false negatives. Along the rows of the matrix we place the actual class, and along the columns we place our predicted class. We can also now plot the confusion matrix. A confusion matrix tells us where we are making mistakes. Along the diagonal it stores the true positives, the points that were positive class that we classified correctly, and the true negatives, the points that were negative class and that we classified correctly. The off diagonal terms contain the false positives and the false negatives. Along the rows of the matrix we place the actual class, and along the columns we place our predicted class. How can you improve your classification, are all the features equally valid? Are some features more helpful than others? What happens if you remove features that appear to be less helpful. How might you select such features? We have decided to classify positive if probability of maternity is greater than 0.5. This has led us to accidentally classify some facilities as havien’t facilities for maternity when in fact they don’t. Imagine you wish to ensure that a facility handles maternity. With your test set how low do you have to set the threshold to avoid all the false negatives (i.e. facilities where you predicted there was no maternity, but in actuality there were? Naive Bayes has given us the class conditional densities: \(p(\mathbf{ x}_i | y_i, \boldsymbol{ \theta})\). To make predictions with these densities we need to form the distribution given by \[
+confusion_matrix How can you improve your classification, are all the features equally valid? Are some features more helpful than others? What happens if you remove features that appear to be less helpful. How might you select such features? We have decided to classify positive if probability of maternity is greater than 0.5. This has led us to accidentally classify some facilities as havien’t facilities for maternity when in fact they don’t. Imagine you wish to ensure that a facility handles maternity. With your test set how low do you have to set the threshold to avoid all the false negatives (i.e. facilities where you predicted there was no maternity, but in actuality there were? Naive Bayes has given us the class conditional densities: \(p(\mathbf{ x}_i | y_i, \boldsymbol{ \theta})\). To make predictions with these densities we need to form the distribution given by \[
P(y^*| \mathbf{ y}, \mathbf{X}, \mathbf{ x}^*, \boldsymbol{ \theta})
-\] Write down the negative log likelihood of the Gaussian density over a vector of variables \(\mathbf{ x}\). Assume independence between each variable. Minimize this objective to obtain the maximum likelihood solution of the form. \[
+\] Write down the negative log likelihood of the Gaussian density over a vector of variables \(\mathbf{ x}\). Assume independence between each variable. Minimize this objective to obtain the maximum likelihood solution of the form. \[
\mu = \frac{\sum_{i=1}^{n} x_i}{n}
\] \[
\sigma^2 = \frac{\sum_{i=1}^{n} (x_i - \mu)^2}{n}
-\] If the input data was binary then we could also make use of the Bernoulli distribution for the features. For that case we would have the form, \[
+\] If the input data was binary then we could also make use of the Bernoulli distribution for the features. For that case we would have the form, \[
p(x_{i, j} | y_i,\boldsymbol{ \theta}) = \theta_{y_i, j}^{x_{i, j}}(1-\theta_{y_i, j})^{(1-x_{i,j})},
-\] where \(\theta_{1, j}\) is the probability that the \(j\)th feature is on if \(y_i\) is 1. In either case, maximum likelihood fitting would proceed in the same way. The objective has the form, \[
+\] where \(\theta_{1, j}\) is the probability that the \(j\)th feature is on if \(y_i\) is 1. In either case, maximum likelihood fitting would proceed in the same way. The objective has the form, \[
E(\boldsymbol{ \theta}) = -\sum_{j=1}^{d} \sum_{i=1}^{n} \log p(x_{i,j} |y_i, \boldsymbol{ \theta}),
\] and if, as above, the parameters of the distributions are specific to each feature vector (we had means and variances for each continuous feature, and a probability for each binary feature) then we can use the fact that these parameters separate into disjoint subsets across the features to write, \[
\begin{align*}
@@ -303,5 +818,40 @@
& \sum_{j=1}^{d}
E(\boldsymbol{ \theta}_j),
\end{align*}
-\] which means we can minimize our objective on each feature independently. These characteristics mean that naive Bayes scales very well with big data. To fit the model we consider each feature in turn, we select the positive class and fit parameters for that class, then we select each negative class and fit features for that class. We have code below. Naive Bayes is making very simple assumptions about the data, in particular it is modeling the full joint probability of the data set, \(p(\mathbf{ y}, \mathbf{X}| \boldsymbol{ \theta}, \pi)\) by very strong assumptions about factorizations that are unlikely to be true in practice. The data conditional independence assumption is common, and relies on a rich parameter vector to absorb all the information in the training data. The additional assumption of naive Bayes is that features are conditional independent given the class label \(y_i\) (and the parameter vector, \(\boldsymbol{ \theta}\). This is quite a strong assumption. However, it causes the objective function to decompose into parts which can be independently fitted to the different feature vectors, meaning it is very easy to fit the model to large data. It is also clear how we should handle streaming data and missing data. This means that the model can be run ‘live,’ adapting parameters and information as it arrives. Indeed, the model is even capable of dealing with new features that might arrive at run time. Such is the strength of the modeling the joint probability density. However, the factorization assumption that allows us to do this efficiently is very strong and may lead to poor decision boundaries in practice. For more information on these subjects and more you might want to check the following resources. These characteristics mean that naive Bayes scales very well with big data. To fit the model we consider each feature in turn, we select the positive class and fit parameters for that class, then we select each negative class and fit features for that class. We have code below. Naive Bayes is making very simple assumptions about the data, in particular it is modeling the full joint probability of the data set, \(p(\mathbf{ y}, \mathbf{X}| \boldsymbol{ \theta}, \pi)\) by very strong assumptions about factorizations that are unlikely to be true in practice. The data conditional independence assumption is common, and relies on a rich parameter vector to absorb all the information in the training data. The additional assumption of naive Bayes is that features are conditional independent given the class label \(y_i\) (and the parameter vector, \(\boldsymbol{ \theta}\). This is quite a strong assumption. However, it causes the objective function to decompose into parts which can be independently fitted to the different feature vectors, meaning it is very easy to fit the model to large data. It is also clear how we should handle streaming data and missing data. This means that the model can be run ‘live’, adapting parameters and information as it arrives. Indeed, the model is even capable of dealing with new features that might arrive at run time. Such is the strength of the modeling the joint probability density. However, the factorization assumption that allows us to do this efficiently is very strong and may lead to poor decision boundaries in practice. For more information on these subjects and more you might want to check the following resources. %%%%%%%%%%%% LOCAL DATA %%%%%%%%%%%%%%%%%%%% https://www.kaggle.com/alaowerre/nigeria-nmis-health-facility-data %%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%% What is machine learning? At its most basic level machine learning is a combination of \[\text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}\] where data is our observations. They can be actively or passively acquired (meta-data). The model contains our assumptions, based on previous experience. That experience can be other data, it can come from transfer learning, or it can merely be our beliefs about the regularities of the universe. In humans our models include our inductive biases. The prediction is an action to be taken or a categorization or a quality score. The reason that machine learning has become a mainstay of artificial intelligence is the importance of predictions in artificial intelligence. The data and the model are combined through computation. In practice we normally perform machine learning using two functions. To combine data with a model we typically make use of: a prediction function it is used to make the predictions. It includes our beliefs about the regularities of the universe, our assumptions about how the world works, e.g., smoothness, spatial similarities, temporal similarities. an objective function it defines the ‘cost’ of misprediction. Typically, it includes knowledge about the world’s generating processes (probabilistic objectives) or the costs we pay for mispredictions (empirical risk minimization). The combination of data and model through the prediction function and the objective function leads to a learning algorithm. The class of prediction functions and objective functions we can make use of is restricted by the algorithms they lead to. If the prediction function or the objective function are too complex, then it can be difficult to find an appropriate learning algorithm. Much of the academic field of machine learning is the quest for new learning algorithms that allow us to bring different types of models and data together. A useful reference for state of the art in machine learning is the UK Royal Society Report, Machine Learning: Power and Promise of Computers that Learn by Example. You can also check my post blog post on What is Machine Learning?. We are now going to do some simple review of probabilities and use this review to explore some aspects of our data. A probability distribution expresses uncertainty about the outcome of an event. We often encode this uncertainty in a variable. So if we are considering the outcome of an event, \(Y\), to be a coin toss, then we might consider \(Y=1\) to be heads and \(Y=0\) to be tails. We represent the probability of a given outcome with the notation: \[
+-->
+ %%%%%%%%%%%% LOCAL DATA %%%%%%%%%%%%%%%%%%%% https://www.kaggle.com/alaowerre/nigeria-nmis-health-facility-data %%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%%% What is machine learning? At its most basic level machine learning is a combination of \[\text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}\] where data is our observations. They can be actively or passively acquired (meta-data). The model contains our assumptions, based on previous experience. That experience can be other data, it can come from transfer learning, or it can merely be our beliefs about the regularities of the universe. In humans our models include our inductive biases. The prediction is an action to be taken or a categorization or a quality score. The reason that machine learning has become a mainstay of artificial intelligence is the importance of predictions in artificial intelligence. The data and the model are combined through computation. In practice we normally perform machine learning using two functions. To combine data with a model we typically make use of: a prediction function it is used to make the predictions. It includes our beliefs about the regularities of the universe, our assumptions about how the world works, e.g., smoothness, spatial similarities, temporal similarities. an objective function it defines the ‘cost’ of misprediction. Typically, it includes knowledge about the world’s generating processes (probabilistic objectives) or the costs we pay for mispredictions (empirical risk minimization). The combination of data and model through the prediction function and the objective function leads to a learning algorithm. The class of prediction functions and objective functions we can make use of is restricted by the algorithms they lead to. If the prediction function or the objective function are too complex, then it can be difficult to find an appropriate learning algorithm. Much of the academic field of machine learning is the quest for new learning algorithms that allow us to bring different types of models and data together. A useful reference for state of the art in machine learning is the UK Royal Society Report, Machine Learning: Power and Promise of Computers that Learn by Example. You can also check my post blog post on What is Machine Learning?. We are now going to do some simple review of probabilities and use this review to explore some aspects of our data. A probability distribution expresses uncertainty about the outcome of an event. We often encode this uncertainty in a variable. So if we are considering the outcome of an event, \(Y\), to be a coin toss, then we might consider \(Y=1\) to be heads and \(Y=0\) to be tails. We represent the probability of a given outcome with the notation: \[
P(Y=1) = 0.5
\] The first rule of probability is that the probability must normalize. The sum of the probability of all events must equal 1. So if the probability of heads (\(Y=1\)) is 0.5, then the probability of tails (the only other possible outcome) is given by \[
P(Y=0) = 1-P(Y=1) = 0.5
-\] Probabilities are often defined as the limit of the ratio between the number of positive outcomes (e.g. heads) given the number of trials. If the number of positive outcomes for event \(y\) is denoted by \(n\) and the number of trials is denoted by \(N\) then this gives the ratio \[
+\] Probabilities are often defined as the limit of the ratio between the number of positive outcomes (e.g. heads) given the number of trials. If the number of positive outcomes for event \(y\) is denoted by \(n\) and the number of trials is denoted by \(N\) then this gives the ratio \[
P(Y=y) = \lim_{N\rightarrow
\infty}\frac{n_y}{N}.
\] In practice we never get to observe an event infinite times, so rather than considering this we often use the following estimate \[
P(Y=y) \approx \frac{n_y}{N}.
-\] As an example data set we will use Nigerian Millennium Development Goals Information System Health Facility (The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) and Columbia University, 2014). It can be found here https://energydata.info/dataset/nigeria-nmis-education-facility-data-2014. Taking from the information on the site, The Nigeria MDG (Millennium Development Goals) Information System – NMIS health facility data is collected by the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) in partner with the Sustainable Engineering Lab at Columbia University. A rigorous, geo-referenced baseline facility inventory across Nigeria is created spanning from 2009 to 2011 with an additional survey effort to increase coverage in 2014, to build Nigeria’s first nation-wide inventory of health facility. The database includes 34,139 health facilities info in Nigeria. The goal of this database is to make the data collected available to planners, government officials, and the public, to be used to make strategic decisions for planning relevant interventions. For data inquiry, please contact Ms. Funlola Osinupebi, Performance Monitoring & Communications, Advisory Power Team, Office of the Vice President at funlola.osinupebi@aptovp.org To learn more, please visit http://csd.columbia.edu/2014/03/10/the-nigeria-mdg-information-system-nmis-takes-open-data-further/ Suggested citation: Nigeria NMIS facility database (2014), the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) & Columbia University For ease of use we’ve packaged this data set in the In Sheffield we created a suite of software tools for ‘Open Data Science.’ Open data science is an approach to sharing code, models and data that should make it easier for companies, health professionals and scientists to gain access to data science techniques. You can also check this blog post on Open Data Science. The software can be installed using from the command prompt where you can access your python installation. The code is also available on GitHub: https://github.com/lawrennd/ods Once Alternatively, you can access the data directly with the following commands. As an example data set we will use Nigerian Millennium Development Goals Information System Health Facility (The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) and Columbia University, 2014). It can be found here https://energydata.info/dataset/nigeria-nmis-education-facility-data-2014. Taking from the information on the site, The Nigeria MDG (Millennium Development Goals) Information System – NMIS health facility data is collected by the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) in partner with the Sustainable Engineering Lab at Columbia University. A rigorous, geo-referenced baseline facility inventory across Nigeria is created spanning from 2009 to 2011 with an additional survey effort to increase coverage in 2014, to build Nigeria’s first nation-wide inventory of health facility. The database includes 34,139 health facilities info in Nigeria. The goal of this database is to make the data collected available to planners, government officials, and the public, to be used to make strategic decisions for planning relevant interventions. For data inquiry, please contact Ms. Funlola Osinupebi, Performance Monitoring & Communications, Advisory Power Team, Office of the Vice President at funlola.osinupebi@aptovp.org To learn more, please visit http://csd.columbia.edu/2014/03/10/the-nigeria-mdg-information-system-nmis-takes-open-data-further/ Suggested citation: Nigeria NMIS facility database (2014), the Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs) & Columbia University For ease of use we’ve packaged this data set in the In Sheffield we created a suite of software tools for ‘Open Data Science’. Open data science is an approach to sharing code, models and data that should make it easier for companies, health professionals and scientists to gain access to data science techniques. You can also check this blog post on Open Data Science. The software can be installed using from the command prompt where you can access your python installation. The code is also available on GitHub: https://github.com/lawrennd/ods Once Alternatively, you can access the data directly with the following commands. Once it is loaded in the data can be summarized using the We can also find out the dimensions of the dataset using the Dataframes have different functions that you can use to explore and understand your data. In python and the Jupyter notebook it is possible to see a list of all possible functions and attributes by typing the name of the object followed by For functions we can also see the documentation about the function by following the name with a question mark. This will open a box with documentation at the bottom which can be closed with the x button. Figure: Location of the over thirty-four thousand health facilities registered in the NMIS data across Nigeria. Each facility plotted according to its latitude and longitude. The NMIS facility data is stored in an object known as a ‘data frame.’ Data frames come from the statistical family of programming languages based on This shows the number of doctors per facility, number of nurses and number of community health workers (CHEWS). We can plot the number of doctors against the number of nurses as follows. You may be curious what the arguments we give to We immediately note that some facilities have a lot of nurses, which prevent’s us seeing the detail of the main number of facilities. First lets identify the facilities with the most nurses. Here we are using the command We now see that the ‘University of Calabar Teaching Hospital’ is a large outlier with 513 nurses. We can try and determine how much of an outlier by histograming the data. We can’t see very much here. Two things are happening. There are so many facilities with zero or one nurse that we don’t see the histogram for hospitals with many nurses. We can try more bins and using a log scale on the \(y\)-axis. Once it is loaded in the data can be summarized using the We can also find out the dimensions of the dataset using the Dataframes have different functions that you can use to explore and understand your data. In python and the Jupyter notebook it is possible to see a list of all possible functions and attributes by typing the name of the object followed by For functions we can also see the documentation about the function by following the name with a question mark. This will open a box with documentation at the bottom which can be closed with the x button. Figure: Location of the over thirty-four thousand health facilities registered in the NMIS data across Nigeria. Each facility plotted according to its latitude and longitude. The NMIS facility data is stored in an object known as a ‘data frame’. Data frames come from the statistical family of programming languages based on This shows the number of doctors per facility, number of nurses and number of community health workers (CHEWS). We can plot the number of doctors against the number of nurses as follows. You may be curious what the arguments we give to We immediately note that some facilities have a lot of nurses, which prevent’s us seeing the detail of the main number of facilities. First lets identify the facilities with the most nurses. Here we are using the command We now see that the ‘University of Calabar Teaching Hospital’ is a large outlier with 513 nurses. We can try and determine how much of an outlier by histograming the data. We can’t see very much here. Two things are happening. There are so many facilities with zero or one nurse that we don’t see the histogram for hospitals with many nurses. We can try more bins and using a log scale on the \(y\)-axis. Let’s try and see how the number of nurses relates to the number of doctors. Let’s try and see how the number of nurses relates to the number of doctors. Note a few things. We are interacting with our data. In particular, we are replotting the data according to what we have learned so far. We are using the progamming language as a scripting language to give the computer one command or another, and then the next command we enter is dependent on the result of the previous. This is a very different paradigm to classical software engineering. In classical software engineering we normally write many lines of code (entire object classes or functions) before compiling the code and running it. Our approach is more similar to the approach we take whilst debugging. Historically, researchers interacted with data using a console. A command line window which allowed command entry. The notebook format we are using is slightly different. Each of the code entry boxes acts like a separate console window. We can move up and down the notebook and run each part in a different order. The state of the program is always as we left it after running the previous part. Let’s use the sum rule to compute the estimate the probability that a facility has more than two nurses. Note a few things. We are interacting with our data. In particular, we are replotting the data according to what we have learned so far. We are using the progamming language as a scripting language to give the computer one command or another, and then the next command we enter is dependent on the result of the previous. This is a very different paradigm to classical software engineering. In classical software engineering we normally write many lines of code (entire object classes or functions) before compiling the code and running it. Our approach is more similar to the approach we take whilst debugging. Historically, researchers interacted with data using a console. A command line window which allowed command entry. The notebook format we are using is slightly different. Each of the code entry boxes acts like a separate console window. We can move up and down the notebook and run each part in a different order. The state of the program is always as we left it after running the previous part. Let’s use the sum rule to compute the estimate the probability that a facility has more than two nurses. When predicting whether a coin turns up head or tails, we might think that this event is independent of the year or time of day. If we include an observation such as time, then in a probability this is known as condtioning. We use this notation, \(P(Y=y|X=x)\), to condition the outcome on a second variable (in this case the number of doctors). Or, often, for a shorthand we use \(P(y|x)\) to represent this distribution (the \(Y=\) and \(X=\) being implicit). If two variables are independent then we find that \[
+print("Probability of number of nurses being greather than 2 is:", prob_large) When predicting whether a coin turns up head or tails, we might think that this event is independent of the year or time of day. If we include an observation such as time, then in a probability this is known as condtioning. We use this notation, \(P(Y=y|X=x)\), to condition the outcome on a second variable (in this case the number of doctors). Or, often, for a shorthand we use \(P(y|x)\) to represent this distribution (the \(Y=\) and \(X=\) being implicit). If two variables are independent then we find that \[
P(y|x) = p(y).
-\] However, we might believe that the number of nurses is dependent on the number of doctors. For this we can try estimating \(P(Y>2 | X>1)\) and compare the result, for example to \(P(Y>2|X\leq 1)\) using our empirical estimate of the probability. Write code that prints out the probability of nurses being greater than 2 for different numbers of doctors. Make sure the plot is included in this notebook file (the Jupyter magic command Figure: Diagram representing the different probabilities, joint, marginal and conditional. This diagram was inspired by lectures given by Christopher Bishop. Typically we should write out \(P\left(X=x,Y=y\right)\), but in practice we often shorten this to \(P\left(x,y\right)\). This looks very much like we might write a multivariate function, e.g. \[
+print("Probability of number of nurses being greater than 2 given number of doctors is greater than 1 is:", prob_both_large) Write code that prints out the probability of nurses being greater than 2 for different numbers of doctors. Make sure the plot is included in this notebook file (the Jupyter magic command Figure: Diagram representing the different probabilities, joint, marginal and conditional. This diagram was inspired by lectures given by Christopher Bishop. Typically we should write out \(P\left(X=x,Y=y\right)\), but in practice we often shorten this to \(P\left(x,y\right)\). This looks very much like we might write a multivariate function, e.g. \[
f\left(x,y\right)=\frac{x}{y},
\] but for a multivariate function \[
f\left(x,y\right)\neq f\left(y,x\right).
@@ -71,15 +272,22 @@
P\left(x,y\right)=P\left(y,x\right)
\] because \[
P\left(X=x,Y=y\right)=P\left(Y=y,X=x\right).
-\] Sometimes I think of this as akin to the way in Python we can write ‘keyword arguments’ in functions. If we use keyword arguments, the ordering of arguments doesn’t matter. We’ve now introduced conditioning and independence to the notion of probability and computed some conditional probabilities on a practical example The scatter plot of deaths vs year that we created above can be seen as a joint probability distribution. We represent a joint probability using the notation \(P(Y=y, X=x)\) or \(P(y, x)\) for short. Computing a joint probability is equivalent to answering the simultaneous questions, what’s the probability that the number of nurses was over 2 and the number of doctors was 1? Or any other question that may occur to us. Again we can easily use pandas to ask such questions. We’ve now introduced conditioning and independence to the notion of probability and computed some conditional probabilities on a practical example The scatter plot of deaths vs year that we created above can be seen as a joint probability distribution. We represent a joint probability using the notation \(P(Y=y, X=x)\) or \(P(y, x)\) for short. Computing a joint probability is equivalent to answering the simultaneous questions, what’s the probability that the number of nurses was over 2 and the number of doctors was 1? Or any other question that may occur to us. Again we can easily use pandas to ask such questions. This number is the joint probability, \(P(Y, X)\) which is much smaller than the conditional probability. The number can never be bigger than the conditional probabililty because it is computed using the product rule. \[
+print("Probability of nurses being greater than 2 and number of doctors being", num_doctors, "is:", prob_large) This number is the joint probability, \(P(Y, X)\) which is much smaller than the conditional probability. The number can never be bigger than the conditional probabililty because it is computed using the product rule. \[
p(Y=y, X=x) = p(Y=y|X=x)p(X=x)
-\] and \[p(X=x)\] is a probability distribution, which is equal or less than 1, ensuring the joint distribution is typically smaller than the conditional distribution. The product rule is a fundamental rule of probability, and you must remember it! It gives the relationship between the two questions: 1) What’s the probability that a facility has over two nurses and one doctor? and 2) What’s the probability that a facility has over two nurses given that it has one doctor? In our shorter notation we can write the product rule as \[
+\] and \[p(X=x)\] is a probability distribution, which is equal or less than 1, ensuring the joint distribution is typically smaller than the conditional distribution. The product rule is a fundamental rule of probability, and you must remember it! It gives the relationship between the two questions: 1) What’s the probability that a facility has over two nurses and one doctor? and 2) What’s the probability that a facility has over two nurses given that it has one doctor? In our shorter notation we can write the product rule as \[
p(y, x) = p(y|x)p(x)
-\] We can see the relation working in practice for our data above by computing the different values for \(x=1\). The other fundamental rule of probability is the sum rule this tells us how to get a marginal distribution from the joint distribution. Simply put it says that we need to sum across the value we’d like to remove. \[
+print("P(y,x) is", p_y_and_x) The other fundamental rule of probability is the sum rule this tells us how to get a marginal distribution from the joint distribution. Simply put it says that we need to sum across the value we’d like to remove. \[
P(Y=y) = \sum_{x} P(Y=y, X=x)
\] Or in our shortened notation \[
P(y) = \sum_{x} P(y, x)
-\] Write code that computes \(P(y)\) by adding \(P(y, x)\) for all values of \(x\). Bayes’ rule is a very simple rule, it’s hardly worth the name of a rule at all. It follows directly from the product rule of probability. Because \(P(y, x) = P(y|x)P(x)\) and by symmetry \(P(y,x)=P(x,y)=P(x|y)P(y)\) then by equating these two equations and dividing through by \(P(y)\) we have \[
+\] Write code that computes \(P(y)\) by adding \(P(y, x)\) for all values of \(x\). Bayes’ rule is a very simple rule, it’s hardly worth the name of a rule at all. It follows directly from the product rule of probability. Because \(P(y, x) = P(y|x)P(x)\) and by symmetry \(P(y,x)=P(x,y)=P(x|y)P(y)\) then by equating these two equations and dividing through by \(P(y)\) we have \[
P(x|y) =
\frac{P(y|x)P(x)}{P(y)}
-\] which is known as Bayes’ rule (or Bayes’s rule, it depends how you choose to pronounce it). It’s not difficult to derive, and its importance is more to do with the semantic operation that it enables. Each of these probability distributions represents the answer to a question we have about the world. Bayes rule (via the product rule) tells us how to invert the probability. Figure: Two barrels: Barrel One holds 20 apples and 4 oranges; Barrel Two holds 4 apples and 8 oranges. A barrel is chosen uniformly at random and a single fruit is drawn. Work the numbers on the board if time allows. The same pattern applies to coins, medical tests, or any two-hypothesis discrete update. That last number is Shannon entropy in nats: \(H(p)=\mathbb{E}_{p}[-\log p(y)]=-\sum_y p(y)\log p(y)\). Same arithmetic under another name. What use is all this probability in data science? Let’s think about how we might use the probabilities to do some decision making. Let’s look at the information data. Now we see we have several additional features. Let’s assume we want to predict Using what you’ve learnt about joint, conditional and marginal probabilities, as well as the sum and product rule, how would you formulate the question you want to answer in terms of probabilities? Should you be using a joint or a conditional distribution? If it’s conditional, what should the distribution be over, and what should it be conditioned on? This Bayesian approach is designed to deal with uncertainty arising from fitting our prediction function to the data we have, a reduced data set. The Bayesian approach can be derived from a broader understanding of what our objective is. If we accept that we can jointly represent all things that happen in the world with a probability distribution, then we can interogate that probability to make predictions. So, if we are interested in predictions, \(y_*\) at future points input locations of interest, \(\mathbf{ x}_*\) given previously training data, \(\mathbf{ y}\) and corresponding inputs, \(\mathbf{X}\), then we are really interogating the following probability density, \[
+\] which is known as Bayes’ rule (or Bayes’s rule, it depends how you choose to pronounce it). It’s not difficult to derive, and its importance is more to do with the semantic operation that it enables. Each of these probability distributions represents the answer to a question we have about the world. Bayes rule (via the product rule) tells us how to invert the probability. Figure: Two barrels: Barrel One holds 20 apples and 4 oranges; Barrel Two holds 4 apples and 8 oranges. A barrel is chosen uniformly at random and a single fruit is drawn. Work the numbers on the board if time allows. The same pattern applies to coins, medical tests, or any two-hypothesis discrete update. That last number is Shannon entropy in nats: \(H(p)=\mathbb{E}_{p}[-\log p(y)]=-\sum_y p(y)\log p(y)\). Same arithmetic under another name. What use is all this probability in data science? Let’s think about how we might use the probabilities to do some decision making. Let’s look at the information data. Now we see we have several additional features. Let’s assume we want to predict Using what you’ve learnt about joint, conditional and marginal probabilities, as well as the sum and product rule, how would you formulate the question you want to answer in terms of probabilities? Should you be using a joint or a conditional distribution? If it’s conditional, what should the distribution be over, and what should it be conditioned on? This Bayesian approach is designed to deal with uncertainty arising from fitting our prediction function to the data we have, a reduced data set. The Bayesian approach can be derived from a broader understanding of what our objective is. If we accept that we can jointly represent all things that happen in the world with a probability distribution, then we can interogate that probability to make predictions. So, if we are interested in predictions, \(y_*\) at future points input locations of interest, \(\mathbf{ x}_*\) given previously training data, \(\mathbf{ y}\) and corresponding inputs, \(\mathbf{X}\), then we are really interogating the following probability density, \[
p(y_*|\mathbf{ y}, \mathbf{X}, \mathbf{ x}_*),
-\] there is nothing controversial here, as long as you accept that you have a good joint model of the world around you that relates test data to training data, \(p(y_*, \mathbf{ y}, \mathbf{X}, \mathbf{ x}_*)\) then this conditional distribution can be recovered through standard rules of probability (\(\text{data} + \text{model} \rightarrow \text{prediction}\)). We can construct this joint density through the use of the following decomposition: \[
+\] there is nothing controversial here, as long as you accept that you have a good joint model of the world around you that relates test data to training data, \(p(y_*, \mathbf{ y}, \mathbf{X}, \mathbf{ x}_*)\) then this conditional distribution can be recovered through standard rules of probability (\(\text{data} + \text{model} \rightarrow \text{prediction}\)). We can construct this joint density through the use of the following decomposition: \[
p(y_*|\mathbf{ y}, \mathbf{X}, \mathbf{ x}_*) = \int p(y_*|\mathbf{ x}_*, \mathbf{W}) p(\mathbf{W}| \mathbf{ y}, \mathbf{X}) \text{d} \mathbf{W}
-\] where, for convenience, we are assuming all the parameters of the model are now represented by \(\boldsymbol{ \theta}\) (which contains \(\mathbf{W}\) and \(\mathbf{V}\)) and \(p(\boldsymbol{ \theta}| \mathbf{ y}, \mathbf{X})\) is recognised as the posterior density of the parameters given data and \(p(y_*|\mathbf{ x}_*, \boldsymbol{ \theta})\) is the likelihood of an individual test data point given the parameters. The likelihood of the data is normally assumed to be independent across the parameters, \[
-p(\mathbf{ y}|\mathbf{X}, \mathbf{W}) = \prod_{i=1}^np(y_i|\mathbf{ x}_i, \mathbf{W}),\] and if that is so, it is easy to extend our predictions across all future, potential, locations, \[
+\] where, for convenience, we are assuming all the parameters of the model are now represented by \(\boldsymbol{ \theta}\) (which contains \(\mathbf{W}\) and \(\mathbf{V}\)) and \(p(\boldsymbol{ \theta}| \mathbf{ y}, \mathbf{X})\) is recognised as the posterior density of the parameters given data and \(p(y_*|\mathbf{ x}_*, \boldsymbol{ \theta})\) is the likelihood of an individual test data point given the parameters. The likelihood of the data is normally assumed to be independent across the parameters, \[
+p(\mathbf{ y}|\mathbf{X}, \mathbf{W}) = \prod_{i=1}^np(y_i|\mathbf{ x}_i, \mathbf{W}),\] and if that is so, it is easy to extend our predictions across all future, potential, locations, \[
p(\mathbf{ y}_*|\mathbf{ y}, \mathbf{X}, \mathbf{X}_*) = \int p(\mathbf{ y}_*|\mathbf{X}_*, \boldsymbol{ \theta}) p(\boldsymbol{ \theta}| \mathbf{ y}, \mathbf{X}) \text{d} \boldsymbol{ \theta}.
-\] The likelihood is also where the prediction function is incorporated. For example in the regression case, we consider an objective based around the Gaussian density, \[
+\] The likelihood is also where the prediction function is incorporated. For example in the regression case, we consider an objective based around the Gaussian density, \[
p(y_i | f(\mathbf{ x}_i)) = \frac{1}{\sqrt{2\pi \sigma^2}} \exp\left(-\frac{\left(y_i - f(\mathbf{ x}_i)\right)^2}{2\sigma^2}\right)
-\] In short, that is the classical approach to probabilistic inference, and all approaches to Bayesian neural networks fall within this path. For a deep probabilistic model, we can simply take this one stage further and place a probability distribution over the input locations, \[
+\] In short, that is the classical approach to probabilistic inference, and all approaches to Bayesian neural networks fall within this path. For a deep probabilistic model, we can simply take this one stage further and place a probability distribution over the input locations, \[
p(\mathbf{ y}_*|\mathbf{ y}) = \int p(\mathbf{ y}_*|\mathbf{X}_*, \boldsymbol{ \theta}) p(\boldsymbol{ \theta}| \mathbf{ y}, \mathbf{X}) p(\mathbf{X}) p(\mathbf{X}_*) \text{d} \boldsymbol{ \theta}\text{d} \mathbf{X}\text{d}\mathbf{X}_*
-\] and we have unsupervised learning (from where we can get deep generative models). One way of representing a joint distribution is to consider conditional dependencies between data. Conditional dependencies allow us to factorize the distribution. For example, a Markov chain is a factorization of a distribution into components that represent the conditional relationships between points that are neighboring, often in time or space. It can be decomposed in the following form. \[p(\mathbf{ y}) = p(y_n| y_{n-1}) p(y_{n-1}|y_{n-2}) \dots p(y_{2} | y_{1})\] Figure: A Markov chain is a simple form of probabilistic graphical model providing a particular decomposition of the joint density. By specifying conditional independencies we can reduce the parameterization required for our data, instead of directly specifying the parameters of the joint distribution, we can specify each set of parameters of the conditonal independently. This can also give an advantage in terms of interpretability. Understanding a conditional independence structure gives a structured understanding of data. If developed correctly, according to causal methodology, it can even inform how we should intervene in the system to drive a desired result (Pearl, 1995). However, a challenge arises when the data becomes more complex. Consider the graphical model shown below, used to predict the perioperative risk of C Difficile infection following colon surgery (Steele et al., 2012). Figure: A probabilistic directed graph used to predict the perioperative risk of C Difficile infection following colon surgery. When these models have good predictive performance they are often difficult to interpret. This may be due to the limited representation capability of the conditional densities in the model. To capture the complexity in the interelationship between the data, the graph itself becomes more complex, and less interpretable. Classification is perhaps the technique most closely assocated with machine learning. In the speech based agents, on-device classifiers are used to determine when the wake word is used. A wake word is a word that wakes up the device. For the Amazon Echo it is “Alexa,” for Siri it is “Hey Siri.” Once the wake word detected with a classifier, the speech can be uploaded to the cloud for full processing, the speech recognition stages. This isn’t just useful for intelligent agents, the UN global pulse project on public discussion on radio also uses wake word detection for recording radio conversations. A major breakthrough in image classification came in 2012 with the ImageNet result of Alex Krizhevsky, Ilya Sutskever and Geoff Hinton from the University of Toronto. ImageNet is a large data base of 14 million images with many thousands of classes. The data is used in a community-wide challenge for object categorization. Krizhevsky et al used convolutional neural networks to outperform all previous approaches on the challenge. They formed a company which was purchased shortly after by Google. This challenge, known as object categorisation, was a major obstacle for practical computer vision systems. Modern object categorization systems are close to human performance. Machine learning problems normally involve a prediction function and an objective function. Regression is the case where the prediction function iss over the real numbers, so the codomain of the functions, \(f(\mathbf{X})\) was the real numbers or sometimes real vectors. The classification problem consists of predicting whether or not a particular example is a member of a particular class. So we may want to know if a particular image represents a digit 6 or if a particular user will click on a given advert. These are classification problems, and they require us to map to yes or no answers. That makes them naturally discrete mappings. In classification we are given an input vector, \(\mathbf{ x}\), and an associated label, \(y\) which either takes the value \(-1\) to represent no or \(1\) to represent yes. In supervised learning the inputs, \(\mathbf{ x}\), are mapped to a label, \(y\), through a function \(f(\cdot)\) that is dependent on a set of parameters, \(\mathbf{ w}\), \[
+\] and we have unsupervised learning (from where we can get deep generative models). One way of representing a joint distribution is to consider conditional dependencies between data. Conditional dependencies allow us to factorize the distribution. For example, a Markov chain is a factorization of a distribution into components that represent the conditional relationships between points that are neighboring, often in time or space. It can be decomposed in the following form. \[p(\mathbf{ y}) = p(y_n| y_{n-1}) p(y_{n-1}|y_{n-2}) \dots p(y_{2} | y_{1})\] Figure: A Markov chain is a simple form of probabilistic graphical model providing a particular decomposition of the joint density. By specifying conditional independencies we can reduce the parameterization required for our data, instead of directly specifying the parameters of the joint distribution, we can specify each set of parameters of the conditonal independently. This can also give an advantage in terms of interpretability. Understanding a conditional independence structure gives a structured understanding of data. If developed correctly, according to causal methodology, it can even inform how we should intervene in the system to drive a desired result (Pearl, 1995). However, a challenge arises when the data becomes more complex. Consider the graphical model shown below, used to predict the perioperative risk of C Difficile infection following colon surgery (Steele et al., 2012). Figure: A probabilistic directed graph used to predict the perioperative risk of C Difficile infection following colon surgery. When these models have good predictive performance they are often difficult to interpret. This may be due to the limited representation capability of the conditional densities in the model. To capture the complexity in the interelationship between the data, the graph itself becomes more complex, and less interpretable. Classification is perhaps the technique most closely assocated with machine learning. In the speech based agents, on-device classifiers are used to determine when the wake word is used. A wake word is a word that wakes up the device. For the Amazon Echo it is “Alexa”, for Siri it is “Hey Siri”. Once the wake word detected with a classifier, the speech can be uploaded to the cloud for full processing, the speech recognition stages. This isn’t just useful for intelligent agents, the UN global pulse project on public discussion on radio also uses wake word detection for recording radio conversations. A major breakthrough in image classification came in 2012 with the ImageNet result of Alex Krizhevsky, Ilya Sutskever and Geoff Hinton from the University of Toronto. ImageNet is a large data base of 14 million images with many thousands of classes. The data is used in a community-wide challenge for object categorization. Krizhevsky et al used convolutional neural networks to outperform all previous approaches on the challenge. They formed a company which was purchased shortly after by Google. This challenge, known as object categorisation, was a major obstacle for practical computer vision systems. Modern object categorization systems are close to human performance. Machine learning problems normally involve a prediction function and an objective function. Regression is the case where the prediction function iss over the real numbers, so the codomain of the functions, \(f(\mathbf{X})\) was the real numbers or sometimes real vectors. The classification problem consists of predicting whether or not a particular example is a member of a particular class. So we may want to know if a particular image represents a digit 6 or if a particular user will click on a given advert. These are classification problems, and they require us to map to yes or no answers. That makes them naturally discrete mappings. In classification we are given an input vector, \(\mathbf{ x}\), and an associated label, \(y\) which either takes the value \(-1\) to represent no or \(1\) to represent yes. In supervised learning the inputs, \(\mathbf{ x}\), are mapped to a label, \(y\), through a function \(f(\cdot)\) that is dependent on a set of parameters, \(\mathbf{ w}\), \[
y= f(\mathbf{ x}; \mathbf{ w}).
-\] The function \(f(\cdot)\) is known as the prediction function. The key challenges are (1) choosing which features, \(\mathbf{ x}\), are relevant in the prediction, (2) defining the appropriate class of function, \(f(\cdot)\), to use and (3) selecting the right parameters, \(\mathbf{ w}\). There are many difference examples of classification problems. One of theoldest is the classification of hand written digits from binary images. The MNIST data was for a long time considered one of the most difficult data sets. When we download this data we are making use of open source code, through the scikit learn project, and the OpenML project which provides open access to data. This reflects a tradition of openness in machine learning that has enabled the tools to be deployed. We will look at a sub-sample of the MNIST digit data set. THE MNIST DATABASE of handwritten digits was created by Yann LeCun, Corinna Cortes and Christopher J. C. Burges. More details can be found at Yann’s site http://yann.lecun.com/exdb/mnist/ The data is a modified version of a data set from the US National Institute of Standards and Technology (NIST. First load in the MNIST data set from scikit learn. This can take a little while because it’s large to download. Sub-sample the dataset to make the training faster. There are many difference examples of classification problems. One of theoldest is the classification of hand written digits from binary images. The MNIST data was for a long time considered one of the most difficult data sets. When we download this data we are making use of open source code, through the scikit learn project, and the OpenML project which provides open access to data. This reflects a tradition of openness in machine learning that has enabled the tools to be deployed. We will look at a sub-sample of the MNIST digit data set. THE MNIST DATABASE of handwritten digits was created by Yann LeCun, Corinna Cortes and Christopher J. C. Burges. More details can be found at Yann’s site http://yann.lecun.com/exdb/mnist/ The data is a modified version of a data set from the US National Institute of Standards and Technology (NIST. First load in the MNIST data set from scikit learn. This can take a little while because it’s large to download. Sub-sample the dataset to make the training faster. Now let’s visualise some examples from our subsampled dataset to get a sense of what the data looks like. Figure: Examples of MNIST digits 0-4 from our subsampled dataset, showing 5 examples of each digit. The visualization shows the variety in handwritten digits even within the same class. Each row represents a different digit (0 through 4), and each column shows a different example of that digit. While the MNIST data doesn’t capture all the nuances of the challenges we face in modern machine learning. It has been an important benchmark data set for and can still be a useful data set for learning about classfication algorithms. Our focus has been on models where the objective function is inspired by a probabilistic analysis of the problem. In particular we’ve argued that we answer questions about the data set by placing probability distributions over the various quantities of interest. For the case of binary classification this will normally involve introducing probability distributions for discrete variables. Such probability distributions, are in some senses easier than those for continuous variables, in particular we can represent a probability distribution over \(y\), where \(y\) is binary, with one value. If we specify the probability that \(y=1\) with a number that is between 0 and 1, i.e. let’s say that \(P(y=1) = \pi\) (here we don’t mean \(\pi\) the number, we are setting \(\pi\) to be a variable) then we can specify the probability distribution through a table. Mathematically we can use a trick to implement this same table. We can use the value \(y\) as a mathematical switch and write that \[
+Y /= 255 Now let’s visualise some examples from our subsampled dataset to get a sense of what the data looks like. Figure: Examples of MNIST digits 0-4 from our subsampled dataset, showing 5 examples of each digit. The visualization shows the variety in handwritten digits even within the same class. Each row represents a different digit (0 through 4), and each column shows a different example of that digit. While the MNIST data doesn’t capture all the nuances of the challenges we face in modern machine learning. It has been an important benchmark data set for and can still be a useful data set for learning about classfication algorithms. Our focus has been on models where the objective function is inspired by a probabilistic analysis of the problem. In particular we’ve argued that we answer questions about the data set by placing probability distributions over the various quantities of interest. For the case of binary classification this will normally involve introducing probability distributions for discrete variables. Such probability distributions, are in some senses easier than those for continuous variables, in particular we can represent a probability distribution over \(y\), where \(y\) is binary, with one value. If we specify the probability that \(y=1\) with a number that is between 0 and 1, i.e. let’s say that \(P(y=1) = \pi\) (here we don’t mean \(\pi\) the number, we are setting \(\pi\) to be a variable) then we can specify the probability distribution through a table. Mathematically we can use a trick to implement this same table. We can use the value \(y\) as a mathematical switch and write that \[
P(y) = \pi^y(1-\pi)^{(1-y)}
- \] where our probability distribution is now written as a function of \(y\). This probability distribution is known as the Bernoulli distribution. The Bernoulli distribution is a clever trick for mathematically switching between two probabilities if we were to write it as code it would be better described as If we insert \(y=1\) then the function is equal to \(\pi\), and if we insert \(y=0\) then the function is equal to \(1-\pi\). So the function recreates the table for the distribution given above. The probability distribution is named for Jacob Bernoulli, the swiss mathematician. In his book Ars Conjectandi he considered the distribution and the result of a number of ‘trials’ under the Bernoulli distribution to form the binomial distribution. Below is the page where he considers Pascal’s triangle in forming combinations of the Bernoulli distribution to realise the binomial distribution for the outcome of positive trials. Figure: Jacob Bernoulli described the Bernoulli distribution through an urn in which there are black and red balls. Thomas Bayes also described the Bernoulli distribution, only he didn’t refer to Jacob Bernoulli’s work, so he didn’t call it by that name. He described the distribution in terms of a table (think of a billiard table) and two balls. Bayes suggests that each ball can be rolled across the table such that it comes to rest at a position that is uniformly distributed between the sides of the table. Let’s assume that the first ball is rolled, and that it comes to reset at a position that is \(\pi\) times the width of the table from the left hand side. Now, we roll the second ball. We are interested if the second ball ends up on the left side (+ve result) or the right side (-ve result) of the first ball. We use the Bernoulli distribution to determine this. For this reason in Bayes’s distribution there is considered to be aleatoric uncertainty about the distribution parameter. Figure: Thomas Bayes described the Bernoulli distribution independently of Jacob Bernoulli. He used the analogy of a billiard table. Any ball on the table is given a uniformly random position between the left and right side of the table. The first ball (in the figure) gives the parameter of the Bernoulli distribution. The second ball (in the figure) gives the outcome as either left or right (relative to the first ball). This is the origin of the term Bayesian because the parameter of the distribution is drawn from a probsbility. Maximum likelihood in the Bernoulli distribution is straightforward. Let’s assume we have data, \(\mathbf{ y}\) which consists of a vector of binary values of length \(n\). If we assume each value was sampled independently from the Bernoulli distribution, conditioned on the parameter \(\pi\) then our joint probability density has the form \[
+ return 1-pi If we insert \(y=1\) then the function is equal to \(\pi\), and if we insert \(y=0\) then the function is equal to \(1-\pi\). So the function recreates the table for the distribution given above. The probability distribution is named for Jacob Bernoulli, the swiss mathematician. In his book Ars Conjectandi he considered the distribution and the result of a number of ‘trials’ under the Bernoulli distribution to form the binomial distribution. Below is the page where he considers Pascal’s triangle in forming combinations of the Bernoulli distribution to realise the binomial distribution for the outcome of positive trials. Figure: Jacob Bernoulli described the Bernoulli distribution through an urn in which there are black and red balls. Thomas Bayes also described the Bernoulli distribution, only he didn’t refer to Jacob Bernoulli’s work, so he didn’t call it by that name. He described the distribution in terms of a table (think of a billiard table) and two balls. Bayes suggests that each ball can be rolled across the table such that it comes to rest at a position that is uniformly distributed between the sides of the table. Let’s assume that the first ball is rolled, and that it comes to reset at a position that is \(\pi\) times the width of the table from the left hand side. Now, we roll the second ball. We are interested if the second ball ends up on the left side (+ve result) or the right side (-ve result) of the first ball. We use the Bernoulli distribution to determine this. For this reason in Bayes’s distribution there is considered to be aleatoric uncertainty about the distribution parameter. Figure: Thomas Bayes described the Bernoulli distribution independently of Jacob Bernoulli. He used the analogy of a billiard table. Any ball on the table is given a uniformly random position between the left and right side of the table. The first ball (in the figure) gives the parameter of the Bernoulli distribution. The second ball (in the figure) gives the outcome as either left or right (relative to the first ball). This is the origin of the term Bayesian because the parameter of the distribution is drawn from a probsbility. Maximum likelihood in the Bernoulli distribution is straightforward. Let’s assume we have data, \(\mathbf{ y}\) which consists of a vector of binary values of length \(n\). If we assume each value was sampled independently from the Bernoulli distribution, conditioned on the parameter \(\pi\) then our joint probability density has the form \[
p(\mathbf{ y}|\pi) = \prod_{i=1}^{n} \pi^{y_i} (1-\pi)^{1-y_i}.
\] As normal in maximum likelihood we consider the negative log likelihood as our objective, \[\begin{align*}
- E(\pi)& = -\log p(\mathbf{ y}|\pi)\\
+ E(\pi)& = -\log p(\mathbf{ y}|\pi)\\
& = -\sum_{i=1}^{n} y_i \log \pi - \sum_{i=1}^{n} (1-y_i) \log(1-\pi),
- \end{align*}\] and we can derive the gradient with respect to the parameter \(\pi\). \[\frac{\text{d}E(\pi)}{\text{d}\pi} = -\frac{\sum_{i=1}^{n} y_i}{\pi} + \frac{\sum_{i=1}^{n} (1-y_i)}{1-\pi},\] and as normal we look for a stationary point for the log likelihood by setting this derivative to zero, \[0 = -\frac{\sum_{i=1}^{n} y_i}{\pi} + \frac{\sum_{i=1}^{n} (1-y_i)}{1-\pi},\] rearranging we form \[(1-\pi)\sum_{i=1}^{n} y_i = \pi\sum_{i=1}^{n} (1-y_i),\] which implies \[\sum_{i=1}^{n} y_i = \pi\left(\sum_{i=1}^{n} (1-y_i) + \sum_{i=1}^{n} y_i\right),\] and now we recognise that \(\sum_{i=1}^{n} (1-y_i) + \sum_{i=1}^{n} y_i = n\) so we have \[\pi = \frac{\sum_{i=1}^{n} y_i}{n}\] so in other words we estimate the probability associated with the Bernoulli by setting it to the number of observed positives, divided by the total length of \(y\). This makes intiutive sense. If I asked you to estimate the probability of a coin being heads, and you tossed the coin 100 times, and recovered 47 heads, then the estimate of the probability of heads should be \(\frac{47}{100}\). Show that the maximum likelihood solution we have found is a minimum for our objective. \[
+ \end{align*}\] and we can derive the gradient with respect to the parameter \(\pi\). \[\frac{\text{d}E(\pi)}{\text{d}\pi} = -\frac{\sum_{i=1}^{n} y_i}{\pi} + \frac{\sum_{i=1}^{n} (1-y_i)}{1-\pi},\] and as normal we look for a stationary point for the log likelihood by setting this derivative to zero, \[0 = -\frac{\sum_{i=1}^{n} y_i}{\pi} + \frac{\sum_{i=1}^{n} (1-y_i)}{1-\pi},\] rearranging we form \[(1-\pi)\sum_{i=1}^{n} y_i = \pi\sum_{i=1}^{n} (1-y_i),\] which implies \[\sum_{i=1}^{n} y_i = \pi\left(\sum_{i=1}^{n} (1-y_i) + \sum_{i=1}^{n} y_i\right),\] and now we recognise that \(\sum_{i=1}^{n} (1-y_i) + \sum_{i=1}^{n} y_i = n\) so we have \[\pi = \frac{\sum_{i=1}^{n} y_i}{n}\] so in other words we estimate the probability associated with the Bernoulli by setting it to the number of observed positives, divided by the total length of \(y\). This makes intiutive sense. If I asked you to estimate the probability of a coin being heads, and you tossed the coin 100 times, and recovered 47 heads, then the estimate of the probability of heads should be \(\frac{47}{100}\). Show that the maximum likelihood solution we have found is a minimum for our objective. \[
\text{posterior} =
\frac{\text{likelihood}\times\text{prior}}{\text{marginal likelihood}}
-\] Four components: Note: Everything we do below is possible using standard packages like In probabilistic machine learning we place probability distributions (or densities) over all the variables of interest, our first classification algorithm will do just that. We will consider how to form a classification by making assumptions about the joint density of our observations. We need to make assumptions to reduce the number of parameters we need to optimise. In the ideal world, given label data \(\mathbf{ y}\) and the inputs \(\mathbf{X}\) we should be able to specify the joint density of all potential values of \(\mathbf{ y}\) and \(\mathbf{X}\), \(p(\mathbf{ y}, \mathbf{X})\). If \(\mathbf{X}\) and \(\mathbf{ y}\) are our training data, and we can somehow extend our density to incorporate future test data (by augmenting \(\mathbf{ y}\) with a new observation \(y^*\) and \(\mathbf{X}\) with the corresponding inputs, \(\mathbf{ x}^*\)), then we can answer any given question about a future test point \(y^*\) given its covariates \(\mathbf{ x}^*\) by conditioning on the training variables to recover, \[
+\] Four components: Note: Everything we do below is possible using standard packages like In probabilistic machine learning we place probability distributions (or densities) over all the variables of interest, our first classification algorithm will do just that. We will consider how to form a classification by making assumptions about the joint density of our observations. We need to make assumptions to reduce the number of parameters we need to optimise. In the ideal world, given label data \(\mathbf{ y}\) and the inputs \(\mathbf{X}\) we should be able to specify the joint density of all potential values of \(\mathbf{ y}\) and \(\mathbf{X}\), \(p(\mathbf{ y}, \mathbf{X})\). If \(\mathbf{X}\) and \(\mathbf{ y}\) are our training data, and we can somehow extend our density to incorporate future test data (by augmenting \(\mathbf{ y}\) with a new observation \(y^*\) and \(\mathbf{X}\) with the corresponding inputs, \(\mathbf{ x}^*\)), then we can answer any given question about a future test point \(y^*\) given its covariates \(\mathbf{ x}^*\) by conditioning on the training variables to recover, \[
p(y^*|\mathbf{X}, \mathbf{ y}, \mathbf{ x}^*),
-\] We can compute this distribution using the product and sum rules. However, to specify this density we must give the probability associated with all possible combinations of \(\mathbf{ y}\) and \(\mathbf{X}\). There are \(2^{n}\) possible combinations for the vector \(\mathbf{ y}\) and the probability for each of these combinations must be jointly specified along with the joint density of the matrix \(\mathbf{X}\), as well as being able to extend the density for any chosen test location \(\mathbf{ x}^*\). In naive Bayes we make certain simplifying assumptions that allow us to perform all of the above in practice. If we are given model parameters \(\boldsymbol{ \theta}\) we assume that conditioned on all these parameters that all data points in the model are independent. In other words we have, \[
+\] We can compute this distribution using the product and sum rules. However, to specify this density we must give the probability associated with all possible combinations of \(\mathbf{ y}\) and \(\mathbf{X}\). There are \(2^{n}\) possible combinations for the vector \(\mathbf{ y}\) and the probability for each of these combinations must be jointly specified along with the joint density of the matrix \(\mathbf{X}\), as well as being able to extend the density for any chosen test location \(\mathbf{ x}^*\). In naive Bayes we make certain simplifying assumptions that allow us to perform all of the above in practice. If we are given model parameters \(\boldsymbol{ \theta}\) we assume that conditioned on all these parameters that all data points in the model are independent. In other words we have, \[
p(y^*, \mathbf{ x}^*, \mathbf{ y}, \mathbf{X}|\boldsymbol{ \theta}) = p(y^*, \mathbf{ x}^*|\boldsymbol{ \theta})\prod_{i=1}^{n} p(y_i, \mathbf{ x}_i | \boldsymbol{ \theta}).
- \] This is a conditional independence assumption because we are not assuming our data are purely independent. If we were to assume that, then there would be nothing to learn about our test data given our training data. We are assuming that they are independent given our parameters, \(\boldsymbol{ \theta}\). We made similar assumptions for regression, where our parameter set included \(\mathbf{ w}\) and \(\sigma^2\). Given those parameters we assumed that the density over \(\mathbf{ y}, y^*\) was independent. Here we are going a little further with that assumption because we are assuming the joint density of \(\mathbf{ y}\) and \(\mathbf{X}\) is independent across the data given the parameters. Computing posterior distribution in this case becomes easier, this is known as the ‘Bayes classifier.’ \[
+ \] This is a conditional independence assumption because we are not assuming our data are purely independent. If we were to assume that, then there would be nothing to learn about our test data given our training data. We are assuming that they are independent given our parameters, \(\boldsymbol{ \theta}\). We made similar assumptions for regression, where our parameter set included \(\mathbf{ w}\) and \(\sigma^2\). Given those parameters we assumed that the density over \(\mathbf{ y}, y^*\) was independent. Here we are going a little further with that assumption because we are assuming the joint density of \(\mathbf{ y}\) and \(\mathbf{X}\) is independent across the data given the parameters. Computing posterior distribution in this case becomes easier, this is known as the ‘Bayes classifier’. \[
p(\mathbf{ x}_i | y_i, \boldsymbol{ \theta}) = \prod_{j=1}^{d} p(x_{i,j}|y_i, \boldsymbol{ \theta})
-\] where \(d\) is the dimensionality of our inputs. The assumption that is particular to naive Bayes is to now consider that the features are also conditionally independent, but not only given the parameters. We assume that the features are independent given the parameters and the label. So for each data point we have \[p(\mathbf{ x}_i | y_i, \boldsymbol{ \theta}) = \prod_{j=1}^{d} p(x_{i,j}|y_i,\boldsymbol{ \theta})\] where \(d\) is the dimensionality of our inputs. \[
+\] where \(d\) is the dimensionality of our inputs. The assumption that is particular to naive Bayes is to now consider that the features are also conditionally independent, but not only given the parameters. We assume that the features are independent given the parameters and the label. So for each data point we have \[p(\mathbf{ x}_i | y_i, \boldsymbol{ \theta}) = \prod_{j=1}^{d} p(x_{i,j}|y_i,\boldsymbol{ \theta})\] where \(d\) is the dimensionality of our inputs. \[
p(x_{i,j},y_i| \boldsymbol{ \theta}) = p(x_{i,j}|y_i, \boldsymbol{ \theta})p(y_i).
-\] We now have nearly all of the components we need to specify the full joint density. However, the feature conditional independence doesn’t yet give us the joint density over \(p(y_i, \mathbf{ x}_i)\) which is required to subsitute in to our data conditional independence to give us the full density. To recover the joint density given the conditional distribution of each feature, \(p(x_{i,j}|y_i, \boldsymbol{ \theta})\), we need to make use of the product rule and combine it with a marginal density for \(y_i\), \[p(x_{i,j},y_i| \boldsymbol{ \theta}) = p(x_{i,j}|y_i, \boldsymbol{ \theta})p(y_i).\] Because \(y_i\) is binary the Bernoulli density makes a suitable choice for our prior over \(y_i\), \[p(y_i|\pi) = \pi^{y_i} (1-\pi)^{1-y_i}\] where \(\pi\) now has the interpretation as being the prior probability that the classification should be positive. This allows us to write down the full joint density of the training data, \[
+\] We now have nearly all of the components we need to specify the full joint density. However, the feature conditional independence doesn’t yet give us the joint density over \(p(y_i, \mathbf{ x}_i)\) which is required to subsitute in to our data conditional independence to give us the full density. To recover the joint density given the conditional distribution of each feature, \(p(x_{i,j}|y_i, \boldsymbol{ \theta})\), we need to make use of the product rule and combine it with a marginal density for \(y_i\), \[p(x_{i,j},y_i| \boldsymbol{ \theta}) = p(x_{i,j}|y_i, \boldsymbol{ \theta})p(y_i).\] Because \(y_i\) is binary the Bernoulli density makes a suitable choice for our prior over \(y_i\), \[p(y_i|\pi) = \pi^{y_i} (1-\pi)^{1-y_i}\] where \(\pi\) now has the interpretation as being the prior probability that the classification should be positive. This allows us to write down the full joint density of the training data, \[
p(\mathbf{ y}, \mathbf{X}|\boldsymbol{ \theta}, \pi) = \prod_{i=1}^{n} \prod_{j=1}^{d} p(x_{i,j}|y_i, \boldsymbol{ \theta})p(y_i|\pi)
- \] which can now be fit by maximum likelihood. As normal we form our objective as the negative log likelihood, \[\begin{align*}
+ \] which can now be fit by maximum likelihood. As normal we form our objective as the negative log likelihood, \[\begin{align*}
E(\boldsymbol{ \theta}, \pi)& = -\log p(\mathbf{ y}, \mathbf{X}|\boldsymbol{ \theta}, \pi) \\ &= -\sum_{i=1}^{n} \sum_{j=1}^{d} \log p(x_{i, j}|y_i, \boldsymbol{ \theta}) - \sum_{i=1}^{n} \log p(y_i|\pi),
\end{align*}\] which we note decomposes into two objective functions, one which is dependent on \(\pi\) alone and one which is dependent on \(\boldsymbol{ \theta}\) alone so we have, \[
E(\pi, \boldsymbol{ \theta}) = E(\boldsymbol{ \theta}) + E(\pi).
@@ -152,16 +603,28 @@
E(\pi) = -\sum_{i=1}^{n}\log p(y_i|\pi) = -\sum_{i=1}^{n} y_i \log \pi - \sum_{i=1}^{n} (1-y_i) \log (1-\pi)
\] which we already minimized above recovering \[
\pi = \frac{\sum_{i=1}^{n} y_i}{n}.
-\] We now need to minimize the objective associated with the conditional distributions for the features, \[
+\] We now need to minimize the objective associated with the conditional distributions for the features, \[
E(\boldsymbol{ \theta}) = -\sum_{i=1}^{n} \sum_{j=1}^{d} \log p(x_{i, j} |y_i, \boldsymbol{ \theta}),
\] which necessarily implies making some assumptions about the form of the conditional distributions. The right assumption will depend on the nature of our input data. For example, if we have an input which is real valued, we could use a Gaussian density and we could allow the mean and variance of the Gaussian to be different according to whether the class was positive or negative and according to which feature we were measuring. That would give us the form, \[
p(x_{i, j} | y_i,\boldsymbol{ \theta}) = \frac{1}{\sqrt{2\pi \sigma_{y_i,j}^2}} \exp \left(-\frac{(x_{i,j} - \mu_{y_i, j})^2}{\sigma_{y_i,j}^2}\right),
-\] where \(\sigma_{1, j}^2\) is the variance of the density for the \(j\)th output and the class \(y_i=1\) and \(\sigma_{0, j}^2\) is the variance if the class is 0. The means can vary similarly. Our parameters, \(\boldsymbol{ \theta}\) would consist of all the means and all the variances for the different dimensions. As normal we form our objective as the negative log likelihood, \[
+\] where \(\sigma_{1, j}^2\) is the variance of the density for the \(j\)th output and the class \(y_i=1\) and \(\sigma_{0, j}^2\) is the variance if the class is 0. The means can vary similarly. Our parameters, \(\boldsymbol{ \theta}\) would consist of all the means and all the variances for the different dimensions. As normal we form our objective as the negative log likelihood, \[
E(\boldsymbol{ \theta}, \pi) = -\log p(\mathbf{ y}, \mathbf{X}|\boldsymbol{ \theta}, \pi) = -\sum_{i=1}^{n} \sum_{j=1}^{d} \log p(x_{i, j}|y_i, \boldsymbol{ \theta}) - \sum_{i=1}^{n} \log p(y_i|\pi),
\] which we note decomposes into two objective functions, one which is dependent on \(\pi\) alone and one which is dependent on \(\boldsymbol{ \theta}\) alone so we have, \[
E(\pi, \boldsymbol{ \theta}) = E(\boldsymbol{ \theta}) + E(\pi).
-\] Our aim will be to predict whether a center has maternal health delivery services given the attributes in the data. We will predict of the number of nurses, the number of doctors, location etc. Now we will convert this data into a form which we can use as inputs Our aim will be to predict whether a center has maternal health delivery services given the attributes in the data. We will predict of the number of nurses, the number of doctors, location etc. Now we will convert this data into a form which we can use as inputs This has given us a new data frame We can now specify the naive Bayes model. For the genres we want to model the data as Bernoulli distributed, and for the year and body count we want to model the data as Gaussian distributed. We set up two data frames to contain the parameters for the rows and the columns below. This has given us a new data frame We can now specify the naive Bayes model. For the genres we want to model the data as Bernoulli distributed, and for the year and body count we want to model the data as Gaussian distributed. We set up two data frames to contain the parameters for the rows and the columns below. Now we have the data in a form ready for analysis, let’s construct our data matrix. Now we have the data in a form ready for analysis, let’s construct our data matrix. And we can now train the model. For each feature we can make the fit independently. The fit is given by either counting the number of positives (for binary data) which gives us the maximum likelihood solution for the Bernoulli. Or by computing the empirical mean and variance of the data for the Gaussian, which also gives us the maximum likelihood solution. And we can now train the model. For each feature we can make the fit independently. The fit is given by either counting the number of positives (for binary data) which gives us the maximum likelihood solution for the Bernoulli. Or by computing the empirical mean and variance of the data for the Gaussian, which also gives us the maximum likelihood solution. We can examine the nature of the distributions we’ve fitted to the model by looking at the entries in these data frames. The distributions show the parameters of the independent class conditional probabilities for no maternity services. It is a Bernoulli distribution with the parameter, \(\pi\), given by ( The naive Bayes assumption says that the joint probability for these services is given by the product of each of these Bernoulli distributions. We have modelled the numbers in our table with a Gaussian density. Since several of these numbers are counts, a more appropriate distribution might be the Poisson distribution. But here we can see that the average number of nurses, healthworkers and doctors is higher in the facilities with maternal services ( The final model parameter is the prior probability of the positive class, \(\pi\), which is computed by maximum likelihood. The prior probability tells us that slightly more facilities have maternity services than those that don’t. Naive Bayes has given us the class conditional densities: \(p(\mathbf{ x}_i | y_i, \boldsymbol{ \theta})\). To make predictions with these densities we need to form the distribution given by \[
+ Bernoulli[column]['theta_1'] = X_train[column][y_train].sum()/(y_train).sum() We can examine the nature of the distributions we’ve fitted to the model by looking at the entries in these data frames. The distributions show the parameters of the independent class conditional probabilities for no maternity services. It is a Bernoulli distribution with the parameter, \(\pi\), given by ( The naive Bayes assumption says that the joint probability for these services is given by the product of each of these Bernoulli distributions. We have modelled the numbers in our table with a Gaussian density. Since several of these numbers are counts, a more appropriate distribution might be the Poisson distribution. But here we can see that the average number of nurses, healthworkers and doctors is higher in the facilities with maternal services ( The final model parameter is the prior probability of the positive class, \(\pi\), which is computed by maximum likelihood. The prior probability tells us that slightly more facilities have maternity services than those that don’t. Naive Bayes has given us the class conditional densities: \(p(\mathbf{ x}_i | y_i, \boldsymbol{ \theta})\). To make predictions with these densities we need to form the distribution given by \[
P(y^*| \mathbf{ y}, \mathbf{X}, \mathbf{ x}^*, \boldsymbol{ \theta})
\] This can be computed by using the product rule. We know that \[
P(y^*| \mathbf{ y}, \mathbf{X}, \mathbf{ x}^*, \boldsymbol{ \theta})p(\mathbf{ y}, \mathbf{X}, \mathbf{ x}^*|\boldsymbol{ \theta}) = p(y*, \mathbf{ y}, \mathbf{X}, \mathbf{ x}^*| \boldsymbol{ \theta})
@@ -241,20 +727,32 @@
\] and we notice that all the terms associated with the training data actually cancel, the test prediction is conditionally independent of the training data given the parameters. This is a result of our conditional independence assumptions over the data points. \[
p(y^*| \mathbf{ x}^*, \boldsymbol{ \theta}) = \frac{\prod_{j=1}^{d} p(x^*_{j}|y^*_i,
\boldsymbol{ \theta})p(y^*|\pi)}{\sum_{y^*=0}^1 \prod_{j=1}^{d} p(x^*_{j}|y^*_i, \boldsymbol{ \theta})p(y^*|\pi)}
-\] This formula is also fairly straightforward to implement. First we implement the log probabilities for the Gaussian density. Now for any test point we compute the joint distribution of the Gaussian features by summing their log probabilities. Working in log space can be a considerable advantage over computing the probabilities directly: as the number of features we include goes up, because all the probabilities are less than 1, the joint probability will become smaller and smaller, and may be difficult to represent accurately (or even underflow). Working in log space can ameliorate this problem. We can also compute the log probability for the Bernoulli distribution. Before we proceed, let’s just pause and think for a moment what will happen if Laplace suggests that when computing the probability of an event where a success or failure is rare (he uses an example of the sun rising across the last 5,000 years or 1,826,213 days) that even though only successes have been observed (in the sun rising case) that the odds for tomorrow shouldn’t be given as \[
+\] This formula is also fairly straightforward to implement. First we implement the log probabilities for the Gaussian density. Now for any test point we compute the joint distribution of the Gaussian features by summing their log probabilities. Working in log space can be a considerable advantage over computing the probabilities directly: as the number of features we include goes up, because all the probabilities are less than 1, the joint probability will become smaller and smaller, and may be difficult to represent accurately (or even underflow). Working in log space can ameliorate this problem. We can also compute the log probability for the Bernoulli distribution. Before we proceed, let’s just pause and think for a moment what will happen if Laplace suggests that when computing the probability of an event where a success or failure is rare (he uses an example of the sun rising across the last 5,000 years or 1,826,213 days) that even though only successes have been observed (in the sun rising case) that the odds for tomorrow shouldn’t be given as \[
\frac{1,826,213}{1,826,213} = 1
\] but rather by adding one to the numerator and two to the denominator, \[
\frac{1,826,213 + 1}{1,826,213 + 2} = 0.99999945.
-\] This technique is sometimes called a ‘pseudocount technique’ because it has an intepretation of assuming some observations before you start, it’s as if instead of observing \(\sum_{i}y_i\) successes you have an additional success, \(\sum_{i}y_i + 1\) and instead of having observed \(n\) events you’ve observed \(n+ 2\). So we can think of Laplace’s idea saying (before we start) that we have ‘two observations worth of belief, that the odds are 50/50,’ because before we start (i.e. when \(n=0\)) our estimate is 0.5, yet because the effective \(n\) is only 2, this estimate is quickly overwhelmed by data. Laplace used ideas like this a lot, and it is known as his ‘principle of insufficient reason.’ His idea was that in the absence of knowledge (i.e. before we start) we should assume that all possible outcomes are equally likely. This idea has a modern counterpart, known as the principle of maximum entropy. A lot of the theory of this approach was developed by Ed Jaynes, who according to his erstwhile collaborator and friend, John Skilling, learnt French as an undergraduate by reading the works of Laplace. Although John also related that Jaynes’s spoken French was not up to the standard of his scientific French. For me Ed Jaynes’s work very much carries on the tradition of Laplace into the modern era, in particular his focus on Bayesian approaches. I’m very proud to have met those that knew and worked with him. It turns out that Laplace’s idea also has a Bayesian interpretation (as Laplace understood), it comes from assuming a particular prior density for the parameter \(\pi\), but we won’t explore that interpretation for the moment, and merely choose to estimate the probability as, \[
+\] This technique is sometimes called a ‘pseudocount technique’ because it has an intepretation of assuming some observations before you start, it’s as if instead of observing \(\sum_{i}y_i\) successes you have an additional success, \(\sum_{i}y_i + 1\) and instead of having observed \(n\) events you’ve observed \(n+ 2\). So we can think of Laplace’s idea saying (before we start) that we have ‘two observations worth of belief, that the odds are 50/50’, because before we start (i.e. when \(n=0\)) our estimate is 0.5, yet because the effective \(n\) is only 2, this estimate is quickly overwhelmed by data. Laplace used ideas like this a lot, and it is known as his ‘principle of insufficient reason’. His idea was that in the absence of knowledge (i.e. before we start) we should assume that all possible outcomes are equally likely. This idea has a modern counterpart, known as the principle of maximum entropy. A lot of the theory of this approach was developed by Ed Jaynes, who according to his erstwhile collaborator and friend, John Skilling, learnt French as an undergraduate by reading the works of Laplace. Although John also related that Jaynes’s spoken French was not up to the standard of his scientific French. For me Ed Jaynes’s work very much carries on the tradition of Laplace into the modern era, in particular his focus on Bayesian approaches. I’m very proud to have met those that knew and worked with him. It turns out that Laplace’s idea also has a Bayesian interpretation (as Laplace understood), it comes from assuming a particular prior density for the parameter \(\pi\), but we won’t explore that interpretation for the moment, and merely choose to estimate the probability as, \[
\pi = \frac{\sum_{i=1}^{n} y_i + 1}{n+ 2}
-\] to prevent problems with certainty causing numerical issues and misclassifications. Let’s refit the Bernoulli features now. That places us in a position to write the prediction function. That places us in a position to write the prediction function. Now we are in a position to make the predictions for the test data. We can test the quality of the predictions in the following way. Firstly, we can threshold our probabilities at 0.5, allocating points with greater than 50% probability of membership of the positive class to the positive class. We can then compare to the true values, and see how many of these values we got correct. This is our total number correct. Now we are in a position to make the predictions for the test data. We can test the quality of the predictions in the following way. Firstly, we can threshold our probabilities at 0.5, allocating points with greater than 50% probability of membership of the positive class to the positive class. We can then compare to the true values, and see how many of these values we got correct. This is our total number correct. We can also now plot the confusion matrix. A confusion matrix tells us where we are making mistakes. Along the diagonal it stores the true positives, the points that were positive class that we classified correctly, and the true negatives, the points that were negative class and that we classified correctly. The off diagonal terms contain the false positives and the false negatives. Along the rows of the matrix we place the actual class, and along the columns we place our predicted class. We can also now plot the confusion matrix. A confusion matrix tells us where we are making mistakes. Along the diagonal it stores the true positives, the points that were positive class that we classified correctly, and the true negatives, the points that were negative class and that we classified correctly. The off diagonal terms contain the false positives and the false negatives. Along the rows of the matrix we place the actual class, and along the columns we place our predicted class. How can you improve your classification, are all the features equally valid? Are some features more helpful than others? What happens if you remove features that appear to be less helpful. How might you select such features? We have decided to classify positive if probability of maternity is greater than 0.5. This has led us to accidentally classify some facilities as havien’t facilities for maternity when in fact they don’t. Imagine you wish to ensure that a facility handles maternity. With your test set how low do you have to set the threshold to avoid all the false negatives (i.e. facilities where you predicted there was no maternity, but in actuality there were? Naive Bayes has given us the class conditional densities: \(p(\mathbf{ x}_i | y_i, \boldsymbol{ \theta})\). To make predictions with these densities we need to form the distribution given by \[
+confusion_matrix How can you improve your classification, are all the features equally valid? Are some features more helpful than others? What happens if you remove features that appear to be less helpful. How might you select such features? We have decided to classify positive if probability of maternity is greater than 0.5. This has led us to accidentally classify some facilities as havien’t facilities for maternity when in fact they don’t. Imagine you wish to ensure that a facility handles maternity. With your test set how low do you have to set the threshold to avoid all the false negatives (i.e. facilities where you predicted there was no maternity, but in actuality there were? Naive Bayes has given us the class conditional densities: \(p(\mathbf{ x}_i | y_i, \boldsymbol{ \theta})\). To make predictions with these densities we need to form the distribution given by \[
P(y^*| \mathbf{ y}, \mathbf{X}, \mathbf{ x}^*, \boldsymbol{ \theta})
-\] Write down the negative log likelihood of the Gaussian density over a vector of variables \(\mathbf{ x}\). Assume independence between each variable. Minimize this objective to obtain the maximum likelihood solution of the form. \[
+\] Write down the negative log likelihood of the Gaussian density over a vector of variables \(\mathbf{ x}\). Assume independence between each variable. Minimize this objective to obtain the maximum likelihood solution of the form. \[
\mu = \frac{\sum_{i=1}^{n} x_i}{n}
\] \[
\sigma^2 = \frac{\sum_{i=1}^{n} (x_i - \mu)^2}{n}
-\] If the input data was binary then we could also make use of the Bernoulli distribution for the features. For that case we would have the form, \[
+\] If the input data was binary then we could also make use of the Bernoulli distribution for the features. For that case we would have the form, \[
p(x_{i, j} | y_i,\boldsymbol{ \theta}) = \theta_{y_i, j}^{x_{i, j}}(1-\theta_{y_i, j})^{(1-x_{i,j})},
-\] where \(\theta_{1, j}\) is the probability that the \(j\)th feature is on if \(y_i\) is 1. In either case, maximum likelihood fitting would proceed in the same way. The objective has the form, \[
+\] where \(\theta_{1, j}\) is the probability that the \(j\)th feature is on if \(y_i\) is 1. In either case, maximum likelihood fitting would proceed in the same way. The objective has the form, \[
E(\boldsymbol{ \theta}) = -\sum_{j=1}^{d} \sum_{i=1}^{n} \log p(x_{i,j} |y_i, \boldsymbol{ \theta}),
\] and if, as above, the parameters of the distributions are specific to each feature vector (we had means and variances for each continuous feature, and a probability for each binary feature) then we can use the fact that these parameters separate into disjoint subsets across the features to write, \[
\begin{align*}
@@ -296,5 +810,30 @@
& \sum_{j=1}^{d}
E(\boldsymbol{ \theta}_j),
\end{align*}
-\] which means we can minimize our objective on each feature independently. These characteristics mean that naive Bayes scales very well with big data. To fit the model we consider each feature in turn, we select the positive class and fit parameters for that class, then we select each negative class and fit features for that class. We have code below. Naive Bayes is making very simple assumptions about the data, in particular it is modeling the full joint probability of the data set, \(p(\mathbf{ y}, \mathbf{X}| \boldsymbol{ \theta}, \pi)\) by very strong assumptions about factorizations that are unlikely to be true in practice. The data conditional independence assumption is common, and relies on a rich parameter vector to absorb all the information in the training data. The additional assumption of naive Bayes is that features are conditional independent given the class label \(y_i\) (and the parameter vector, \(\boldsymbol{ \theta}\). This is quite a strong assumption. However, it causes the objective function to decompose into parts which can be independently fitted to the different feature vectors, meaning it is very easy to fit the model to large data. It is also clear how we should handle streaming data and missing data. This means that the model can be run ‘live,’ adapting parameters and information as it arrives. Indeed, the model is even capable of dealing with new features that might arrive at run time. Such is the strength of the modeling the joint probability density. However, the factorization assumption that allows us to do this efficiently is very strong and may lead to poor decision boundaries in practice. These characteristics mean that naive Bayes scales very well with big data. To fit the model we consider each feature in turn, we select the positive class and fit parameters for that class, then we select each negative class and fit features for that class. We have code below. Naive Bayes is making very simple assumptions about the data, in particular it is modeling the full joint probability of the data set, \(p(\mathbf{ y}, \mathbf{X}| \boldsymbol{ \theta}, \pi)\) by very strong assumptions about factorizations that are unlikely to be true in practice. The data conditional independence assumption is common, and relies on a rich parameter vector to absorb all the information in the training data. The additional assumption of naive Bayes is that features are conditional independent given the class label \(y_i\) (and the parameter vector, \(\boldsymbol{ \theta}\). This is quite a strong assumption. However, it causes the objective function to decompose into parts which can be independently fitted to the different feature vectors, meaning it is very easy to fit the model to large data. It is also clear how we should handle streaming data and missing data. This means that the model can be run ‘live’, adapting parameters and information as it arrives. Indeed, the model is even capable of dealing with new features that might arrive at run time. Such is the strength of the modeling the joint probability density. However, the factorization assumption that allows us to do this efficiently is very strong and may lead to poor decision boundaries in practice. This small package is a helper package for various notebook utilities used below. The software can be installed using from the command prompt where you can access your python installation. The code is also available on GitHub: https://github.com/lawrennd/notutils Once In Sheffield we created a suite of software tools for ‘Open Data Science.’ Open data science is an approach to sharing code, models and data that should make it easier for companies, health professionals and scientists to gain access to data science techniques. You can also check this blog post on Open Data Science. The software can be installed using from the command prompt where you can access your python installation. The code is also available on GitHub: https://github.com/lawrennd/ods Once The The software can be installed using from the command prompt where you can access your python installation. The code is also available on GitHub: https://github.com/lawrennd/mlai Once Figure: A key reference for Gaussian process models remains the excellent book “Gaussian Processes for Machine Learning” (Rasmussen and Williams (2006)). The book is also freely available online. Rasmussen and Williams (2006) is still one of the most important references on Gaussian process models. It is available freely online. Figure: The main course text is “A First Course in Machine Learning” by Rogers and Girolami (2011). As an example of using Gaussian process models within the full pipeline from data to decsion, we’ll consider the prediction of Malaria incidence in Uganda. For the purposes of this study malaria reports come in two forms, HMIS reports from health centres and Sentinel data, which is curated by the WHO. There are limited sentinel sites and many HMIS sites. The work is from Ricardo Andrade Pacheco’s PhD thesis, completed in collaboration with John Quinn and Martin Mubangizi (Andrade-Pacheco et al., 2014; Mubangizi et al., 2014). John and Martin were initally from the AI-DEV group from the University of Makerere in Kampala and more latterly they were based at UN Global Pulse in Kampala. You can see the work summarized on the UN Global Pulse disease outbreaks project site here. Malaria data is spatial data. Uganda is split into districts, and health reports can be found for each district. This suggests that models such as conditional random fields could be used for spatial modelling, but there are two complexities with this. First of all, occasionally districts split into two. Secondly, sentinel sites are a specific location within a district, such as Nagongera which is a sentinel site based in the Tororo district. Figure: Ugandan districts. Data SRTM/NASA from https://dds.cr.usgs.gov/srtm/version2_1. The common standard for collecting health data on the African continent is from the Health management information systems (HMIS). However, this data suffers from missing values (Gething et al., 2006) and diagnosis of diseases like typhoid and malaria may be confounded. Figure: The Tororo district, where the sentinel site, Nagongera, is located. World Health Organization Sentinel Surveillance systems are set up “when high-quality data are needed about a particular disease that cannot be obtained through a passive system.” Several sentinel sites give accurate assessment of malaria disease levels in Uganda, including a site in Nagongera. Figure: Sentinel and HMIS data along with rainfall and temperature for the Nagongera sentinel station in the Tororo district. In collaboration with the AI Research Group at Makerere we chose to investigate whether Gaussian process models could be used to assimilate information from these two different sources of disease informaton. Further, we were interested in whether local information on rainfall and temperature could be used to improve malaria estimates. The aim of the project was to use WHO Sentinel sites, alongside rainfall and temperature, to improve predictions from HMIS data of levels of malaria. Figure: The Mubende District. Figure: Prediction of malaria incidence in Mubende. Figure: The project arose out of the Gaussian process summer school held at Makerere in Kampala in 2013. The school led, in turn, to the Data Science Africa initiative. Figure: The Kabarole district in Uganda. Figure: Estimate of the current disease situation in the Kabarole district over time. Estimate is constructed with a Gaussian process with an additive covariance funciton. Health monitoring system for the Kabarole district. Here we have fitted the reports with a Gaussian process with an additive covariance function. It has two components, one is a long time scale component (in red above) the other is a short time scale component (in blue). Monitoring proceeds by considering two aspects of the curve. Is the blue line (the short term report signal) above the red (which represents the long term trend? If so we have higher than expected reports. If this is the case and the gradient is still positive (i.e. reports are going up) we encode this with a red color. If it is the case and the gradient of the blue line is negative (i.e. reports are going down) we encode this with an amber color. Conversely, if the blue line is below the red and decreasing, we color green. On the other hand if it is below red but increasing, we color yellow. This gives us an early warning system for disease. Red is a bad situation getting worse, amber is bad, but improving. Green is good and getting better and yellow good but degrading. Finally, there is a gray region which represents when the scale of the effect is small. Figure: The map of Ugandan districts with an overview of the Malaria situation in each district. These colors can now be observed directly on a spatial map of the districts to give an immediate impression of the current status of the disease across the country. What is machine learning? At its most basic level machine learning is a combination of \[\text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}\] where data is our observations. They can be actively or passively acquired (meta-data). The model contains our assumptions, based on previous experience. That experience can be other data, it can come from transfer learning, or it can merely be our beliefs about the regularities of the universe. In humans our models include our inductive biases. The prediction is an action to be taken or a categorization or a quality score. The reason that machine learning has become a mainstay of artificial intelligence is the importance of predictions in artificial intelligence. The data and the model are combined through computation. In practice we normally perform machine learning using two functions. To combine data with a model we typically make use of: a prediction function it is used to make the predictions. It includes our beliefs about the regularities of the universe, our assumptions about how the world works, e.g., smoothness, spatial similarities, temporal similarities. an objective function it defines the ‘cost’ of misprediction. Typically, it includes knowledge about the world’s generating processes (probabilistic objectives) or the costs we pay for mispredictions (empirical risk minimization). The combination of data and model through the prediction function and the objective function leads to a learning algorithm. The class of prediction functions and objective functions we can make use of is restricted by the algorithms they lead to. If the prediction function or the objective function are too complex, then it can be difficult to find an appropriate learning algorithm. Much of the academic field of machine learning is the quest for new learning algorithms that allow us to bring different types of models and data together. A useful reference for state of the art in machine learning is the UK Royal Society Report, Machine Learning: Power and Promise of Computers that Learn by Example. You can also check my post blog post on What is Machine Learning?. The challenge with a linear model is that it has two unknowns, \(m\), and \(c\). Observing data allows us to write down a system of simultaneous linear equations. So, for example if we observe two data points, the first with the input value, \(x_1 = 1\) and the output value, \(y_1 =3\) and a second data point, \(x= 3\), \(y=1\), then we can write two simultaneous linear equations of the form. point 1: \(x= 1\), \(y=3\) \[
+sns.set_palette('colorblind')}-->
+ This small package is a helper package for various notebook utilities used below. The software can be installed using from the command prompt where you can access your python installation. The code is also available on GitHub: https://github.com/lawrennd/notutils Once In Sheffield we created a suite of software tools for ‘Open Data Science’. Open data science is an approach to sharing code, models and data that should make it easier for companies, health professionals and scientists to gain access to data science techniques. You can also check this blog post on Open Data Science. The software can be installed using from the command prompt where you can access your python installation. The code is also available on GitHub: https://github.com/lawrennd/ods Once The The software can be installed using from the command prompt where you can access your python installation. The code is also available on GitHub: https://github.com/lawrennd/mlai Once Figure: A key reference for Gaussian process models remains the excellent book “Gaussian Processes for Machine Learning” (Rasmussen and Williams (2006)). The book is also freely available online. Rasmussen and Williams (2006) is still one of the most important references on Gaussian process models. It is available freely online. Figure: The main course text is “A First Course in Machine Learning” by Rogers and Girolami (2011). As an example of using Gaussian process models within the full pipeline from data to decsion, we’ll consider the prediction of Malaria incidence in Uganda. For the purposes of this study malaria reports come in two forms, HMIS reports from health centres and Sentinel data, which is curated by the WHO. There are limited sentinel sites and many HMIS sites. The work is from Ricardo Andrade Pacheco’s PhD thesis, completed in collaboration with John Quinn and Martin Mubangizi (Andrade-Pacheco et al., 2014; Mubangizi et al., 2014). John and Martin were initally from the AI-DEV group from the University of Makerere in Kampala and more latterly they were based at UN Global Pulse in Kampala. You can see the work summarized on the UN Global Pulse disease outbreaks project site here. Malaria data is spatial data. Uganda is split into districts, and health reports can be found for each district. This suggests that models such as conditional random fields could be used for spatial modelling, but there are two complexities with this. First of all, occasionally districts split into two. Secondly, sentinel sites are a specific location within a district, such as Nagongera which is a sentinel site based in the Tororo district. Figure: Ugandan districts. Data SRTM/NASA from https://dds.cr.usgs.gov/srtm/version2_1. The common standard for collecting health data on the African continent is from the Health management information systems (HMIS). However, this data suffers from missing values (Gething et al., 2006) and diagnosis of diseases like typhoid and malaria may be confounded. Figure: The Tororo district, where the sentinel site, Nagongera, is located. World Health Organization Sentinel Surveillance systems are set up “when high-quality data are needed about a particular disease that cannot be obtained through a passive system”. Several sentinel sites give accurate assessment of malaria disease levels in Uganda, including a site in Nagongera. Figure: Sentinel and HMIS data along with rainfall and temperature for the Nagongera sentinel station in the Tororo district. In collaboration with the AI Research Group at Makerere we chose to investigate whether Gaussian process models could be used to assimilate information from these two different sources of disease informaton. Further, we were interested in whether local information on rainfall and temperature could be used to improve malaria estimates. The aim of the project was to use WHO Sentinel sites, alongside rainfall and temperature, to improve predictions from HMIS data of levels of malaria. Figure: The Mubende District. Figure: Prediction of malaria incidence in Mubende. Figure: The project arose out of the Gaussian process summer school held at Makerere in Kampala in 2013. The school led, in turn, to the Data Science Africa initiative. Figure: The Kabarole district in Uganda. Figure: Estimate of the current disease situation in the Kabarole district over time. Estimate is constructed with a Gaussian process with an additive covariance funciton. Health monitoring system for the Kabarole district. Here we have fitted the reports with a Gaussian process with an additive covariance function. It has two components, one is a long time scale component (in red above) the other is a short time scale component (in blue). Monitoring proceeds by considering two aspects of the curve. Is the blue line (the short term report signal) above the red (which represents the long term trend? If so we have higher than expected reports. If this is the case and the gradient is still positive (i.e. reports are going up) we encode this with a red color. If it is the case and the gradient of the blue line is negative (i.e. reports are going down) we encode this with an amber color. Conversely, if the blue line is below the red and decreasing, we color green. On the other hand if it is below red but increasing, we color yellow. This gives us an early warning system for disease. Red is a bad situation getting worse, amber is bad, but improving. Green is good and getting better and yellow good but degrading. Finally, there is a gray region which represents when the scale of the effect is small. Figure: The map of Ugandan districts with an overview of the Malaria situation in each district. These colors can now be observed directly on a spatial map of the districts to give an immediate impression of the current status of the disease across the country. What is machine learning? At its most basic level machine learning is a combination of \[\text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}\] where data is our observations. They can be actively or passively acquired (meta-data). The model contains our assumptions, based on previous experience. That experience can be other data, it can come from transfer learning, or it can merely be our beliefs about the regularities of the universe. In humans our models include our inductive biases. The prediction is an action to be taken or a categorization or a quality score. The reason that machine learning has become a mainstay of artificial intelligence is the importance of predictions in artificial intelligence. The data and the model are combined through computation. In practice we normally perform machine learning using two functions. To combine data with a model we typically make use of: a prediction function it is used to make the predictions. It includes our beliefs about the regularities of the universe, our assumptions about how the world works, e.g., smoothness, spatial similarities, temporal similarities. an objective function it defines the ‘cost’ of misprediction. Typically, it includes knowledge about the world’s generating processes (probabilistic objectives) or the costs we pay for mispredictions (empirical risk minimization). The combination of data and model through the prediction function and the objective function leads to a learning algorithm. The class of prediction functions and objective functions we can make use of is restricted by the algorithms they lead to. If the prediction function or the objective function are too complex, then it can be difficult to find an appropriate learning algorithm. Much of the academic field of machine learning is the quest for new learning algorithms that allow us to bring different types of models and data together. A useful reference for state of the art in machine learning is the UK Royal Society Report, Machine Learning: Power and Promise of Computers that Learn by Example. You can also check my post blog post on What is Machine Learning?. The challenge with a linear model is that it has two unknowns, \(m\), and \(c\). Observing data allows us to write down a system of simultaneous linear equations. So, for example if we observe two data points, the first with the input value, \(x_1 = 1\) and the output value, \(y_1 =3\) and a second data point, \(x= 3\), \(y=1\), then we can write two simultaneous linear equations of the form. point 1: \(x= 1\), \(y=3\) \[
3 = m + c
\] point 2: \(x= 3\), \(y=1\) \[
1 = 3m + c
-\] The solution to these two simultaneous equations can be represented graphically as Figure: The solution of two linear equations represented as the fit of a straight line through two data The challenge comes when a third data point is observed, and it doesn’t fit on the straight line. point 3: \(x= 2\), \(y=2.5\) \[
+\] The solution to these two simultaneous equations can be represented graphically as Figure: The solution of two linear equations represented as the fit of a straight line through two data The challenge comes when a third data point is observed, and it doesn’t fit on the straight line. point 3: \(x= 2\), \(y=2.5\) \[
2.5 = 2m + c
-\] Figure: A third observation of data is inconsistent with the solution dictated by the first two observations Now there are three candidate lines, each consistent with our data. Figure: Three solutions to the problem, each consistent with two points of the three observations This is known as an overdetermined system because there are more data than we need to determine our parameters. The problem arises because the model is a simplification of the real world, and the data we observe is therefore inconsistent with our model. The solution was proposed by Pierre-Simon Laplace. His idea was to accept that the model was an incomplete representation of the real world, and the way it was incomplete is unknown. His idea was that such unknowns could be dealt with through probability. Figure: Pierre-Simon Laplace 1749-1827. Figure: Laplace’s determinism book reference. Famously, Laplace considered the idea of a deterministic Universe, one in which the model is known, or as the below translation refers to it, “an intelligence which could comprehend all the forces by which nature is animated.” He speculates on an “intelligence” that can submit this vast data to analysis and propsoses that such an entity would be able to predict the future. Given for one instant an intelligence which could comprehend all the forces by which nature is animated and the respective situation of the beings who compose it—an intelligence sufficiently vast to submit these data to analysis—it would embrace in the same formulate the movements of the greatest bodies of the universe and those of the lightest atom; for it, nothing would be uncertain and the future, as the past, would be present in its eyes. This notion is known as Laplace’s demon or Laplace’s superman. Figure: Laplace’s determinsim in English translation. Unfortunately, most analyses of his ideas stop at that point, whereas his real point is that such a notion is unreachable. Not so much superman as strawman. Just three pages later in the “Philosophical Essay on Probabilities” (Laplace, 1814), Laplace goes on to observe: The curve described by a simple molecule of air or vapor is regulated in a manner just as certain as the planetary orbits; the only difference between them is that which comes from our ignorance. Probability is relative, in part to this ignorance, in part to our knowledge. Figure: Laplace’s gremlin in the original French. Figure: To Laplace, determinism is a strawman. Ignorance of mechanism and data leads to uncertainty which should be dealt with through probability. In other words, we can never make use of the idealistic deterministic Universe due to our ignorance about the world, Laplace’s suggestion, and focus in this essay is that we turn to probability to deal with this uncertainty. This is also our inspiration for using probability in machine learning. This is the true message of Laplace’s essay, not determinism, but the gremlin of uncertainty that emerges from our ignorance. The “forces by which nature is animated” is our model, the “situation of beings that compose it” is our data and the “intelligence sufficiently vast enough to submit these data to analysis” is our compute. The fly in the ointment is our ignorance about these aspects. And probability is the tool we use to incorporate this ignorance leading to uncertainty or doubt in our predictions. Laplace’s concept was that the reason that the data doesn’t match up to the model is because of unconsidered factors, and that these might be well represented through probability densities. He tackles the challenge of the unknown factors by adding a variable, \(\epsilon\), that represents the unknown. In modern parlance we would call this a latent variable. But in the context Laplace uses it, the variable is so common that it has other names such as a “slack” variable or the noise in the system. point 1: \(x= 1\), \(y=3\) \[
+\] Figure: A third observation of data is inconsistent with the solution dictated by the first two observations Now there are three candidate lines, each consistent with our data. Figure: Three solutions to the problem, each consistent with two points of the three observations This is known as an overdetermined system because there are more data than we need to determine our parameters. The problem arises because the model is a simplification of the real world, and the data we observe is therefore inconsistent with our model. The solution was proposed by Pierre-Simon Laplace. His idea was to accept that the model was an incomplete representation of the real world, and the way it was incomplete is unknown. His idea was that such unknowns could be dealt with through probability. Figure: Pierre-Simon Laplace 1749-1827. Figure: Laplace’s determinism book reference. Famously, Laplace considered the idea of a deterministic Universe, one in which the model is known, or as the below translation refers to it, “an intelligence which could comprehend all the forces by which nature is animated”. He speculates on an “intelligence” that can submit this vast data to analysis and propsoses that such an entity would be able to predict the future. Given for one instant an intelligence which could comprehend all the forces by which nature is animated and the respective situation of the beings who compose it—an intelligence sufficiently vast to submit these data to analysis—it would embrace in the same formulate the movements of the greatest bodies of the universe and those of the lightest atom; for it, nothing would be uncertain and the future, as the past, would be present in its eyes. This notion is known as Laplace’s demon or Laplace’s superman. Figure: Laplace’s determinsim in English translation. Unfortunately, most analyses of his ideas stop at that point, whereas his real point is that such a notion is unreachable. Not so much superman as strawman. Just three pages later in the “Philosophical Essay on Probabilities” (Laplace, 1814), Laplace goes on to observe: The curve described by a simple molecule of air or vapor is regulated in a manner just as certain as the planetary orbits; the only difference between them is that which comes from our ignorance. Probability is relative, in part to this ignorance, in part to our knowledge. Figure: Laplace’s gremlin in the original French. Figure: To Laplace, determinism is a strawman. Ignorance of mechanism and data leads to uncertainty which should be dealt with through probability. In other words, we can never make use of the idealistic deterministic Universe due to our ignorance about the world, Laplace’s suggestion, and focus in this essay is that we turn to probability to deal with this uncertainty. This is also our inspiration for using probability in machine learning. This is the true message of Laplace’s essay, not determinism, but the gremlin of uncertainty that emerges from our ignorance. The “forces by which nature is animated” is our model, the “situation of beings that compose it” is our data and the “intelligence sufficiently vast enough to submit these data to analysis” is our compute. The fly in the ointment is our ignorance about these aspects. And probability is the tool we use to incorporate this ignorance leading to uncertainty or doubt in our predictions. Laplace’s concept was that the reason that the data doesn’t match up to the model is because of unconsidered factors, and that these might be well represented through probability densities. He tackles the challenge of the unknown factors by adding a variable, \(\epsilon\), that represents the unknown. In modern parlance we would call this a latent variable. But in the context Laplace uses it, the variable is so common that it has other names such as a “slack” variable or the noise in the system. point 1: \(x= 1\), \(y=3\) \[
3 = m + c + \epsilon_1
\] point 2: \(x= 3\), \(y=1\) \[
1 = 3m + c + \epsilon_2
\] point 3: \(x= 2\), \(y=2.5\) \[
2.5 = 2m + c + \epsilon_3
-\] Laplace’s trick has converted the overdetermined system into an underdetermined system. He has now added three variables, \(\{\epsilon_i\}_{i=1}^3\), which represent the unknown corruptions of the real world. Laplace’s idea is that we should represent that unknown corruption with a probability distribution. However, it was left to an admirer of Laplace to develop a practical probability density for that purpose. It was Carl Friedrich Gauss who suggested that the Gaussian density (which at the time was unnamed!) should be used to represent this error. The result is a noisy function, a function which has a deterministic part, and a stochastic part. This type of function is sometimes known as a probabilistic or stochastic process, to distinguish it from a deterministic process. The Gaussian density has many important properties, but for the moment we’ll review two of them. If we assume that a variable, \(y_i\), is sampled from a Gaussian density, \[y_i \sim \mathscr{N}\left(\mu_i,\sigma_i^2\right)\] Then we can show that the sum of a set of variables, each drawn independently from such a density is also distributed as Gaussian. The mean of the resulting density is the sum of the means, and the variance is the sum of the variances, \[
+\] Laplace’s trick has converted the overdetermined system into an underdetermined system. He has now added three variables, \(\{\epsilon_i\}_{i=1}^3\), which represent the unknown corruptions of the real world. Laplace’s idea is that we should represent that unknown corruption with a probability distribution. However, it was left to an admirer of Laplace to develop a practical probability density for that purpose. It was Carl Friedrich Gauss who suggested that the Gaussian density (which at the time was unnamed!) should be used to represent this error. The result is a noisy function, a function which has a deterministic part, and a stochastic part. This type of function is sometimes known as a probabilistic or stochastic process, to distinguish it from a deterministic process. The Gaussian density has many important properties, but for the moment we’ll review two of them. If we assume that a variable, \(y_i\), is sampled from a Gaussian density, \[y_i \sim \mathscr{N}\left(\mu_i,\sigma_i^2\right)\] Then we can show that the sum of a set of variables, each drawn independently from such a density is also distributed as Gaussian. The mean of the resulting density is the sum of the means, and the variance is the sum of the variances, \[
\sum_{i=1}^{n} y_i \sim \mathscr{N}\left(\sum_{i=1}^n\mu_i,\sum_{i=1}^n\sigma_i^2\right)
-\] Since we are very familiar with the Gaussian density and its properties, it is not immediately apparent how unusual this is. Most random variables, when you add them together, change the family of density they are drawn from. For example, the Gaussian is exceptional in this regard. Indeed, other random variables, if they are independently drawn and summed together tend to a Gaussian density. That is the central limit theorem which is a major justification for the use of a Gaussian density. Less unusual is the scaling property of a Gaussian density. If a variable, \(y\), is sampled from a Gaussian density, \[y\sim \mathscr{N}\left(\mu,\sigma^2\right)\] and we choose to scale that variable by a deterministic value, \(w\), then the scaled variable is distributed as \[wy\sim \mathscr{N}\left(w\mu,w^2 \sigma^2\right).\] Unlike the summing properties, where adding two or more random variables independently sampled from a family of densitites typically brings the summed variable outside that family, scaling many densities leaves the distribution of that variable in the same family of densities. Indeed, many densities include a scale parameter (e.g. the Gamma density) which is purely for this purpose. In the Gaussian the standard deviation, \(\sigma\), is the scale parameter. To see why this makes sense, let’s consider, \[z \sim \mathscr{N}\left(0,1\right),\] then if we scale by \(\sigma\) so we have, \(y=\sigma z\), we can write, \[y=\sigma z \sim \mathscr{N}\left(0,\sigma^2\right)\] Let’s first of all review the properties of the multivariate Gaussian distribution that make linear Gaussian models easier to deal with. We’ll return to the, perhaps surprising, result on the parameters within the nonlinearity, \(\boldsymbol{ \theta}\), shortly. To work with linear Gaussian models, to find the marginal likelihood all you need to know is the following rules. If \[
+\] Since we are very familiar with the Gaussian density and its properties, it is not immediately apparent how unusual this is. Most random variables, when you add them together, change the family of density they are drawn from. For example, the Gaussian is exceptional in this regard. Indeed, other random variables, if they are independently drawn and summed together tend to a Gaussian density. That is the central limit theorem which is a major justification for the use of a Gaussian density. Less unusual is the scaling property of a Gaussian density. If a variable, \(y\), is sampled from a Gaussian density, \[y\sim \mathscr{N}\left(\mu,\sigma^2\right)\] and we choose to scale that variable by a deterministic value, \(w\), then the scaled variable is distributed as \[wy\sim \mathscr{N}\left(w\mu,w^2 \sigma^2\right).\] Unlike the summing properties, where adding two or more random variables independently sampled from a family of densitites typically brings the summed variable outside that family, scaling many densities leaves the distribution of that variable in the same family of densities. Indeed, many densities include a scale parameter (e.g. the Gamma density) which is purely for this purpose. In the Gaussian the standard deviation, \(\sigma\), is the scale parameter. To see why this makes sense, let’s consider, \[z \sim \mathscr{N}\left(0,1\right),\] then if we scale by \(\sigma\) so we have, \(y=\sigma z\), we can write, \[y=\sigma z \sim \mathscr{N}\left(0,\sigma^2\right)\] Let’s first of all review the properties of the multivariate Gaussian distribution that make linear Gaussian models easier to deal with. We’ll return to the, perhaps surprising, result on the parameters within the nonlinearity, \(\boldsymbol{ \theta}\), shortly. To work with linear Gaussian models, to find the marginal likelihood all you need to know is the following rules. If \[
\mathbf{ y}= \mathbf{W}\mathbf{ x}+ \boldsymbol{ \epsilon},
\] where \(\mathbf{ y}\), \(\mathbf{ x}\) and \(\boldsymbol{ \epsilon}\) are vectors and we assume that \(\mathbf{ x}\) and \(\boldsymbol{ \epsilon}\) are drawn from multivariate Gaussians, \[
\begin{align}
@@ -48,26 +526,99 @@
\end{align}
\] then we know that \(\mathbf{ y}\) is also drawn from a multivariate Gaussian with, \[
\mathbf{ y}\sim \mathscr{N}\left(\mathbf{W}\boldsymbol{ \mu},\mathbf{W}\mathbf{C}\mathbf{W}^\top + \boldsymbol{ \Sigma}\right).
-\] With appropriately defined covariance, \(\boldsymbol{ \Sigma}\), this is actually the marginal likelihood for Factor Analysis, or Probabilistic Principal Component Analysis (Tipping and Bishop, 1999), because we integrated out the inputs (or latent variables they would be called in that case). Laplace had the idea to augment the observations by noise, that is equivalent to considering a probability density whose mean is given by the prediction function \[p\left(y_i|x_i\right)=\frac{1}{\sqrt{2\pi\sigma^2}}\exp\left(-\frac{\left(y_i-f\left(x_i\right)\right)^{2}}{2\sigma^2}\right).\] This is known as stochastic process. It is a function that is corrupted by noise. Laplace didn’t suggest the Gaussian density for that purpose, that was an innovation from Carl Friederich Gauss, which is what gives the Gaussian density its name. In the standard Gaussian, parameterized by mean and variance, make the mean a linear function of an input. This leads to a regression model. \[
+\] With appropriately defined covariance, \(\boldsymbol{ \Sigma}\), this is actually the marginal likelihood for Factor Analysis, or Probabilistic Principal Component Analysis (Tipping and Bishop, 1999), because we integrated out the inputs (or latent variables they would be called in that case). Laplace had the idea to augment the observations by noise, that is equivalent to considering a probability density whose mean is given by the prediction function \[p\left(y_i|x_i\right)=\frac{1}{\sqrt{2\pi\sigma^2}}\exp\left(-\frac{\left(y_i-f\left(x_i\right)\right)^{2}}{2\sigma^2}\right).\] This is known as stochastic process. It is a function that is corrupted by noise. Laplace didn’t suggest the Gaussian density for that purpose, that was an innovation from Carl Friederich Gauss, which is what gives the Gaussian density its name. In the standard Gaussian, parameterized by mean and variance, make the mean a linear function of an input. This leads to a regression model. \[
\begin{align*}
y_i=&f\left(x_i\right)+\epsilon_i,\\
\epsilon_i \sim & \mathscr{N}\left(0,\sigma^2\right).
\end{align*}
-\] Assume \(y_i\) is height and \(x_i\) is weight. Image from Wikimedia Commons The Olympic Marathon data is a standard dataset for regression modelling. The data consists of the pace of Olympic Gold Medal Marathon winners for the Olympics from 1896 to present. Let’s load in the data and plot. Assume \(y_i\) is height and \(x_i\) is weight. Image from Wikimedia Commons The Olympic Marathon data is a standard dataset for regression modelling. The data consists of the pace of Olympic Gold Medal Marathon winners for the Olympics from 1896 to present. Let’s load in the data and plot. Figure: Olympic marathon pace times since 1896. Things to notice about the data include the outlier in 1904, in that year the Olympics was in St Louis, USA. Organizational problems and challenges with dust kicked up by the cars following the race meant that participants got lost, and only very few participants completed. More recent years see more consistently quick marathons. Note that The aim of this lab is to have you coding linear regression in python. We will do it in two ways, once using iterative updates (coordinate ascent) and then using linear algebra. The linear algebra approach will not only work much better, it is also easy to extend to multiple input linear regression and non-linear regression using basis functions. Now we will take the maximum likelihood approach we derived in the lecture to fit a line, \(y_i=mx_i + c\), to the data you’ve plotted. We are trying to minimize the error function, \[
+yhat = (y - offset)/scale Figure: Olympic marathon pace times since 1896. Things to notice about the data include the outlier in 1904, in that year the Olympics was in St Louis, USA. Organizational problems and challenges with dust kicked up by the cars following the race meant that participants got lost, and only very few participants completed. More recent years see more consistently quick marathons. Note that The aim of this lab is to have you coding linear regression in python. We will do it in two ways, once using iterative updates (coordinate ascent) and then using linear algebra. The linear algebra approach will not only work much better, it is also easy to extend to multiple input linear regression and non-linear regression using basis functions. Now we will take the maximum likelihood approach we derived in the lecture to fit a line, \(y_i=mx_i + c\), to the data you’ve plotted. We are trying to minimize the error function, \[
E(m, c) = \sum_{i=1}^n(y_i-mx_i-c)^2,
-\] with respect to \(m\), \(c\) and \(\sigma^2\). We can start with an initial guess for \(m\), Then we use the maximum likelihood update to find an estimate for the offset, \(c\). Now we’ve identified the empirical risk with the loss, we’ll use \(E(\mathbf{ w})\) to represent our objective function. \[
+\] with respect to \(m\), \(c\) and \(\sigma^2\). We can start with an initial guess for \(m\), Then we use the maximum likelihood update to find an estimate for the offset, \(c\). Now we’ve identified the empirical risk with the loss, we’ll use \(E(\mathbf{ w})\) to represent our objective function. \[
E(\mathbf{ w}) = \sum_{i=1}^n\left(y_i - f(\mathbf{ x}_i, \mathbf{ w})\right)^2
-\] gives us our objective. In the case of the linear prediction function, we can substitute \(f(\mathbf{ x}_i, \mathbf{ w}) = \mathbf{ w}^\top \mathbf{ x}_i\). \[
+\] gives us our objective. In the case of the linear prediction function, we can substitute \(f(\mathbf{ x}_i, \mathbf{ w}) = \mathbf{ w}^\top \mathbf{ x}_i\). \[
E(\mathbf{ w}) = \sum_{i=1}^n\left(y_i - \mathbf{ w}^\top \mathbf{ x}_i\right)^2
-\] To compute the gradient of the objective, we first expand the brackets. \[
+\] To compute the gradient of the objective, we first expand the brackets. \[
\begin{align*}
E(\mathbf{ w},\sigma^2) = &
\frac{n}{2}\log \sigma^2 + \frac{1}{2\sigma^2}\sum
@@ -81,32 +632,43 @@
\mathbf{ w}^{\top}\left[\sum
_{i=1}^{n}\mathbf{ x}_i\mathbf{ x}_i^{\top}\right]\mathbf{ w}+\text{const}.
\end{align*}
-\] In this section we’re going compute the minimum of the quadratic loss with respect to the parameters. When we do this, we’ll also review linear algebra. We will represent all our errors and functions in the form of matrices and vectors. Linear algebra is just a shorthand for performing lots of multiplications and additions simultaneously. What does it have to do with our system then? Well, the first thing to note is that the classic linear function we fit for a one-dimensional regression has the form: \[
+\] In this section we’re going compute the minimum of the quadratic loss with respect to the parameters. When we do this, we’ll also review linear algebra. We will represent all our errors and functions in the form of matrices and vectors. Linear algebra is just a shorthand for performing lots of multiplications and additions simultaneously. What does it have to do with our system then? Well, the first thing to note is that the classic linear function we fit for a one-dimensional regression has the form: \[
f(x) = mx + c
-\] the classical form for a straight line. From a linear algebraic perspective, we are looking for multiplications and additions. We are also looking to separate our parameters from our data. The data is the givens. In French the word is données literally translated means givens that’s great, because we don’t need to change the data, what we need to change are the parameters (or variables) of the model. In this function the data comes in through \(x\), and the parameters are \(m\) and \(c\). What we’d like to create is a vector of parameters and a vector of data. Then we could represent the system with vectors that represent the data, and vectors that represent the parameters. We look to turn the multiplications and additions into a linear algebraic form, we have one multiplication (\(m\times c\)) and one addition (\(mx + c\)). But we can turn this into an inner product by writing it in the following way, \[
+\] the classical form for a straight line. From a linear algebraic perspective, we are looking for multiplications and additions. We are also looking to separate our parameters from our data. The data is the givens. In French the word is données literally translated means givens that’s great, because we don’t need to change the data, what we need to change are the parameters (or variables) of the model. In this function the data comes in through \(x\), and the parameters are \(m\) and \(c\). What we’d like to create is a vector of parameters and a vector of data. Then we could represent the system with vectors that represent the data, and vectors that represent the parameters. We look to turn the multiplications and additions into a linear algebraic form, we have one multiplication (\(m\times c\)) and one addition (\(mx + c\)). But we can turn this into an inner product by writing it in the following way, \[
f(x) = m \times x +
c \times 1,
\] in other words, we’ve extracted the unit value from the offset, \(c\). We can think of this unit value like an extra item of data, because it is always given to us, and it is always set to 1 (unlike regular data, which is likely to vary!). We can therefore write each input data location, \(\mathbf{ x}\), as a vector \[
\mathbf{ x}= \begin{bmatrix} 1\\ x\end{bmatrix}.
-\] Now we choose to also turn our parameters into a vector. The parameter vector will be defined to contain \[
+\] Now we choose to also turn our parameters into a vector. The parameter vector will be defined to contain \[
\mathbf{ w}= \begin{bmatrix} c \\ m\end{bmatrix}
\] because if we now take the inner product between these two vectors we recover \[
\mathbf{ x}\cdot\mathbf{ w}= 1 \times c + x \times m = mx + c
-\] In This gives us the equivalence between original operation and an operation in vector space. Whilst the notation here isn’t a lot shorter, the beauty is that we will be able to add as many features as we like and keep the same representation. In general, we are now moving to a system where each of our predictions is given by an inner product. When we want to represent a linear product in linear algebra, we tend to do it with the transpose operation, so since we have \(\mathbf{a}\cdot\mathbf{b} = \mathbf{a}^\top\mathbf{b}\) we can write \[
+w[1] = c This gives us the equivalence between original operation and an operation in vector space. Whilst the notation here isn’t a lot shorter, the beauty is that we will be able to add as many features as we like and keep the same representation. In general, we are now moving to a system where each of our predictions is given by an inner product. When we want to represent a linear product in linear algebra, we tend to do it with the transpose operation, so since we have \(\mathbf{a}\cdot\mathbf{b} = \mathbf{a}^\top\mathbf{b}\) we can write \[
f(\mathbf{ x}_i) = \mathbf{ x}_i^\top\mathbf{ w}.
\] Where we’ve assumed that each data point, \(\mathbf{ x}_i\), is now written by appending a 1 onto the original vector \[
-\mathbf{ x}_i = \begin{bmatrix}
+\mathbf{ x}_i = \begin{bmatrix}
1 \\
x_i
\end{bmatrix}
-\] We can do this for the entire data set to form a design matrix \(\boldsymbol{ \Phi}\), \[
+\] We can do this for the entire data set to form a design matrix \(\boldsymbol{ \Phi}\), \[
\boldsymbol{ \Phi}
-= \begin{bmatrix}
-\mathbf{ x}_1^\top \\\
-\mathbf{ x}_2^\top \\\
+= \begin{bmatrix}
+\mathbf{ x}_1^\top \\\
+\mathbf{ x}_2^\top \\\
\vdots \\\
\mathbf{ x}_n^\top
\end{bmatrix} = \begin{bmatrix}
@@ -116,8 +678,12 @@
& \vdots \\\
1 & x_n
\end{bmatrix},
-\] which in When we think of the objective function, we can think of it as the errors where the error is defined in a similar way to what it was in Legendre’s day \(y_i - f(\mathbf{ x}_i)\), in statistics these errors are also sometimes called residuals. So, we can think as the objective and the prediction function as two separate parts, first we have, \[
+\] which in When we think of the objective function, we can think of it as the errors where the error is defined in a similar way to what it was in Legendre’s day \(y_i - f(\mathbf{ x}_i)\), in statistics these errors are also sometimes called residuals. So, we can think as the objective and the prediction function as two separate parts, first we have, \[
E(\mathbf{ w}) = \sum_{i=1}^n(y_i - f(\mathbf{ x}_i; \mathbf{ w}))^2,
\] where we’ve made the function \(f(\cdot)\)’s dependence on the parameters \(\mathbf{ w}\) explicit in this equation. Then we have the definition of the function itself, \[
f(\mathbf{ x}_i; \mathbf{ w}) = \mathbf{ x}_i^\top \mathbf{ w}.
@@ -136,28 +702,44 @@
f_i = \mathbf{ x}_i^\top\mathbf{ w}.
\] This operation tells us that each element of the vector \(\mathbf{ f}\) (our vector valued function) is given by an inner product between \(\mathbf{ x}_i\) and \(\mathbf{ w}\). In other words, it is a series of inner products. Let’s look at the definition of matrix multiplication, it takes the form \[
\mathbf{c} = \mathbf{B}\mathbf{a},
-\] where \(\mathbf{c}\) might be a \(k\) dimensional vector (which we can interpret as a \(k\times 1\) dimensional matrix), and \(\mathbf{B}\) is a \(k\times k\) dimensional matrix and \(\mathbf{a}\) is a \(k\) dimensional vector (\(k\times 1\) dimensional matrix). The result of this multiplication is of the form \[
+\] where \(\mathbf{c}\) might be a \(k\) dimensional vector (which we can interpret as a \(k\times 1\) dimensional matrix), and \(\mathbf{B}\) is a \(k\times k\) dimensional matrix and \(\mathbf{a}\) is a \(k\) dimensional vector (\(k\times 1\) dimensional matrix). The result of this multiplication is of the form \[
\begin{bmatrix}c_1\\c_2 \\ \vdots \\
-a_k\end{bmatrix} =
+a_k\end{bmatrix} =
\begin{bmatrix} b_{1,1} & b_{1, 2} & \dots & b_{1, k} \\
b_{2, 1} & b_{2, 2} & \dots & b_{2, k} \\
\vdots & \vdots & \ddots & \vdots \\
b_{k, 1} & b_{k, 2} & \dots & b_{k, k} \end{bmatrix} \begin{bmatrix}a_1\\a_2 \\
\vdots\\ c_k\end{bmatrix} = \begin{bmatrix} b_{1, 1}a_1 + b_{1, 2}a_2 + \dots +
b_{1, k}a_k\\
-b_{2, 1}a_1 + b_{2, 2}a_2 + \dots + b_{2, k}a_k \\
+b_{2, 1}a_1 + b_{2, 2}a_2 + \dots + b_{2, k}a_k \\
\vdots\\
b_{k, 1}a_1 + b_{k, 2}a_2 + \dots + b_{k, k}a_k\end{bmatrix}.
-\] We see that each element of the result, \(\mathbf{a}\) is simply the inner product between each row of \(\mathbf{B}\) and the vector \(\mathbf{c}\). Because we have defined each element of \(\mathbf{ f}\) to be given by the inner product between each row of the design matrix and the vector \(\mathbf{ w}\) we now can write the full operation in one matrix multiplication, \[
+\] We see that each element of the result, \(\mathbf{a}\) is simply the inner product between each row of \(\mathbf{B}\) and the vector \(\mathbf{c}\). Because we have defined each element of \(\mathbf{ f}\) to be given by the inner product between each row of the design matrix and the vector \(\mathbf{ w}\) we now can write the full operation in one matrix multiplication, \[
\mathbf{ f}= \boldsymbol{ \Phi}\mathbf{ w}.
-\] Combining this result with our objective function, \[
+\] Combining this result with our objective function, \[
E(\mathbf{ w}) = (\mathbf{ y}- \mathbf{ f})^\top(\mathbf{ y}- \mathbf{ f})
-\] we find we have defined the model with two equations. One equation tells us the form of our predictive function and how it depends on its parameters, the other tells us the form of our objective function. Our model has now been defined with two equations: the prediction function and the objective function. Now we will use multivariate calculus to define an algorithm to fit the model. The separation between model and algorithm is important and is often overlooked. Our model contains a function that shows how it will be used for prediction, and a function that describes the objective function we need to optimize to obtain a good set of parameters. The model linear regression model we have described is still the same as the one we fitted above with a coordinate ascent algorithm. We have only played with the notation to obtain the same model in a matrix and vector notation. However, we will now fit this model with a different algorithm, one that is much faster. It is such a widely used algorithm that from the end user’s perspective it doesn’t even look like an algorithm, it just appears to be a single operation (or function). However, underneath the computer calls an algorithm to find the solution. Further, the algorithm we obtain is very widely used, and because of this it turns out to be highly optimized. Once again, we are going to try and find the stationary points of our objective by finding the stationary points. However, the stationary points of a multivariate function, are a little bit more complex to find. As before we need to find the point at which the gradient is zero, but now we need to use multivariate calculus to find it. This involves learning a few additional rules of differentiation (that allow you to do the derivatives of a function with respect to vector), but in the end it makes things quite a bit easier. We define vectorial derivatives as follows, \[
+print("Error function is:", E) Our model has now been defined with two equations: the prediction function and the objective function. Now we will use multivariate calculus to define an algorithm to fit the model. The separation between model and algorithm is important and is often overlooked. Our model contains a function that shows how it will be used for prediction, and a function that describes the objective function we need to optimize to obtain a good set of parameters. The model linear regression model we have described is still the same as the one we fitted above with a coordinate ascent algorithm. We have only played with the notation to obtain the same model in a matrix and vector notation. However, we will now fit this model with a different algorithm, one that is much faster. It is such a widely used algorithm that from the end user’s perspective it doesn’t even look like an algorithm, it just appears to be a single operation (or function). However, underneath the computer calls an algorithm to find the solution. Further, the algorithm we obtain is very widely used, and because of this it turns out to be highly optimized. Once again, we are going to try and find the stationary points of our objective by finding the stationary points. However, the stationary points of a multivariate function, are a little bit more complex to find. As before we need to find the point at which the gradient is zero, but now we need to use multivariate calculus to find it. This involves learning a few additional rules of differentiation (that allow you to do the derivatives of a function with respect to vector), but in the end it makes things quite a bit easier. We define vectorial derivatives as follows, \[
\frac{\text{d}E(\mathbf{ w})}{\text{d}\mathbf{ w}} =
\begin{bmatrix}\frac{\text{d}E(\mathbf{ w})}{\text{d}w_1}\\\frac{\text{d}E(\mathbf{ w})}{\text{d}w_2}\end{bmatrix}.
-\] where \(\frac{\text{d}E(\mathbf{ w})}{\text{d}w_1}\) is the partial derivative of the error function with respect to \(w_1\). Differentiation through multiplications and additions is relatively straightforward, and since linear algebra is just multiplication and addition, then its rules of differentiation are quite straightforward too, but slightly more complex than regular derivatives. We will need two rules of multivariate or matrix differentiation. The first is differentiation of an inner product. By remembering that the inner product is made up of multiplication and addition, we can hope that its derivative is quite straightforward, and so it proves to be. We can start by thinking about the definition of the inner product, \[
+\] where \(\frac{\text{d}E(\mathbf{ w})}{\text{d}w_1}\) is the partial derivative of the error function with respect to \(w_1\). Differentiation through multiplications and additions is relatively straightforward, and since linear algebra is just multiplication and addition, then its rules of differentiation are quite straightforward too, but slightly more complex than regular derivatives. We will need two rules of multivariate or matrix differentiation. The first is differentiation of an inner product. By remembering that the inner product is made up of multiplication and addition, we can hope that its derivative is quite straightforward, and so it proves to be. We can start by thinking about the definition of the inner product, \[
\mathbf{a}^\top\mathbf{z} = \sum_{i} a_i
z_i,
\] which if we were to take the derivative with respect to \(z_k\) would simply return the gradient of the one term in the sum for which the derivative was non-zero, that of \(a_k\), so we know that \[
@@ -165,12 +747,15 @@
\] and by our definition for multivariate derivatives, we can simply stack all the partial derivatives of this form in a vector to obtain the result that \[
\frac{\text{d}}{\text{d}\mathbf{z}}
\mathbf{a}^\top \mathbf{z} = \mathbf{a}.
-\] The second rule that’s required is differentiation of a ‘matrix quadratic.’ A scalar quadratic in \(z\) with coefficient \(c\) has the form \(cz^2\). If \(\mathbf{z}\) is a \(k\times 1\) vector and \(\mathbf{C}\) is a \(k \times k\) matrix of coefficients then the matrix quadratic form is written as \(\mathbf{z}^\top \mathbf{C}\mathbf{z}\), which is itself a scalar quantity, but it is a function of a vector. There’s a trick for telling a multiplication leads to a scalar result. When you are doing mathematics with matrices, it’s always worth pausing to perform a quick sanity check on the dimensions. Matrix multplication only works when the dimensions match. To be precise, the ‘inner’ dimension of the matrix must match. What is the inner dimension? If we multiply two matrices \(\mathbf{A}\) and \(\mathbf{B}\), the first of which has \(k\) rows and \(\ell\) columns and the second of which has \(p\) rows and \(q\) columns, then we can check whether the multiplication works by writing the dimensionalities next to each other, \[
+\] The second rule that’s required is differentiation of a ‘matrix quadratic’. A scalar quadratic in \(z\) with coefficient \(c\) has the form \(cz^2\). If \(\mathbf{z}\) is a \(k\times 1\) vector and \(\mathbf{C}\) is a \(k \times k\) matrix of coefficients then the matrix quadratic form is written as \(\mathbf{z}^\top \mathbf{C}\mathbf{z}\), which is itself a scalar quantity, but it is a function of a vector. There’s a trick for telling a multiplication leads to a scalar result. When you are doing mathematics with matrices, it’s always worth pausing to perform a quick sanity check on the dimensions. Matrix multplication only works when the dimensions match. To be precise, the ‘inner’ dimension of the matrix must match. What is the inner dimension? If we multiply two matrices \(\mathbf{A}\) and \(\mathbf{B}\), the first of which has \(k\) rows and \(\ell\) columns and the second of which has \(p\) rows and \(q\) columns, then we can check whether the multiplication works by writing the dimensionalities next to each other, \[
\mathbf{A} \mathbf{B} \rightarrow (k \times
\underbrace{\ell)(p}_\text{inner dimensions} \times q) \rightarrow (k\times q).
-\] The inner dimensions are the two inside dimensions, \(\ell\) and \(p\). The multiplication will only work if \(\ell=p\). The result of the multiplication will then be a \(k\times q\) matrix: this dimensionality comes from the ‘outer dimensions.’ Note that matrix multiplication is not commutative. And if you change the order of the multiplication, \[
+\] The inner dimensions are the two inside dimensions, \(\ell\) and \(p\). The multiplication will only work if \(\ell=p\). The result of the multiplication will then be a \(k\times q\) matrix: this dimensionality comes from the ‘outer dimensions’. Note that matrix multiplication is not commutative. And if you change the order of the multiplication, \[
\mathbf{B} \mathbf{A} \rightarrow (\ell \times \underbrace{k)(q}_\text{inner dimensions} \times p) \rightarrow (\ell \times p).
-\] Firstly, it may no longer even work, because now the condition is that \(k=q\), and secondly the result could be of a different dimensionality. An exception is if the matrices are square matrices (e.g., same number of rows as columns) and they are both symmetric. A symmetric matrix is one for which \(\mathbf{A}=\mathbf{A}^\top\), or equivalently, \(a_{i,j} = a_{j,i}\) for all \(i\) and \(j\). For applying and developing machine learning algorithms you should get familiar with working with matrices and vectors. You should have come across them before, but you may not have used them as extensively as we are doing now. It’s worth getting used to using this trick to check your work and ensure you know what the dimension of an output matrix should be. For our matrix quadratic form, it turns out that we can see it as a special type of inner product. \[
+\] Firstly, it may no longer even work, because now the condition is that \(k=q\), and secondly the result could be of a different dimensionality. An exception is if the matrices are square matrices (e.g., same number of rows as columns) and they are both symmetric. A symmetric matrix is one for which \(\mathbf{A}=\mathbf{A}^\top\), or equivalently, \(a_{i,j} = a_{j,i}\) for all \(i\) and \(j\). For applying and developing machine learning algorithms you should get familiar with working with matrices and vectors. You should have come across them before, but you may not have used them as extensively as we are doing now. It’s worth getting used to using this trick to check your work and ensure you know what the dimension of an output matrix should be. For our matrix quadratic form, it turns out that we can see it as a special type of inner product. \[
\mathbf{z}^\top\mathbf{C}\mathbf{z} \rightarrow (1\times
\underbrace{k) (k}_\text{inner dimensions}\times k) (k\times 1) \rightarrow
\mathbf{b}^\top\mathbf{z}
@@ -178,14 +763,17 @@
\mathbf{b}^\top\mathbf{z} \rightarrow
(1\times \underbrace{k) (k}_\text{inner dimensions}\times 1) \rightarrow
(1\times 1)
-\] where a \((1\times 1)\) matrix is recognised as a scalar. This implies that we should be able to differentiate this form, and indeed the rule for its differentiation is slightly more complex than the inner product, but still quite simple, \[
+\] where a \((1\times 1)\) matrix is recognised as a scalar. This implies that we should be able to differentiate this form, and indeed the rule for its differentiation is slightly more complex than the inner product, but still quite simple, \[
\frac{\text{d}}{\text{d}\mathbf{z}}
\mathbf{z}^\top\mathbf{C}\mathbf{z}= \mathbf{C}\mathbf{z} + \mathbf{C}^\top
\mathbf{z}.
\] Note that in the special case where \(\mathbf{C}\) is symmetric then we have \(\mathbf{C} = \mathbf{C}^\top\) and the derivative simplifies to \[
\frac{\text{d}}{\text{d}\mathbf{z}} \mathbf{z}^\top\mathbf{C}\mathbf{z}=
2\mathbf{C}\mathbf{z}.
-\] First, we need to compute the full objective by substituting our prediction function into the objective function to obtain the objective in terms of \(\mathbf{ w}\). Doing this we obtain \[
+\] First, we need to compute the full objective by substituting our prediction function into the objective function to obtain the objective in terms of \(\mathbf{ w}\). Doing this we obtain \[
E(\mathbf{ w})= (\mathbf{ y}- \boldsymbol{ \Phi}\mathbf{ w})^\top (\mathbf{ y}- \boldsymbol{ \Phi}\mathbf{ w}).
\] We now need to differentiate this quadratic form to find the minimum. We differentiate with respect to the vector \(\mathbf{ w}\). But before we do that, we’ll expand the brackets in the quadratic form to obtain a series of scalar terms. The rules for bracket expansion across the vectors are similar to those for the scalar system giving, \[
(\mathbf{a} - \mathbf{b})^\top
@@ -195,57 +783,203 @@
E(\mathbf{ w})=
\mathbf{ y}^\top\mathbf{ y}- 2\mathbf{ y}^\top\boldsymbol{ \Phi}\mathbf{ w}+
\mathbf{ w}^\top\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\mathbf{ w}
-\] where we used the fact that \(\mathbf{ y}^\top\boldsymbol{ \Phi}\mathbf{ w}=\mathbf{ w}^\top\boldsymbol{ \Phi}^\top\mathbf{ y}\). Now we can use our rules of differentiation to compute the derivative of this form, which is, \[
+\] where we used the fact that \(\mathbf{ y}^\top\boldsymbol{ \Phi}\mathbf{ w}=\mathbf{ w}^\top\boldsymbol{ \Phi}^\top\mathbf{ y}\). Now we can use our rules of differentiation to compute the derivative of this form, which is, \[
\frac{\text{d}}{\text{d}\mathbf{ w}}E(\mathbf{ w})=- 2\boldsymbol{ \Phi}^\top \mathbf{ y}+
2\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\mathbf{ w},
-\] where we have exploited the fact that \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\) is symmetric to obtain this result. Use the equivalence between our vector and our matrix formulations of linear regression, alongside our definition of vector derivates, to match the gradients we’ve computed directly for \(\frac{\text{d}E(c, m)}{\text{d}c}\) and \(\frac{\text{d}E(c, m)}{\text{d}m}\) to those for \(\frac{\text{d}E(\mathbf{ w})}{\text{d}\mathbf{ w}}\). We need to find the minimum of our objective function. Using our objective function, we can minimize for our parameter vector \(\mathbf{ w}\). Firstly, we seek stationary points by find parameter vectors that solve for when the gradients are zero, \[
+\] where we have exploited the fact that \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\) is symmetric to obtain this result. Use the equivalence between our vector and our matrix formulations of linear regression, alongside our definition of vector derivates, to match the gradients we’ve computed directly for \(\frac{\text{d}E(c, m)}{\text{d}c}\) and \(\frac{\text{d}E(c, m)}{\text{d}m}\) to those for \(\frac{\text{d}E(\mathbf{ w})}{\text{d}\mathbf{ w}}\). We need to find the minimum of our objective function. Using our objective function, we can minimize for our parameter vector \(\mathbf{ w}\). Firstly, we seek stationary points by find parameter vectors that solve for when the gradients are zero, \[
\mathbf{0}=- 2\boldsymbol{ \Phi}^\top
\mathbf{ y}+ 2\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\mathbf{ w},
\] where \(\mathbf{0}\) is a vector of zeros. Rearranging this equation, we find the solution to be \[
\boldsymbol{ \Phi}^\top \boldsymbol{ \Phi}\mathbf{ w}= \boldsymbol{ \Phi}^\top
\mathbf{ y}
-\] which is a matrix equation of the familiar form \(\mathbf{A}\mathbf{x} = \mathbf{b}\). The solution for \(\mathbf{ w}\) can be written mathematically in terms of a matrix inverse of \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\), but computation of a matrix inverse requires an algorithm to resolve it. You’ll know this if you had to invert, by hand, a \(3\times 3\) matrix in high school. From a numerical stability perspective, it is also best not to compute the matrix inverse directly, but rather to ask the computer to solve the system of linear equations given by \[
+\] which is a matrix equation of the familiar form \(\mathbf{A}\mathbf{x} = \mathbf{b}\). The solution for \(\mathbf{ w}\) can be written mathematically in terms of a matrix inverse of \(\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\), but computation of a matrix inverse requires an algorithm to resolve it. You’ll know this if you had to invert, by hand, a \(3\times 3\) matrix in high school. From a numerical stability perspective, it is also best not to compute the matrix inverse directly, but rather to ask the computer to solve the system of linear equations given by \[
\boldsymbol{ \Phi}^\top\boldsymbol{ \Phi}\mathbf{ w}= \boldsymbol{ \Phi}^\top\mathbf{ y}
-\] for \(\mathbf{ w}\). A major advantage of the new system is that we can build a linear regression on a multivariate system. The matrix calculus didn’t specify what the length of the vector \(\mathbf{ x}\) should be, or equivalently the size of the design matrix. This is a data set created by Simon Garnier and Rany Olson for exploring the differences between R and Python for data science. The data contains information about different movies augmented by estimates about how many on-screen deaths are contained in the movie. The data is craped from http://www.moviebodycounts.com. The data contains the following featuers for each movie: The data is provided to us in the form of a pandas data frame, we can see the features we’re provided with by inspecting the columns of the data frame. Once it is loaded in the data can be summarized using the Now we will build a design matrix based on the numeric features: year, Body_Count, Length_Minutes in an effort to predict the rating. We build the design matrix as follows: Bias as an additional feature. A major advantage of the new system is that we can build a linear regression on a multivariate system. The matrix calculus didn’t specify what the length of the vector \(\mathbf{ x}\) should be, or equivalently the size of the design matrix. This is a data set created by Simon Garnier and Rany Olson for exploring the differences between R and Python for data science. The data contains information about different movies augmented by estimates about how many on-screen deaths are contained in the movie. The data is craped from http://www.moviebodycounts.com. The data contains the following featuers for each movie: The data is provided to us in the form of a pandas data frame, we can see the features we’re provided with by inspecting the columns of the data frame. Once it is loaded in the data can be summarized using the Now we will build a design matrix based on the numeric features: year, Body_Count, Length_Minutes in an effort to predict the rating. We build the design matrix as follows: Bias as an additional feature. Now let’s perform a linear regression. But this time, we will create a pandas data frame for the result so we can store it in a form that we can visualise easily. Now let’s perform a linear regression. But this time, we will create a pandas data frame for the result so we can store it in a form that we can visualise easily. We can check the residuals to see how good our estimates are. First we create a pandas data frame containing the predictions and use it to compute the residuals. Figure: Residual values for the ratings from the prediction of the movie rating given the data from the film. Which shows our model hasn’t yet done a great job of representation, because the spread of values is large. We can check what the rating is dominated by in terms of regression coefficients. Although we have to be a little careful about interpretation because our input values live on different scales, however it looks like we are dominated by the bias, with a small negative effect for later films (but bear in mind the years are large, so this effect is probably larger than it looks) and a positive effect for length. So it looks like long earlier films generally do better, but the residuals are so high that we probably haven’t modelled the system very well. What about the situation where you have more parameters than data in your simultaneous equation? This is known as an underdetermined system. In fact, this set up is in some sense easier to solve, because we don’t need to think about introducing a slack variable (although it might make a lot of sense from a modelling perspective to do so). The way Laplace proposed resolving an overdetermined system, was to introduce slack variables, \(\epsilon_i\), which needed to be estimated for each point. The slack variable represented the difference between our actual prediction and the true observation. This is known as the residual. By introducing the slack variable, we now have an additional \(n\) variables to estimate, one for each data point, \(\{\epsilon_i\}\). This turns the overdetermined system into an underdetermined system. Introduction of \(n\) variables, plus the original \(m\) and \(c\) gives us \(n+2\) parameters to be estimated from \(n\) observations, which makes the system underdetermined. However, we then made a probabilistic assumption about the slack variables, we assumed that the slack variables were distributed according to a probability density. And for the moment we have been assuming that density was the Gaussian, \[\epsilon_i \sim \mathscr{N}\left(0,\sigma^2\right),\] with zero mean and variance \(\sigma^2\). The follow up question is whether we can do the same thing with the parameters. If we have two parameters and only one unknown, can we place a probability distribution over the parameters as we did with the slack variables? The answer is yes. Figure: An underdetermined system can be fit by considering uncertainty. Multiple solutions are consistent with one specified point. Consider the distribution of height (in meters) of an adult male human population. We will approximate the marginal density of heights as a Gaussian density with mean given by \(1.7\text{m}\) and a standard deviation of \(0.15\text{m}\), implying a variance of \(\sigma^2=0.0225\), \[
+ columns=['regression_coefficient']) # the column of Phi is the value of regression coefficient We can check the residuals to see how good our estimates are. First we create a pandas data frame containing the predictions and use it to compute the residuals. Figure: Residual values for the ratings from the prediction of the movie rating given the data from the film. Which shows our model hasn’t yet done a great job of representation, because the spread of values is large. We can check what the rating is dominated by in terms of regression coefficients. Although we have to be a little careful about interpretation because our input values live on different scales, however it looks like we are dominated by the bias, with a small negative effect for later films (but bear in mind the years are large, so this effect is probably larger than it looks) and a positive effect for length. So it looks like long earlier films generally do better, but the residuals are so high that we probably haven’t modelled the system very well. What about the situation where you have more parameters than data in your simultaneous equation? This is known as an underdetermined system. In fact, this set up is in some sense easier to solve, because we don’t need to think about introducing a slack variable (although it might make a lot of sense from a modelling perspective to do so). The way Laplace proposed resolving an overdetermined system, was to introduce slack variables, \(\epsilon_i\), which needed to be estimated for each point. The slack variable represented the difference between our actual prediction and the true observation. This is known as the residual. By introducing the slack variable, we now have an additional \(n\) variables to estimate, one for each data point, \(\{\epsilon_i\}\). This turns the overdetermined system into an underdetermined system. Introduction of \(n\) variables, plus the original \(m\) and \(c\) gives us \(n+2\) parameters to be estimated from \(n\) observations, which makes the system underdetermined. However, we then made a probabilistic assumption about the slack variables, we assumed that the slack variables were distributed according to a probability density. And for the moment we have been assuming that density was the Gaussian, \[\epsilon_i \sim \mathscr{N}\left(0,\sigma^2\right),\] with zero mean and variance \(\sigma^2\). The follow up question is whether we can do the same thing with the parameters. If we have two parameters and only one unknown, can we place a probability distribution over the parameters as we did with the slack variables? The answer is yes. Figure: An underdetermined system can be fit by considering uncertainty. Multiple solutions are consistent with one specified point. Consider the distribution of height (in meters) of an adult male human population. We will approximate the marginal density of heights as a Gaussian density with mean given by \(1.7\text{m}\) and a standard deviation of \(0.15\text{m}\), implying a variance of \(\sigma^2=0.0225\), \[
p(h) \sim \mathscr{N}\left(1.7,0.0225\right).
\] Similarly, we assume that weights of the population are distributed a Gaussian density with a mean of \(75 \text{kg}\) and a standard deviation of \(6 kg\) (implying a variance of 36), \[
p(w) \sim \mathscr{N}\left(75,36\right).
- \] Figure: Gaussian distributions for height and weight. First of all, we make an independence assumption, we assume that height and weight are independent. The definition of probabilistic independence is that the joint density, \(p(w, h)\), factorizes into its marginal densities, \[
+ \] Figure: Gaussian distributions for height and weight. First of all, we make an independence assumption, we assume that height and weight are independent. The definition of probabilistic independence is that the joint density, \(p(w, h)\), factorizes into its marginal densities, \[
p(w, h) = p(w)p(h).
- \] Given this assumption we can sample from the joint distribution by independently sampling weights and heights. Figure: Samples from independent Gaussian variables that might represent heights and weights. In reality height and weight are not independent. Taller people tend on average to be heavier, and heavier people are likely to be taller. This is reflected by the body mass index. A ratio suggested by one of the fathers of statistics, Adolphe Quetelet. Quetelet was interested in the notion of the average man and collected various statistics about people. He defined the BMI to be, \[
+ \] Given this assumption we can sample from the joint distribution by independently sampling weights and heights. Figure: Samples from independent Gaussian variables that might represent heights and weights. In reality height and weight are not independent. Taller people tend on average to be heavier, and heavier people are likely to be taller. This is reflected by the body mass index. A ratio suggested by one of the fathers of statistics, Adolphe Quetelet. Quetelet was interested in the notion of the average man and collected various statistics about people. He defined the BMI to be, \[
\text{BMI} = \frac{w}{h^2}
-\]To deal with this dependence we now introduce the notion of correlation to the multivariate Gaussian density. \[
+\]To deal with this dependence we now introduce the notion of correlation to the multivariate Gaussian density. \[
p(w, h) = p(w)p(h)
-\] \[
+\] \[
p(w, h) = \frac{1}{\sqrt{2\pi \sigma_1^2}\sqrt{2\pi\sigma_2^2}} \exp\left(-\frac{1}{2}\left(\frac{(w-\mu_1)^2}{\sigma_1^2} + \frac{(h-\mu_2)^2}{\sigma_2^2}\right)\right)
-\] \[
+\] \[
p(w, h) = \frac{1}{\sqrt{2\pi\sigma_1^22\pi\sigma_2^2}} \exp\left(-\frac{1}{2}\left(\begin{bmatrix}w \\ h\end{bmatrix} - \begin{bmatrix}\mu_1 \\ \mu_2\end{bmatrix}\right)^\top\begin{bmatrix}\sigma_1^2& 0\\0&\sigma_2^2\end{bmatrix}^{-1}\left(\begin{bmatrix}w \\ h\end{bmatrix} - \begin{bmatrix}\mu_1 \\ \mu_2\end{bmatrix}\right)\right)
-\] \[
+\] \[
p(\mathbf{ y}) = \frac{1}{\det{2\pi \mathbf{D}}^{\frac{1}{2}}} \exp\left(-\frac{1}{2}(\mathbf{ y}- \boldsymbol{ \mu})^\top\mathbf{D}^{-1}(\mathbf{ y}- \boldsymbol{ \mu})\right)
-\] Form correlated from original by rotating the data space using matrix \(\mathbf{R}\). \[
+\] Form correlated from original by rotating the data space using matrix \(\mathbf{R}\). \[
p(\mathbf{ y}) = \frac{1}{\det{2\pi\mathbf{D}}^{\frac{1}{2}}} \exp\left(-\frac{1}{2}(\mathbf{ y}- \boldsymbol{ \mu})^\top\mathbf{D}^{-1}(\mathbf{ y}- \boldsymbol{ \mu})\right)
-\] \[
+\] \[
p(\mathbf{ y}) = \frac{1}{\det{2\pi\mathbf{D}}^{\frac{1}{2}}} \exp\left(-\frac{1}{2}(\mathbf{R}^\top\mathbf{ y}- \mathbf{R}^\top\boldsymbol{ \mu})^\top\mathbf{D}^{-1}(\mathbf{R}^\top\mathbf{ y}- \mathbf{R}^\top\boldsymbol{ \mu})\right)
-\] \[
+\] \[
p(\mathbf{ y}) = \frac{1}{\det{2\pi\mathbf{D}}^{\frac{1}{2}}} \exp\left(-\frac{1}{2}(\mathbf{ y}- \boldsymbol{ \mu})^\top\mathbf{R}\mathbf{D}^{-1}\mathbf{R}^\top(\mathbf{ y}- \boldsymbol{ \mu})\right)
\] this gives an inverse covariance matrix: \[
\mathbf{C}^{-1} = \mathbf{R}\mathbf{D}^{-1} \mathbf{R}^\top
-\] \[
+\] \[
p(\mathbf{ y}) = \frac{1}{\det{2\pi\mathbf{C}}^{\frac{1}{2}}} \exp\left(-\frac{1}{2}(\mathbf{ y}- \boldsymbol{ \mu})^\top\mathbf{C}^{-1} (\mathbf{ y}- \boldsymbol{ \mu})\right)
\] \[
\mathbf{C}= \mathbf{R}\mathbf{D} \mathbf{R}^\top
-\] Here’s the idea, instead of working directly on the original input space, \(\mathbf{ x}\), we build models in a new space, \(\boldsymbol{ \phi}(\mathbf{ x})\) where \(\boldsymbol{ \phi}(\cdot)\) is a vector-valued function that is defined on the space \(\mathbf{ x}\). Remember, that a vector-valued function is just a vector that contains functions instead of values. Here’s an example for a one dimensional input space, \(x\), being projected to a quadratic basis. First we consider each basis function in turn, we can think of the elements of our vector as being indexed so that we have \[
+\] Here’s the idea, instead of working directly on the original input space, \(\mathbf{ x}\), we build models in a new space, \(\boldsymbol{ \phi}(\mathbf{ x})\) where \(\boldsymbol{ \phi}(\cdot)\) is a vector-valued function that is defined on the space \(\mathbf{ x}\). Remember, that a vector-valued function is just a vector that contains functions instead of values. Here’s an example for a one dimensional input space, \(x\), being projected to a quadratic basis. First we consider each basis function in turn, we can think of the elements of our vector as being indexed so that we have \[
\begin{align*}
\phi_1(x) & = 1, \\
\phi_2(x) & = x, \\
@@ -253,52 +987,201 @@
\end{align*}
\] Now we can consider them together by placing them in a vector, \[
\boldsymbol{ \phi}(x) = \begin{bmatrix} 1\\ x \\ x^2\end{bmatrix}.
-\] For the vector-valued function, we have simply collected the different functions together in the same vector making them notationally easier to deal with in our mathematics. When we consider the vector-valued function for each data point, then we place all the data into a matrix. The result is a matrix valued function, \[
-\boldsymbol{ \Phi}(\mathbf{ x}) =
+\] For the vector-valued function, we have simply collected the different functions together in the same vector making them notationally easier to deal with in our mathematics. When we consider the vector-valued function for each data point, then we place all the data into a matrix. The result is a matrix valued function, \[
+\boldsymbol{ \Phi}(\mathbf{ x}) =
\begin{bmatrix} 1 & x_1 &
x_1^2 \\
1 & x_2 & x_2^2\\
\vdots & \vdots & \vdots \\
1 & x_n & x_n^2
\end{bmatrix}
-\] where we are still in the one dimensional input setting so \(\mathbf{ x}\) here represents a vector of our inputs with \(n\) elements. Let’s try constructing such a matrix for a set of inputs. First of all, we create a function that returns the matrix valued function. Let’s try constructing such a matrix for a set of inputs. First of all, we create a function that returns the matrix valued function. \[
+ return np.hstack([np.ones((x.shape[0], 1)), x, x**2]) \[
f(x) = {\color{red}{w_0}} + {\color{magenta}{w_1 x}} + {\color{blue}{w_2 x^2}}
-\] Figure: The set of functions which are combined to form a quadratic basis. This function takes in an \(n\times 1\) dimensional vector and returns an \(n\times 3\) dimensional design matrix containing the basis functions. We can plot those basis functions against there input as follows. The actual function we observe is then made up of a sum of these functions. This is the reason for the name basis. The term basis means ‘the underlying support or foundation for an idea, argument, or process,’ and in this context they form the underlying support for our prediction function. Our prediction function can only be composed of a weighted linear sum of our basis functions. Figure: Functions constructed by weighted sum of the components of a quadratic basis. The rectified linear unit is a basis function that emerged out of the deep learning community. Rectified linear units are popular in the current generation of multilayer perceptron models, or deep networks. These basis functions start flat, and then become linear functions at a certain threshold. \[
+\] Figure: The set of functions which are combined to form a quadratic basis. This function takes in an \(n\times 1\) dimensional vector and returns an \(n\times 3\) dimensional design matrix containing the basis functions. We can plot those basis functions against there input as follows. The actual function we observe is then made up of a sum of these functions. This is the reason for the name basis. The term basis means ‘the underlying support or foundation for an idea, argument, or process’, and in this context they form the underlying support for our prediction function. Our prediction function can only be composed of a weighted linear sum of our basis functions. Figure: Functions constructed by weighted sum of the components of a quadratic basis. The rectified linear unit is a basis function that emerged out of the deep learning community. Rectified linear units are popular in the current generation of multilayer perceptron models, or deep networks. These basis functions start flat, and then become linear functions at a certain threshold. \[
\phi_j(x) = xH(x+ v_j)
-\] Figure: The set of functions which are combined to form a rectified linear unit basis. \[
+\] Figure: The set of functions which are combined to form a rectified linear unit basis. \[
f(x) = \color{red}{w_0} + \color{magenta}{w_1 xH(x+1.0) } + \color{blue}{w_2 xH(x+0.33) } + \color{green}{w_3 xH(x-0.33)} + \color{cyan}{w_4 xH(x-1.0)}
-\] Figure: A rectified linear unit basis is made up of different rectified linear unit functions centered at different points. Models where we model the entire joint distribution of our training data, \(p(\mathbf{ y}, \mathbf{X})\) are sometimes described as generative models. Because we can use sampling to generate data sets that represent all our assumptions. However, as we discussed in the sessions on and , this can be a bad idea, because if our assumptions are wrong then we can make poor predictions. We can try to make more complex assumptions about data to alleviate the problem, but then this typically leads to challenges for tractable application of the sum and rules of probability that are needed to compute the relevant marginal and conditional densities. If we know the form of the question we wish to answer then we typically try and represent that directly, through \(p(\mathbf{ y}|\mathbf{X})\). In practice, we also have been making assumptions of conditional independence given the model parameters, \[
+\] Figure: A rectified linear unit basis is made up of different rectified linear unit functions centered at different points. Models where we model the entire joint distribution of our training data, \(p(\mathbf{ y}, \mathbf{X})\) are sometimes described as generative models. Because we can use sampling to generate data sets that represent all our assumptions. However, as we discussed in the sessions on and , this can be a bad idea, because if our assumptions are wrong then we can make poor predictions. We can try to make more complex assumptions about data to alleviate the problem, but then this typically leads to challenges for tractable application of the sum and rules of probability that are needed to compute the relevant marginal and conditional densities. If we know the form of the question we wish to answer then we typically try and represent that directly, through \(p(\mathbf{ y}|\mathbf{X})\). In practice, we also have been making assumptions of conditional independence given the model parameters, \[
p(\mathbf{ y}|\mathbf{X}, \mathbf{ w}) =
\prod_{i=1}^{n} p(y_i | \mathbf{ x}_i, \mathbf{ w})
\] Gaussian processes are not normally considered to be generative models, but we will be much more interested in the principles of conditioning in Gaussian processes because we will use conditioning to make predictions between our test and training data. We will avoid the data conditional indpendence assumption in favour of a richer assumption about the data, in a Gaussian process we assume data is jointly Gaussian with a particular mean and covariance, \[
\mathbf{ y}|\mathbf{X}\sim \mathscr{N}\left(\mathbf{m}(\mathbf{X}),\mathbf{K}(\mathbf{X})\right),
-\] where the conditioning is on the inputs \(\mathbf{X}\) which are used for computing the mean and covariance. For this reason they are known as mean and covariance functions. However, we are focussing on what happens in models which are non-linear in the inputs, whereas the above would be linear in the inputs. To consider these, we introduce a matrix, called the design matrix. We set each activation function computed at each data point to be \[
+\] where the conditioning is on the inputs \(\mathbf{X}\) which are used for computing the mean and covariance. For this reason they are known as mean and covariance functions. However, we are focussing on what happens in models which are non-linear in the inputs, whereas the above would be linear in the inputs. To consider these, we introduce a matrix, called the design matrix. We set each activation function computed at each data point to be \[
\phi_{i,j} = \phi(\mathbf{ w}^{(1)}_{j}, \mathbf{ x}_{i})
\] and define the matrix of activations (known as the design matrix in statistics) to be, \[
-\boldsymbol{ \Phi}=
+\boldsymbol{ \Phi}=
\begin{bmatrix}
\phi_{1, 1} & \phi_{1, 2} & \dots & \phi_{1, h} \\
\phi_{1, 2} & \phi_{1, 2} & \dots & \phi_{1, n} \\
\vdots & \vdots & \ddots & \vdots \\
\phi_{n, 1} & \phi_{n, 2} & \dots & \phi_{n, h}
\end{bmatrix}.
-\] By convention this matrix always has \(n\) rows and \(h\) columns, now if we define the vector of all noise corruptions, \(\boldsymbol{ \epsilon}= \left[\epsilon_1, \dots \epsilon_n\right]^\top\). If we define the prior distribution over the vector \(\mathbf{ w}\) to be Gaussian, \[
+\] By convention this matrix always has \(n\) rows and \(h\) columns, now if we define the vector of all noise corruptions, \(\boldsymbol{ \epsilon}= \left[\epsilon_1, \dots \epsilon_n\right]^\top\). If we define the prior distribution over the vector \(\mathbf{ w}\) to be Gaussian, \[
\mathbf{ w}\sim \mathscr{N}\left(\mathbf{0},\alpha\mathbf{I}\right),
\] then we can use rules of multivariate Gaussians to see that, \[
\mathbf{ y}\sim \mathscr{N}\left(\mathbf{0},\alpha \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top + \sigma^2 \mathbf{I}\right).
-\] In other words, our training data is distributed as a multivariate Gaussian, with zero mean and a covariance given by \[
+\] In other words, our training data is distributed as a multivariate Gaussian, with zero mean and a covariance given by \[
\mathbf{K}= \alpha \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top + \sigma^2 \mathbf{I}.
-\] This is an \(n\times n\) size matrix. Its elements are in the form of a function. The maths shows that any element, index by \(i\) and \(j\), is a function only of inputs associated with data points \(i\) and \(j\), \(\mathbf{ y}_i\), \(\mathbf{ y}_j\). \(k_{i,j} = k\left(\mathbf{ x}_i, \mathbf{ x}_j\right)\) If we look at the portion of this function associated only with \(f(\cdot)\), i.e. we remove the noise, then we can write down the covariance associated with our neural network, \[
+\] This is an \(n\times n\) size matrix. Its elements are in the form of a function. The maths shows that any element, index by \(i\) and \(j\), is a function only of inputs associated with data points \(i\) and \(j\), \(\mathbf{ y}_i\), \(\mathbf{ y}_j\). \(k_{i,j} = k\left(\mathbf{ x}_i, \mathbf{ x}_j\right)\) If we look at the portion of this function associated only with \(f(\cdot)\), i.e. we remove the noise, then we can write down the covariance associated with our neural network, \[
k_f\left(\mathbf{ x}_i, \mathbf{ x}_j\right) = \alpha \boldsymbol{ \phi}\left(\mathbf{W}_1, \mathbf{ x}_i\right)^\top \boldsymbol{ \phi}\left(\mathbf{W}_1, \mathbf{ x}_j\right)
-\] so the elements of the covariance or kernel matrix are formed by inner products of the rows of the design matrix. This is the essence of a Gaussian process. Instead of making assumptions about our density over each data point, \(y_i\) as i.i.d. we make a joint Gaussian assumption over our data. The covariance matrix is now a function of both the parameters of the activation function, \(\mathbf{V}\), and the input variables, \(\mathbf{X}\). This comes about through integrating out the parameters of the model, \(\mathbf{ w}\). We can basically put anything inside the basis functions, and many people do. These can be deep kernels (Cho and Saul, 2009) or we can learn the parameters of a convolutional neural network inside there. Viewing a neural network in this way is also what allows us to beform sensible batch normalizations (Ioffe and Szegedy, 2015). Another type of basis is sometimes known as a ‘radial basis’ because the effect basis functions are constructed on ‘centres’ and the effect of each basis function decreases as the radial distance from each centre increases. \[
+\] so the elements of the covariance or kernel matrix are formed by inner products of the rows of the design matrix. This is the essence of a Gaussian process. Instead of making assumptions about our density over each data point, \(y_i\) as i.i.d. we make a joint Gaussian assumption over our data. The covariance matrix is now a function of both the parameters of the activation function, \(\mathbf{V}\), and the input variables, \(\mathbf{X}\). This comes about through integrating out the parameters of the model, \(\mathbf{ w}\). We can basically put anything inside the basis functions, and many people do. These can be deep kernels (Cho and Saul, 2009) or we can learn the parameters of a convolutional neural network inside there. Viewing a neural network in this way is also what allows us to beform sensible batch normalizations (Ioffe and Szegedy, 2015). Another type of basis is sometimes known as a ‘radial basis’ because the effect basis functions are constructed on ‘centres’ and the effect of each basis function decreases as the radial distance from each centre increases. \[
\phi_j(x) = \exp\left(-\frac{(x-\mu_j)^2}{\ell^2}\right)
-\] Figure: The set of functions which are combined to form the radial basis. \[
+\] Figure: The set of functions which are combined to form the radial basis. \[
f(x) = \color{red}{w_1 e^{-2(x+1)^2}} + \color{magenta}{w_2e^{-2x^2}} + \color{blue}{w_3 e^{-2(x-1)^2}}
-\] Figure: A radial basis is made up of different locally effective functions centered at different points. To understand the Gaussian process we’re going to build on our understanding of the marginal likelihood for Bayesian regression. In the session on we sampled directly from the weight vector, \(\mathbf{ w}\) and applied it to the basis matrix \(\boldsymbol{ \Phi}\) to obtain a sample from the prior and a sample from the posterior. It is often helpful to think of modeling techniques as generative models. To give some thought as to what the process for obtaining data from the model is. From the perspective of Gaussian processes, we want to start by thinking of basis function models, where the parameters are sampled from a prior, but move to thinking about sampling from the marginal likelihood directly. A very important aspect of probabilistic modelling is to sample from your model to see what type of assumptions you are making about your data. In this case that involves a two stage process. Given a prior variance (as defined above) we can now sample from the prior distribution and combine with a basis set to see what assumptions we are making about the functions a priori (i.e. before we’ve seen the data). Firstly we compute the basis function matrix. We will do it both for our training data, and for a range of prediction locations ( Figure: A radial basis is made up of different locally effective functions centered at different points. To understand the Gaussian process we’re going to build on our understanding of the marginal likelihood for Bayesian regression. In the session on we sampled directly from the weight vector, \(\mathbf{ w}\) and applied it to the basis matrix \(\boldsymbol{ \Phi}\) to obtain a sample from the prior and a sample from the posterior. It is often helpful to think of modeling techniques as generative models. To give some thought as to what the process for obtaining data from the model is. From the perspective of Gaussian processes, we want to start by thinking of basis function models, where the parameters are sampled from a prior, but move to thinking about sampling from the marginal likelihood directly. A very important aspect of probabilistic modelling is to sample from your model to see what type of assumptions you are making about your data. In this case that involves a two stage process. Given a prior variance (as defined above) we can now sample from the prior distribution and combine with a basis set to see what assumptions we are making about the functions a priori (i.e. before we’ve seen the data). Firstly we compute the basis function matrix. We will do it both for our training data, and for a range of prediction locations ( Now let’s build the basis matrices. We define the polynomial basis as follows. Now let’s build the basis matrices. We define the polynomial basis as follows. Now we will sample from the prior to produce a vector \(\mathbf{ w}\) and use it to plot a function which is representative of our belief before we fit the data. To do this we are going to use the properties of the Gaussian density and a sample from a standard normal using the function Let’s use this way of constructing samples from a Gaussian to check what functions look like a priori. The process will be as follows. First, we sample a random vector \(K\) dimensional from Now we will sample from the prior to produce a vector \(\mathbf{ w}\) and use it to plot a function which is representative of our belief before we fit the data. To do this we are going to use the properties of the Gaussian density and a sample from a standard normal using the function Let’s use this way of constructing samples from a Gaussian to check what functions look like a priori. The process will be as follows. First, we sample a random vector \(K\) dimensional from Now we can combine our sample from the prior with the basis functions to create a function, Figure: Prior sample of \(\boldsymbol{ \Phi}\mathbf{ w}\) with \(\mathbf{ w}\) taken from the prior. Note that we have carefully scaled our data using Now we need to recompute the basis functions from above, The prediction function can now be computed. In matrix form, the predictions can be computed as \[
+print(w_sample) Now we can combine our sample from the prior with the basis functions to create a function, Figure: Prior sample of \(\boldsymbol{ \Phi}\mathbf{ w}\) with \(\mathbf{ w}\) taken from the prior. Note that we have carefully scaled our data using Now we need to recompute the basis functions from above, The prediction function can now be computed. In matrix form, the predictions can be computed as \[
\mathbf{ f}_s = \boldsymbol{ \Phi}\mathbf{ w}_s.
-\] This involves a matrix multiplication between a fixed matrix \(\boldsymbol{ \Phi}\) and a vector drawn from a distribution \(p(\mathbf{ w})\). Because \(\mathbf{ w}_s\) is drawn from a distribution, this imples that \(\mathbf{ f}_s\) should also be drawn from a distribution. Now let’s loop through some samples and plot various functions as samples from this system, Figure: Samples of \(\boldsymbol{ \Phi}\mathbf{ w}\) with \(\mathbf{ w}\) taken from the prior. There are two distributions we are interested in though. We have just been sampling from the prior distribution to see what sort of functions we get before looking at the data. In Bayesian inference, we also need to compute the posterior distribution and sample from that density. The process we have used to generate the samples is a two stage process. To obtain each function, we first generated a sample from the prior, \[
+\] This involves a matrix multiplication between a fixed matrix \(\boldsymbol{ \Phi}\) and a vector drawn from a distribution \(p(\mathbf{ w})\). Because \(\mathbf{ w}_s\) is drawn from a distribution, this imples that \(\mathbf{ f}_s\) should also be drawn from a distribution. Now let’s loop through some samples and plot various functions as samples from this system, Figure: Samples of \(\boldsymbol{ \Phi}\mathbf{ w}\) with \(\mathbf{ w}\) taken from the prior. There are two distributions we are interested in though. We have just been sampling from the prior distribution to see what sort of functions we get before looking at the data. In Bayesian inference, we also need to compute the posterior distribution and sample from that density. The process we have used to generate the samples is a two stage process. To obtain each function, we first generated a sample from the prior, \[
\mathbf{ w}\sim \mathscr{N}\left(\mathbf{0},\alpha \mathbf{I}\right)
\] then if we compose our basis matrix, \(\boldsymbol{ \Phi}\) from the basis functions associated with each row then we get, \[
\boldsymbol{ \Phi}= \begin{bmatrix}\boldsymbol{ \phi}(\mathbf{ x}_1) \\ \vdots \\
@@ -330,61 +1262,228 @@
\\ \vdots \\ f_n\end{bmatrix}
\] in the form \[
\mathbf{ f}= \boldsymbol{ \Phi}\mathbf{ w}.
-\] Now we can use standard properties of multivariate Gaussians to write down the probability density that is implied over \(\mathbf{ f}\). In particular we know that if \(\mathbf{ w}\) is sampled from a multivariate normal (or multivariate Gaussian) with covariance \(\alpha \mathbf{I}\) and zero mean, then assuming that \(\boldsymbol{ \Phi}\) is a deterministic matrix (i.e. it is not sampled from a probability density) then the vector \(\mathbf{ f}\) will also be distributed according to a zero mean multivariate normal as follows, \[
+\] Now we can use standard properties of multivariate Gaussians to write down the probability density that is implied over \(\mathbf{ f}\). In particular we know that if \(\mathbf{ w}\) is sampled from a multivariate normal (or multivariate Gaussian) with covariance \(\alpha \mathbf{I}\) and zero mean, then assuming that \(\boldsymbol{ \Phi}\) is a deterministic matrix (i.e. it is not sampled from a probability density) then the vector \(\mathbf{ f}\) will also be distributed according to a zero mean multivariate normal as follows, \[
\mathbf{ f}\sim \mathscr{N}\left(\mathbf{0},\alpha \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top\right).
-\] The question now is, what happens if we sample \(\mathbf{ f}\) directly from this density, rather than first sampling \(\mathbf{ w}\) and then multiplying by \(\boldsymbol{ \Phi}\). Let’s try this. First of all we define the covariance as \[
+\] The question now is, what happens if we sample \(\mathbf{ f}\) directly from this density, rather than first sampling \(\mathbf{ w}\) and then multiplying by \(\boldsymbol{ \Phi}\). Let’s try this. First of all we define the covariance as \[
\mathbf{K}= \alpha
\boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top.
-\] Now we can use the Now we can use the Figure: Samples directly from the covariance function implied by the basis function based covariance, \(\alpha \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top\). The samples appear very similar to those which we obtained indirectly. That is no surprise because they are effectively drawn from the same mutivariate normal density. However, when sampling \(\mathbf{ f}\) directly we created the covariance for \(\mathbf{ f}\). We can visualise the form of this covaraince in an image in python with a colorbar to show scale. Figure: Covariance of the function implied by the basis set \(\alpha\boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top\). This image is the covariance expressed between different points on the function. In regression we normally also add independent Gaussian noise to obtain our observations \(\mathbf{ y}\), \[
+mlai.write_figure('gp-sample-basis-function.svg', directory='./kern') Figure: Samples directly from the covariance function implied by the basis function based covariance, \(\alpha \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top\). The samples appear very similar to those which we obtained indirectly. That is no surprise because they are effectively drawn from the same mutivariate normal density. However, when sampling \(\mathbf{ f}\) directly we created the covariance for \(\mathbf{ f}\). We can visualise the form of this covaraince in an image in python with a colorbar to show scale. Figure: Covariance of the function implied by the basis set \(\alpha\boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top\). This image is the covariance expressed between different points on the function. In regression we normally also add independent Gaussian noise to obtain our observations \(\mathbf{ y}\), \[
\mathbf{ y}= \mathbf{ f}+ \boldsymbol{\epsilon}
\] where the noise is sampled from an independent Gaussian distribution with variance \(\sigma^2\), \[
\epsilon \sim \mathscr{N}\left(\mathbf{0},\sigma^2\mathbf{I}\right).
\] we can use properties of Gaussian variables, i.e. the fact that sum of two Gaussian variables is also Gaussian, and that it’s covariance is given by the sum of the two covariances, whilst the mean is given by the sum of the means, to write down the marginal likelihood, \[
\mathbf{ y}\sim \mathscr{N}\left(\mathbf{0},\boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top +\sigma^2\mathbf{I}\right).
-\] Sampling directly from this density gives us the noise corrupted functions, Figure: Samples directly from the covariance function implied by the noise corrupted basis function based covariance, \(\alpha \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top + \sigma^2 \mathbf{I}\). where the effect of our noise term is to roughen the sampled functions, we can also increase the variance of the noise to see a different effect, Figure: Samples directly from the covariance function implied by the noise corrupted basis function based covariance, \(\alpha \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top + \sigma^2 \mathbf{I}\). where the effect of our noise term is to roughen the sampled functions, we can also increase the variance of the noise to see a different effect, Figure: Samples directly from the covariance function implied by the noise corrupted basis function based covariance, \(\alpha \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top + \mathbf{I}\). The process described above is degenerate. The covariance function is of rank at most \(h\) and since the theoretical amount of data could always increase \(n\rightarrow \infty\), the covariance function is not full rank. This means as we increase the amount of data to infinity, there will come a point where we can’t normalize the process because the multivariate Gaussian has the form, \[
+ directory='./kern') Figure: Samples directly from the covariance function implied by the noise corrupted basis function based covariance, \(\alpha \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top + \mathbf{I}\). The process described above is degenerate. The covariance function is of rank at most \(h\) and since the theoretical amount of data could always increase \(n\rightarrow \infty\), the covariance function is not full rank. This means as we increase the amount of data to infinity, there will come a point where we can’t normalize the process because the multivariate Gaussian has the form, \[
\mathscr{N}\left(\mathbf{ f}|\mathbf{0},\mathbf{K}\right) = \frac{1}{\left(2\pi\right)^{\frac{n}{2}}\det{\mathbf{K}}^\frac{1}{2}} \exp\left(-\frac{\mathbf{ f}^\top\mathbf{K}\mathbf{ f}}{2}\right)
-\] and a non-degenerate kernel matrix leads to \(\det{\mathbf{K}} = 0\) defeating the normalization (it’s equivalent to finding a projection in the high dimensional Gaussian where the variance of the the resulting univariate Gaussian is zero, i.e. there is a null space on the covariance, or alternatively you can imagine there are one or more directions where the Gaussian has become the delta function). In the machine learning field, it was Radford Neal (Neal, 1994) that realized the potential of the next step. In his 1994 thesis, he was considering Bayesian neural networks, of the type we described above, and in considered what would happen if you took the number of hidden nodes, or neurons, to infinity, i.e. \(h\rightarrow \infty\). Figure: Page 37 of Radford Neal’s 1994 thesis In loose terms, what Radford considers is what happens to the elements of the covariance function, \[
+\] and a non-degenerate kernel matrix leads to \(\det{\mathbf{K}} = 0\) defeating the normalization (it’s equivalent to finding a projection in the high dimensional Gaussian where the variance of the the resulting univariate Gaussian is zero, i.e. there is a null space on the covariance, or alternatively you can imagine there are one or more directions where the Gaussian has become the delta function). In the machine learning field, it was Radford Neal (Neal, 1994) that realized the potential of the next step. In his 1994 thesis, he was considering Bayesian neural networks, of the type we described above, and in considered what would happen if you took the number of hidden nodes, or neurons, to infinity, i.e. \(h\rightarrow \infty\). In loose terms, what Radford considers is what happens to the elements of the covariance function, \[
\begin{align*}
k_f\left(\mathbf{ x}_i, \mathbf{ x}_j\right) & = \alpha \boldsymbol{ \phi}\left(\mathbf{W}_1, \mathbf{ x}_i\right)^\top \boldsymbol{ \phi}\left(\mathbf{W}_1, \mathbf{ x}_j\right)\\
& = \alpha \sum_k \phi\left(\mathbf{ w}^{(1)}_k, \mathbf{ x}_i\right) \phi\left(\mathbf{ w}^{(1)}_k, \mathbf{ x}_j\right)
\end{align*}
- \] if instead of considering a finite number you sample infinitely many of these activation functions, sampling parameters from a prior density, \(p(\mathbf{ v})\), for each one, \[
+ \] if instead of considering a finite number you sample infinitely many of these activation functions, sampling parameters from a prior density, \(p(\mathbf{ v})\), for each one, \[
k_f\left(\mathbf{ x}_i, \mathbf{ x}_j\right) = \alpha \int \phi\left(\mathbf{ w}^{(1)}, \mathbf{ x}_i\right) \phi\left(\mathbf{ w}^{(1)}, \mathbf{ x}_j\right) p(\mathbf{ w}^{(1)}) \text{d}\mathbf{ w}^{(1)}
-\] And that’s not only for Gaussian \(p(\mathbf{ v})\). In fact this result holds for a range of activations, and a range of prior densities because of the central limit theorem. To write it in the form of a probabilistic program, as long as the distribution for \(\phi_i\) implied by this short probabilistic program, \[
+\] And that’s not only for Gaussian \(p(\mathbf{ v})\). In fact this result holds for a range of activations, and a range of prior densities because of the central limit theorem. To write it in the form of a probabilistic program, as long as the distribution for \(\phi_i\) implied by this short probabilistic program, \[
\begin{align*}
\mathbf{ v}& \sim p(\cdot)\\
- \phi_i & = \phi\left(\mathbf{ v}, \mathbf{ x}_i\right),
+ \phi_i & = \phi\left(\mathbf{ v}, \mathbf{ x}_i\right),
\end{align*}
- \] has finite variance, then the result of taking the number of hidden units to infinity, with appropriate scaling, is also a Gaussian process. To understand this argument in more detail, I highly recommend reading chapter 2 of Neal’s thesis (Neal, 1994), which remains easy to read and clear today. Indeed, for readers interested in Bayesian neural networks, both Raford Neal’s and David MacKay’s PhD thesis (MacKay, 1992) remain essential reading. Both theses embody a clarity of thought, and an ability to weave together threads from different fields that was the business of machine learning in the 1990s. Radford and David were also pioneers in making their software widely available and publishing material on the web. In our we sampled from the prior over paraemters. Through the properties of multivariate Gaussian densities this prior over parameters implies a particular density for our data observations, \(\mathbf{ y}\). In this session we sampled directly from this distribution for our data, avoiding the intermediate weight-space representation. This is the approach taken by Gaussian processes. In a Gaussian process you specify the covariance function directly, rather than implicitly through a basis matrix and a prior over parameters. Gaussian processes have the advantage that they can be nonparametric, which in simple terms means that they can have infinite basis functions. In the lectures we introduced the exponentiated quadratic covariance, also known as the RBF or the Gaussian or the squared exponential covariance function. This covariance function is specified by \[
+ \] has finite variance, then the result of taking the number of hidden units to infinity, with appropriate scaling, is also a Gaussian process. To understand this argument in more detail, I highly recommend reading chapter 2 of Neal’s thesis (Neal, 1994), which remains easy to read and clear today. Indeed, for readers interested in Bayesian neural networks, both Raford Neal’s and David MacKay’s PhD thesis (MacKay, 1992) remain essential reading. Both theses embody a clarity of thought, and an ability to weave together threads from different fields that was the business of machine learning in the 1990s. Radford and David were also pioneers in making their software widely available and publishing material on the web. In our we sampled from the prior over paraemters. Through the properties of multivariate Gaussian densities this prior over parameters implies a particular density for our data observations, \(\mathbf{ y}\). In this session we sampled directly from this distribution for our data, avoiding the intermediate weight-space representation. This is the approach taken by Gaussian processes. In a Gaussian process you specify the covariance function directly, rather than implicitly through a basis matrix and a prior over parameters. Gaussian processes have the advantage that they can be nonparametric, which in simple terms means that they can have infinite basis functions. In the lectures we introduced the exponentiated quadratic covariance, also known as the RBF or the Gaussian or the squared exponential covariance function. This covariance function is specified by \[
k(\mathbf{ x}, \mathbf{ x}^\prime) = \alpha \exp\left( -\frac{\left\Vert \mathbf{ x}-\mathbf{ x}^\prime\right\Vert^2}{2\ell^2}\right),
\] where \(\left\Vert\mathbf{ x}- \mathbf{ x}^\prime\right\Vert^2\) is the squared distance between the two input vectors \[
-\left\Vert\mathbf{ x}- \mathbf{ x}^\prime\right\Vert^2 = (\mathbf{ x}- \mathbf{ x}^\prime)^\top (\mathbf{ x}- \mathbf{ x}^\prime)
-\] Let’s build a covariance matrix based on this function. First we define the form of the covariance function, We can use this to compute directly the covariance for \(\mathbf{ f}\) at the points given by Now we can image the resulting covariance, To visualise the covariance between the points we can use the Finally, we can sample functions from the marginal likelihood. Moving Parameters Have a play with the parameters for this covariance function (the lengthscale and the variance) and see what effects the parameters have on the types of functions you observe. One view of Bayesian inference is to assume we are given a mechanism for generating samples, where we assume that mechanism is representing an accurate view on the way we believe the world works. This mechanism is known as our prior belief. We combine our prior belief with our observations of the real world by discarding all those prior samples that are inconsistent with our observations. The likelihood defines mathematically what we mean by inconsistent with the observations. The higher the noise level in the likelihood, the looser the notion of consistent. The samples that remain are samples from the posterior. This approach to Bayesian inference is closely related to two sampling techniques known as rejection sampling and importance sampling. It is realized in practice in an approach known as approximate Bayesian computation (ABC) or likelihood-free inference. In practice, the algorithm is often too slow to be practical, because most samples will be inconsistent with the observations and as a result the mechanism must be operated many times to obtain a few posterior samples. However, in the Gaussian process case, when the likelihood also assumes Gaussian noise, we can operate this mechanism mathematically, and obtain the posterior density analytically. This is the benefit of Gaussian processes. First, we will load in two python functions for computing the covariance function. Next, we sample from a multivariate normal density (a multivariate Gaussian), using the covariance function as the covariance matrix. Figure: One view of Bayesian inference is we have a machine for generating samples (the prior), and we discard all samples inconsistent with our data, leaving the samples of interest (the posterior). This is a rejection sampling view of Bayesian inference. The Gaussian process allows us to do this analytically by multiplying the prior by the likelihood. The Gaussian process perspective takes the marginal likelihood of the data to be a joint Gaussian density with a covariance given by \(\mathbf{K}\). So the model likelihood is of the form, \[
+\left\Vert\mathbf{ x}- \mathbf{ x}^\prime\right\Vert^2 = (\mathbf{ x}- \mathbf{ x}^\prime)^\top (\mathbf{ x}- \mathbf{ x}^\prime)
+\] Let’s build a covariance matrix based on this function. First we define the form of the covariance function, We can use this to compute directly the covariance for \(\mathbf{ f}\) at the points given by Now we can image the resulting covariance, To visualise the covariance between the points we can use the Finally, we can sample functions from the marginal likelihood. Moving Parameters Have a play with the parameters for this covariance function (the lengthscale and the variance) and see what effects the parameters have on the types of functions you observe. One view of Bayesian inference is to assume we are given a mechanism for generating samples, where we assume that mechanism is representing an accurate view on the way we believe the world works. This mechanism is known as our prior belief. We combine our prior belief with our observations of the real world by discarding all those prior samples that are inconsistent with our observations. The likelihood defines mathematically what we mean by inconsistent with the observations. The higher the noise level in the likelihood, the looser the notion of consistent. The samples that remain are samples from the posterior. This approach to Bayesian inference is closely related to two sampling techniques known as rejection sampling and importance sampling. It is realized in practice in an approach known as approximate Bayesian computation (ABC) or likelihood-free inference. In practice, the algorithm is often too slow to be practical, because most samples will be inconsistent with the observations and as a result the mechanism must be operated many times to obtain a few posterior samples. However, in the Gaussian process case, when the likelihood also assumes Gaussian noise, we can operate this mechanism mathematically, and obtain the posterior density analytically. This is the benefit of Gaussian processes. First, we will load in two python functions for computing the covariance function. Next, we sample from a multivariate normal density (a multivariate Gaussian), using the covariance function as the covariance matrix. Figure: One view of Bayesian inference is we have a machine for generating samples (the prior), and we discard all samples inconsistent with our data, leaving the samples of interest (the posterior). This is a rejection sampling view of Bayesian inference. The Gaussian process allows us to do this analytically by multiplying the prior by the likelihood. The Gaussian process perspective takes the marginal likelihood of the data to be a joint Gaussian density with a covariance given by \(\mathbf{K}\). So the model likelihood is of the form, \[
p(\mathbf{ y}|\mathbf{X}) =
\frac{1}{(2\pi)^{\frac{n}{2}}|\mathbf{K}|^{\frac{1}{2}}}
\exp\left(-\frac{1}{2}\mathbf{ y}^\top \left(\mathbf{K}+\sigma^2
\mathbf{I}\right)^{-1}\mathbf{ y}\right)
-\] where the input data, \(\mathbf{X}\), influences the density through the covariance matrix, \(\mathbf{K}\) whose elements are computed through the covariance function, \(k(\mathbf{ x}, \mathbf{ x}^\prime)\). This means that the negative log likelihood (the objective function) is given by, \[
+\] where the input data, \(\mathbf{X}\), influences the density through the covariance matrix, \(\mathbf{K}\) whose elements are computed through the covariance function, \(k(\mathbf{ x}, \mathbf{ x}^\prime)\). This means that the negative log likelihood (the objective function) is given by, \[
E(\boldsymbol{\theta}) = \frac{1}{2} \log |\mathbf{K}|
+ \frac{1}{2} \mathbf{ y}^\top \left(\mathbf{K}+
\sigma^2\mathbf{I}\right)^{-1}\mathbf{ y}
-\] where the parameters of the model are also embedded in the covariance function, they include the parameters of the kernel (such as lengthscale and variance), and the noise variance, \(\sigma^2\). Let’s create a set of classes in python for storing these variables. We now have a probability density that represents functions. How do we make predictions with this density? The density is known as a process because it is consistent. By consistency, here, we mean that the model makes predictions for \(\mathbf{ f}\) that are unaffected by future values of \(\mathbf{ f}^*\) that are currently unobserved (such as test points). If we think of \(\mathbf{ f}^*\) as test points, we can still write down a joint probability density over the training observations, \(\mathbf{ f}\) and the test observations, \(\mathbf{ f}^*\). This joint probability density will be Gaussian, with a covariance matrix given by our covariance function, \(k(\mathbf{ x}_i, \mathbf{ x}_j)\). \[
+\] where the parameters of the model are also embedded in the covariance function, they include the parameters of the kernel (such as lengthscale and variance), and the noise variance, \(\sigma^2\). Let’s create a set of classes in python for storing these variables. We now have a probability density that represents functions. How do we make predictions with this density? The density is known as a process because it is consistent. By consistency, here, we mean that the model makes predictions for \(\mathbf{ f}\) that are unaffected by future values of \(\mathbf{ f}^*\) that are currently unobserved (such as test points). If we think of \(\mathbf{ f}^*\) as test points, we can still write down a joint probability density over the training observations, \(\mathbf{ f}\) and the test observations, \(\mathbf{ f}^*\). This joint probability density will be Gaussian, with a covariance matrix given by our covariance function, \(k(\mathbf{ x}_i, \mathbf{ x}_j)\). \[
\begin{bmatrix}\mathbf{ f}\\ \mathbf{ f}^*\end{bmatrix} \sim \mathscr{N}\left(\mathbf{0},\begin{bmatrix} \mathbf{K}& \mathbf{K}_\ast \\
\mathbf{K}_\ast^\top & \mathbf{K}_{\ast,\ast}\end{bmatrix}\right)
-\] where here \(\mathbf{K}\) is the covariance computed between all the training points, \(\mathbf{K}_\ast\) is the covariance matrix computed between the training points and the test points and \(\mathbf{K}_{\ast,\ast}\) is the covariance matrix computed betwen all the tests points and themselves. To be clear, let’s compute these now for our example, using Now we use this structure to visualise the covariance between test data and training data. This structure is how information is passed between test and training data. Unlike the maximum likelihood formalisms we’ve been considering so far, the structure expresses correlation between our different data points. However, just like the we now have a joint density between some variables of interest. In particular we have the joint density over \(p(\mathbf{ f}, \mathbf{ f}^*)\). The joint density is Gaussian and zero mean. It is specified entirely by the covariance matrix, \(\mathbf{K}\). That covariance matrix is, in turn, defined by a covariance function. Now we will visualise the form of that covariance in the form of the matrix, \[
+K_starstar = kernel.K(x_pred, x_pred) Now we use this structure to visualise the covariance between test data and training data. This structure is how information is passed between test and training data. Unlike the maximum likelihood formalisms we’ve been considering so far, the structure expresses correlation between our different data points. However, just like the we now have a joint density between some variables of interest. In particular we have the joint density over \(p(\mathbf{ f}, \mathbf{ f}^*)\). The joint density is Gaussian and zero mean. It is specified entirely by the covariance matrix, \(\mathbf{K}\). That covariance matrix is, in turn, defined by a covariance function. Now we will visualise the form of that covariance in the form of the matrix, \[
\begin{bmatrix} \mathbf{K}& \mathbf{K}_\ast \\ \mathbf{K}_\ast^\top
& \mathbf{K}_{\ast,\ast}\end{bmatrix}
-\] Figure: Different blocks of the covariance function. The upper left block is the covariance of the training data with itself, \(\mathbf{K}\). The top right is the cross covariance between training data (rows) and prediction locations (columns). The lower left is the same matrix transposed. The bottom right is the covariance matrix of the test data with itself. There are four blocks to this plot. The upper left block is the covariance of the training data with itself, \(\mathbf{K}\). We see some structure here due to the missing data from the first and second world wars. Alongside this covariance (to the right and below) we see the cross covariance between the training and the test data (\(\mathbf{K}_*\) and \(\mathbf{K}_*^\top\)). This is giving us the covariation between our training and our test data. Finally the lower right block The banded structure we now observe is because some of the training points are near to some of the test points. This is how we obtain ‘communication’ between our training data and our test data. If there is no structure in \(\mathbf{K}_*\) then our belief about the test data simply matches our prior. We will consider a multivariate Gaussian with a particular structure of covariance matrix. We will generate a single sample from this 25 dimensional Gaussian density. \[
+\] Figure: Different blocks of the covariance function. The upper left block is the covariance of the training data with itself, \(\mathbf{K}\). The top right is the cross covariance between training data (rows) and prediction locations (columns). The lower left is the same matrix transposed. The bottom right is the covariance matrix of the test data with itself. There are four blocks to this plot. The upper left block is the covariance of the training data with itself, \(\mathbf{K}\). We see some structure here due to the missing data from the first and second world wars. Alongside this covariance (to the right and below) we see the cross covariance between the training and the test data (\(\mathbf{K}_*\) and \(\mathbf{K}_*^\top\)). This is giving us the covariation between our training and our test data. Finally the lower right block The banded structure we now observe is because some of the training points are near to some of the test points. This is how we obtain ‘communication’ between our training data and our test data. If there is no structure in \(\mathbf{K}_*\) then our belief about the test data simply matches our prior. We will consider a multivariate Gaussian with a particular structure of covariance matrix. We will generate a single sample from this 25 dimensional Gaussian density. \[
\mathbf{ f}=\left[f_{1},f_{2}\dots f_{25}\right].
-\] in the figure below we plot these data on the \(y\)-axis against their indices on the \(x\)-axis. Figure: The joint Gaussian over \(f_1\) and \(f_2\) along with the conditional distribution of \(f_2\) given \(f_1\) Figure: The joint Gaussian over \(f_1\) and \(f_2\) along with the conditional distribution of \(f_2\) given \(f_1\) Figure: Uluru, the sacred rock in Australia. If we think of it as a probability density, viewing it from this side gives us one marginal from the density. Figuratively speaking, slicing through the rock would give a conditional density. When viewing these contour plots, I sometimes find it helpful to think of Uluru, the prominent rock formation in Australia. The rock rises above the surface of the plane, just like a probability density rising above the zero line. The rock is three dimensional, but when we view Uluru from the classical position, we are looking at one side of it. This is equivalent to viewing the marginal density. The joint density can be viewed from above, using contours. The conditional density is equivalent to slicing the rock. Uluru is a holy rock, so this has to be an imaginary slice. Imagine we cut down a vertical plane orthogonal to our view point (e.g. coming across our view point). This would give a profile of the rock, which when renormalized, would give us the conditional distribution, the value of conditioning would be the location of the slice in the direction we are facing. Of course in practice, rather than manipulating mountains physically, the advantage of the Gaussian density is that we can perform these manipulations mathematically. Prediction of \(f_2\) given \(f_1\) requires the conditional density, \(p(f_2|f_1)\).Another remarkable property of the Gaussian density is that this conditional distribution is also guaranteed to be a Gaussian density. It has the form, \[
+\] in the figure below we plot these data on the \(y\)-axis against their indices on the \(x\)-axis. Figure: The joint Gaussian over \(f_1\) and \(f_2\) along with the conditional distribution of \(f_2\) given \(f_1\) Figure: The joint Gaussian over \(f_1\) and \(f_2\) along with the conditional distribution of \(f_2\) given \(f_1\) Figure: Uluru, the sacred rock in Australia. If we think of it as a probability density, viewing it from this side gives us one marginal from the density. Figuratively speaking, slicing through the rock would give a conditional density. When viewing these contour plots, I sometimes find it helpful to think of Uluru, the prominent rock formation in Australia. The rock rises above the surface of the plane, just like a probability density rising above the zero line. The rock is three dimensional, but when we view Uluru from the classical position, we are looking at one side of it. This is equivalent to viewing the marginal density. The joint density can be viewed from above, using contours. The conditional density is equivalent to slicing the rock. Uluru is a holy rock, so this has to be an imaginary slice. Imagine we cut down a vertical plane orthogonal to our view point (e.g. coming across our view point). This would give a profile of the rock, which when renormalized, would give us the conditional distribution, the value of conditioning would be the location of the slice in the direction we are facing. Of course in practice, rather than manipulating mountains physically, the advantage of the Gaussian density is that we can perform these manipulations mathematically. Prediction of \(f_2\) given \(f_1\) requires the conditional density, \(p(f_2|f_1)\).Another remarkable property of the Gaussian density is that this conditional distribution is also guaranteed to be a Gaussian density. It has the form, \[
p(f_2|f_1) = \mathscr{N}\left(f_2|\frac{k_{1, 2}}{k_{1, 1}}f_1, k_{2, 2} - \frac{k_{1,2}^2}{k_{1,1}}\right)
\]where we have assumed that the covariance of the original joint density was given by \[
\mathbf{K}= \begin{bmatrix} k_{1, 1} & k_{1, 2}\\ k_{2, 1} & k_{2, 2}.\end{bmatrix}
-\] Using these formulae we can determine the conditional density for any of the elements of our vector \(\mathbf{ f}\). For example, the variable \(f_8\) is less correlated with \(f_1\) than \(f_2\). If we consider this variable we see the conditional density is more diffuse. Figure: Sample from the joint Gaussian model, points indexed by 1 and 8 highlighted. Figure: The joint Gaussian over \(f_1\) and \(f_8\) along with the conditional distribution of \(f_8\) given \(f_1\) Conditional density: \(p(f_8|f_1=?)\). Prediction of \(\mathbf{ f}_*\) from \(\mathbf{ f}\). Multivariate conditional density is also Gaussian. \[
+\] Using these formulae we can determine the conditional density for any of the elements of our vector \(\mathbf{ f}\). For example, the variable \(f_8\) is less correlated with \(f_1\) than \(f_2\). If we consider this variable we see the conditional density is more diffuse. Figure: Sample from the joint Gaussian model, points indexed by 1 and 8 highlighted. Figure: The joint Gaussian over \(f_1\) and \(f_8\) along with the conditional distribution of \(f_8\) given \(f_1\) . . . . . . Conditional density: \(p(f_8|f_1=?)\). Prediction of \(\mathbf{ f}_*\) from \(\mathbf{ f}\). Multivariate conditional density is also Gaussian. \[
p(\mathbf{ f}_*|\mathbf{ f}) = {\mathcal{N}\left(\mathbf{ f}_*|\mathbf{K}_{*,\mathbf{ f}}\mathbf{K}_{\mathbf{ f},\mathbf{ f}}^{-1}\mathbf{ f},\mathbf{K}_{*,*}-\mathbf{K}_{*,\mathbf{ f}} \mathbf{K}_{\mathbf{ f},\mathbf{ f}}^{-1}\mathbf{K}_{\mathbf{ f},*}\right)}
-\] Here covariance of joint density is given by \[
+\] Here covariance of joint density is given by \[
\mathbf{K}= \begin{bmatrix} \mathbf{K}_{\mathbf{ f}, \mathbf{ f}} & \mathbf{K}_{*, \mathbf{ f}}\\ \mathbf{K}_{\mathbf{ f}, *} & \mathbf{K}_{*, *}\end{bmatrix}
-\] Prediction of \(\mathbf{ f}_*\) from \(\mathbf{ f}\). Multivariate conditional density is also Gaussian. \[
+\] Prediction of \(\mathbf{ f}_*\) from \(\mathbf{ f}\). Multivariate conditional density is also Gaussian. \[
p(\mathbf{ f}_*|\mathbf{ f}) = {\mathcal{N}\left(\mathbf{ f}_*|\boldsymbol{ \mu},\boldsymbol{ \Sigma}\right)}
\] \[
\boldsymbol{ \mu}= \mathbf{K}_{*,\mathbf{ f}}\mathbf{K}_{\mathbf{ f},\mathbf{ f}}^{-1}\mathbf{ f}
\] \[
\boldsymbol{ \Sigma}= \mathbf{K}_{*,*}-\mathbf{K}_{*,\mathbf{ f}} \mathbf{K}_{\mathbf{ f},\mathbf{ f}}^{-1}\mathbf{K}_{\mathbf{ f},*}
-\] Here covariance of joint density is given by \[
+\] Here covariance of joint density is given by \[
\mathbf{K}= \begin{bmatrix} \mathbf{K}_{\mathbf{ f}, \mathbf{ f}} & \mathbf{K}_{*, \mathbf{ f}}\\ \mathbf{K}_{\mathbf{ f}, *} & \mathbf{K}_{*, *}\end{bmatrix}
-\] The covariance function encapsulates our assumptions about the data. The equations for the distribution of the prediction function, given the training observations, are highly sensitive to the covariation between the test locations and the training locations as expressed by the matrix \(\mathbf{K}_*\). We defined a matrix \(\mathbf{A}\) which allowed us to express our conditional mean in the form, \[
+\] The covariance function encapsulates our assumptions about the data. The equations for the distribution of the prediction function, given the training observations, are highly sensitive to the covariation between the test locations and the training locations as expressed by the matrix \(\mathbf{K}_*\). We defined a matrix \(\mathbf{A}\) which allowed us to express our conditional mean in the form, \[
\boldsymbol{ \mu}_f= \mathbf{A}^\top \mathbf{ y},
-\] where \(\mathbf{ y}\) were our training observations. In other words our mean predictions are always a linear weighted combination of our training data. The weights are given by computing the covariation between the training and the test data (\(\mathbf{K}_*\)) and scaling it by the inverse covariance of the training data observations, \(\left[\mathbf{K}+ \sigma^2 \mathbf{I}\right]^{-1}\). This inverse is the main computational object that needs to be resolved for a Gaussian process. It has a computational burden which is \(O(n^3)\) and a storage burden which is \(O(n^2)\). This makes working with Gaussian processes computationally intensive for the situation where \(n>10,000\). Figure: Introduction to Gaussian processes given by Neil Lawrence at the 2014 Gaussian process Winter School at the University of Sheffield. In practice we shouldn’t be using matrix inverse directly to solve the GP system. One more stable way is to compute the Cholesky decomposition of the kernel matrix. The log determinant of the covariance can also be derived from the Cholesky decomposition. Gaussian processes are sometimes seen as part of a wider family of methods known as kernel methods. Kernel methods are also based around covariance functions, but in the field they are known as Mercer kernels. Mercer kernels have interpretations as inner products in potentially infinite dimensional Hilbert spaces. This interpretation arises because, if we take \(\alpha=1\), then the kernel can be expressed as \[
-\mathbf{K}= \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top
+\] where \(\mathbf{ y}\) were our training observations. In other words our mean predictions are always a linear weighted combination of our training data. The weights are given by computing the covariation between the training and the test data (\(\mathbf{K}_*\)) and scaling it by the inverse covariance of the training data observations, \(\left[\mathbf{K}+ \sigma^2 \mathbf{I}\right]^{-1}\). This inverse is the main computational object that needs to be resolved for a Gaussian process. It has a computational burden which is \(O(n^3)\) and a storage burden which is \(O(n^2)\). This makes working with Gaussian processes computationally intensive for the situation where \(n>10,000\). Figure: Introduction to Gaussian processes given by Neil Lawrence at the 2014 Gaussian process Winter School at the University of Sheffield. In practice we shouldn’t be using matrix inverse directly to solve the GP system. One more stable way is to compute the Cholesky decomposition of the kernel matrix. The log determinant of the covariance can also be derived from the Cholesky decomposition. Gaussian processes are sometimes seen as part of a wider family of methods known as kernel methods. Kernel methods are also based around covariance functions, but in the field they are known as Mercer kernels. Mercer kernels have interpretations as inner products in potentially infinite dimensional Hilbert spaces. This interpretation arises because, if we take \(\alpha=1\), then the kernel can be expressed as \[
+\mathbf{K}= \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top
\] which imples the elements of the kernel are given by, \[
k(\mathbf{ x}, \mathbf{ x}^\prime) = \boldsymbol{ \phi}(\mathbf{ x})^\top \boldsymbol{ \phi}(\mathbf{ x}^\prime).
-\] So we see that the kernel function is developed from an inner product between the basis functions. Mercer’s theorem tells us that any valid positive definite function can be expressed as this inner product but with the caveat that the inner product could be infinite length. This idea has been used quite widely to kernelize algorithms that depend on inner products. The kernel functions are equivalent to covariance functions and they are parameterized accordingly. In the kernel modeling community it is generally accepted that kernel parameter estimation is a difficult problem and the normal solution is to cross validate to obtain parameters. This can cause difficulties when a large number of kernel parameters need to be estimated. In Gaussian process modelling kernel parameter estimation (in the simplest case proceeds) by maximum likelihood. This involves taking gradients of the likelihood with respect to the parameters of the covariance function. The easiest conceptual way to obtain the gradients is a two step process. The first step involves taking the gradient of the likelihood with respect to the covariance function, the second step involves considering the gradient of the covariance function with respect to its parameters. In general we won’t be able to find parameters of the covariance function through fixed point equations, we will need to do gradient based optimization. The objective function can be decomposed into two terms, a capacity control term, and a data fit term. The capacity control term is the log determinant of the covariance. The data fit term is the matrix inner product between the data and the inverse covariance. Can we determine covariance parameters from the data? \[
+\] So we see that the kernel function is developed from an inner product between the basis functions. Mercer’s theorem tells us that any valid positive definite function can be expressed as this inner product but with the caveat that the inner product could be infinite length. This idea has been used quite widely to kernelize algorithms that depend on inner products. The kernel functions are equivalent to covariance functions and they are parameterized accordingly. In the kernel modeling community it is generally accepted that kernel parameter estimation is a difficult problem and the normal solution is to cross validate to obtain parameters. This can cause difficulties when a large number of kernel parameters need to be estimated. In Gaussian process modelling kernel parameter estimation (in the simplest case proceeds) by maximum likelihood. This involves taking gradients of the likelihood with respect to the parameters of the covariance function. The easiest conceptual way to obtain the gradients is a two step process. The first step involves taking the gradient of the likelihood with respect to the covariance function, the second step involves considering the gradient of the covariance function with respect to its parameters. In general we won’t be able to find parameters of the covariance function through fixed point equations, we will need to do gradient based optimization. The objective function can be decomposed into two terms, a capacity control term, and a data fit term. The capacity control term is the log determinant of the covariance. The data fit term is the matrix inner product between the data and the inverse covariance. Can we determine covariance parameters from the data? \[
\mathscr{N}\left(\mathbf{ y}|\mathbf{0},\mathbf{K}\right)=\frac{1}{(2\pi)^\frac{n}{2}{\det{\mathbf{K}}^{\frac{1}{2}}}}{\exp\left(-\frac{\mathbf{ y}^{\top}\mathbf{K}^{-1}\mathbf{ y}}{2}\right)}
-\] \[
+\] \[
\begin{aligned}
\mathscr{N}\left(\mathbf{ y}|\mathbf{0},\mathbf{K}\right)=\frac{1}{(2\pi)^\frac{n}{2}\color{blue}{\det{\mathbf{K}}^{\frac{1}{2}}}}\color{red}{\exp\left(-\frac{\mathbf{ y}^{\top}\mathbf{K}^{-1}\mathbf{ y}}{2}\right)}
\end{aligned}
-\] \[
+\] \[
\begin{aligned}
\log \mathscr{N}\left(\mathbf{ y}|\mathbf{0},\mathbf{K}\right)=&\color{blue}{-\frac{1}{2}\log\det{\mathbf{K}}}\color{red}{-\frac{\mathbf{ y}^{\top}\mathbf{K}^{-1}\mathbf{ y}}{2}} \\ &-\frac{n}{2}\log2\pi
\end{aligned}
-\] \[
+\] \[
E(\boldsymbol{ \theta}) = \color{blue}{\frac{1}{2}\log\det{\mathbf{K}}} + \color{red}{\frac{\mathbf{ y}^{\top}\mathbf{K}^{-1}\mathbf{ y}}{2}}
-\] The parameters are inside the covariance function (matrix). \[k_{i, j} = k(\mathbf{ x}_i, \mathbf{ x}_j; \boldsymbol{ \theta})\] \[\mathbf{K}= \mathbf{R}\boldsymbol{ \Lambda}^2 \mathbf{R}^\top\] Figure: The determinant of the covariance is dependent only on the eigenvalues. It represents the ‘footprint’ of the Gaussian. Figure: The data fit term of the Gaussian process is a quadratic loss centered around zero. This has eliptical contours, the principal axes of which are given by the covariance matrix. The parameters are inside the covariance function (matrix). \[k_{i, j} = k(\mathbf{ x}_i, \mathbf{ x}_j; \boldsymbol{ \theta})\] \[\mathbf{K}= \mathbf{R}\boldsymbol{ \Lambda}^2 \mathbf{R}^\top\] Figure: The determinant of the covariance is dependent only on the eigenvalues. It represents the ‘footprint’ of the Gaussian. Figure: The data fit term of the Gaussian process is a quadratic loss centered around zero. This has eliptical contours, the principal axes of which are given by the covariance matrix. Figure: Variation in the data fit term, the capacity term and the negative log likelihood for different lengthscales. The exponentiated quadratic covariance, also known as the Gaussian covariance or the RBF covariance and the squared exponential. Covariance between two points is related to the negative exponential of the squared distnace between those points. This covariance function can be derived in a few different ways: as the infinite limit of a radial basis function neural network, as diffusion in the heat equation, as a Gaussian filter in Fourier space or as the composition as a series of linear filters applied to a base function. The covariance takes the following form, \[
+gp = GP(x, y, sigma2=0.01, kernel=kernel) Figure: Variation in the data fit term, the capacity term and the negative log likelihood for different lengthscales. The exponentiated quadratic covariance, also known as the Gaussian covariance or the RBF covariance and the squared exponential. Covariance between two points is related to the negative exponential of the squared distnace between those points. This covariance function can be derived in a few different ways: as the infinite limit of a radial basis function neural network, as diffusion in the heat equation, as a Gaussian filter in Fourier space or as the composition as a series of linear filters applied to a base function. The covariance takes the following form, \[
k(\mathbf{ x}, \mathbf{ x}^\prime) = \alpha \exp\left(-\frac{\left\Vert \mathbf{ x}-\mathbf{ x}^\prime \right\Vert_2^2}{2\ell^2}\right)
-\] where \(\ell\) is the length scale or time scale of the process and \(\alpha\) represents the overall process variance. Figure: The exponentiated quadratic covariance function. If you’re interested in finding out more about Gaussian processes, you can attend the Gaussian process summer school, or view the lectures and material on line. Details of the school, future events and past events can be found at the website http://gpss.cc. Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. This GPy tutorial is based on material we share in the Gaussian process summer school for teaching these models https://gpss.cc. It contains material from various members and former members of the Sheffield machine learning group, but particular mention should be made of Nicolas Durrande and James Hensman, see http://gpss.cc/gpss17/labs/GPSS_Lab1_2017.ipynb. To give a feel for the software we’ll start by creating an exponentiated quadratic covariance function, \[
+\] where \(\ell\) is the length scale or time scale of the process and \(\alpha\) represents the overall process variance. Figure: The exponentiated quadratic covariance function. If you’re interested in finding out more about Gaussian processes, you can attend the Gaussian process summer school, or view the lectures and material on line. Details of the school, future events and past events can be found at the website http://gpss.cc. Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. This GPy tutorial is based on material we share in the Gaussian process summer school for teaching these models https://gpss.cc. It contains material from various members and former members of the Sheffield machine learning group, but particular mention should be made of Nicolas Durrande and James Hensman, see http://gpss.cc/gpss17/labs/GPSS_Lab1_2017.ipynb. To give a feel for the software we’ll start by creating an exponentiated quadratic covariance function, \[
k(\mathbf{ x}, \mathbf{ x}^\prime) = \alpha \exp\left(-\frac{\left\Vert \mathbf{ x}- \mathbf{ x}^\prime \right\Vert_2^2}{2\ell^2}\right),
-\] where the length scale is \(\ell\) and the variance is \(\alpha\). To set this up in GPy we create a kernel in the following manner. To set this up in GPy we create a kernel in the following manner. That builds a kernel object for us. The kernel can be displayed. Or because it’s one dimensional, you can also plot the kernel as a function of its inputs (while the other is fixed). Figure: The exponentiated quadratic covariance function as plotted by the You can set the length scale of the covariance to different values and plot the result. Figure: The exponentiated quadratic covariance function plotted for different length scales by Many covariance functions are already implemented in GPy. Instead of rbf, try constructing and plotting the following covariance functions: In GPy you can easily combine covariance functions you have created using the sum and product operators, That builds a kernel object for us. The kernel can be displayed. Or because it’s one dimensional, you can also plot the kernel as a function of its inputs (while the other is fixed). Figure: The exponentiated quadratic covariance function as plotted by the You can set the length scale of the covariance to different values and plot the result. Figure: The exponentiated quadratic covariance function plotted for different length scales by Many covariance functions are already implemented in GPy. Instead of rbf, try constructing and plotting the following covariance functions: In GPy you can easily combine covariance functions you have created using the sum and product operators, Figure: A combination of the exponentiated quadratic covariance plus the Matern \(5/2\) covariance. Or if we wanted to multiply them, we can write Figure: A combination of the exponentiated quadratic covariance plus the Matern \(5/2\) covariance. Or if we wanted to multiply them, we can write Figure: A combination of the exponentiated quadratic covariance multiplied by the Matern \(5/2\) covariance. You can learn about how to implement new kernel objects in GPy here. Figure: Designing the covariance function for your Gaussian process is a key place in which you introduce your understanding of the data problem. To learn more about the design of covariance functions, see this talk from Nicolas Durrande at GPSS in 2016. We will now combine the Gaussian process prior with some data to form a GP regression model with GPy. We will generate data from the function \[
+display(kern) Figure: A combination of the exponentiated quadratic covariance multiplied by the Matern \(5/2\) covariance. You can learn about how to implement new kernel objects in GPy here. Figure: Designing the covariance function for your Gaussian process is a key place in which you introduce your understanding of the data problem. To learn more about the design of covariance functions, see this talk from Nicolas Durrande at GPSS in 2016. We will now combine the Gaussian process prior with some data to form a GP regression model with GPy. We will generate data from the function \[
f( x) = − \cos(\pi x) + \sin(4\pi x)
\] over the domain \([0, 1]\), adding some noise to gives \[
y(x) = f(x) + \epsilon,
-\] with the noise being Gaussian distributed, \(\epsilon\sim \mathscr{N}\left(0,0.01\right)\). Figure: Data from the noisy sine wave for fitting with a GPy model. A GP regression model based on an exponentiated quadratic covariance function can be defined by first defining a covariance function. And then combining it with the data to form a Gaussian process model. Just as for the covariance function object, we can find out about the model using the command Note that by default the model includes some observation noise with variance 1. We can see the posterior mean prediction and visualize the marginal posterior variances using Figure: A Gaussian process fit to the noisy sine data. Here the parameters of the process and the covariance function haven’t yet been optimized. You can also look directly at the predictions for the model using. Which gives you the mean ( As we have seen during the lectures, the parameters values can be estimated by maximizing the likelihood of the observations. Since we don’t want any of the variances to become negative during the optimization, we can constrain all parameters to be positive before running the optimization. The warnings are because the parameters are already constrained by default, the software is warning us that they are being reconstrained. Now we can optimize the model using the By default, the optimization is using a limited memory BFGS optimizer (Byrd et al., 1995). Once again, we can display the model, now to see how the parameters have changed. The length scale is much smaller, as well as the noise level. The variance of the exponentiated quadratic has also reduced. Figure: A Gaussian process fit to the noisy sine data with parameters optimized. GPy has inspired other software solutions, first of all GPflow, which uses Tensor Flow’s automatic differentiation engine to allow rapid prototyping of new covariance functions and algorithms. More recently, GPyTorch uses PyTorch for the same purpose. The Probabilistic programming language pyro also has GP support. Chapter 2 of Neal (1994) Rest of Neal (1994) All of MacKay (1992) For more information on these subjects and more you might want to check the following resources. Figure: Data from the noisy sine wave for fitting with a GPy model. A GP regression model based on an exponentiated quadratic covariance function can be defined by first defining a covariance function. And then combining it with the data to form a Gaussian process model. Just as for the covariance function object, we can find out about the model using the command Note that by default the model includes some observation noise with variance 1. We can see the posterior mean prediction and visualize the marginal posterior variances using Figure: A Gaussian process fit to the noisy sine data. Here the parameters of the process and the covariance function haven’t yet been optimized. You can also look directly at the predictions for the model using. Which gives you the mean ( As we have seen during the lectures, the parameters values can be estimated by maximizing the likelihood of the observations. Since we don’t want any of the variances to become negative during the optimization, we can constrain all parameters to be positive before running the optimization. The warnings are because the parameters are already constrained by default, the software is warning us that they are being reconstrained. Now we can optimize the model using the By default, the optimization is using a limited memory BFGS optimizer (Byrd et al., 1995). Once again, we can display the model, now to see how the parameters have changed. The length scale is much smaller, as well as the noise level. The variance of the exponentiated quadratic has also reduced. Figure: A Gaussian process fit to the noisy sine data with parameters optimized. GPy has inspired other software solutions, first of all GPflow, which uses Tensor Flow’s automatic differentiation engine to allow rapid prototyping of new covariance functions and algorithms. More recently, GPyTorch uses PyTorch for the same purpose. The Probabilistic programming language pyro also has GP support. Chapter 2 of Neal (1994) Rest of Neal (1994) All of MacKay (1992) For more information on these subjects and more you might want to check the following resources.predict, fit and objective. You will find *args (or **kwargs) useful.offset=1956. and scale=120. to ensure that the data is mapped (roughly) to the -1, 1 range.Bias Variance Decomposition
+
+Bias vs Variance Error Plots
import numpy as np
+import matplotlib
+ \] The variance term is often described as arising from a model that is too complex, but we must be careful with this idea. Is the model really too complex relative to the real world that generates the data? The real world is a complex place, and it is rare that we are constructing mathematical models that are more complex than the world around us. Rather, the ‘too complex’ refers to ability to estimate the parameters of the model given the data we have. Slight variations in the training set cause changes in prediction.
+Bias vs Variance Error Plots
+
+
+import numpy as npimport matplotlib
font = {'family' : 'sans',
'weight' : 'bold',
'size' : 22}
matplotlib.rc('font', **font)
-import matplotlib.pyplot as pltfrom sklearn import svm
+# Create an instance of SVM and fit the data.
+import matplotlib.pyplot as plt
+from sklearn import svm# Create an instance of SVM and fit the data.
C = 100.0 # SVM regularization parameter
gammas = [0.001, 0.01, 0.1, 1]
@@ -309,12 +1429,525 @@
directory='./ml',
titles=titles,
xlim=xlim,
- ylim=ylim)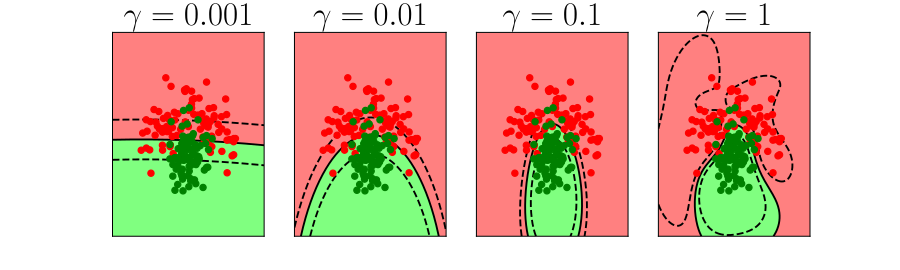
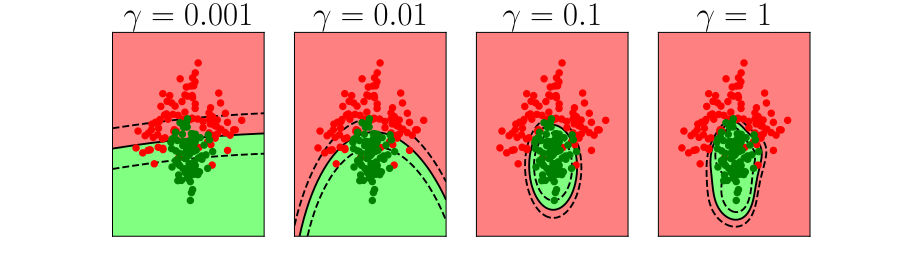
Overfitting
import numpy as np
-import pods
+
+data = pods.datasets.olympic_marathon_men()
+ ylim=ylim)
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Overfitting
+
+
+
+
+
+
+
+
+
+
+
+import numpy as np
+import podsdata = pods.datasets.olympic_marathon_men()
x = data['X']
y = data['Y']
offset = y.mean()
scale = np.sqrt(y.var())
-yhat = (y - offset)/scaleOlympic Data with Bayesian Polynomials
import mlai
-import podsHold Out Validation
5-fold Cross Validation
Andrade-Pacheco, R., Mubangizi, M., Quinn, J., Lawrence, N.D., 2014. Consistent mapping of government malaria records across a changing territory delimitation. Malaria Journal 13, 5. https://doi.org/10.1186/1475-2875-13-S1-P5Breiman, L., 2001. Random forests. Machine Learning 45, 5–32. https://doi.org/10.1023/A:1010933404324Breiman, L., 1996. Bagging predictors. Machine Learning 24, 123–140. https://doi.org/10.1007/BF00058655Cooper, B., 1991. Transformation of a valley: Derbyshire derwent. Scarthin Books.Efron, B., 1979. Bootstrap methods: Another look at the jackknife. Annals of Statistics 7, 1–26.Gelman, A., Carlin, J.B., Stern, H.S., Dunson, D.B., Vehtari, A., Rubin, D.B., 2013. Bayesian data analysis, 3rd ed. Chapman; Hall.Geman, S., Bienenstock, E., Doursat, R., 1992. Neural networks and the bias/variance dilemma. Neural Computation 4, 1–58. https://doi.org/10.1162/neco.1992.4.1.1Gething, P.W., Noor, A.M., Gikandi, P.W., Ogara, E.A.A., Hay, S.I., Nixon, M.S., Snow, R.W., Atkinson, P.M., 2006. Improving imperfect data from health management information systems in Africa using space–time geostatistics. PLoS Medicine 3. https://doi.org/10.1371/journal.pmed.0030271Lawrence, N.D., 2015. How Africa can benefit from the data revolution.McCullagh, P., Nelder, J.A., 1989. Generalized linear models, 2nd ed. Chapman; Hall.McCulloch, W.S., Pitts, W., 1943. A logical calculus of the ideas immanent in nervous activity. Bulletin of Mathematical Biophysics 5, 115–133. https://doi.org/10.1007/BF02478259Mubangizi, M., Andrade-Pacheco, R., Smith, M.T., Quinn, J., Lawrence, N.D., 2014. Malaria surveillance with multiple data sources using Gaussian process models, in: 1st International Conference on the Use of Mobile ICT in Africa.Robbins, H., Monro, S., 1951. A stochastic approximation method. Annals of Mathematical Statistics 22, 400–407.Taigman, Y., Yang, M., Ranzato, M., Wolf, L., 2014. DeepFace: Closing the gap to human-level performance in face verification, in: Proceedings of the IEEE Computer Society Conference on Computer Vision and Pattern Recognition. https://doi.org/10.1109/CVPR.2014.220The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs), Columbia University, 2014. Nigeria NMIS facility database.Olympic Data with Bayesian Polynomials
+
+
+import mlai
+import pods
+
+
+
+
+
+
+
+
+
+Hold Out Validation
+
+
+
+
+
+
+
+
+
+
+5-fold Cross Validation
+
+
+
+
+
+
+
+
+
+
+
+Unsupervised Learning
+
+Unsupervised Learning
+Context
+Discrete vs Continuous
+Clustering
+
+\(k\)-means Clustering
+
+Squared Distance
+\(k\)-Means Clustering
+
+
+
+from mlai import generate_cluster_data
+from mlai import dist2
+from mlai import kmeans_assignments
+from mlai import kmeans_update
+from mlai import kmeans_objective
+import numpy as np
+# Generate synthetic data with cluster structure
+np.random.seed(24)
+Y = generate_cluster_data(n_points_per_cluster=30)
+
+# Initialize cluster centres from first cluster
+# Note: this is a *bad* initialisation so we can observe algorithm.
+nclusters = 3
+centres = Y[:nclusters, :].copy()
+# Run k-means algorithm for several iterations
+niters = 10
+centres_store = [centres.copy()] # Store initial centres
+objective_store = [kmeans_objective(Y, centres)] # Calculate initial objective
+
+print(f"Initial objective: {objective_store[0]:.2f}")
+print("Running k-means algorithm...")
+
+for iteration in range(niters):
+ centres, assignments = kmeans_update(Y, centres)
+ objective = kmeans_objective(Y, centres)
+
+ print(f" Iteration {iteration+1}: objective = {objective:.2f}")
+
+ # Store results for plotting
+ centres_store.append(centres.copy())
+ objective_store.append(objective)
+
+print(f"Final objective: {objective_store[-1]:.2f}")
+print(f"Objective improvement: {objective_store[0] - objective_store[-1]:.2f}")
+
+
+
+
+
+
+
+
+
+Hierarchical Clustering
+
+Linkage Criteria
+Ward’s Criterion
+Mathematical Derivation
+
+from mlai import generate_cluster_data
+from mlai import ClusterModel
+from mlai import WardsMethod
+# Generate synthetic data with cluster structure
+np.random.seed(24)
+Y = generate_cluster_data(n_points_per_cluster=30)
+
+ward = WardsMethod(Y)
+ward.fit()
+
+linkage_matrix = ward.get_linkage_matrix()
+print(f'Linkage matrix shape: {linkage_matrix.shape}')
+
+print(f"\nFinal clustering completed in {len(linkage_matrix)} steps")
+print(f"Ward distances at each step: {[f'{d:.3f}' for d in linkage_matrix[:, 2]]}")
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Oil Flow Data
+
+
+import pods
+data = pods.datasets.oil()
+# Convert data["Y"] from [1, -1, -1] in each row to rows of 0 or 1 or 2
+Y = data["Y"]
+# Find rows with 1 in first column (class 0)
+class0 = (Y[:, 0] == 1).astype(int) * 0
+# Find rows with 1 in second column (class 1)
+class1 = (Y[:, 1] == 1).astype(int) * 1
+# Find rows with 1 in third column (class 2)
+class2 = (Y[:, 2] == 1).astype(int) * 2
+# Combine into single array of class labels 0,1,2
+labels = class0 + class1 + class2
+
+
+
+
+
+
+
+
+
+
+print(data['citation'])info and details.
+print(data['details'])
+X = data['X']
+Y = data['Y']Hierarchical Clustering of Oil Flow Data
+
+
+import numpy as np
+from scipy.cluster.hierarchy import dendrogram, linkage
+import pods
+# Perform hierarchical clustering
+linked = linkage(X, 'ward') # Ward's method for minimum variance
+
+
+
+
+
+
+
+
+
+Phylogenetic Trees
+Product Clustering
+Hierarchical Clustering Challenge
+Dimensionality Reduction
+
+
+
+
+
+
+
+
+
+
+
+Examples in Social Sciences
+Principal Component Analysis
+
+
+
+
+
+
+
+
+
+
+Hotelling’s PCA
+Parameters
+Reinforcement Learning
+
+“Reward”
+
+
+Game Play
+AlphaGo
+Reinforcement Learning and Classical Control
+Optimization Methods
+Bayesian Optimization
+Surrogate Models
+Model-Based and Model Free: Performance
+Deployment
+
+Where to Deploy?
+
+
+Is this Right?
+Model Choice
+Thanks!
+
+
+References
+
+
+
diff --git a/_lectures/02-ml-systems.html b/_lectures/02-ml-systems.html
index db28aa2..7adada8 100644
--- a/_lectures/02-ml-systems.html
+++ b/_lectures/02-ml-systems.html
@@ -29,9 +29,8 @@
date: 2020-07-24
session: 2
reveal: 02-ml-systems.slides.html
-transition: None
+transition: none
ipynb: 02-ml-systems.ipynb
-pptx: 02-ml-systems.pptx
layout: lecture
categories:
- notes
@@ -39,23 +38,171 @@
-
+
+
+
+
+
+
+
+
+
+Andrade-Pacheco, R., Mubangizi, M., Quinn, J., Lawrence, N.D., 2014. Consistent mapping of government malaria records across a changing territory delimitation. Malaria Journal 13, 5. https://doi.org/10.1186/1475-2875-13-S1-P5
+
+
+Bishop, C.M., James, G.D., 1993. Analysis of multiphase flows using dual-energy gamma densitometry and neural networks. Nuclear Instruments and Methods in Physics Research A327, 580–593. https://doi.org/10.1016/0168-9002(93)90728-Z
+
+
+Breiman, L., 2001. Random forests. Machine Learning 45, 5–32. https://doi.org/10.1023/A:1010933404324
+
+
+Breiman, L., 1996. Bagging predictors. Machine Learning 24, 123–140. https://doi.org/10.1007/BF00058655
+
+
+Cooper, B., 1991. Transformation of a valley: Derbyshire derwent. Scarthin Books.
+
+
+Efron, B., 1979. Bootstrap methods: Another look at the jackknife. Annals of Statistics 7, 1–26.
+
+
+Gelman, A., Carlin, J.B., Stern, H.S., Dunson, D.B., Vehtari, A., Rubin, D.B., 2013. Bayesian data analysis, 3rd ed. Chapman; Hall.
+
+
+Geman, S., Bienenstock, E., Doursat, R., 1992. Neural networks and the bias/variance dilemma. Neural Computation 4, 1–58. https://doi.org/10.1162/neco.1992.4.1.1
+
+
+Gething, P.W., Noor, A.M., Gikandi, P.W., Ogara, E.A.A., Hay, S.I., Nixon, M.S., Snow, R.W., Atkinson, P.M., 2006. Improving imperfect data from health management information systems in Africa using space–time geostatistics. PLoS Medicine 3. https://doi.org/10.1371/journal.pmed.0030271
+
+
+Lake, B.M., Lawrence, N.D., Tenenbaum, J.B., 2018. The emergence of organizing structure in conceptual representation. Cognitive science 42 Suppl 3, 809–832. https://doi.org/10.1111/cogs.12580
+
+
+Lawrence, N.D., 2015. How Africa can benefit from the data revolution.
+
+
+McCullagh, P., Nelder, J.A., 1989. Generalized linear models, 2nd ed. Chapman; Hall.
+
+
+McCulloch, W.S., Pitts, W., 1943. A logical calculus of the ideas immanent in nervous activity. Bulletin of Mathematical Biophysics 5, 115–133. https://doi.org/10.1007/BF02478259
+
+
+Mubangizi, M., Andrade-Pacheco, R., Smith, M.T., Quinn, J., Lawrence, N.D., 2014. Malaria surveillance with multiple data sources using Gaussian process models, in: 1st International Conference on the Use of Mobile ICT in Africa.
+
+
+Robbins, H., Monro, S., 1951. A stochastic approximation method. Annals of Mathematical Statistics 22, 400–407.
+
+
+Taigman, Y., Yang, M., Ranzato, M., Wolf, L., 2014. DeepFace: Closing the gap to human-level performance in face verification, in: Proceedings of the IEEE Computer Society Conference on Computer Vision and Pattern Recognition. https://doi.org/10.1109/CVPR.2014.220
+
+
+The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs), Columbia University, 2014. Nigeria NMIS facility database.
+
+Nigerian Health Facility Distribution
pandas to manipulate the data, our focus will be on introducing some concepts from databases.Nigerian Health Facility Distribution
+pandas to manipulate the data, our focus will be on introducing some concepts from databases.Datasets
Imports, Installs, and Downloads
geopandas which will help us deal with ‘shape files’ that give the geographical lay out of Nigeria. We also need pygeos for indexing.import importlib.utilcmd = install_command('geopandas')%system {cmd}cmd = install_command('pygeos')%system {cmd}Setup
notutils
cmd = install_command('notutils')%system {cmd}notutils is installed, it can be imported in the usual manner.import notutilspods
cmd = install_command('pods')%system {cmd}pods is installed, it can be imported in the usual manner.import podsmlai
mlai software is a suite of helper functions for teaching and demonstrating machine learning algorithms. It was first used in the Machine Learning and Adaptive Intelligence course in Sheffield in 2013.cmd = install_command('mlai')%system {cmd}mlai is installed, it can be imported in the usual manner.import mlai
-from mlai import plotDatabases and Joins
pandas which is a great way of storing and structuring your data set to make it easier to plot and manipulate your data.pandas.Scaling ML Systems
pandas and python is about as safe and reliable as taking six children to school on a boda boda.Nigeria NMIS Data
pods librarydata = pods.datasets.nigeria_nmis()['Y']
-data.head()
+import urllib.request
+sns.set_palette('colorblind')}-->
+notutils
+
+
+cmd = install_command('notutils')
+%system {cmd}notutils is installed, it can be imported in the usual manner.
+import notutilspods
+
+
+cmd = install_command('pods')
+%system {cmd}pods is installed, it can be imported in the usual manner.
+import podsmlai
+
+mlai software is a suite of helper functions for teaching and demonstrating machine learning algorithms. It was first used in the Machine Learning and Adaptive Intelligence course in Sheffield in 2013.
+cmd = install_command('mlai')
+%system {cmd}mlai is installed, it can be imported in the usual manner.
+import mlai
+from mlai import plotDatabases and Joins
+
+pandas which is a great way of storing and structuring your data set to make it easier to plot and manipulate your data.pandas.Scaling ML Systems
+pandas and python is about as safe and reliable as taking six children to school on a boda boda.Nigeria NMIS Data
+
+
+
+pods library
+data = pods.datasets.nigeria_nmis()['Y']
+data.head()import urllib.request
urllib.request.urlretrieve('https://energydata.info/dataset/f85d1796-e7f2-4630-be84-79420174e3bd/resource/6e640a13-cab4-457b-b9e6-0336051bac27/download/healthmopupandbaselinenmisfacility.csv', 'healthmopupandbaselinenmisfacility.csv')
import pandas as pd
-data = pd.read_csv('healthmopupandbaselinenmisfacility.csv')describe method in pandas.data.describe()shape property.data.shape.<Tab> for example in the above case if we type data.<Tab> it show the columns available (these are attributes in pandas dataframes) such as num_nurses_fulltime, and also functions, such as .describe().data.describe?hospital_data = dataAdministrative Zone Geo Data
gdb or GeoDataBase format. It comes in a zip file. Let’s download the outline files for the Nigerian states. They have been made available by the Humanitarian Data Exchange, you can also find other states data from the same site.Nigerian Administrative Zones Data
pods library
+data = pods.datasets.nigerian_administrative_zones()['Y']
+data = pd.read_csv('healthmopupandbaselinenmisfacility.csv')describe method in pandas.
+data.describe()shape property.
+data.shape.<Tab> for example in the above case if we type data.<Tab> it show the columns available (these are attributes in pandas dataframes) such as num_nurses_fulltime, and also functions, such as .describe().
+data.describe?
+
+
+
+
+
+
+
+
+
+
+
+
+hospital_data = dataAdministrative Zone Geo Data
+
+gdb or GeoDataBase format. It comes in a zip file. Let’s download the outline files for the Nigerian states. They have been made available by the Humanitarian Data Exchange, you can also find other states data from the same site.Nigerian Administrative Zones Data
+
+pods librarydata = pods.datasets.nigerian_administrative_zones()['Y']
data.set_index("admin1Name_en", inplace=True)
-data.head()
+import zipfile
+data.head()import zipfile
admin_zones_url = 'https://data.humdata.org/dataset/81ac1d38-f603-4a98-804d-325c658599a3/resource/0bc2f7bb-9ff6-40db-a569-1989b8ffd3bc/download/nga_admbnda_osgof_eha_itos.gdb.zip'
_, msg = urllib.request.urlretrieve(admin_zones_url, 'nga_admbnda_osgof_eha_itos.gdb.zip')
@@ -71,16 +218,139 @@
data = gpd.read_file(states_file, layer=1)
data.crs = "EPSG:4326"
data = data.set_index('admin1Name_en')
- zones_gdf = data.reset_index()MultiPolygon objects that define the boundaries of different states, we can perform a spatial join (sjoin) from the coordinates of individual health facilities (which we already converted to the appropriate Point type when moving the health data to a GeoDataFrame.)Joining a GeoDataFrame
pandas dataframe of health facilities into a GeoDataFrame which allows us to do the spatial join.geopandas data frame.import geopandas as gpd
+geometry = gpd.points_from_xy(hospital_data.longitude, hospital_data.latitude)
+
+
+
+
+
+
+
+
+
+
+
+zones_gdf = data.reset_index()MultiPolygon objects that define the boundaries of different states, we can perform a spatial join (sjoin) from the coordinates of individual health facilities (which we already converted to the appropriate Point type when moving the health data to a GeoDataFrame.)Joining a GeoDataFrame
+pandas dataframe of health facilities into a GeoDataFrame which allows us to do the spatial join.geopandas data frame.
+import geopandas as gpdgeometry = gpd.points_from_xy(hospital_data.longitude, hospital_data.latitude)
hosp_gdf = gpd.GeoDataFrame(hospital_data,
geometry=geometry)
-hosp_gdf.crs = "EPSG:4326"crs refers to the coordinate system in use by a particular GeoDataFrame. EPSG:4326 is the standard coordinate system of latitude/longitude.Your First Join: Converting GPS Coordinates to States
GeoPandas format, we can start converting into states. We will use the fiona library for reading the right layers from the files. Before we do the join, lets plot the location of health centers and states on the same map.
+nigeria_gdf = zones_gdf.dissolve()
+hosp_gdf.crs = "EPSG:4326"crs refers to the coordinate system in use by a particular GeoDataFrame. EPSG:4326 is the standard coordinate system of latitude/longitude.Your First Join: Converting GPS Coordinates to States
+GeoPandas format, we can start converting into states. We will use the fiona library for reading the right layers from the files. Before we do the join, lets plot the location of health centers and states on the same map.nigeria_gdf = zones_gdf.dissolve()
if nigeria_gdf.crs is None:
- nigeria_gdf.crs = "EPSG:4326"Performing the Spatial Join
alpha in the plot). This means that we can see the regions where there are more health centers, you should be able to spot where the major cities in Nigeria are given the increased number of health centers in those regions.GeoPandas provides us with the spatial join. Here we’re going to do a left or outer join.from geopandas.tools import sjoinhosp_gdf and zones_gdf. Let’s have a look at the columns the contain.hosp_gdf.columnszones_gdf data frame.zones_gdf.columnsset(hosp_gdf.columns).intersection(set(zones_gdf.columns))hosp_state_joined = sjoin(hosp_gdf, zones_gdf, how='left')set(hosp_gdf.columns).union(set(zones_gdf.columns))hosp_state_joined. Notice also that there’s a new column: index_right. The two original data bases had separate indices. The index_right column represents the index from the zones_gdf, which is the Nigerian state.set(hosp_state_joined.columns)hosp_state_joined.head()SQL Database
gdb format and the GeoPandas tool for manipulating that data. But we’ve now saved our updated data in a new file.MariaDB which is open source, or Microsoft’s SQL Server.MySQL server hosted on top of AWS. Although since MySQL was sold to Sun, and then passed on to Oracle, the open source community has turned its attention to MariaDB, here’s the AWS instructions on how to set up MariaDB.pandas commands, which would often be what you would use when you’re doing data analysis in python and Jupyter.Create the SQLite Database
hosp_state_joined.to_csv("hospitals_zones_joined.csv")cmd = install_command('csv-to-sqlite')%system {cmd}!csv-to-sqlite -f hospitals_zones_joined.csv -t full -o db.sqlitedb.sqlite.Accessing the SQL Database
SELECT. It allows us to extract rows from a given table. It operates a bit like the .head() method in pandas, it will return the first N rows (by default the .head() command returns the first 5 rows, but you can set N to whatever you like. Here we’ve included a default value of 5 to make it match the pandas command.execute command on the connection.SELECT * FROM table_name LIMIT NN entries from a given database called table_name.table_name and number of rows, n, to the python command.conn = create_connection("db.sqlite")SELECT. It allows us to extract rows from a given table. It operates a bit like the .head() method in pandas, it will return the first N rows (by default the .head() command returns the first 5 rows, but you can set N to whatever you like. Here we’ve included a default value of 5 to make it match the pandas command.sqlite3, allows us to access the SQL database directly from python..head() method does so we can inspect our database.
+def head(conn, table, n=5):
+ nigeria_gdf.crs = "EPSG:4326"
+
+
+
+
+
+
+
+
+
+Performing the Spatial Join
+alpha in the plot). This means that we can see the regions where there are more health centers, you should be able to spot where the major cities in Nigeria are given the increased number of health centers in those regions.GeoPandas provides us with the spatial join. Here we’re going to do a left or outer join.
+from geopandas.tools import sjoinhosp_gdf and zones_gdf. Let’s have a look at the columns the contain.
+hosp_gdf.columnszones_gdf data frame.
+zones_gdf.columns
+set(hosp_gdf.columns).intersection(set(zones_gdf.columns))
+hosp_state_joined = sjoin(hosp_gdf, zones_gdf, how='left')
+set(hosp_gdf.columns).union(set(zones_gdf.columns))hosp_state_joined. Notice also that there’s a new column: index_right. The two original data bases had separate indices. The index_right column represents the index from the zones_gdf, which is the Nigerian state.
+set(hosp_state_joined.columns)
+hosp_state_joined.head()SQL Database
+
+gdb format and the GeoPandas tool for manipulating that data. But we’ve now saved our updated data in a new file.MariaDB which is open source, or Microsoft’s SQL Server.MySQL server hosted on top of AWS. Although since MySQL was sold to Sun, and then passed on to Oracle, the open source community has turned its attention to MariaDB, here’s the AWS instructions on how to set up MariaDB.pandas commands, which would often be what you would use when you’re doing data analysis in python and Jupyter.Create the SQLite Database
+
+
+hosp_state_joined.to_csv("hospitals_zones_joined.csv")
+cmd = install_command('csv-to-sqlite')
+%system {cmd}
+!csv-to-sqlite -f hospitals_zones_joined.csv -t full -o db.sqlitedb.sqlite.Accessing the SQL Database
+SELECT. It allows us to extract rows from a given table. It operates a bit like the .head() method in pandas, it will return the first N rows (by default the .head() command returns the first 5 rows, but you can set N to whatever you like. Here we’ve included a default value of 5 to make it match the pandas command.execute command on the connection.
+SELECT * FROM table_name LIMIT NN entries from a given database called table_name.table_name and number of rows, n, to the python command.
+conn = create_connection("db.sqlite")SELECT. It allows us to extract rows from a given table. It operates a bit like the .head() method in pandas, it will return the first N rows (by default the .head() command returns the first 5 rows, but you can set N to whatever you like. Here we’ve included a default value of 5 to make it match the pandas command.sqlite3, allows us to access the SQL database directly from python..head() method does so we can inspect our database.def head(conn, table, n=5):
rows = select_top(conn, table, n)
for r in rows:
- print(r)head(conn, "hospitals_zones_joined")pandas and the database utilities.Covid Data
Nigerian COVID Data
pods libraryimport podsdata = pods.datasets.nigerian_covid()['Y']
-data.head()
+import urllib.request
+ print(r)
+head(conn, "hospitals_zones_joined")pandas and the database utilities.Covid Data
+
+Nigerian COVID Data
+
+pods library
+import pods
+data = pods.datasets.nigerian_covid()['Y']
+data.head()import urllib.request
import pandas as pd
urllib.request.urlretrieve('https://raw.githubusercontent.com/dsfsi/covid19africa/master/data/line_lists/line-list-nigeria.csv', 'line-list-nigeria.csv')
@@ -88,12 +358,43 @@
'date_confirmation',
'date_admission_hospital',
'date_onset_symptoms',
- 'death_date'])describe method in pandas.data.describe()covid_data=data
-covid_data.to_csv('cases.csv')!csv-to-sqlite -f cases.csv -t full -o db.sqlitePopulation Data
+import urllib
+ 'death_date'])describe method in pandas.
+data.describe()
+
+
+
+
+
+
+
+
+
+
+covid_data=data
+covid_data.to_csv('cases.csv')
+!csv-to-sqlite -f cases.csv -t full -o db.sqlitePopulation Data
+
+import urllib
pop_url = "https://data.humdata.org/dataset/a7c3de5e-ff27-4746-99cd-05f2ad9b1066/resource/d9fc551a-b5e4-4bed-9d0d-b047b6961817/download/nga_admpop_adm1_2020.csv"
_, msg = urllib.request.urlretrieve(pop_url,"nga_admpop_adm1_2020.csv")
-data = pd.read_csv("nga_admpop_adm1_2020.csv")
+data.dropna(axis=0, how="all", inplace=True)
+data = pd.read_csv("nga_admpop_adm1_2020.csv")data.dropna(axis=0, how="all", inplace=True)
data.dropna(axis=1, how="all", inplace=True)
data.rename(columns = {"ADM0_NAME" : "admin0Name_en",
"ADM0_PCODE" : "admin0Pcode",
@@ -104,5 +405,43 @@
data["admin0Name_en"] = data["admin0Name_en"].str.title()
data["admin1Name_en"] = data["admin1Name_en"].str.title()
-data = data.set_index("admin1Name_en")data = pods.datasets.nigerian_population()["Y"]data.head()pop_data=dataSave to database file
Loading the Population Data into the SQLite Database
pop_data.to_csv('pop_data.csv')!csv-to-sqlite -f pop_data.csv -t full -o db.sqliteThanks!
References
Marivate, V., Nsoesie, E., Bekele, E., Africa open COVID-19 data working group, 2020. Coronavirus COVID-19 (2019-nCoV) Data Repository for Africa. https://doi.org/10.5281/zenodo.3757554The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs), Columbia University, 2014. Nigeria NMIS facility database.
+data = pods.datasets.nigerian_population()["Y"]
+data.head()
+pop_data=dataSave to database file
+Loading the Population Data into the SQLite Database
+
+
+pop_data.to_csv('pop_data.csv')
+!csv-to-sqlite -f pop_data.csv -t full -o db.sqliteThanks!
+
+
+References
+
+
+
diff --git a/_lectures/03-bayesian-methods-abuja.html b/_lectures/03-bayesian-methods-abuja.html
index 20684a1..95f7ebe 100644
--- a/_lectures/03-bayesian-methods-abuja.html
+++ b/_lectures/03-bayesian-methods-abuja.html
@@ -22,9 +22,8 @@
date: 2018-11-14
session: 3
reveal: 03-bayesian-methods-abuja.slides.html
-transition: None
+transition: none
ipynb: 03-bayesian-methods-abuja.ipynb
-pptx: 03-bayesian-methods-abuja.pptx
layout: lecture
categories:
- notes
@@ -32,45 +31,248 @@
-
+
+
+
+
+
+
+
+
+
+Marivate, V., Nsoesie, E., Bekele, E., Africa open COVID-19 data working group, 2020. Coronavirus COVID-19 (2019-nCoV) Data Repository for Africa. https://doi.org/10.5281/zenodo.3757554
+
+
+The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs), Columbia University, 2014. Nigeria NMIS facility database.
+
+What is Machine Learning?
Nigeria NMIS Data
pods librarypods
import importlib.utilcmd = install_command('pods')%system {cmd}pods is installed, it can be imported in the usual manner.import podsdata = pods.datasets.nigeria_nmis()['Y']
-data.head()
+import urllib.request
+-->
+What is Machine Learning?
+
+Nigeria NMIS Data
+
+
+
+pods librarypods
+
+
+import importlib.util
+cmd = install_command('pods')
+%system {cmd}pods is installed, it can be imported in the usual manner.
+import pods
+data = pods.datasets.nigeria_nmis()['Y']
+data.head()import urllib.request
urllib.request.urlretrieve('https://energydata.info/dataset/f85d1796-e7f2-4630-be84-79420174e3bd/resource/6e640a13-cab4-457b-b9e6-0336051bac27/download/healthmopupandbaselinenmisfacility.csv', 'healthmopupandbaselinenmisfacility.csv')
import pandas as pd
-data = pd.read_csv('healthmopupandbaselinenmisfacility.csv')describe method in pandas.data.describe()shape property.data.shape.<Tab> for example in the above case if we type data.<Tab> it show the columns available (these are attributes in pandas dataframes) such as num_nurses_fulltime, and also functions, such as .describe().data.describe?Probabilities
describe method in pandas.
+data.describe()shape property.
+data.shape.<Tab> for example in the above case if we type data.<Tab> it show the columns available (these are attributes in pandas dataframes) such as num_nurses_fulltime, and also functions, such as .describe().
+data.describe?
+
+
+
+
+
+
+
+
+
+
+
+Probabilities
+
+import podsdata = pods.datasets.nigeria_nmis()['Y']Exploring the NMIS Data
S, the most widely used of which is R. The data frame gives us a convenient object for manipulating data. The describe method summarizes which columns there are in the data frame and gives us counts, means, standard deviations and percentiles for the values in those columns. To access a column directly we can writeprint(data['num_doctors_fulltime'])
-#print(data['num_nurses_fulltime'])import matplotlib.pyplot as plt # this imports the plotting library in python_ = plt.plot(data['num_doctors_fulltime'], data['num_nurses_fulltime'], 'rx')plt.plot are for, now is the perfect time to look at the documentationplt.plot?data[data['num_nurses_fulltime']>100]data['num_nurses_fulltime']>100 to index the facilities in the pandas data frame which have over 100 nurses. To sort them in order we can also use the sort command. The result of this command on its own is a data Series of True and False values. However, when it is passed to the data data frame it returns a new data frame which contains only those values for which the data series is True. We can also sort the result. To sort the result by the values in the num_nurses_fulltime column in descending order we use the following command.data[data['num_nurses_fulltime']>100].sort_values(by='num_nurses_fulltime', ascending=False)Plotting the Data
data['num_nurses_fulltime'].hist(bins=20) # histogram the data with 20 bins.
-plt.title('Histogram of Number of Nurses')
+data['num_nurses_fulltime'].hist(bins=100) # histogram the data with 20 bins.
+\]
+
+import pods
+data = pods.datasets.nigeria_nmis()['Y']Exploring the NMIS Data
+
+S, the most widely used of which is R. The data frame gives us a convenient object for manipulating data. The describe method summarizes which columns there are in the data frame and gives us counts, means, standard deviations and percentiles for the values in those columns. To access a column directly we can write
+print(data['num_doctors_fulltime'])
+#print(data['num_nurses_fulltime'])
+import matplotlib.pyplot as plt # this imports the plotting library in python
+_ = plt.plot(data['num_doctors_fulltime'], data['num_nurses_fulltime'], 'rx')plt.plot are for, now is the perfect time to look at the documentation
+plt.plot?
+data[data['num_nurses_fulltime']>100]data['num_nurses_fulltime']>100 to index the facilities in the pandas data frame which have over 100 nurses. To sort them in order we can also use the sort command. The result of this command on its own is a data Series of True and False values. However, when it is passed to the data data frame it returns a new data frame which contains only those values for which the data series is True. We can also sort the result. To sort the result by the values in the num_nurses_fulltime column in descending order we use the following command.
+data[data['num_nurses_fulltime']>100].sort_values(by='num_nurses_fulltime', ascending=False)Plotting the Data
+
+data['num_nurses_fulltime'].hist(bins=20) # histogram the data with 20 bins.
+plt.title('Histogram of Number of Nurses')data['num_nurses_fulltime'].hist(bins=100) # histogram the data with 20 bins.
plt.title('Histogram of Number of Nurses')
ax = plt.gca()
-ax.set_yscale('log')
+fig, ax = plt.subplots(figsize=(10, 7))
+ax.set_yscale('log')fig, ax = plt.subplots(figsize=(10, 7))
ax.plot(data['num_doctors_fulltime'], data['num_nurses_fulltime'], 'rx')
ax.set_xscale('log') # use a logarithmic x scale
ax.set_yscale('log') # use a logarithmic Y scale
# give the plot some titles and labels
plt.title('Number of Nurses against Number of Doctors')
plt.ylabel('number of nurses')
-plt.xlabel('number of doctors')Probability and the NMIS Data
+large = (data.num_nurses_fulltime>2).sum() # number of positive outcomes (in sum True counts as 1, False counts as 0)
+plt.xlabel('number of doctors')Probability and the NMIS Data
+
+large = (data.num_nurses_fulltime>2).sum() # number of positive outcomes (in sum True counts as 1, False counts as 0)
total_facilities = data.num_nurses_fulltime.count()
prob_large = float(large)/float(total_facilities)
-print("Probability of number of nurses being greather than 2 is:", prob_large)Conditioning
Conditioning
+
+large = ((data.num_nurses_fulltime>2) & (data.num_doctors_fulltime>1)).sum()
+\] However, we might believe that the number of nurses is dependent on the number of doctors. For this we can try estimating \(P(Y>2 | X>1)\) and compare the result, for example to \(P(Y>2|X\leq 1)\) using our empirical estimate of the probability.
+large = ((data.num_nurses_fulltime>2) & (data.num_doctors_fulltime>1)).sum()
total_large_doctors = (data.num_doctors_fulltime>1).sum()
prob_both_large = large/total_large_doctors
-print("Probability of number of nurses being greater than 2 given number of doctors is greater than 1 is:", prob_both_large)Exercise 1
%matplotlib inline we ran above will do that for you, it only needs to be run once per file).Terminology Mathematical notation Description joint \(P(X=x, Y=y)\) prob. that X=x and Y=y marginal \(P(X=x)\) prob. that X=x regardless of Y conditional \(P(X=x\vert Y=y)\) prob. that X=x given that Y=y A Pictorial Definition of Probability
Inspired by lectures from Christopher BishopDefinition of probability distributions
Terminology Definition Probability Notation Joint Probability \(\lim_{N\rightarrow\infty}\frac{n_{X=3,Y=4}}{N}\) \(P\left(X=3,Y=4\right)\) Marginal Probability \(\lim_{N\rightarrow\infty}\frac{n_{X=5}}{N}\) \(P\left(X=5\right)\) Conditional Probability \(\lim_{N\rightarrow\infty}\frac{n_{X=3,Y=4}}{n_{Y=4}}\) \(P\left(X=3\vert Y=4\right)\) Notational Details
Exercise 1
+%matplotlib inline we ran above will do that for you, it only needs to be run once per file).
+
+
+
+
+
+
+Terminology
+Mathematical notation
+Description
+
+
+joint
+\(P(X=x, Y=y)\)
+prob. that X=x and Y=y
+
+
+marginal
+\(P(X=x)\)
+prob. that X=x regardless of Y
+
+
+
+conditional
+\(P(X=x\vert Y=y)\)
+prob. that X=x given that Y=y
+A Pictorial Definition of Probability
+
+
+
+
+
+
+
+
+
+
+
+
+Inspired by lectures from Christopher Bishop
+
+Definition of probability distributions
+
+
+
+
+
+
+Terminology
+Definition
+Probability Notation
+
+
+Joint Probability
+\(\lim_{N\rightarrow\infty}\frac{n_{X=3,Y=4}}{N}\)
+\(P\left(X=3,Y=4\right)\)
+
+
+Marginal Probability
+\(\lim_{N\rightarrow\infty}\frac{n_{X=5}}{N}\)
+\(P\left(X=5\right)\)
+
+
+
+Conditional Probability
+\(\lim_{N\rightarrow\infty}\frac{n_{X=3,Y=4}}{n_{Y=4}}\)
+\(P\left(X=3\vert Y=4\right)\)
+Notational Details
+
+num_doctors = 1
+\] Sometimes I think of this as akin to the way in Python we can write ‘keyword arguments’ in functions. If we use keyword arguments, the ordering of arguments doesn’t matter.
+num_doctors = 1
large = (data.num_nurses_fulltime[data.num_doctors_fulltime==num_doctors]>2).sum()
total_facilities = data.num_nurses_fulltime.count() # this is total number of films
prob_large = float(large)/float(total_facilities)
-print("Probability of nurses being greater than 2 and number of doctors being", num_doctors, "is:", prob_large)The Product Rule
The Product Rule
+
+num_doctors=1
+\] We can see the relation working in practice for our data above by computing the different values for \(x=1\).
+num_doctors=1
num_nurses=2
p_x = float((data.num_doctors_fulltime==num_doctors).sum())/float(data.num_doctors_fulltime.count())
p_y_given_x = float((data.num_nurses_fulltime[data.num_doctors_fulltime==num_doctors]>num_nurses).sum())/float((data.num_doctors_fulltime==num_doctors).sum())
@@ -94,27 +303,148 @@
print("P(x) is", p_x)
print("P(y|x) is", p_y_given_x)
-print("P(y,x) is", p_y_and_x)The Sum Rule
The Sum Rule
+Exercise 2
Bayes’ Rule
Exercise 2
+Bayes’ Rule
+Further Reading
Exercises
Probabilities for Extracting Information from Data
data.columnsExercise 3
maternal_health_delivery_services. How would we go about doing it?Probabilistic Modelling
+
+
+
+
+
+
+
+
+
+Further Reading
+
+
+
+Exercises
+
+
+Probabilities for Extracting Information from Data
+
+
+data.columnsExercise 3
+maternal_health_delivery_services. How would we go about doing it?Probabilistic Modelling
+
+Graphical Models
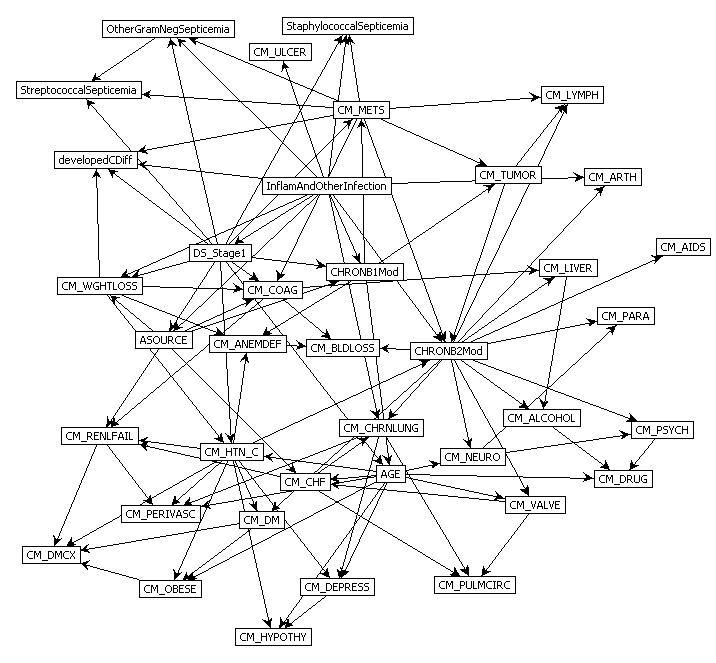
Introduction to Classification
Graphical Models
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Introduction to Classification
+
+Classification Examples
Subsample of the MNIST Data
from sklearn.datasets import fetch_openmlmnist = fetch_openml('mnist_784', version=1, as_frame=False, parser='liac-arff')import numpy as np
+np.random.seed(0)
+\] The function \(f(\cdot)\) is known as the prediction function. The key challenges are (1) choosing which features, \(\mathbf{ x}\), are relevant in the prediction, (2) defining the appropriate class of function, \(f(\cdot)\), to use and (3) selecting the right parameters, \(\mathbf{ w}\).
+Classification Examples
+
+Subsample of the MNIST Data
+
+
+from sklearn.datasets import fetch_openml
+mnist = fetch_openml('mnist_784', version=1, as_frame=False, parser='liac-arff')
+import numpy as npnp.random.seed(0)
digits = [0,1,2,3,4]
N_per_digit = 100
Y = []
@@ -127,31 +457,153 @@
labels.append(np.ones(N_per_digit)*d)
Y = np.vstack(Y).astype(np.float64)
labels = np.hstack(labels)
-Y /= 255MNIST Digit Examples
Bernoulli Distribution
\(y\) 0 1 \(P(y)\) \((1-\pi)\) \(\pi\) MNIST Digit Examples
+
+
+
+
+
+
+
+
+
+
+
+Bernoulli Distribution
+
+
+
+
+
+
+
+
+\(y\)
+0
+1
+
+
+
+\(P(y)\)
+\((1-\pi)\)
+\(\pi\)
+
+def bernoulli(y_i, pi):
+ \] where our probability distribution is now written as a function of \(y\). This probability distribution is known as the Bernoulli distribution. The Bernoulli distribution is a clever trick for mathematically switching between two probabilities if we were to write it as code it would be better described as
+def bernoulli(y_i, pi):
if y_i == 1:
return pi
else:
- return 1-piMaximum Likelihood in the Bernoulli
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Maximum Likelihood in the Bernoulli
+
+Exercise 4
Exercise 4
+Naive Bayes Classifiers
scikit-learn, our purpose in this session is to help you understand how those engines are constructed. In practice for an application you should use a library like scikit-learn.
+
+Naive Bayes Classifiers
+
+scikit-learn, our purpose in this session is to help you understand how those engines are constructed. In practice for an application you should use a library like scikit-learn.Data Conditional Independence
Data Conditional Independence
+Feature Conditional Independence
Feature Conditional Independence
+Marginal Density for \(y_i\)
Marginal Density for \(y_i\)
+Joint Density for Naive Bayes
Joint Density for Naive Bayes
+import podsdata = pods.datasets.nigeria_nmis()['Y']Nigeria NMIS Data Classification
X, and labels y.import pandas as pd
-import numpy as np
+data = data[~pd.isnull(data['maternal_health_delivery_services'])]
+\]
+
+import pods
+data = pods.datasets.nigeria_nmis()['Y']Nigeria NMIS Data Classification
+
+X, and labels y.
+import pandas as pd
+import numpy as npdata = data[~pd.isnull(data['maternal_health_delivery_services'])]
data = data.dropna() # Remove entries with missing values
X = data[['emergency_transport',
'num_chews_fulltime',
@@ -198,7 +662,15 @@
type_col=htype.replace(' ', '_').replace('/','-').lower()
type_names.append(type_col)
X.loc[:, type_col] = 0.0
- X.loc[index, type_col] = 1.0X which contains the different facility types in different columns.X.describe()Naive Bayes NMIS
+# assume data is binary or real.
+ X.loc[index, type_col] = 1.0X which contains the different facility types in different columns.
+X.describe()Naive Bayes NMIS
+
+# assume data is binary or real.
# this list encodes whether it is binary or real (1 for binary, 0 for real)
binary_columns = ['emergency_transport',
'phcn_electricity',
@@ -214,14 +686,18 @@
'latitude',
'longitude']
Bernoulli = pd.DataFrame(data=np.zeros((2,len(binary_columns))), columns=binary_columns, index=['theta_0', 'theta_1'])
-Gaussian = pd.DataFrame(data=np.zeros((4,len(real_columns))), columns=real_columns, index=['mu_0', 'sigma2_0', 'mu_1', 'sigma2_1'])
+num_train = 20000
+Gaussian = pd.DataFrame(data=np.zeros((4,len(real_columns))), columns=real_columns, index=['mu_0', 'sigma2_0', 'mu_1', 'sigma2_1'])num_train = 20000
indices = np.random.permutation(X.shape[0])
train_indices = indices[:num_train]
test_indices = indices[num_train:]
X_train = X.iloc[train_indices]
y_train = y.iloc[train_indices]==True
X_test = X.iloc[test_indices]
-y_test = y.iloc[test_indices]==True
+for column in X_train:
+y_test = y.iloc[test_indices]==Truefor column in X_train:
if column in Gaussian:
Gaussian[column]['mu_0'] = X_train[column][~y_train].mean()
Gaussian[column]['mu_1'] = X_train[column][y_train].mean()
@@ -229,7 +705,18 @@
Gaussian[column]['sigma2_1'] = X_train[column][y_train].var(ddof=0)
if column in Bernoulli:
Bernoulli[column]['theta_0'] = X_train[column][~y_train].sum()/(~y_train).sum()
- Bernoulli[column]['theta_1'] = X_train[column][y_train].sum()/(y_train).sum()Bernoullitheta_0) for the facilities without maternity services and theta_1 for the facilities with maternity services. The parameters whow that, facilities with maternity services also are more likely to have other services such as grid electricity, emergency transport, immunization programs etc.Gaussianmu_1) than those without maternal services (mu_0). There is also a small difference between the mean latitude and longitudes. However, the standard deviation which would be given by the square root of the variance parameters (sigma_0 and sigma_1) is large, implying that a difference in latitude and longitude may be due to sampling error. To be sure more analysis would be required.prior = float(y_train.sum())/len(y_train)Making Predictions
+Bernoullitheta_0) for the facilities without maternity services and theta_1 for the facilities with maternity services. The parameters whow that, facilities with maternity services also are more likely to have other services such as grid electricity, emergency transport, immunization programs etc.
+Gaussianmu_1) than those without maternal services (mu_0). There is also a small difference between the mean latitude and longitudes. However, the standard deviation which would be given by the square root of the variance parameters (sigma_0 and sigma_1) is large, implying that a difference in latitude and longitude may be due to sampling error. To be sure more analysis would be required.
+prior = float(y_train.sum())/len(y_train)Making Predictions
+def log_gaussian(x, mu, sigma2):
- return -0.5* np.log(2*np.pi*sigma2)-((x-mu)**2)/(2*sigma2)def log_bernoulli(x, theta):
- return x*np.log(theta) + (1-x)*np.log(1-theta)Laplace Smoothing
theta here is either zero or one. This will result in \(\log 0 = -\infty\) and cause numerical problems. This definitely can happen in practice. If some of the features are rare or very common across the data set then the maximum likelihood solution could find values of zero or one respectively. Such values are problematic because they cause posterior probabilities of class membership of either one or zero. In practice we deal with this using Laplace smoothing (which actually has an interpretation as a Bayesian fit of the Bernoulli distribution. Laplace used an example of the sun rising each day, and a wish to predict the sun rise the following day to describe his idea of smoothing, which can be found at the bottom of following page from Laplace’s ‘Essai Philosophique …’
+def log_gaussian(x, mu, sigma2):
+ return -0.5* np.log(2*np.pi*sigma2)-((x-mu)**2)/(2*sigma2)
+def log_bernoulli(x, theta):
+ return x*np.log(theta) + (1-x)*np.log(1-theta)Laplace Smoothing
+theta here is either zero or one. This will result in \(\log 0 = -\infty\) and cause numerical problems. This definitely can happen in practice. If some of the features are rare or very common across the data set then the maximum likelihood solution could find values of zero or one respectively. Such values are problematic because they cause posterior probabilities of class membership of either one or zero. In practice we deal with this using Laplace smoothing (which actually has an interpretation as a Bayesian fit of the Bernoulli distribution. Laplace used an example of the sun rising each day, and a wish to predict the sun rise the following day to describe his idea of smoothing, which can be found at the bottom of following page from Laplace’s ‘Essai Philosophique …’
+# fit the Bernoulli with Laplace smoothing.
+\] to prevent problems with certainty causing numerical issues and misclassifications. Let’s refit the Bernoulli features now.
+# fit the Bernoulli with Laplace smoothing.
for column in X_train:
if column in Bernoulli:
Bernoulli[column]['theta_0'] = (X_train[column][~y_train].sum() + 1)/((~y_train).sum() + 2)
- Bernoulli[column]['theta_1'] = (X_train[column][y_train].sum() + 1)/((y_train).sum() + 2)import numpy as np
-import pandas as pd
+def predict(X_test, Gaussian, Bernoulli, prior):
+ Bernoulli[column]['theta_1'] = (X_train[column][y_train].sum() + 1)/((y_train).sum() + 2)
+import numpy as np
+import pandas as pddef predict(X_test, Gaussian, Bernoulli, prior):
log_positive = pd.Series(data = np.zeros(X_test.shape[0]), index=X_test.index)
log_negative = pd.Series(data = np.zeros(X_test.shape[0]), index=X_test.index)
for column in X_test.columns:
@@ -277,24 +776,40 @@
v[i] = np.exp(log_positive.values[i] + np.log(prior))/(np.exp(log_positive.values[i] + np.log(prior))
+ np.exp(log_negative.values[i] + np.log(1-prior)))
return v
- #return np.exp(log_positive + np.log(prior))/(np.exp(log_positive + np.log(prior)) + np.exp(log_negative + np.log(1-prior)))p_y = predict(X_test, Gaussian, Bernoulli, prior)
+correct = y_test.eq(p_y>0.5)
+ #return np.exp(log_positive + np.log(prior))/(np.exp(log_positive + np.log(prior)) + np.exp(log_negative + np.log(1-prior)))
+p_y = predict(X_test, Gaussian, Bernoulli, prior)correct = y_test.eq(p_y>0.5)
total_correct = sum(correct)
-print("Total correct", total_correct, " out of ", len(y_test), "which is", float(total_correct)/len(y_test), "%")
+confusion_matrix = pd.DataFrame(data=np.zeros((2,2)),
+print("Total correct", total_correct, " out of ", len(y_test), "which is", float(total_correct)/len(y_test), "%")confusion_matrix = pd.DataFrame(data=np.zeros((2,2)),
columns=['predicted no maternity', 'predicted maternity'],
index =['actual no maternity','actual maternity'])
confusion_matrix['predicted maternity']['actual maternity'] = (y_test & (p_y>0.5)).sum()
confusion_matrix['predicted maternity']['actual no maternity'] = (~y_test & (p_y>0.5)).sum()
confusion_matrix['predicted no maternity']['actual maternity'] = (y_test & ~(p_y>0.5)).sum()
confusion_matrix['predicted no maternity']['actual no maternity'] = (~y_test & ~(p_y>0.5)).sum()
-confusion_matrixExercise 5
Exercise 6
Making Predictions
Exercise 5
+Exercise 6
+Making Predictions
+Exercise 7
Exercise 7
+Naive Bayes Summary
Other Reading
References
Thanks!
+\] which means we can minimize our objective on each feature independently.Bishop, C.M., 2006. Pattern recognition and machine learning. springer.Pearl, J., 1995. From Bayesian networks to causal networks, in: Gammerman, A. (Ed.), Probabilistic Reasoning and Bayesian Belief Networks. Alfred Waller, pp. 1–31.Rogers, S., Girolami, M., 2011. A first course in machine learning. CRC Press.Steele, S., Bilchik, A., Eberhardt, J., Kalina, P., Nissan, A., Johnson, E., Avital, I., Stojadinovic, A., 2012. Using machine-learned Bayesian belief networks to predict perioperative risk of clostridium difficile infection following colon surgery. Interact J Med Res 1, e6. https://doi.org/10.2196/ijmr.2131The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs), Columbia University, 2014. Nigeria NMIS facility database.Naive Bayes Summary
+Other Reading
+
+
+References
+Thanks!
+
+
+
+
diff --git a/_lectures/03-probabilistic-machine-learning.html b/_lectures/03-probabilistic-machine-learning.html
index b9c552c..f4f53a2 100644
--- a/_lectures/03-probabilistic-machine-learning.html
+++ b/_lectures/03-probabilistic-machine-learning.html
@@ -15,9 +15,8 @@
date: 2018-11-16
session: 3
reveal: 03-probabilistic-machine-learning.slides.html
-transition: None
+transition: none
ipynb: 03-probabilistic-machine-learning.ipynb
-pptx: 03-probabilistic-machine-learning.pptx
layout: lecture
categories:
- notes
@@ -25,45 +24,247 @@
-
+
+
+
+
+
+
+
+
+
+Bishop, C.M., 2006. Pattern recognition and machine learning. springer.
+
+
+Pearl, J., 1995. From Bayesian networks to causal networks, in: Gammerman, A. (Ed.), Probabilistic Reasoning and Bayesian Belief Networks. Alfred Waller, pp. 1–31.
+
+
+Rogers, S., Girolami, M., 2011. A first course in machine learning. CRC Press.
+
+
+Steele, S., Bilchik, A., Eberhardt, J., Kalina, P., Nissan, A., Johnson, E., Avital, I., Stojadinovic, A., 2012. Using machine-learned Bayesian belief networks to predict perioperative risk of clostridium difficile infection following colon surgery. Interact J Med Res 1, e6. https://doi.org/10.2196/ijmr.2131
+
+
+The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs), Columbia University, 2014. Nigeria NMIS facility database.
+
+What is Machine Learning?
Probabilities
What is Machine Learning?
+
+Probabilities
+
+Nigeria NMIS Data
pods librarypods
import importlib.utilcmd = install_command('pods')%system {cmd}pods is installed, it can be imported in the usual manner.import podsdata = pods.datasets.nigeria_nmis()['Y']
-data.head()
+import urllib.request
+\]
+Nigeria NMIS Data
+
+
+
+pods librarypods
+
+
+import importlib.util
+cmd = install_command('pods')
+%system {cmd}pods is installed, it can be imported in the usual manner.
+import pods
+data = pods.datasets.nigeria_nmis()['Y']
+data.head()import urllib.request
urllib.request.urlretrieve('https://energydata.info/dataset/f85d1796-e7f2-4630-be84-79420174e3bd/resource/6e640a13-cab4-457b-b9e6-0336051bac27/download/healthmopupandbaselinenmisfacility.csv', 'healthmopupandbaselinenmisfacility.csv')
import pandas as pd
-data = pd.read_csv('healthmopupandbaselinenmisfacility.csv')describe method in pandas.data.describe()shape property.data.shape.<Tab> for example in the above case if we type data.<Tab> it show the columns available (these are attributes in pandas dataframes) such as num_nurses_fulltime, and also functions, such as .describe().data.describe?Exploring the NMIS Data
S, the most widely used of which is R. The data frame gives us a convenient object for manipulating data. The describe method summarizes which columns there are in the data frame and gives us counts, means, standard deviations and percentiles for the values in those columns. To access a column directly we can writeprint(data['num_doctors_fulltime'])
-#print(data['num_nurses_fulltime'])import matplotlib.pyplot as plt # this imports the plotting library in python_ = plt.plot(data['num_doctors_fulltime'], data['num_nurses_fulltime'], 'rx')plt.plot are for, now is the perfect time to look at the documentationplt.plot?data[data['num_nurses_fulltime']>100]data['num_nurses_fulltime']>100 to index the facilities in the pandas data frame which have over 100 nurses. To sort them in order we can also use the sort command. The result of this command on its own is a data Series of True and False values. However, when it is passed to the data data frame it returns a new data frame which contains only those values for which the data series is True. We can also sort the result. To sort the result by the values in the num_nurses_fulltime column in descending order we use the following command.data[data['num_nurses_fulltime']>100].sort_values(by='num_nurses_fulltime', ascending=False)Plotting the Data
data['num_nurses_fulltime'].hist(bins=20) # histogram the data with 20 bins.
-plt.title('Histogram of Number of Nurses')
+data['num_nurses_fulltime'].hist(bins=100) # histogram the data with 20 bins.
+data = pd.read_csv('healthmopupandbaselinenmisfacility.csv')describe method in pandas.
+data.describe()shape property.
+data.shape.<Tab> for example in the above case if we type data.<Tab> it show the columns available (these are attributes in pandas dataframes) such as num_nurses_fulltime, and also functions, such as .describe().
+data.describe?
+
+
+
+
+
+
+
+
+
+
+
+Exploring the NMIS Data
+
+S, the most widely used of which is R. The data frame gives us a convenient object for manipulating data. The describe method summarizes which columns there are in the data frame and gives us counts, means, standard deviations and percentiles for the values in those columns. To access a column directly we can write
+print(data['num_doctors_fulltime'])
+#print(data['num_nurses_fulltime'])
+import matplotlib.pyplot as plt # this imports the plotting library in python
+_ = plt.plot(data['num_doctors_fulltime'], data['num_nurses_fulltime'], 'rx')plt.plot are for, now is the perfect time to look at the documentation
+plt.plot?
+data[data['num_nurses_fulltime']>100]data['num_nurses_fulltime']>100 to index the facilities in the pandas data frame which have over 100 nurses. To sort them in order we can also use the sort command. The result of this command on its own is a data Series of True and False values. However, when it is passed to the data data frame it returns a new data frame which contains only those values for which the data series is True. We can also sort the result. To sort the result by the values in the num_nurses_fulltime column in descending order we use the following command.
+data[data['num_nurses_fulltime']>100].sort_values(by='num_nurses_fulltime', ascending=False)Plotting the Data
+
+data['num_nurses_fulltime'].hist(bins=20) # histogram the data with 20 bins.
+plt.title('Histogram of Number of Nurses')data['num_nurses_fulltime'].hist(bins=100) # histogram the data with 20 bins.
plt.title('Histogram of Number of Nurses')
ax = plt.gca()
-ax.set_yscale('log')
+fig, ax = plt.subplots(figsize=(10, 7))
+ax.set_yscale('log')fig, ax = plt.subplots(figsize=(10, 7))
ax.plot(data['num_doctors_fulltime'], data['num_nurses_fulltime'], 'rx')
ax.set_xscale('log') # use a logarithmic x scale
ax.set_yscale('log') # use a logarithmic Y scale
# give the plot some titles and labels
plt.title('Number of Nurses against Number of Doctors')
plt.ylabel('number of nurses')
-plt.xlabel('number of doctors')Probability and the NMIS Data
+large = (data.num_nurses_fulltime>2).sum() # number of positive outcomes (in sum True counts as 1, False counts as 0)
+plt.xlabel('number of doctors')Probability and the NMIS Data
+
+large = (data.num_nurses_fulltime>2).sum() # number of positive outcomes (in sum True counts as 1, False counts as 0)
total_facilities = data.num_nurses_fulltime.count()
prob_large = float(large)/float(total_facilities)
-print("Probability of number of nurses being greather than 2 is:", prob_large)Conditioning
Conditioning
+
+large = ((data.num_nurses_fulltime>2) & (data.num_doctors_fulltime>1)).sum()
+\] However, we might believe that the number of nurses is dependent on the number of doctors. For this we can try estimating \(P(Y>2 | X>1)\) and compare the result, for example to \(P(Y>2|X\leq 1)\) using our empirical estimate of the probability.
+large = ((data.num_nurses_fulltime>2) & (data.num_doctors_fulltime>1)).sum()
total_large_doctors = (data.num_doctors_fulltime>1).sum()
prob_both_large = large/total_large_doctors
-print("Probability of number of nurses being greater than 2 given number of doctors is greater than 1 is:", prob_both_large)Exercise 1
%matplotlib inline we ran above will do that for you, it only needs to be run once per file).Terminology Mathematical notation Description joint \(P(X=x, Y=y)\) prob. that X=x and Y=y marginal \(P(X=x)\) prob. that X=x regardless of Y conditional \(P(X=x\vert Y=y)\) prob. that X=x given that Y=y A Pictorial Definition of Probability
Inspired by lectures from Christopher BishopDefinition of probability distributions
Terminology Definition Probability Notation Joint Probability \(\lim_{N\rightarrow\infty}\frac{n_{X=3,Y=4}}{N}\) \(P\left(X=3,Y=4\right)\) Marginal Probability \(\lim_{N\rightarrow\infty}\frac{n_{X=5}}{N}\) \(P\left(X=5\right)\) Conditional Probability \(\lim_{N\rightarrow\infty}\frac{n_{X=3,Y=4}}{n_{Y=4}}\) \(P\left(X=3\vert Y=4\right)\) Notational Details
Exercise 1
+%matplotlib inline we ran above will do that for you, it only needs to be run once per file).
+
+
+
+
+
+
+Terminology
+Mathematical notation
+Description
+
+
+joint
+\(P(X=x, Y=y)\)
+prob. that X=x and Y=y
+
+
+marginal
+\(P(X=x)\)
+prob. that X=x regardless of Y
+
+
+
+conditional
+\(P(X=x\vert Y=y)\)
+prob. that X=x given that Y=y
+A Pictorial Definition of Probability
+
+
+
+
+
+
+
+
+
+
+
+
+Inspired by lectures from Christopher Bishop
+
+Definition of probability distributions
+
+
+
+
+
+
+Terminology
+Definition
+Probability Notation
+
+
+Joint Probability
+\(\lim_{N\rightarrow\infty}\frac{n_{X=3,Y=4}}{N}\)
+\(P\left(X=3,Y=4\right)\)
+
+
+Marginal Probability
+\(\lim_{N\rightarrow\infty}\frac{n_{X=5}}{N}\)
+\(P\left(X=5\right)\)
+
+
+
+Conditional Probability
+\(\lim_{N\rightarrow\infty}\frac{n_{X=3,Y=4}}{n_{Y=4}}\)
+\(P\left(X=3\vert Y=4\right)\)
+Notational Details
+
+num_doctors = 1
+\] Sometimes I think of this as akin to the way in Python we can write ‘keyword arguments’ in functions. If we use keyword arguments, the ordering of arguments doesn’t matter.
+num_doctors = 1
large = (data.num_nurses_fulltime[data.num_doctors_fulltime==num_doctors]>2).sum()
total_facilities = data.num_nurses_fulltime.count() # this is total number of films
prob_large = float(large)/float(total_facilities)
-print("Probability of nurses being greater than 2 and number of doctors being", num_doctors, "is:", prob_large)The Product Rule
The Product Rule
+
+num_doctors=1
+\] We can see the relation working in practice for our data above by computing the different values for \(x=1\).
+num_doctors=1
num_nurses=2
p_x = float((data.num_doctors_fulltime==num_doctors).sum())/float(data.num_doctors_fulltime.count())
p_y_given_x = float((data.num_nurses_fulltime[data.num_doctors_fulltime==num_doctors]>num_nurses).sum())/float((data.num_doctors_fulltime==num_doctors).sum())
@@ -87,27 +295,148 @@
print("P(x) is", p_x)
print("P(y|x) is", p_y_given_x)
-print("P(y,x) is", p_y_and_x)The Sum Rule
The Sum Rule
+Exercise 2
Bayes’ Rule
Exercise 2
+Bayes’ Rule
+Further Reading
Exercises
Probabilities for Extracting Information from Data
data.columnsExercise 3
maternal_health_delivery_services. How would we go about doing it?Probabilistic Modelling
+
+
+
+
+
+
+
+
+
+Further Reading
+
+
+
+Exercises
+
+
+Probabilities for Extracting Information from Data
+
+
+data.columnsExercise 3
+maternal_health_delivery_services. How would we go about doing it?Probabilistic Modelling
+
+Graphical Models
Introduction to Classification
Graphical Models
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Introduction to Classification
+
+Classification Examples
Subsample of the MNIST Data
from sklearn.datasets import fetch_openmlmnist = fetch_openml('mnist_784', version=1, as_frame=False, parser='liac-arff')import numpy as np
+np.random.seed(0)
+\] The function \(f(\cdot)\) is known as the prediction function. The key challenges are (1) choosing which features, \(\mathbf{ x}\), are relevant in the prediction, (2) defining the appropriate class of function, \(f(\cdot)\), to use and (3) selecting the right parameters, \(\mathbf{ w}\).
+Classification Examples
+
+Subsample of the MNIST Data
+
+
+from sklearn.datasets import fetch_openml
+mnist = fetch_openml('mnist_784', version=1, as_frame=False, parser='liac-arff')
+import numpy as npnp.random.seed(0)
digits = [0,1,2,3,4]
N_per_digit = 100
Y = []
@@ -120,31 +449,153 @@
labels.append(np.ones(N_per_digit)*d)
Y = np.vstack(Y).astype(np.float64)
labels = np.hstack(labels)
-Y /= 255MNIST Digit Examples
Bernoulli Distribution
\(y\) 0 1 \(P(y)\) \((1-\pi)\) \(\pi\) MNIST Digit Examples
+
+
+
+
+
+
+
+
+
+
+
+Bernoulli Distribution
+
+
+
+
+
+
+
+
+\(y\)
+0
+1
+
+
+
+\(P(y)\)
+\((1-\pi)\)
+\(\pi\)
+
+def bernoulli(y_i, pi):
+ \] where our probability distribution is now written as a function of \(y\). This probability distribution is known as the Bernoulli distribution. The Bernoulli distribution is a clever trick for mathematically switching between two probabilities if we were to write it as code it would be better described as
+def bernoulli(y_i, pi):
if y_i == 1:
return pi
else:
- return 1-piMaximum Likelihood in the Bernoulli
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Maximum Likelihood in the Bernoulli
+
+Exercise 4
Exercise 4
+Naive Bayes Classifiers
scikit-learn, our purpose in this session is to help you understand how those engines are constructed. In practice for an application you should use a library like scikit-learn.
+
+Naive Bayes Classifiers
+
+scikit-learn, our purpose in this session is to help you understand how those engines are constructed. In practice for an application you should use a library like scikit-learn.Data Conditional Independence
Data Conditional Independence
+Feature Conditional Independence
Feature Conditional Independence
+Marginal Density for \(y_i\)
Marginal Density for \(y_i\)
+Joint Density for Naive Bayes
Joint Density for Naive Bayes
+import podsdata = pods.datasets.nigeria_nmis()['Y']Nigeria NMIS Data Classification
X, and labels y.import pandas as pd
-import numpy as np
+data = data[~pd.isnull(data['maternal_health_delivery_services'])]
+\]
+
+import pods
+data = pods.datasets.nigeria_nmis()['Y']Nigeria NMIS Data Classification
+
+X, and labels y.
+import pandas as pd
+import numpy as npdata = data[~pd.isnull(data['maternal_health_delivery_services'])]
data = data.dropna() # Remove entries with missing values
X = data[['emergency_transport',
'num_chews_fulltime',
@@ -191,7 +654,15 @@
type_col=htype.replace(' ', '_').replace('/','-').lower()
type_names.append(type_col)
X.loc[:, type_col] = 0.0
- X.loc[index, type_col] = 1.0X which contains the different facility types in different columns.X.describe()Naive Bayes NMIS
+# assume data is binary or real.
+ X.loc[index, type_col] = 1.0X which contains the different facility types in different columns.
+X.describe()Naive Bayes NMIS
+
+# assume data is binary or real.
# this list encodes whether it is binary or real (1 for binary, 0 for real)
binary_columns = ['emergency_transport',
'phcn_electricity',
@@ -207,14 +678,18 @@
'latitude',
'longitude']
Bernoulli = pd.DataFrame(data=np.zeros((2,len(binary_columns))), columns=binary_columns, index=['theta_0', 'theta_1'])
-Gaussian = pd.DataFrame(data=np.zeros((4,len(real_columns))), columns=real_columns, index=['mu_0', 'sigma2_0', 'mu_1', 'sigma2_1'])
+num_train = 20000
+Gaussian = pd.DataFrame(data=np.zeros((4,len(real_columns))), columns=real_columns, index=['mu_0', 'sigma2_0', 'mu_1', 'sigma2_1'])num_train = 20000
indices = np.random.permutation(X.shape[0])
train_indices = indices[:num_train]
test_indices = indices[num_train:]
X_train = X.iloc[train_indices]
y_train = y.iloc[train_indices]==True
X_test = X.iloc[test_indices]
-y_test = y.iloc[test_indices]==True
+for column in X_train:
+y_test = y.iloc[test_indices]==Truefor column in X_train:
if column in Gaussian:
Gaussian[column]['mu_0'] = X_train[column][~y_train].mean()
Gaussian[column]['mu_1'] = X_train[column][y_train].mean()
@@ -222,7 +697,18 @@
Gaussian[column]['sigma2_1'] = X_train[column][y_train].var(ddof=0)
if column in Bernoulli:
Bernoulli[column]['theta_0'] = X_train[column][~y_train].sum()/(~y_train).sum()
- Bernoulli[column]['theta_1'] = X_train[column][y_train].sum()/(y_train).sum()Bernoullitheta_0) for the facilities without maternity services and theta_1 for the facilities with maternity services. The parameters whow that, facilities with maternity services also are more likely to have other services such as grid electricity, emergency transport, immunization programs etc.Gaussianmu_1) than those without maternal services (mu_0). There is also a small difference between the mean latitude and longitudes. However, the standard deviation which would be given by the square root of the variance parameters (sigma_0 and sigma_1) is large, implying that a difference in latitude and longitude may be due to sampling error. To be sure more analysis would be required.prior = float(y_train.sum())/len(y_train)Making Predictions
+Bernoullitheta_0) for the facilities without maternity services and theta_1 for the facilities with maternity services. The parameters whow that, facilities with maternity services also are more likely to have other services such as grid electricity, emergency transport, immunization programs etc.
+Gaussianmu_1) than those without maternal services (mu_0). There is also a small difference between the mean latitude and longitudes. However, the standard deviation which would be given by the square root of the variance parameters (sigma_0 and sigma_1) is large, implying that a difference in latitude and longitude may be due to sampling error. To be sure more analysis would be required.
+prior = float(y_train.sum())/len(y_train)Making Predictions
+def log_gaussian(x, mu, sigma2):
- return -0.5* np.log(2*np.pi*sigma2)-((x-mu)**2)/(2*sigma2)def log_bernoulli(x, theta):
- return x*np.log(theta) + (1-x)*np.log(1-theta)Laplace Smoothing
theta here is either zero or one. This will result in \(\log 0 = -\infty\) and cause numerical problems. This definitely can happen in practice. If some of the features are rare or very common across the data set then the maximum likelihood solution could find values of zero or one respectively. Such values are problematic because they cause posterior probabilities of class membership of either one or zero. In practice we deal with this using Laplace smoothing (which actually has an interpretation as a Bayesian fit of the Bernoulli distribution. Laplace used an example of the sun rising each day, and a wish to predict the sun rise the following day to describe his idea of smoothing, which can be found at the bottom of following page from Laplace’s ‘Essai Philosophique …’
+def log_gaussian(x, mu, sigma2):
+ return -0.5* np.log(2*np.pi*sigma2)-((x-mu)**2)/(2*sigma2)
+def log_bernoulli(x, theta):
+ return x*np.log(theta) + (1-x)*np.log(1-theta)Laplace Smoothing
+theta here is either zero or one. This will result in \(\log 0 = -\infty\) and cause numerical problems. This definitely can happen in practice. If some of the features are rare or very common across the data set then the maximum likelihood solution could find values of zero or one respectively. Such values are problematic because they cause posterior probabilities of class membership of either one or zero. In practice we deal with this using Laplace smoothing (which actually has an interpretation as a Bayesian fit of the Bernoulli distribution. Laplace used an example of the sun rising each day, and a wish to predict the sun rise the following day to describe his idea of smoothing, which can be found at the bottom of following page from Laplace’s ‘Essai Philosophique …’
+# fit the Bernoulli with Laplace smoothing.
+\] to prevent problems with certainty causing numerical issues and misclassifications. Let’s refit the Bernoulli features now.
+# fit the Bernoulli with Laplace smoothing.
for column in X_train:
if column in Bernoulli:
Bernoulli[column]['theta_0'] = (X_train[column][~y_train].sum() + 1)/((~y_train).sum() + 2)
- Bernoulli[column]['theta_1'] = (X_train[column][y_train].sum() + 1)/((y_train).sum() + 2)import numpy as np
-import pandas as pd
+def predict(X_test, Gaussian, Bernoulli, prior):
+ Bernoulli[column]['theta_1'] = (X_train[column][y_train].sum() + 1)/((y_train).sum() + 2)
+import numpy as np
+import pandas as pddef predict(X_test, Gaussian, Bernoulli, prior):
log_positive = pd.Series(data = np.zeros(X_test.shape[0]), index=X_test.index)
log_negative = pd.Series(data = np.zeros(X_test.shape[0]), index=X_test.index)
for column in X_test.columns:
@@ -270,24 +768,40 @@
v[i] = np.exp(log_positive.values[i] + np.log(prior))/(np.exp(log_positive.values[i] + np.log(prior))
+ np.exp(log_negative.values[i] + np.log(1-prior)))
return v
- #return np.exp(log_positive + np.log(prior))/(np.exp(log_positive + np.log(prior)) + np.exp(log_negative + np.log(1-prior)))p_y = predict(X_test, Gaussian, Bernoulli, prior)
+correct = y_test.eq(p_y>0.5)
+ #return np.exp(log_positive + np.log(prior))/(np.exp(log_positive + np.log(prior)) + np.exp(log_negative + np.log(1-prior)))
+p_y = predict(X_test, Gaussian, Bernoulli, prior)correct = y_test.eq(p_y>0.5)
total_correct = sum(correct)
-print("Total correct", total_correct, " out of ", len(y_test), "which is", float(total_correct)/len(y_test), "%")
+confusion_matrix = pd.DataFrame(data=np.zeros((2,2)),
+print("Total correct", total_correct, " out of ", len(y_test), "which is", float(total_correct)/len(y_test), "%")confusion_matrix = pd.DataFrame(data=np.zeros((2,2)),
columns=['predicted no maternity', 'predicted maternity'],
index =['actual no maternity','actual maternity'])
confusion_matrix['predicted maternity']['actual maternity'] = (y_test & (p_y>0.5)).sum()
confusion_matrix['predicted maternity']['actual no maternity'] = (~y_test & (p_y>0.5)).sum()
confusion_matrix['predicted no maternity']['actual maternity'] = (y_test & ~(p_y>0.5)).sum()
confusion_matrix['predicted no maternity']['actual no maternity'] = (~y_test & ~(p_y>0.5)).sum()
-confusion_matrixExercise 5
Exercise 6
Making Predictions
Exercise 5
+Exercise 6
+Making Predictions
+Exercise 7
Exercise 7
+Naive Bayes Summary
Other Reading
References
+\] which means we can minimize our objective on each feature independently.Bishop, C.M., 2006. Pattern recognition and machine learning. springer.Pearl, J., 1995. From Bayesian networks to causal networks, in: Gammerman, A. (Ed.), Probabilistic Reasoning and Bayesian Belief Networks. Alfred Waller, pp. 1–31.Rogers, S., Girolami, M., 2011. A first course in machine learning. CRC Press.Steele, S., Bilchik, A., Eberhardt, J., Kalina, P., Nissan, A., Johnson, E., Avital, I., Stojadinovic, A., 2012. Using machine-learned Bayesian belief networks to predict perioperative risk of clostridium difficile infection following colon surgery. Interact J Med Res 1, e6. https://doi.org/10.2196/ijmr.2131The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs), Columbia University, 2014. Nigeria NMIS facility database.Naive Bayes Summary
+Other Reading
+
+
+References
+
+
diff --git a/_lectures/04-gaussian-processes.html b/_lectures/04-gaussian-processes.html
index 2da1704..a5cf855 100644
--- a/_lectures/04-gaussian-processes.html
+++ b/_lectures/04-gaussian-processes.html
@@ -8,9 +8,8 @@
time: "15:00 (West Africa Standard Time)"
session: 4
reveal: 04-gaussian-processes.slides.html
-transition: None
+transition: none
ipynb: 04-gaussian-processes.ipynb
-pptx: 04-gaussian-processes.pptx
layout: lecture
categories:
- notes
@@ -18,28 +17,507 @@
-
+
+
+
+
+
+
+
+
+
+Bishop, C.M., 2006. Pattern recognition and machine learning. springer.
+
+
+Pearl, J., 1995. From Bayesian networks to causal networks, in: Gammerman, A. (Ed.), Probabilistic Reasoning and Bayesian Belief Networks. Alfred Waller, pp. 1–31.
+
+
+Rogers, S., Girolami, M., 2011. A first course in machine learning. CRC Press.
+
+
+Steele, S., Bilchik, A., Eberhardt, J., Kalina, P., Nissan, A., Johnson, E., Avital, I., Stojadinovic, A., 2012. Using machine-learned Bayesian belief networks to predict perioperative risk of clostridium difficile infection following colon surgery. Interact J Med Res 1, e6. https://doi.org/10.2196/ijmr.2131
+
+
+The Office of the Senior Special Assistant to the President on the Millennium Development Goals (OSSAP-MDGs), Columbia University, 2014. Nigeria NMIS facility database.
+
+Setup
+Setup
+
+notutils
import importlib.utilcmd = install_command('notutils')%system {cmd}notutils is installed, it can be imported in the usual manner.import notutilspods
cmd = install_command('pods')%system {cmd}pods is installed, it can be imported in the usual manner.import podsmlai
mlai software is a suite of helper functions for teaching and demonstrating machine learning algorithms. It was first used in the Machine Learning and Adaptive Intelligence course in Sheffield in 2013.cmd = install_command('mlai')%system {cmd}mlai is installed, it can be imported in the usual manner.import mlai
-from mlai import plot
A First Course in Machine Learning
Example: Prediction of Malaria Incidence in Uganda
\martinMubangiziPicture{15%}\ricardoAndradePachecoPicture{15%}\johnQuinnPicture{15%}(Andrade-Pacheco et al., 2014; Mubangizi et al., 2014)Early Warning Systems
What is Machine Learning?
Overdetermined System
notutils
+
+
+import importlib.util
+cmd = install_command('notutils')
+%system {cmd}notutils is installed, it can be imported in the usual manner.
+import notutilspods
+
+
+cmd = install_command('pods')
+%system {cmd}pods is installed, it can be imported in the usual manner.
+import podsmlai
+
+mlai software is a suite of helper functions for teaching and demonstrating machine learning algorithms. It was first used in the Machine Learning and Adaptive Intelligence course in Sheffield in 2013.
+cmd = install_command('mlai')
+%system {cmd}mlai is installed, it can be imported in the usual manner.
+import mlai
+from mlai import plot
+
+
+
+
+
+
+
+
+
+
+
+A First Course in Machine Learning
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Example: Prediction of Malaria Incidence in Uganda
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+(Andrade-Pacheco et al., 2014; Mubangizi et al., 2014)
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Early Warning Systems
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+What is Machine Learning?
+
+Overdetermined System
+
+
+
+
+
+
+
+
+
+
+
+Pierre-Simon Laplace
Pierre-Simon Laplace
Laplace’s Determism
Laplace’s Gremlin
Latent Variables
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Pierre-Simon Laplace
+
+Pierre-Simon Laplace
+
+
+
+
+
+
+
+
+
+
+
+
+
+Laplace’s Determism
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Laplace’s Gremlin
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Latent Variables
+
+A Probabilistic Process
Two Important Gaussian Properties
Sum of Gaussians
A Probabilistic Process
+Two Important Gaussian Properties
+
+Sum of Gaussians
+Scaling a Gaussian
Scaling a Gaussian
+Laplace’s Idea
Height as a Function of Weight
Laplace’s Idea
+
+Height as a Function of Weight
+Olympic Marathon Data
cmd = install_command('pods')%system {cmd}import numpy as np
-import pods
+data = pods.datasets.olympic_marathon_men()
+\]
+Olympic Marathon Data
+
+
+
+
+
+
+
+
+
+
+
+
+
+cmd = install_command('pods')
+%system {cmd}
+import numpy as np
+import podsdata = pods.datasets.olympic_marathon_men()
x = data['X']
y = data['Y']
offset = y.mean()
scale = np.sqrt(y.var())
-yhat = (y - offset)/scaleRunning Example: Olympic Marathons
x and y are not pandas data frames for this example, they are just arrays of dimensionality \(n\times 1\), where \(n\) is the number of data.Maximum Likelihood: Iterative Solution
+
+
+
+
+
+
+
+
+
+Running Example: Olympic Marathons
+
+x and y are not pandas data frames for this example, they are just arrays of dimensionality \(n\times 1\), where \(n\) is the number of data.Maximum Likelihood: Iterative Solution
+m = -0.4
-c = 80Log Likelihood for Multivariate Regression
Quadratic Loss
+m = -0.4
+c = 80Log Likelihood for Multivariate Regression
+
+Quadratic Loss
+
+Bracket Expansion
Bracket Expansion
+Solution with Linear Algebra
Solution with Linear Algebra
+numpy we can define this vector as followsimport numpy as np
+# define the vector w
+\] In numpy we can define this vector as follows
+
+import numpy as np# define the vector w
w = np.zeros(shape=(2, 1))
w[0] = m
-w[1] = cDesign Matrix
Design Matrix
+numpy can be done with the following commands:import numpy as npPhi = np.hstack((np.ones_like(x), x))
-print(Phi)Writing the Objective with Linear Algebra
numpy can be done with the following commands:
+import numpy as np
+Phi = np.hstack((np.ones_like(x), x))
+print(Phi)Writing the Objective with Linear Algebra
+import numpy as npf = Phi@w # The @ sign performs matrix multiplication
+import numpy as np
+f = Phi@w # The @ sign performs matrix multiplication
+resid = (y-f)
+\] we find we have defined the model with two equations. One equation tells us the form of our predictive function and how it depends on its parameters, the other tells us the form of our objective function.
+resid = (y-f)
E = np.dot(resid.T, resid) # matrix multiplication on a single vector is equivalent to a dot product.
-print("Error function is:", E)Objective Optimization
Objective Optimization
+
+Multivariate Derivatives
Multivariate Derivatives
+Matching Dimensions in Matrix Multiplications
Matching Dimensions in Matrix Multiplications
+Differentiate the Objective
Differentiate the Objective
+Exercise 1
Update Equation for Global Optimum
Exercise 1
+Update Equation for Global Optimum
+Solving the Multivariate System
Solving the Multivariate System
+Multivariate Linear Regression
Movie Violence Data
Year, Body_Count, MPAA_Rating, Genre, Director, Actors, Length_Minutes, IMDB_Rating.import podsdata = pods.datasets.movie_body_count()
-movies = data['Y']print(', '.join(movies.columns))describe method in pandas.Multivariate Regression on Movie Violence Data
+select_features = ['Year', 'Body_Count', 'Length_Minutes']
+\] for \(\mathbf{ w}\).
+Multivariate Linear Regression
+Movie Violence Data
+
+Year, Body_Count, MPAA_Rating, Genre, Director, Actors, Length_Minutes, IMDB_Rating.
+import pods
+data = pods.datasets.movie_body_count()
+movies = data['Y']
+print(', '.join(movies.columns))describe method in pandas.Multivariate Regression on Movie Violence Data
+
+select_features = ['Year', 'Body_Count', 'Length_Minutes']
Phi = movies[select_features].copy()
Phi['Eins'] = 1 # add a column for the offset
-y = movies[['IMDB_Rating']]import numpy as np
-import pandas as pd
+solution = np.linalg.solve(Phi.T@Phi, Phi.T@y) # solve linear regression here
+y = movies[['IMDB_Rating']]
+import numpy as np
+import pandas as pdsolution = np.linalg.solve(Phi.T@Phi, Phi.T@y) # solve linear regression here
# Place the solution in the data frame
w = pd.DataFrame(data=solution,
index = Phi.columns, # columns of Phi become rows of w
- columns=['regression_coefficient']) # the column of Phi is the value of regression coefficientypred = pd.DataFrame(data=(Phi@w).values, columns=['IMDB_Rating'])
-resid = y-ypredwUnderdetermined System
Underdetermined System
Two Dimensional Gaussian
+ypred = pd.DataFrame(data=(Phi@w).values, columns=['IMDB_Rating'])
+resid = y-ypred
+
+
+
+
+
+
+
+
+
+
+wUnderdetermined System
+
+Underdetermined System
+
+
+
+
+
+
+
+
+
+
+Two Dimensional Gaussian
+
+Independence Assumption
+
+
+
+
+
+
+
+
+
+Independence Assumption
+
-displaycode{nu.display_plots(‘independent_height_weight{fig:0>3}.svg,’ directory=‘./ml,’ fig=IntSlider(0, 0, 7, 1))}
+displaycode{nu.display_plots(‘independent_height_weight{fig:0>3}.svg’, directory=‘./ml’, fig=IntSlider(0, 0, 7, 1))}
+
+
+
+
+
+
+
+
+
+Sampling Two Dimensional Variables
Independent Gaussians
Sampling Two Dimensional Variables
+
+
+
+
+
+
+Independent Gaussians
+
+Correlated Gaussian
Correlated Gaussian
+Basis Functions
Quadratic Basis
Basis Functions
+
+Quadratic Basis
+import numpy as np
+def quadratic(x, **kwargs):
+\] where we are still in the one dimensional input setting so \(\mathbf{ x}\) here represents a vector of our inputs with \(n\) elements.
+
+import numpy as npdef quadratic(x, **kwargs):
"""Take in a vector of input values and return the design matrix associated
with the basis functions."""
- return np.hstack([np.ones((x.shape[0], 1)), x, x**2])Functions Derived from Quadratic Basis
Functions Derived from Quadratic Basis
+Quadratic Functions
Rectified Linear Units
+
+
+
+
+
+
+
+
+
+Quadratic Functions
+
+
+
+
+
+
+
+
+
+
+Rectified Linear Units
+
+import numpy as npfrom mlai import reluFunctions Derived from Relu Basis
+import numpy as np
+from mlai import relu
+
+
+
+
+
+
+
+
+
+Functions Derived from Relu Basis
+Gaussian Processes
+
+
+
+
+
+
+
+
+
+Gaussian Processes
+Linear Model Overview
Linear Model Overview
+
+Gaussian Process
Basis Functions
Radial Basis Functions
Gaussian Process
+Basis Functions
+Radial Basis Functions
+
+from mlai import radialFunctions Derived from Radial Basis
+from mlai import radial
+
+
+
+
+
+
+
+
+
+Functions Derived from Radial Basis
+Marginal Likelihood
Generating from the Model
x_pred).Olympic Marathon Polynomial Sample
import numpy as np
-import pods
+data = pods.datasets.olympic_marathon_men()
+\]
+
+
+
+
+
+
+
+
+
+
+Marginal Likelihood
+
+Generating from the Model
+
+
+
+x_pred).Olympic Marathon Polynomial Sample
+
+
+import numpy as np
+import podsdata = pods.datasets.olympic_marathon_men()
x = data['X']
y = data['Y']
@@ -307,7 +1190,11 @@
yhat = (y - offset)/scale
xlim = (1876,2044)
-num_data = x.shape[0]from mlai import polynomialimport mlai
+degree=4
+num_data = x.shape[0]
+from mlai import polynomial
+import mlaidegree=4
alpha = 4
sigma2 = 0.1
num_pred_data = 100 # how many points to use for plotting predictions
@@ -315,12 +1202,57 @@
data_limits=xlim
basis = mlai.Basis(polynomial, number=degree+1, data_limits=data_limits)
Phi_pred = basis.Phi(x_pred)
-Phi = basis.Phi(x)Sampling from the Prior
np.random.normal.np.random.normal. Then we scale it by \(\sqrt{\alpha}\) to obtain a prior sample of \(\mathbf{ w}\).
+K = degree + 1
+Phi = basis.Phi(x)Sampling from the Prior
+np.random.normal.np.random.normal. Then we scale it by \(\sqrt{\alpha}\) to obtain a prior sample of \(\mathbf{ w}\).K = degree + 1
z_vec = np.random.normal(size=K)
w_sample = z_vec*np.sqrt(alpha)
-print(w_sample)import numpy as npf_sample = Phi_pred@w_samplexlim to ensure that the polynomials don’t go too large. These samples should be well behaved.Mean Output
+import numpy as np
+f_sample = Phi_pred@w_sample
+
+
+
+
+
+
+
+
+
+xlim to ensure that the polynomials don’t go too large. These samples should be well behaved.Mean Output
+import numpy as npf_sample = Phi_pred@w_sampleFunction Space View
+import numpy as np
+f_sample = Phi_pred@w_sample
+
+
+
+
+
+
+
+
+
+Function Space View
+K = alpha*Phi_pred@Phi_pred.Tnp.random.multivariate_normal command for sampling from a multivariate normal with covariance given by \(\mathbf{K}\) and zero mean,
+fig, ax = plt.subplots(figsize=plot.big_wide_figsize)
+\]
+
+K = alpha*Phi_pred@Phi_pred.Tnp.random.multivariate_normal command for sampling from a multivariate normal with covariance given by \(\mathbf{K}\) and zero mean,fig, ax = plt.subplots(figsize=plot.big_wide_figsize)
for i in range(10):
f_sample = np.random.multivariate_normal(mean=np.zeros(x_pred.size), cov=K)
ax.plot(x_pred.flatten(), f_sample.flatten(), linewidth=2)
-mlai.write_figure('gp-sample-basis-function.svg', directory='./kern')
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+sigma2 = 1.
-K = alpha*Phi_pred@Phi_pred.T + sigma2*np.eye(x_pred.size)
+fig, ax = plt.subplots(figsize=plot.big_wide_figsize)
+\] Sampling directly from this density gives us the noise corrupted functions,
+
+
+
+
+
+
+
+
+
+
+
+sigma2 = 1.
+K = alpha*Phi_pred@Phi_pred.T + sigma2*np.eye(x_pred.size)fig, ax = plt.subplots(figsize=plot.big_wide_figsize)
for i in range(10):
y_sample = np.random.multivariate_normal(mean=np.zeros(x_pred.size), cov=K)
plt.plot(x_pred.flatten(), y_sample.flatten())
mlai.write_figure('gp-sample-basis-function-plus-large-noise.svg',
- directory='./kern')Non-degenerate Gaussian Processes
+
+
+
+
+
+
+
+
+
+Non-degenerate Gaussian Processes
+
+\radfordNealPicture{15%}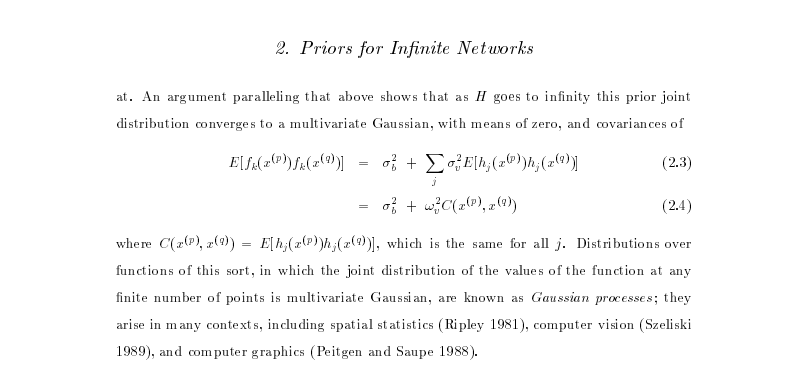 +
+
+
Further Reading
Gaussian Process
Further Reading
+Gaussian Process
+
+from mlai import eq_covx_pred. Let’s define a new function K() which does this,from mlai import Kernelkernel = mlai.Kernel(function=mlai.eq_cov, variance=1., lengthscale=10.)
-K = kernel.K(x_pred, x_pred)imshow function in matplotlib.Exercise 2
Bayesian Inference by Rejection Sampling
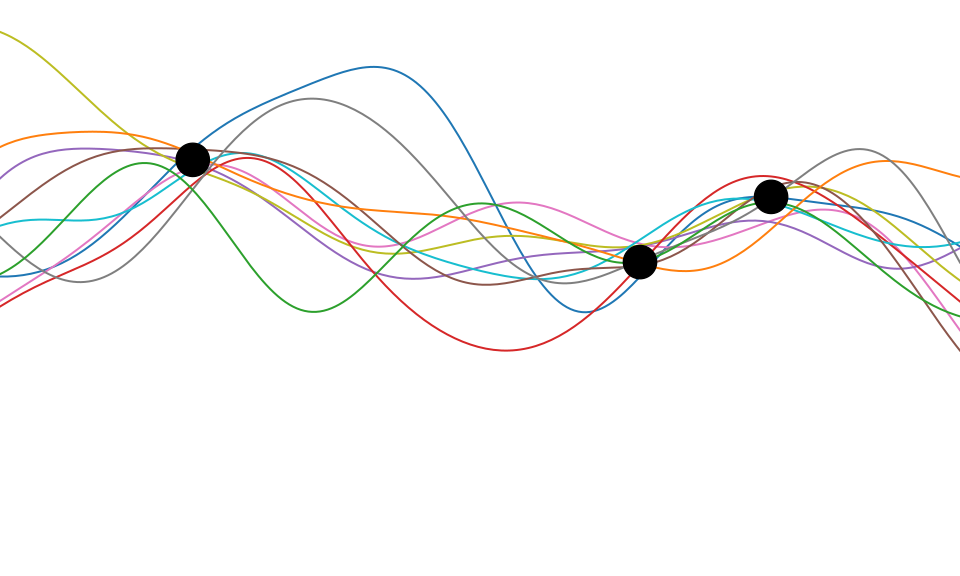
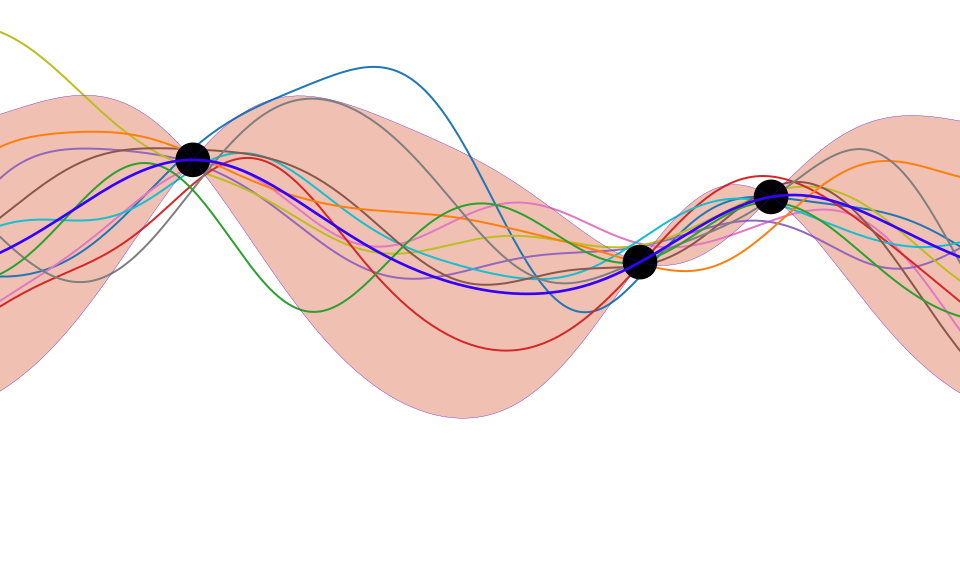
Making Predictions with Gaussian Process
+from mlai import eq_covx_pred. Let’s define a new function K() which does this,
+from mlai import Kernel
+kernel = mlai.Kernel(function=mlai.eq_cov, variance=1., lengthscale=10.)
+K = kernel.K(x_pred, x_pred)imshow function in matplotlib.Exercise 2
+Bayesian Inference by Rejection Sampling
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Making Predictions with Gaussian Process
+
+from mlai import ProbMapModelfrom mlai import GPMaking Predictions
+from mlai import ProbMapModel
+from mlai import GPMaking Predictions
+x and y for the training data (although y doesn’t enter the covariance) and x_pred as the test locations.
+# set covariance function parameters
+\] where here \(\mathbf{K}\) is the covariance computed between all the training points, \(\mathbf{K}_\ast\) is the covariance matrix computed between the training points and the test points and \(\mathbf{K}_{\ast,\ast}\) is the covariance matrix computed betwen all the tests points and themselves. To be clear, let’s compute these now for our example, using x and y for the training data (although y doesn’t enter the covariance) and x_pred as the test locations.
+# set covariance function parameters
variance = 16.0
lengthscale = 8
# set noise variance
@@ -393,76 +1492,662 @@
kernel = Kernel(eq_cov, variance=variance, lengthscale=lengthscale)
K = kernel.K(x, x)
K_star = kernel.K(x, x_pred)
-K_starstar = kernel.K(x_pred, x_pred)Prediction Across Two Points with GPs
Sampling a Function
+
+
+
+
+
+
+
+
+
+Prediction Across Two Points with GPs
+
+Sampling a Function
+
+import numpy as np
-np.random.seed(4949)from mlai import Kernelfrom mlai import polynomial_covfrom mlai import eq_covSampling a Function from a Gaussian
Joint Density of \(f_1\) and \(f_2\)
Uluru
Prediction of \(f_2\) from \(f_1\)
+import numpy as np
+np.random.seed(4949)
+from mlai import Kernel
+from mlai import polynomial_cov
+from mlai import eq_covSampling a Function from a Gaussian
+
+
+
+
+
+
+
+
+
+
+Joint Density of \(f_1\) and \(f_2\)
+
+
+
+
+
+
+
+
+
+
+Uluru
+
+
+
+
+
+
+
+
+
+
+
+
+Prediction of \(f_2\) from \(f_1\)
+Joint Density of \(f_1\) and \(f_8\)
Prediction of \(f_{8}\) from \(f_{1}\)
Joint Density of \(f_1\) and \(f_8\)
+
+
+
+
+
+
+
+
+
+
+
+Prediction of \(f_{8}\) from \(f_{1}\)
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
The Importance of the Covariance Function
The Importance of the Covariance Function
+
+Improving the Numerics
import scipy.linalg as lafrom mlai import GPfrom mlai import update_inverse# Bind the updated inverse to our GP model
-GP.update_inverse = update_inverseCapacity Control
+
+
+
+
+
+
+
+
+
+Improving the Numerics
+
+
+import scipy.linalg as la
+from mlai import GP
+from mlai import update_inverse
+# Bind the updated inverse to our GP model
+GP.update_inverse = update_inverseCapacity Control
+Gradients of the Likelihood
Overall Process Scale
Capacity Control and Data Fit
Learning Covariance Parameters
Gradients of the Likelihood
+Overall Process Scale
+Capacity Control and Data Fit
+Learning Covariance Parameters
+
+Capacity Control through the Determinant
 \(\boldsymbol{ \Lambda}\) represents distance on axes. \(\mathbf{R}\) gives rotation.
Quadratic Data Fit
Data Fit Term
+x = np.linspace(-1, 1, 6)[:, np.newaxis]
+\]
+Capacity Control through the Determinant
+
+
+
+
+
+
+
+
+
+\(\boldsymbol{ \Lambda}\) represents distance on axes. \(\mathbf{R}\) gives rotation.
+
+
+
+
+
+
+
+
+
+
+
+
+
+Quadratic Data Fit
+
+
+
+
+
+
+
+
+
+
+
+Data Fit Term
+
+x = np.linspace(-1, 1, 6)[:, np.newaxis]
xtest = np.linspace(x_lim[0], x_lim[1], 200)[:, np.newaxis]
# True data
true_kernel = Kernel(eq_cov, name='Exponentiated Quadratic', shortname='eq', lengthscale=1)
K = true_kernel.K(x) + np.eye(6)*0.01
-y = np.random.multivariate_normal(np.zeros((6,)), K, 1).T
+
+y = np.random.multivariate_normal(np.zeros((6,)), K, 1).T
# Fitted model
kernel = Kernel(eq_cov, name='Exponentiated Quadratic', shortname='eq', lengthscale=1)
-gp = GP(x, y, sigma2=0.01, kernel=kernel)Exponentiated Quadratic Covariance
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+Exponentiated Quadratic Covariance
+
+
GPSS: Gaussian Process Summer School
cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python
GPy Tutorial
\jamesHensmanPicture{15%}\nicolasDurrandePicture{15%}cmd = install_command('GPy')%system {cmd}cmd = install_command('mlai')%system {cmd}import numpy as np
-import GPy
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+GPSS: Gaussian Process Summer School
+
+
+
+
+
+cmd = install_command('GPy')
+%system {cmd}GPy: A Gaussian Process Framework in Python
+
+
+
+
+
+
+
+
+
+
+
+
+
+GPy Tutorial
+
+
+
+
+
+
+cmd = install_command('GPy')
+%system {cmd}
+cmd = install_command('mlai')
+%system {cmd}
+import numpy as np
+import GPy
+input_dim=1
+\] where the length scale is \(\ell\) and the variance is \(\alpha\).
+input_dim=1
alpha = 1.0
lengthscale = 2.0
-kern = GPy.kern.RBF(input_dim=input_dim, variance=alpha, lengthscale=lengthscale)display(kern)GPy.kern.plot command.kern = GPy.kern.RBF(input_dim=input_dim) # By default, the parameters are set to 1.
-lengthscales = np.asarray([0.2,0.5,1.,2.,4.])GPy.kern.plot command.Covariance Functions in GPy
exponential, Matern32, Matern52, Brownian, linear, bias, rbfcos, periodic_Matern32, etc. Some of these covariance functions, such as rbfcos, are not parametrized by a variance and a length scale. Further, not all kernels are stationary (i.e., they can’t all be written as \(k(\mathbf{ x}, \mathbf{ x}^\prime) = f(\mathbf{ x}-\mathbf{ x}^\prime)\), see for example the Brownian covariance function). So for plotting it may be interesting to change the value of the fixed input.Combining Covariance Functions in GPy
+ and *. So, for example, if we wish to combine an exponentiated quadratic covariance with a Matern 5/2 then we can write
+kern1 = GPy.kern.RBF(1, variance=1., lengthscale=2.)
+kern = GPy.kern.RBF(input_dim=input_dim, variance=alpha, lengthscale=lengthscale)
+display(kern)
+
+
+
+
+
+
+
+
+
+GPy.kern.plot command.
+kern = GPy.kern.RBF(input_dim=input_dim) # By default, the parameters are set to 1.
+lengthscales = np.asarray([0.2,0.5,1.,2.,4.])
+
+
+
+
+
+
+
+
+
+GPy.kern.plot command.Covariance Functions in GPy
+exponential, Matern32, Matern52, Brownian, linear, bias, rbfcos, periodic_Matern32, etc. Some of these covariance functions, such as rbfcos, are not parametrized by a variance and a length scale. Further, not all kernels are stationary (i.e., they can’t all be written as \(k(\mathbf{ x}, \mathbf{ x}^\prime) = f(\mathbf{ x}-\mathbf{ x}^\prime)\), see for example the Brownian covariance function). So for plotting it may be interesting to change the value of the fixed input.Combining Covariance Functions in GPy
++ and *. So, for example, if we wish to combine an exponentiated quadratic covariance with a Matern 5/2 then we can writekern1 = GPy.kern.RBF(1, variance=1., lengthscale=2.)
kern2 = GPy.kern.Matern52(1, variance=2., lengthscale=4.)
kern = kern1 + kern2
-display(kern)
+kern1 = GPy.kern.RBF(1, variance=1., lengthscale=2.)
+display(kern)
+
+
+
+
+
+
+
+
+
+kern1 = GPy.kern.RBF(1, variance=1., lengthscale=2.)
kern2 = GPy.kern.Matern52(1, variance=2., lengthscale=4.)
kern = kern1 * kern2
-display(kern)A Gaussian Process Regression Model
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+A Gaussian Process Regression Model
+X = np.linspace(0.05,0.95,10)[:,np.newaxis]
-Y = -np.cos(np.pi*X) + np.sin(4*np.pi*X) + np.random.normal(loc=0.0, scale=0.1, size=(10,1))kern = GPy.kern.RBF(input_dim=1, variance=1., lengthscale=1.)model = GPy.models.GPRegression(X,Y,kern)display(model).display(model)model.plot().Xstar = np.linspace(0, 10, 100)[:, np.newaxis]
-Ystar, Vstar = model.predict(Xstar)Ystar), the variance (Vstar) at the locations given by Xstar.Covariance Function Parameter Estimation
model.constrain_positive()model.optimize() method. Here we switch messages on, which allows us to see the progression of the optimization.model.optimize(messages=True)display(model)Review
Other Software
Further Reading
Thanks!
References
+\] with the noise being Gaussian distributed, \(\epsilon\sim \mathscr{N}\left(0,0.01\right)\).Andrade-Pacheco, R., Mubangizi, M., Quinn, J., Lawrence, N.D., 2014. Consistent mapping of government malaria records across a changing territory delimitation. Malaria Journal 13, 5. https://doi.org/10.1186/1475-2875-13-S1-P5Byrd, R.H., Lu, P., Nocedal, J., 1995. A limited memory algorithm for bound constrained optimization. SIAM Journal on Scientific and Statistical Computing 16, 1190–1208.Cho, Y., Saul, L.K., 2009. Kernel methods for deep learning, in: Bengio, Y., Schuurmans, D., Lafferty, J.D., Williams, C.K.I., Culotta, A. (Eds.), Advances in Neural Information Processing Systems 22. Curran Associates, Inc., pp. 342–350.Gething, P.W., Noor, A.M., Gikandi, P.W., Ogara, E.A.A., Hay, S.I., Nixon, M.S., Snow, R.W., Atkinson, P.M., 2006. Improving imperfect data from health management information systems in Africa using space–time geostatistics. PLoS Medicine 3. https://doi.org/10.1371/journal.pmed.0030271Ioffe, S., Szegedy, C., 2015. Batch normalization: Accelerating deep network training by reducing internal covariate shift, in: Bach, F., Blei, D. (Eds.), Proceedings of the 32nd International Conference on Machine Learning, Proceedings of Machine Learning Research. PMLR, Lille, France, pp. 448–456.Laplace, P.S., 1814. Essai philosophique sur les probabilités, 2nd ed. Courcier, Paris.MacKay, D.J.C., 1992. Bayesian methods for adaptive models (PhD thesis). California Institute of Technology.Mubangizi, M., Andrade-Pacheco, R., Smith, M.T., Quinn, J., Lawrence, N.D., 2014. Malaria surveillance with multiple data sources using Gaussian process models, in: 1st International Conference on the Use of Mobile ICT in Africa.Neal, R.M., 1994. Bayesian learning for neural networks (PhD thesis). Dept. of Computer Science, University of Toronto.Rasmussen, C.E., Williams, C.K.I., 2006. Gaussian processes for machine learning. mit, Cambridge, MA.Rogers, S., Girolami, M., 2011. A first course in machine learning. CRC Press.Tipping, M.E., Bishop, C.M., 1999. Probabilistic principal component analysis. Journal of the Royal Statistical Society, B 6, 611–622. https://doi.org/doi:10.1111/1467-9868.00196
+X = np.linspace(0.05,0.95,10)[:,np.newaxis]
+Y = -np.cos(np.pi*X) + np.sin(4*np.pi*X) + np.random.normal(loc=0.0, scale=0.1, size=(10,1))
+
+
+
+
+
+
+
+
+
+
+kern = GPy.kern.RBF(input_dim=1, variance=1., lengthscale=1.)
+model = GPy.models.GPRegression(X,Y,kern)display(model).
+display(model)model.plot().
+
+
+
+
+
+
+
+
+
+
+Xstar = np.linspace(0, 10, 100)[:, np.newaxis]
+Ystar, Vstar = model.predict(Xstar)Ystar), the variance (Vstar) at the locations given by Xstar.Covariance Function Parameter Estimation
+
+model.constrain_positive()model.optimize() method. Here we switch messages on, which allows us to see the progression of the optimization.
+model.optimize(messages=True)
+display(model)
+
+
+
+
+
+
+
+
+
+Review
+Other Software
+
+Further Reading
+
+
+Thanks!
+
+
+References
+
+
diff --git a/_notebooks/01-what-is-machine-learning.ipynb b/_notebooks/01-what-is-machine-learning.ipynb
index 5eab96f..a0b8239 100644
--- a/_notebooks/01-what-is-machine-learning.ipynb
+++ b/_notebooks/01-what-is-machine-learning.ipynb
@@ -11,7 +11,8 @@
"and University of Sheffield\n",
"\n",
"### 2019-06-03"
- ]
+ ],
+ "id": "53e6aa5c-5369-41af-87ef-c54ffc7a84c8"
},
{
"cell_type": "markdown",
@@ -22,7 +23,8 @@
"prediction function and the objective function. We don’t so much focus\n",
"on the derivation of particular algorithms, but more the general\n",
"principles involved to give an idea of the machine learning *landscape*."
- ]
+ ],
+ "id": "2dcec9fe-b2a6-43e3-b933-9857d64e7577"
},
{
"cell_type": "markdown",
@@ -30,7 +32,8 @@
"source": [
"$$\n",
"$$"
- ]
+ ],
+ "id": "16e25da9-5a39-4d46-9eb1-b3c1ff254a8b"
},
{
"cell_type": "markdown",
@@ -50,14 +53,16 @@
""
- ]
+ ],
+ "id": "1cd2c862-9ff6-45b2-8d53-92275010339d"
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"# Introduction"
- ]
+ ],
+ "id": "81489a63-982b-4382-997e-c0a123d7663d"
},
{
"cell_type": "markdown",
@@ -65,8 +70,8 @@
"source": [
"## Data Science Africa\n",
"\n",
- "\\[
+Andrade-Pacheco, R., Mubangizi, M., Quinn, J., Lawrence, N.D., 2014. Consistent mapping of government malaria records across a changing territory delimitation. Malaria Journal 13, 5. https://doi.org/10.1186/1475-2875-13-S1-P5
+
+
+Byrd, R.H., Lu, P., Nocedal, J., 1995. A limited memory algorithm for bound constrained optimization. SIAM Journal on Scientific and Statistical Computing 16, 1190–1208.
+
+
+Cho, Y., Saul, L.K., 2009. Kernel methods for deep learning, in: Bengio, Y., Schuurmans, D., Lafferty, J.D., Williams, C.K.I., Culotta, A. (Eds.), Advances in Neural Information Processing Systems 22. Curran Associates, Inc., pp. 342–350.
+
+
+Gething, P.W., Noor, A.M., Gikandi, P.W., Ogara, E.A.A., Hay, S.I., Nixon, M.S., Snow, R.W., Atkinson, P.M., 2006. Improving imperfect data from health management information systems in Africa using space–time geostatistics. PLoS Medicine 3. https://doi.org/10.1371/journal.pmed.0030271
+
+
+Ioffe, S., Szegedy, C., 2015. Batch normalization: Accelerating deep network training by reducing internal covariate shift, in: Bach, F., Blei, D. (Eds.), Proceedings of the 32nd International Conference on Machine Learning, Proceedings of Machine Learning Research. PMLR, Lille, France, pp. 448–456.
+
+
+Laplace, P.S., 1814. Essai philosophique sur les probabilités, 2nd ed. Courcier, Paris.
+
+
+MacKay, D.J.C., 1992. Bayesian methods for adaptive models (PhD thesis). California Institute of Technology.
+
+
+Mubangizi, M., Andrade-Pacheco, R., Smith, M.T., Quinn, J., Lawrence, N.D., 2014. Malaria surveillance with multiple data sources using Gaussian process models, in: 1st International Conference on the Use of Mobile ICT in Africa.
+
+
+Neal, R.M., 1994. Bayesian learning for neural networks (PhD thesis). Dept. of Computer Science, University of Toronto.
+
+
+Rasmussen, C.E., Williams, C.K.I., 2006. Gaussian processes for machine learning. mit, Cambridge, MA.
+
+
+Rogers, S., Girolami, M., 2011. A first course in machine learning. CRC Press.
+
+
+Tipping, M.E., Bishop, C.M., 1999. Probabilistic principal component analysis. Journal of the Royal Statistical Society, B 6, 611–622. https://doi.org/doi:10.1111/1467-9868.00196
+
+ \n",
@@ -89,7 +94,8 @@
"Uganda; Arusha, Tanzania (twice); Abuja, Nigeria; Addis Ababa, Ethiopia;\n",
"Accra, Ghana; Kampala, Uganda and Kimberley, South Africa (virtual),\n",
"Kigali, Rwanda and Ibadan, Nigeria."
- ]
+ ],
+ "id": "9f4e2010-1eb2-4fcb-afd0-df6e66f111bd"
},
{
"cell_type": "markdown",
@@ -97,7 +103,7 @@
"source": [
"## DSA Ibadan, Nigeria\n",
"\n",
- "
