Figure: A key reference for Gaussian process models remains the excellent book “Gaussian Processes for Machine Learning” (Rasmussen and Williams (2006)). The book is also freely available online.
Figure: A key reference for Gaussian process models remains the excellent book “Gaussian Processes for Machine Learning” (Rasmussen and Williams (2006)). The book is also freely available online.
Rasmussen and Williams (2006) is still one of the most important references on Gaussian process models. It is available freely online.
What is machine learning? At its most basic level machine learning is a combination of
\[\text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}\]
where data is our observations. They can be actively or passively acquired (meta-data). The model contains our assumptions, based on previous experience. That experience can be other data, it can come from transfer learning, or it can merely be our beliefs about the regularities of the universe. In humans our models include our inductive biases. The prediction is an action to be taken or a categorization or a quality score. The reason that machine learning has become a mainstay of artificial intelligence is the importance of predictions in artificial intelligence. The data and the model are combined through computation.
In practice we normally perform machine learning using two functions. To combine data with a model we typically make use of:
a prediction function it is used to make the predictions. It includes our beliefs about the regularities of the universe, our assumptions about how the world works, e.g., smoothness, spatial similarities, temporal similarities.
an objective function it defines the ‘cost’ of misprediction. Typically, it includes knowledge about the world’s generating processes (probabilistic objectives) or the costs we pay for mispredictions (empirical risk minimization).
The combination of data and model through the prediction function and the objective function leads to a learning algorithm. The class of prediction functions and objective functions we can make use of is restricted by the algorithms they lead to. If the prediction function or the objective function are too complex, then it can be difficult to find an appropriate learning algorithm. Much of the academic field of machine learning is the quest for new learning algorithms that allow us to bring different types of models and data together.
A useful reference for state of the art in machine learning is the UK Royal Society Report, Machine Learning: Power and Promise of Computers that Learn by Example.
You can also check my post blog post on What is Machine Learning?.
We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling.
import importlib.utilcmd = install_command('pods')%system {cmd}cmd = install_command('notutils')%system {cmd}cmd = install_command('mlai')%system {cmd}
Figure: A key reference for Gaussian process models remains the excellent book “Gaussian Processes for Machine Learning” (Rasmussen and Williams (2006)). The book is also freely available online.
Rasmussen and Williams (2006) is still one of the most important references on Gaussian process models. It is available freely online.
What is machine learning? At its most basic level machine learning is a combination of
\[\text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}\]
where data is our observations. They can be actively or passively acquired (meta-data). The model contains our assumptions, based on previous experience. That experience can be other data, it can come from transfer learning, or it can merely be our beliefs about the regularities of the universe. In humans our models include our inductive biases. The prediction is an action to be taken or a categorization or a quality score. The reason that machine learning has become a mainstay of artificial intelligence is the importance of predictions in artificial intelligence. The data and the model are combined through computation.
In practice we normally perform machine learning using two functions. To combine data with a model we typically make use of:
a prediction function it is used to make the predictions. It includes our beliefs about the regularities of the universe, our assumptions about how the world works, e.g., smoothness, spatial similarities, temporal similarities.
an objective function it defines the ‘cost’ of misprediction. Typically, it includes knowledge about the world’s generating processes (probabilistic objectives) or the costs we pay for mispredictions (empirical risk minimization).
The combination of data and model through the prediction function and the objective function leads to a learning algorithm. The class of prediction functions and objective functions we can make use of is restricted by the algorithms they lead to. If the prediction function or the objective function are too complex, then it can be difficult to find an appropriate learning algorithm. Much of the academic field of machine learning is the quest for new learning algorithms that allow us to bring different types of models and data together.
A useful reference for state of the art in machine learning is the UK Royal Society Report, Machine Learning: Power and Promise of Computers that Learn by Example.
You can also check my post blog post on What is Machine Learning?.
We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling.
import importlib.utilcmd = install_command('pods')%system {cmd}cmd = install_command('notutils')%system {cmd}cmd = install_command('mlai')%system {cmd}cmd = install_command('GPy')%system {cmd}Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics.
Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy
GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries.
The software itself is available on GitHub and the team welcomes contributions.
The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets.
The documentation for GPy can be found here.

Image from Wikimedia Commons
The Olympic Marathon data is a standard dataset for regression modelling. The data consists of the pace of Olympic Gold Medal Marathon winners for the Olympics from 1896 to present. Let’s load in the data and plot.
cmd = install_command('pods')%system {cmd}import numpy as np
+sns.set_palette('colorblind')}-->cmd = install_command('GPy')
%system {cmd}
GPy: A Gaussian Process Framework in Python
Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics.

Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy
GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries.
The software itself is available on GitHub and the team welcomes contributions.
The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets.
The documentation for GPy can be found here.
Olympic Marathon Data
- Gold medal times for Olympic Marathon since 1896.
- Marathons before 1924 didn’t have a standardized distance.
- Present results using pace per km.
- In 1904 Marathon was badly organized leading to very slow times.

Image from Wikimedia Commons
The Olympic Marathon data is a standard dataset for regression modelling. The data consists of the pace of Olympic Gold Medal Marathon winners for the Olympics from 1896 to present. Let’s load in the data and plot.
cmd = install_command('pods')
%system {cmd}
import numpy as np
import pods
data = pods.datasets.olympic_marathon_men()
x = data['X']
y = data['Y']
offset = y.mean()
scale = np.sqrt(y.var())
-yhat = (y - offset)/scale
Figure: Olympic marathon pace times since 1896.
Things to notice about the data include the outlier in 1904, in that year the Olympics was in St Louis, USA. Organizational problems and challenges with dust kicked up by the cars following the race meant that participants got lost, and only very few participants completed. More recent years see more consistently quick marathons.
Overdetermined System
The challenge with a linear model is that it has two unknowns, \(m\), and \(c\). Observing data allows us to write down a system of simultaneous linear equations. So, for example if we observe two data points, the first with the input value, \(x_1 = 1\) and the output value, \(y_1 =3\) and a second data point, \(x= 3\), \(y=1\), then we can write two simultaneous linear equations of the form.
point 1: \(x= 1\), \(y=3\) \[
+yhat = (y - offset)/scale
Figure: Olympic marathon pace times since 1896.
Things to notice about the data include the outlier in 1904, in that year the Olympics was in St Louis, USA. Organizational problems and challenges with dust kicked up by the cars following the race meant that participants got lost, and only very few participants completed. More recent years see more consistently quick marathons.
The challenge with a linear model is that it has two unknowns, \(m\), and \(c\). Observing data allows us to write down a system of simultaneous linear equations. So, for example if we observe two data points, the first with the input value, \(x_1 = 1\) and the output value, \(y_1 =3\) and a second data point, \(x= 3\), \(y=1\), then we can write two simultaneous linear equations of the form.
point 1: \(x= 1\), \(y=3\) \[ 3 = m + c \] point 2: \(x= 3\), \(y=1\) \[ 1 = 3m + c -\]
The solution to these two simultaneous equations can be represented graphically as
Figure: The solution of two linear equations represented as the fit of a straight line through two data
The challenge comes when a third data point is observed, and it doesn’t fit on the straight line.
point 3: \(x= 2\), \(y=2.5\) \[ +\]
The solution to these two simultaneous equations can be represented graphically as
Figure: The solution of two linear equations represented as the fit of a straight line through two data
The challenge comes when a third data point is observed, and it doesn’t fit on the straight line.
point 3: \(x= 2\), \(y=2.5\) \[ 2.5 = 2m + c -\]
Figure: A third observation of data is inconsistent with the solution dictated by the first two observations
Now there are three candidate lines, each consistent with our data.
Figure: Three solutions to the problem, each consistent with two points of the three observations
This is known as an overdetermined system because there are more data than we need to determine our parameters. The problem arises because the model is a simplification of the real world, and the data we observe is therefore inconsistent with our model.
The solution was proposed by Pierre-Simon Laplace. His idea was to accept that the model was an incomplete representation of the real world, and the way it was incomplete is unknown. His idea was that such unknowns could be dealt with through probability.
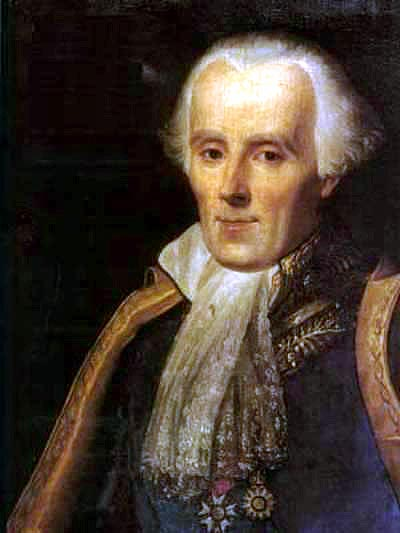
Figure: Pierre-Simon Laplace 1749-1827.
Figure: Laplace’s determinism book reference.
Famously, Laplace considered the idea of a deterministic Universe, one in which the model is known, or as the below translation refers to it, “an intelligence which could comprehend all the forces by which nature is animated.” He speculates on an “intelligence” that can submit this vast data to analysis and propsoses that such an entity would be able to predict the future.
Given for one instant an intelligence which could comprehend all the forces by which nature is animated and the respective situation of the beings who compose it—an intelligence sufficiently vast to submit these data to analysis—it would embrace in the same formulate the movements of the greatest bodies of the universe and those of the lightest atom; for it, nothing would be uncertain and the future, as the past, would be present in its eyes.
This notion is known as Laplace’s demon or Laplace’s superman.
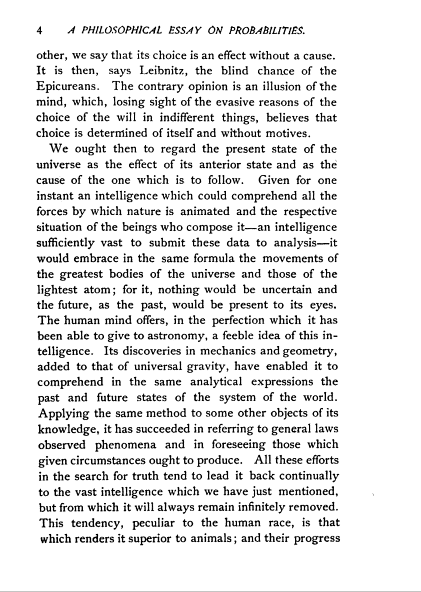
Figure: Laplace’s determinsim in English translation.
Unfortunately, most analyses of his ideas stop at that point, whereas his real point is that such a notion is unreachable. Not so much superman as strawman. Just three pages later in the “Philosophical Essay on Probabilities” (Laplace, 1814), Laplace goes on to observe:
The curve described by a simple molecule of air or vapor is regulated in a manner just as certain as the planetary orbits; the only difference between them is that which comes from our ignorance.
Probability is relative, in part to this ignorance, in part to our knowledge.
Figure: Laplace’s gremlin in the original French.
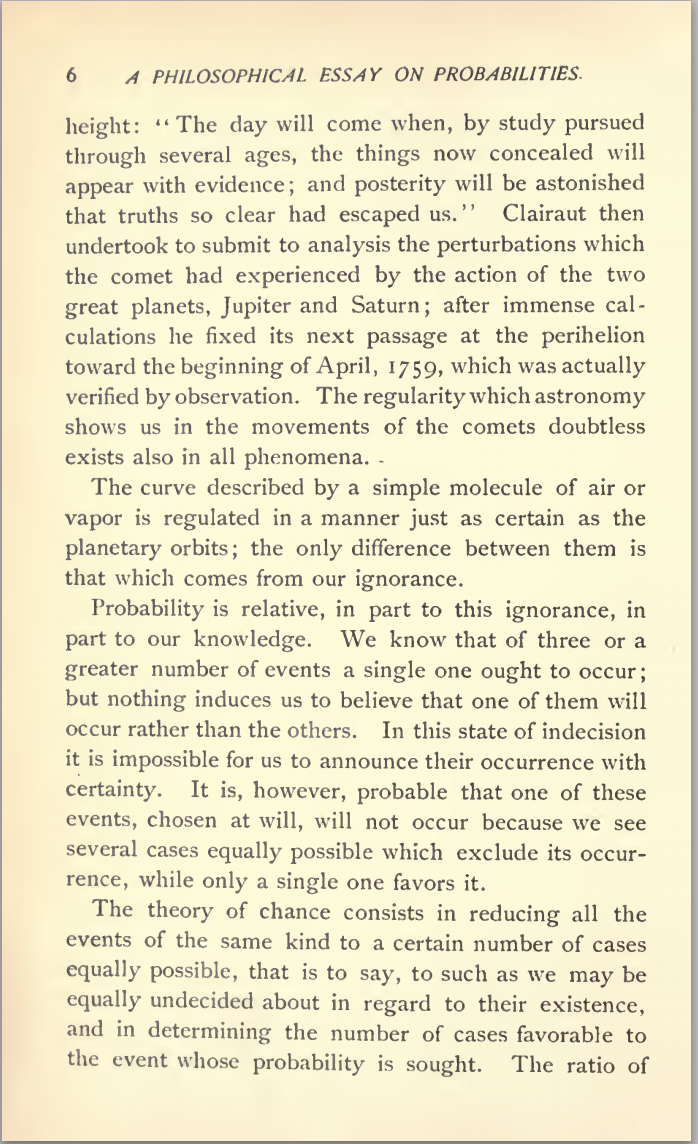
Figure: To Laplace, determinism is a strawman. Ignorance of mechanism and data leads to uncertainty which should be dealt with through probability.
In other words, we can never make use of the idealistic deterministic Universe due to our ignorance about the world, Laplace’s suggestion, and focus in this essay is that we turn to probability to deal with this uncertainty. This is also our inspiration for using probability in machine learning. This is the true message of Laplace’s essay, not determinism, but the gremlin of uncertainty that emerges from our ignorance.
The “forces by which nature is animated” is our model, the “situation of beings that compose it” is our data and the “intelligence sufficiently vast enough to submit these data to analysis” is our compute. The fly in the ointment is our ignorance about these aspects. And probability is the tool we use to incorporate this ignorance leading to uncertainty or doubt in our predictions.
Laplace’s concept was that the reason that the data doesn’t match up to the model is because of unconsidered factors, and that these might be well represented through probability densities. He tackles the challenge of the unknown factors by adding a variable, \(\epsilon\), that represents the unknown. In modern parlance we would call this a latent variable. But in the context Laplace uses it, the variable is so common that it has other names such as a “slack” variable or the noise in the system.
point 1: \(x= 1\), \(y=3\) \[ +\]
Figure: A third observation of data is inconsistent with the solution dictated by the first two observations
Now there are three candidate lines, each consistent with our data.
Figure: Three solutions to the problem, each consistent with two points of the three observations
This is known as an overdetermined system because there are more data than we need to determine our parameters. The problem arises because the model is a simplification of the real world, and the data we observe is therefore inconsistent with our model.
The solution was proposed by Pierre-Simon Laplace. His idea was to accept that the model was an incomplete representation of the real world, and the way it was incomplete is unknown. His idea was that such unknowns could be dealt with through probability.

Figure: Pierre-Simon Laplace 1749-1827.
Figure: Laplace’s determinism book reference.
Famously, Laplace considered the idea of a deterministic Universe, one in which the model is known, or as the below translation refers to it, “an intelligence which could comprehend all the forces by which nature is animated.” He speculates on an “intelligence” that can submit this vast data to analysis and propsoses that such an entity would be able to predict the future.
Given for one instant an intelligence which could comprehend all the forces by which nature is animated and the respective situation of the beings who compose it—an intelligence sufficiently vast to submit these data to analysis—it would embrace in the same formulate the movements of the greatest bodies of the universe and those of the lightest atom; for it, nothing would be uncertain and the future, as the past, would be present in its eyes.
This notion is known as Laplace’s demon or Laplace’s superman.

Figure: Laplace’s determinsim in English translation.
Unfortunately, most analyses of his ideas stop at that point, whereas his real point is that such a notion is unreachable. Not so much superman as strawman. Just three pages later in the “Philosophical Essay on Probabilities” (Laplace, 1814), Laplace goes on to observe:
The curve described by a simple molecule of air or vapor is regulated in a manner just as certain as the planetary orbits; the only difference between them is that which comes from our ignorance.
Probability is relative, in part to this ignorance, in part to our knowledge.
Figure: Laplace’s gremlin in the original French.

Figure: To Laplace, determinism is a strawman. Ignorance of mechanism and data leads to uncertainty which should be dealt with through probability.
In other words, we can never make use of the idealistic deterministic Universe due to our ignorance about the world, Laplace’s suggestion, and focus in this essay is that we turn to probability to deal with this uncertainty. This is also our inspiration for using probability in machine learning. This is the true message of Laplace’s essay, not determinism, but the gremlin of uncertainty that emerges from our ignorance.
The “forces by which nature is animated” is our model, the “situation of beings that compose it” is our data and the “intelligence sufficiently vast enough to submit these data to analysis” is our compute. The fly in the ointment is our ignorance about these aspects. And probability is the tool we use to incorporate this ignorance leading to uncertainty or doubt in our predictions.
Laplace’s concept was that the reason that the data doesn’t match up to the model is because of unconsidered factors, and that these might be well represented through probability densities. He tackles the challenge of the unknown factors by adding a variable, \(\epsilon\), that represents the unknown. In modern parlance we would call this a latent variable. But in the context Laplace uses it, the variable is so common that it has other names such as a “slack” variable or the noise in the system.
point 1: \(x= 1\), \(y=3\) \[ 3 = m + c + \epsilon_1 \] point 2: \(x= 3\), \(y=1\) \[ 1 = 3m + c + \epsilon_2 @@ -51,9 +50,9 @@ 2.5 = 2m + c + \epsilon_3 \]
Laplace’s trick has converted the overdetermined system into an underdetermined system. He has now added three variables, \(\{\epsilon_i\}_{i=1}^3\), which represent the unknown corruptions of the real world. Laplace’s idea is that we should represent that unknown corruption with a probability distribution.
However, it was left to an admirer of Laplace to develop a practical probability density for that purpose. It was Carl Friedrich Gauss who suggested that the Gaussian density (which at the time was unnamed!) should be used to represent this error.
The result is a noisy function, a function which has a deterministic part, and a stochastic part. This type of function is sometimes known as a probabilistic or stochastic process, to distinguish it from a deterministic process.
The Gaussian density is perhaps the most commonly used probability density. It is defined by a mean, \(\mu\), and a variance, \(\sigma^2\). The variance is taken to be the square of the standard deviation, \(\sigma\).
\[\begin{align} p(y| \mu, \sigma^2) & = \frac{1}{\sqrt{2\pi\sigma^2}}\exp\left(-\frac{(y- \mu)^2}{2\sigma^2}\right)\\& \buildrel\triangle\over = \mathscr{N}\left(y|\mu,\sigma^2\right) - \end{align}\]
Figure: The Gaussian PDF with \({\mu}=1.7\) and variance \({\sigma}^2=0.0225\). Mean shown as red line. It could represent the heights of a population of students.
The Gaussian density has many important properties, but for the moment we’ll review two of them.
If we assume that a variable, \(y_i\), is sampled from a Gaussian density,
\[y_i \sim \mathscr{N}\left(\mu_i,\sigma_i^2\right)\]
Then we can show that the sum of a set of variables, each drawn independently from such a density is also distributed as Gaussian. The mean of the resulting density is the sum of the means, and the variance is the sum of the variances,
\[ + \end{align}\]
Figure: The Gaussian PDF with \({\mu}=1.7\) and variance \({\sigma}^2=0.0225\). Mean shown as red line. It could represent the heights of a population of students.
The Gaussian density has many important properties, but for the moment we’ll review two of them.
If we assume that a variable, \(y_i\), is sampled from a Gaussian density,
\[y_i \sim \mathscr{N}\left(\mu_i,\sigma_i^2\right)\]
Then we can show that the sum of a set of variables, each drawn independently from such a density is also distributed as Gaussian. The mean of the resulting density is the sum of the means, and the variance is the sum of the variances,
\[ \sum_{i=1}^{n} y_i \sim \mathscr{N}\left(\sum_{i=1}^n\mu_i,\sum_{i=1}^n\sigma_i^2\right) -\]
Since we are very familiar with the Gaussian density and its properties, it is not immediately apparent how unusual this is. Most random variables, when you add them together, change the family of density they are drawn from. For example, the Gaussian is exceptional in this regard. Indeed, other random variables, if they are independently drawn and summed together tend to a Gaussian density. That is the central limit theorem which is a major justification for the use of a Gaussian density.
Less unusual is the scaling property of a Gaussian density. If a variable, \(y\), is sampled from a Gaussian density,
\[y\sim \mathscr{N}\left(\mu,\sigma^2\right)\] and we choose to scale that variable by a deterministic value, \(w\), then the scaled variable is distributed as
\[wy\sim \mathscr{N}\left(w\mu,w^2 \sigma^2\right).\] Unlike the summing properties, where adding two or more random variables independently sampled from a family of densitites typically brings the summed variable outside that family, scaling many densities leaves the distribution of that variable in the same family of densities. Indeed, many densities include a scale parameter (e.g. the Gamma density) which is purely for this purpose. In the Gaussian the standard deviation, \(\sigma\), is the scale parameter. To see why this makes sense, let’s consider, \[z \sim \mathscr{N}\left(0,1\right),\] then if we scale by \(\sigma\) so we have, \(y=\sigma z\), we can write, \[y=\sigma z \sim \mathscr{N}\left(0,\sigma^2\right)\]
Regression involves predicting a real value, \(y_i\), given an input vector, \(\mathbf{ x}_i\). For example, the Tecator data involves predicting the quality of meat given spectral measurements. Or in radiocarbon dating, the C14 calibration curve maps from radiocarbon age to age measured through a back-trace of tree rings. Regression has also been used to predict the quality of board game moves given expert rated training data.
What about the situation where you have more parameters than data in your simultaneous equation? This is known as an underdetermined system. In fact, this set up is in some sense easier to solve, because we don’t need to think about introducing a slack variable (although it might make a lot of sense from a modelling perspective to do so).
The way Laplace proposed resolving an overdetermined system, was to introduce slack variables, \(\epsilon_i\), which needed to be estimated for each point. The slack variable represented the difference between our actual prediction and the true observation. This is known as the residual. By introducing the slack variable, we now have an additional \(n\) variables to estimate, one for each data point, \(\{\epsilon_i\}\). This turns the overdetermined system into an underdetermined system. Introduction of \(n\) variables, plus the original \(m\) and \(c\) gives us \(n+2\) parameters to be estimated from \(n\) observations, which makes the system underdetermined. However, we then made a probabilistic assumption about the slack variables, we assumed that the slack variables were distributed according to a probability density. And for the moment we have been assuming that density was the Gaussian, \[\epsilon_i \sim \mathscr{N}\left(0,\sigma^2\right),\] with zero mean and variance \(\sigma^2\).
The follow up question is whether we can do the same thing with the parameters. If we have two parameters and only one unknown, can we place a probability distribution over the parameters as we did with the slack variables? The answer is yes.
Figure: An underdetermined system can be fit by considering uncertainty. Multiple solutions are consistent with one specified point.
Classically, there are two types of uncertainty that we consider. The first is known as aleatoric uncertainty. This is uncertainty we couldn’t resolve even if we wanted to. An example, would be the result of a football match before it’s played, or where a sheet of paper lands on the floor.
The second is known as epistemic uncertainty. This is uncertainty that we could, in principle, resolve. We just haven’t yet made the observation. For example, the result of a football match after it is played, or the color of socks that a lecturer is wearing.
Note, that there isn’t a clean difference between the two. It is arguable, that if we knew enough about a football match, or the physics of a falling sheet of paper then we might be able to resolve the uncertainty. The reason we can’t is because chaotic behaviour means that a very small change in any of the initial conditions we would need to resolve can have a large change in downstream effects. By this argument, the only truly aleatoric uncertainty might be quantum uncertainty. However, in practice the distinction is often applied.
In classical statistics, the frequentist approach only treats aleatoric uncertainty with probability. The key philosophical difference in the Bayesian approach is to treat any unknowns through probability. This approach was formally justified seperately by Cox (1946) and Finetti (1937).
The term Bayesian was a mocking term promoted by Fisher, it comes from the use, by Bayes, of a billiard table formulation to justify the Bernoulli distribution. Bayes considers a ball landing uniform at random between two sides of a billiard table. He then considers the outcome of the Bernoulli as being whether a second ball comes to rest to the right or left of the original. In this way, the parameter of his Bernoulli distribution is a stochastic variable (the uncertainty in the parameter is aleatoric). In contrast, when Bernoulli formulates the distribution he considers a bag of red and black balls. The parameter of his Bernoulli is the ratio of red balls to total balls, a deterministic variable.
Note how this relates to Laplace’s demon. Laplace describes the deterministic universe (“… for it nothing would be uncertain and the future, as the past, would be present in its eyes”), but acknowledges the impossibility of achieving this in practice, (" … the curve described by a simple molecule of air or vapor is regulated in a manner just as certain as the planetary orbits; the only difference between them is that which comes from our ignorance. Probability is relative in part to this ignorance, in part to our knowledge …)
The tradition in Bayesian inference is to place a probability density over the parameters of interest in your model. This choice is made regardless of whether you generally believe those parameters to be stochastic or deterministic in origin. In other words, to a Bayesian, the modelling treatment does not differentiate between epistemic and aleatoric uncertainty. For linear regression we could consider the following Gaussian prior on the intercept parameter, \[c \sim \mathscr{N}\left(0,\alpha_1\right)\] where \(\alpha_1\) is the variance of the prior distribution, its mean being zero.
The posterior distribution is found by Bayes’ rule. ## Posterior Distribution
\[ +\]
Since we are very familiar with the Gaussian density and its properties, it is not immediately apparent how unusual this is. Most random variables, when you add them together, change the family of density they are drawn from. For example, the Gaussian is exceptional in this regard. Indeed, other random variables, if they are independently drawn and summed together tend to a Gaussian density. That is the central limit theorem which is a major justification for the use of a Gaussian density.
Less unusual is the scaling property of a Gaussian density. If a variable, \(y\), is sampled from a Gaussian density,
\[y\sim \mathscr{N}\left(\mu,\sigma^2\right)\] and we choose to scale that variable by a deterministic value, \(w\), then the scaled variable is distributed as
\[wy\sim \mathscr{N}\left(w\mu,w^2 \sigma^2\right).\] Unlike the summing properties, where adding two or more random variables independently sampled from a family of densitites typically brings the summed variable outside that family, scaling many densities leaves the distribution of that variable in the same family of densities. Indeed, many densities include a scale parameter (e.g. the Gamma density) which is purely for this purpose. In the Gaussian the standard deviation, \(\sigma\), is the scale parameter. To see why this makes sense, let’s consider, \[z \sim \mathscr{N}\left(0,1\right),\] then if we scale by \(\sigma\) so we have, \(y=\sigma z\), we can write, \[y=\sigma z \sim \mathscr{N}\left(0,\sigma^2\right)\]
Regression involves predicting a real value, \(y_i\), given an input vector, \(\mathbf{ x}_i\). For example, the Tecator data involves predicting the quality of meat given spectral measurements. Or in radiocarbon dating, the C14 calibration curve maps from radiocarbon age to age measured through a back-trace of tree rings. Regression has also been used to predict the quality of board game moves given expert rated training data.
What about the situation where you have more parameters than data in your simultaneous equation? This is known as an underdetermined system. In fact, this set up is in some sense easier to solve, because we don’t need to think about introducing a slack variable (although it might make a lot of sense from a modelling perspective to do so).
The way Laplace proposed resolving an overdetermined system, was to introduce slack variables, \(\epsilon_i\), which needed to be estimated for each point. The slack variable represented the difference between our actual prediction and the true observation. This is known as the residual. By introducing the slack variable, we now have an additional \(n\) variables to estimate, one for each data point, \(\{\epsilon_i\}\). This turns the overdetermined system into an underdetermined system. Introduction of \(n\) variables, plus the original \(m\) and \(c\) gives us \(n+2\) parameters to be estimated from \(n\) observations, which makes the system underdetermined. However, we then made a probabilistic assumption about the slack variables, we assumed that the slack variables were distributed according to a probability density. And for the moment we have been assuming that density was the Gaussian, \[\epsilon_i \sim \mathscr{N}\left(0,\sigma^2\right),\] with zero mean and variance \(\sigma^2\).
The follow up question is whether we can do the same thing with the parameters. If we have two parameters and only one unknown, can we place a probability distribution over the parameters as we did with the slack variables? The answer is yes.
Figure: An underdetermined system can be fit by considering uncertainty. Multiple solutions are consistent with one specified point.
Classically, there are two types of uncertainty that we consider. The first is known as aleatoric uncertainty. This is uncertainty we couldn’t resolve even if we wanted to. An example, would be the result of a football match before it’s played, or where a sheet of paper lands on the floor.
The second is known as epistemic uncertainty. This is uncertainty that we could, in principle, resolve. We just haven’t yet made the observation. For example, the result of a football match after it is played, or the color of socks that a lecturer is wearing.
Note, that there isn’t a clean difference between the two. It is arguable, that if we knew enough about a football match, or the physics of a falling sheet of paper then we might be able to resolve the uncertainty. The reason we can’t is because chaotic behaviour means that a very small change in any of the initial conditions we would need to resolve can have a large change in downstream effects. By this argument, the only truly aleatoric uncertainty might be quantum uncertainty. However, in practice the distinction is often applied.
In classical statistics, the frequentist approach only treats aleatoric uncertainty with probability. The key philosophical difference in the Bayesian approach is to treat any unknowns through probability. This approach was formally justified seperately by Cox (1946) and Finetti (1937).
The term Bayesian was a mocking term promoted by Fisher, it comes from the use, by Bayes, of a billiard table formulation to justify the Bernoulli distribution. Bayes considers a ball landing uniform at random between two sides of a billiard table. He then considers the outcome of the Bernoulli as being whether a second ball comes to rest to the right or left of the original. In this way, the parameter of his Bernoulli distribution is a stochastic variable (the uncertainty in the parameter is aleatoric). In contrast, when Bernoulli formulates the distribution he considers a bag of red and black balls. The parameter of his Bernoulli is the ratio of red balls to total balls, a deterministic variable.
Note how this relates to Laplace’s demon. Laplace describes the deterministic universe (“… for it nothing would be uncertain and the future, as the past, would be present in its eyes”), but acknowledges the impossibility of achieving this in practice, (" … the curve described by a simple molecule of air or vapor is regulated in a manner just as certain as the planetary orbits; the only difference between them is that which comes from our ignorance. Probability is relative in part to this ignorance, in part to our knowledge …)
The tradition in Bayesian inference is to place a probability density over the parameters of interest in your model. This choice is made regardless of whether you generally believe those parameters to be stochastic or deterministic in origin. In other words, to a Bayesian, the modelling treatment does not differentiate between epistemic and aleatoric uncertainty. For linear regression we could consider the following Gaussian prior on the intercept parameter, \[c \sim \mathscr{N}\left(0,\alpha_1\right)\] where \(\alpha_1\) is the variance of the prior distribution, its mean being zero.
The posterior distribution is found by Bayes’ rule. ## Posterior Distribution
\[ p(c|y) = \frac{p(y|c)p(c)}{p(y)} \] \[ \text{posterior} = \frac{\text{likelihood}\times \text{prior}}{\text{marginal likelihood}} @@ -62,7 +61,7 @@ \]
where \(p(y)\) is the marginal probability of the data, obtained through integration over the joint density, \(p(y, c)=p(y|c)p(c)\). Overall the equation can be summarized as,
\[
\text{posterior} = \frac{\text{likelihood}\times \text{prior}}{\text{marginal likelihood}}.
- \]
Figure: Combining a Gaussian likelihood with a Gaussian prior to form a Gaussian posterior
Another way of seeing what’s going on is to note that the numerator of Bayes’ rule merely multiplies the likelihood by the prior. The denominator, is not a function of \(c\). So the functional form is entirely determined by the multiplication of prior and likelihood. This has the effect of ensuring that the posterior only has probability mass in regions where both the prior and the likelihood have probability mass.
The marginal likelihood, \(p(y)\), operates to ensure that the distribution is normalised.
For the Gaussian case, the normalisation of the posterior can be performed analytically. This is because both the prior and the likelihood have the form of an exponentiated quadratic, \[ + \]
Figure: Combining a Gaussian likelihood with a Gaussian prior to form a Gaussian posterior
Another way of seeing what’s going on is to note that the numerator of Bayes’ rule merely multiplies the likelihood by the prior. The denominator, is not a function of \(c\). So the functional form is entirely determined by the multiplication of prior and likelihood. This has the effect of ensuring that the posterior only has probability mass in regions where both the prior and the likelihood have probability mass.
The marginal likelihood, \(p(y)\), operates to ensure that the distribution is normalised.
For the Gaussian case, the normalisation of the posterior can be performed analytically. This is because both the prior and the likelihood have the form of an exponentiated quadratic, \[ \exp(a^2)\exp(b^2) = \exp(a^2 + b^2), \] and the properties of the exponential mean that the product of two exponentiated quadratics is also an exponentiated quadratic. That implies that the posterior is also Gaussian, because a normalized exponentiated quadratic is a Gaussian distribution.1
For general Bayesian inference, over more than one parameter, we need multivariate priors. For example, consider the multivariate linear regression where an observation, \(y_i\) is related to a vector of features, \(\mathbf{ x}_{i, :}\), through a vector of parameters, \(\mathbf{ w}\), \[y_i = \sum_j w_j x_{i, j} + \epsilon_i,\] or in vector notation, \[y_i = \mathbf{ w}^\top \mathbf{ x}_{i, :} + \epsilon_i.\] Here we’ve dropped the intercpet for convenience, it can be reintroduced by augmenting the feature vector, \(\mathbf{ x}_{i, :}\), with a constant valued feature.
This motivates the need for a multivariate Gaussian density.
For more information on these subjects and more you might want to check the following resources.
Note not all exponentiated quadratics can be normalized, to do so, the coefficient associated with the variable squared, \(y^2\), must be strictly positive.↩︎
We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling.
-import importlib.utilcmd = install_command('pods')%system {cmd}cmd = install_command('notutils')%system {cmd}cmd = install_command('mlai')%system {cmd}We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling.
import importlib.utilcmd = install_command('pods')%system {cmd}cmd = install_command('notutils')%system {cmd}cmd = install_command('mlai')%system {cmd}cmd = install_command('GPy')%system {cmd}Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics.
-
-Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy
-GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries.
-The software itself is available on GitHub and the team welcomes contributions.
-The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets.
-The documentation for GPy can be found here.
-Consider the distribution of height (in meters) of an adult male human population. We will approximate the marginal density of heights as a Gaussian density with mean given by \(1.7\text{m}\) and a standard deviation of \(0.15\text{m}\), implying a variance of \(\sigma^2=0.0225\), \[
+sns.set_palette('colorblind')}--> Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. Consider the distribution of height (in meters) of an adult male human population. We will approximate the marginal density of heights as a Gaussian density with mean given by \(1.7\text{m}\) and a standard deviation of \(0.15\text{m}\), implying a variance of \(\sigma^2=0.0225\), \[
p(h) \sim \mathscr{N}\left(1.7,0.0225\right).
\] Similarly, we assume that weights of the population are distributed a Gaussian density with a mean of \(75 \text{kg}\) and a standard deviation of \(6 kg\) (implying a variance of 36), \[
p(w) \sim \mathscr{N}\left(75,36\right).
- \] Figure: Gaussian distributions for height and weight. First of all, we make an independence assumption, we assume that height and weight are independent. The definition of probabilistic independence is that the joint density, \(p(w, h)\), factorizes into its marginal densities, \[
+ \] Figure: Gaussian distributions for height and weight. First of all, we make an independence assumption, we assume that height and weight are independent. The definition of probabilistic independence is that the joint density, \(p(w, h)\), factorizes into its marginal densities, \[
p(w, h) = p(w)p(h).
- \] Given this assumption we can sample from the joint distribution by independently sampling weights and heights. Figure: Samples from independent Gaussian variables that might represent heights and weights. In reality height and weight are not independent. Taller people tend on average to be heavier, and heavier people are likely to be taller. This is reflected by the body mass index. A ratio suggested by one of the fathers of statistics, Adolphe Quetelet. Quetelet was interested in the notion of the average man and collected various statistics about people. He defined the BMI to be, \[
+ \] Given this assumption we can sample from the joint distribution by independently sampling weights and heights. Figure: Samples from independent Gaussian variables that might represent heights and weights. In reality height and weight are not independent. Taller people tend on average to be heavier, and heavier people are likely to be taller. This is reflected by the body mass index. A ratio suggested by one of the fathers of statistics, Adolphe Quetelet. Quetelet was interested in the notion of the average man and collected various statistics about people. He defined the BMI to be, \[
\text{BMI} = \frac{w}{h^2}
-\]To deal with this dependence we now introduce the notion of correlation to the multivariate Gaussian density. \[
+\]To deal with this dependence we now introduce the notion of correlation to the multivariate Gaussian density. \[
p(w, h) = p(w)p(h)
-\] \[
+\] \[
p(w, h) = \frac{1}{\sqrt{2\pi \sigma_1^2}\sqrt{2\pi\sigma_2^2}} \exp\left(-\frac{1}{2}\left(\frac{(w-\mu_1)^2}{\sigma_1^2} + \frac{(h-\mu_2)^2}{\sigma_2^2}\right)\right)
-\] \[
+\] \[
p(w, h) = \frac{1}{\sqrt{2\pi\sigma_1^22\pi\sigma_2^2}} \exp\left(-\frac{1}{2}\left(\begin{bmatrix}w \\ h\end{bmatrix} - \begin{bmatrix}\mu_1 \\ \mu_2\end{bmatrix}\right)^\top\begin{bmatrix}\sigma_1^2& 0\\0&\sigma_2^2\end{bmatrix}^{-1}\left(\begin{bmatrix}w \\ h\end{bmatrix} - \begin{bmatrix}\mu_1 \\ \mu_2\end{bmatrix}\right)\right)
-\] \[
+\] \[
p(\mathbf{ y}) = \frac{1}{\det{2\pi \mathbf{D}}^{\frac{1}{2}}} \exp\left(-\frac{1}{2}(\mathbf{ y}- \boldsymbol{ \mu})^\top\mathbf{D}^{-1}(\mathbf{ y}- \boldsymbol{ \mu})\right)
-\] Form correlated from original by rotating the data space using matrix \(\mathbf{R}\). \[
+\] Form correlated from original by rotating the data space using matrix \(\mathbf{R}\). \[
p(\mathbf{ y}) = \frac{1}{\det{2\pi\mathbf{D}}^{\frac{1}{2}}} \exp\left(-\frac{1}{2}(\mathbf{ y}- \boldsymbol{ \mu})^\top\mathbf{D}^{-1}(\mathbf{ y}- \boldsymbol{ \mu})\right)
-\] \[
+\] \[
p(\mathbf{ y}) = \frac{1}{\det{2\pi\mathbf{D}}^{\frac{1}{2}}} \exp\left(-\frac{1}{2}(\mathbf{R}^\top\mathbf{ y}- \mathbf{R}^\top\boldsymbol{ \mu})^\top\mathbf{D}^{-1}(\mathbf{R}^\top\mathbf{ y}- \mathbf{R}^\top\boldsymbol{ \mu})\right)
-\] \[
+\] \[
p(\mathbf{ y}) = \frac{1}{\det{2\pi\mathbf{D}}^{\frac{1}{2}}} \exp\left(-\frac{1}{2}(\mathbf{ y}- \boldsymbol{ \mu})^\top\mathbf{R}\mathbf{D}^{-1}\mathbf{R}^\top(\mathbf{ y}- \boldsymbol{ \mu})\right)
\] this gives an inverse covariance matrix: \[
\mathbf{C}^{-1} = \mathbf{R}\mathbf{D}^{-1} \mathbf{R}^\top
-\] \[
+\] \[
p(\mathbf{ y}) = \frac{1}{\det{2\pi\mathbf{C}}^{\frac{1}{2}}} \exp\left(-\frac{1}{2}(\mathbf{ y}- \boldsymbol{ \mu})^\top\mathbf{C}^{-1} (\mathbf{ y}- \boldsymbol{ \mu})\right)
\] \[
\mathbf{C}= \mathbf{R}\mathbf{D} \mathbf{R}^\top
-\] Let’s first of all review the properties of the multivariate Gaussian distribution that make linear Gaussian models easier to deal with. We’ll return to the, perhaps surprising, result on the parameters within the nonlinearity, \(\boldsymbol{ \theta}\), shortly. To work with linear Gaussian models, to find the marginal likelihood all you need to know is the following rules. If \[
+\] Let’s first of all review the properties of the multivariate Gaussian distribution that make linear Gaussian models easier to deal with. We’ll return to the, perhaps surprising, result on the parameters within the nonlinearity, \(\boldsymbol{ \theta}\), shortly. To work with linear Gaussian models, to find the marginal likelihood all you need to know is the following rules. If \[
\mathbf{ y}= \mathbf{W}\mathbf{ x}+ \boldsymbol{ \epsilon},
\] where \(\mathbf{ y}\), \(\mathbf{ x}\) and \(\boldsymbol{ \epsilon}\) are vectors and we assume that \(\mathbf{ x}\) and \(\boldsymbol{ \epsilon}\) are drawn from multivariate Gaussians, \[
\begin{align}
@@ -175,367 +58,72 @@ With appropriately defined covariance, \(\boldsymbol{ \Sigma}\), this is actually the marginal likelihood for Factor Analysis, or Probabilistic Principal Component Analysis (Tipping and Bishop, 1999), because we integrated out the inputs (or latent variables they would be called in that case). However, we are focussing on what happens in models which are non-linear in the inputs, whereas the above would be linear in the inputs. To consider these, we introduce a matrix, called the design matrix. We set each activation function computed at each data point to be \[
+\] With appropriately defined covariance, \(\boldsymbol{ \Sigma}\), this is actually the marginal likelihood for Factor Analysis, or Probabilistic Principal Component Analysis (Tipping and Bishop, 1999), because we integrated out the inputs (or latent variables they would be called in that case). However, we are focussing on what happens in models which are non-linear in the inputs, whereas the above would be linear in the inputs. To consider these, we introduce a matrix, called the design matrix. We set each activation function computed at each data point to be \[
\phi_{i,j} = \phi(\mathbf{ w}^{(1)}_{j}, \mathbf{ x}_{i})
\] and define the matrix of activations (known as the design matrix in statistics) to be, \[
-\boldsymbol{ \Phi}=
+\boldsymbol{ \Phi}=
\begin{bmatrix}
\phi_{1, 1} & \phi_{1, 2} & \dots & \phi_{1, h} \\
\phi_{1, 2} & \phi_{1, 2} & \dots & \phi_{1, n} \\
\vdots & \vdots & \ddots & \vdots \\
\phi_{n, 1} & \phi_{n, 2} & \dots & \phi_{n, h}
\end{bmatrix}.
-\] By convention this matrix always has \(n\) rows and \(h\) columns, now if we define the vector of all noise corruptions, \(\boldsymbol{ \epsilon}= \left[\epsilon_1, \dots \epsilon_n\right]^\top\). If we define the prior distribution over the vector \(\mathbf{ w}\) to be Gaussian, \[
+\] By convention this matrix always has \(n\) rows and \(h\) columns, now if we define the vector of all noise corruptions, \(\boldsymbol{ \epsilon}= \left[\epsilon_1, \dots \epsilon_n\right]^\top\). If we define the prior distribution over the vector \(\mathbf{ w}\) to be Gaussian, \[
\mathbf{ w}\sim \mathscr{N}\left(\mathbf{0},\alpha\mathbf{I}\right),
\] then we can use rules of multivariate Gaussians to see that, \[
\mathbf{ y}\sim \mathscr{N}\left(\mathbf{0},\alpha \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top + \sigma^2 \mathbf{I}\right).
-\] In other words, our training data is distributed as a multivariate Gaussian, with zero mean and a covariance given by \[
+\] In other words, our training data is distributed as a multivariate Gaussian, with zero mean and a covariance given by \[
\mathbf{K}= \alpha \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top + \sigma^2 \mathbf{I}.
-\] This is an \(n\times n\) size matrix. Its elements are in the form of a function. The maths shows that any element, index by \(i\) and \(j\), is a function only of inputs associated with data points \(i\) and \(j\), \(\mathbf{ y}_i\), \(\mathbf{ y}_j\). \(k_{i,j} = k\left(\mathbf{ x}_i, \mathbf{ x}_j\right)\) If we look at the portion of this function associated only with \(f(\cdot)\), i.e. we remove the noise, then we can write down the covariance associated with our neural network, \[
+\] This is an \(n\times n\) size matrix. Its elements are in the form of a function. The maths shows that any element, index by \(i\) and \(j\), is a function only of inputs associated with data points \(i\) and \(j\), \(\mathbf{ y}_i\), \(\mathbf{ y}_j\). \(k_{i,j} = k\left(\mathbf{ x}_i, \mathbf{ x}_j\right)\) If we look at the portion of this function associated only with \(f(\cdot)\), i.e. we remove the noise, then we can write down the covariance associated with our neural network, \[
k_f\left(\mathbf{ x}_i, \mathbf{ x}_j\right) = \alpha \boldsymbol{ \phi}\left(\mathbf{W}_1, \mathbf{ x}_i\right)^\top \boldsymbol{ \phi}\left(\mathbf{W}_1, \mathbf{ x}_j\right)
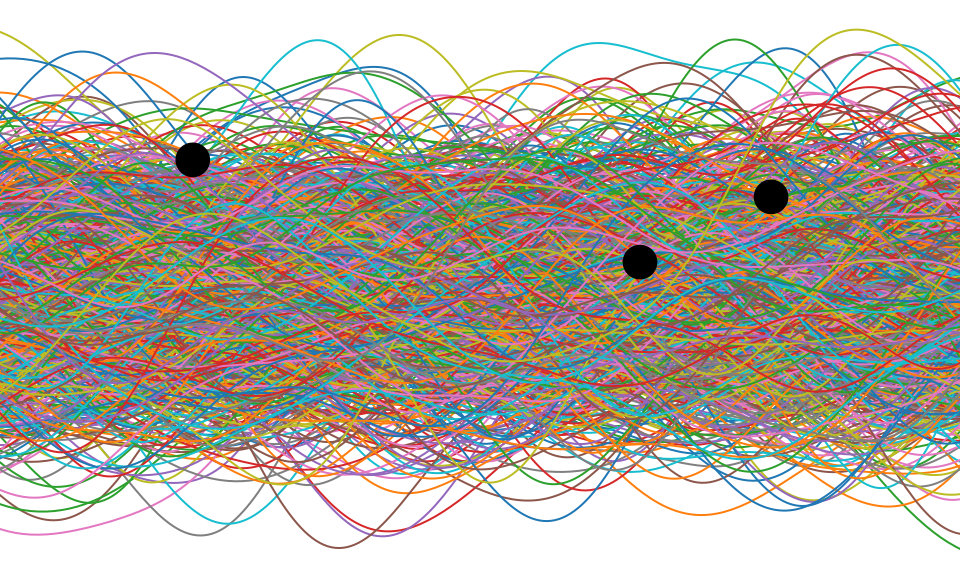
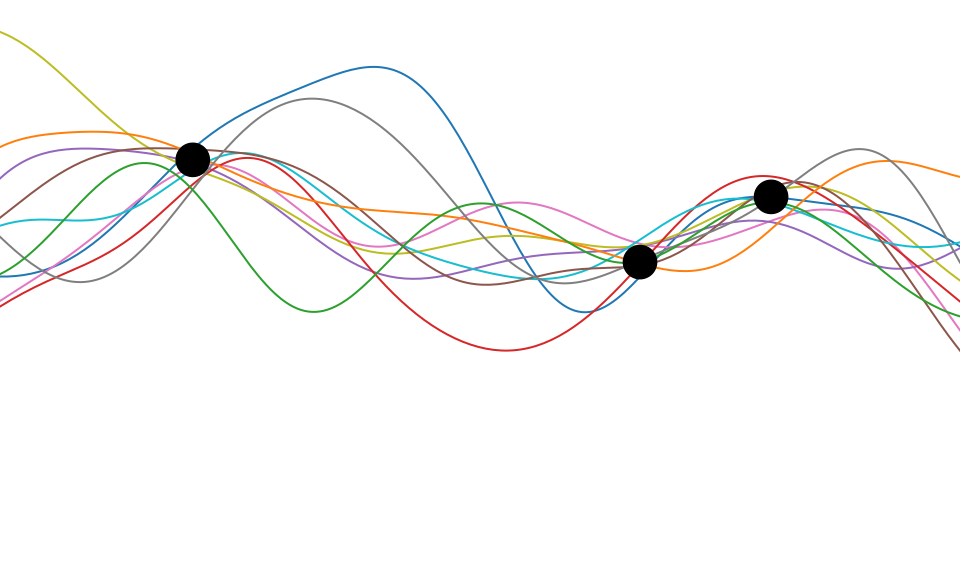
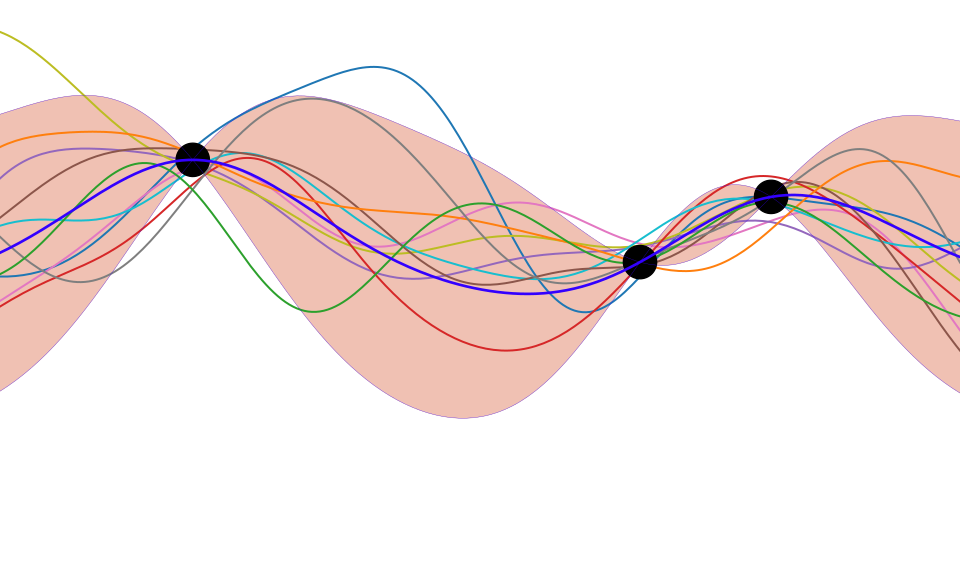
-\] so the elements of the covariance or kernel matrix are formed by inner products of the rows of the design matrix. This is the essence of a Gaussian process. Instead of making assumptions about our density over each data point, \(y_i\) as i.i.d. we make a joint Gaussian assumption over our data. The covariance matrix is now a function of both the parameters of the activation function, \(\mathbf{V}\), and the input variables, \(\mathbf{X}\). This comes about through integrating out the parameters of the model, \(\mathbf{ w}\). We can basically put anything inside the basis functions, and many people do. These can be deep kernels (Cho and Saul, 2009) or we can learn the parameters of a convolutional neural network inside there. Viewing a neural network in this way is also what allows us to beform sensible batch normalizations (Ioffe and Szegedy, 2015). One view of Bayesian inference is to assume we are given a mechanism for generating samples, where we assume that mechanism is representing an accurate view on the way we believe the world works. This mechanism is known as our prior belief. We combine our prior belief with our observations of the real world by discarding all those prior samples that are inconsistent with our observations. The likelihood defines mathematically what we mean by inconsistent with the observations. The higher the noise level in the likelihood, the looser the notion of consistent. The samples that remain are samples from the posterior. This approach to Bayesian inference is closely related to two sampling techniques known as rejection sampling and importance sampling. It is realized in practice in an approach known as approximate Bayesian computation (ABC) or likelihood-free inference. In practice, the algorithm is often too slow to be practical, because most samples will be inconsistent with the observations and as a result the mechanism must be operated many times to obtain a few posterior samples. However, in the Gaussian process case, when the likelihood also assumes Gaussian noise, we can operate this mechanism mathematically, and obtain the posterior density analytically. This is the benefit of Gaussian processes. First, we will load in two python functions for computing the covariance function. Next, we sample from a multivariate normal density (a multivariate Gaussian), using the covariance function as the covariance matrix. Figure: One view of Bayesian inference is we have a machine for generating samples (the prior), and we discard all samples inconsistent with our data, leaving the samples of interest (the posterior). This is a rejection sampling view of Bayesian inference. The Gaussian process allows us to do this analytically by multiplying the prior by the likelihood. We will consider a multivariate Gaussian with a particular structure of covariance matrix. We will generate a single sample from this 25 dimensional Gaussian density. \[
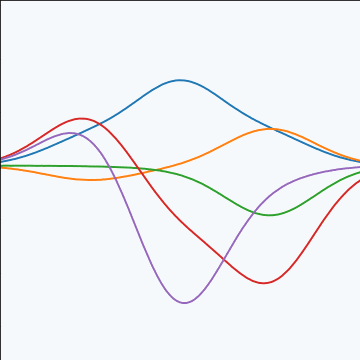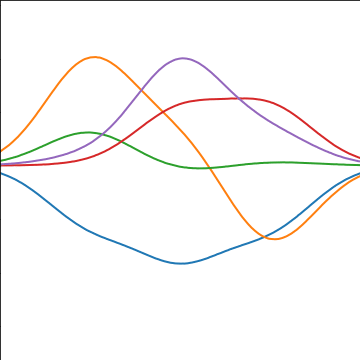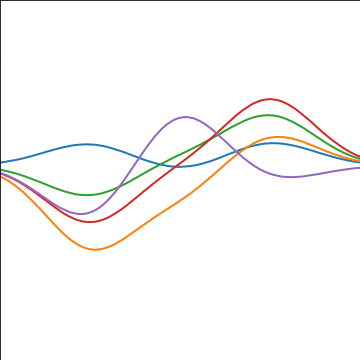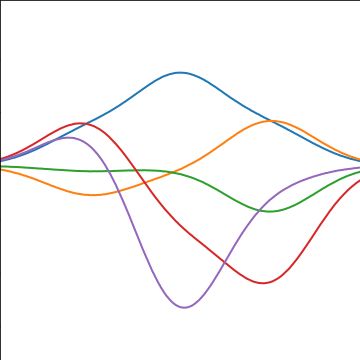
+\] so the elements of the covariance or kernel matrix are formed by inner products of the rows of the design matrix. This is the essence of a Gaussian process. Instead of making assumptions about our density over each data point, \(y_i\) as i.i.d. we make a joint Gaussian assumption over our data. The covariance matrix is now a function of both the parameters of the activation function, \(\mathbf{V}\), and the input variables, \(\mathbf{X}\). This comes about through integrating out the parameters of the model, \(\mathbf{ w}\). We can basically put anything inside the basis functions, and many people do. These can be deep kernels (Cho and Saul, 2009) or we can learn the parameters of a convolutional neural network inside there. Viewing a neural network in this way is also what allows us to beform sensible batch normalizations (Ioffe and Szegedy, 2015). One view of Bayesian inference is to assume we are given a mechanism for generating samples, where we assume that mechanism is representing an accurate view on the way we believe the world works. This mechanism is known as our prior belief. We combine our prior belief with our observations of the real world by discarding all those prior samples that are inconsistent with our observations. The likelihood defines mathematically what we mean by inconsistent with the observations. The higher the noise level in the likelihood, the looser the notion of consistent. The samples that remain are samples from the posterior. This approach to Bayesian inference is closely related to two sampling techniques known as rejection sampling and importance sampling. It is realized in practice in an approach known as approximate Bayesian computation (ABC) or likelihood-free inference. In practice, the algorithm is often too slow to be practical, because most samples will be inconsistent with the observations and as a result the mechanism must be operated many times to obtain a few posterior samples. However, in the Gaussian process case, when the likelihood also assumes Gaussian noise, we can operate this mechanism mathematically, and obtain the posterior density analytically. This is the benefit of Gaussian processes. First, we will load in two python functions for computing the covariance function. Next, we sample from a multivariate normal density (a multivariate Gaussian), using the covariance function as the covariance matrix. Figure: One view of Bayesian inference is we have a machine for generating samples (the prior), and we discard all samples inconsistent with our data, leaving the samples of interest (the posterior). This is a rejection sampling view of Bayesian inference. The Gaussian process allows us to do this analytically by multiplying the prior by the likelihood. We will consider a multivariate Gaussian with a particular structure of covariance matrix. We will generate a single sample from this 25 dimensional Gaussian density. \[
\mathbf{ f}=\left[f_{1},f_{2}\dots f_{25}\right].
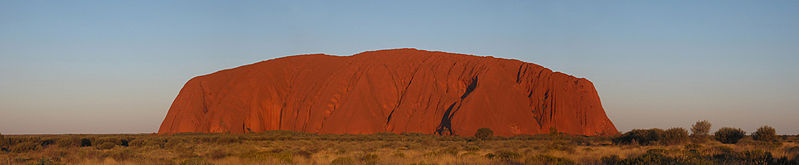
-\] in the figure below we plot these data on the \(y\)-axis against their indices on the \(x\)-axis. Figure: The joint Gaussian over \(f_1\) and \(f_2\) along with the conditional distribution of \(f_2\) given \(f_1\) Figure: The joint Gaussian over \(f_1\) and \(f_2\) along with the conditional distribution of \(f_2\) given \(f_1\) Figure: Uluru, the sacred rock in Australia. If we think of it as a probability density, viewing it from this side gives us one marginal from the density. Figuratively speaking, slicing through the rock would give a conditional density. When viewing these contour plots, I sometimes find it helpful to think of Uluru, the prominent rock formation in Australia. The rock rises above the surface of the plane, just like a probability density rising above the zero line. The rock is three dimensional, but when we view Uluru from the classical position, we are looking at one side of it. This is equivalent to viewing the marginal density. The joint density can be viewed from above, using contours. The conditional density is equivalent to slicing the rock. Uluru is a holy rock, so this has to be an imaginary slice. Imagine we cut down a vertical plane orthogonal to our view point (e.g. coming across our view point). This would give a profile of the rock, which when renormalized, would give us the conditional distribution, the value of conditioning would be the location of the slice in the direction we are facing. Of course in practice, rather than manipulating mountains physically, the advantage of the Gaussian density is that we can perform these manipulations mathematically. Prediction of \(f_2\) given \(f_1\) requires the conditional density, \(p(f_2|f_1)\).Another remarkable property of the Gaussian density is that this conditional distribution is also guaranteed to be a Gaussian density. It has the form, \[
+\] in the figure below we plot these data on the \(y\)-axis against their indices on the \(x\)-axis. Figure: The joint Gaussian over \(f_1\) and \(f_2\) along with the conditional distribution of \(f_2\) given \(f_1\) Figure: The joint Gaussian over \(f_1\) and \(f_2\) along with the conditional distribution of \(f_2\) given \(f_1\) Figure: Uluru, the sacred rock in Australia. If we think of it as a probability density, viewing it from this side gives us one marginal from the density. Figuratively speaking, slicing through the rock would give a conditional density. When viewing these contour plots, I sometimes find it helpful to think of Uluru, the prominent rock formation in Australia. The rock rises above the surface of the plane, just like a probability density rising above the zero line. The rock is three dimensional, but when we view Uluru from the classical position, we are looking at one side of it. This is equivalent to viewing the marginal density. The joint density can be viewed from above, using contours. The conditional density is equivalent to slicing the rock. Uluru is a holy rock, so this has to be an imaginary slice. Imagine we cut down a vertical plane orthogonal to our view point (e.g. coming across our view point). This would give a profile of the rock, which when renormalized, would give us the conditional distribution, the value of conditioning would be the location of the slice in the direction we are facing. Of course in practice, rather than manipulating mountains physically, the advantage of the Gaussian density is that we can perform these manipulations mathematically. Prediction of \(f_2\) given \(f_1\) requires the conditional density, \(p(f_2|f_1)\).Another remarkable property of the Gaussian density is that this conditional distribution is also guaranteed to be a Gaussian density. It has the form, \[
p(f_2|f_1) = \mathscr{N}\left(f_2|\frac{k_{1, 2}}{k_{1, 1}}f_1, k_{2, 2} - \frac{k_{1,2}^2}{k_{1,1}}\right)
\]where we have assumed that the covariance of the original joint density was given by \[
\mathbf{K}= \begin{bmatrix} k_{1, 1} & k_{1, 2}\\ k_{2, 1} & k_{2, 2}.\end{bmatrix}
-\] Using these formulae we can determine the conditional density for any of the elements of our vector \(\mathbf{ f}\). For example, the variable \(f_8\) is less correlated with \(f_1\) than \(f_2\). If we consider this variable we see the conditional density is more diffuse. Figure: Sample from the joint Gaussian model, points indexed by 1 and 8 highlighted. Figure: The joint Gaussian over \(f_1\) and \(f_8\) along with the conditional distribution of \(f_8\) given \(f_1\) . . . . . . Conditional density: \(p(f_8|f_1=?)\). Prediction of \(\mathbf{ f}_*\) from \(\mathbf{ f}\). Multivariate conditional density is also Gaussian. \[
+\] Using these formulae we can determine the conditional density for any of the elements of our vector \(\mathbf{ f}\). For example, the variable \(f_8\) is less correlated with \(f_1\) than \(f_2\). If we consider this variable we see the conditional density is more diffuse. Figure: Sample from the joint Gaussian model, points indexed by 1 and 8 highlighted. Figure: The joint Gaussian over \(f_1\) and \(f_8\) along with the conditional distribution of \(f_8\) given \(f_1\) Conditional density: \(p(f_8|f_1=?)\). Prediction of \(\mathbf{ f}_*\) from \(\mathbf{ f}\). Multivariate conditional density is also Gaussian. \[
p(\mathbf{ f}_*|\mathbf{ f}) = {\mathcal{N}\left(\mathbf{ f}_*|\mathbf{K}_{*,\mathbf{ f}}\mathbf{K}_{\mathbf{ f},\mathbf{ f}}^{-1}\mathbf{ f},\mathbf{K}_{*,*}-\mathbf{K}_{*,\mathbf{ f}} \mathbf{K}_{\mathbf{ f},\mathbf{ f}}^{-1}\mathbf{K}_{\mathbf{ f},*}\right)}
-\] Here covariance of joint density is given by \[
+\] Here covariance of joint density is given by \[
\mathbf{K}= \begin{bmatrix} \mathbf{K}_{\mathbf{ f}, \mathbf{ f}} & \mathbf{K}_{*, \mathbf{ f}}\\ \mathbf{K}_{\mathbf{ f}, *} & \mathbf{K}_{*, *}\end{bmatrix}
-\] Prediction of \(\mathbf{ f}_*\) from \(\mathbf{ f}\). Multivariate conditional density is also Gaussian. \[
+\] Prediction of \(\mathbf{ f}_*\) from \(\mathbf{ f}\). Multivariate conditional density is also Gaussian. \[
p(\mathbf{ f}_*|\mathbf{ f}) = {\mathcal{N}\left(\mathbf{ f}_*|\boldsymbol{ \mu},\boldsymbol{ \Sigma}\right)}
\] \[
\boldsymbol{ \mu}= \mathbf{K}_{*,\mathbf{ f}}\mathbf{K}_{\mathbf{ f},\mathbf{ f}}^{-1}\mathbf{ f}
\] \[
\boldsymbol{ \Sigma}= \mathbf{K}_{*,*}-\mathbf{K}_{*,\mathbf{ f}} \mathbf{K}_{\mathbf{ f},\mathbf{ f}}^{-1}\mathbf{K}_{\mathbf{ f},*}
-\] Here covariance of joint density is given by \[
+\] Here covariance of joint density is given by \[
\mathbf{K}= \begin{bmatrix} \mathbf{K}_{\mathbf{ f}, \mathbf{ f}} & \mathbf{K}_{*, \mathbf{ f}}\\ \mathbf{K}_{\mathbf{ f}, *} & \mathbf{K}_{*, *}\end{bmatrix}
-\] \[
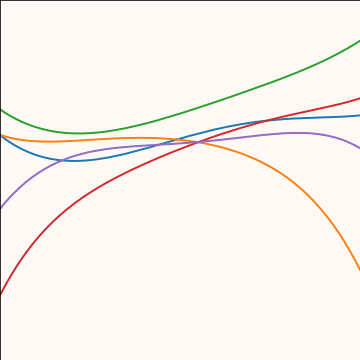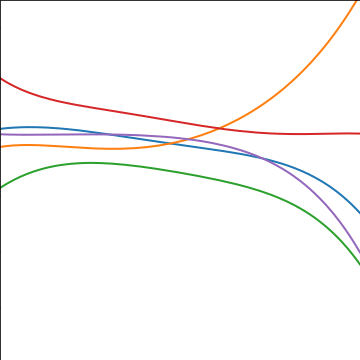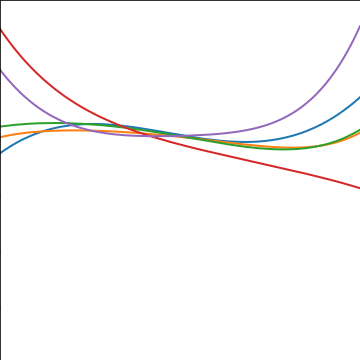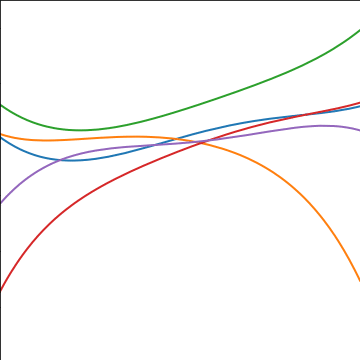
-k(\mathbf{ x}, \mathbf{ x}^\prime) = \alpha \exp\left(-\frac{\left\Vert \mathbf{ x}- \mathbf{ x}^\prime\right\Vert^2_2}{2\ell^2}\right)\] Figure: Entrywise fill in of the covariance matrix from the covariance function. Figure: Entrywise fill in of the covariance matrix from the covariance function. Figure: Entrywise fill in of the covariance matrix from the covariance function. Figure: Polynomial covariance function. Any linear basis function can also be incorporated into a covariance function. For example, an RBF network is a type of neural network with a set of radial basis functions. Meaning, the basis funciton is radially symmetric. These basis functions take the form, \[
+\] \[
+k(\mathbf{ x}, \mathbf{ x}^\prime) = \alpha \exp\left(-\frac{\left\Vert \mathbf{ x}- \mathbf{ x}^\prime\right\Vert^2_2}{2\ell^2}\right)\] Figure: Entrywise fill in of the covariance matrix from the covariance function. Figure: Entrywise fill in of the covariance matrix from the covariance function. Figure: Entrywise fill in of the covariance matrix from the covariance function. Figure: Polynomial covariance function. Any linear basis function can also be incorporated into a covariance function. For example, an RBF network is a type of neural network with a set of radial basis functions. Meaning, the basis funciton is radially symmetric. These basis functions take the form, \[
\phi_k(x) = \exp\left(-\frac{\left\Vert x-\mu_k \right\Vert_2^{2}}{\ell^{2}}\right).
\] Given a set of parameters, \[
\boldsymbol{ \mu}= \begin{bmatrix} -1 \\ 0 \\ 1\end{bmatrix},
\] we can construct the corresponding covariance function, which has the form, \[
k\left(\mathbf{ x},\mathbf{ x}^{\prime}\right)=\alpha\boldsymbol{ \phi}(\mathbf{ x})^\top \boldsymbol{ \phi}(\mathbf{ x}^\prime).
-\] The fixed basis function covariance just comes from the properties of a multivariate Gaussian, if we decide \[
+\] The fixed basis function covariance just comes from the properties of a multivariate Gaussian, if we decide \[
\mathbf{ f}=\boldsymbol{ \Phi}\mathbf{ w}
\] and then we assume \[
\mathbf{ w}\sim \mathscr{N}\left(\mathbf{0},\alpha\mathbf{I}\right)
\] then it follows from the properties of a multivariate Gaussian that \[
\mathbf{ f}\sim \mathscr{N}\left(\mathbf{0},\alpha\boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top\right)
-\] meaning that the vector of observations from the function is jointly distributed as a Gaussian process and the covariance matrix is \(\mathbf{K}= \alpha\boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top\), each element of the covariance matrix can then be found as the inner product between two rows of the basis funciton matrix. Figure: A covariance function based on a non-linear basis given by \(\boldsymbol{ \phi}(\mathbf{ x})\). One very clever of finessing this problem is to choose to have infinite basis functions and place them everywhere. To show how this is possible, we will consider a one dimensional system, \(x\), which should give the intuition of how to do this. However, these ideas also extend to multidimensional systems as shown in, for example, Williams (n.d.) and Neal (1994). We consider a one dimensional set up with exponentiated quadratic basis functions, \[
+\] meaning that the vector of observations from the function is jointly distributed as a Gaussian process and the covariance matrix is \(\mathbf{K}= \alpha\boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top\), each element of the covariance matrix can then be found as the inner product between two rows of the basis funciton matrix. Figure: A covariance function based on a non-linear basis given by \(\boldsymbol{ \phi}(\mathbf{ x})\). One very clever of finessing this problem is to choose to have infinite basis functions and place them everywhere. To show how this is possible, we will consider a one dimensional system, \(x\), which should give the intuition of how to do this. However, these ideas also extend to multidimensional systems as shown in, for example, Williams (n.d.) and Neal (1994). We consider a one dimensional set up with exponentiated quadratic basis functions, \[
\phi_k(x_i) = \exp\left(\frac{\left\Vert x_i - \mu_k \right\Vert_2^2}{2\ell^2}\right)
-\] To place these basis functions, we first define the basis function centers in terms of a starting point on the left of our input, \(a\), and a finishing point, \(b\). The gap between basis is given by \(\Delta\mu\). The location of each basis is then given by \[\mu_k = a+\Delta\mu\cdot (k-1).\] The covariance function can then be given as \[
+\] To place these basis functions, we first define the basis function centers in terms of a starting point on the left of our input, \(a\), and a finishing point, \(b\). The gap between basis is given by \(\Delta\mu\). The location of each basis is then given by \[\mu_k = a+\Delta\mu\cdot (k-1).\] The covariance function can then be given as \[
k\left(x_i,x_j\right) = \sum_{k=1}^m\phi_k(x_i)\phi_k(x_j)
\] \[\begin{aligned}
k\left(x_i,x_j\right) = &\alpha^\prime\Delta\mu\sum_{k=1}^{m} \exp\Bigg(
- -\frac{x_i^2 + x_j^2}{2\ell^2}\\
+ -\frac{x_i^2 + x_j^2}{2\ell^2}\\
& - \frac{2\left(a+\Delta\mu\cdot (k-1)\right)
\left(x_i+x_j\right) + 2\left(a+\Delta\mu\cdot (k-1)\right)^2}{2\ell^2} \Bigg)
- \end{aligned}\] where we’ve also scaled the variance of the process by \(\Delta\mu\). A consequence of our definition is that the first and last basis function locations are given by \[
+ \end{aligned}\] where we’ve also scaled the variance of the process by \(\Delta\mu\). A consequence of our definition is that the first and last basis function locations are given by \[
\mu_1=a \ \text{and}\ \mu_m=b \ \text{so}\ b= a+ \Delta\mu\cdot(m-1)
\] This implies that the distance between \(b\) and \(a\) is given by \[
b-a = \Delta\mu(m-1)
\] and since the basis functions are separated by \(\Delta\mu\) the number of basis functions is given by \[
m= \frac{b-a}{\Delta \mu} + 1
- \] The next step is to take the limit as \(\Delta\mu\rightarrow 0\) so \(m\rightarrow \infty\) where we have used \(a + k\cdot\Delta\mu\rightarrow \mu\). Performing the integration gives \[\begin{aligned}
+ \] The next step is to take the limit as \(\Delta\mu\rightarrow 0\) so \(m\rightarrow \infty\) where we have used \(a + k\cdot\Delta\mu\rightarrow \mu\). Performing the integration gives \[\begin{aligned}
k(x_i,&x_j) = \alpha^\prime \sqrt{\pi\ell^2}
\exp\left( -\frac{\left(x_i-x_j\right)^2}{4\ell^2}\right)\\ &\times
\frac{1}{2}\left[\text{erf}\left(\frac{\left(b - \frac{1}{2}\left(x_i +
@@ -543,35 +131,6 @@ In conclusion, an RBF model with infinite basis functions is a Gaussian process with the exponentiated quadratic covariance function \[k\left(x_i,x_j\right) = \alpha \exp\left(
- -\frac{\left(x_i-x_j\right)^2}{4\ell^2}\right).\] For more information on these subjects and more you might want to check the following resources.cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python
Two Dimensional Gaussian
-
-
-
-
-
-
-
-
-
-Independence Assumption
-Independence Assumption
-displaycode{nu.display_plots(‘independent_height_weight{fig:0>3}.svg’, directory=‘./ml’, fig=IntSlider(0, 0, 7, 1))}
-
-
-
-
-
-
-
-
-
-
+displaycode{nu.display_plots(‘independent_height_weight{fig:0>3}.svg,’ directory=‘./ml,’ fig=IntSlider(0, 0, 7, 1))}Sampling Two Dimensional Variables
-
-
-
-
-
-
-Independent Gaussians
-
-Sampling Two Dimensional Variables
Independent Gaussians
Correlated Gaussian
-Correlated Gaussian
Correlated Gaussian
\end{align}
\] then we know that \(\mathbf{ y}\) is also drawn from a multivariate Gaussian with, \[
\mathbf{ y}\sim \mathscr{N}\left(\mathbf{W}\boldsymbol{ \mu},\mathbf{W}\mathbf{C}\mathbf{W}^\top + \boldsymbol{ \Sigma}\right).
-\]Linear Model Overview
-
-Linear Model Overview
Gaussian Process
-Basis Functions
-Bayesian Inference by Rejection Sampling
-
-
-
-
-
-
-
- -
-
-
 -
-
-
 -
-
-
-
-
-
Sampling a Function
-
-Gaussian Process
Basis Functions
Bayesian Inference by Rejection Sampling


Sampling a Function
-import numpy as np
-np.random.seed(4949)
-from mlai import Kernel
-from mlai import polynomial_cov
-from mlai import eq_covSampling a Function from a Gaussian
-
-
-
-
-
-
-
-
-
-
-Joint Density of \(f_1\) and \(f_2\)
-
-
-
-
-
-
-
-
-
-
-Uluru
-
-
-
-
-
-
- -
-
-
-
-
-
Prediction of \(f_2\) from \(f_1\)
-import numpy as np
+np.random.seed(4949)from mlai import Kernelfrom mlai import polynomial_covfrom mlai import eq_covSampling a Function from a Gaussian
Joint Density of \(f_1\) and \(f_2\)
Uluru

Prediction of \(f_2\) from \(f_1\)
Joint Density of \(f_1\) and \(f_8\)
-
-
-
-
-
-
-
-
-
-
-
-Prediction of \(f_{8}\) from \(f_{1}\)
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
where \(\alpha=\alpha^\prime \sqrt{\pi\ell^2}\).Joint Density of \(f_1\) and \(f_8\)
Prediction of \(f_{8}\) from \(f_{1}\)
-Where Did This Covariance Matrix Come From?
-
-
-from mlai import Kernel
-from mlai import eq_cov
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Polynomial Covariance
-
-
-
-
-
-
-
-
-
-
-
-
-
-
- -
-
-
-
-
-
Degenerate Covariance Functions
-
-Where Did This Covariance Matrix Come From?
from mlai import Kernelfrom mlai import eq_covPolynomial Covariance

Degenerate Covariance Functions
Basis Function Covariance
-
-Basis Function Covariance
-from mlai import basis_cov
-from mlai import radial
-
-
-
-
-
-
-
-
-
-
-
-
- -
-
-
-
-
-
-
-
-
-
-from mlai import basis_covfrom mlai import radial
Basis Function Covariance
\text{erf}\left(\frac{\left(a - \frac{1}{2}\left(x_i +
x_j\right)\right)}{\ell} \right)\right],
\end{aligned}\]Now we take the limit as \(a\rightarrow -\infty\) and \(b\rightarrow \infty\) \[k\left(x_i,x_j\right) = \alpha\exp\left(
- -\frac{\left(x_i-x_j\right)^2}{4\ell^2}\right).\] where \(\alpha=\alpha^\prime \sqrt{\pi\ell^2}\).Thanks!
-
-
-References
-
-
+ -\frac{\left(x_i-x_j\right)^2}{4\ell^2}\right).\]
-Cho, Y., Saul, L.K., 2009. Kernel methods for deep learning, in: Bengio, Y., Schuurmans, D., Lafferty, J.D., Williams, C.K.I., Culotta, A. (Eds.), Advances in Neural Information Processing Systems 22. Curran Associates, Inc., pp. 342–350.
-
-
-Ioffe, S., Szegedy, C., 2015. Batch normalization: Accelerating deep network training by reducing internal covariate shift, in: Bach, F., Blei, D. (Eds.), Proceedings of the 32nd International Conference on Machine Learning, Proceedings of Machine Learning Research. PMLR, Lille, France, pp. 448–456.
-
-
-Neal, R.M., 1994. Bayesian learning for neural networks (PhD thesis). University of Toronto, Canada.
-
-
-Tipping, M.E., Bishop, C.M., 1999. Probabilistic principal component analysis. Journal of the Royal Statistical Society, B 6, 611–622. https://doi.org/doi:10.1111/1467-9868.00196
-
-
-Williams, C.K.I., n.d. Computing with infinite networks.
-
-
In conclusion, an RBF model with infinite basis functions is a Gaussian process with the exponentiated quadratic covariance function \[k\left(x_i,x_j\right) = \alpha \exp\left( + -\frac{\left(x_i-x_j\right)^2}{4\ell^2}\right).\]
For more information on these subjects and more you might want to check the following resources.
We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling.
-import importlib.utilcmd = install_command('pods')%system {cmd}cmd = install_command('notutils')%system {cmd}cmd = install_command('mlai')%system {cmd}We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling.
import importlib.utilcmd = install_command('pods')%system {cmd}cmd = install_command('notutils')%system {cmd}cmd = install_command('mlai')%system {cmd}cmd = install_command('GPy')%system {cmd}Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics.
-
-Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy
-GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries.
-The software itself is available on GitHub and the team welcomes contributions.
-The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets.
-The documentation for GPy can be found here.
-The covariance function encapsulates our assumptions about the data. The equations for the distribution of the prediction function, given the training observations, are highly sensitive to the covariation between the test locations and the training locations as expressed by the matrix \(\mathbf{K}_*\). We defined a matrix \(\mathbf{A}\) which allowed us to express our conditional mean in the form, \[
+sns.set_palette('colorblind')}--> Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. The covariance function encapsulates our assumptions about the data. The equations for the distribution of the prediction function, given the training observations, are highly sensitive to the covariation between the test locations and the training locations as expressed by the matrix \(\mathbf{K}_*\). We defined a matrix \(\mathbf{A}\) which allowed us to express our conditional mean in the form, \[
\boldsymbol{ \mu}_f= \mathbf{A}^\top \mathbf{ y},
-\] where \(\mathbf{ y}\) were our training observations. In other words our mean predictions are always a linear weighted combination of our training data. The weights are given by computing the covariation between the training and the test data (\(\mathbf{K}_*\)) and scaling it by the inverse covariance of the training data observations, \(\left[\mathbf{K}+ \sigma^2 \mathbf{I}\right]^{-1}\). This inverse is the main computational object that needs to be resolved for a Gaussian process. It has a computational burden which is \(O(n^3)\) and a storage burden which is \(O(n^2)\). This makes working with Gaussian processes computationally intensive for the situation where \(n>10,000\). Figure: Introduction to Gaussian processes given by Neil Lawrence at the 2014 Gaussian process Winter School at the University of Sheffield. In practice we shouldn’t be using matrix inverse directly to solve the GP system. One more stable way is to compute the Cholesky decomposition of the kernel matrix. The log determinant of the covariance can also be derived from the Cholesky decomposition. Gaussian processes are sometimes seen as part of a wider family of methods known as kernel methods. Kernel methods are also based around covariance functions, but in the field they are known as Mercer kernels. Mercer kernels have interpretations as inner products in potentially infinite dimensional Hilbert spaces. This interpretation arises because, if we take \(\alpha=1\), then the kernel can be expressed as \[
-\mathbf{K}= \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top
+\] where \(\mathbf{ y}\) were our training observations. In other words our mean predictions are always a linear weighted combination of our training data. The weights are given by computing the covariation between the training and the test data (\(\mathbf{K}_*\)) and scaling it by the inverse covariance of the training data observations, \(\left[\mathbf{K}+ \sigma^2 \mathbf{I}\right]^{-1}\). This inverse is the main computational object that needs to be resolved for a Gaussian process. It has a computational burden which is \(O(n^3)\) and a storage burden which is \(O(n^2)\). This makes working with Gaussian processes computationally intensive for the situation where \(n>10,000\). Figure: Introduction to Gaussian processes given by Neil Lawrence at the 2014 Gaussian process Winter School at the University of Sheffield. In practice we shouldn’t be using matrix inverse directly to solve the GP system. One more stable way is to compute the Cholesky decomposition of the kernel matrix. The log determinant of the covariance can also be derived from the Cholesky decomposition. Gaussian processes are sometimes seen as part of a wider family of methods known as kernel methods. Kernel methods are also based around covariance functions, but in the field they are known as Mercer kernels. Mercer kernels have interpretations as inner products in potentially infinite dimensional Hilbert spaces. This interpretation arises because, if we take \(\alpha=1\), then the kernel can be expressed as \[
+\mathbf{K}= \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top
\] which imples the elements of the kernel are given by, \[
k(\mathbf{ x}, \mathbf{ x}^\prime) = \boldsymbol{ \phi}(\mathbf{ x})^\top \boldsymbol{ \phi}(\mathbf{ x}^\prime).
-\] So we see that the kernel function is developed from an inner product between the basis functions. Mercer’s theorem tells us that any valid positive definite function can be expressed as this inner product but with the caveat that the inner product could be infinite length. This idea has been used quite widely to kernelize algorithms that depend on inner products. The kernel functions are equivalent to covariance functions and they are parameterized accordingly. In the kernel modeling community it is generally accepted that kernel parameter estimation is a difficult problem and the normal solution is to cross validate to obtain parameters. This can cause difficulties when a large number of kernel parameters need to be estimated. In Gaussian process modelling kernel parameter estimation (in the simplest case proceeds) by maximum likelihood. This involves taking gradients of the likelihood with respect to the parameters of the covariance function. The easiest conceptual way to obtain the gradients is a two step process. The first step involves taking the gradient of the likelihood with respect to the covariance function, the second step involves considering the gradient of the covariance function with respect to its parameters. In general we won’t be able to find parameters of the covariance function through fixed point equations, we will need to do gradient based optimization. The objective function can be decomposed into two terms, a capacity control term, and a data fit term. The capacity control term is the log determinant of the covariance. The data fit term is the matrix inner product between the data and the inverse covariance. Can we determine covariance parameters from the data? \[
+\] So we see that the kernel function is developed from an inner product between the basis functions. Mercer’s theorem tells us that any valid positive definite function can be expressed as this inner product but with the caveat that the inner product could be infinite length. This idea has been used quite widely to kernelize algorithms that depend on inner products. The kernel functions are equivalent to covariance functions and they are parameterized accordingly. In the kernel modeling community it is generally accepted that kernel parameter estimation is a difficult problem and the normal solution is to cross validate to obtain parameters. This can cause difficulties when a large number of kernel parameters need to be estimated. In Gaussian process modelling kernel parameter estimation (in the simplest case proceeds) by maximum likelihood. This involves taking gradients of the likelihood with respect to the parameters of the covariance function. The easiest conceptual way to obtain the gradients is a two step process. The first step involves taking the gradient of the likelihood with respect to the covariance function, the second step involves considering the gradient of the covariance function with respect to its parameters. In general we won’t be able to find parameters of the covariance function through fixed point equations, we will need to do gradient based optimization. The objective function can be decomposed into two terms, a capacity control term, and a data fit term. The capacity control term is the log determinant of the covariance. The data fit term is the matrix inner product between the data and the inverse covariance. Can we determine covariance parameters from the data? \[
\mathscr{N}\left(\mathbf{ y}|\mathbf{0},\mathbf{K}\right)=\frac{1}{(2\pi)^\frac{n}{2}{\det{\mathbf{K}}^{\frac{1}{2}}}}{\exp\left(-\frac{\mathbf{ y}^{\top}\mathbf{K}^{-1}\mathbf{ y}}{2}\right)}
-\] \[
+\] \[
\begin{aligned}
\mathscr{N}\left(\mathbf{ y}|\mathbf{0},\mathbf{K}\right)=\frac{1}{(2\pi)^\frac{n}{2}\color{blue}{\det{\mathbf{K}}^{\frac{1}{2}}}}\color{red}{\exp\left(-\frac{\mathbf{ y}^{\top}\mathbf{K}^{-1}\mathbf{ y}}{2}\right)}
\end{aligned}
-\] \[
+\] \[
\begin{aligned}
\log \mathscr{N}\left(\mathbf{ y}|\mathbf{0},\mathbf{K}\right)=&\color{blue}{-\frac{1}{2}\log\det{\mathbf{K}}}\color{red}{-\frac{\mathbf{ y}^{\top}\mathbf{K}^{-1}\mathbf{ y}}{2}} \\ &-\frac{n}{2}\log2\pi
\end{aligned}
-\] \[
+\] \[
E(\boldsymbol{ \theta}) = \color{blue}{\frac{1}{2}\log\det{\mathbf{K}}} + \color{red}{\frac{\mathbf{ y}^{\top}\mathbf{K}^{-1}\mathbf{ y}}{2}}
-\] The parameters are inside the covariance function (matrix). \[k_{i, j} = k(\mathbf{ x}_i, \mathbf{ x}_j; \boldsymbol{ \theta})\] \[\mathbf{K}= \mathbf{R}\boldsymbol{ \Lambda}^2 \mathbf{R}^\top\] Figure: The determinant of the covariance is dependent only on the eigenvalues. It represents the ‘footprint’ of the Gaussian. Figure: The data fit term of the Gaussian process is a quadratic loss centered around zero. This has eliptical contours, the principal axes of which are given by the covariance matrix. The parameters are inside the covariance function (matrix). \[k_{i, j} = k(\mathbf{ x}_i, \mathbf{ x}_j; \boldsymbol{ \theta})\] \[\mathbf{K}= \mathbf{R}\boldsymbol{ \Lambda}^2 \mathbf{R}^\top\] Figure: The determinant of the covariance is dependent only on the eigenvalues. It represents the ‘footprint’ of the Gaussian. Figure: The data fit term of the Gaussian process is a quadratic loss centered around zero. This has eliptical contours, the principal axes of which are given by the covariance matrix. Figure: Variation in the data fit term, the capacity term and the negative log likelihood for different lengthscales. The exponentiated quadratic covariance, also known as the Gaussian covariance or the RBF covariance and the squared exponential. Covariance between two points is related to the negative exponential of the squared distnace between those points. This covariance function can be derived in a few different ways: as the infinite limit of a radial basis function neural network, as diffusion in the heat equation, as a Gaussian filter in Fourier space or as the composition as a series of linear filters applied to a base function. The covariance takes the following form, \[
+gp = GP(x, y, sigma2=0.01, kernel=kernel) Figure: Variation in the data fit term, the capacity term and the negative log likelihood for different lengthscales. The exponentiated quadratic covariance, also known as the Gaussian covariance or the RBF covariance and the squared exponential. Covariance between two points is related to the negative exponential of the squared distnace between those points. This covariance function can be derived in a few different ways: as the infinite limit of a radial basis function neural network, as diffusion in the heat equation, as a Gaussian filter in Fourier space or as the composition as a series of linear filters applied to a base function. The covariance takes the following form, \[
k(\mathbf{ x}, \mathbf{ x}^\prime) = \alpha \exp\left(-\frac{\left\Vert \mathbf{ x}-\mathbf{ x}^\prime \right\Vert_2^2}{2\ell^2}\right)
-\] where \(\ell\) is the length scale or time scale of the process and \(\alpha\) represents the overall process variance. Figure: The exponentiated quadratic covariance function. \[
-k(\mathbf{ x}, \mathbf{ x}^\prime) = \alpha \exp\left(-\frac{\left\Vert \mathbf{ x}- \mathbf{ x}^\prime\right\Vert^2_2}{2\ell^2}\right)\] Figure: Entrywise fill in of the covariance matrix from the covariance function. Figure: Entrywise fill in of the covariance matrix from the covariance function. Figure: Entrywise fill in of the covariance matrix from the covariance function. Brownian motion is also a Gaussian process. It follows a Gaussian random walk, with diffusion occuring at each time point driven by a Gaussian input. This implies it is both Markov and Gaussian. The covariance function for Brownian motion has the form \[
+\] where \(\ell\) is the length scale or time scale of the process and \(\alpha\) represents the overall process variance. Figure: The exponentiated quadratic covariance function. \[
+k(\mathbf{ x}, \mathbf{ x}^\prime) = \alpha \exp\left(-\frac{\left\Vert \mathbf{ x}- \mathbf{ x}^\prime\right\Vert^2_2}{2\ell^2}\right)\] Figure: Entrywise fill in of the covariance matrix from the covariance function. Figure: Entrywise fill in of the covariance matrix from the covariance function. Figure: Entrywise fill in of the covariance matrix from the covariance function. Brownian motion is also a Gaussian process. It follows a Gaussian random walk, with diffusion occuring at each time point driven by a Gaussian input. This implies it is both Markov and Gaussian. The covariance function for Brownian motion has the form \[
k(t, t^\prime)=\alpha \min(t, t^\prime)
-\] Figure: Brownian motion covariance function. Markov Process Visualization of inverse covariance (precision). Precision matrix is sparse: only neighbours in matrix are non-zero. This reflects conditional independencies in data. In this case Markov structure. Exponentiated Quadratic Visualization of inverse covariance (precision). rbfprecisionSample Markov Process Visualization of inverse covariance (precision). markovprecisionPlot The expontential covariance, in one dimension this is also known as the Ornstein Uhlenbeck covariance, and in multiple dimensions it’s also the Mater 1/2 covaraince. It has an interpretation as a stochastic differential equation with a linear drift term (equivalent to a quadratic potential). The drift keeps the covariance stationary (unlike the Brownian motion covariance). It also has an interpretation as a Cauchy filter in Fourier space (Stein, 1999) (from Bochner’s theorem). The covariance takes the following form, \[
+\] Figure: Brownian motion covariance function. Markov Process Visualization of inverse covariance (precision). Precision matrix is sparse: only neighbours in matrix are non-zero. This reflects conditional independencies in data. In this case Markov structure. Exponentiated Quadratic Visualization of inverse covariance (precision). rbfprecisionSample Markov Process Visualization of inverse covariance (precision). markovprecisionPlot The expontential covariance, in one dimension this is also known as the Ornstein Uhlenbeck covariance, and in multiple dimensions it’s also the Mater 1/2 covaraince. It has an interpretation as a stochastic differential equation with a linear drift term (equivalent to a quadratic potential). The drift keeps the covariance stationary (unlike the Brownian motion covariance). It also has an interpretation as a Cauchy filter in Fourier space (Stein, 1999) (from Bochner’s theorem). The covariance takes the following form, \[
k(\mathbf{ x}, \mathbf{ x}^\prime) = \alpha \exp\left(-\frac{\left\Vert \mathbf{ x}-\mathbf{ x}^\prime \right\Vert_2}{\ell}\right)
-\] where \(\ell\) is the length scale or time scale of the process and \(\alpha\) represents the overall process variance. Figure: The exponential covariance function. The fixed basis function covariance just comes from the properties of a multivariate Gaussian, if we decide \[
+\] where \(\ell\) is the length scale or time scale of the process and \(\alpha\) represents the overall process variance. Figure: The exponential covariance function. The fixed basis function covariance just comes from the properties of a multivariate Gaussian, if we decide \[
\mathbf{ f}=\boldsymbol{ \Phi}\mathbf{ w}
\] and then we assume \[
\mathbf{ w}\sim \mathscr{N}\left(\mathbf{0},\alpha\mathbf{I}\right)
\] then it follows from the properties of a multivariate Gaussian that \[
\mathbf{ f}\sim \mathscr{N}\left(\mathbf{0},\alpha\boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top\right)
-\] meaning that the vector of observations from the function is jointly distributed as a Gaussian process and the covariance matrix is \(\mathbf{K}= \alpha\boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top\), each element of the covariance matrix can then be found as the inner product between two rows of the basis funciton matrix. Figure: A covariance function based on a non-linear basis given by \(\boldsymbol{ \phi}(\mathbf{ x})\). Any linear basis function can also be incorporated into a covariance function. For example, an RBF network is a type of neural network with a set of radial basis functions. Meaning, the basis funciton is radially symmetric. These basis functions take the form, \[
+\] meaning that the vector of observations from the function is jointly distributed as a Gaussian process and the covariance matrix is \(\mathbf{K}= \alpha\boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top\), each element of the covariance matrix can then be found as the inner product between two rows of the basis funciton matrix. Figure: A covariance function based on a non-linear basis given by \(\boldsymbol{ \phi}(\mathbf{ x})\). Any linear basis function can also be incorporated into a covariance function. For example, an RBF network is a type of neural network with a set of radial basis functions. Meaning, the basis funciton is radially symmetric. These basis functions take the form, \[
\phi_k(x) = \exp\left(-\frac{\left\Vert x-\mu_k \right\Vert_2^{2}}{\ell^{2}}\right).
\] Given a set of parameters, \[
\boldsymbol{ \mu}= \begin{bmatrix} -1 \\ 0 \\ 1\end{bmatrix},
\] we can construct the corresponding covariance function, which has the form, \[
k\left(\mathbf{ x},\mathbf{ x}^{\prime}\right)=\alpha\boldsymbol{ \phi}(\mathbf{ x})^\top \boldsymbol{ \phi}(\mathbf{ x}^\prime).
-\] \[
+\] \[
Q(t) = \int_{\mathbb{R}} e^{-itx} \text{d} \mu(x).
- \] Imagine we are given data and we wish to generalize from it. Without making further assumptions, we have no more information than the given data set. We can think of this ssomewhat like a weighted sum of Dirac delta functions. The Dirac delta function is defined to be a function with an integral of one, which is zero at all places apart from zero, where it is infinite. Given observations at particular times (or locations) \(\mathbf{ x}_i\) we can think of our observations as being a function, \[
+ \] Imagine we are given data and we wish to generalize from it. Without making further assumptions, we have no more information than the given data set. We can think of this ssomewhat like a weighted sum of Dirac delta functions. The Dirac delta function is defined to be a function with an integral of one, which is zero at all places apart from zero, where it is infinite. Given observations at particular times (or locations) \(\mathbf{ x}_i\) we can think of our observations as being a function, \[
f(\mathbf{ x}) = \sum_{i=1}^ny_i \delta(\mathbf{ x}-\mathbf{ x}_i),
\] This function is highly discontinuous, imagine if we wished to smooth it by filtering in Fourier space. The Fourier transform of a function is given by, \[
F(\boldsymbol{\omega}) = \int_{-\infty}^\infty f(\mathbf{ x}) \exp\left(-i2\pi \boldsymbol{\omega}^\top \mathbf{ x}\right) \text{d} \mathbf{ x}
\] and since our function is a series of delta functions the the transform is easy to compute, \[
F(\boldsymbol{\omega}) = \sum_{i=1}^ny_i\exp\left(-i 2\pi \boldsymbol{\omega}^\top \mathbf{ x}_i\right)
-\] which has a real part given by a weighted sum of cosines and a complex part given by a weighted sum of sines. One theorem that gives insight into covariances is Bochner’s theorem. Bochner’s theorem states that any positive filter in Fourier space gives rise to a valid covariance function. Further, it gives a relationship between the filter and the form of the covariance function. The form of the covariance is given by the Fourier transform of the filter, with the argument of the transform being replaced by the distance between the points. Fourier space is a transformed space of the original function to a new basis. The transformation occurs through a convolution with a sine and cosine basis. Given a function of time \(f(t)\) the Fourier transform moves it to a weighted linear sum of a sine and cosine basis, \[
+\] which has a real part given by a weighted sum of cosines and a complex part given by a weighted sum of sines. One theorem that gives insight into covariances is Bochner’s theorem. Bochner’s theorem states that any positive filter in Fourier space gives rise to a valid covariance function. Further, it gives a relationship between the filter and the form of the covariance function. The form of the covariance is given by the Fourier transform of the filter, with the argument of the transform being replaced by the distance between the points. Fourier space is a transformed space of the original function to a new basis. The transformation occurs through a convolution with a sine and cosine basis. Given a function of time \(f(t)\) the Fourier transform moves it to a weighted linear sum of a sine and cosine basis, \[
F(\omega) = \int_{-\infty}^\infty f(t) \left[\cos(2\pi \omega t) - i \sin(2\pi \omega t) \right]\text{d} t
\] where is the imaginary basis, \(i=\sqrt{-1}\). Through Euler’s formula, \[
-\exp(ix) = \cos x + i\sin x
+\exp(ix) = \cos x + i\sin x
\] we can re-express this form as \[
F(\omega) = \int_{-\infty}^\infty f(t) \exp(-i 2\pi\omega)\text{d} t
\] which is a standard form for the Fourier transform. Fourier’s theorem was that the inverse transform can also be expressed in a similar form so we have \[
f(t) = \int_{-\infty}^\infty F(\omega) \exp(2\pi\omega)\text{d} \omega.
-\] Although we’ve introduced the transform in the context of time Fourier’s interest was an analytical theory of heat and the transform can be applied to a multidimensional spatial function, \(f(\mathbf{ x})\). Another approach to developing covariance function exploits Bochner’s theorem Bochner (1959). Bochner’s theorem tells us that any positve filter in Fourier space implies has an associated Gaussian process with a stationary covariance function. The covariance function is the inverse Fourier transform of the filter applied in Fourier space. For example, in signal processing, band limitations are commonly applied as an assumption. For example, we may believe that no frequency above \(w=2\) exists in the signal. This is equivalent to a rectangle function being applied as a the filter in Fourier space. The inverse Fourier transform of the rectangle function is the \(\text{sinc}(\cdot)\) function. So the sinc is a valid covariance function, and it represents band limited signals. Note that other covariance functions we’ve introduced can also be interpreted in this way. For example, the exponentiated quadratic covariance function can be Fourier transformed to see what the implied filter in Fourier space is. The Fourier transform of the exponentiated quadratic is an exponentiated quadratic, so the standard EQ-covariance implies a EQ filter in Fourier space. Figure: Sinc covariance function. The Matérn 3/2 (Stein, 1999) covariance is which is once differentiable, it arises from applying a Student-\(t\) based filter in Fourier space with three degrees of freedom. The covariance takes the following form, \[
+\] Although we’ve introduced the transform in the context of time Fourier’s interest was an analytical theory of heat and the transform can be applied to a multidimensional spatial function, \(f(\mathbf{ x})\). Another approach to developing covariance function exploits Bochner’s theorem Bochner (1959). Bochner’s theorem tells us that any positve filter in Fourier space implies has an associated Gaussian process with a stationary covariance function. The covariance function is the inverse Fourier transform of the filter applied in Fourier space. For example, in signal processing, band limitations are commonly applied as an assumption. For example, we may believe that no frequency above \(w=2\) exists in the signal. This is equivalent to a rectangle function being applied as a the filter in Fourier space. The inverse Fourier transform of the rectangle function is the \(\text{sinc}(\cdot)\) function. So the sinc is a valid covariance function, and it represents band limited signals. Note that other covariance functions we’ve introduced can also be interpreted in this way. For example, the exponentiated quadratic covariance function can be Fourier transformed to see what the implied filter in Fourier space is. The Fourier transform of the exponentiated quadratic is an exponentiated quadratic, so the standard EQ-covariance implies a EQ filter in Fourier space. Figure: Sinc covariance function. The Matérn 3/2 (Stein, 1999) covariance is which is once differentiable, it arises from applying a Student-\(t\) based filter in Fourier space with three degrees of freedom. The covariance takes the following form, \[
k(\mathbf{ x}, \mathbf{ x}^\prime) = \alpha \left(1+\frac{\sqrt{3}\left\Vert \mathbf{ x}-\mathbf{ x}^\prime \right\Vert_2}{\ell}\right)\exp\left(-\frac{\sqrt{3}\left\Vert \mathbf{ x}-\mathbf{ x}^\prime \right\Vert_2}{\ell}\right)
-\] where \(\ell\) is the length scale or time scale of the process and \(\alpha\) represents the overall process variance. Figure: The Matérn 3/2 covariance function. The Matérn 5/2 (Stein, 1999) covariance is which is once differentiable, it arises from applying a Student-\(t\) based filter in Fourier space with five degrees of freedom. The covariance takes the following form, \[
+\] where \(\ell\) is the length scale or time scale of the process and \(\alpha\) represents the overall process variance. Figure: The Matérn 3/2 covariance function. The Matérn 5/2 (Stein, 1999) covariance is which is once differentiable, it arises from applying a Student-\(t\) based filter in Fourier space with five degrees of freedom. The covariance takes the following form, \[
k(\mathbf{ x}, \mathbf{ x}^\prime) = \alpha \left(1+\frac{\sqrt{5}\left\Vert \mathbf{ x}-\mathbf{ x}^\prime \right\Vert_2}{\ell} + \frac{5\left\Vert \mathbf{ x}-\mathbf{ x}^\prime \right\Vert_2^2}{3\ell^2}\right)\exp\left(-\frac{\sqrt{5}\left\Vert \mathbf{ x}-\mathbf{ x}^\prime \right\Vert_2}{\ell}\right)
-\] where \(\ell\) is the length scale or time scale of the process and \(\alpha\) represents the overall process variance. Figure: The Matérn 5/2 covariance function. The rational quadratic covariance function is derived by a continuous mixture of exponentiated quadratic covariance funcitons, where the lengthscale is given by an inverse gamma distribution. The resulting covariance is infinitely smooth (in terms of differentiability) but has a family of length scales present. As \(a\) gets larger, the exponentiated quadratic covariance funciton is recovered. The covariance takes the following form, \[
+\] where \(\ell\) is the length scale or time scale of the process and \(\alpha\) represents the overall process variance. Figure: The Matérn 5/2 covariance function. The rational quadratic covariance function is derived by a continuous mixture of exponentiated quadratic covariance funcitons, where the lengthscale is given by an inverse gamma distribution. The resulting covariance is infinitely smooth (in terms of differentiability) but has a family of length scales present. As \(a\) gets larger, the exponentiated quadratic covariance funciton is recovered. The covariance takes the following form, \[
k(\mathbf{ x}, \mathbf{ x}^\prime) = \alpha \left(1+\frac{\left\Vert \mathbf{ x}-\mathbf{ x}^\prime \right\Vert_2^2}{2 a \ell^2}\right)^{-a}
-\] where \(\ell\) is the length scale or time scale of the process and \(\alpha\) represents the overall process variance and \(a\) represents shape parameter of the inverse Gamma used to create the scale mixture. Figure: The rational quadratic covariance function. Figure: Polynomial covariance function. Figure: Periodic covariance function. The multi-layer perceptron (MLP) covariance, also known as the neural network covariance or the arcsin covariance, is derived by considering the infinite limit of a neural network. Figure: The multi-layer perceptron covariance function. This is derived by considering the infinite limit of a neural network with probit activation functions. Figure: Rectified linear unit covariance function. An additive covariance function is derived from considering the result of summing two Gaussian processes together. If the first Gaussian process is \(g(\cdot)\), governed by covariance \(k_g(\cdot, \cdot)\) and the second process is \(h(\cdot)\), governed by covariance \(k_h(\cdot, \cdot)\) then the combined process \(f(\cdot) = g(\cdot) + h(\cdot)\) is govererned by a covariance function, \[
+\] where \(\ell\) is the length scale or time scale of the process and \(\alpha\) represents the overall process variance and \(a\) represents shape parameter of the inverse Gamma used to create the scale mixture. Figure: The rational quadratic covariance function. Figure: Polynomial covariance function. Figure: Periodic covariance function. The multi-layer perceptron (MLP) covariance, also known as the neural network covariance or the arcsin covariance, is derived by considering the infinite limit of a neural network. Figure: The multi-layer perceptron covariance function. This is derived by considering the infinite limit of a neural network with probit activation functions. Figure: Rectified linear unit covariance function. An additive covariance function is derived from considering the result of summing two Gaussian processes together. If the first Gaussian process is \(g(\cdot)\), governed by covariance \(k_g(\cdot, \cdot)\) and the second process is \(h(\cdot)\), governed by covariance \(k_h(\cdot, \cdot)\) then the combined process \(f(\cdot) = g(\cdot) + h(\cdot)\) is govererned by a covariance function, \[
k_f(\mathbf{ x}, \mathbf{ x}^\prime) = k_g(\mathbf{ x}, \mathbf{ x}^\prime) + k_h(\mathbf{ x}, \mathbf{ x}^\prime)
-\] Figure: An additive covariance function formed by combining a linear and an exponentiated quadratic covariance functions. An product covariance function is derived from considering the result of multiplying two stochastic processes together. If the first stochastic process is \(g(\cdot)\), governed by covariance \(k_g(\cdot, \cdot)\) and the second process is \(h(\cdot)\), governed by covariance \(k_h(\cdot, \cdot)\) then the combined process \(f(\cdot) = g(\cdot) h(\cdot)\) is governed by a covariance function, \[
+\] Figure: An additive covariance function formed by combining a linear and an exponentiated quadratic covariance functions. An product covariance function is derived from considering the result of multiplying two stochastic processes together. If the first stochastic process is \(g(\cdot)\), governed by covariance \(k_g(\cdot, \cdot)\) and the second process is \(h(\cdot)\), governed by covariance \(k_h(\cdot, \cdot)\) then the combined process \(f(\cdot) = g(\cdot) h(\cdot)\) is governed by a covariance function, \[
k_f(\mathbf{ x}, \mathbf{ x}^\prime) = k_g(\mathbf{ x}, \mathbf{ x}^\prime) k_h(\mathbf{ x}, \mathbf{ x}^\prime)
-\] Note that if \(g(\cdot)\) and \(h(\cdot)\) are Gaussian processes then \(f(\cdot)\) will not in general be a Gaussian process. So the base processes are (presumably) some (unspecified) non-Gaussian processes. Figure: An product covariance function formed by combining a linear and an exponentiated quadratic covariance functions. The Mauna Loa data consists of monthly mean carbon dioxide measured at Mauna Loa Observatory, Hawaii. According to the website, https://www.esrl.noaa.gov/gmd/ccgg/trends/. The carbon dioxide data on Mauna Loa constitute the longest record of direct measurements of CO2 in the atmosphere. They were started by C. David Keeling of the Scripps Institution of Oceanography in March of 1958 at a facility of the National Oceanic and Atmospheric Administration (Keeling et al., 1976). NOAA started its own CO2 measurements in May of 1974, and they have run in parallel with those made by Scripps since then (Thoning et al., 1989). Here, if you’ve downloaded the data before you have a cached version. To download a fresh version of the data I can set Figure: An product covariance function formed by combining a linear and an exponentiated quadratic covariance functions. The Mauna Loa data consists of monthly mean carbon dioxide measured at Mauna Loa Observatory, Hawaii. According to the website, https://www.esrl.noaa.gov/gmd/ccgg/trends/. The carbon dioxide data on Mauna Loa constitute the longest record of direct measurements of CO2 in the atmosphere. They were started by C. David Keeling of the Scripps Institution of Oceanography in March of 1958 at a facility of the National Oceanic and Atmospheric Administration (Keeling et al., 1976). NOAA started its own CO2 measurements in May of 1974, and they have run in parallel with those made by Scripps since then (Thoning et al., 1989). Here, if you’ve downloaded the data before you have a cached version. To download a fresh version of the data I can set The data dictionary contains the standard keys ‘X’ and ‘Y’ which give a unidimensional regression problem. Figure: Mauna Loa data shows carbon dioxide monthly average measurements from the Mauna Loa Observatory in Hawaii. Additionally there are keys The data dictionary contains the standard keys ‘X’ and ‘Y’ which give a unidimensional regression problem. Figure: Mauna Loa data shows carbon dioxide monthly average measurements from the Mauna Loa Observatory in Hawaii. Additionally there are keys Figure: Mauna Loa test data shows carbon dioxide monthly average measurements from the Mauna Loa Observatory in Hawaii. Of course we have included the citation information for the data. And extra information about the data is included, as standard, under the keys Figure: Mauna Loa test data shows carbon dioxide monthly average measurements from the Mauna Loa Observatory in Hawaii. Of course we have included the citation information for the data. And extra information about the data is included, as standard, under the keys And, importantly, for reference you can also check the license for the data: The data set was used as a demonstration of model selection for Gaussian processes in Rasmussen and Williams (2006) (Chapter 5). Here we reconstruct that analysis in GPy. Our first objective will be to perform a Gaussian process fit to the data, we’ll do this using the GPy software. And, importantly, for reference you can also check the license for the data: The data set was used as a demonstration of model selection for Gaussian processes in Rasmussen and Williams (2006) (Chapter 5). Here we reconstruct that analysis in GPy. Our first objective will be to perform a Gaussian process fit to the data, we’ll do this using the GPy software. The first command sets up the model, then The first command sets up the model, then Now we plot the results using the helper function in Figure: Gaussian process fit to the Mauna Loa Observatory data on CO2 concentrations. This data is giving airline passenger numbers between 1948 and 1960. It was published by Box and Jenkins (1976). Now we plot the results using the helper function in Figure: Gaussian process fit to the Mauna Loa Observatory data on CO2 concentrations. This data is giving airline passenger numbers between 1948 and 1960. It was published by Box and Jenkins (1976). Figure: Box-Jenkins data set on airline passenger numbers. Here we reconstruct that analysis in GPy. Our first objective will be to perform a Gaussian process fit to the data, we’ll do this using the GPy software. Figure: Box-Jenkins data set on airline passenger numbers. Here we reconstruct that analysis in GPy. Our first objective will be to perform a Gaussian process fit to the data, we’ll do this using the GPy software. The first command sets up the model, then The first command sets up the model, then Now we plot the results using the helper function in Figure: Gaussian process fit to the Box-Jenkins airline passenger data. Now we plot the results using the helper function in Figure: Gaussian process fit to the Box-Jenkins airline passenger data. Figure: Spectral mixture GP as applied to the Box-Jenkins airline data. Figure: Spectral mixture GP as applied to the Box-Jenkins airline data. Now we optimize the model. Figure: Spectral mixture GP as applied to the Mauna Loa Observatory carbon dioxide concentration data. For more information on these subjects and more you might want to check the following resources. Now we optimize the model. Figure: Spectral mixture GP as applied to the Mauna Loa Observatory carbon dioxide concentration data. For more information on these subjects and more you might want to check the following resources. We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling. We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling. Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. In practice we shouldn’t be using matrix inverse directly to solve the GP system. One more stable way is to compute the Cholesky decomposition of the kernel matrix. The log determinant of the covariance can also be derived from the Cholesky decomposition. Gaussian processes are sometimes seen as part of a wider family of methods known as kernel methods. Kernel methods are also based around covariance functions, but in the field they are known as Mercer kernels. Mercer kernels have interpretations as inner products in potentially infinite dimensional Hilbert spaces. This interpretation arises because, if we take \(\alpha=1\), then the kernel can be expressed as \[
-\mathbf{K}= \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top
+sns.set_palette('colorblind')}--> Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. In practice we shouldn’t be using matrix inverse directly to solve the GP system. One more stable way is to compute the Cholesky decomposition of the kernel matrix. The log determinant of the covariance can also be derived from the Cholesky decomposition. Gaussian processes are sometimes seen as part of a wider family of methods known as kernel methods. Kernel methods are also based around covariance functions, but in the field they are known as Mercer kernels. Mercer kernels have interpretations as inner products in potentially infinite dimensional Hilbert spaces. This interpretation arises because, if we take \(\alpha=1\), then the kernel can be expressed as \[
+\mathbf{K}= \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top
\] which imples the elements of the kernel are given by, \[
k(\mathbf{ x}, \mathbf{ x}^\prime) = \boldsymbol{ \phi}(\mathbf{ x})^\top \boldsymbol{ \phi}(\mathbf{ x}^\prime).
-\] So we see that the kernel function is developed from an inner product between the basis functions. Mercer’s theorem tells us that any valid positive definite function can be expressed as this inner product but with the caveat that the inner product could be infinite length. This idea has been used quite widely to kernelize algorithms that depend on inner products. The kernel functions are equivalent to covariance functions and they are parameterized accordingly. In the kernel modeling community it is generally accepted that kernel parameter estimation is a difficult problem and the normal solution is to cross validate to obtain parameters. This can cause difficulties when a large number of kernel parameters need to be estimated. In Gaussian process modelling kernel parameter estimation (in the simplest case proceeds) by maximum likelihood. This involves taking gradients of the likelihood with respect to the parameters of the covariance function. The easiest conceptual way to obtain the gradients is a two step process. The first step involves taking the gradient of the likelihood with respect to the covariance function, the second step involves considering the gradient of the covariance function with respect to its parameters. In general we won’t be able to find parameters of the covariance function through fixed point equations, we will need to do gradient based optimization. The objective function can be decomposed into two terms, a capacity control term, and a data fit term. The capacity control term is the log determinant of the covariance. The data fit term is the matrix inner product between the data and the inverse covariance. Can we determine covariance parameters from the data? \[
+\] So we see that the kernel function is developed from an inner product between the basis functions. Mercer’s theorem tells us that any valid positive definite function can be expressed as this inner product but with the caveat that the inner product could be infinite length. This idea has been used quite widely to kernelize algorithms that depend on inner products. The kernel functions are equivalent to covariance functions and they are parameterized accordingly. In the kernel modeling community it is generally accepted that kernel parameter estimation is a difficult problem and the normal solution is to cross validate to obtain parameters. This can cause difficulties when a large number of kernel parameters need to be estimated. In Gaussian process modelling kernel parameter estimation (in the simplest case proceeds) by maximum likelihood. This involves taking gradients of the likelihood with respect to the parameters of the covariance function. The easiest conceptual way to obtain the gradients is a two step process. The first step involves taking the gradient of the likelihood with respect to the covariance function, the second step involves considering the gradient of the covariance function with respect to its parameters. In general we won’t be able to find parameters of the covariance function through fixed point equations, we will need to do gradient based optimization. The objective function can be decomposed into two terms, a capacity control term, and a data fit term. The capacity control term is the log determinant of the covariance. The data fit term is the matrix inner product between the data and the inverse covariance. Can we determine covariance parameters from the data? \[
\mathscr{N}\left(\mathbf{ y}|\mathbf{0},\mathbf{K}\right)=\frac{1}{(2\pi)^\frac{n}{2}{\det{\mathbf{K}}^{\frac{1}{2}}}}{\exp\left(-\frac{\mathbf{ y}^{\top}\mathbf{K}^{-1}\mathbf{ y}}{2}\right)}
-\] \[
+\] \[
\begin{aligned}
\mathscr{N}\left(\mathbf{ y}|\mathbf{0},\mathbf{K}\right)=\frac{1}{(2\pi)^\frac{n}{2}\color{blue}{\det{\mathbf{K}}^{\frac{1}{2}}}}\color{red}{\exp\left(-\frac{\mathbf{ y}^{\top}\mathbf{K}^{-1}\mathbf{ y}}{2}\right)}
\end{aligned}
-\] \[
+\] \[
\begin{aligned}
\log \mathscr{N}\left(\mathbf{ y}|\mathbf{0},\mathbf{K}\right)=&\color{blue}{-\frac{1}{2}\log\det{\mathbf{K}}}\color{red}{-\frac{\mathbf{ y}^{\top}\mathbf{K}^{-1}\mathbf{ y}}{2}} \\ &-\frac{n}{2}\log2\pi
\end{aligned}
-\] \[
+\] \[
E(\boldsymbol{ \theta}) = \color{blue}{\frac{1}{2}\log\det{\mathbf{K}}} + \color{red}{\frac{\mathbf{ y}^{\top}\mathbf{K}^{-1}\mathbf{ y}}{2}}
-\] The parameters are inside the covariance function (matrix). \[k_{i, j} = k(\mathbf{ x}_i, \mathbf{ x}_j; \boldsymbol{ \theta})\] \[\mathbf{K}= \mathbf{R}\boldsymbol{ \Lambda}^2 \mathbf{R}^\top\] Figure: The determinant of the covariance is dependent only on the eigenvalues. It represents the ‘footprint’ of the Gaussian. Figure: The data fit term of the Gaussian process is a quadratic loss centered around zero. This has eliptical contours, the principal axes of which are given by the covariance matrix. The parameters are inside the covariance function (matrix). \[k_{i, j} = k(\mathbf{ x}_i, \mathbf{ x}_j; \boldsymbol{ \theta})\] \[\mathbf{K}= \mathbf{R}\boldsymbol{ \Lambda}^2 \mathbf{R}^\top\] Figure: The determinant of the covariance is dependent only on the eigenvalues. It represents the ‘footprint’ of the Gaussian. Figure: The data fit term of the Gaussian process is a quadratic loss centered around zero. This has eliptical contours, the principal axes of which are given by the covariance matrix. Figure: Variation in the data fit term, the capacity term and the negative log likelihood for different lengthscales. We now consider an example in gene expression. Gene expression is the measurement of mRNA levels expressed in cells. These mRNA levels show which genes are ‘switched on’ and producing data. In the example we will use a Gaussian process to determine whether a given gene is active, or we are merely observing a noise response. Figure: Variation in the data fit term, the capacity term and the negative log likelihood for different lengthscales. We now consider an example in gene expression. Gene expression is the measurement of mRNA levels expressed in cells. These mRNA levels show which genes are ‘switched on’ and producing data. In the example we will use a Gaussian process to determine whether a given gene is active, or we are merely observing a noise response. Figure: Gene expression levels over time for a gene from data provided by Della Gatta et al. (2008). We would like to understand whether there is signal in the data, or we are only observing noise. Figure: The example is taken from the paper “A Simple Approach to Ranking Differentially Expressed Gene Expression Time Courses through Gaussian Process Regression.” Kalaitzis and Lawrence (2011). Our first objective will be to perform a Gaussian process fit to the data, we’ll do this using the GPy software. Figure: Gene expression levels over time for a gene from data provided by Della Gatta et al. (2008). We would like to understand whether there is signal in the data, or we are only observing noise. Figure: The example is taken from the paper “A Simple Approach to Ranking Differentially Expressed Gene Expression Time Courses through Gaussian Process Regression.” Kalaitzis and Lawrence (2011). Our first objective will be to perform a Gaussian process fit to the data, we’ll do this using the GPy software. Initialize the length scale parameter (which here actually represents a time scale of the covariance function) to a reasonable value. Default would be 1, but here we set it to 50 minutes, given points are arriving across zero to 250 minutes. Initialize the length scale parameter (which here actually represents a time scale of the covariance function) to a reasonable value. Default would be 1, but here we set it to 50 minutes, given points are arriving across zero to 250 minutes. Now we plot the results using the helper function in Figure: Result of the fit of the Gaussian process model with the time scale parameter initialized to 50 minutes. Now we try a model initialized with a longer length scale. Now we plot the results using the helper function in Figure: Result of the fit of the Gaussian process model with the time scale parameter initialized to 50 minutes. Now we try a model initialized with a longer length scale. Figure: Result of the fit of the Gaussian process model with the time scale parameter initialized to 2000 minutes. Now we try a model initialized with a lower noise. Figure: Result of the fit of the Gaussian process model with the time scale parameter initialized to 2000 minutes. Now we try a model initialized with a lower noise. Figure: Result of the fit of the Gaussian process model with the noise initialized low (standard deviation 0.1) and the time scale parameter initialized to 20 minutes. Figure: For more information on these subjects and more you might want to check the following resources. For more information on these subjects and more you might want to check the following resources. We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling. Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. We have state vector \(\mathbf{X}= \left[\mathbf{ x}_1 \dots \mathbf{ x}_q\right] \in \mathbb{R}^{T \times q}\) and if each state evolves independently we have \[
+sns.set_palette('colorblind')}--> Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. We have state vector \(\mathbf{X}= \left[\mathbf{ x}_1 \dots \mathbf{ x}_q\right] \in \mathbb{R}^{T \times q}\) and if each state evolves independently we have \[
\begin{align*}
p(\mathbf{X}) &= \prod_{i=1}^qp(\mathbf{ x}_{:, i}) \\
p(\mathbf{ x}_{:, i}) &= \mathscr{N}\left(\mathbf{ x}_{:, i}|\mathbf{0},\mathbf{K}\right).
@@ -38,7 +37,7 @@
\vdots\\
\mathbf{ x}_{:, q}
\end{bmatrix}
-\] Figure: Illustration of the Kronecker product. Figure: Kronecker product between two matrices. Figure: Illustration of the Kronecker product. Figure: Kronecker product between two matrices. For this stacking the marginal distribution over time is given by the block diagonals. Figure: The marginal distribution for the first three variables (highlighted) is givne by \(\mathbf{K}\) when the form of stacking is \(\mathbf{I}\otimes \mathbf{K}\). This is the ‘column stacking’ case. Can also stack each row of \(\mathbf{X}\) to form column vector: \[\mathbf{ x}= \begin{bmatrix}
+ \] For this stacking the marginal distribution over time is given by the block diagonals. Figure: The marginal distribution for the first three variables (highlighted) is givne by \(\mathbf{K}\) when the form of stacking is \(\mathbf{I}\otimes \mathbf{K}\). This is the ‘column stacking’ case. Can also stack each row of \(\mathbf{X}\) to form column vector: \[\mathbf{ x}= \begin{bmatrix}
\mathbf{ x}_{1, :}\\
\mathbf{ x}_{2, :}\\
\vdots\\
\mathbf{ x}_{T, :}
- \end{bmatrix}\] \[p(\mathbf{ x}) = \mathscr{N}\left(\mathbf{ x}|\mathbf{0},\mathbf{K}\otimes \mathbf{I}\right)\] For this stacking the marginal distribution over the latent dimensions is given by the block diagonals. Figure: The marginal distribution for the first three variables (highlighted) is independent when the form of stacking is \(\mathbf{K}\otimes \mathbf{I}\). This is the ‘row stacking’ case. Figure: Mapping from latent process to observed The observations are related to the latent points by a linear mapping matrix, \[
+ \end{bmatrix}\] \[p(\mathbf{ x}) = \mathscr{N}\left(\mathbf{ x}|\mathbf{0},\mathbf{K}\otimes \mathbf{I}\right)\] For this stacking the marginal distribution over the latent dimensions is given by the block diagonals. Figure: The marginal distribution for the first three variables (highlighted) is independent when the form of stacking is \(\mathbf{K}\otimes \mathbf{I}\). This is the ‘row stacking’ case. Figure: Mapping from latent process to observed The observations are related to the latent points by a linear mapping matrix, \[
\mathbf{ y}_{i, :} = \mathbf{W}\mathbf{ x}_{i, :} + \boldsymbol{ \epsilon}_{i, :}
\] \[
\boldsymbol{ \epsilon}\sim \mathscr{N}\left(\mathbf{0},\sigma^2\mathbf{I}\right)
-\] Figure: This leads to a covariance of the form \[
+\] Figure: This leads to a covariance of the form \[
(\mathbf{I}\otimes \mathbf{W}) (\mathbf{K}\otimes \mathbf{I}) (\mathbf{I}\otimes \mathbf{W}^\top) + \mathbf{I}\sigma^2
\] Using \((\mathbf{A}\otimes\mathbf{B}) (\mathbf{C}\otimes\mathbf{D}) = \mathbf{A}\mathbf{C} \otimes \mathbf{B}\mathbf{D}\) This leads to \[
\mathbf{K}\otimes {\mathbf{W}}{\mathbf{W}}^\top + \mathbf{I}\sigma^2
@@ -72,7 +71,7 @@
\mathbf{ w}= \begin{bmatrix} 1 \\ 5\end{bmatrix}
\] \[
\mathbf{B}= \begin{bmatrix} 1 & 5\\ 5&25\end{bmatrix}
-\] Figure: Intrinsic coregionalization model covariance function. \[
+\] Figure: Intrinsic coregionalization model covariance function. \[
\mathbf{K}(\mathbf{X}, \mathbf{X}) = \mathbf{B}\otimes k(\mathbf{X}, \mathbf{X}).
\] \[
\mathbf{B}= \begin{bmatrix} 1 & 0.5\\ 0.5& 1.5\end{bmatrix}
@@ -84,19 +83,19 @@
\mathbf{ w}_1 = \begin{bmatrix} 0.5 \\ 1\end{bmatrix}
\] \[
\mathbf{ w}_2 = \begin{bmatrix} 1 \\ 0.5\end{bmatrix}
-\] Bonilla et al. (n.d.) suggest ICM for multitask learning. Use a PPCA form for \(\mathbf{B}\): similar to our Kalman filter example. Refer to the autokrigeability effect as the cancellation of inter-task transfer. Also discuss the similarities between the multi-task GP and the ICM, and its relationship to the SLFM and the LMC. Mostly restricted to the case where the outputs are conditionally independent given the hyperparameters \(\boldsymbol{\phi}\) (Lawrence and Platt, 2004; Minka and Picard, 1997; Rasmussen and Williams, 2006; Seeger and Jordan, 2004; Williams and Barber, 1998; Yu et al., 2005). Intrinsic coregionalization model has been used in the multiclass scenario. Skolidis and Sanguinetti (2011) use the intrinsic coregionalization model for classification, by introducing a probit noise model as the likelihood. Posterior distribution is no longer analytically tractable: approximate inference is required. A statistical model used as a surrogate for a computationally expensive computer model. Higdon et al. (2008) use the linear model of coregionalization to model images representing the evolution of the implosion of steel cylinders. In Conti and O’Hagan (2009) use the ICM to model a vegetation model: called the Sheffield Dynamic Global Vegetation Model Woodward et al. (1998). Image from Wikimedia Commons http://bit.ly/16kMKHQ by Darren Wilkinson The first think we will look at is a multiple output model. Our aim is to jointly model all sprinting events from olympics since 1896. Data is provided by Rogers & Girolami’s “First Course in Machine Learning.” Firstly, let’s load in the data. Bonilla et al. (n.d.) suggest ICM for multitask learning. Use a PPCA form for \(\mathbf{B}\): similar to our Kalman filter example. Refer to the autokrigeability effect as the cancellation of inter-task transfer. Also discuss the similarities between the multi-task GP and the ICM, and its relationship to the SLFM and the LMC. Mostly restricted to the case where the outputs are conditionally independent given the hyperparameters \(\boldsymbol{\phi}\) (Lawrence and Platt, 2004; Minka and Picard, 1997; Rasmussen and Williams, 2006; Seeger and Jordan, 2004; Williams and Barber, 1998; Yu et al., 2005). Intrinsic coregionalization model has been used in the multiclass scenario. Skolidis and Sanguinetti (2011) use the intrinsic coregionalization model for classification, by introducing a probit noise model as the likelihood. Posterior distribution is no longer analytically tractable: approximate inference is required. A statistical model used as a surrogate for a computationally expensive computer model. Higdon et al. (2008) use the linear model of coregionalization to model images representing the evolution of the implosion of steel cylinders. In Conti and O’Hagan (2009) use the ICM to model a vegetation model: called the Sheffield Dynamic Global Vegetation Model Woodward et al. (1998). Image from Wikimedia Commons http://bit.ly/16kMKHQ by Darren Wilkinson The first think we will look at is a multiple output model. Our aim is to jointly model all sprinting events from olympics since 1896. Data is provided by Rogers & Girolami’s “First Course in Machine Learning.” Firstly, let’s load in the data. When using data sets it’s good practice to cite the originators of the data, you can get information about the source of the data from The data consists of all the male and female sprinting data for 100m, 200m and 400m since 1896 (six outputs in total). The output information can be found from: In Now let’s plot the data Figure: Olympic sprint gold medal winning times from Rogers and Girolami (2011). In the plot above red is women’s events, blue is men’s. Squares are 400 m, crosses 200m and circles 100m. Not all events were run in all years, for example the women’s 400 m only started in 1964. We will perform a multi-output Gaussian process fit to the data, we’ll do this using the GPy software. We will look at modelling the data using coregionalization approaches described in this morning’s lecture. We introduced these approaches through the Kronecker product. To indicate we want to construct a covariance function of this type in GPy we’ve overloaded the The coregionalize matrix, \(\mathbf{B}\), is itself is constructed from two other matrices, \(\mathbf{B} = \mathbf{W}\mathbf{W}^\top + \text{diag}(\boldsymbol{\kappa})\). This allows us to specify a low rank form for the coregionalization matrix. However, for our first example we want to specify that the matrix \(\mathbf{B}\) is not constrained to have a low rank form. Note here that the rank we specify is that of the \(\mathbf{W}\mathbf{W}^\top\) part. When this part is combined with the diagonal matrix from \(\mathbf{\kappa}\) the matrix \(\mathbf{B}\) is totally general. This covariance function can now be used in a standard Gaussian process regression model. Let’s build the model and optimize it. We can plot the results using the ability to ‘fix inputs’ in the Figure: Gaussian process fit to the Olympic Sprint data. There is a lot we can do with this model. First of all, each of the races is a different length, so the series have a different mean. We can include another coregionalization term to deal with the mean. Below we do this and reduce the rank of the coregionalization matrix to 1. Now let’s plot the data Figure: Olympic sprint gold medal winning times from Rogers and Girolami (2011). In the plot above red is women’s events, blue is men’s. Squares are 400 m, crosses 200m and circles 100m. Not all events were run in all years, for example the women’s 400 m only started in 1964. We will perform a multi-output Gaussian process fit to the data, we’ll do this using the GPy software. We will look at modelling the data using coregionalization approaches described in this morning’s lecture. We introduced these approaches through the Kronecker product. To indicate we want to construct a covariance function of this type in GPy we’ve overloaded the The coregionalize matrix, \(\mathbf{B}\), is itself is constructed from two other matrices, \(\mathbf{B} = \mathbf{W}\mathbf{W}^\top + \text{diag}(\boldsymbol{\kappa})\). This allows us to specify a low rank form for the coregionalization matrix. However, for our first example we want to specify that the matrix \(\mathbf{B}\) is not constrained to have a low rank form. Note here that the rank we specify is that of the \(\mathbf{W}\mathbf{W}^\top\) part. When this part is combined with the diagonal matrix from \(\mathbf{\kappa}\) the matrix \(\mathbf{B}\) is totally general. This covariance function can now be used in a standard Gaussian process regression model. Let’s build the model and optimize it. We can plot the results using the ability to ‘fix inputs’ in the Figure: Gaussian process fit to the Olympic Sprint data. There is a lot we can do with this model. First of all, each of the races is a different length, so the series have a different mean. We can include another coregionalization term to deal with the mean. Below we do this and reduce the rank of the coregionalization matrix to 1. Figure: Gaussian process fit to the Olympic Sprint data. This is a simple form of the linear model of coregionalization. Note how confident the model is about what the women’s 400 m performance would have been. You might feel that the model is being over confident in this region. Perhaps we are forcing too much sharing of information between the sprints. We could return to the intrinsic coregionalization model and force the two base covariance functions to share the same coregionalization matrix. Figure: Gaussian process fit to the Olympic Sprint data. This is a simple form of the linear model of coregionalization. Note how confident the model is about what the women’s 400 m performance would have been. You might feel that the model is being over confident in this region. Perhaps we are forcing too much sharing of information between the sprints. We could return to the intrinsic coregionalization model and force the two base covariance functions to share the same coregionalization matrix. Figure: Gaussian process fit to the Olympic Sprint data. Predictions in the multioutput case can be very effected by our covariance function design. This reflects the themes we saw on the first day where the importance of covariance function choice was emphasized at design time. For more information on these subjects and more you might want to check the following resources. Figure: Gaussian process fit to the Olympic Sprint data. Predictions in the multioutput case can be very effected by our covariance function design. This reflects the themes we saw on the first day where the importance of covariance function choice was emphasized at design time. For more information on these subjects and more you might want to check the following resources. We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling. Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. Figure: In recent years, approximations for Gaussian process models haven’t been the most fashionable approach to machine learning. Image credit: Kai Arulkumaran Inference in a Gaussian process has computational complexity of \(\mathscr{O}(n^3)\) and storage demands of \(\mathscr{O}(n^2)\). This is too large for many modern data sets. Low rank approximations allow us to work with Gaussian processes with computational complexity of \(\mathscr{O}(nm^2)\) and storage demands of \(\mathscr{O}(nm)\), where \(m\) is a user chosen parameter. In machine learning, low rank approximations date back to Smola and Bartlett (n.d.), Williams and Seeger (n.d.), who considered the Nyström approximation and Csató and Opper (2002);Csató (2002) who considered low rank approximations in the context of on-line learning. Selection of active points for the approximation was considered by Seeger et al. (n.d.) and Snelson and Ghahramani (n.d.) first proposed that the active set could be optimized directly. Those approaches were reviewed by Quiñonero Candela and Rasmussen (2005) under a unifying likelihood approximation perspective. General rules for deriving the maximum likelihood for these sparse approximations were given in Lawrence (n.d.). Modern variational interpretations of these low rank approaches were first explored in Titsias (n.d.). A more modern summary which considers each of these approximations as an \(\alpha\)-divergence is given by Bui et al. (2017). Inducing variables are a compression of the real observations. The basic idea is can I create a new data set that summarizes all the information in the original data set. If this data set is smaller, I’ve compressed the information in the original data set. Inducing variables can be thought of as pseudo-data, indeed in Snelson and Ghahramani (n.d.) they were referred to as pseudo-points. The only requirement for inducing variables is that they are jointly distributed as a Gaussian process with the original data. This means that they can be from the space \(\mathbf{ f}\) or a space that is related through a linear operator (see e.g. Álvarez et al. (2010)). For example we could choose to store the gradient of the function at particular points or a value from the frequency spectrum of the function (Lázaro-Gredilla et al., 2010). Inducing variables don’t only allow for the compression of the non-parameteric information into a reduced data aset but they also allow for computational scaling of the algorithms through, for example stochastic variational approaches Hensman et al. (n.d.) or parallelization Gal et al. (n.d.),Dai et al. (2014), Seeger et al. (2017). We’ve seen how we go from parametric to non-parametric. The limit implies infinite dimensional \(\mathbf{ w}\). Gaussian processes are generally non-parametric: combine data with covariance function to get model. This representation cannot be summarized by a parameter vector of a fixed size. Parametric models have a representation that does not respond to increasing training set size. Bayesian posterior distributions over parameters contain the information about the training data, for example if we use use Bayes’ rule from training data, \[
+sns.set_palette('colorblind')}--> Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. Figure: In recent years, approximations for Gaussian process models haven’t been the most fashionable approach to machine learning. Image credit: Kai Arulkumaran Inference in a Gaussian process has computational complexity of \(\mathscr{O}(n^3)\) and storage demands of \(\mathscr{O}(n^2)\). This is too large for many modern data sets. Low rank approximations allow us to work with Gaussian processes with computational complexity of \(\mathscr{O}(nm^2)\) and storage demands of \(\mathscr{O}(nm)\), where \(m\) is a user chosen parameter. In machine learning, low rank approximations date back to Smola and Bartlett (n.d.), Williams and Seeger (n.d.), who considered the Nyström approximation and Csató and Opper (2002);Csató (2002) who considered low rank approximations in the context of on-line learning. Selection of active points for the approximation was considered by Seeger et al. (n.d.) and Snelson and Ghahramani (n.d.) first proposed that the active set could be optimized directly. Those approaches were reviewed by Quiñonero Candela and Rasmussen (2005) under a unifying likelihood approximation perspective. General rules for deriving the maximum likelihood for these sparse approximations were given in Lawrence (n.d.). Modern variational interpretations of these low rank approaches were first explored in Titsias (n.d.). A more modern summary which considers each of these approximations as an \(\alpha\)-divergence is given by Bui et al. (2017). Inducing variables are a compression of the real observations. The basic idea is can I create a new data set that summarizes all the information in the original data set. If this data set is smaller, I’ve compressed the information in the original data set. Inducing variables can be thought of as pseudo-data, indeed in Snelson and Ghahramani (n.d.) they were referred to as pseudo-points. The only requirement for inducing variables is that they are jointly distributed as a Gaussian process with the original data. This means that they can be from the space \(\mathbf{ f}\) or a space that is related through a linear operator (see e.g. Álvarez et al. (2010)). For example we could choose to store the gradient of the function at particular points or a value from the frequency spectrum of the function (Lázaro-Gredilla et al., 2010). Inducing variables don’t only allow for the compression of the non-parameteric information into a reduced data aset but they also allow for computational scaling of the algorithms through, for example stochastic variational approaches Hensman et al. (n.d.) or parallelization Gal et al. (n.d.),Dai et al. (2014), Seeger et al. (2017). We’ve seen how we go from parametric to non-parametric. The limit implies infinite dimensional \(\mathbf{ w}\). Gaussian processes are generally non-parametric: combine data with covariance function to get model. This representation cannot be summarized by a parameter vector of a fixed size. Parametric models have a representation that does not respond to increasing training set size. Bayesian posterior distributions over parameters contain the information about the training data, for example if we use use Bayes’ rule from training data, \[
p\left(\mathbf{ w}|\mathbf{ y}, \mathbf{X}\right),
\] to make predictions on test data \[
p\left(y_*|\mathbf{X}_*, \mathbf{ y}, \mathbf{X}\right) = \int
@@ -32,21 +31,21 @@
k\left(\mathbf{ x}_i,\mathbf{ x}_j\right)=\phi_:\left(\mathbf{ x}_i\right)^\top\phi_:\left(\mathbf{ x}_j\right).
\] These are known as degenerate covariance matrices. Their rank is at most \(m\), non-parametric models have full rank covariance matrices. Most well known is the “linear kernel,” \[
k(\mathbf{ x}_i, \mathbf{ x}_j) = \mathbf{ x}_i^\top\mathbf{ x}_j.
-\] For non-parametrics prediction at a new point, \(\mathbf{ f}_*\), is made by conditioning on \(\mathbf{ f}\) in the joint distribution. In GPs this involves combining the training data with the covariance function and the mean function. Parametric is a special case when conditional prediction can be summarized in a fixed number of parameters. Complexity of parametric model remains fixed regardless of the size of our training data set. For a non-parametric model the required number of parameters grows with the size of the training data. The Nystr"om approximation takes the form, \[
+\] For non-parametrics prediction at a new point, \(\mathbf{ f}_*\), is made by conditioning on \(\mathbf{ f}\) in the joint distribution. In GPs this involves combining the training data with the covariance function and the mean function. Parametric is a special case when conditional prediction can be summarized in a fixed number of parameters. Complexity of parametric model remains fixed regardless of the size of our training data set. For a non-parametric model the required number of parameters grows with the size of the training data. The Nystr"om approximation takes the form, \[
\mathbf{K}_{\mathbf{ f}\mathbf{ f}}\approx \mathbf{Q}_{\mathbf{ f}\mathbf{ f}}= \mathbf{K}_{\mathbf{ f}\mathbf{ u}}\mathbf{K}_{\mathbf{ u}\mathbf{ u}}^{-1}\mathbf{K}_{\mathbf{ u}\mathbf{ f}}
-\] The idea is that instead of inverting \(\mathbf{K}_{\mathbf{ f}\mathbf{ f}}\), we make a low rank (or Nyström) approximation, and invert \(\mathbf{K}_{\mathbf{ u}\mathbf{ u}}\) instead. In the original Nystr"om method the columns to incorporate are sampled from the complete set of columns (without replacement). In a kernel matrix each of these columns corresponds to a data point. In the Nystr"om method these points are sometimes called landmark points. In the original Nystr"om method the columns to incorporate are sampled from the complete set of columns (without replacement). In a kernel matrix each of these columns corresponds to a data point. In the Nystr"om method these points are sometimes called landmark points. Take an extra \(m\) points on the function, \(\mathbf{ u}= f(\mathbf{Z})\). \[p(\mathbf{ y},\mathbf{ f},\mathbf{ u}) = p(\mathbf{ y}|\mathbf{ f}) p(\mathbf{ f}|\mathbf{ u}) p(\mathbf{ u})\] Take and extra \(M\) points on the function, \(\mathbf{ u}= f(\mathbf{Z})\). \[p(\mathbf{ y},\mathbf{ f},\mathbf{ u}) = p(\mathbf{ y}|\mathbf{ f}) p(\mathbf{ f}|\mathbf{ u}) p(\mathbf{ u})\] \[\begin{aligned}
+\] Take an extra \(m\) points on the function, \(\mathbf{ u}= f(\mathbf{Z})\). \[p(\mathbf{ y},\mathbf{ f},\mathbf{ u}) = p(\mathbf{ y}|\mathbf{ f}) p(\mathbf{ f}|\mathbf{ u}) p(\mathbf{ u})\] Take and extra \(M\) points on the function, \(\mathbf{ u}= f(\mathbf{Z})\). \[p(\mathbf{ y},\mathbf{ f},\mathbf{ u}) = p(\mathbf{ y}|\mathbf{ f}) p(\mathbf{ f}|\mathbf{ u}) p(\mathbf{ u})\] \[\begin{aligned}
p(\mathbf{ y}|\mathbf{ f}) &= \mathscr{N}\left(\mathbf{ y}|\mathbf{ f},\sigma^2 \mathbf{I}\right)\\
p(\mathbf{ f}|\mathbf{ u}) &= \mathscr{N}\left(\mathbf{ f}| \mathbf{K}_{\mathbf{ f}\mathbf{ u}}\mathbf{K}_{\mathbf{ u}\mathbf{ u}}^{-1}\mathbf{ u}, \tilde{\mathbf{K}}\right)\\
p(\mathbf{ u}) &= \mathscr{N}\left(\mathbf{ u}| \mathbf{0},\mathbf{K}_{\mathbf{ u}\mathbf{ u}}\right)
- \end{aligned}\] \[\mathbf{X},\,\mathbf{ y}\] \[f(\mathbf{ x}) \sim {\mathcal GP}\] \[p(\mathbf{ f}) = \mathscr{N}\left(\mathbf{0},\mathbf{K}_{\mathbf{ f}\mathbf{ f}}\right)\] \[p(\mathbf{ f}|\mathbf{ y},\mathbf{X})\] \[
+ \end{aligned}\] \[\mathbf{X},\,\mathbf{ y}\] \[f(\mathbf{ x}) \sim {\mathcal GP}\] \[p(\mathbf{ f}) = \mathscr{N}\left(\mathbf{0},\mathbf{K}_{\mathbf{ f}\mathbf{ f}}\right)\] \[p(\mathbf{ f}|\mathbf{ y},\mathbf{X})\] \[
\begin{align}
&\qquad\mathbf{Z}, \mathbf{ u}\\ &p({\color{red} \mathbf{ u}}) = \mathscr{N}\left(\mathbf{0},\mathbf{K}_{\mathbf{ u}\mathbf{ u}}\right)\end{align}
-\] { \[\mathbf{X},\,\mathbf{ y}\] \[f(\mathbf{ x}) \sim {\mathcal GP}\] \[p(\mathbf{ f}) = \mathscr{N}\left(\mathbf{0},\mathbf{K}_{\mathbf{ f}\mathbf{ f}}\right)\] \[p(\mathbf{ f}|\mathbf{ y},\mathbf{X})\] \[p(\mathbf{ u}) = \mathscr{N}\left(\mathbf{0},\mathbf{K}_{\mathbf{ u}\mathbf{ u}}\right)\] \[\widetilde p({\color{red}\mathbf{ u}}|\mathbf{ y},\mathbf{X})\] }{ Instead of doing \[
+\] { \[\mathbf{X},\,\mathbf{ y}\] \[f(\mathbf{ x}) \sim {\mathcal GP}\] \[p(\mathbf{ f}) = \mathscr{N}\left(\mathbf{0},\mathbf{K}_{\mathbf{ f}\mathbf{ f}}\right)\] \[p(\mathbf{ f}|\mathbf{ y},\mathbf{X})\] \[p(\mathbf{ u}) = \mathscr{N}\left(\mathbf{0},\mathbf{K}_{\mathbf{ u}\mathbf{ u}}\right)\] \[\widetilde p({\color{red}\mathbf{ u}}|\mathbf{ y},\mathbf{X})\] }{ Instead of doing \[
p(\mathbf{ f}|\mathbf{ y},\mathbf{X}) = \frac{p(\mathbf{ y}|\mathbf{ f})p(\mathbf{ f}|\mathbf{X})}{\int p(\mathbf{ y}|\mathbf{ f})p(\mathbf{ f}|\mathbf{X}){\text{d}\mathbf{ f}}}
\] We’ll do \[
p(\mathbf{ u}|\mathbf{ y},\mathbf{Z}) = \frac{p(\mathbf{ y}|\mathbf{ u})p(\mathbf{ u}|\mathbf{Z})}{\int p(\mathbf{ y}|\mathbf{ u})p(\mathbf{ u}|\mathbf{Z}){\text{d}\mathbf{ u}}}
@@ -127,7 +126,7 @@
\end{bmatrix}
\] Choosing the inducing variables amounts to specifying \(\mathbf{K}_{\mathbf{ f}\mathbf{ u}}\) and \(\mathbf{K}_{\mathbf{ u}\mathbf{ u}}\) such that \(\mathbf{K}\) remains positive definite. The typical choice is to choose \(\mathbf{ u}\) in the same domain as \(\mathbf{ f}\), associating each inducing output, \(u_i\) with a corresponding input location \(\mathbf{ z}\). However, more imaginative choices are absolutely possible. In particular, if \(\mathbf{ u}\) is related to \(\mathbf{ f}\) through a linear operator (see e.g. Álvarez et al. (2010)), then valid \(\mathbf{K}_{\mathbf{ u}\mathbf{ u}}\) and \(\mathbf{K}_{\mathbf{ u}\mathbf{ f}}\) can be constructed. For example we could choose to store the gradient of the function at particular points or a value from the frequency spectrum of the function (Lázaro-Gredilla et al., 2010). Inducing variables don’t only allow for the compression of the non-parameteric information into a reduced data set but they also allow for computational scaling of the algorithms through, for example stochastic variational approaches(Hensman et al., n.d.; Hoffman et al., 2012) or parallelization (Dai et al., 2014; Gal et al., n.d.; Seeger et al., 2017). If the likelihood, \(p(\mathbf{ y}|\mathbf{ f})\), factorizes <8-> Then the bound factorizes. <10-> Now need a choice of distributions for \(\mathbf{ f}\) and \(\mathbf{ y}|\mathbf{ f}\) … Choose to go a different way. Introduce a set of auxiliary variables, \(\mathbf{ u}\), which are \(m\) in length. They are like “artificial data.” Used to induce a distribution: \(q(\mathbf{ u}|\mathbf{ y})\) Introduce variable set which is finite dimensional. \[
p(\mathbf{ y}^*|\mathbf{ y}) \approx \int p(\mathbf{ y}^*|\mathbf{ u}) q(\mathbf{ u}|\mathbf{ y}) \text{d}\mathbf{ u}
-\] But dimensionality of \(\mathbf{ u}\) can be changed to improve approximation. Model for our data, \(\mathbf{ y}\) \[p(\mathbf{ y})\] Prior density over \(\mathbf{ f}\). Likelihood relates data, \(\mathbf{ y}\), to \(\mathbf{ f}\). \[p(\mathbf{ y})=\int p(\mathbf{ y}|\mathbf{ f})p(\mathbf{ f})\text{d}\mathbf{ f}\] Prior density over \(\mathbf{ f}\). Likelihood relates data, \(\mathbf{ y}\), to \(\mathbf{ f}\). \[p(\mathbf{ y})=\int p(\mathbf{ y}|\mathbf{ f})p(\mathbf{ u}|\mathbf{ f})p(\mathbf{ f})\text{d}\mathbf{ f}\text{d}\mathbf{ u}\] \[p(\mathbf{ y})=\int \int p(\mathbf{ y}|\mathbf{ f})p(\mathbf{ f}|\mathbf{ u})\text{d}\mathbf{ f}p(\mathbf{ u})\text{d}\mathbf{ u}\] \[p(\mathbf{ y})=\int \int p(\mathbf{ y}|\mathbf{ f})p(\mathbf{ f}|\mathbf{ u})\text{d}\mathbf{ f}p(\mathbf{ u})\text{d}\mathbf{ u}\] \[p(\mathbf{ y}|\mathbf{ u})=\int p(\mathbf{ y}|\mathbf{ f})p(\mathbf{ f}|\mathbf{ u})\text{d}\mathbf{ f}\] \[p(\mathbf{ y}|\mathbf{ u})\] \[p(\mathbf{ y}|\boldsymbol{ \theta})\] \[\mathbf{ f}, \mathbf{ u}\sim \mathscr{N}\left(\mathbf{0},\begin{bmatrix}\mathbf{K}_{\mathbf{ f}\mathbf{ f}}& \mathbf{K}_{\mathbf{ f}\mathbf{ u}}\\\mathbf{K}_{\mathbf{ u}\mathbf{ f}}& \mathbf{K}_{\mathbf{ u}\mathbf{ u}}\end{bmatrix}\right)\] \[\mathbf{ y}|\mathbf{ f}= \prod_{i} \mathscr{N}\left(f,\sigma^2\right)\] For Gaussian likelihoods: Define: \[q_{i, i} = \text{var}_{p(f_i|\mathbf{ u})}\left( f_i \right) = \left\langle f_i^2\right\rangle_{p(f_i|\mathbf{ u})} - \left\langle f_i\right\rangle_{p(f_i|\mathbf{ u})}^2\] We can write: \[c_i = \exp\left(-{\frac{q_{i,i}}{2\sigma^2}}\right)\] If joint distribution of \(p(\mathbf{ f}, \mathbf{ u})\) is Gaussian then: \[q_{i, i} = k_{i, i} - \mathbf{ k}_{i, \mathbf{ u}}^\top \mathbf{K}_{\mathbf{ u}, \mathbf{ u}}^{-1} \mathbf{ k}_{i, \mathbf{ u}}\] \(c_i\) is not a function of \(\mathbf{ u}\) but is a function of \(\mathbf{X}_\mathbf{ u}\). The sum of \(q_{i,i}\) is the total conditional variance. If conditional density \(p(\mathbf{ f}|\mathbf{ u})\) is Gaussian then it has covariance \[\mathbf{Q} = \mathbf{K}_{\mathbf{ f}\mathbf{ f}} - \mathbf{K}_{\mathbf{ f}\mathbf{ u}}\mathbf{K}_{\mathbf{ u}\mathbf{ u}}^{-1} \mathbf{K}_{\mathbf{ u}\mathbf{ f}}\] \(\text{tr}\left(\mathbf{Q}\right) = \sum_{i}q_{i,i}\) is known as total variance. Because it is on conditional distribution we call it total conditional variance. Measure the ’capacity of a density’. Determinant of covariance represents ’volume’ of density. log determinant is entropy: sum of log eigenvalues of covariance. trace of covariance is total variance: sum of eigenvalues of covariance. \(\lambda > \log \lambda\) then total conditional variance upper bounds entropy. Exponentiated total variance bounds determinant. \[\det{\mathbf{Q}} < \exp \text{tr}\left(\mathbf{Q}\right)\] Because \[\prod_{i=1}^k \lambda_i < \prod_{i=1}^k \exp(\lambda_i)\] where \(\{\lambda_i\}_{i=1}^k\) are the positive eigenvalues of \(\mathbf{Q}\) This in turn implies \[\det{\mathbf{Q}} < \prod_{i=1}^k \exp\left(q_{i,i}\right)\] Conditional density \(p(\mathbf{ f}|\mathbf{ u})\) can be seen as a communication channel. Normally we have: \[\text{Transmitter} \stackrel{\mathbf{ u}}{\rightarrow} \begin{smallmatrix}p(\mathbf{ f}|\mathbf{ u}) \\ \text{Channel}\end{smallmatrix} \stackrel{\mathbf{ f}}{\rightarrow} \text{Receiver}\] and we control \(p(\mathbf{ u})\) (the source density). Here we can also control the transmission channel \(p(\mathbf{ f}|\mathbf{ u})\). Substitute variational bound into marginal likelihood: \[p(\mathbf{ y})\geq \prod_{i=1}^nc_i \int \mathscr{N}\left(\mathbf{ y}|\left\langle\mathbf{ f}\right\rangle,\sigma^2\mathbf{I}\right)p(\mathbf{ u}) \text{d}\mathbf{ u}\] Note that: \[\left\langle\mathbf{ f}\right\rangle_{p(\mathbf{ f}|\mathbf{ u})} = \mathbf{K}_{\mathbf{ f}, \mathbf{ u}} \mathbf{K}_{\mathbf{ u}, \mathbf{ u}}^{-1}\mathbf{ u}\] is linearly dependent on \(\mathbf{ u}\). Making the marginalization of \(\mathbf{ u}\) straightforward. In the Gaussian case: \[p(\mathbf{ u}) = \mathscr{N}\left(\mathbf{ u}|\mathbf{0},\mathbf{K}_{\mathbf{ u},\mathbf{ u}}\right)\] \[\log p(\mathbf{ y}|\mathbf{ u}) = \log\int p(\mathbf{ y}|\mathbf{ f})p(\mathbf{ f}|\mathbf{ u},\mathbf{X})\text{d}\mathbf{ f}\] \[\log p(\mathbf{ y}|\mathbf{ u}) = \log \mathbb{E}_{p(\mathbf{ f}|\mathbf{ u},\mathbf{X})}\left[p(\mathbf{ y}|\mathbf{ f})\right]\] \[\log p(\mathbf{ y}|\mathbf{ u}) \geq \mathbb{E}_{p(\mathbf{ f}|\mathbf{ u},\mathbf{X})}\left[\log p(\mathbf{ y}|\mathbf{ f})\right]\triangleq \log\widetilde p(\mathbf{ y}|\mathbf{ u})\] No inversion of \(\mathbf{K}_{\mathbf{ f}\mathbf{ f}}\) required \[p(\mathbf{ y}|\mathbf{ u}) = \frac{p(\mathbf{ y}|\mathbf{ f})p(\mathbf{ f}|\mathbf{ u})}{p(\mathbf{ f}|\mathbf{ y}, \mathbf{ u})}\] \[\log p(\mathbf{ y}|\mathbf{ u}) = \log p(\mathbf{ y}|\mathbf{ f}) + \log \frac{p(\mathbf{ f}|\mathbf{ u})}{p(\mathbf{ f}|\mathbf{ y}, \mathbf{ u})}\] \[\log p(\mathbf{ y}|\mathbf{ u}) = \bbE_{p(\mathbf{ f}|\mathbf{ u})}\big[\log p(\mathbf{ y}|\mathbf{ f})\big] + \bbE_{p(\mathbf{ f}|\mathbf{ u})}\big[\log \frac{p(\mathbf{ f}|\mathbf{ u})}{p(\mathbf{ f}|\mathbf{ y}, \mathbf{ u})}\big]\] \[\log p(\mathbf{ y}|\mathbf{ u}) = \widetilde p(\mathbf{ y}|\mathbf{ u}) + \textsc{KL}[p(\mathbf{ f}|\mathbf{ u})||p(\mathbf{ f}|\mathbf{ y}, \mathbf{ u})]\] No inversion of \(\mathbf{K}_{\mathbf{ f}\mathbf{ f}}\) required \[\widetilde p(\mathbf{ y}|\mathbf{ u}) = \prod_{i=1}^n\widetilde p(y_i|\mathbf{ u})\] \[\widetilde p(y|\mathbf{ u}) = \mathscr{N}\left(y|\mathbf{ k}_{fu}\mathbf{K}_{\mathbf{ u}\mathbf{ u}}^{-1}\mathbf{ u},\sigma^2\right) \,{\color{red}\exp\left\{-\tfrac{1}{2\sigma^2}\left(k_{ff}- \mathbf{ k}_{fu}\mathbf{K}_{\mathbf{ u}\mathbf{ u}}^{-1}\mathbf{ k}_{uf}\right)\right\}}\] A straightforward likelihood approximation, and a penalty term \[\widetilde p(\mathbf{ u}|\mathbf{ y},\mathbf{Z}) = \frac{\widetilde p(\mathbf{ y}|\mathbf{ u})p(\mathbf{ u}|\mathbf{Z})}{\int \widetilde p(\mathbf{ y}|\mathbf{ u})p(\mathbf{ u}|\mathbf{Z})\text{d}{\mathbf{ u}}}\] Computing the posterior costs \(\mathscr{O}(nm^2)\) We also get a lower bound of the marginal likelihood \[{\color{red}\sum_{i=1}^n-\tfrac{1}{2\sigma^2}\left(k_{ff}- \mathbf{ k}_{fu}\mathbf{K}_{\mathbf{ u}\mathbf{ u}}^{-1}\mathbf{ k}_{uf}\right)}\] \[{\color{red}\sum_{i=1}^n-\tfrac{1}{2\sigma^2}\left(k_{ff}- \mathbf{ k}_{fu}\mathbf{K}_{\mathbf{ u}\mathbf{ u}}^{-1}\mathbf{ k}_{uf}\right)}\] It’s easy to show that as \(\mathbf{Z}\to \mathbf{X}\): \(\mathbf{ u}\to \mathbf{ f}\) (and the posterior is exact) The penalty term is zero. The cost returns to \(\mathscr{O}(n^3)\) But dimensionality of \(\mathbf{ u}\) can be changed to improve approximation. Model for our data, \(\mathbf{ y}\) \[p(\mathbf{ y})\] Prior density over \(\mathbf{ f}\). Likelihood relates data, \(\mathbf{ y}\), to \(\mathbf{ f}\). \[p(\mathbf{ y})=\int p(\mathbf{ y}|\mathbf{ f})p(\mathbf{ f})\text{d}\mathbf{ f}\] Prior density over \(\mathbf{ f}\). Likelihood relates data, \(\mathbf{ y}\), to \(\mathbf{ f}\). \[p(\mathbf{ y})=\int p(\mathbf{ y}|\mathbf{ f})p(\mathbf{ u}|\mathbf{ f})p(\mathbf{ f})\text{d}\mathbf{ f}\text{d}\mathbf{ u}\] \[p(\mathbf{ y})=\int \int p(\mathbf{ y}|\mathbf{ f})p(\mathbf{ f}|\mathbf{ u})\text{d}\mathbf{ f}p(\mathbf{ u})\text{d}\mathbf{ u}\] \[p(\mathbf{ y})=\int \int p(\mathbf{ y}|\mathbf{ f})p(\mathbf{ f}|\mathbf{ u})\text{d}\mathbf{ f}p(\mathbf{ u})\text{d}\mathbf{ u}\] \[p(\mathbf{ y}|\mathbf{ u})=\int p(\mathbf{ y}|\mathbf{ f})p(\mathbf{ f}|\mathbf{ u})\text{d}\mathbf{ f}\] \[p(\mathbf{ y}|\mathbf{ u})\] \[p(\mathbf{ y}|\boldsymbol{ \theta})\] \[\mathbf{ f}, \mathbf{ u}\sim \mathscr{N}\left(\mathbf{0},\begin{bmatrix}\mathbf{K}_{\mathbf{ f}\mathbf{ f}}& \mathbf{K}_{\mathbf{ f}\mathbf{ u}}\\\mathbf{K}_{\mathbf{ u}\mathbf{ f}}& \mathbf{K}_{\mathbf{ u}\mathbf{ u}}\end{bmatrix}\right)\] \[\mathbf{ y}|\mathbf{ f}= \prod_{i} \mathscr{N}\left(f,\sigma^2\right)\] For Gaussian likelihoods: Define: \[q_{i, i} = \text{var}_{p(f_i|\mathbf{ u})}\left( f_i \right) = \left\langle f_i^2\right\rangle_{p(f_i|\mathbf{ u})} - \left\langle f_i\right\rangle_{p(f_i|\mathbf{ u})}^2\] We can write: \[c_i = \exp\left(-{\frac{q_{i,i}}{2\sigma^2}}\right)\] If joint distribution of \(p(\mathbf{ f}, \mathbf{ u})\) is Gaussian then: \[q_{i, i} = k_{i, i} - \mathbf{ k}_{i, \mathbf{ u}}^\top \mathbf{K}_{\mathbf{ u}, \mathbf{ u}}^{-1} \mathbf{ k}_{i, \mathbf{ u}}\] \(c_i\) is not a function of \(\mathbf{ u}\) but is a function of \(\mathbf{X}_\mathbf{ u}\). The sum of \(q_{i,i}\) is the total conditional variance. If conditional density \(p(\mathbf{ f}|\mathbf{ u})\) is Gaussian then it has covariance \[\mathbf{Q} = \mathbf{K}_{\mathbf{ f}\mathbf{ f}} - \mathbf{K}_{\mathbf{ f}\mathbf{ u}}\mathbf{K}_{\mathbf{ u}\mathbf{ u}}^{-1} \mathbf{K}_{\mathbf{ u}\mathbf{ f}}\] \(\text{tr}\left(\mathbf{Q}\right) = \sum_{i}q_{i,i}\) is known as total variance. Because it is on conditional distribution we call it total conditional variance. Measure the ’capacity of a density’. Determinant of covariance represents ’volume’ of density. log determinant is entropy: sum of log eigenvalues of covariance. trace of covariance is total variance: sum of eigenvalues of covariance. \(\lambda > \log \lambda\) then total conditional variance upper bounds entropy. Exponentiated total variance bounds determinant. \[\det{\mathbf{Q}} < \exp \text{tr}\left(\mathbf{Q}\right)\] Because \[\prod_{i=1}^k \lambda_i < \prod_{i=1}^k \exp(\lambda_i)\] where \(\{\lambda_i\}_{i=1}^k\) are the positive eigenvalues of \(\mathbf{Q}\) This in turn implies \[\det{\mathbf{Q}} < \prod_{i=1}^k \exp\left(q_{i,i}\right)\] Conditional density \(p(\mathbf{ f}|\mathbf{ u})\) can be seen as a communication channel. Normally we have: \[\text{Transmitter} \stackrel{\mathbf{ u}}{\rightarrow} \begin{smallmatrix}p(\mathbf{ f}|\mathbf{ u}) \\ \text{Channel}\end{smallmatrix} \stackrel{\mathbf{ f}}{\rightarrow} \text{Receiver}\] and we control \(p(\mathbf{ u})\) (the source density). Here we can also control the transmission channel \(p(\mathbf{ f}|\mathbf{ u})\). Substitute variational bound into marginal likelihood: \[p(\mathbf{ y})\geq \prod_{i=1}^nc_i \int \mathscr{N}\left(\mathbf{ y}|\left\langle\mathbf{ f}\right\rangle,\sigma^2\mathbf{I}\right)p(\mathbf{ u}) \text{d}\mathbf{ u}\] Note that: \[\left\langle\mathbf{ f}\right\rangle_{p(\mathbf{ f}|\mathbf{ u})} = \mathbf{K}_{\mathbf{ f}, \mathbf{ u}} \mathbf{K}_{\mathbf{ u}, \mathbf{ u}}^{-1}\mathbf{ u}\] is linearly dependent on \(\mathbf{ u}\). Making the marginalization of \(\mathbf{ u}\) straightforward. In the Gaussian case: \[p(\mathbf{ u}) = \mathscr{N}\left(\mathbf{ u}|\mathbf{0},\mathbf{K}_{\mathbf{ u},\mathbf{ u}}\right)\] \[\log p(\mathbf{ y}|\mathbf{ u}) = \log\int p(\mathbf{ y}|\mathbf{ f})p(\mathbf{ f}|\mathbf{ u},\mathbf{X})\text{d}\mathbf{ f}\] \[\log p(\mathbf{ y}|\mathbf{ u}) = \log \mathbb{E}_{p(\mathbf{ f}|\mathbf{ u},\mathbf{X})}\left[p(\mathbf{ y}|\mathbf{ f})\right]\] \[\log p(\mathbf{ y}|\mathbf{ u}) \geq \mathbb{E}_{p(\mathbf{ f}|\mathbf{ u},\mathbf{X})}\left[\log p(\mathbf{ y}|\mathbf{ f})\right]\triangleq \log\widetilde p(\mathbf{ y}|\mathbf{ u})\] No inversion of \(\mathbf{K}_{\mathbf{ f}\mathbf{ f}}\) required \[p(\mathbf{ y}|\mathbf{ u}) = \frac{p(\mathbf{ y}|\mathbf{ f})p(\mathbf{ f}|\mathbf{ u})}{p(\mathbf{ f}|\mathbf{ y}, \mathbf{ u})}\] \[\log p(\mathbf{ y}|\mathbf{ u}) = \log p(\mathbf{ y}|\mathbf{ f}) + \log \frac{p(\mathbf{ f}|\mathbf{ u})}{p(\mathbf{ f}|\mathbf{ y}, \mathbf{ u})}\] \[\log p(\mathbf{ y}|\mathbf{ u}) = \bbE_{p(\mathbf{ f}|\mathbf{ u})}\big[\log p(\mathbf{ y}|\mathbf{ f})\big] + \bbE_{p(\mathbf{ f}|\mathbf{ u})}\big[\log \frac{p(\mathbf{ f}|\mathbf{ u})}{p(\mathbf{ f}|\mathbf{ y}, \mathbf{ u})}\big]\] \[\log p(\mathbf{ y}|\mathbf{ u}) = \widetilde p(\mathbf{ y}|\mathbf{ u}) + \textsc{KL}[p(\mathbf{ f}|\mathbf{ u})||p(\mathbf{ f}|\mathbf{ y}, \mathbf{ u})]\] No inversion of \(\mathbf{K}_{\mathbf{ f}\mathbf{ f}}\) required \[\widetilde p(\mathbf{ y}|\mathbf{ u}) = \prod_{i=1}^n\widetilde p(y_i|\mathbf{ u})\] \[\widetilde p(y|\mathbf{ u}) = \mathscr{N}\left(y|\mathbf{ k}_{fu}\mathbf{K}_{\mathbf{ u}\mathbf{ u}}^{-1}\mathbf{ u},\sigma^2\right) \,{\color{red}\exp\left\{-\tfrac{1}{2\sigma^2}\left(k_{ff}- \mathbf{ k}_{fu}\mathbf{K}_{\mathbf{ u}\mathbf{ u}}^{-1}\mathbf{ k}_{uf}\right)\right\}}\] A straightforward likelihood approximation, and a penalty term \[\widetilde p(\mathbf{ u}|\mathbf{ y},\mathbf{Z}) = \frac{\widetilde p(\mathbf{ y}|\mathbf{ u})p(\mathbf{ u}|\mathbf{Z})}{\int \widetilde p(\mathbf{ y}|\mathbf{ u})p(\mathbf{ u}|\mathbf{Z})\text{d}{\mathbf{ u}}}\] Computing the posterior costs \(\mathscr{O}(nm^2)\) We also get a lower bound of the marginal likelihood \[{\color{red}\sum_{i=1}^n-\tfrac{1}{2\sigma^2}\left(k_{ff}- \mathbf{ k}_{fu}\mathbf{K}_{\mathbf{ u}\mathbf{ u}}^{-1}\mathbf{ k}_{uf}\right)}\] \[{\color{red}\sum_{i=1}^n-\tfrac{1}{2\sigma^2}\left(k_{ff}- \mathbf{ k}_{fu}\mathbf{K}_{\mathbf{ u}\mathbf{ u}}^{-1}\mathbf{ k}_{uf}\right)}\] It’s easy to show that as \(\mathbf{Z}\to \mathbf{X}\): \(\mathbf{ u}\to \mathbf{ f}\) (and the posterior is exact) The penalty term is zero. The cost returns to \(\mathscr{O}(n^3)\) So far we: introduced \(\mathbf{Z}, \mathbf{ u}\) approximated the intergral over \(\mathbf{ f}\) variationally captured the information in \(\widetilde p(\mathbf{ u}|\mathbf{ y})\) obtained a lower bound on the marginal likeihood saw the effect of the penalty term prediction for new points Omitted details: optimization of the covariance parameters using the bound optimization of Z (simultaneously) the form of \(\widetilde p(\mathbf{ u}|\mathbf{ y})\) historical approximations Random or systematic Set \(\mathbf{Z}\) to subset of \(\mathbf{X}\) Set \(\mathbf{ u}\) to subset of \(\mathbf{ f}\) Approximation to \(p(\mathbf{ y}|\mathbf{ u})\): $ p(_i) = p(_i_i) i$ $ p(_i) = 1 i$ {Deterministic Training Conditional (DTC)} Approximation to \(p(\mathbf{ y}|\mathbf{ u})\): As our variational formulation, but without penalty Optimization of \(\mathbf{Z}\) is difficult Approximation to \(p(\mathbf{ y}|\mathbf{ u})\): $ p() = _i p(_i) $ Optimization of \(\mathbf{Z}\) is still difficult, and there are some weird heteroscedatic effects Bayesian GP-LVM First we perform a full Gaussian process regression on the data. We create a GP model, Figure: Full Gaussian process fitted to the data set. Now we set up the inducing variables, \(\mathbf{u}\). Each inducing variable has its own associated input index, \(\mathbf{Z}\), which lives in the same space as \(\mathbf{X}\). Here we are using the true covariance function parameters to generate the fit. Figure: Full Gaussian process fitted to the data set. Now we set up the inducing variables, \(\mathbf{u}\). Each inducing variable has its own associated input index, \(\mathbf{Z}\), which lives in the same space as \(\mathbf{X}\). Here we are using the true covariance function parameters to generate the fit. Figure: Sparse Gaussian process fitted with six inducing variables, no optimization of parameters or inducing variables. Figure: Gaussian process fitted with inducing variables fixed and parameters optimized Figure: Sparse Gaussian process fitted with six inducing variables, no optimization of parameters or inducing variables. Figure: Gaussian process fitted with inducing variables fixed and parameters optimized Figure: Gaussian process fitted with location of inducing variables and parameters both optimized Now we will vary the number of inducing points used to form the approximation. Figure: Gaussian process fitted with location of inducing variables and parameters both optimized Now we will vary the number of inducing points used to form the approximation. Figure: Comparison of the full Gaussian process fit with a sparse Gaussian process using eight inducing varibles. Both inducing variables and parameters are optimized. And we can compare the probability of the result to the full model. For more information on these subjects and more you might want to check the following resources. Figure: Comparison of the full Gaussian process fit with a sparse Gaussian process using eight inducing varibles. Both inducing variables and parameters are optimized. And we can compare the probability of the result to the full model. For more information on these subjects and more you might want to check the following resources. We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling. We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling. Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. [Gaussian processes model functions. If our observation is a corrupted version of this function and the corruption process is also Gaussian, it is trivial to account for this. However, there are many circumstances where our observation may be non Gaussian. In these cases we need to turn to approximate inference techniques. As a simple illustration, we’ll use a dataset of binary observations of the language that is spoken in different regions of East-Timor. First we will load the data and a couple of libraries to visualize it.} Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. [Gaussian processes model functions. If our observation is a corrupted version of this function and the corruption process is also Gaussian, it is trivial to account for this. However, there are many circumstances where our observation may be non Gaussian. In these cases we need to turn to approximate inference techniques. As a simple illustration, we’ll use a dataset of binary observations of the language that is spoken in different regions of East-Timor. First we will load the data and a couple of libraries to visualize it.} Now we will create a map of East Timor and, using GPy, plot the data on top of it. A classification model can be defined in a similar way to the regression model, but now using Now we will create a map of East Timor and, using GPy, plot the data on top of it. A classification model can be defined in a similar way to the regression model, but now using The decision boundary should be quite poor! However we haven’t optimized the model. Try the following: The optimization is based on the likelihood approximation that was made after we constructed the model. However, because we’ve now changed the model parameters the quality of that approximation has now probably deteriorated. To improve the model we should iterate between updating the Expectation propagation approximation and optimizing the model parameters. Image from Wikimedia Commons The Olympic Marathon data is a standard dataset for regression modelling. The data consists of the pace of Olympic Gold Medal Marathon winners for the Olympics from 1896 to present. Let’s load in the data and plot. The decision boundary should be quite poor! However we haven’t optimized the model. Try the following: The optimization is based on the likelihood approximation that was made after we constructed the model. However, because we’ve now changed the model parameters the quality of that approximation has now probably deteriorated. To improve the model we should iterate between updating the Expectation propagation approximation and optimizing the model parameters. Image from Wikimedia Commons The Olympic Marathon data is a standard dataset for regression modelling. The data consists of the pace of Olympic Gold Medal Marathon winners for the Olympics from 1896 to present. Let’s load in the data and plot. Figure: Olympic marathon pace times since 1896. Things to notice about the data include the outlier in 1904, in that year the Olympics was in St Louis, USA. Organizational problems and challenges with dust kicked up by the cars following the race meant that participants got lost, and only very few participants completed. More recent years see more consistently quick marathons. Figure: Alan Turing, in 1946 he was only 11 minutes slower than the winner of the 1948 games. Would he have won a hypothetical games held in 1946? Source: Alan Turing Internet Scrapbook. If we had to summarise the objectives of machine learning in one word, a very good candidate for that word would be generalization. What is generalization? From a human perspective it might be summarised as the ability to take lessons learned in one domain and apply them to another domain. If we accept the definition given in the first session for machine learning, \[
+yhat = (y - offset)/scale Figure: Olympic marathon pace times since 1896. Things to notice about the data include the outlier in 1904, in that year the Olympics was in St Louis, USA. Organizational problems and challenges with dust kicked up by the cars following the race meant that participants got lost, and only very few participants completed. More recent years see more consistently quick marathons. Figure: Alan Turing, in 1946 he was only 11 minutes slower than the winner of the 1948 games. Would he have won a hypothetical games held in 1946? Source: Alan Turing Internet Scrapbook. If we had to summarise the objectives of machine learning in one word, a very good candidate for that word would be generalization. What is generalization? From a human perspective it might be summarised as the ability to take lessons learned in one domain and apply them to another domain. If we accept the definition given in the first session for machine learning, \[
\text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}
-\] then we see that without a model we can’t generalise: we only have data. Data is fine for answering very specific questions, like “Who won the Olympic Marathon in 2012?”, because we have that answer stored, however, we are not given the answer to many other questions. For example, Alan Turing was a formidable marathon runner, in 1946 he ran a time 2 hours 46 minutes (just under four minutes per kilometer, faster than I and most of the other Endcliffe Park Run runners can do 5 km). What is the probability he would have won an Olympics if one had been held in 1946? To answer this question we need to generalize, but before we formalize the concept of generalization let’s introduce some formal representation of what it means to generalize in machine learning. Our first objective will be to perform a Gaussian process fit to the data, we’ll do this using the GPy software. The first command sets up the model, then To answer this question we need to generalize, but before we formalize the concept of generalization let’s introduce some formal representation of what it means to generalize in machine learning. Our first objective will be to perform a Gaussian process fit to the data, we’ll do this using the GPy software. The first command sets up the model, then Now we plot the results using the helper function in Figure: Gaussian process fit to the Olympic Marathon data. The error bars are too large, perhaps due to the outlier from 1904. In the fit we see that the error bars (coming mainly from the noise variance) are quite large. This is likely due to the outlier point in 1904, ignoring that point we can see that a tighter fit is obtained. To see this make a version of the model, Now we plot the results using the helper function in Figure: Gaussian process fit to the Olympic Marathon data. The error bars are too large, perhaps due to the outlier from 1904. In the fit we see that the error bars (coming mainly from the noise variance) are quite large. This is likely due to the outlier point in 1904, ignoring that point we can see that a tighter fit is obtained. To see this make a version of the model, Figure: Gaussian process fit to the Olympic Marathon data. Here we’ve removed the outlier from 1904. We already considered the olympic marathon data. In 1904 we noted there was an outlier example. Today we’ll see if we can deal with that outlier by considering a non-Gaussian likelihood. Noise sampled from a Student-\(t\) density is heavier tailed than that sampled from a Gaussian. However, it cannot be trivially assimilated into the Gaussian process. Below we use the Laplace approximation to incorporate this noise model. Figure: Gaussian process fit to the Olympic Marathon data. Here we’ve removed the outlier from 1904. We already considered the olympic marathon data. In 1904 we noted there was an outlier example. Today we’ll see if we can deal with that outlier by considering a non-Gaussian likelihood. Noise sampled from a Student-\(t\) density is heavier tailed than that sampled from a Gaussian. However, it cannot be trivially assimilated into the Gaussian process. Below we use the Laplace approximation to incorporate this noise model. Figure: Fit to the Olympic marathon data using the Student-\(t\) likelihood and the Laplace approximation. In this section we’ll combine expectation propagation with the low rank approximation to build a simple image classification application. For this toy example we’ll classify whether or not the subject of the image is wearing glasses. Correspond to whether the subject of the image is wearing glasses. Set up the ipython environment and download the data: First let’s retrieve some data. We will use the ORL faces data set, our objective will be to classify whether or not the subject in an image is wearing glasess. Here’s a simple way to visualise the data. Each pixel in the image will become an input to the GP. Figure: Fit to the Olympic marathon data using the Student-\(t\) likelihood and the Laplace approximation. In this section we’ll combine expectation propagation with the low rank approximation to build a simple image classification application. For this toy example we’ll classify whether or not the subject of the image is wearing glasses. Correspond to whether the subject of the image is wearing glasses. Set up the ipython environment and download the data: First let’s retrieve some data. We will use the ORL faces data set, our objective will be to classify whether or not the subject in an image is wearing glasess. Here’s a simple way to visualise the data. Each pixel in the image will become an input to the GP. Figure: Image from the Oivetti glasses data sets. Next we choose some inducing inputs. Here we’ve chosen inducing inputs by applying k-means clustering to the training data. Think about whether this is a good scheme for choosing the inputs? Can you devise a better one? Figure: Image from the Oivetti glasses data sets. Next we choose some inducing inputs. Here we’ve chosen inducing inputs by applying k-means clustering to the training data. Think about whether this is a good scheme for choosing the inputs? Can you devise a better one? Finally, we’re ready to build the classifier object. Finally, we’re ready to build the classifier object. Figure: The gradients of the inducing variable. For more information on these subjects and more you might want to check the following resources. Figure: The gradients of the inducing variable. For more information on these subjects and more you might want to check the following resources. We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling. We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling. Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. This linear relationship between the observed data and the latent variables is at the heart of Hotelling’s original formulation of PCA. It explicitly models the idea that the observed high-dimensional data is generated from a lower-dimensional set of latent variables, with some added noise. This perspective aligns PCA more closely with factor analysis and highlights its nature as a latent variable model. Probabilistic PCA (PPCA) provides a probabilistic interpretation of PCA by explicitly modeling the generative process that creates the observed data. The model assumes that each high-dimensional data point \(\mathbf{ y}_{i,:}\) is generated from a lower-dimensional latent variable \(\mathbf{ z}_{i,:}\) through a linear transformation with added Gaussian noise: \[
+sns.set_palette('colorblind')}--> Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. This linear relationship between the observed data and the latent variables is at the heart of Hotelling’s original formulation of PCA. It explicitly models the idea that the observed high-dimensional data is generated from a lower-dimensional set of latent variables, with some added noise. This perspective aligns PCA more closely with factor analysis and highlights its nature as a latent variable model. Probabilistic PCA (PPCA) provides a probabilistic interpretation of PCA by explicitly modeling the generative process that creates the observed data. The model assumes that each high-dimensional data point \(\mathbf{ y}_{i,:}\) is generated from a lower-dimensional latent variable \(\mathbf{ z}_{i,:}\) through a linear transformation with added Gaussian noise: \[
\mathbf{ y}_{i,:} = \mathbf{W}\mathbf{ z}_{i,:} + \boldsymbol{ \epsilon}_{i,:}
\] where \(\boldsymbol{ \epsilon}_{i,:} \sim \mathscr{N}\left(\mathbf{0},\sigma^2\mathbf{I}\right)\) represents isotropic Gaussian noise. The model places a standard Gaussian prior over the latent variables: \[
p(\mathbf{ z}_{i,:}) = \mathscr{N}\left(\mathbf{ z}_{i,:}|\mathbf{0},\mathbf{I}\right)
@@ -78,25 +28,7 @@ Figure: Graphical model representing probabilistic PCA. In 1997 Tipping and Bishop (Tipping and Bishop, 1999b) and Roweis (Roweis, n.d.) independently revisited Hotelling’s model and considered the case where the noise variance was finite, but shared across all output dimensons. Their model can be thought of as a factor analysis where \[
+\] This probabilistic formulation, developed by Tipping and Bishop (Tipping and Bishop, 1999a), provides a principled framework that not only recovers classical PCA as a special case when \(\sigma^2 \to 0\), but also enables extensions like handling missing data and mixture models. Figure: Graphical model representing probabilistic PCA. In 1997 Tipping and Bishop (Tipping and Bishop, 1999b) and Roweis (Roweis, n.d.) independently revisited Hotelling’s model and considered the case where the noise variance was finite, but shared across all output dimensons. Their model can be thought of as a factor analysis where \[
\boldsymbol{\Sigma} = \sigma^2 \mathbf{I}.
\] This leads to a marginal likelihood of the form \[
p(\mathbf{Y}|\mathbf{W}, \sigma^2)
@@ -107,23 +39,7 @@ Probabilistic PCA can be viewed as a simple manifold learning algorithm. It assumes that: This view helps explain why PPCA works well when the manifold hypothesis holds and the manifold is approximately linear. When the manifold is nonlinear, we need more sophisticated methods like kernel PCA or neural network-based approaches. We will now implement this algorithm in python. In practice we may not wish to compute the eigenvectors of the covariance matrix directly. This is because it requires us to estimate the covariance, which involves a sum of squares term, before estimating the eigenvectors. We can estimate the eigenvectors directly either through QR decomposition or singular value decomposition. We saw a similar issue arise when , where we also wished to avoid computation of \(\mathbf{Z}^\top\mathbf{Z}\) (or in the case of \(\boldsymbol{\Phi}^\top\boldsymbol{\Phi}\)). Under the latent variable model justification for principal component analysis, we are normally interested in inferring something about the latent variables given the data. This is the distribution, \[
+\] where \(\sigma^2\) is the noise variance. Note that if \(\sigma^2\) is larger than any particular eigenvalue, then that eigenvalue (along with its corresponding eigenvector) is discarded from the solution. Probabilistic PCA can be viewed as a simple manifold learning algorithm. It assumes that: This view helps explain why PPCA works well when the manifold hypothesis holds and the manifold is approximately linear. When the manifold is nonlinear, we need more sophisticated methods like kernel PCA or neural network-based approaches. We will now implement this algorithm in python. In practice we may not wish to compute the eigenvectors of the covariance matrix directly. This is because it requires us to estimate the covariance, which involves a sum of squares term, before estimating the eigenvectors. We can estimate the eigenvectors directly either through QR decomposition or singular value decomposition. We saw a similar issue arise when , where we also wished to avoid computation of \(\mathbf{Z}^\top\mathbf{Z}\) (or in the case of \(\boldsymbol{\Phi}^\top\boldsymbol{\Phi}\)). Under the latent variable model justification for principal component analysis, we are normally interested in inferring something about the latent variables given the data. This is the distribution, \[
p(\mathbf{ z}_{i, :} | \mathbf{ y}_{i, :})
\] for any given data point. Determining this density turns out to be very similar to the approach for determining the Bayesian posterior of \(\mathbf{ w}\) in Bayesian linear regression, only this time we place the prior density over \(\mathbf{ z}_{i, :}\) instead of \(\mathbf{ w}\). The posterior is proportional to the joint density as follows, \[
p(\mathbf{ z}_{i, :} | \mathbf{ y}_{i, :}) \propto p(\mathbf{ y}_{i,
@@ -136,30 +52,17 @@ Multiply out the terms in the brackets. Then collect the quadratic term and the linear terms together. Show that the posterior has the form \[
+\] Multiply out the terms in the brackets. Then collect the quadratic term and the linear terms together. Show that the posterior has the form \[
\mathbf{ z}_{i, :} | \mathbf{W}\sim \mathscr{N}\left(\boldsymbol{ \mu}_x,\mathbf{C}_x\right)
\] where \[
\mathbf{C}_x = \left(\sigma^{-2}
\mathbf{W}^\top\mathbf{W}+ \mathbf{I}\right)^{-1}
\] and \[
\boldsymbol{ \mu}_x
-= \mathbf{C}_x \sigma^{-2}\mathbf{W}^\top \mathbf{ y}_{i, :}
-\] Compare this to the posterior for the Bayesian linear regression from last week, do they have similar forms? What matches and what differs? Now let’s implement the system in code. Use the values for \(\mathbf{W}\) and \(\sigma^2\) you have computed, along with the data set \(\mathbf{Y}\) to compute the posterior density over \(\mathbf{Z}\). Write a function of the form where Don’t forget to subtract the mean of the data Just as we saw for and computation of a matrix such as \(\mathbf{Y}^\top\mathbf{Y}\) (or its centred version) can be a bad idea in terms of loss of numerical accuracy. Fortunately, we can find the eigenvalues and eigenvectors of the matrix \(\mathbf{Y}^\top\mathbf{Y}\) without direct computation of the matrix. This can be done with the singular value decomposition. The singular value decompsition takes a matrix, \(\mathbf{Z}\) and represents it in the form, \[
+= \mathbf{C}_x \sigma^{-2}\mathbf{W}^\top \mathbf{ y}_{i, :}
+\] Compare this to the posterior for the Bayesian linear regression from last week, do they have similar forms? What matches and what differs? Now let’s implement the system in code. Use the values for \(\mathbf{W}\) and \(\sigma^2\) you have computed, along with the data set \(\mathbf{Y}\) to compute the posterior density over \(\mathbf{Z}\). Write a function of the form where Don’t forget to subtract the mean of the data Just as we saw for and computation of a matrix such as \(\mathbf{Y}^\top\mathbf{Y}\) (or its centred version) can be a bad idea in terms of loss of numerical accuracy. Fortunately, we can find the eigenvalues and eigenvectors of the matrix \(\mathbf{Y}^\top\mathbf{Y}\) without direct computation of the matrix. This can be done with the singular value decomposition. The singular value decompsition takes a matrix, \(\mathbf{Z}\) and represents it in the form, \[
\mathbf{Z} = \mathbf{U}\boldsymbol{\Lambda}\mathbf{V}^\top
-\] where \(\mathbf{U}\) is a matrix of orthogonal vectors in the columns, meaning \(\mathbf{U}^\top\mathbf{U} = \mathbf{I}\). It has the same number of rows and columns as \(\mathbf{Z}\). The matrices \(\mathbf{\Lambda}\) and \(\mathbf{V}\) are both square with dimensionality given by the number of columns of \(\mathbf{Z}\). The matrix \(\mathbf{\Lambda}\) is diagonal and \(\mathbf{V}\) is an orthogonal matrix so \(\mathbf{V}^\top\mathbf{V} = \mathbf{V}\mathbf{V}^\top = \mathbf{I}\). The eigenvalues of the matrix \(\mathbf{Y}^\top\mathbf{Y}\) are then given by the singular values of the matrix \(\mathbf{Y}^\top\) squared and the eigenvectors are given by \(\mathbf{U}\). Given the singular value decomposition of \(\mathbf{Y}\) then we have \[
+\] where \(\mathbf{U}\) is a matrix of orthogonal vectors in the columns, meaning \(\mathbf{U}^\top\mathbf{U} = \mathbf{I}\). It has the same number of rows and columns as \(\mathbf{Z}\). The matrices \(\mathbf{\Lambda}\) and \(\mathbf{V}\) are both square with dimensionality given by the number of columns of \(\mathbf{Z}\). The matrix \(\mathbf{\Lambda}\) is diagonal and \(\mathbf{V}\) is an orthogonal matrix so \(\mathbf{V}^\top\mathbf{V} = \mathbf{V}\mathbf{V}^\top = \mathbf{I}\). The eigenvalues of the matrix \(\mathbf{Y}^\top\mathbf{Y}\) are then given by the singular values of the matrix \(\mathbf{Y}^\top\) squared and the eigenvectors are given by \(\mathbf{U}\). Given the singular value decomposition of \(\mathbf{Y}\) then we have \[
\mathbf{W}=
\mathbf{U}\mathbf{L}\mathbf{R}^\top
\] where \(\mathbf{R}\) is an arbitrary rotation matrix. This implies that the posterior is given by \[
@@ -175,27 +78,9 @@ We’ve implemented PCA as part of supporting the learning process, but in practice we can use the This data set is from a physics-based simulation of oil flow in a pipeline. The data was generated as part of a project to determine the fraction of oil, water and gas in North Sea oil pipes (Bishop and James, 1993). The data consists of 1000 12-dimensional observations of simulated oil flow in a pipeline. Each observation is labelled according to the multi-phase flow configuration (homogeneous, annular or laminar). We’ve implemented PCA as part of supporting the learning process, but in practice we can use the This data set is from a physics-based simulation of oil flow in a pipeline. The data was generated as part of a project to determine the fraction of oil, water and gas in North Sea oil pipes (Bishop and James, 1993). The data consists of 1000 12-dimensional observations of simulated oil flow in a pipeline. Each observation is labelled according to the multi-phase flow configuration (homogeneous, annular or laminar). The data is returned as a dictionary containing training and test inputs (‘X’, ‘Xtst’), training and test labels (‘Y’, ‘Ytst’), and the names of the features. Figure: Visualization of the first two dimensions of the oil flow data from Bishop and James (1993) As normal we include the citation information for the data. And extra information about the data is included, as standard, under the keys The data is returned as a dictionary containing training and test inputs (‘X,’ ‘Xtst’), training and test labels (‘Y,’ ‘Ytst’), and the names of the features. Figure: Visualization of the first two dimensions of the oil flow data from Bishop and James (1993) As normal we include the citation information for the data. And extra information about the data is included, as standard, under the keys Figure: PCA of the oil flow data. The flow is homogeneous, annular and stratified. The challenge for composition of probabilistic models is that you need to propagate a probability densities through non linear mappings. This allows you to create broader classes of probability density. Unfortunately it renders the resulting densities intractable. Figure: A two dimensional grid mapped into three dimensions to form a two dimensional manifold. Figure: A one dimensional line mapped into two dimensions by two separate independent functions. Each point can be mapped exactly through the mappings. Figure: A Gaussian density over the input of a non linear function leads to a very non Gaussian output. Here the output is multimodal. Figure: PCA of the oil flow data. The flow is homogeneous, annular and stratified. The challenge for composition of probabilistic models is that you need to propagate a probability densities through non linear mappings. This allows you to create broader classes of probability density. Unfortunately it renders the resulting densities intractable. Figure: A two dimensional grid mapped into three dimensions to form a two dimensional manifold. Figure: A one dimensional line mapped into two dimensions by two separate independent functions. Each point can be mapped exactly through the mappings. Figure: A Gaussian density over the input of a non linear function leads to a very non Gaussian output. Here the output is multimodal. The following code is for plotting and to prepare the bigger models for later useage. If you are interested, you can have a look, but this is not essential. For this lab, we’ll use a data set containing all handwritten digits from \(0 \cdots 9\) handwritten, provided by de Campos et al. (2009). We will only use some of the digits for the demonstrations in this lab class, but you can edit the code below to select different subsets of the digit data as you wish. The following code is for plotting and to prepare the bigger models for later useage. If you are interested, you can have a look, but this is not essential. For this lab, we’ll use a data set containing all handwritten digits from \(0 \cdots 9\) handwritten, provided by de Campos et al. (2009). We will only use some of the digits for the demonstrations in this lab class, but you can edit the code below to select different subsets of the digit data as you wish. You can try to plot some of the digits using Principal component analysis (PCA) finds a rotation of the observed outputs, such that the rotated principal component (PC) space maximizes the variance of the data observed, sorted from most to least important (most to least variable in the corresponding PC). In order to apply PCA in an easy way, we have included a PCA module in pca.py. You can import the module by import <path.to.pca> (without the ending .py!). To run PCA on the digits we have to reshape (Hint: np.reshape ) digits . We will call the reshaped observed outputs \(\mathbf{Y}\) in the following. Now let’s run PCA on the reshaped dataset \(\mathbf{Y}\): The resulting plot will show the lower dimensional representation of the digits in 2 dimensions. The Gaussian Process Latent Variable Model (GP-LVM) (Lawrence, 2005) embeds PCA into a Gaussian process framework, where the latent inputs \(\mathbf{Z}\) are learnt as hyperparameters and the mapping variables \(\mathbf{W}\) are integrated out. The advantage of this interpretation is it allows PCA to be generalized in a non linear way by replacing the resulting linear covariance witha non linear covariance. But first, let’s see how GPLVM is equivalent to PCA using an automatic relevance determination (ARD, see e.g. Bishop (2006)) linear kernel: You can try to plot some of the digits using Principal component analysis (PCA) finds a rotation of the observed outputs, such that the rotated principal component (PC) space maximizes the variance of the data observed, sorted from most to least important (most to least variable in the corresponding PC). In order to apply PCA in an easy way, we have included a PCA module in pca.py. You can import the module by import <path.to.pca> (without the ending .py!). To run PCA on the digits we have to reshape (Hint: np.reshape ) digits . We will call the reshaped observed outputs \(\mathbf{Y}\) in the following. Now let’s run PCA on the reshaped dataset \(\mathbf{Y}\): The resulting plot will show the lower dimensional representation of the digits in 2 dimensions. The Gaussian Process Latent Variable Model (GP-LVM) (Lawrence, 2005) embeds PCA into a Gaussian process framework, where the latent inputs \(\mathbf{Z}\) are learnt as hyperparameters and the mapping variables \(\mathbf{W}\) are integrated out. The advantage of this interpretation is it allows PCA to be generalized in a non linear way by replacing the resulting linear covariance witha non linear covariance. But first, let’s see how GPLVM is equivalent to PCA using an automatic relevance determination (ARD, see e.g. Bishop (2006)) linear kernel: As you can see the solution with a linear kernel is the same as the PCA solution with the exception of rotational changes and axis flips. For the sake of time, the solution you see was only running for 1000 iterations, thus it might not be converged fully yet. The GP-LVM proceeds by iterative optimization of the inputs to the covariance. As we saw in the lecture earlier, for the linear covariance, these latent points can be optimized with an eigenvalue problem, but generally, for non-linear covariance functions, we are obliged to use gradient based optimization. Motion capture data from the CMU motion capture data base (CMU Motion Capture Lab, 2003). You can download any subject and motion from the data set. Here we will download motion The data dictionary contains the keys ‘Y’ and ‘skel’, which represent the data and the skeleton.. The data was used in the hierarchical GP-LVM paper (Lawrence and Moore, 2007) in an experiment that was also recreated in the Deep Gaussian process paper (Damianou and Lawrence, 2013). And extra information about the data is included, as standard, under the keys As you can see the solution with a linear kernel is the same as the PCA solution with the exception of rotational changes and axis flips. For the sake of time, the solution you see was only running for 1000 iterations, thus it might not be converged fully yet. The GP-LVM proceeds by iterative optimization of the inputs to the covariance. As we saw in the lecture earlier, for the linear covariance, these latent points can be optimized with an eigenvalue problem, but generally, for non-linear covariance functions, we are obliged to use gradient based optimization. Motion capture data from the CMU motion capture data base (CMU Motion Capture Lab, 2003). You can download any subject and motion from the data set. Here we will download motion The data dictionary contains the keys ‘Y’ and ‘skel,’ which represent the data and the skeleton.. The data was used in the hierarchical GP-LVM paper (Lawrence and Moore, 2007) in an experiment that was also recreated in the Deep Gaussian process paper (Damianou and Lawrence, 2013). And extra information about the data is included, as standard, under the keys The original data has the figure moving across the floor during the motion capture sequence. We can make the figure walk ‘in place’, by setting the x, y, z positions of the root node to zero. This makes it easier to visualize the result. We can also remove the mean of the data. Now we create the GP-LVM model. Now we optimize the model. Figure: Gaussian process latent variable model visualisation of CMU motion capture data set. Figure: The latent doodle space idea of Baxter and Anjyo (2006) manages to build a smooth mapping across very sparse data. Generalization with much less Data than Dimensions Powerful uncertainly handling of GPs leads to surprising properties. Non-linear models can be used where there are fewer data points than dimensions without overfitting. The original data has the figure moving across the floor during the motion capture sequence. We can make the figure walk ‘in place,’ by setting the x, y, z positions of the root node to zero. This makes it easier to visualize the result. We can also remove the mean of the data. Now we create the GP-LVM model. Now we optimize the model. Figure: Gaussian process latent variable model visualisation of CMU motion capture data set. Figure: The latent doodle space idea of Baxter and Anjyo (2006) manages to build a smooth mapping across very sparse data. Generalization with much less Data than Dimensions Powerful uncertainly handling of GPs leads to surprising properties. Non-linear models can be used where there are fewer data points than dimensions without overfitting. Figure: Character control in the latent space described the the GP-LVM Levine et al. (2012). Now we analyze some single cell data from Guo et al. (2010). Tey performed qPCR TaqMan array on single cells from the developing blastocyst in mouse. The data is taken from the early stages of development when the Blastocyst is forming. At the 32 cell stage the data is already separated into the trophectoderm (TE) which goes onto form the placenta and the inner cellular mass (ICM). The ICM further differentiates into the epiblast (EPI)—which gives rise to the endoderm, mesoderm and ectoderm—and the primitive endoderm (PE) which develops into the amniotic sack. Guo et al. (2010) selected 48 genes for expression measurement. They labelled the resulting cells and their labels are included as an aide to visualization. They first visualized their data using principal component analysis. In the first two principal components this fails to separate the domains. This is perhaps because the principal components are dominated by the variation in the 64 cell systems. This in turn may be because there are more cells from the data set in that regime, and may be because the natural variation is greater. We first recreate their visualization using principal component analysis. In this notebook we will perform PCA on the original data, showing that the different regimes do not separate. Next we load in the data. We’ve provided a convenience function for loading in the data with Figure: Character control in the latent space described the the GP-LVM Levine et al. (2012). Now we analyze some single cell data from Guo et al. (2010). Tey performed qPCR TaqMan array on single cells from the developing blastocyst in mouse. The data is taken from the early stages of development when the Blastocyst is forming. At the 32 cell stage the data is already separated into the trophectoderm (TE) which goes onto form the placenta and the inner cellular mass (ICM). The ICM further differentiates into the epiblast (EPI)—which gives rise to the endoderm, mesoderm and ectoderm—and the primitive endoderm (PE) which develops into the amniotic sack. Guo et al. (2010) selected 48 genes for expression measurement. They labelled the resulting cells and their labels are included as an aide to visualization. They first visualized their data using principal component analysis. In the first two principal components this fails to separate the domains. This is perhaps because the principal components are dominated by the variation in the 64 cell systems. This in turn may be because there are more cells from the data set in that regime, and may be because the natural variation is greater. We first recreate their visualization using principal component analysis. In this notebook we will perform PCA on the original data, showing that the different regimes do not separate. Next we load in the data. We’ve provided a convenience function for loading in the data with Now we follow Guo et al. (2010) in performing PCA on the data. Rather than calling a ‘PCA routine’, here we break the algorithm down into its steps: compute the data covariance, compute the eigenvalues and eigenvectors and sort according to magnitude of eigenvalue. Because we want to visualize the data, we’ve chose to compute the eigenvectors of the inner product matrix rather than the covariance matrix. This allows us to plot the eigenvalues directly. However, this is less efficient (in this case because the number of genes is smaller than the number of data) than computing the eigendecomposition of the covariance matrix. Now we follow Guo et al. (2010) in performing PCA on the data. Rather than calling a ‘PCA routine,’ here we break the algorithm down into its steps: compute the data covariance, compute the eigenvalues and eigenvectors and sort according to magnitude of eigenvalue. Because we want to visualize the data, we’ve chose to compute the eigenvectors of the inner product matrix rather than the covariance matrix. This allows us to plot the eigenvalues directly. However, this is less efficient (in this case because the number of genes is smaller than the number of data) than computing the eigendecomposition of the covariance matrix. To visualize the result, we now construct a simple helper function. This will ensure that the plots have the same legends as the GP-LVM plots we use below. Now, using the helper function we can plot the results with appropriate labels. Figure: First two principal compoents of the Guo et al. (2010) blastocyst development data. Work done as a collaboration between Max Zwiessele, Oliver Stegle and Neil D. Lawrence. Then, we follow Buettner and Theis (2012) in applying the GP-LVM to the data. There is a slight pathology in the result, one which they fixed by using priors that were dependent on the developmental stage. We then show how the Bayesian GP-LVM doesn’t exhibit those pathologies and gives a nice results that seems to show the lineage of the cells. They used modified prior to ensure that small differences between cells at the same differential stage were preserved. Here we apply a standard GP-LVM (no modified prior) to the data. To visualize the result, we now construct a simple helper function. This will ensure that the plots have the same legends as the GP-LVM plots we use below. Now, using the helper function we can plot the results with appropriate labels. Figure: First two principal compoents of the Guo et al. (2010) blastocyst development data. Work done as a collaboration between Max Zwiessele, Oliver Stegle and Neil D. Lawrence. Then, we follow Buettner and Theis (2012) in applying the GP-LVM to the data. There is a slight pathology in the result, one which they fixed by using priors that were dependent on the developmental stage. We then show how the Bayesian GP-LVM doesn’t exhibit those pathologies and gives a nice results that seems to show the lineage of the cells. They used modified prior to ensure that small differences between cells at the same differential stage were preserved. Here we apply a standard GP-LVM (no modified prior) to the data. Figure: Visualisation of the Guo et al. (2010) blastocyst development data with the GP-LVM. Figure: The ARD parameters of the GP-LVM for the Guo et al. (2010) blastocyst development data. Isomap first builds a neighbourhood graph, and then uses distances along this graph to approximate the geodesic distance between points. These distances are then visualized by performing classical multidimensional scaling (which involves computing the eigendecomposition of the centred distance matrix). As the neighborhood size is increased to match the data, principal component analysis is recovered (or strictly speaking, principal coordinate analysis). The fewer the neighbors, the more ‘non-linear’ the isomap embeddings are. Figure: Visualisation of the Guo et al. (2010) blastocyst development data with the GP-LVM. Figure: The ARD parameters of the GP-LVM for the Guo et al. (2010) blastocyst development data. Isomap first builds a neighbourhood graph, and then uses distances along this graph to approximate the geodesic distance between points. These distances are then visualized by performing classical multidimensional scaling (which involves computing the eigendecomposition of the centred distance matrix). As the neighborhood size is increased to match the data, principal component analysis is recovered (or strictly speaking, principal coordinate analysis). The fewer the neighbors, the more ‘non-linear’ the isomap embeddings are. Figure: Visualisation of the Guo et al. (2010) blastocyst development data with Isomap. Next we try locally linear embedding. In locally linear embedding a neighborhood is also computed. Each point is then reconstructed by it’s neighbors using a linear weighting. This implies a locally linear patch is being fitted to the data in that region. These patches are assimilated into a large \(n\times n\) matrix and a lower dimensional data set which reflects the same relationships is then sought. Quite a large number of neighbours needs to be selected for the data to not collapse in on itself. When a large number of neighbours is selected the embedding is more linear and begins to look like PCA. However, the algorithm does not converge to PCA in the limit as the number of neighbors approaches \(n\). Figure: Visualisation of the Guo et al. (2010) blastocyst development data with Isomap. Next we try locally linear embedding. In locally linear embedding a neighborhood is also computed. Each point is then reconstructed by it’s neighbors using a linear weighting. This implies a locally linear patch is being fitted to the data in that region. These patches are assimilated into a large \(n\times n\) matrix and a lower dimensional data set which reflects the same relationships is then sought. Quite a large number of neighbours needs to be selected for the data to not collapse in on itself. When a large number of neighbours is selected the embedding is more linear and begins to look like PCA. However, the algorithm does not converge to PCA in the limit as the number of neighbors approaches \(n\). Figure: Visualisation of the Guo et al. (2010) blastocyst development data with a locally linear embedding. For more information on these subjects and more you might want to check the following resources. Figure: Visualisation of the Guo et al. (2010) blastocyst development data with a locally linear embedding. For more information on these subjects and more you might want to check the following resources. We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling. Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. For more information on these subjects and more you might want to check the following resources. Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. For more information on these subjects and more you might want to check the following resources. We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling. Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. Bayesian GP-LVM Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. Bayesian GP-LVM \end{tikzpicture} Separate ARD parameters for mappings to \(\mathbf{Y}^{(1)}\) and \(\mathbf{Y}^{(2)}\). \end{center} Figure: The Yale Faces data set shows different people under different lighting conditions Figure: ARD Demonstrates not all of the latent space is used. Figure: Other applications include inferring pose from silhouette Figure: A short video description of the Manifold Relevance Determination method as published at ICML 2012 \end{tikzpicture} Separate ARD parameters for mappings to \(\mathbf{Y}^{(1)}\) and \(\mathbf{Y}^{(2)}\). \end{center} Figure: The Yale Faces data set shows different people under different lighting conditions Figure: ARD Demonstrates not all of the latent space is used. Figure: Other applications include inferring pose from silhouette Figure: A short video description of the Manifold Relevance Determination method as published at ICML 2012 The following code is for plotting and to prepare the bigger models for later useage. If you are interested, you can have a look, but this is not essential. For this lab, we’ll use a data set containing all handwritten digits from \(0 \cdots 9\) handwritten, provided by de Campos et al. (2009). We will only use some of the digits for the demonstrations in this lab class, but you can edit the code below to select different subsets of the digit data as you wish. You can try to plot some of the digits using In GP-LVM we use a point estimate of the distribution of the input \(\mathbf{Z}\). This estimate is derived through maximum likelihood or through a maximum a posteriori (MAP) approach. Ideally, we would like to also estimate a distribution over the input \(\mathbf{Z}\). In the Bayesian GPLVM we approximate the true distribution \(p(\mathbf{Z}|\mathbf{Y})\) by a variational approximation \(q(\mathbf{Z})\) and integrate \(\mathbf{Z}\) out (Titsias and Lawrence, 2010). Approximating the posterior in this way allows us to optimize a lower bound on the marginal likelihood. Handling the uncertainty in a principled way allows the model to make an assessment of whether a particular latent dimension is required, or the variation is better explained by noise. This allows the algorithm to switch off latent dimensions. The switching off can take some time though, so below in Section 6 we provide a pre-learnt module, but to complete section 6 you’ll need to be working in the IPython console instead of the notebook. For the moment we’ll run a short experiment applying the Bayesian GP-LVM with an exponentiated quadratic covariance function. Because we are now also considering the uncertainty in the model, this optimization can take some time. However, you are free to interrupt the optimization at any point selecting A good way of working with latent variable models is to interact with the latent dimensions, generating data. This is a little bit tricky in the notebook, so below in section 6 we provide code for setting up an interactive demo in the standard IPython shell. If you are working on your own machine you can try this now. Otherwise continue with section 5. In Manifold Relevance Determination we try to find one latent space, common for \(K\) observed output sets (modalities) \(\{\mathbf{Y}_{k}\}_{k=1}^{K}\). Each modality is associated with a separate set of ARD parameters so that it switches off different parts of the whole latent space and, therefore, \(\mathbf{Z}\) is softly segmented into parts that are private to some, or shared for all modalities. Can you explain what happens in the following example? Again, you can stop the optimizer at any point and explore the result obtained with the so far training: The module below loads a pre-optimized Bayesian GPLVM model (like the one you just trained) and allows you to interact with the latent space. Three interactive figures pop up: the latent space, the ARD scales and a sample in the output space (corresponding to the current selected latent point of the other figure). You can sample with the mouse from the latent space and obtain samples in the output space. You can select different latent dimensions to vary by clicking on the corresponding scales with the left and right mouse buttons. This will also cause the latent space to be projected on the selected latent dimensions in the other figure. Prepare for plotting of this model. If you run on a webserver the interactive plotting will not work. Thus, you can skip to the next codeblock and run it on your own machine, later. Confirm the following observations by interacting with the demo: You can also run the dimensionality reduction example Now we analyze some single cell data from Guo et al. (2010). Tey performed qPCR TaqMan array on single cells from the developing blastocyst in mouse. The data is taken from the early stages of development when the Blastocyst is forming. At the 32 cell stage the data is already separated into the trophectoderm (TE) which goes onto form the placenta and the inner cellular mass (ICM). The ICM further differentiates into the epiblast (EPI)—which gives rise to the endoderm, mesoderm and ectoderm—and the primitive endoderm (PE) which develops into the amniotic sack. Guo et al. (2010) selected 48 genes for expression measurement. They labelled the resulting cells and their labels are included as an aide to visualization. They first visualized their data using principal component analysis. In the first two principal components this fails to separate the domains. This is perhaps because the principal components are dominated by the variation in the 64 cell systems. This in turn may be because there are more cells from the data set in that regime, and may be because the natural variation is greater. We first recreate their visualization using principal component analysis. In this notebook we will perform PCA on the original data, showing that the different regimes do not separate. Next we load in the data. We’ve provided a convenience function for loading in the data with Now we follow Guo et al. (2010) in performing PCA on the data. Rather than calling a ‘PCA routine,’ here we break the algorithm down into its steps: compute the data covariance, compute the eigenvalues and eigenvectors and sort according to magnitude of eigenvalue. Because we want to visualize the data, we’ve chose to compute the eigenvectors of the inner product matrix rather than the covariance matrix. This allows us to plot the eigenvalues directly. However, this is less efficient (in this case because the number of genes is smaller than the number of data) than computing the eigendecomposition of the covariance matrix. To visualize the result, we now construct a simple helper function. This will ensure that the plots have the same legends as the GP-LVM plots we use below. Now, using the helper function we can plot the results with appropriate labels. Figure: First two principal compoents of the Guo et al. (2010) blastocyst development data. Here we show the new code that uses the Bayesian GP-LVM to fit the data. This means we can automatically determine the dimensionality of the model whilst fitting a non-linear dimensionality reduction. The approximations we use also mean that it is faster than the original GP-LVM. Figure: Visualisation of the Guo et al. (2010) blastocyst development data with the Bayesian GP-LVM. Figure: The ARD parameters of the Bayesian GP-LVM for the Guo et al. (2010) blastocyst development data. This gives a really nice result. Broadly speaking two latent dimensions dominate the representation. When we visualize using these two dimensions we can see the entire cell phylogeny laid out nicely in the two dimensions. For more information on these subjects and more you might want to check the following resources. We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling. We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling. Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. Even in the early days of Gaussian processes in machine learning, it was understood that we were throwing something fundamental away. This is perhaps captured best by David MacKay in his 1997 NeurIPS tutorial on Gaussian processes, where he asked “Have we thrown out the baby with the bathwater?”. The quote below is from his summarization paper. According to the hype of 1987, neural networks were meant to be intelligent models which discovered features and patterns in data. Gaussian processes in contrast are simply smoothing devices. How can Gaussian processes possibly replace neural networks? What is going on? MacKay (n.d.) Figure: A deep neural network Figure: A deep neural network. Input nodes are shown at the bottom. Each hidden layer is the result of applying an affine transformation to the previous layer and placing through an activation function. Mathematically, each layer of a neural network is given through computing the activation function, \(\phi(\cdot)\), contingent on the previous layer, or the inputs. In this way the activation functions, are composed to generate more complex interactions than would be possible with any single layer. \[
+sns.set_palette('colorblind')}--> Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. Even in the early days of Gaussian processes in machine learning, it was understood that we were throwing something fundamental away. This is perhaps captured best by David MacKay in his 1997 NeurIPS tutorial on Gaussian processes, where he asked “Have we thrown out the baby with the bathwater?” The quote below is from his summarization paper. According to the hype of 1987, neural networks were meant to be intelligent models which discovered features and patterns in data. Gaussian processes in contrast are simply smoothing devices. How can Gaussian processes possibly replace neural networks? What is going on? MacKay (n.d.) Figure: A deep neural network Figure: A deep neural network. Input nodes are shown at the bottom. Each hidden layer is the result of applying an affine transformation to the previous layer and placing through an activation function. Mathematically, each layer of a neural network is given through computing the activation function, \(\phi(\cdot)\), contingent on the previous layer, or the inputs. In this way the activation functions, are composed to generate more complex interactions than would be possible with any single layer. \[
\begin{align*}
\mathbf{ h}_{1} &= \phi\left(\mathbf{W}_1 \mathbf{ x}\right)\\
\mathbf{ h}_{2} &= \phi\left(\mathbf{W}_2\mathbf{ h}_{1}\right)\\
\mathbf{ h}_{3} &= \phi\left(\mathbf{W}_3 \mathbf{ h}_{2}\right)\\
f&= \mathbf{ w}_4 ^\top\mathbf{ h}_{3}
\end{align*}
-\] One potential problem is that as the number of nodes in two adjacent layers increases, the number of parameters in the affine transformation between layers, \(\mathbf{W}\), increases. If there are \(k_{i-1}\) nodes in one layer, and \(k_i\) nodes in the following, then that matrix contains \(k_i k_{i-1}\) parameters, when we have layer widths in the 1000s that leads to millions of parameters. One proposed solution is known as dropout where only a sub-set of the neural network is trained at each iteration. An alternative solution would be to reparameterize \(\mathbf{W}\) with its singular value decomposition. \[
+\] One potential problem is that as the number of nodes in two adjacent layers increases, the number of parameters in the affine transformation between layers, \(\mathbf{W}\), increases. If there are \(k_{i-1}\) nodes in one layer, and \(k_i\) nodes in the following, then that matrix contains \(k_i k_{i-1}\) parameters, when we have layer widths in the 1000s that leads to millions of parameters. One proposed solution is known as dropout where only a sub-set of the neural network is trained at each iteration. An alternative solution would be to reparameterize \(\mathbf{W}\) with its singular value decomposition. \[
\mathbf{W}= \mathbf{U}\boldsymbol{ \Lambda}\mathbf{V}^\top
\] or \[
\mathbf{W}= \mathbf{U}\mathbf{V}^\top
- \] where if \(\mathbf{W}\in \Re^{k_1\times k_2}\) then \(\mathbf{U}\in \Re^{k_1\times q}\) and \(\mathbf{V}\in \Re^{k_2\times q}\), i.e. we have a low rank matrix factorization for the weights. Figure: Pictorial representation of the low rank form of the matrix \(\mathbf{W}\). In practice there is evidence that deep models seek these low rank solutions where we expect better generalisation. See e.g. Arora et al. (2019);Jacot et al. (2021). Figure: Inserting the bottleneck layers introduces a new set of variables. Including the low rank decomposition of \(\mathbf{W}\) in the neural network, we obtain a new mathematical form. Effectively, we are adding additional latent layers, \(\mathbf{ z}\), in between each of the existing hidden layers. In a neural network these are sometimes known as bottleneck layers. The network can now be written mathematically as \[
+ \] where if \(\mathbf{W}\in \Re^{k_1\times k_2}\) then \(\mathbf{U}\in \Re^{k_1\times q}\) and \(\mathbf{V}\in \Re^{k_2\times q}\), i.e. we have a low rank matrix factorization for the weights. Figure: Pictorial representation of the low rank form of the matrix \(\mathbf{W}\). In practice there is evidence that deep models seek these low rank solutions where we expect better generalisation. See e.g. Arora et al. (2019);Jacot et al. (2021). Figure: Inserting the bottleneck layers introduces a new set of variables. Including the low rank decomposition of \(\mathbf{W}\) in the neural network, we obtain a new mathematical form. Effectively, we are adding additional latent layers, \(\mathbf{ z}\), in between each of the existing hidden layers. In a neural network these are sometimes known as bottleneck layers. The network can now be written mathematically as \[
\begin{align}
\mathbf{ z}_{1} &= \mathbf{V}^\top_1 \mathbf{ x}\\
\mathbf{ h}_{1} &= \phi\left(\mathbf{U}_1 \mathbf{ z}_{1}\right)\\
@@ -167,292 +41,49 @@ \[
+\] \[
\begin{align}
\mathbf{ z}_{1} &= \mathbf{V}^\top_1 \mathbf{ x}\\
\mathbf{ z}_{2} &= \mathbf{V}^\top_2 \phi\left(\mathbf{U}_1 \mathbf{ z}_{1}\right)\\
\mathbf{ z}_{3} &= \mathbf{V}^\top_3 \phi\left(\mathbf{U}_2 \mathbf{ z}_{2}\right)\\
\mathbf{ y}&= \mathbf{ w}_4 ^\top \mathbf{ z}_{3}
\end{align}
-\] Now if we replace each of these neural networks with a Gaussian process. This is equivalent to taking the limit as the width of each layer goes to infinity, while appropriately scaling down the outputs. \[
+\] Now if we replace each of these neural networks with a Gaussian process. This is equivalent to taking the limit as the width of each layer goes to infinity, while appropriately scaling down the outputs. \[
\begin{align}
\mathbf{ z}_{1} &= \mathbf{ f}_1\left(\mathbf{ x}\right)\\
\mathbf{ z}_{2} &= \mathbf{ f}_2\left(\mathbf{ z}_{1}\right)\\
\mathbf{ z}_{3} &= \mathbf{ f}_3\left(\mathbf{ z}_{2}\right)\\
\mathbf{ y}&= \mathbf{ f}_4\left(\mathbf{ z}_{3}\right)
\end{align}
-\] Figure: The DeepFace architecture (Taigman et al., 2014), visualized through colors to represent the functional mappings at each layer. There are 120 million parameters in the model. The DeepFace architecture (Taigman et al., 2014) consists of layers that deal with translation invariances, known as convolutional layers. These layers are followed by three locally-connected layers and two fully-connected layers. Color illustrates feature maps produced at each layer. The neural network includes more than 120 million parameters, where more than 95% come from the local and fully connected layers. Figure: Deep learning models are composition of simple functions. We can think of a pinball machine as an analogy. Each layer of pins corresponds to one of the layers of functions in the model. Input data is represented by the location of the ball from left to right when it is dropped in from the top. Output class comes from the position of the ball as it leaves the pins at the bottom. Sometimes deep learning models are described as being like the brain, or too complex to understand, but one analogy I find useful to help the gist of these models is to think of them as being similar to early pin ball machines. In a deep neural network, we input a number (or numbers), whereas in pinball, we input a ball. Think of the location of the ball on the left-right axis as a single number. Our simple pinball machine can only take one number at a time. As the ball falls through the machine, each layer of pins can be thought of as a different layer of ‘neurons’. Each layer acts to move the ball from left to right. In a pinball machine, when the ball gets to the bottom it might fall into a hole defining a score, in a neural network, that is equivalent to the decision: a classification of the input object. An image has more than one number associated with it, so it is like playing pinball in a hyper-space. Figure: At initialization, the pins, which represent the parameters of the function, aren’t in the right place to bring the balls to the correct decisions. Figure: After learning the pins are now in the right place to bring the balls to the correct decisions. Learning involves moving all the pins to be in the correct position, so that the ball ends up in the right place when it’s fallen through the machine. But moving all these pins in hyperspace can be difficult. In a hyper-space you have to put a lot of data through the machine for to explore the positions of all the pins. Even when you feed many millions of data points through the machine, there are likely to be regions in the hyper-space where no ball has passed. When future test data passes through the machine in a new route unusual things can happen. Adversarial examples exploit this high dimensional space. If you have access to the pinball machine, you can use gradient methods to find a position for the ball in the hyper space where the image looks like one thing, but will be classified as another. Probabilistic methods explore more of the space by considering a range of possible paths for the ball through the machine. This helps to make them more data efficient and gives some robustness to adversarial examples. Mathematically, a deep Gaussian process can be seen as a composite multivariate function, \[
+\] Figure: The DeepFace architecture (Taigman et al., 2014), visualized through colors to represent the functional mappings at each layer. There are 120 million parameters in the model. The DeepFace architecture (Taigman et al., 2014) consists of layers that deal with translation invariances, known as convolutional layers. These layers are followed by three locally-connected layers and two fully-connected layers. Color illustrates feature maps produced at each layer. The neural network includes more than 120 million parameters, where more than 95% come from the local and fully connected layers. Figure: Deep learning models are composition of simple functions. We can think of a pinball machine as an analogy. Each layer of pins corresponds to one of the layers of functions in the model. Input data is represented by the location of the ball from left to right when it is dropped in from the top. Output class comes from the position of the ball as it leaves the pins at the bottom. Sometimes deep learning models are described as being like the brain, or too complex to understand, but one analogy I find useful to help the gist of these models is to think of them as being similar to early pin ball machines. In a deep neural network, we input a number (or numbers), whereas in pinball, we input a ball. Think of the location of the ball on the left-right axis as a single number. Our simple pinball machine can only take one number at a time. As the ball falls through the machine, each layer of pins can be thought of as a different layer of ‘neurons.’ Each layer acts to move the ball from left to right. In a pinball machine, when the ball gets to the bottom it might fall into a hole defining a score, in a neural network, that is equivalent to the decision: a classification of the input object. An image has more than one number associated with it, so it is like playing pinball in a hyper-space. Figure: At initialization, the pins, which represent the parameters of the function, aren’t in the right place to bring the balls to the correct decisions. Figure: After learning the pins are now in the right place to bring the balls to the correct decisions. Learning involves moving all the pins to be in the correct position, so that the ball ends up in the right place when it’s fallen through the machine. But moving all these pins in hyperspace can be difficult. In a hyper-space you have to put a lot of data through the machine for to explore the positions of all the pins. Even when you feed many millions of data points through the machine, there are likely to be regions in the hyper-space where no ball has passed. When future test data passes through the machine in a new route unusual things can happen. Adversarial examples exploit this high dimensional space. If you have access to the pinball machine, you can use gradient methods to find a position for the ball in the hyper space where the image looks like one thing, but will be classified as another. Probabilistic methods explore more of the space by considering a range of possible paths for the ball through the machine. This helps to make them more data efficient and gives some robustness to adversarial examples. Mathematically, a deep Gaussian process can be seen as a composite multivariate function, \[
\mathbf{g}(\mathbf{ x})=\mathbf{ f}_5(\mathbf{ f}_4(\mathbf{ f}_3(\mathbf{ f}_2(\mathbf{ f}_1(\mathbf{ x}))))).
- \] Or if we view it from the probabilistic perspective we can see that a deep Gaussian process is specifying a factorization of the joint density, the standard deep model takes the form of a Markov chain. \[
+ \] Or if we view it from the probabilistic perspective we can see that a deep Gaussian process is specifying a factorization of the joint density, the standard deep model takes the form of a Markov chain. \[
p(\mathbf{ y}|\mathbf{ x})= p(\mathbf{ y}|\mathbf{ f}_5)p(\mathbf{ f}_5|\mathbf{ f}_4)p(\mathbf{ f}_4|\mathbf{ f}_3)p(\mathbf{ f}_3|\mathbf{ f}_2)p(\mathbf{ f}_2|\mathbf{ f}_1)p(\mathbf{ f}_1|\mathbf{ x})
- \] Figure: Probabilistically the deep Gaussian process can be represented as a Markov chain. Indeed they can even be analyzed in this way (Dunlop et al., n.d.). Figure: More usually deep probabilistic models are written vertically rather than horizontally as in the Markov chain. If the result of composing many functions together is simply another function, then why do we bother? The key point is that we can change the class of functions we are modeling by composing in this manner. A Gaussian process is specifying a prior over functions, and one with a number of elegant properties. For example, the derivative process (if it exists) of a Gaussian process is also Gaussian distributed. That makes it easy to assimilate, for example, derivative observations. But that also might raise some alarm bells. That implies that the marginal derivative distribution is also Gaussian distributed. If that’s the case, then it means that functions which occasionally exhibit very large derivatives are hard to model with a Gaussian process. For example, a function with jumps in. A one off discontinuity is easy to model with a Gaussian process, or even multiple discontinuities. They can be introduced in the mean function, or independence can be forced between two covariance functions that apply in different areas of the input space. But in these cases we will need to specify the number of discontinuities and where they occur. In otherwords we need to parameterise the discontinuities. If we do not know the number of discontinuities and don’t wish to specify where they occur, i.e. if we want a non-parametric representation of discontinuities, then the standard Gaussian process doesn’t help. The deep Gaussian process leads to non-Gaussian models, and non-Gaussian characteristics in the covariance function. In effect, what we are proposing is that we change the properties of the functions we are considering by composing stochastic processes. This is an approach to creating new stochastic processes from well known processes. Additionally, we are not constrained to the formalism of the chain. For example, we can easily add single nodes emerging from some point in the depth of the chain. This allows us to combine the benefits of the graphical modelling formalism, but with a powerful framework for relating one set of variables to another, that of Gaussian processes Figure: More generally we aren’t constrained by the Markov chain. We can design structures that respect our belief about the underlying conditional dependencies. Here we are adding a side note from the chain. The challenge for composition of probabilistic models is that you need to propagate a probability densities through non linear mappings. This allows you to create broader classes of probability density. Unfortunately it renders the resulting densities intractable. Figure: A two dimensional grid mapped into three dimensions to form a two dimensional manifold. Figure: A one dimensional line mapped into two dimensions by two separate independent functions. Each point can be mapped exactly through the mappings. Figure: A Gaussian density over the input of a non linear function leads to a very non Gaussian output. Here the output is multimodal. Figure: Probabilistically the deep Gaussian process can be represented as a Markov chain. Indeed they can even be analyzed in this way (Dunlop et al., n.d.). Figure: More usually deep probabilistic models are written vertically rather than horizontally as in the Markov chain. If the result of composing many functions together is simply another function, then why do we bother? The key point is that we can change the class of functions we are modeling by composing in this manner. A Gaussian process is specifying a prior over functions, and one with a number of elegant properties. For example, the derivative process (if it exists) of a Gaussian process is also Gaussian distributed. That makes it easy to assimilate, for example, derivative observations. But that also might raise some alarm bells. That implies that the marginal derivative distribution is also Gaussian distributed. If that’s the case, then it means that functions which occasionally exhibit very large derivatives are hard to model with a Gaussian process. For example, a function with jumps in. A one off discontinuity is easy to model with a Gaussian process, or even multiple discontinuities. They can be introduced in the mean function, or independence can be forced between two covariance functions that apply in different areas of the input space. But in these cases we will need to specify the number of discontinuities and where they occur. In otherwords we need to parameterise the discontinuities. If we do not know the number of discontinuities and don’t wish to specify where they occur, i.e. if we want a non-parametric representation of discontinuities, then the standard Gaussian process doesn’t help. The deep Gaussian process leads to non-Gaussian models, and non-Gaussian characteristics in the covariance function. In effect, what we are proposing is that we change the properties of the functions we are considering by composing stochastic processes. This is an approach to creating new stochastic processes from well known processes. Additionally, we are not constrained to the formalism of the chain. For example, we can easily add single nodes emerging from some point in the depth of the chain. This allows us to combine the benefits of the graphical modelling formalism, but with a powerful framework for relating one set of variables to another, that of Gaussian processes Figure: More generally we aren’t constrained by the Markov chain. We can design structures that respect our belief about the underlying conditional dependencies. Here we are adding a side note from the chain. The challenge for composition of probabilistic models is that you need to propagate a probability densities through non linear mappings. This allows you to create broader classes of probability density. Unfortunately it renders the resulting densities intractable. Figure: A two dimensional grid mapped into three dimensions to form a two dimensional manifold. Figure: A one dimensional line mapped into two dimensions by two separate independent functions. Each point can be mapped exactly through the mappings. Figure: A Gaussian density over the input of a non linear function leads to a very non Gaussian output. Here the output is multimodal. The standard variational approach would require the expectation of \(\log p(\mathbf{ y}|\mathbf{Z})\) under \(q(\mathbf{Z})\). \[
+\] The standard variational approach would require the expectation of \(\log p(\mathbf{ y}|\mathbf{Z})\) under \(q(\mathbf{Z})\). \[
\begin{align}
\log p(\mathbf{ y}|\mathbf{Z}) = & -\frac{1}{2}\mathbf{ y}^\top\left(\mathbf{K}_{\mathbf{ f}, \mathbf{ f}}+\sigma^2\mathbf{I}\right)^{-1}\mathbf{ y}\\ & -\frac{1}{2}\log \det{\mathbf{K}_{\mathbf{ f}, \mathbf{ f}}+\sigma^2 \mathbf{I}} -\frac{n}{2}\log 2\pi
\end{align}
- \] But this is extremely difficult to compute because \(\mathbf{K}_{\mathbf{ f}, \mathbf{ f}}\) is dependent on \(\mathbf{Z}\) and it appears in the inverse. The alternative approach is to consider the collapsed variational bound (used for low rank (sparse is a misnomer) Gaussian process approximations. \[
+ \] But this is extremely difficult to compute because \(\mathbf{K}_{\mathbf{ f}, \mathbf{ f}}\) is dependent on \(\mathbf{Z}\) and it appears in the inverse. The alternative approach is to consider the collapsed variational bound (used for low rank (sparse is a misnomer) Gaussian process approximations. \[
p(\mathbf{ y})\geq \prod_{i=1}^nc_i \int \mathscr{N}\left(\mathbf{ y}|\left\langle\mathbf{ f}\right\rangle,\sigma^2\mathbf{I}\right)p(\mathbf{ u}) \text{d}\mathbf{ u}
\] \[
p(\mathbf{ y}|\mathbf{Z})\geq \prod_{i=1}^nc_i \int \mathscr{N}\left(\mathbf{ y}|\left\langle\mathbf{ f}\right\rangle_{p(\mathbf{ f}|\mathbf{ u}, \mathbf{Z})},\sigma^2\mathbf{I}\right)p(\mathbf{ u}) \text{d}\mathbf{ u}
\] \[
\int p(\mathbf{ y}|\mathbf{Z})p(\mathbf{Z}) \text{d}\mathbf{Z}\geq \int \prod_{i=1}^nc_i \mathscr{N}\left(\mathbf{ y}|\left\langle\mathbf{ f}\right\rangle_{p(\mathbf{ f}|\mathbf{ u}, \mathbf{Z})},\sigma^2\mathbf{I}\right) p(\mathbf{Z})\text{d}\mathbf{Z}p(\mathbf{ u}) \text{d}\mathbf{ u}
- \] To integrate across \(\mathbf{Z}\) we apply the lower bound to the inner integral. \[
+ \] To integrate across \(\mathbf{Z}\) we apply the lower bound to the inner integral. \[
\begin{align}
\int \prod_{i=1}^nc_i \mathscr{N}\left(\mathbf{ y}|\left\langle\mathbf{ f}\right\rangle_{p(\mathbf{ f}|\mathbf{ u}, \mathbf{Z})},\sigma^2\mathbf{I}\right) p(\mathbf{Z})\text{d}\mathbf{Z}\geq & \left\langle\sum_{i=1}^n\log c_i\right\rangle_{q(\mathbf{Z})}\\ & +\left\langle\log\mathscr{N}\left(\mathbf{ y}|\left\langle\mathbf{ f}\right\rangle_{p(\mathbf{ f}|\mathbf{ u}, \mathbf{Z})},\sigma^2\mathbf{I}\right)\right\rangle_{q(\mathbf{Z})}\\& + \text{KL}\left( q(\mathbf{Z})\,\|\,p(\mathbf{Z}) \right)
\end{align}
- \] * Which is analytically tractable for Gaussian \(q(\mathbf{Z})\) and some covariance functions. Need expectations under \(q(\mathbf{Z})\) of: \[
+ \] * Which is analytically tractable for Gaussian \(q(\mathbf{Z})\) and some covariance functions. Need expectations under \(q(\mathbf{Z})\) of: \[
\log c_i = \frac{1}{2\sigma^2} \left[k_{i, i} - \mathbf{ k}_{i, \mathbf{ u}}^\top \mathbf{K}_{\mathbf{ u}, \mathbf{ u}}^{-1} \mathbf{ k}_{i, \mathbf{ u}}\right]
\] and \[
\log \mathscr{N}\left(\mathbf{ y}|\left\langle\mathbf{ f}\right\rangle_{p(\mathbf{ f}|\mathbf{ u},\mathbf{Y})},\sigma^2\mathbf{I}\right) = -\frac{1}{2}\log 2\pi\sigma^2 - \frac{1}{2\sigma^2}\left(y_i - \mathbf{K}_{\mathbf{ f}, \mathbf{ u}}\mathbf{K}_{\mathbf{ u},\mathbf{ u}}^{-1}\mathbf{ u}\right)^2
-\] This requires the expectations \[
+\] This requires the expectations \[
\left\langle\mathbf{K}_{\mathbf{ f},\mathbf{ u}}\right\rangle_{q(\mathbf{Z})}
\] and \[
\left\langle\mathbf{K}_{\mathbf{ f},\mathbf{ u}}\mathbf{K}_{\mathbf{ u},\mathbf{ u}}^{-1}\mathbf{K}_{\mathbf{ u},\mathbf{ f}}\right\rangle_{q(\mathbf{Z})}
-\] which can be computed analytically for some covariance functions (Damianou et al., 2016) or through sampling (Damianou, 2015; Salimbeni and Deisenroth, 2017). Variational approximations aren’t the only approach to approximate inference. The original work on deep Gaussian processes made use of MAP approximations (Lawrence and Moore, 2007), which couldn’t propagate the uncertainty through the model at the data points but sustain uncertainty elsewhere. Since the variational approximation was proposed researchers have also considered sampling approaches (Havasi et al., 2018) and expectation propagation (Bui et al., 2016). Figure: Even the latest work on Bayesian neural networks has severe problems handling uncertainty. In this example, (Izmailov et al., 2019), methods even fail to interpolate through the data correctly or provide well calibrated error bars in regions where data is observed. The argument in the deep learning revolution is that deep architectures allow us to develop an abstraction of the feature set through model composition. Composing Gaussian processes is analytically intractable. To form deep Gaussian processes we use a variational approach to stack the models. Figure: Composition of linear functions just leads to a new linear function. Here you see the result of multiple affine transformations applied to a square in two dimensions. Stacking a series of linear functions simply leads to a new linear function. The use of multiple linear function merely changes the covariance of the resulting Gaussian. If \[
+\] which can be computed analytically for some covariance functions (Damianou et al., 2016) or through sampling (Damianou, 2015; Salimbeni and Deisenroth, 2017). Variational approximations aren’t the only approach to approximate inference. The original work on deep Gaussian processes made use of MAP approximations (Lawrence and Moore, 2007), which couldn’t propagate the uncertainty through the model at the data points but sustain uncertainty elsewhere. Since the variational approximation was proposed researchers have also considered sampling approaches (Havasi et al., 2018) and expectation propagation (Bui et al., 2016). Figure: Even the latest work on Bayesian neural networks has severe problems handling uncertainty. In this example, (Izmailov et al., 2019), methods even fail to interpolate through the data correctly or provide well calibrated error bars in regions where data is observed. The argument in the deep learning revolution is that deep architectures allow us to develop an abstraction of the feature set through model composition. Composing Gaussian processes is analytically intractable. To form deep Gaussian processes we use a variational approach to stack the models. Figure: Composition of linear functions just leads to a new linear function. Here you see the result of multiple affine transformations applied to a square in two dimensions. Stacking a series of linear functions simply leads to a new linear function. The use of multiple linear function merely changes the covariance of the resulting Gaussian. If \[
\mathbf{Z}\sim \mathscr{N}\left(\mathbf{0},\mathbf{I}\right)
\] and the \(i\)th hidden layer is a multivariate linear transformation defined by \(\mathbf{W}_i\), \[
\mathbf{Y}= \mathbf{Z}\mathbf{W}_1 \mathbf{W}_2 \dots \mathbf{W}_L
@@ -473,56 +104,7 @@ Figure: Stacking Gaussian process models leads to non linear mappings at each stage. Here we are mapping from two dimensions to two dimensions in each layer. Note that once the box has folded over on itself, it cannot be unfolded. So a feature that is generated near the top of the model cannot be removed further down the model. This folding over effect happens in low dimensions. In higher dimensions it is less common. Observation of this effect at a talk in Cambridge was one of the things that caused David Duvenaud (and collaborators) to consider the behavior of deeper Gaussian process models (Duvenaud et al., 2014). Such folding over in the latent spaces necessarily forces the density to be non-Gaussian. Indeed, since folding-over is avoided as we increase the dimensionality of the latent spaces, such processes become more Gaussian. If we take the limit of the latent space dimensionality as it tends to infinity, the entire deep Gaussian process returns to a standard Gaussian process, with a covariance function given as a deep kernel (such as those described by Cho and Saul (2009)). Further analysis of these deep networks has been conducted by Dunlop et al. (n.d.), who use analysis of the deep network’s stationary density (treating it as a Markov chain across layers), to explore the nature of the implied process prior for a deep GP. Both of these works, however, make constraining assumptions on the form of the Gaussian process prior at each layer (e.g. same covariance at each layer). In practice, the form of this covariance can be learnt and the densities described by the deep GP are more general than those mentioned in either of these papers. Figure: Visualization of mapping of a two dimensional space through a deep Gaussian process. David Duvenaud also created a YouTube video to help visualize what happens as you drop through the layers of a deep GP. This notebook depends on PyDeepGP. This library can be installed via pip. Figure: Stacking Gaussian process models leads to non linear mappings at each stage. Here we are mapping from two dimensions to two dimensions in each layer. Note that once the box has folded over on itself, it cannot be unfolded. So a feature that is generated near the top of the model cannot be removed further down the model. This folding over effect happens in low dimensions. In higher dimensions it is less common. Observation of this effect at a talk in Cambridge was one of the things that caused David Duvenaud (and collaborators) to consider the behavior of deeper Gaussian process models (Duvenaud et al., 2014). Such folding over in the latent spaces necessarily forces the density to be non-Gaussian. Indeed, since folding-over is avoided as we increase the dimensionality of the latent spaces, such processes become more Gaussian. If we take the limit of the latent space dimensionality as it tends to infinity, the entire deep Gaussian process returns to a standard Gaussian process, with a covariance function given as a deep kernel (such as those described by Cho and Saul (2009)). Further analysis of these deep networks has been conducted by Dunlop et al. (n.d.), who use analysis of the deep network’s stationary density (treating it as a Markov chain across layers), to explore the nature of the implied process prior for a deep GP. Both of these works, however, make constraining assumptions on the form of the Gaussian process prior at each layer (e.g. same covariance at each layer). In practice, the form of this covariance can be learnt and the densities described by the deep GP are more general than those mentioned in either of these papers. Figure: Visualization of mapping of a two dimensional space through a deep Gaussian process. David Duvenaud also created a YouTube video to help visualize what happens as you drop through the layers of a deep GP. This notebook depends on PyDeepGP. This library can be installed via pip. Image from Wikimedia Commons The Olympic Marathon data is a standard dataset for regression modelling. The data consists of the pace of Olympic Gold Medal Marathon winners for the Olympics from 1896 to present. Let’s load in the data and plot. Image from Wikimedia Commons The Olympic Marathon data is a standard dataset for regression modelling. The data consists of the pace of Olympic Gold Medal Marathon winners for the Olympics from 1896 to present. Let’s load in the data and plot. Figure: Olympic marathon pace times since 1896. Things to notice about the data include the outlier in 1904, in that year the Olympics was in St Louis, USA. Organizational problems and challenges with dust kicked up by the cars following the race meant that participants got lost, and only very few participants completed. More recent years see more consistently quick marathons. Figure: Alan Turing, in 1946 he was only 11 minutes slower than the winner of the 1948 games. Would he have won a hypothetical games held in 1946? Source: Alan Turing Internet Scrapbook. If we had to summarise the objectives of machine learning in one word, a very good candidate for that word would be generalization. What is generalization? From a human perspective it might be summarised as the ability to take lessons learned in one domain and apply them to another domain. If we accept the definition given in the first session for machine learning, \[
+yhat = (y - offset)/scale Figure: Olympic marathon pace times since 1896. Things to notice about the data include the outlier in 1904, in that year the Olympics was in St Louis, USA. Organizational problems and challenges with dust kicked up by the cars following the race meant that participants got lost, and only very few participants completed. More recent years see more consistently quick marathons. Figure: Alan Turing, in 1946 he was only 11 minutes slower than the winner of the 1948 games. Would he have won a hypothetical games held in 1946? Source: Alan Turing Internet Scrapbook. If we had to summarise the objectives of machine learning in one word, a very good candidate for that word would be generalization. What is generalization? From a human perspective it might be summarised as the ability to take lessons learned in one domain and apply them to another domain. If we accept the definition given in the first session for machine learning, \[
\text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}
-\] then we see that without a model we can’t generalise: we only have data. Data is fine for answering very specific questions, like “Who won the Olympic Marathon in 2012?”, because we have that answer stored, however, we are not given the answer to many other questions. For example, Alan Turing was a formidable marathon runner, in 1946 he ran a time 2 hours 46 minutes (just under four minutes per kilometer, faster than I and most of the other Endcliffe Park Run runners can do 5 km). What is the probability he would have won an Olympics if one had been held in 1946? To answer this question we need to generalize, but before we formalize the concept of generalization let’s introduce some formal representation of what it means to generalize in machine learning. Our first objective will be to perform a Gaussian process fit to the data, we’ll do this using the GPy software. The first command sets up the model, then To answer this question we need to generalize, but before we formalize the concept of generalization let’s introduce some formal representation of what it means to generalize in machine learning. Our first objective will be to perform a Gaussian process fit to the data, we’ll do this using the GPy software. The first command sets up the model, then Now we plot the results using the helper function in Figure: Gaussian process fit to the Olympic Marathon data. The error bars are too large, perhaps due to the outlier from 1904. In the fit we see that the error bars (coming mainly from the noise variance) are quite large. This is likely due to the outlier point in 1904, ignoring that point we can see that a tighter fit is obtained. To see this make a version of the model, Now we plot the results using the helper function in Figure: Gaussian process fit to the Olympic Marathon data. The error bars are too large, perhaps due to the outlier from 1904. In the fit we see that the error bars (coming mainly from the noise variance) are quite large. This is likely due to the outlier point in 1904, ignoring that point we can see that a tighter fit is obtained. To see this make a version of the model, Figure: Gaussian process fit to the Olympic Marathon data. Here we’ve removed the outlier from 1904. Let’s see if a deep Gaussian process can help here. We will construct a deep Gaussian process with one hidden layer (i.e. one Gaussian process feeding into another). Build a Deep GP with an additional hidden layer (one dimensional) to fit the model. Figure: Gaussian process fit to the Olympic Marathon data. Here we’ve removed the outlier from 1904. Let’s see if a deep Gaussian process can help here. We will construct a deep Gaussian process with one hidden layer (i.e. one Gaussian process feeding into another). Build a Deep GP with an additional hidden layer (one dimensional) to fit the model. Now optimize the model. Now optimize the model. Figure: Deep GP fit to the Olympic marathon data. Error bars now change as the prediction evolves. Figure: Point samples run through the deep Gaussian process show the distribution of output locations. Now we explore the GPs the model has used to fit each layer. First of all, we look at the hidden layer. Figure: The mapping from input to the latent layer is broadly, with some flattening as time goes on. Variance is high across the input range. Figure: The mapping from the latent layer to the output layer. Figure: A pinball plot shows the movement of the ‘ball’ as it passes through each layer of the Gaussian processes. Mean directions of movement are shown by lines. Shading gives one standard deviation of movement position. At each layer, the uncertainty is reset. The overal uncertainty is the cumulative uncertainty from all the layers. There is some grouping of later points towards the right in the first layer, which also injects a large amount of uncertainty. Due to flattening of the curve in the second layer towards the right the uncertainty is reduced in final output. The pinball plot shows the flow of any input ball through the deep Gaussian process. In a pinball plot a series of vertical parallel lines would indicate a purely linear function. For the olypmic marathon data we can see the first layer begins to shift from input towards the right. Note it also does so with some uncertainty (indicated by the shaded backgrounds). The second layer has less uncertainty, but bunches the inputs more strongly to the right. This input layer of uncertainty, followed by a layer that pushes inputs to the right is what gives the heteroschedastic noise. We now consider an example in gene expression. Gene expression is the measurement of mRNA levels expressed in cells. These mRNA levels show which genes are ‘switched on’ and producing data. In the example we will use a Gaussian process to determine whether a given gene is active, or we are merely observing a noise response. Figure: Deep GP fit to the Olympic marathon data. Error bars now change as the prediction evolves. Figure: Point samples run through the deep Gaussian process show the distribution of output locations. Now we explore the GPs the model has used to fit each layer. First of all, we look at the hidden layer. Figure: The mapping from input to the latent layer is broadly, with some flattening as time goes on. Variance is high across the input range. Figure: The mapping from the latent layer to the output layer. Figure: A pinball plot shows the movement of the ‘ball’ as it passes through each layer of the Gaussian processes. Mean directions of movement are shown by lines. Shading gives one standard deviation of movement position. At each layer, the uncertainty is reset. The overal uncertainty is the cumulative uncertainty from all the layers. There is some grouping of later points towards the right in the first layer, which also injects a large amount of uncertainty. Due to flattening of the curve in the second layer towards the right the uncertainty is reduced in final output. The pinball plot shows the flow of any input ball through the deep Gaussian process. In a pinball plot a series of vertical parallel lines would indicate a purely linear function. For the olypmic marathon data we can see the first layer begins to shift from input towards the right. Note it also does so with some uncertainty (indicated by the shaded backgrounds). The second layer has less uncertainty, but bunches the inputs more strongly to the right. This input layer of uncertainty, followed by a layer that pushes inputs to the right is what gives the heteroschedastic noise. We now consider an example in gene expression. Gene expression is the measurement of mRNA levels expressed in cells. These mRNA levels show which genes are ‘switched on’ and producing data. In the example we will use a Gaussian process to determine whether a given gene is active, or we are merely observing a noise response. Figure: Gene expression levels over time for a gene from data provided by Della Gatta et al. (2008). We would like to understand whether there is signal in the data, or we are only observing noise. Figure: The example is taken from the paper “A Simple Approach to Ranking Differentially Expressed Gene Expression Time Courses through Gaussian Process Regression.” Kalaitzis and Lawrence (2011). Our first objective will be to perform a Gaussian process fit to the data, we’ll do this using the GPy software. Figure: Gene expression levels over time for a gene from data provided by Della Gatta et al. (2008). We would like to understand whether there is signal in the data, or we are only observing noise. Figure: The example is taken from the paper “A Simple Approach to Ranking Differentially Expressed Gene Expression Time Courses through Gaussian Process Regression.” Kalaitzis and Lawrence (2011). Our first objective will be to perform a Gaussian process fit to the data, we’ll do this using the GPy software. Initialize the length scale parameter (which here actually represents a time scale of the covariance function) to a reasonable value. Default would be 1, but here we set it to 50 minutes, given points are arriving across zero to 250 minutes. Initialize the length scale parameter (which here actually represents a time scale of the covariance function) to a reasonable value. Default would be 1, but here we set it to 50 minutes, given points are arriving across zero to 250 minutes. Now we plot the results using the helper function in Figure: Result of the fit of the Gaussian process model with the time scale parameter initialized to 50 minutes. Now we try a model initialized with a longer length scale. Now we plot the results using the helper function in Figure: Result of the fit of the Gaussian process model with the time scale parameter initialized to 50 minutes. Now we try a model initialized with a longer length scale. Figure: Result of the fit of the Gaussian process model with the time scale parameter initialized to 2000 minutes. Now we try a model initialized with a lower noise. Figure: Result of the fit of the Gaussian process model with the time scale parameter initialized to 2000 minutes. Now we try a model initialized with a lower noise. Figure: Result of the fit of the Gaussian process model with the noise initialized low (standard deviation 0.1) and the time scale parameter initialized to 20 minutes. Figure: The deep Gaussian process code we are using is research code by Andreas Damianou. To extend the research code we introduce some approaches to initialization and optimization that we’ll use in examples. These approaches live in the Deep Gaussian process models also can require some thought in the initialization. Here we choose to start by setting the noise variance to be one percent of the data variance. Secondly, we introduce a staged optimization approach. Optimization requires moving variational parameters in the hidden layer representing the mean and variance of the expected values in that layer. Since all those values can be scaled up, and this only results in a downscaling in the output of the first GP, and a downscaling of the input length scale to the second GP. It makes sense to first of all fix the scales of the covariance function in each of the GPs. Sometimes, deep Gaussian processes can find a local minima which involves increasing the noise level of one or more of the GPs. This often occurs because it allows a minimum in the KL divergence term in the lower bound on the likelihood. To avoid this minimum we habitually train with the likelihood variance (the noise on the output of the GP) fixed to some lower value for some iterations. Next an optimization of the kernel function parameters at each layer is performed, but with the variance of the likelihood fixed. Again, this is to prevent the model minimizing the Kullback-Leibler divergence between the approximate posterior and the prior before achieving a good data-fit. Finally, all parameters of the model are optimized together. The next code is for visualizing the intermediate layers of the deep model. This visualization is only appropriate for models with intermediate layers containing a single latent variable. The pinball visualization is to bring the pinball-analogy to life in the model. It shows how a ball would fall through the model to end up in the right pbosition. This visualization is only appropriate for models with intermediate layers containing a single latent variable. The Finally, we bind these methods to the DeepGP object for ease of calling. The deep Gaussian process code we are using is research code by Andreas Damianou. To extend the research code we introduce some approaches to initialization and optimization that we’ll use in examples. These approaches live in the Deep Gaussian process models also can require some thought in the initialization. Here we choose to start by setting the noise variance to be one percent of the data variance. Secondly, we introduce a staged optimization approach. Optimization requires moving variational parameters in the hidden layer representing the mean and variance of the expected values in that layer. Since all those values can be scaled up, and this only results in a downscaling in the output of the first GP, and a downscaling of the input length scale to the second GP. It makes sense to first of all fix the scales of the covariance function in each of the GPs. Sometimes, deep Gaussian processes can find a local minima which involves increasing the noise level of one or more of the GPs. This often occurs because it allows a minimum in the KL divergence term in the lower bound on the likelihood. To avoid this minimum we habitually train with the likelihood variance (the noise on the output of the GP) fixed to some lower value for some iterations. Next an optimization of the kernel function parameters at each layer is performed, but with the variance of the likelihood fixed. Again, this is to prevent the model minimizing the Kullback-Leibler divergence between the approximate posterior and the prior before achieving a good data-fit. Finally, all parameters of the model are optimized together. The next code is for visualizing the intermediate layers of the deep model. This visualization is only appropriate for models with intermediate layers containing a single latent variable. The pinball visualization is to bring the pinball-analogy to life in the model. It shows how a ball would fall through the model to end up in the right pbosition. This visualization is only appropriate for models with intermediate layers containing a single latent variable. The Finally, we bind these methods to the DeepGP object for ease of calling. Figure: Deep Gaussian process fit to the Della Gatta gene expression data. Figure: Deep Gaussian process samples fitted to the Della Gatta gene expression data. Figure: Gaussian process mapping from input to latent layer for the della Gatta gene expression data. Figure: Gaussian process mapping from latent to output layer for the della Gatta gene expression data. Figure: A pinball plot shows the movement of the ‘ball’ as it passes through each layer of the Gaussian processes. Mean directions of movement are shown by lines. Shading gives one standard deviation of movement position. At each layer, the uncertainty is reset. The overal uncertainty is the cumulative uncertainty from all the layers. Pinball plot of the della Gatta gene expression data. Next we consider a simple step function data set. Figure: Deep Gaussian process fit to the Della Gatta gene expression data. Figure: Deep Gaussian process samples fitted to the Della Gatta gene expression data. Figure: Gaussian process mapping from input to latent layer for the della Gatta gene expression data. Figure: Gaussian process mapping from latent to output layer for the della Gatta gene expression data. Figure: A pinball plot shows the movement of the ‘ball’ as it passes through each layer of the Gaussian processes. Mean directions of movement are shown by lines. Shading gives one standard deviation of movement position. At each layer, the uncertainty is reset. The overal uncertainty is the cumulative uncertainty from all the layers. Pinball plot of the della Gatta gene expression data. Next we consider a simple step function data set. Figure: Simulation study of step function data artificially generated. Here there is a small overlap between the two lines. We can fit a Gaussian process to the step function data using Where The model is optimized using Figure: Gaussian process fit to the step function data. Note the large error bars and the over-smoothing of the discontinuity. Error bars are shown at two standard deviations. The resulting fit to the step function data shows some challenges. In particular, the over smoothing at the discontinuity. If we know how many discontinuities there are, we can parameterize them in the step function. But by doing this, we form a semi-parametric model. The parameters indicate how many discontinuities are, and where they are. They can be optimized as part of the model fit. But if new, unforeseen, discontinuities arise when the model is being deployed in practice, these won’t be accounted for in the predictions. First we initialize a deep Gaussian process with three latent layers (four layers total). Within each layer we create a GP with an exponentiated quadratic covariance ( At each layer we use 20 inducing points for the variational approximation. Figure: Simulation study of step function data artificially generated. Here there is a small overlap between the two lines. We can fit a Gaussian process to the step function data using Where The model is optimized using Figure: Gaussian process fit to the step function data. Note the large error bars and the over-smoothing of the discontinuity. Error bars are shown at two standard deviations. The resulting fit to the step function data shows some challenges. In particular, the over smoothing at the discontinuity. If we know how many discontinuities there are, we can parameterize them in the step function. But by doing this, we form a semi-parametric model. The parameters indicate how many discontinuities are, and where they are. They can be optimized as part of the model fit. But if new, unforeseen, discontinuities arise when the model is being deployed in practice, these won’t be accounted for in the predictions. First we initialize a deep Gaussian process with three latent layers (four layers total). Within each layer we create a GP with an exponentiated quadratic covariance ( At each layer we use 20 inducing points for the variational approximation. Once the model is constructed we initialize the parameters, and perform the staged optimization which starts by optimizing variational parameters with a low noise and proceeds to optimize the whole model. We plot the output of the deep Gaussian process fitted to the step data as follows. The deep Gaussian process does a much better job of fitting the data. It handles the discontinuity easily, and error bars drop to smaller values in the regions of data. Figure: Deep Gaussian process fit to the step function data. The samples of the model can be plotted with the helper function from The samples from the model show that the error bars, which are informative for Gaussian outputs, are less informative for this model. They make clear that the data points lie, in output mainly at 0 or 1, or occasionally in between. Figure: Samples from the deep Gaussian process model for the step function fit. The visualize code allows us to inspect the intermediate layers in the deep GP model to understand how it has reconstructed the step function. Figure: From top to bottom, the Gaussian process mapping function that makes up each layer of the resulting deep Gaussian process. A pinball plot can be created for the resulting model to understand how the input is being translated to the output across the different layers. Figure: Pinball plot of the deep GP fitted to the step function data. Each layer of the model pushes the ‘ball’ towards the left or right, saturating at 1 and 0. This causes the final density to be be peaked at 0 and 1. Transitions occur driven by the uncertainty of the mapping in each layer. Once the model is constructed we initialize the parameters, and perform the staged optimization which starts by optimizing variational parameters with a low noise and proceeds to optimize the whole model. We plot the output of the deep Gaussian process fitted to the step data as follows. The deep Gaussian process does a much better job of fitting the data. It handles the discontinuity easily, and error bars drop to smaller values in the regions of data. Figure: Deep Gaussian process fit to the step function data. The samples of the model can be plotted with the helper function from The samples from the model show that the error bars, which are informative for Gaussian outputs, are less informative for this model. They make clear that the data points lie, in output mainly at 0 or 1, or occasionally in between. Figure: Samples from the deep Gaussian process model for the step function fit. The visualize code allows us to inspect the intermediate layers in the deep GP model to understand how it has reconstructed the step function. Figure: From top to bottom, the Gaussian process mapping function that makes up each layer of the resulting deep Gaussian process. A pinball plot can be created for the resulting model to understand how the input is being translated to the output across the different layers. Figure: Pinball plot of the deep GP fitted to the step function data. Each layer of the model pushes the ‘ball’ towards the left or right, saturating at 1 and 0. This causes the final density to be be peaked at 0 and 1. Transitions occur driven by the uncertainty of the mapping in each layer. Figure: Motorcycle helmet data. The data consists of acceleration readings on a motorcycle helmet undergoing a collision. The data exhibits heteroschedastic (time varying) noise levles and non-stationarity. Figure: Gaussian process fit to the motorcycle helmet accelerometer data. Figure: Motorcycle helmet data. The data consists of acceleration readings on a motorcycle helmet undergoing a collision. The data exhibits heteroschedastic (time varying) noise levles and non-stationarity. Figure: Gaussian process fit to the motorcycle helmet accelerometer data. Figure: Deep Gaussian process fit to the motorcycle helmet accelerometer data. Figure: Samples from the deep Gaussian process as fitted to the motorcycle helmet accelerometer data. Figure: Mappings from the input to the latent layer for the motorcycle helmet accelerometer data. Figure: Mappings from the latent layer to the output layer for the motorcycle helmet accelerometer data. Figure: Pinball plot for the mapping from input to output layer for the motorcycle helmet accelerometer data. For more information on these subjects and more you might want to check the following resources. Figure: Deep Gaussian process fit to the motorcycle helmet accelerometer data. Figure: Samples from the deep Gaussian process as fitted to the motorcycle helmet accelerometer data. Figure: Mappings from the input to the latent layer for the motorcycle helmet accelerometer data. Figure: Mappings from the latent layer to the output layer for the motorcycle helmet accelerometer data. Figure: Pinball plot for the mapping from input to output layer for the motorcycle helmet accelerometer data. For more information on these subjects and more you might want to check the following resources. We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling. We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling. Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. The robot wireless data is taken from an experiment run by Brian Ferris at University of Washington. It consists of the measurements of WiFi access point signal strengths as Brian walked in a loop. It was published at IJCAI in 2007 (Ferris et al., 2007). The ground truth is recorded in the data, the actual loop is given in the plot below. Figure: Ground truth movement for the position taken while recording the multivariate time-course of wireless access point signal strengths. We will ignore this ground truth in making our predictions, but see if the model can recover something similar in one of the latent layers. Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. The robot wireless data is taken from an experiment run by Brian Ferris at University of Washington. It consists of the measurements of WiFi access point signal strengths as Brian walked in a loop. It was published at IJCAI in 2007 (Ferris et al., 2007). The ground truth is recorded in the data, the actual loop is given in the plot below. Figure: Ground truth movement for the position taken while recording the multivariate time-course of wireless access point signal strengths. We will ignore this ground truth in making our predictions, but see if the model can recover something similar in one of the latent layers. One challenge with the data is that the signal strength ‘drops out’. This is because the device only tracks a limited number of wifi access points, when one of the access points falls outside the track, the value disappears (in the plot below it reads -0.5). The data is missing, but it is not missing at random because the implication is that the wireless access point must be weak to have dropped from the list of those that are tracked. Figure: Output dimension 1 from the robot wireless data. This plot shows signal strength changing over time. Perform a Gaussian process fit on the data using GPy. Figure: Gaussian process fit to the Robot Wireless dimension 1. The deep Gaussian process code we are using is research code by Andreas Damianou. To extend the research code we introduce some approaches to initialization and optimization that we’ll use in examples. These approaches live in the Deep Gaussian process models also can require some thought in the initialization. Here we choose to start by setting the noise variance to be one percent of the data variance. Secondly, we introduce a staged optimization approach. Optimization requires moving variational parameters in the hidden layer representing the mean and variance of the expected values in that layer. Since all those values can be scaled up, and this only results in a downscaling in the output of the first GP, and a downscaling of the input length scale to the second GP. It makes sense to first of all fix the scales of the covariance function in each of the GPs. Sometimes, deep Gaussian processes can find a local minima which involves increasing the noise level of one or more of the GPs. This often occurs because it allows a minimum in the KL divergence term in the lower bound on the likelihood. To avoid this minimum we habitually train with the likelihood variance (the noise on the output of the GP) fixed to some lower value for some iterations. Next an optimization of the kernel function parameters at each layer is performed, but with the variance of the likelihood fixed. Again, this is to prevent the model minimizing the Kullback-Leibler divergence between the approximate posterior and the prior before achieving a good data-fit. Finally, all parameters of the model are optimized together. The next code is for visualizing the intermediate layers of the deep model. This visualization is only appropriate for models with intermediate layers containing a single latent variable. The pinball visualization is to bring the pinball-analogy to life in the model. It shows how a ball would fall through the model to end up in the right pbosition. This visualization is only appropriate for models with intermediate layers containing a single latent variable. The Finally, we bind these methods to the DeepGP object for ease of calling. One challenge with the data is that the signal strength ‘drops out.’ This is because the device only tracks a limited number of wifi access points, when one of the access points falls outside the track, the value disappears (in the plot below it reads -0.5). The data is missing, but it is not missing at random because the implication is that the wireless access point must be weak to have dropped from the list of those that are tracked. Figure: Output dimension 1 from the robot wireless data. This plot shows signal strength changing over time. Perform a Gaussian process fit on the data using GPy. Figure: Gaussian process fit to the Robot Wireless dimension 1. The deep Gaussian process code we are using is research code by Andreas Damianou. To extend the research code we introduce some approaches to initialization and optimization that we’ll use in examples. These approaches live in the Deep Gaussian process models also can require some thought in the initialization. Here we choose to start by setting the noise variance to be one percent of the data variance. Secondly, we introduce a staged optimization approach. Optimization requires moving variational parameters in the hidden layer representing the mean and variance of the expected values in that layer. Since all those values can be scaled up, and this only results in a downscaling in the output of the first GP, and a downscaling of the input length scale to the second GP. It makes sense to first of all fix the scales of the covariance function in each of the GPs. Sometimes, deep Gaussian processes can find a local minima which involves increasing the noise level of one or more of the GPs. This often occurs because it allows a minimum in the KL divergence term in the lower bound on the likelihood. To avoid this minimum we habitually train with the likelihood variance (the noise on the output of the GP) fixed to some lower value for some iterations. Next an optimization of the kernel function parameters at each layer is performed, but with the variance of the likelihood fixed. Again, this is to prevent the model minimizing the Kullback-Leibler divergence between the approximate posterior and the prior before achieving a good data-fit. Finally, all parameters of the model are optimized together. The next code is for visualizing the intermediate layers of the deep model. This visualization is only appropriate for models with intermediate layers containing a single latent variable. The pinball visualization is to bring the pinball-analogy to life in the model. It shows how a ball would fall through the model to end up in the right pbosition. This visualization is only appropriate for models with intermediate layers containing a single latent variable. The Finally, we bind these methods to the DeepGP object for ease of calling. Figure: Fit of the deep Gaussian process to dimension 1 of the robot wireless data. Figure: Samples from the deep Gaussian process fit to dimension 1 of the robot wireless data. Figure: Inferred two dimensional latent space from the model for the robot wireless data. This notebook depends on PyDeepGP. This library can be installed via pip. Figure: Fit of the deep Gaussian process to dimension 1 of the robot wireless data. Figure: Samples from the deep Gaussian process fit to dimension 1 of the robot wireless data. Figure: Inferred two dimensional latent space from the model for the robot wireless data. This notebook depends on PyDeepGP. This library can be installed via pip. Image from Wikimedia Commons The Olympic Marathon data is a standard dataset for regression modelling. The data consists of the pace of Olympic Gold Medal Marathon winners for the Olympics from 1896 to present. Let’s load in the data and plot. Image from Wikimedia Commons The Olympic Marathon data is a standard dataset for regression modelling. The data consists of the pace of Olympic Gold Medal Marathon winners for the Olympics from 1896 to present. Let’s load in the data and plot. Figure: Olympic marathon pace times since 1896. Things to notice about the data include the outlier in 1904, in that year the Olympics was in St Louis, USA. Organizational problems and challenges with dust kicked up by the cars following the race meant that participants got lost, and only very few participants completed. More recent years see more consistently quick marathons. Figure: Alan Turing, in 1946 he was only 11 minutes slower than the winner of the 1948 games. Would he have won a hypothetical games held in 1946? Source: Alan Turing Internet Scrapbook. If we had to summarise the objectives of machine learning in one word, a very good candidate for that word would be generalization. What is generalization? From a human perspective it might be summarised as the ability to take lessons learned in one domain and apply them to another domain. If we accept the definition given in the first session for machine learning, \[
+yhat = (y - offset)/scale Figure: Olympic marathon pace times since 1896. Things to notice about the data include the outlier in 1904, in that year the Olympics was in St Louis, USA. Organizational problems and challenges with dust kicked up by the cars following the race meant that participants got lost, and only very few participants completed. More recent years see more consistently quick marathons. Figure: Alan Turing, in 1946 he was only 11 minutes slower than the winner of the 1948 games. Would he have won a hypothetical games held in 1946? Source: Alan Turing Internet Scrapbook. If we had to summarise the objectives of machine learning in one word, a very good candidate for that word would be generalization. What is generalization? From a human perspective it might be summarised as the ability to take lessons learned in one domain and apply them to another domain. If we accept the definition given in the first session for machine learning, \[
\text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}
-\] then we see that without a model we can’t generalise: we only have data. Data is fine for answering very specific questions, like “Who won the Olympic Marathon in 2012?”, because we have that answer stored, however, we are not given the answer to many other questions. For example, Alan Turing was a formidable marathon runner, in 1946 he ran a time 2 hours 46 minutes (just under four minutes per kilometer, faster than I and most of the other Endcliffe Park Run runners can do 5 km). What is the probability he would have won an Olympics if one had been held in 1946? To answer this question we need to generalize, but before we formalize the concept of generalization let’s introduce some formal representation of what it means to generalize in machine learning. Our first objective will be to perform a Gaussian process fit to the data, we’ll do this using the GPy software. The first command sets up the model, then To answer this question we need to generalize, but before we formalize the concept of generalization let’s introduce some formal representation of what it means to generalize in machine learning. Our first objective will be to perform a Gaussian process fit to the data, we’ll do this using the GPy software. The first command sets up the model, then Now we plot the results using the helper function in Figure: Gaussian process fit to the Olympic Marathon data. The error bars are too large, perhaps due to the outlier from 1904. In the fit we see that the error bars (coming mainly from the noise variance) are quite large. This is likely due to the outlier point in 1904, ignoring that point we can see that a tighter fit is obtained. To see this make a version of the model, Now we plot the results using the helper function in Figure: Gaussian process fit to the Olympic Marathon data. The error bars are too large, perhaps due to the outlier from 1904. In the fit we see that the error bars (coming mainly from the noise variance) are quite large. This is likely due to the outlier point in 1904, ignoring that point we can see that a tighter fit is obtained. To see this make a version of the model, Figure: Gaussian process fit to the Olympic Marathon data. Here we’ve removed the outlier from 1904. Let’s see if a deep Gaussian process can help here. We will construct a deep Gaussian process with one hidden layer (i.e. one Gaussian process feeding into another). Build a Deep GP with an additional hidden layer (one dimensional) to fit the model. Figure: Gaussian process fit to the Olympic Marathon data. Here we’ve removed the outlier from 1904. Let’s see if a deep Gaussian process can help here. We will construct a deep Gaussian process with one hidden layer (i.e. one Gaussian process feeding into another). Build a Deep GP with an additional hidden layer (one dimensional) to fit the model. Now optimize the model. Now optimize the model. Figure: Deep GP fit to the Olympic marathon data. Error bars now change as the prediction evolves. Figure: Point samples run through the deep Gaussian process show the distribution of output locations. Now we explore the GPs the model has used to fit each layer. First of all, we look at the hidden layer. Figure: The mapping from input to the latent layer is broadly, with some flattening as time goes on. Variance is high across the input range. Figure: The mapping from the latent layer to the output layer. Figure: A pinball plot shows the movement of the ‘ball’ as it passes through each layer of the Gaussian processes. Mean directions of movement are shown by lines. Shading gives one standard deviation of movement position. At each layer, the uncertainty is reset. The overal uncertainty is the cumulative uncertainty from all the layers. There is some grouping of later points towards the right in the first layer, which also injects a large amount of uncertainty. Due to flattening of the curve in the second layer towards the right the uncertainty is reduced in final output. The pinball plot shows the flow of any input ball through the deep Gaussian process. In a pinball plot a series of vertical parallel lines would indicate a purely linear function. For the olypmic marathon data we can see the first layer begins to shift from input towards the right. Note it also does so with some uncertainty (indicated by the shaded backgrounds). The second layer has less uncertainty, but bunches the inputs more strongly to the right. This input layer of uncertainty, followed by a layer that pushes inputs to the right is what gives the heteroschedastic noise. We now consider an example in gene expression. Gene expression is the measurement of mRNA levels expressed in cells. These mRNA levels show which genes are ‘switched on’ and producing data. In the example we will use a Gaussian process to determine whether a given gene is active, or we are merely observing a noise response. Figure: Deep GP fit to the Olympic marathon data. Error bars now change as the prediction evolves. Figure: Point samples run through the deep Gaussian process show the distribution of output locations. Now we explore the GPs the model has used to fit each layer. First of all, we look at the hidden layer. Figure: The mapping from input to the latent layer is broadly, with some flattening as time goes on. Variance is high across the input range. Figure: The mapping from the latent layer to the output layer. Figure: A pinball plot shows the movement of the ‘ball’ as it passes through each layer of the Gaussian processes. Mean directions of movement are shown by lines. Shading gives one standard deviation of movement position. At each layer, the uncertainty is reset. The overal uncertainty is the cumulative uncertainty from all the layers. There is some grouping of later points towards the right in the first layer, which also injects a large amount of uncertainty. Due to flattening of the curve in the second layer towards the right the uncertainty is reduced in final output. The pinball plot shows the flow of any input ball through the deep Gaussian process. In a pinball plot a series of vertical parallel lines would indicate a purely linear function. For the olypmic marathon data we can see the first layer begins to shift from input towards the right. Note it also does so with some uncertainty (indicated by the shaded backgrounds). The second layer has less uncertainty, but bunches the inputs more strongly to the right. This input layer of uncertainty, followed by a layer that pushes inputs to the right is what gives the heteroschedastic noise. We now consider an example in gene expression. Gene expression is the measurement of mRNA levels expressed in cells. These mRNA levels show which genes are ‘switched on’ and producing data. In the example we will use a Gaussian process to determine whether a given gene is active, or we are merely observing a noise response. Figure: Gene expression levels over time for a gene from data provided by Della Gatta et al. (2008). We would like to understand whether there is signal in the data, or we are only observing noise. Figure: The example is taken from the paper “A Simple Approach to Ranking Differentially Expressed Gene Expression Time Courses through Gaussian Process Regression.” Kalaitzis and Lawrence (2011). Our first objective will be to perform a Gaussian process fit to the data, we’ll do this using the GPy software. Figure: Gene expression levels over time for a gene from data provided by Della Gatta et al. (2008). We would like to understand whether there is signal in the data, or we are only observing noise. Figure: The example is taken from the paper “A Simple Approach to Ranking Differentially Expressed Gene Expression Time Courses through Gaussian Process Regression.” Kalaitzis and Lawrence (2011). Our first objective will be to perform a Gaussian process fit to the data, we’ll do this using the GPy software. Initialize the length scale parameter (which here actually represents a time scale of the covariance function) to a reasonable value. Default would be 1, but here we set it to 50 minutes, given points are arriving across zero to 250 minutes. Initialize the length scale parameter (which here actually represents a time scale of the covariance function) to a reasonable value. Default would be 1, but here we set it to 50 minutes, given points are arriving across zero to 250 minutes. Now we plot the results using the helper function in Figure: Result of the fit of the Gaussian process model with the time scale parameter initialized to 50 minutes. Now we try a model initialized with a longer length scale. Now we plot the results using the helper function in Figure: Result of the fit of the Gaussian process model with the time scale parameter initialized to 50 minutes. Now we try a model initialized with a longer length scale. Figure: Result of the fit of the Gaussian process model with the time scale parameter initialized to 2000 minutes. Now we try a model initialized with a lower noise. Figure: Result of the fit of the Gaussian process model with the time scale parameter initialized to 2000 minutes. Now we try a model initialized with a lower noise. Figure: Result of the fit of the Gaussian process model with the noise initialized low (standard deviation 0.1) and the time scale parameter initialized to 20 minutes. Figure: Figure: Deep Gaussian process fit to the Della Gatta gene expression data. Figure: Deep Gaussian process samples fitted to the Della Gatta gene expression data. Figure: Gaussian process mapping from input to latent layer for the della Gatta gene expression data. Figure: Gaussian process mapping from latent to output layer for the della Gatta gene expression data. Figure: A pinball plot shows the movement of the ‘ball’ as it passes through each layer of the Gaussian processes. Mean directions of movement are shown by lines. Shading gives one standard deviation of movement position. At each layer, the uncertainty is reset. The overal uncertainty is the cumulative uncertainty from all the layers. Pinball plot of the della Gatta gene expression data. Next we consider a simple step function data set. Figure: Deep Gaussian process fit to the Della Gatta gene expression data. Figure: Deep Gaussian process samples fitted to the Della Gatta gene expression data. Figure: Gaussian process mapping from input to latent layer for the della Gatta gene expression data. Figure: Gaussian process mapping from latent to output layer for the della Gatta gene expression data. Figure: A pinball plot shows the movement of the ‘ball’ as it passes through each layer of the Gaussian processes. Mean directions of movement are shown by lines. Shading gives one standard deviation of movement position. At each layer, the uncertainty is reset. The overal uncertainty is the cumulative uncertainty from all the layers. Pinball plot of the della Gatta gene expression data. Next we consider a simple step function data set. Figure: Simulation study of step function data artificially generated. Here there is a small overlap between the two lines. We can fit a Gaussian process to the step function data using Where The model is optimized using Figure: Gaussian process fit to the step function data. Note the large error bars and the over-smoothing of the discontinuity. Error bars are shown at two standard deviations. The resulting fit to the step function data shows some challenges. In particular, the over smoothing at the discontinuity. If we know how many discontinuities there are, we can parameterize them in the step function. But by doing this, we form a semi-parametric model. The parameters indicate how many discontinuities are, and where they are. They can be optimized as part of the model fit. But if new, unforeseen, discontinuities arise when the model is being deployed in practice, these won’t be accounted for in the predictions. First we initialize a deep Gaussian process with three latent layers (four layers total). Within each layer we create a GP with an exponentiated quadratic covariance ( At each layer we use 20 inducing points for the variational approximation. Figure: Simulation study of step function data artificially generated. Here there is a small overlap between the two lines. We can fit a Gaussian process to the step function data using Where The model is optimized using Figure: Gaussian process fit to the step function data. Note the large error bars and the over-smoothing of the discontinuity. Error bars are shown at two standard deviations. The resulting fit to the step function data shows some challenges. In particular, the over smoothing at the discontinuity. If we know how many discontinuities there are, we can parameterize them in the step function. But by doing this, we form a semi-parametric model. The parameters indicate how many discontinuities are, and where they are. They can be optimized as part of the model fit. But if new, unforeseen, discontinuities arise when the model is being deployed in practice, these won’t be accounted for in the predictions. First we initialize a deep Gaussian process with three latent layers (four layers total). Within each layer we create a GP with an exponentiated quadratic covariance ( At each layer we use 20 inducing points for the variational approximation. Once the model is constructed we initialize the parameters, and perform the staged optimization which starts by optimizing variational parameters with a low noise and proceeds to optimize the whole model. We plot the output of the deep Gaussian process fitted to the step data as follows. The deep Gaussian process does a much better job of fitting the data. It handles the discontinuity easily, and error bars drop to smaller values in the regions of data. Figure: Deep Gaussian process fit to the step function data. The samples of the model can be plotted with the helper function from The samples from the model show that the error bars, which are informative for Gaussian outputs, are less informative for this model. They make clear that the data points lie, in output mainly at 0 or 1, or occasionally in between. Figure: Samples from the deep Gaussian process model for the step function fit. The visualize code allows us to inspect the intermediate layers in the deep GP model to understand how it has reconstructed the step function. Figure: From top to bottom, the Gaussian process mapping function that makes up each layer of the resulting deep Gaussian process. A pinball plot can be created for the resulting model to understand how the input is being translated to the output across the different layers. Figure: Pinball plot of the deep GP fitted to the step function data. Each layer of the model pushes the ‘ball’ towards the left or right, saturating at 1 and 0. This causes the final density to be be peaked at 0 and 1. Transitions occur driven by the uncertainty of the mapping in each layer. Once the model is constructed we initialize the parameters, and perform the staged optimization which starts by optimizing variational parameters with a low noise and proceeds to optimize the whole model. We plot the output of the deep Gaussian process fitted to the step data as follows. The deep Gaussian process does a much better job of fitting the data. It handles the discontinuity easily, and error bars drop to smaller values in the regions of data. Figure: Deep Gaussian process fit to the step function data. The samples of the model can be plotted with the helper function from The samples from the model show that the error bars, which are informative for Gaussian outputs, are less informative for this model. They make clear that the data points lie, in output mainly at 0 or 1, or occasionally in between. Figure: Samples from the deep Gaussian process model for the step function fit. The visualize code allows us to inspect the intermediate layers in the deep GP model to understand how it has reconstructed the step function. Figure: From top to bottom, the Gaussian process mapping function that makes up each layer of the resulting deep Gaussian process. A pinball plot can be created for the resulting model to understand how the input is being translated to the output across the different layers. Figure: Pinball plot of the deep GP fitted to the step function data. Each layer of the model pushes the ‘ball’ towards the left or right, saturating at 1 and 0. This causes the final density to be be peaked at 0 and 1. Transitions occur driven by the uncertainty of the mapping in each layer. Figure: Motorcycle helmet data. The data consists of acceleration readings on a motorcycle helmet undergoing a collision. The data exhibits heteroschedastic (time varying) noise levles and non-stationarity. Figure: Gaussian process fit to the motorcycle helmet accelerometer data. Figure: Motorcycle helmet data. The data consists of acceleration readings on a motorcycle helmet undergoing a collision. The data exhibits heteroschedastic (time varying) noise levles and non-stationarity. Figure: Gaussian process fit to the motorcycle helmet accelerometer data. Figure: Deep Gaussian process fit to the motorcycle helmet accelerometer data. Figure: Samples from the deep Gaussian process as fitted to the motorcycle helmet accelerometer data. Figure: Mappings from the input to the latent layer for the motorcycle helmet accelerometer data. Figure: Mappings from the latent layer to the output layer for the motorcycle helmet accelerometer data. Figure: Pinball plot for the mapping from input to output layer for the motorcycle helmet accelerometer data. Motion capture data from the CMU motion capture data base (CMU Motion Capture Lab, 2003). It contains two subjects approaching each other and executing a ‘high five’. The subjects are number 10 and 11 and their motion numbers are 21. The data dictionary contains the keys ‘Y1’ and ‘Y2’, which represent the motions of the two different subjects. Their skeleton files are included in the keys ‘skel1’ and ‘skel2’. The data was used in the hierarchical GP-LVM paper (Lawrence and Moore, 2007) in an experiment that was also recreated in the Deep Gaussian process paper (Damianou and Lawrence, 2013). And extra information about the data is included, as standard, under the keys Figure: Deep Gaussian process fit to the motorcycle helmet accelerometer data. Figure: Samples from the deep Gaussian process as fitted to the motorcycle helmet accelerometer data. Figure: Mappings from the input to the latent layer for the motorcycle helmet accelerometer data. Figure: Mappings from the latent layer to the output layer for the motorcycle helmet accelerometer data. Figure: Pinball plot for the mapping from input to output layer for the motorcycle helmet accelerometer data. Motion capture data from the CMU motion capture data base (CMU Motion Capture Lab, 2003). It contains two subjects approaching each other and executing a ‘high five.’ The subjects are number 10 and 11 and their motion numbers are 21. The data dictionary contains the keys ‘Y1’ and ‘Y2,’ which represent the motions of the two different subjects. Their skeleton files are included in the keys ‘skel1’ and ‘skel2.’ The data was used in the hierarchical GP-LVM paper (Lawrence and Moore, 2007) in an experiment that was also recreated in the Deep Gaussian process paper (Damianou and Lawrence, 2013). And extra information about the data is included, as standard, under the keys Figure: Latent spaces of the ‘high five’ data. The structure of the model is automatically learnt. One of the latent spaces is coordinating how the two figures walk together, the other latent spaces contain latent variables that are specific to each of the figures separately. We will look at a sub-sample of the MNIST digit data set. THE MNIST DATABASE of handwritten digits was created by Yann LeCun, Corinna Cortes and Christopher J. C. Burges. More details can be found at Yann’s site http://yann.lecun.com/exdb/mnist/ The data is a modified version of a data set from the US National Institute of Standards and Technology (NIST. First load in the MNIST data set from scikit learn. This can take a little while because it’s large to download. Sub-sample the dataset to make the training faster. Figure: Latent spaces of the ‘high five’ data. The structure of the model is automatically learnt. One of the latent spaces is coordinating how the two figures walk together, the other latent spaces contain latent variables that are specific to each of the figures separately. We will look at a sub-sample of the MNIST digit data set. THE MNIST DATABASE of handwritten digits was created by Yann LeCun, Corinna Cortes and Christopher J. C. Burges. More details can be found at Yann’s site http://yann.lecun.com/exdb/mnist/ The data is a modified version of a data set from the US National Institute of Standards and Technology (NIST. First load in the MNIST data set from scikit learn. This can take a little while because it’s large to download. Sub-sample the dataset to make the training faster. Now let’s visualise some examples from our subsampled dataset to get a sense of what the data looks like. Figure: Examples of MNIST digits 0-4 from our subsampled dataset, showing 5 examples of each digit. The visualization shows the variety in handwritten digits even within the same class. Each row represents a different digit (0 through 4), and each column shows a different example of that digit. We now look at the deep Gaussian processes’ capacity to perform unsupervised learning. We’re going to fit a Deep Gaussian process model to the MNIST data with two hidden layers. Each of the two Gaussian processes (one from the first hidden layer to the second, one from the second hidden layer to the data) has an exponentiated quadratic covariance. Now let’s visualise some examples from our subsampled dataset to get a sense of what the data looks like. Figure: Examples of MNIST digits 0-4 from our subsampled dataset, showing 5 examples of each digit. The visualization shows the variety in handwritten digits even within the same class. Each row represents a different digit (0 through 4), and each column shows a different example of that digit. We now look at the deep Gaussian processes’ capacity to perform unsupervised learning. We’re going to fit a Deep Gaussian process model to the MNIST data with two hidden layers. Each of the two Gaussian processes (one from the first hidden layer to the second, one from the second hidden layer to the data) has an exponentiated quadratic covariance. Just like deep neural networks, there are some tricks to intitializing these models. The tricks we use here include some early training of the model with model parameters constrained. This gives the variational inducing parameters some scope to tighten the bound for the case where the noise variance is small and the variances of the Gaussian processes are around 1. Just like deep neural networks, there are some tricks to intitializing these models. The tricks we use here include some early training of the model with model parameters constrained. This gives the variational inducing parameters some scope to tighten the bound for the case where the noise variance is small and the variances of the Gaussian processes are around 1. We now we optimize for a hundred iterations with the constrained model. Now we remove the fixed constraint on the kernel variance parameters, but keep the noise output constrained, and run for a further 100 iterations. We now we optimize for a hundred iterations with the constrained model. Now we remove the fixed constraint on the kernel variance parameters, but keep the noise output constrained, and run for a further 100 iterations. Finally we unconstrain the layer likelihoods and allow the full model to be trained for 1000 iterations. Finally we unconstrain the layer likelihoods and allow the full model to be trained for 1000 iterations. Now the model is trained, let’s plot the mean of the posterior distributions in the top latent layer of the model. Figure: Latent space for the deep Gaussian process learned through unsupervised learning and fitted to a subset of the MNIST digits subsample. We can also visualize dimensions of the intermediate layer. First the lengthscale of those dimensions is given by Now we can take a look at a sample from the model, by drawing a Gaussian random sample in the latent space and propagating it through the model. Now the model is trained, let’s plot the mean of the posterior distributions in the top latent layer of the model. Figure: Latent space for the deep Gaussian process learned through unsupervised learning and fitted to a subset of the MNIST digits subsample. We can also visualize dimensions of the intermediate layer. First the lengthscale of those dimensions is given by Now we can take a look at a sample from the model, by drawing a Gaussian random sample in the latent space and propagating it through the model. Figure: These digits are produced by taking a tour of the two dimensional latent space (as described by a Gaussian process sample) and mapping the tour into the data space. We visualize the mean of the mapping in the images. Figure: The deep health model uses different layers of abstraction in the deep Gaussian process to represent information about diagnostics and treatment to model interelationships between a patients different data modalities. From a machine learning perspective, we’d like to be able to interrelate all the different modalities that are informative about the state of the disease. For deep health, the notion is that the state of the disease is appearing at the more abstract levels, as we descend the model, we express relationships between the more abstract concept, that sits within the physician’s mind, and the data we can measure. For more information on these subjects and more you might want to check the following resources. Figure: These digits are produced by taking a tour of the two dimensional latent space (as described by a Gaussian process sample) and mapping the tour into the data space. We visualize the mean of the mapping in the images. Figure: The deep health model uses different layers of abstraction in the deep Gaussian process to represent information about diagnostics and treatment to model interelationships between a patients different data modalities. From a machine learning perspective, we’d like to be able to interrelate all the different modalities that are informative about the state of the disease. For deep health, the notion is that the state of the disease is appearing at the more abstract levels, as we descend the model, we express relationships between the more abstract concept, that sits within the physician’s mind, and the data we can measure. For more information on these subjects and more you might want to check the following resources. We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling. We install packages used across the notebooks for data loading, plotting helpers, and Gaussian process modelling. Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. We may regard the present state of the universe as the effect of its past and the cause of its future. An intellect which at a certain moment would know all forces that set nature in motion, and all positions of all items of which nature is composed, … … if this intellect were also vast enough to submit these data to analysis, it would embrace in a single formula the movements of the greatest bodies of the universe and those of the tiniest atom; for such an intellect nothing would be uncertain and the future just like the past would be present before its eyes. — Pierre Simon Laplace (Laplace, 1814) John Horton Conway was a mathematician who developed a game known as the Game of Life. He died in April 2020, but since he invented the game, he was in effect ‘god’ for this game. But as we will see, just inventing the rules doesn’t give you omniscience in the game. The Game of Life is played on a grid of squares, or pixels. Each pixel is either on or off. The game has no players, but a set of simple rules that are followed at each turn the rules are. Cellular automata are systems of cells that evolve according to fixed rules. The rules depend on the current state of cells and their neighbors. We’ll explore both one-dimensional (Wolfram) and two-dimensional (Conway) cellular automata. First, we’ll set up some base functionality that both types share. These base classes and functions provide: We’ll build on this foundation to implement both Wolfram’s elementary one dimensional cellular automata and later Conway’s two dimensional Game of Life. These diagram generation functions maintain consistent styling while providing specialized visualizations for: They work with the base Grid class but provide custom layouts specific to teaching and explaining the rules of each system. John Conway’s game of life is a cellular automaton where the cells obey three very simple rules. The cells live on a rectangular grid, so that each cell has 8 possible neighbors. Figure: ‘Death’ through loneliness in Conway’s game of life. If a cell is surrounded by less than three cells, it ‘dies’ through loneliness. The game proceeds in turns, and at each location in the grid is either alive or dead. Each turn, a cell counts its neighbors. If there are two or fewer neighbors, the cell ‘dies’ of ‘loneliness’. Figure: ‘Death’ through overpopulation in Conway’s game of life. If a cell is surrounded by more than three cells, it ‘dies’ through loneliness. If there are four or more neighbors, the cell ‘dies’ from ‘overcrowding’. If there are three neighbors, the cell persists, or if it is currently dead, a new cell is born. Figure: Birth in Conway’s life. Any position surrounded by precisely three live cells will give birth to a new cell at the next turn. And that’s it. Those are the simple ‘physical laws’ for Conway’s game. Now that we understand the rules of Life, let’s implement them. Each cell’s fate is determined by counting its eight neighbors and applying Conway’s rules. The implementation above provides: 1. Neighbor counting with different boundary conditions 2. Rule application following Conway’s specifications 3. Support for both periodic and fixed boundaries 4. History tracking for visualization 5. Flexible initial state configuration This base implementation will be essential when we combine it with Wolfram automata, as we’ll need to modify the boundary conditions to interact with the Wolfram rules. Figure: Evolution of a simple oscillator (blinker) in the Game of Life. This implementation will serve as the foundation for our exploration of Life patterns and ultimately for our hybrid system combining Life with Wolfram automata. The key is the flexibility in boundary conditions, which will allow us to interface with Wolfram rules at the edges. The game leads to patterns emerging, some of these patterns are static, but some oscillate in place, with varying periods. Others oscillate, but when they complete their cycle they’ve translated to a new location, in other words they move. In Life the former are known as oscillators and the latter as spaceships. Before looking at specific examples, let’s understand how these patterns behave. Life patterns can be classified by their periodic behavior and movement: - Static patterns remain unchanged from one generation to the next - Oscillators return to their initial state after a fixed number of generations (their period) - Spaceships combine oscillation with translation, moving across the grid while cycling through their states Each pattern can be characterized by: - Its period (how many steps before it repeats) - Its translation (how far it moves each period) - Its velocity (translation per period) Figure: Left A Glider pattern discovered 1969 by Richard K. Guy. Right. John Horton Conway, creator of Life (1937-2020). The glider is an oscillator that moves diagonally after creation. The glider was ‘discovered’ in 1969 by Richard K. Guy. What do we mean by discovered in this context? Well, as soon as the game of life is defined, objects such as the glider do somehow exist, but the many configurations of the game mean that it takes some time for us to see one and know it exists. This means, that despite being the creator, Conway, and despite the rules of the game being simple, and despite the rules being deterministic, we are not ‘omniscient’ in any simplistic sense. It requires computation to ‘discover’ what can exist in this universe once it’s been defined. Figure: The Gosper glider gun is a configuration that creates gliders. A new glider is released after every 30 turns. These patterns had to be discovered, in the same way that a scientist might discover a disease, or an explorer a new land. For example, the Gosper glider gun was discovered by Bill Gosper in 1970. It is a pattern that creates a new glider every 30 turns of the game. Figure: Left A Loafer pattern discovered by Josh Ball in 2013. Right. John Horton Conway, creator of Life (1937-2020). Despite widespread interest in Life, some of its patterns were only very recently discovered like the Loafer, discovered in 2013 by Josh Ball. So, despite the game having existed for over forty years, and the rules of the game being simple, there are emergent behaviors that are unknown. Once these patterns are discovered, they are combined (or engineered) to create new Life patterns that do some remarkable things. For example, there’s a life pattern that runs a Turing machine, or more remarkably there’s a Life pattern that runs Life itself. Figure: The Game of Life running in Life. The video is drawing out recursively showing pixels that are being formed by filling cells with moving spaceships. Each individual pixel in this game of life is made up of \(2048 \times 2048\) pixels called an OTCA metapixel. To find out more about the Game of Life you can watch this video by Alan Zucconi or read his associated blog post. Figure: An introduction to the Game of Life by Alan Zucconi. Contrast this with our situation where in ‘real life’ we don’t know the simple rules of the game, the state space is larger, and emergent behaviors (hurricanes, earthquakes, volcanos, climate change) have direct consequences for our daily lives, and we understand why the process of ‘understanding’ the physical world is so difficult. We also see immediately how much easier we might expect the physical sciences to be than the social sciences, where the emergent behaviors are contingent on highly complex human interactions. We summarize this notion as \[
+sns.set_palette('colorblind')}--> Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics. Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries. The software itself is available on GitHub and the team welcomes contributions. The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets. The documentation for GPy can be found here. We may regard the present state of the universe as the effect of its past and the cause of its future. An intellect which at a certain moment would know all forces that set nature in motion, and all positions of all items of which nature is composed, … … if this intellect were also vast enough to submit these data to analysis, it would embrace in a single formula the movements of the greatest bodies of the universe and those of the tiniest atom; for such an intellect nothing would be uncertain and the future just like the past would be present before its eyes. — Pierre Simon Laplace (Laplace, 1814) John Horton Conway was a mathematician who developed a game known as the Game of Life. He died in April 2020, but since he invented the game, he was in effect ‘god’ for this game. But as we will see, just inventing the rules doesn’t give you omniscience in the game. The Game of Life is played on a grid of squares, or pixels. Each pixel is either on or off. The game has no players, but a set of simple rules that are followed at each turn the rules are. Cellular automata are systems of cells that evolve according to fixed rules. The rules depend on the current state of cells and their neighbors. We’ll explore both one-dimensional (Wolfram) and two-dimensional (Conway) cellular automata. First, we’ll set up some base functionality that both types share. These base classes and functions provide: We’ll build on this foundation to implement both Wolfram’s elementary one dimensional cellular automata and later Conway’s two dimensional Game of Life. These diagram generation functions maintain consistent styling while providing specialized visualizations for: They work with the base Grid class but provide custom layouts specific to teaching and explaining the rules of each system. John Conway’s game of life is a cellular automaton where the cells obey three very simple rules. The cells live on a rectangular grid, so that each cell has 8 possible neighbors. Figure: ‘Death’ through loneliness in Conway’s game of life. If a cell is surrounded by less than three cells, it ‘dies’ through loneliness. The game proceeds in turns, and at each location in the grid is either alive or dead. Each turn, a cell counts its neighbors. If there are two or fewer neighbors, the cell ‘dies’ of ‘loneliness.’ Figure: ‘Death’ through overpopulation in Conway’s game of life. If a cell is surrounded by more than three cells, it ‘dies’ through loneliness. If there are four or more neighbors, the cell ‘dies’ from ‘overcrowding.’ If there are three neighbors, the cell persists, or if it is currently dead, a new cell is born. Figure: Birth in Conway’s life. Any position surrounded by precisely three live cells will give birth to a new cell at the next turn. And that’s it. Those are the simple ‘physical laws’ for Conway’s game. Now that we understand the rules of Life, let’s implement them. Each cell’s fate is determined by counting its eight neighbors and applying Conway’s rules. The implementation above provides: 1. Neighbor counting with different boundary conditions 2. Rule application following Conway’s specifications 3. Support for both periodic and fixed boundaries 4. History tracking for visualization 5. Flexible initial state configuration This base implementation will be essential when we combine it with Wolfram automata, as we’ll need to modify the boundary conditions to interact with the Wolfram rules. Figure: Evolution of a simple oscillator (blinker) in the Game of Life. This implementation will serve as the foundation for our exploration of Life patterns and ultimately for our hybrid system combining Life with Wolfram automata. The key is the flexibility in boundary conditions, which will allow us to interface with Wolfram rules at the edges. The game leads to patterns emerging, some of these patterns are static, but some oscillate in place, with varying periods. Others oscillate, but when they complete their cycle they’ve translated to a new location, in other words they move. In Life the former are known as oscillators and the latter as spaceships. Before looking at specific examples, let’s understand how these patterns behave. Life patterns can be classified by their periodic behavior and movement: - Static patterns remain unchanged from one generation to the next - Oscillators return to their initial state after a fixed number of generations (their period) - Spaceships combine oscillation with translation, moving across the grid while cycling through their states Each pattern can be characterized by: - Its period (how many steps before it repeats) - Its translation (how far it moves each period) - Its velocity (translation per period) Figure: Left A Glider pattern discovered 1969 by Richard K. Guy. Right. John Horton Conway, creator of Life (1937-2020). The glider is an oscillator that moves diagonally after creation. The glider was ‘discovered’ in 1969 by Richard K. Guy. What do we mean by discovered in this context? Well, as soon as the game of life is defined, objects such as the glider do somehow exist, but the many configurations of the game mean that it takes some time for us to see one and know it exists. This means, that despite being the creator, Conway, and despite the rules of the game being simple, and despite the rules being deterministic, we are not ‘omniscient’ in any simplistic sense. It requires computation to ‘discover’ what can exist in this universe once it’s been defined. Figure: The Gosper glider gun is a configuration that creates gliders. A new glider is released after every 30 turns. These patterns had to be discovered, in the same way that a scientist might discover a disease, or an explorer a new land. For example, the Gosper glider gun was discovered by Bill Gosper in 1970. It is a pattern that creates a new glider every 30 turns of the game. Figure: Left A Loafer pattern discovered by Josh Ball in 2013. Right. John Horton Conway, creator of Life (1937-2020). Despite widespread interest in Life, some of its patterns were only very recently discovered like the Loafer, discovered in 2013 by Josh Ball. So, despite the game having existed for over forty years, and the rules of the game being simple, there are emergent behaviors that are unknown. Once these patterns are discovered, they are combined (or engineered) to create new Life patterns that do some remarkable things. For example, there’s a life pattern that runs a Turing machine, or more remarkably there’s a Life pattern that runs Life itself. Figure: The Game of Life running in Life. The video is drawing out recursively showing pixels that are being formed by filling cells with moving spaceships. Each individual pixel in this game of life is made up of \(2048 \times 2048\) pixels called an OTCA metapixel. To find out more about the Game of Life you can watch this video by Alan Zucconi or read his associated blog post. Figure: An introduction to the Game of Life by Alan Zucconi. Contrast this with our situation where in ‘real life’ we don’t know the simple rules of the game, the state space is larger, and emergent behaviors (hurricanes, earthquakes, volcanos, climate change) have direct consequences for our daily lives, and we understand why the process of ‘understanding’ the physical world is so difficult. We also see immediately how much easier we might expect the physical sciences to be than the social sciences, where the emergent behaviors are contingent on highly complex human interactions. We summarize this notion as \[
\text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}
-\] As we pointed out, there is an irony in Laplace’s demon forming the cornerstone of a movement known as ‘determinism’, because Laplace wrote about this idea in an essay on probabilities. The more important quote in the essay was The curve described by a simple molecule of air or vapor is regulated in a manner just as certain as the planetary orbits; the only difference between them is that which comes from our ignorance. Probability is relative, in part to this ignorance, in part to our knowledge. We know that of three or greater number of events a single one ought to occur; but nothing induces us to believe that one of them will occur rather than the others. In this state of indecision it is impossible for us to announce their occurrence with certainty. It is, however, probable that one of these events, chosen at will, will not occur because we see several cases equally possible which exclude its occurrence, while only a single one favors it. — Pierre-Simon Laplace (Laplace, 1814), pg 5 The representation of ignorance through probability is the true message of Laplace, I refer to this message as “Laplace’s gremlin”, because it is the gremlin of uncertainty that interferes with the demon of determinism to mean that our predictions are not deterministic. Our separation of the uncertainty into the data, the model and the computation give us three domains in which our doubts can creep into our ability to predict. Over the last three lectures we’ve introduced some of the basic tools we can use to unpick this uncertainty. You’ve been introduced to, (or have yow reviewed) Bayes’ rule. The rule, which is a simple consequence of the product rule of probability, is the foundation of how we update our beliefs in the presence of new information. The real point of Laplace’s essay was that we don’t have access to all the data, we don’t have access to a complete physical understanding, and as the example of the Game of Life shows, even if we did have access to both (as we do for “Conway’s universe”) we still don’t have access to all the compute that we need to make deterministic predictions. There is uncertainty in the system which means we can’t make precise predictions. Gremlins are imaginary creatures used as an explanation of failure in aircraft, causing crashes. In that sense the Gremlin represents the uncertainty that a pilot felt about what might go wrong in a plane which might be “theoretically sound” but in practice is poorly maintained or exposed to conditions that take it beyond its design criteria. Laplace’s gremlin is all the things that your model, data and ability to compute don’t account for bringing about failures in your ability to predict. Laplace’s gremlin is the uncertainty in the system. Figure: Gremlins are seen as the cause of a number of challenges in this World War II poster. An example of a complex decision-making system might be a climate model, in such a system there are separate models for the atmosphere, the ocean and the land. The components of these systems include flowing of currents, chemical interactions in the upper atmosphere, evaporation of water etc.. Figure: Representation of the Carbon Cycle from the US National Oceanic and Atmospheric Administration. While everything is interconnected in the system, we can decompose into separate models for atmosphere, ocean, land. The influence of human activity also needs to be incorporated and modelled so we can make judgments about how to mitigate the effects of global warming. Figure: The components of a simulation system for climate modelling. The classical approach to building these systems was a ‘monolithic system’. Built in a similar way to the successful applications software such as Excel or Word, or large operating systems, a single code base was constructed. The complexity of such code bases run to many lines. In practice, shared dynamically linked libraries may be used for aspects such as user interface, or networking, but the software often has many millions of lines of code. For example, the Microsoft Office suite is said to contain over 30 million lines of code. Figure: A potential path of models in a machine learning system. Such software is not only difficult to develop, but also to scale when computation demands increase. For example, Amazon’s original website software (called Obidos) was a monolithic design but by the early noughties it was becoming difficult to sustain and maintain. The software was phased out in 2006 to be replaced by a modularized software known as a ‘service-oriented architecture’. In Service Oriented Architecture, or “Software as a Service” the idea is that code bases are modularized and communicate with one another using network requests. A standard approach is to use a REST API. So, rather than a single monolithic code base, the code is developed with individual services that handle the different requests. The simulation software is turned inside out to expose the individual components to the operator. Figure: A potential path of models in a machine learning system. This is the landscape we now find ourselves in for software development. In practice, each of these services is often ‘owned’ and maintained by an individual team. The team is judged by the quality of their service provision. They work to detailed specifications on what their service should output, what its availability should be and other objectives like speed of response. This allows for conditional independence between teams and for faster development. One question is to what extent is the same approach possible/desirable for scientific models? The components we listed above are already separated and often run independently. But those components themselves are made up of other sub-components that could also be exposed in a similar manner to software-as-a-service, giving us the notion of “simulation as a service”. One thing about working in an industrial environment, is the way that short-term thinking actions become important. For example, in Formula One, the teams are working on a two-week cycle to digest information from the previous week’s race and incorporate updates to the car or their strategy. However, businesses must also think about more medium-term horizons. For example, in Formula 1 you need to worry about next year’s car. So, while you’re working on updating this year’s car, you also need to think about what will happen for next year and prioritize these conflicting needs appropriately. In the Amazon supply chain, there are equivalent demands. If we accept that an artificial intelligence is just an automated decision-making system. And if we measure in terms of money automatically spent, or goods automatically moved, then Amazon’s buying system is perhaps the world’s largest AI. Those decisions are being made on short time schedules; purchases are made by the system on weekly cycles. But just as in Formula 1, there is also a need to think about what needs to be done next month, next quarter and next year. Planning meetings are held not only on a weekly basis (known as weekly business reviews), but monthly, quarterly, and then yearly meetings for planning spends and investments. Amazon is known for being longer term thinking than many companies, and a lot of this is coming from the CEO. One quote from Jeff Bezos that stuck with me was the following. “I very frequently get the question: ‘What’s going to change in the next 10 years?’ And that is a very interesting question; it’s a very common one. I almost never get the question: ‘What’s not going to change in the next 10 years?’ And I submit to you that that second question is actually the more important of the two – because you can build a business strategy around the things that are stable in time. … [I]n our retail business, we know that customers want low prices, and I know that’s going to be true 10 years from now. They want fast delivery; they want vast selection. It’s impossible to imagine a future 10 years from now where a customer comes up and says, ‘Jeff I love Amazon; I just wish the prices were a little higher,’ [or] ‘I love Amazon; I just wish you’d deliver a little more slowly.’ Impossible. And so the effort we put into those things, spinning those things up, we know the energy we put into it today will still be paying off dividends for our customers 10 years from now. When you have something that you know is true, even over the long term, you can afford to put a lot of energy into it.” This quote is incredibly important for long term thinking. Indeed, it’s a failure of many of our simulations that they focus on what is going to happen, not what will not happen. In Amazon, this meant that there was constant focus on these three areas, keeping costs low, making delivery fast and improving selection. For example, shortly before I left Amazon moved its entire US network from two-day delivery to one-day delivery. This involves changing the way the entire buying system operates. Or, more recently, the company has had to radically change the portfolio of products it buys in the face of Covid19. Figure: Experiment, analyze and design is a flywheel of knowledge that is the dual of the model, data and compute. By running through this spiral, we refine our hypothesis/model and develop new experiments which can be analyzed to further refine our hypothesis. From the perspective of the team that we had in the supply chain, we looked at what we most needed to focus on. Amazon moves very quickly, but we could also take a leaf out of Jeff’s book, and instead of worrying about what was going to change, remember what wasn’t going to change. We don’t know what science we’ll want to do in five years’ time, but we won’t want slower experiments, we won’t want more expensive experiments and we won’t want a narrower selection of experiments. As a result, our focus was on how to speed up the process of experiments, increase the diversity of experiments that we can do, and keep the experiments price as low as possible. The faster the innovation flywheel can be iterated, then the quicker we can ask about different parts of the supply chain, and the better we can tailor systems to answering those questions. We need faster, cheaper and more diverse experiments which implies we need better ecosystems for experimentation. This has led us to focus on the software frameworks we’re using to develop machine learning systems including data oriented architectures (Cabrera et al. (2023),Paleyes et al. (2022b),Paleyes et al. (2022a),Borchert (2020);Lawrence (2019);Vorhemus and Schikuta (2017);Joshi (2007)), data maturity assessments (Lawrence et al. (2020)) and data readiness levels (See this blog post on Data Readiness Levels. and Lawrence (2017);The DELVE Initiative (2020)) Figure: The UK Met office runs a shared code base for its simulations of climate and the weather. This plot shows the different spatial and temporal scales used. In many real-world systems, decisions are made through simulating the environment. Simulations may operate at different granularities. For example, simulations are used in weather forecasts and climate forecasts. Interestingly, the UK Met office uses the same code for both, it has a “Unified Model” approach, but they operate climate simulations at greater spatial and temporal resolutions. Figure: Real world systems consist of simulators that capture our domain knowledge about how our systems operate. Different simulators run at different speeds and granularities. Figure: A statistical emulator is a system that reconstructs the simulation with a statistical model. A statistical emulator is a data-driven model that learns about the underlying simulation. Importantly, learns with uncertainty, so it ‘knows what it doesn’t know’. In practice, we can call the emulator in place of the simulator. If the emulator ‘doesn’t know’, it can call the simulator for the answer. Figure: A statistical emulator is a system that reconstructs the simulation with a statistical model. As well as reconstructing the simulation, a statistical emulator can be used to correlate with the real world. As well as reconstructing an individual simulator, the emulator can calibrate the simulation to the real world, by monitoring differences between the simulator and real data. This allows the emulator to characterize where the simulation can be relied on, i.e., we can validate the simulator. Similarly, the emulator can adjudicate between simulations. This is known as multi-fidelity emulation. The emulator characterizes which emulations perform well where. If all this modelling is done with judicious handling of the uncertainty, the computational doubt, then the emulator can assist in deciding what experiment should be run next to aid a decision: should we run a simulator, in which case which one, or should we attempt to acquire data from a real-world intervention. Let \(\mathbf{ x}\) be a random variable defined over the real numbers, \(\Re\), and \(f(\cdot)\) be a function mapping between the real numbers \(\Re \rightarrow \Re\). The problem of uncertainty propagation is the study of the distribution of the random variable \(f(\mathbf{ x})\). We’re going to address this problem using emulation and GPy. We will see in this section the advantage of using a model when only a few observations of \(f\) are available. Firstly, we’ll make use of a test function known as the Branin test function. \[
+\] As we pointed out, there is an irony in Laplace’s demon forming the cornerstone of a movement known as ‘determinism,’ because Laplace wrote about this idea in an essay on probabilities. The more important quote in the essay was The curve described by a simple molecule of air or vapor is regulated in a manner just as certain as the planetary orbits; the only difference between them is that which comes from our ignorance. Probability is relative, in part to this ignorance, in part to our knowledge. We know that of three or greater number of events a single one ought to occur; but nothing induces us to believe that one of them will occur rather than the others. In this state of indecision it is impossible for us to announce their occurrence with certainty. It is, however, probable that one of these events, chosen at will, will not occur because we see several cases equally possible which exclude its occurrence, while only a single one favors it. — Pierre-Simon Laplace (Laplace, 1814), pg 5 The representation of ignorance through probability is the true message of Laplace, I refer to this message as “Laplace’s gremlin,” because it is the gremlin of uncertainty that interferes with the demon of determinism to mean that our predictions are not deterministic. Our separation of the uncertainty into the data, the model and the computation give us three domains in which our doubts can creep into our ability to predict. Over the last three lectures we’ve introduced some of the basic tools we can use to unpick this uncertainty. You’ve been introduced to, (or have yow reviewed) Bayes’ rule. The rule, which is a simple consequence of the product rule of probability, is the foundation of how we update our beliefs in the presence of new information. The real point of Laplace’s essay was that we don’t have access to all the data, we don’t have access to a complete physical understanding, and as the example of the Game of Life shows, even if we did have access to both (as we do for “Conway’s universe”) we still don’t have access to all the compute that we need to make deterministic predictions. There is uncertainty in the system which means we can’t make precise predictions. Gremlins are imaginary creatures used as an explanation of failure in aircraft, causing crashes. In that sense the Gremlin represents the uncertainty that a pilot felt about what might go wrong in a plane which might be “theoretically sound” but in practice is poorly maintained or exposed to conditions that take it beyond its design criteria. Laplace’s gremlin is all the things that your model, data and ability to compute don’t account for bringing about failures in your ability to predict. Laplace’s gremlin is the uncertainty in the system. Figure: Gremlins are seen as the cause of a number of challenges in this World War II poster. An example of a complex decision-making system might be a climate model, in such a system there are separate models for the atmosphere, the ocean and the land. The components of these systems include flowing of currents, chemical interactions in the upper atmosphere, evaporation of water etc.. Figure: Representation of the Carbon Cycle from the US National Oceanic and Atmospheric Administration. While everything is interconnected in the system, we can decompose into separate models for atmosphere, ocean, land. The influence of human activity also needs to be incorporated and modelled so we can make judgments about how to mitigate the effects of global warming. Figure: The components of a simulation system for climate modelling. The classical approach to building these systems was a ‘monolithic system.’ Built in a similar way to the successful applications software such as Excel or Word, or large operating systems, a single code base was constructed. The complexity of such code bases run to many lines. In practice, shared dynamically linked libraries may be used for aspects such as user interface, or networking, but the software often has many millions of lines of code. For example, the Microsoft Office suite is said to contain over 30 million lines of code. Figure: A potential path of models in a machine learning system. Such software is not only difficult to develop, but also to scale when computation demands increase. For example, Amazon’s original website software (called Obidos) was a monolithic design but by the early noughties it was becoming difficult to sustain and maintain. The software was phased out in 2006 to be replaced by a modularized software known as a ‘service-oriented architecture.’ In Service Oriented Architecture, or “Software as a Service” the idea is that code bases are modularized and communicate with one another using network requests. A standard approach is to use a REST API. So, rather than a single monolithic code base, the code is developed with individual services that handle the different requests. The simulation software is turned inside out to expose the individual components to the operator. Figure: A potential path of models in a machine learning system. This is the landscape we now find ourselves in for software development. In practice, each of these services is often ‘owned’ and maintained by an individual team. The team is judged by the quality of their service provision. They work to detailed specifications on what their service should output, what its availability should be and other objectives like speed of response. This allows for conditional independence between teams and for faster development. One question is to what extent is the same approach possible/desirable for scientific models? The components we listed above are already separated and often run independently. But those components themselves are made up of other sub-components that could also be exposed in a similar manner to software-as-a-service, giving us the notion of “simulation as a service.” One thing about working in an industrial environment, is the way that short-term thinking actions become important. For example, in Formula One, the teams are working on a two-week cycle to digest information from the previous week’s race and incorporate updates to the car or their strategy. However, businesses must also think about more medium-term horizons. For example, in Formula 1 you need to worry about next year’s car. So, while you’re working on updating this year’s car, you also need to think about what will happen for next year and prioritize these conflicting needs appropriately. In the Amazon supply chain, there are equivalent demands. If we accept that an artificial intelligence is just an automated decision-making system. And if we measure in terms of money automatically spent, or goods automatically moved, then Amazon’s buying system is perhaps the world’s largest AI. Those decisions are being made on short time schedules; purchases are made by the system on weekly cycles. But just as in Formula 1, there is also a need to think about what needs to be done next month, next quarter and next year. Planning meetings are held not only on a weekly basis (known as weekly business reviews), but monthly, quarterly, and then yearly meetings for planning spends and investments. Amazon is known for being longer term thinking than many companies, and a lot of this is coming from the CEO. One quote from Jeff Bezos that stuck with me was the following. “I very frequently get the question: ‘What’s going to change in the next 10 years?’ And that is a very interesting question; it’s a very common one. I almost never get the question: ‘What’s not going to change in the next 10 years?’ And I submit to you that that second question is actually the more important of the two – because you can build a business strategy around the things that are stable in time. … [I]n our retail business, we know that customers want low prices, and I know that’s going to be true 10 years from now. They want fast delivery; they want vast selection. It’s impossible to imagine a future 10 years from now where a customer comes up and says, ‘Jeff I love Amazon; I just wish the prices were a little higher,’ [or] ‘I love Amazon; I just wish you’d deliver a little more slowly.’ Impossible. And so the effort we put into those things, spinning those things up, we know the energy we put into it today will still be paying off dividends for our customers 10 years from now. When you have something that you know is true, even over the long term, you can afford to put a lot of energy into it.” This quote is incredibly important for long term thinking. Indeed, it’s a failure of many of our simulations that they focus on what is going to happen, not what will not happen. In Amazon, this meant that there was constant focus on these three areas, keeping costs low, making delivery fast and improving selection. For example, shortly before I left Amazon moved its entire US network from two-day delivery to one-day delivery. This involves changing the way the entire buying system operates. Or, more recently, the company has had to radically change the portfolio of products it buys in the face of Covid19. Figure: Experiment, analyze and design is a flywheel of knowledge that is the dual of the model, data and compute. By running through this spiral, we refine our hypothesis/model and develop new experiments which can be analyzed to further refine our hypothesis. From the perspective of the team that we had in the supply chain, we looked at what we most needed to focus on. Amazon moves very quickly, but we could also take a leaf out of Jeff’s book, and instead of worrying about what was going to change, remember what wasn’t going to change. We don’t know what science we’ll want to do in five years’ time, but we won’t want slower experiments, we won’t want more expensive experiments and we won’t want a narrower selection of experiments. As a result, our focus was on how to speed up the process of experiments, increase the diversity of experiments that we can do, and keep the experiments price as low as possible. The faster the innovation flywheel can be iterated, then the quicker we can ask about different parts of the supply chain, and the better we can tailor systems to answering those questions. We need faster, cheaper and more diverse experiments which implies we need better ecosystems for experimentation. This has led us to focus on the software frameworks we’re using to develop machine learning systems including data oriented architectures (Cabrera et al. (2023),Paleyes et al. (2022b),Paleyes et al. (2022a),Borchert (2020);Lawrence (2019);Vorhemus and Schikuta (2017);Joshi (2007)), data maturity assessments (Lawrence et al. (2020)) and data readiness levels (See this blog post on Data Readiness Levels. and Lawrence (2017);The DELVE Initiative (2020)) Figure: The UK Met office runs a shared code base for its simulations of climate and the weather. This plot shows the different spatial and temporal scales used. In many real-world systems, decisions are made through simulating the environment. Simulations may operate at different granularities. For example, simulations are used in weather forecasts and climate forecasts. Interestingly, the UK Met office uses the same code for both, it has a “Unified Model” approach, but they operate climate simulations at greater spatial and temporal resolutions. Figure: Real world systems consist of simulators that capture our domain knowledge about how our systems operate. Different simulators run at different speeds and granularities. Figure: A statistical emulator is a system that reconstructs the simulation with a statistical model. A statistical emulator is a data-driven model that learns about the underlying simulation. Importantly, learns with uncertainty, so it ‘knows what it doesn’t know.’ In practice, we can call the emulator in place of the simulator. If the emulator ‘doesn’t know,’ it can call the simulator for the answer. Figure: A statistical emulator is a system that reconstructs the simulation with a statistical model. As well as reconstructing the simulation, a statistical emulator can be used to correlate with the real world. As well as reconstructing an individual simulator, the emulator can calibrate the simulation to the real world, by monitoring differences between the simulator and real data. This allows the emulator to characterize where the simulation can be relied on, i.e., we can validate the simulator. Similarly, the emulator can adjudicate between simulations. This is known as multi-fidelity emulation. The emulator characterizes which emulations perform well where. If all this modelling is done with judicious handling of the uncertainty, the computational doubt, then the emulator can assist in deciding what experiment should be run next to aid a decision: should we run a simulator, in which case which one, or should we attempt to acquire data from a real-world intervention. Let \(\mathbf{ x}\) be a random variable defined over the real numbers, \(\Re\), and \(f(\cdot)\) be a function mapping between the real numbers \(\Re \rightarrow \Re\). The problem of uncertainty propagation is the study of the distribution of the random variable \(f(\mathbf{ x})\). We’re going to address this problem using emulation and GPy. We will see in this section the advantage of using a model when only a few observations of \(f\) are available. Firstly, we’ll make use of a test function known as the Branin test function. \[
f(\mathbf{ x}) = a(x_2 - bx_1^2 + cx_1 - r)^2 + s(1-t \cos(x_1)) + s
-\] where we are setting \(a=1\), \(b=5.1/(4\pi^2)\), \(c=5/\pi\), \(r=6\), \(s=10\) and \(t=1/(8\pi)\). We’ll define a grid of twenty-five observations over [−5, 10] × [0, 15] and a set of 25 observations. We’ll define a grid of twenty-five observations over [−5, 10] × [0, 15] and a set of 25 observations. The task here will be to consider the distribution of \(f(U)\), where \(U\) is a random variable with uniform distribution over the input space of \(f\). We focus on the computaiton of two quantities, the expectation of \(f(U)\), \(\left\langle f(U)\right\rangle\), and the probability that the value is greater than 200. The expectation of \(f(U )\) is given by \(\int_\mathbf{ x}f( \mathbf{ x})\text{d}\mathbf{ x}\). A basic approach to approximate this integral is to compute the mean of the 25 observations: The result can be compared with the actual mean of the Branin function which is 54.31. Alternatively, we can fit a GP model and compute the integral of the best predictor by Monte Carlo sampling. Firstly, we create the covariance function. Here we’re going to use an exponentiated quadratic, but we’ll augment it with the ‘bias’ covariance function. This covariance function represents a single fixed bias that is added to the overall covariance. It allows us to deal with non-zero-mean emulations. The task here will be to consider the distribution of \(f(U)\), where \(U\) is a random variable with uniform distribution over the input space of \(f\). We focus on the computaiton of two quantities, the expectation of \(f(U)\), \(\left\langle f(U)\right\rangle\), and the probability that the value is greater than 200. The expectation of \(f(U )\) is given by \(\int_\mathbf{ x}f( \mathbf{ x})\text{d}\mathbf{ x}\). A basic approach to approximate this integral is to compute the mean of the 25 observations: The result can be compared with the actual mean of the Branin function which is 54.31. Alternatively, we can fit a GP model and compute the integral of the best predictor by Monte Carlo sampling. Firstly, we create the covariance function. Here we’re going to use an exponentiated quadratic, but we’ll augment it with the ‘bias’ covariance function. This covariance function represents a single fixed bias that is added to the overall covariance. It allows us to deal with non-zero-mean emulations. Now we construct the Gaussian process regression model in GPy. In the sinusoid example above, we learnt the variance of the process. But in this example, we are fitting an emulator to a function we know is noise-free. However, we don’t fix the noise value to precisely zero, as this can lead to some numerical errors. Instead, we fix the variance of the Gaussian noise to a very small value. Now we fit the model. Note, that the initial values for the length scale are not appropriate. So first set the length scale of the model needs to be reset. It’s a common error in Gaussian process fitting to initialize the length scale too small or too big. The challenge is that the error surface is normally multimodal, and the final solution can be very sensitive to this initialization. If the length scale is initialized too small, the solution can converge on an place where the signal isn’t extracted by the covariance function. If the length scale is initialized too large, then the variations of the function are often missing. Here the length scale is set for each dimension of inputs as 3. Now that’s done, we can optimize the model. Figure: A Gaussian process fit to the Branin test function, used to assess the mean of the function by emulation. Finally, we can compute the mean of the model predictions using very many Monte Carlo samples. Note, that in this example, because we’re using a test function, we could simply have done the Monte Carlo estimation directly on the Branin function. However, imagine instead that we were trying to understand the results of a complex computational fluid dynamics simulation, where each run of the simulation (which is equivalent to our test function) took many hours. In that case the advantage of the emulator is clear. Now we construct the Gaussian process regression model in GPy. In the sinusoid example above, we learnt the variance of the process. But in this example, we are fitting an emulator to a function we know is noise-free. However, we don’t fix the noise value to precisely zero, as this can lead to some numerical errors. Instead, we fix the variance of the Gaussian noise to a very small value. Now we fit the model. Note, that the initial values for the length scale are not appropriate. So first set the length scale of the model needs to be reset. It’s a common error in Gaussian process fitting to initialize the length scale too small or too big. The challenge is that the error surface is normally multimodal, and the final solution can be very sensitive to this initialization. If the length scale is initialized too small, the solution can converge on an place where the signal isn’t extracted by the covariance function. If the length scale is initialized too large, then the variations of the function are often missing. Here the length scale is set for each dimension of inputs as 3. Now that’s done, we can optimize the model. Figure: A Gaussian process fit to the Branin test function, used to assess the mean of the function by emulation. Finally, we can compute the mean of the model predictions using very many Monte Carlo samples. Note, that in this example, because we’re using a test function, we could simply have done the Monte Carlo estimation directly on the Branin function. However, imagine instead that we were trying to understand the results of a complex computational fluid dynamics simulation, where each run of the simulation (which is equivalent to our test function) took many hours. In that case the advantage of the emulator is clear. Now think about how to make use of the variance estimation from the Gaussian process to obtain error bars around your estimate. You’ve seen how the Monte Carlo estimates work with the Gaussian process. Now make your estimate of the probability that the Branin function is greater than 200 with the uniform random inputs. We’re introducing you to the optimization and analysis of real-world models through emulation, a domain that is part of the broader field known as surrogate modelling. This involves creating simplified models that approximate more complex systems, allowing for efficient exploration and analysis. Although we’re approaching this from the machine learning perspective, with a computer-scientist’s approach, you won’t be surprised to hear that this field is not new. There are diverse research communities, including statisticians and engineers, who have long been interested in these methods. Our focus has been on active experimental design, where we sequentially select points to run our simulation based on previous results, optimizing the process iteratively. Now, we pause to explore passive experimental design approaches. In passive design, we select initial points to ‘seed’ the emulator without running the simulator. This is crucial for setting up the emulator effectively. The challenge of determining where to run simulations to obtain the necessary answers is longstanding. A seminal paper by McKay et al. (1979) reviews three foundational methods for designing these inputs: random sampling, stratified sampling, and Latin hypercube sampling. These methods provide structured ways to explore the input space and are essential for effective experimental design. Random sampling is the default approach, where samples are selected randomly across the input domain of interest. This can be done uniformly or based on an assumed underlying distribution. It is straightforward but may not always provide comprehensive coverage of the input space. Let the input values \(\mathbf{ x}_1, \dots, \mathbf{ x}_n\) be a random sample from \(f(\mathbf{ x})\). This method of sampling is perhaps the most obvious, and an entire body of statistical literature may be used in making inferences regarding the distribution of \(Y(t)\). Stratified sampling involves dividing a population into sub-populations, or strata, before sampling. This ensures that all sub-populations are represented in the sample. For instance, in Covid-19 tracking, stratifying by age groups ensures coverage across all ages, which might be missed in simple random sampling. In emulation, similar principles apply. The input domain can be divided into areas of particular interest. For example, when testing an F1 car component, you might focus on performance in different track sections, ensuring comprehensive data collection across varied conditions. Using stratified sampling, all areas of the sample space of \(\mathbf{ x}\) are represented by input values. Let the sample space \(S\) of \(\mathbf{ x}\) be partitioned into \(I\) disjoint strata \(S_t\). Let \(\pi = P(\mathbf{ x}\in S_i)\) represent the size of \(S_i\). Obtain a random sample \(\mathbf{ x}_{ij}\), \(j = 1, \dots, n\) from \(S_i\). Then of course the \(n_i\) sum to \(n\). If \(I = 1\), we have random sampling over the entire sample space. Latin hypercube sampling is an advanced form of stratified sampling. It ensures that each input variable’s distribution is fully represented by dividing the input space into \(M\) rows and columns, with samples taken such that each row and column contains only one sample. This method extends to multiple dimensions, providing a comprehensive sampling strategy. The same reasoning that led to stratified sampling, ensuring that all portions of \(S\) were sampled, could lead further. If we wish to ensure also that each of the input variables \(\mathbf{ x}_k\) has all portions of its distribution represented by input values, we can divide the range of each \(\mathbf{ x}_k\) into \(n\) strata of equal marginal probability \(1/n\), and sample once from each stratum. Let this sample be \(\mathbf{ x}_{kj}\), \(j = 1, \dots, n\). These form the \(\mathbf{ x}_k\) component, \(k = 1, \dots , K\), in \(\mathbf{ x}_i\), \(i = 1, \dots, n\). The components of the various \(\mathbf{ x}_k\)’s are matched at random. This method of selecting input values is an extension of quota sampling (Steinberg 1963), and can be viewed as a \(K\)-dimensional extension of Latin square sampling (Raj 1968). The paper’s rather dated reference to “Output from a Computer Code” highlights the historical context of these methods, which remain relevant today. Tony O’Hagan, who was a colleague in Sheffield when I first arrived there, was a pioneer in Gaussian process models, and has contributed significantly to this field, including work on managing uncertainty in computational models (Kennedy and O’Hagan, 2001). More information can be found in the technical reports from the EPSRC funded project http://www.mucm.ac.uk/. Another key group is the “MASCOT-NUM Research Group” in France and it’s follow on RT-UQ, https://uq.math.cnrs.fr/, which unites statisticians, applied mathematicians, and engineers to tackle these complex problems. The Emukit software we will be using across the next part of this module is a python software library that facilitates emulation of systems. The software’s origins go back to work done by Javier Gonzalez as part of his post-doctoral project at the University of Sheffield. Javier led the design and build of a Bayesian optimization software. The package However, Emukit (Paleyes et al., 2019) is designed and built for a more general approach. The software is MIT licensed and its design and implementation was led by Javier Gonzalez and Andrei Paleyes at Amazon. Building on the experience of Figure: The Emukit software is a set of software tools for emulation and surrogate modeling. https://emukit.github.io/emukit/ To use Emukit you need a set of models to use as the surrogates, we’ll use Emukit does active experimental design, to access stratified sampling and latin hypercube designs it makes use of the The software was initially built by the team in Amazon. As well as Javier Gonzalez (ML side) and Andrei Paleyes (Software Engineering) the team included Mark Pullin, Maren Mahsereci, Alex Gessner, Aaron Klein, Henry Moss, David-Elias Künstle as well as management input from Cliff McCollum and myself. We see emulation comprising of three main parts: Models. This is a probabilistic data-driven representation of the process/simulator that the user is working with. There is normally a modelling framework that is used to create a model. Examples: neural network, Gaussian process, random forest. Methods. Relatively low-level techniques that are aimed that either understanding, quantifying or using uncertainty that the model provides. Examples: Bayesian optimization, experimental design. Tasks. High level goals that owners of the process/simulator might be interested in. Examples: measure quality of a simulator, explain complex system behavior. Typical workflow that we envision for a user interested in emulation is: Figure out which questions/tasks are important for them in regard to their process/simulation. Understand which emulation techniques are needed to accomplish the chosen task. Build an emulator of the process. That can be a very involved step, that may include a lot of fine tuning and validation. Feed the emulator to the chosen technique and use it to answer the question/complete the task. Figure: The emukit approach to the three parts of emulation. This is the main focus of Emukit. Emukit defines a general structure of a decision-making method, called OuterLoop, and then offers implementations of few such methods: Bayesian optimization, experimental design. In addition to provide a framework for decision making Emukit provide other tools, like sensitivity analysis, that help to debug and interpret emulators. All methods in Emukit are model agnostic. Generally speaking, Emukit does not provide modelling capabilities, instead expecting users to bring their own models. Because of the variety of modelling frameworks out there, Emukit does not mandate or make any assumptions about a particular modelling technique or a library. Instead, it suggests to implement a subset of defined model interfaces required to use a particular method. Nevertheless, there are a few model-related functionalities in Emukit: - Example models, which give users something to play with to explore Emukit. - Model wrappers, which are designed to help adapting models in particular modelling frameworks to Emukit interfaces. - Multi-fidelity models, implemented based on GPy. Emukit does not contribute much to this part at the moment. However, the Emukit team are on lookout for typical use cases for Emukit, and if a reoccuring pattern emerges, it may become a part of the library. Now think about how to make use of the variance estimation from the Gaussian process to obtain error bars around your estimate. You’ve seen how the Monte Carlo estimates work with the Gaussian process. Now make your estimate of the probability that the Branin function is greater than 200 with the uniform random inputs. We’re introducing you to the optimization and analysis of real-world models through emulation, a domain that is part of the broader field known as surrogate modelling. This involves creating simplified models that approximate more complex systems, allowing for efficient exploration and analysis. Although we’re approaching this from the machine learning perspective, with a computer-scientist’s approach, you won’t be surprised to hear that this field is not new. There are diverse research communities, including statisticians and engineers, who have long been interested in these methods. Our focus has been on active experimental design, where we sequentially select points to run our simulation based on previous results, optimizing the process iteratively. Now, we pause to explore passive experimental design approaches. In passive design, we select initial points to ‘seed’ the emulator without running the simulator. This is crucial for setting up the emulator effectively. The challenge of determining where to run simulations to obtain the necessary answers is longstanding. A seminal paper by McKay et al. (1979) reviews three foundational methods for designing these inputs: random sampling, stratified sampling, and Latin hypercube sampling. These methods provide structured ways to explore the input space and are essential for effective experimental design. Random sampling is the default approach, where samples are selected randomly across the input domain of interest. This can be done uniformly or based on an assumed underlying distribution. It is straightforward but may not always provide comprehensive coverage of the input space. Let the input values \(\mathbf{ x}_1, \dots, \mathbf{ x}_n\) be a random sample from \(f(\mathbf{ x})\). This method of sampling is perhaps the most obvious, and an entire body of statistical literature may be used in making inferences regarding the distribution of \(Y(t)\). Stratified sampling involves dividing a population into sub-populations, or strata, before sampling. This ensures that all sub-populations are represented in the sample. For instance, in Covid-19 tracking, stratifying by age groups ensures coverage across all ages, which might be missed in simple random sampling. In emulation, similar principles apply. The input domain can be divided into areas of particular interest. For example, when testing an F1 car component, you might focus on performance in different track sections, ensuring comprehensive data collection across varied conditions. Using stratified sampling, all areas of the sample space of \(\mathbf{ x}\) are represented by input values. Let the sample space \(S\) of \(\mathbf{ x}\) be partitioned into \(I\) disjoint strata \(S_t\). Let \(\pi = P(\mathbf{ x}\in S_i)\) represent the size of \(S_i\). Obtain a random sample \(\mathbf{ x}_{ij}\), \(j = 1, \dots, n\) from \(S_i\). Then of course the \(n_i\) sum to \(n\). If \(I = 1\), we have random sampling over the entire sample space. Latin hypercube sampling is an advanced form of stratified sampling. It ensures that each input variable’s distribution is fully represented by dividing the input space into \(M\) rows and columns, with samples taken such that each row and column contains only one sample. This method extends to multiple dimensions, providing a comprehensive sampling strategy. The same reasoning that led to stratified sampling, ensuring that all portions of \(S\) were sampled, could lead further. If we wish to ensure also that each of the input variables \(\mathbf{ x}_k\) has all portions of its distribution represented by input values, we can divide the range of each \(\mathbf{ x}_k\) into \(n\) strata of equal marginal probability \(1/n\), and sample once from each stratum. Let this sample be \(\mathbf{ x}_{kj}\), \(j = 1, \dots, n\). These form the \(\mathbf{ x}_k\) component, \(k = 1, \dots , K\), in \(\mathbf{ x}_i\), \(i = 1, \dots, n\). The components of the various \(\mathbf{ x}_k\)’s are matched at random. This method of selecting input values is an extension of quota sampling (Steinberg 1963), and can be viewed as a \(K\)-dimensional extension of Latin square sampling (Raj 1968). The paper’s rather dated reference to “Output from a Computer Code” highlights the historical context of these methods, which remain relevant today. Tony O’Hagan, who was a colleague in Sheffield when I first arrived there, was a pioneer in Gaussian process models, and has contributed significantly to this field, including work on managing uncertainty in computational models (Kennedy and O’Hagan, 2001). More information can be found in the technical reports from the EPSRC funded project http://www.mucm.ac.uk/. Another key group is the “MASCOT-NUM Research Group” in France and it’s follow on RT-UQ, https://uq.math.cnrs.fr/, which unites statisticians, applied mathematicians, and engineers to tackle these complex problems. The Emukit software we will be using across the next part of this module is a python software library that facilitates emulation of systems. The software’s origins go back to work done by Javier Gonzalez as part of his post-doctoral project at the University of Sheffield. Javier led the design and build of a Bayesian optimization software. The package However, Emukit (Paleyes et al., 2019) is designed and built for a more general approach. The software is MIT licensed and its design and implementation was led by Javier Gonzalez and Andrei Paleyes at Amazon. Building on the experience of Figure: The Emukit software is a set of software tools for emulation and surrogate modeling. https://emukit.github.io/emukit/ To use Emukit you need a set of models to use as the surrogates, we’ll use Emukit does active experimental design, to access stratified sampling and latin hypercube designs it makes use of the The software was initially built by the team in Amazon. As well as Javier Gonzalez (ML side) and Andrei Paleyes (Software Engineering) the team included Mark Pullin, Maren Mahsereci, Alex Gessner, Aaron Klein, Henry Moss, David-Elias Künstle as well as management input from Cliff McCollum and myself. We see emulation comprising of three main parts: Models. This is a probabilistic data-driven representation of the process/simulator that the user is working with. There is normally a modelling framework that is used to create a model. Examples: neural network, Gaussian process, random forest. Methods. Relatively low-level techniques that are aimed that either understanding, quantifying or using uncertainty that the model provides. Examples: Bayesian optimization, experimental design. Tasks. High level goals that owners of the process/simulator might be interested in. Examples: measure quality of a simulator, explain complex system behavior. Typical workflow that we envision for a user interested in emulation is: Figure out which questions/tasks are important for them in regard to their process/simulation. Understand which emulation techniques are needed to accomplish the chosen task. Build an emulator of the process. That can be a very involved step, that may include a lot of fine tuning and validation. Feed the emulator to the chosen technique and use it to answer the question/complete the task. Figure: The emukit approach to the three parts of emulation. This is the main focus of Emukit. Emukit defines a general structure of a decision-making method, called OuterLoop, and then offers implementations of few such methods: Bayesian optimization, experimental design. In addition to provide a framework for decision making Emukit provide other tools, like sensitivity analysis, that help to debug and interpret emulators. All methods in Emukit are model agnostic. Generally speaking, Emukit does not provide modelling capabilities, instead expecting users to bring their own models. Because of the variety of modelling frameworks out there, Emukit does not mandate or make any assumptions about a particular modelling technique or a library. Instead, it suggests to implement a subset of defined model interfaces required to use a particular method. Nevertheless, there are a few model-related functionalities in Emukit: - Example models, which give users something to play with to explore Emukit. - Model wrappers, which are designed to help adapting models in particular modelling frameworks to Emukit interfaces. - Multi-fidelity models, implemented based on GPy. Emukit does not contribute much to this part at the moment. However, the Emukit team are on lookout for typical use cases for Emukit, and if a reoccuring pattern emerges, it may become a part of the library. Emukit is built in a modular way so that each component in this loop can be swapped out. This means that scientists, applied mathematicians, machine learnings, statisticians can swap out the relevant part of their method and build on the underlying structure. You just need to pick out the part that requires implementation. The All Different models and modelling frameworks will provide different functionality. For instance, a Gaussian process will usually have derivatives of the predictions available but random forests will not. These different functionalities are represented by a set of interfaces which a model implements. The basic interface that all models must implement is This class decides which point to evaluate next. The simplest implementation, The acquisition is a heuristic quantification of how valuable collecting a future point might be. It is used by the candidate point calculator to decide which point(s) to collect next. The This is the function that we are trying to reason about. It can be either evaluated by the user or it can be passed into the loop and evaluated by Emukit. The The You can see more of Emukit being put into practice in this case study on Machine Learning in the Multiverse by Sam Bell. Emukit playground is a software toolkit for exploring the use of statistical emulation as a tool. It was built by Leah Hirst, during her software engineering internship at Amazon and supervised by Cliff McCollum. Figure: Emukit playground is a tutorial for understanding the simulation/emulation relationship. https://amzn.github.io/emukit-playground/ Figure: Tutorial on Bayesian optimization of the number of taxis deployed from Emukit playground. https://amzn.github.io/emukit-playground/#!/learn/bayesian_optimization You can explore Bayesian optimization of a taxi simulation. Set up the python imports that Emukit will use. Now set up Emukit to run. Let’s check the help function for the experimental design loop. This is the outer loop that provides all the decision making parts of Emukit. Now let’s load in the model wrapper for our probabilistic model. In this case, instead of using GPy, we’ll make use of a simple model wrapper Emukit provides for a basic form of Gaussian process. Let’s have a quick look at how the included GP model works. Now let’s create the data. Emukit is built in a modular way so that each component in this loop can be swapped out. This means that scientists, applied mathematicians, machine learnings, statisticians can swap out the relevant part of their method and build on the underlying structure. You just need to pick out the part that requires implementation. The All Different models and modelling frameworks will provide different functionality. For instance, a Gaussian process will usually have derivatives of the predictions available but random forests will not. These different functionalities are represented by a set of interfaces which a model implements. The basic interface that all models must implement is This class decides which point to evaluate next. The simplest implementation, The acquisition is a heuristic quantification of how valuable collecting a future point might be. It is used by the candidate point calculator to decide which point(s) to collect next. The This is the function that we are trying to reason about. It can be either evaluated by the user or it can be passed into the loop and evaluated by Emukit. The The You can see more of Emukit being put into practice in this case study on Machine Learning in the Multiverse by Sam Bell. Emukit playground is a software toolkit for exploring the use of statistical emulation as a tool. It was built by Leah Hirst, during her software engineering internship at Amazon and supervised by Cliff McCollum. Figure: Emukit playground is a tutorial for understanding the simulation/emulation relationship. https://amzn.github.io/emukit-playground/ Figure: Tutorial on Bayesian optimization of the number of taxis deployed from Emukit playground. https://amzn.github.io/emukit-playground/#!/learn/bayesian_optimization You can explore Bayesian optimization of a taxi simulation. Set up the python imports that Emukit will use. Now set up Emukit to run. Let’s check the help function for the experimental design loop. This is the outer loop that provides all the decision making parts of Emukit. Now let’s load in the model wrapper for our probabilistic model. In this case, instead of using GPy, we’ll make use of a simple model wrapper Emukit provides for a basic form of Gaussian process. Let’s have a quick look at how the included GP model works. Now let’s create the data. To learn about how to include your own model in Emukit, check this notebook which shows how to include a To learn about how to include your own model in Emukit, check this notebook which shows how to include a Figure: Experimental design in Emukit using the Computer the predictions from the Emukit model. Figure: Experimental design in Emukit using the Computer the predictions from the Emukit model. Figure: The fit to the sine function after runnning the Emukit Repeat the above experiment but using the Gaussian process model from The aim is to provide a suite where different approaches to emulation are assimilated under one roof. The current version of Emukit includes multi-fidelity emulation for build surrogate models when data is obtained from multiple information sources that have different fidelity and/or cost; Bayesian optimisation for optimising physical experiments and tune parameters of machine learning algorithms or other computational simulations; experimental design and active learning: design the most informative experiments and perform active learning with machine learning models; sensitivity analysis: analyse the influence of inputs on the outputs of a given system; and Bayesian quadrature: efficiently compute the integrals of functions that are expensive to evaluate. But it’s easy to extend. This introduction is based on Introduction to Global Sensitivity Analysis with Emukit written by Mark Pullin, Javier Gonzalez, Juan Emmanuel Johnson and Andrei Paleyes. Some references include (Kennedy and O’Hagan, 2000; Saltelli et al., 2010, 2008, 2004; Sobol, 2001, 1990) A possible definition of sensitivity analysis is the following: The study of how uncertainty in the output of a model (numerical or otherwise) can be apportioned to different sources of uncertainty in the model input (Saltelli et al., 2004). A related practice is ‘uncertainty analysis’, which focuses rather on quantifying uncertainty in model output. Ideally, uncertainty and sensitivity analyses should be run in tandem, with uncertainty analysis preceding in current practice. In Chapter 1 of Saltelli et al. (2008) Figure: The fit to the sine function after runnning the Emukit Repeat the above experiment but using the Gaussian process model from The aim is to provide a suite where different approaches to emulation are assimilated under one roof. The current version of Emukit includes multi-fidelity emulation for build surrogate models when data is obtained from multiple information sources that have different fidelity and/or cost; Bayesian optimisation for optimising physical experiments and tune parameters of machine learning algorithms or other computational simulations; experimental design and active learning: design the most informative experiments and perform active learning with machine learning models; sensitivity analysis: analyse the influence of inputs on the outputs of a given system; and Bayesian quadrature: efficiently compute the integrals of functions that are expensive to evaluate. But it’s easy to extend. This introduction is based on Introduction to Global Sensitivity Analysis with Emukit written by Mark Pullin, Javier Gonzalez, Juan Emmanuel Johnson and Andrei Paleyes. Some references include (Kennedy and O’Hagan, 2000; Saltelli et al., 2010, 2008, 2004; Sobol, 2001, 1990) A possible definition of sensitivity analysis is the following: The study of how uncertainty in the output of a model (numerical or otherwise) can be apportioned to different sources of uncertainty in the model input (Saltelli et al., 2004). A related practice is ‘uncertainty analysis,’ which focuses rather on quantifying uncertainty in model output. Ideally, uncertainty and sensitivity analyses should be run in tandem, with uncertainty analysis preceding in current practice. In Chapter 1 of Saltelli et al. (2008) Sensitivity analysis is a statistical technique widely used to test the reliability of real systems. Imagine a simulator of taxis picking up customers in a city like the one showed in the Emukit playground. The profit of the taxi company depends on factors like the number of taxis on the road and the price per trip. In this example, a global sensitivity analysis of the simulator could be useful to decompose the variance of the profit in a way that can be assigned to the input variables of the simulator. There are different ways of doing a sensitivity analysis of the variables of a simulator. In this notebook we will start with an approach based on Monte Carlo sampling that is useful when evaluating the simulator is cheap. If evaluating the simulator is expensive, emulators can then be used to speed up computations. We will show this in the last part of the notebook. Next, we start with a few formal definitions and literature review so we can understand the basics of Sensitivity Analysis and how it can be performed with Emukit. Given any function, \(g(\cdot)\), we might be interested in how sensitive that function is to variations in its input space. One route to determining this is to compute the partial derivatives of that function with respect to its inputs, \[
+from matplotlib import cm Sensitivity analysis is a statistical technique widely used to test the reliability of real systems. Imagine a simulator of taxis picking up customers in a city like the one showed in the Emukit playground. The profit of the taxi company depends on factors like the number of taxis on the road and the price per trip. In this example, a global sensitivity analysis of the simulator could be useful to decompose the variance of the profit in a way that can be assigned to the input variables of the simulator. There are different ways of doing a sensitivity analysis of the variables of a simulator. In this notebook we will start with an approach based on Monte Carlo sampling that is useful when evaluating the simulator is cheap. If evaluating the simulator is expensive, emulators can then be used to speed up computations. We will show this in the last part of the notebook. Next, we start with a few formal definitions and literature review so we can understand the basics of Sensitivity Analysis and how it can be performed with Emukit. Given any function, \(g(\cdot)\), we might be interested in how sensitive that function is to variations in its input space. One route to determining this is to compute the partial derivatives of that function with respect to its inputs, \[
\frac{\partial}{\partial x_i} g(\mathbf{ x}).
-\] The matrix of all these partial derivatives is known as the Jacobian. These types of local sensitivity analysis can be used for determining the effect of changing an input variable around an operating point. But they don’t give us an understanding of the response of the target function to variations in the input across the domain of inputs. For this, we need to look to global sensitivity analysis. In global sensitivity analysis, rather than looking around a single operating point, we’re interested in the overall sensitivity of a function to its inputs, or combinations of inputs, across its entire domain. The key tool in determining this sensitivity is known as the ANOVA decomposition, or the Hoeffding-Sobol decomposition. For global sensitivity analysis, we need to make an assumption about how inputs are going to vary to create different values of the function. The fundamental object we’re interested in is the total variance of the function, \[
+\] The matrix of all these partial derivatives is known as the Jacobian. These types of local sensitivity analysis can be used for determining the effect of changing an input variable around an operating point. But they don’t give us an understanding of the response of the target function to variations in the input across the domain of inputs. For this, we need to look to global sensitivity analysis. In global sensitivity analysis, rather than looking around a single operating point, we’re interested in the overall sensitivity of a function to its inputs, or combinations of inputs, across its entire domain. The key tool in determining this sensitivity is known as the ANOVA decomposition, or the Hoeffding-Sobol decomposition. For global sensitivity analysis, we need to make an assumption about how inputs are going to vary to create different values of the function. The fundamental object we’re interested in is the total variance of the function, \[
\text{var}\left(g(\mathbf{ x})\right) = \left\langle g(\mathbf{ x})^2 \right\rangle _{p(\mathbf{ x})} - \left\langle g(\mathbf{ x}) \right\rangle _{p(\mathbf{ x})}^2,
\] where \[
\left\langle h(\mathbf{ x}) \right\rangle _{p(\mathbf{ x})} = \int_\mathbf{ x}h(\mathbf{ x}) p(\mathbf{ x}) \text{d}\mathbf{ x}
-\] is the expectation of the function \(h(\mathbf{ x})\) under the density \(p(\mathbf{ x})\), which represents the probability distribution of inputs we’re interested in. {The Hoeffding-Sobol, or ANOVA, decomposition of a function allows us to write it as, \[
+\] is the expectation of the function \(h(\mathbf{ x})\) under the density \(p(\mathbf{ x})\), which represents the probability distribution of inputs we’re interested in. {The Hoeffding-Sobol, or ANOVA, decomposition of a function allows us to write it as, \[
\begin{align*}
g(\mathbf{ x}) = & g_0 + \sum_{i=1}^dg_i(x_i) + \sum_{i<j}^{d} g_{ij}(x_i,x_j) + \cdots \\
& + g_{1,2,\dots,d}(x_1,x_2,\dots,x_d),
@@ -966,372 +106,78 @@ Note that to compute each of these individual terms, you need to first compute the low order terms, and then compute the high order terms. This can be problematic when \(d\) is large. We’re interested in the variance of the function \(g\), so implicitly we’re assuming that the square of this function is integrable across its domain, i.e., we’re assuming that \(\left\langle g(\mathbf{ x})^2 \right\rangle _{p(\mathbf{ x})}\) exists and is finite. The Sobol decomposition has some important properties, in particular, its components are orthogonal, so this means that when we substitute it in to the variance, we have, \[
+\] and similar expressions can be written for higher order terms up to \(g_{1,2,\dots,d}(\mathbf{ x})\).} Note that to compute each of these individual terms, you need to first compute the low order terms, and then compute the high order terms. This can be problematic when \(d\) is large. We’re interested in the variance of the function \(g\), so implicitly we’re assuming that the square of this function is integrable across its domain, i.e., we’re assuming that \(\left\langle g(\mathbf{ x})^2 \right\rangle _{p(\mathbf{ x})}\) exists and is finite. The Sobol decomposition has some important properties, in particular, its components are orthogonal, so this means that when we substitute it in to the variance, we have, \[
\begin{align*}
\text{var}(g) = & \left\langle g(\mathbf{ x})^2 \right\rangle _{p(\mathbf{ x})} - \left\langle g(\mathbf{ x}) \right\rangle _{p(\mathbf{ x})}^2 \\
-= & \left\langle g(\mathbf{ x})^2 \right\rangle _{p(\mathbf{ x})} - g_0^2\\
-= & \sum_{i=1}^d\text{var}\left(g_i(x_i)\right) + \sum_{i<j}^{d} \text{var}\left(g_{ij}(x_i,x_j)\right) + \cdots \\ & + \text{var}\left(g_{1,2,\dots,d}(x_1,x_2,\dots,x_d)\right).
+ = & \left\langle g(\mathbf{ x})^2 \right\rangle _{p(\mathbf{ x})} - g_0^2\\
+ = & \sum_{i=1}^d\text{var}\left(g_i(x_i)\right) + \sum_{i<j}^{d} \text{var}\left(g_{ij}(x_i,x_j)\right) + \cdots \\ & + \text{var}\left(g_{1,2,\dots,d}(x_1,x_2,\dots,x_d)\right).
\end{align*}
-\] So, this decomposition gives us a decomposition of the function in terms of variances. It’s for this reason that it’s sometimes known as an ANOVA decomposition. ANOVA stands a for analysis of variance. The ANOVA decomposition decomposes the function into additive variance parts that are each stemming from interactions between different inputs. As is common in various analyses of variance, we can rescale the components with the total variance of the function. These rescaled components are known as Sobol indicies. \[
+\] So, this decomposition gives us a decomposition of the function in terms of variances. It’s for this reason that it’s sometimes known as an ANOVA decomposition. ANOVA stands a for analysis of variance. The ANOVA decomposition decomposes the function into additive variance parts that are each stemming from interactions between different inputs. As is common in various analyses of variance, we can rescale the components with the total variance of the function. These rescaled components are known as Sobol indicies. \[
S_\ell = \frac{\text{var}\left(g(\mathbf{ x}_\ell)\right)}{\text{var}\left(g(\mathbf{ x})\right)},
-\] where the \(\ell\) represents the relevent set of indices for the different combinations of inputs. In practice, for an elegant approach that exploits a particular covariance function structure to perform global sensitivity analysis see Durrande et al. (2013). In this section, we’ll work through a practical example of sensitivity analysis using the Ishigami function. We’ve specifically chosen this function because it’s one of the rare cases where we can calculate Sobol indices exactly. This gives us a valuable reference point for understanding approximate methods. However, it’s important to note that in real-world applications, exact calculation of sensitivity indices is often impossible. The methods we’ll demonstrate progress from: 1. Exact calculation (possible only for special cases like Ishigami) 2. Monte Carlo estimation (applicable generally but computationally expensive) 3. Gaussian process emulation (an efficient approximation method for expensive functions) Through this progression, you’ll understand both the ideal case and the practical approaches needed in real applications. We illustrate the exact calculation of the Sobol indices with the three-dimensional Ishigami function of (Ishigami and Homma, 1989). The Ishigami function (Ishigami and Homma, 1989) is a well-known test function for uncertainty and sensitivity analysis methods because of its strong nonlinearity and peculiar dependence on \(x_3\). More details of this function can be found in (Sobol and Levitan, 1999). Mathematically, the form of the Ishigami function is \[
-g(\textbf{x}) = \sin(x_1) + a \sin^2(x_2) + b x_3^4 \sin(x_1).
-\] We will set the parameters to be \(a = 5\) and \(b=0.1\) . The input variables are sampled randomly \(x_i \sim \mathscr{U}\left(-\pi,\pi\right)\). Next, we create the function object and visualize its shape marginally for each one of its three inputs. Load the Ishigami function That gives us the target function, next we define the input space for the simulator. In practice, for an elegant approach that exploits a particular covariance function structure to perform global sensitivity analysis see Durrande et al. (2013). In this section, we’ll work through a practical example of sensitivity analysis using the Ishigami function. We’ve specifically chosen this function because it’s one of the rare cases where we can calculate Sobol indices exactly. This gives us a valuable reference point for understanding approximate methods. However, it’s important to note that in real-world applications, exact calculation of sensitivity indices is often impossible. The methods we’ll demonstrate progress from: 1. Exact calculation (possible only for special cases like Ishigami) 2. Monte Carlo estimation (applicable generally but computationally expensive) 3. Gaussian process emulation (an efficient approximation method for expensive functions) Through this progression, you’ll understand both the ideal case and the practical approaches needed in real applications. We illustrate the exact calculation of the Sobol indices with the three-dimensional Ishigami function of (Ishigami and Homma, 1989). The Ishigami function (Ishigami and Homma, 1989) is a well-known test function for uncertainty and sensitivity analysis methods because of its strong nonlinearity and peculiar dependence on \(x_3\). More details of this function can be found in (Sobol and Levitan, 1999). Mathematically, the form of the Ishigami function is \[
+g(\textbf{x}) = \sin(x_1) + a \sin^2(x_2) + b x_3^4 \sin(x_1).
+\] We will set the parameters to be \(a = 5\) and \(b=0.1\) . The input variables are sampled randomly \(x_i \sim \mathscr{U}\left(-\pi,\pi\right)\). Next, we create the function object and visualize its shape marginally for each one of its three inputs. Load the Ishigami function That gives us the target function, next we define the input space for the simulator. Before moving to any further analysis, we first plot the non-zero components \(g(\mathbf{ x})\). These components are \[
+ ContinuousParameter('x3', *variable_domain)]) Before moving to any further analysis, we first plot the non-zero components \(g(\mathbf{ x})\). These components are \[
\begin{align*}
g_1(x_1) & = \sin(x_1) \\
g_2(x_2) & = a \sin^2 (x_2) \\
-g_{13}(x_1,x_3) & = b x_3^4 \sin(x_1)
+g_{13}(x_1,x_3) & = b x_3^4 \sin(x_1)
\end{align*}
-\] Figure: The non-zero components of the Ishigami function. The total variance \(\text{var}(y)\) in this example is which is the sum of the variance of \(\text{var}\left(g_1(x_1)\right)\), \(\text{var}\left(g_2(x_2)\right)\) and \(\text{var}\left(g_{1,3}(x_{1,3})\right)\) The first order Sobol indices are a measure of “first order sensitivity” of each input variable. They account for the proportion of variance of \(y\) explained by changing each variable alone while marginalizing over the rest. Recall that the Sobol index of the \(i\)th variable is computed as \[
+F13 = ishigami.f13(np.array([x_grid,x_grid]).T)[:,np.newaxis] Figure: The non-zero components of the Ishigami function. The total variance \(\text{var}(y)\) in this example is which is the sum of the variance of \(\text{var}\left(g_1(x_1)\right)\), \(\text{var}\left(g_2(x_2)\right)\) and \(\text{var}\left(g_{1,3}(x_{1,3})\right)\) The first order Sobol indices are a measure of “first order sensitivity” of each input variable. They account for the proportion of variance of \(y\) explained by changing each variable alone while marginalizing over the rest. Recall that the Sobol index of the \(i\)th variable is computed as \[
S_i = \frac{\text{var}\left(g_i(x_i)\right)}{\text{var}\left(g(\mathbf{ x})\right)}.
-\] This value is standardized using the total variance, so it is possible to account for a fractional contribution of each variable to the total variance of the output. The Sobol indices for higher order interactions \(S_{i,j}\) are computed similarly. Due to the normalization by the total variance, the the sum of all Sobol indices equals to one. In most cases we are interested in the first order indices. The Ishigami function has the benefit that these can be computed analytically. In But in general, these indices need to be sampled using Monte Carlo or one of the quasi-Monte Carlo methods we’ve seen in the model-free experimental design. Details are given in (Sobol, 2001). With Emukit, the first-order Sobol indices can be easily computed. We first need to define the space where the target simulator is analyzed. The Sobol indices for higher order interactions \(S_{i,j}\) are computed similarly. Due to the normalization by the total variance, the the sum of all Sobol indices equals to one. In most cases we are interested in the first order indices. The Ishigami function has the benefit that these can be computed analytically. In But in general, these indices need to be sampled using Monte Carlo or one of the quasi-Monte Carlo methods we’ve seen in the model-free experimental design. Details are given in (Sobol, 2001). With Emukit, the first-order Sobol indices can be easily computed. We first need to define the space where the target simulator is analyzed. We compare the true effects with the Monte Carlo effects in a bar-plot. The total effects are discussed later. Figure: The non-zero components of the Ishigami function. Computing high order sensitivity indices can be computationally very demanding in high dimensional scenarios and measuring the total influence of each variable on the variance of the output is infeasible. To solve this issue the total indices are used which account for the contribution to the output variance of \(x_i\) including all variance caused by the variable alone and all its interactions of any order. The total effect for \(x_i\) is given by: \[
+print(main_effects) We compare the true effects with the Monte Carlo effects in a bar-plot. The total effects are discussed later. Figure: The non-zero components of the Ishigami function. Computing high order sensitivity indices can be computationally very demanding in high dimensional scenarios and measuring the total influence of each variable on the variance of the output is infeasible. To solve this issue the total indices are used which account for the contribution to the output variance of \(x_i\) including all variance caused by the variable alone and all its interactions of any order. The total effect for \(x_i\) is given by: \[
S_{Ti} = \frac{\left\langle \text{var}_{x_i} (y\mid \mathbf{ x}_{\sim i}) \right\rangle _{p(\mathbf{ x}_{\sim i})}}{\text{var}\left(g(\mathbf{ x})\right)} = 1 - \frac{\text{var}_{\mathbf{ x}_{\sim i}} \left\langle y\mid \mathbf{ x}_{\sim i} \right\rangle _{p(\mathbf{ x}_{\sim i})}}{\text{var}\left(g(\mathbf{ x})\right)}
-\] Note that the sum of \(S_{Ti}\) is not necessarily one in this case unless the model is additive. In the Ishigami example the value of the total effects is As in the previous example, the total effects can be computed with Monte Carlo. In the next plot we show the comparison with the true total effects. Figure: The total effects from the Ishigami function as computed via Monte Carlo estimate alongside the true total effects for the Ishigami function. In the example used above the Ishigami function is very cheap to evaluate. However, in most real scenarios the functions of interest are expensive, and we need to limit ourselves to a few number of evaluations. Using Monte Carlo methods is infeasible in these scenarios as a large number of samples are typically required to provide good estimates of the Sobol indices. An alternative in these cases is to use Gaussaian process emulator of the function of interest trained on a few inputs and outputs (Marrel et al., 2009). If the model is properly trained, its mean prediction which is cheap to evaluate, can be used to compute the Monte Carlo estimates of the Sobol indices, the variance from the GP emulator can also be used to assess our uncertainty about the Sobol indices. Let’s see how we can do this in Emukit. We start by generating 100 samples in the input domain. Note that this a just 1% of the number of samples that we used to compute the Sobol coefficients using Monte Carlo. Note that the sum of \(S_{Ti}\) is not necessarily one in this case unless the model is additive. In the Ishigami example the value of the total effects is As in the previous example, the total effects can be computed with Monte Carlo. In the next plot we show the comparison with the true total effects. Figure: The total effects from the Ishigami function as computed via Monte Carlo estimate alongside the true total effects for the Ishigami function. In the example used above the Ishigami function is very cheap to evaluate. However, in most real scenarios the functions of interest are expensive, and we need to limit ourselves to a few number of evaluations. Using Monte Carlo methods is infeasible in these scenarios as a large number of samples are typically required to provide good estimates of the Sobol indices. An alternative in these cases is to use Gaussaian process emulator of the function of interest trained on a few inputs and outputs (Marrel et al., 2009). If the model is properly trained, its mean prediction which is cheap to evaluate, can be used to compute the Monte Carlo estimates of the Sobol indices, the variance from the GP emulator can also be used to assess our uncertainty about the Sobol indices. Let’s see how we can do this in Emukit. We start by generating 100 samples in the input domain. Note that this a just 1% of the number of samples that we used to compute the Sobol coefficients using Monte Carlo. Now, we fit a standard Gaussian process to the samples, and we wrap it as an Emukit model. Now, we fit a standard Gaussian process to the samples, and we wrap it as an Emukit model. The final step is to compute the coefficients using the class The final step is to compute the coefficients using the class Figure: First order Sobol indices as estimated by Monte Carlo and GP-emulator based Monte Carlo. Figure: Total effects as estimated by Monte Carlo and GP based Monte Carlo. We observe some discrepancies with respect to the real value of the Sobol index when using the Gaussian process, but we get a fairly good approximation with a very reduced number of evaluations of the original target function. The Sobol indices are a tool for explaining the variance of the output of a function as components of the input variables. Monte Carlo is an approach for computing these indices if the function is cheap to evaluate. Other approaches are needed when \(g(\cdot)\) is expensive to compute. \nicolasDurrandePicture{15%} As a worked example we’re going to introduce a catapult simulation written by Nicolas Durrande, https://durrande.shinyapps.io/catapult/. Figure: A catapult simulation for experimenting with surrogate models, kindly provided by Nicolas Durrande The simulator allows you to set various parameters of the catapult including the axis of rotation, These parameters are then collated in a vector, \[
+main_effects_gp, total_effects_gp, _ = senstivity_ishigami_gpbased.compute_effects(num_monte_carlo_points = num_mc) Figure: First order Sobol indices as estimated by Monte Carlo and GP-emulator based Monte Carlo. Figure: Total effects as estimated by Monte Carlo and GP based Monte Carlo. We observe some discrepancies with respect to the real value of the Sobol index when using the Gaussian process, but we get a fairly good approximation with a very reduced number of evaluations of the original target function. The Sobol indices are a tool for explaining the variance of the output of a function as components of the input variables. Monte Carlo is an approach for computing these indices if the function is cheap to evaluate. Other approaches are needed when \(g(\cdot)\) is expensive to compute. \nicolasDurrandePicture{15%} As a worked example we’re going to introduce a catapult simulation written by Nicolas Durrande, https://durrande.shinyapps.io/catapult/. Figure: A catapult simulation for experimenting with surrogate models, kindly provided by Nicolas Durrande The simulator allows you to set various parameters of the catapult including the axis of rotation, These parameters are then collated in a vector, \[
\mathbf{ x}_i = \begin{bmatrix}
\texttt{rotation_axis} \\
\texttt{arm_stop} \\
\texttt{spring_binding_1} \\
\texttt{spring_binding_2}
\end{bmatrix}
-\] Having set those parameters, you can run an experiment, by firing the catapult. This will show you how far it goes. Because you will need to operate the catapult yourself, we’ll create a function to query you about the result of an individual firing. We can also set the parameter space for the model. Each of these variables is scaled to operate \(\in [0, 1]\). Having set those parameters, you can run an experiment, by firing the catapult. This will show you how far it goes. Because you will need to operate the catapult yourself, we’ll create a function to query you about the result of an individual firing. We can also set the parameter space for the model. Each of these variables is scaled to operate \(\in [0, 1]\). Before we perform sensitivity analysis, we need to build an emulator of the catapulter, which we do using our experimental design process. Now we will build an emulator for the catapult using the experimental design loop. We’ll start with a small model-free design, we’ll use a random design for initializing our model. Before we perform sensitivity analysis, we need to build an emulator of the catapulter, which we do using our experimental design process. Now we will build an emulator for the catapult using the experimental design loop. We’ll start with a small model-free design, we’ll use a random design for initializing our model. Set up the GPy model. The variance of the RBF kernel is set to \(150^2\) because that’s roughly the square of the range of the catapult. We set the noise variance to a small value. Set up the GPy model. The variance of the RBF kernel is set to \(150^2\) because that’s roughly the square of the range of the catapult. We set the noise variance to a small value. Wrap the model for EmuKit. Now we set up the model loop. We’ll use integrated variance reduction as the acquisition function for our model-based design loop. Warning: This loop runs much slower on Google Wrap the model for EmuKit. Now we set up the model loop. We’ll use integrated variance reduction as the acquisition function for our model-based design loop. Warning: This loop runs much slower on Google The final step is to compute the coefficients using the class The final step is to compute the coefficients using the class Figure: First Order sobol indices as estimated by GP-emulator based Monte Carlo on the catapult. Figure: Total effects as estimated by GP based Monte Carlo on the catapult. For more information on these subjects and more you might want to check the following resources. Figure: First Order sobol indices as estimated by GP-emulator based Monte Carlo on the catapult. Figure: Total effects as estimated by GP based Monte Carlo on the catapult. For more information on these subjects and more you might want to check the following resources.cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python
The Importance of the Covariance Function
-
-
-
-
-
-
-
-
-
-Improving the Numerics
-
-
-import scipy.linalg as la
-from mlai import GP
-from mlai import update_inverse
-# Bind the updated inverse to our GP model
-GP.update_inverse = update_inverseCapacity Control
-Improving the Numerics
import scipy.linalg as lafrom mlai import GPfrom mlai import update_inverse# Bind the updated inverse to our GP model
+GP.update_inverse = update_inverseCapacity Control
Gradients of the Likelihood
-Overall Process Scale
-Capacity Control and Data Fit
-Learning Covariance Parameters
-
-Gradients of the Likelihood
Overall Process Scale
Capacity Control and Data Fit
Learning Covariance Parameters
Capacity Control through the Determinant
-
-
-
-
-
-
-
-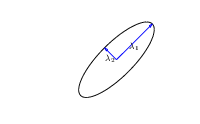 -
-\(\boldsymbol{ \Lambda}\) represents distance on axes. \(\mathbf{R}\) gives rotation.
-
-
-
-
-
-
-
-
-
-
-
-
-
-Quadratic Data Fit
-
-
-
-
-
-
-
-
-
-
-
-Data Fit Term
-
-x = np.linspace(-1, 1, 6)[:, np.newaxis]
+\]Capacity Control through the Determinant
 \(\boldsymbol{ \Lambda}\) represents distance on axes. \(\mathbf{R}\) gives rotation.
Quadratic Data Fit
Data Fit Term
-x = np.linspace(-1, 1, 6)[:, np.newaxis]
xtest = np.linspace(x_lim[0], x_lim[1], 200)[:, np.newaxis]
# True data
true_kernel = Kernel(eq_cov, name='Exponentiated Quadratic', shortname='eq', lengthscale=1)
K = true_kernel.K(x) + np.eye(6)*0.01
-y = np.random.multivariate_normal(np.zeros((6,)), K, 1).T
+y = np.random.multivariate_normal(np.zeros((6,)), K, 1).T
-
# Fitted model
kernel = Kernel(eq_cov, name='Exponentiated Quadratic', shortname='eq', lengthscale=1)
-gp = GP(x, y, sigma2=0.01, kernel=kernel)
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Exponentiated Quadratic Covariance
-
-Exponentiated Quadratic Covariance
-
-
-
-
-
-
-
-
-
-
-
-
-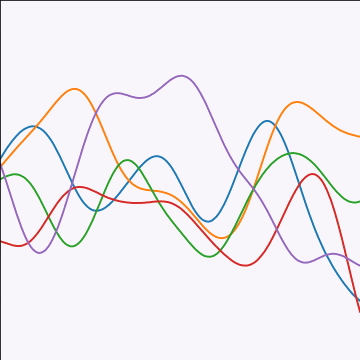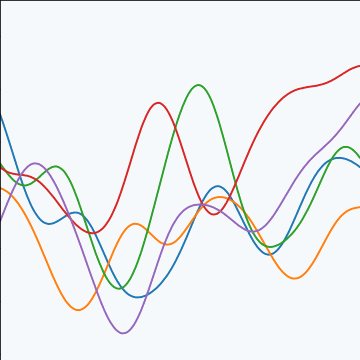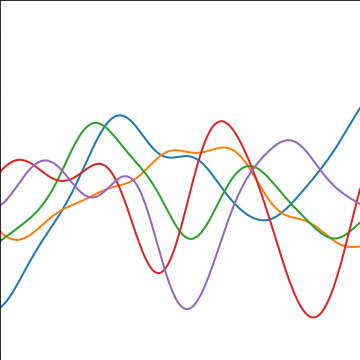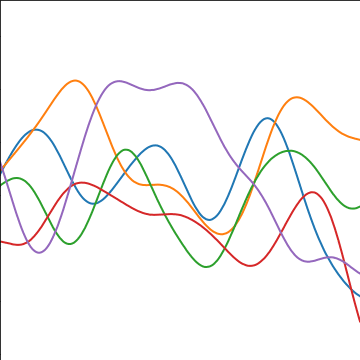 -
-
-
-
-
-
Where Did This Covariance Matrix Come From?
-
-
-from mlai import Kernel
-from mlai import eq_cov
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Brownian Covariance
-
-
-from mlai import brownian_cov
Where Did This Covariance Matrix Come From?
from mlai import Kernelfrom mlai import eq_covBrownian Covariance
from mlai import brownian_cov
-
-
-
-
-
-
-
-
-
-
-
-
- -
-
-
-
-
-
Where did this covariance matrix come from?
-
-
-
-Where did this covariance matrix come from?
-
-
-
-
-
-
-
-
-Covariance Functions
-
-
-
-
-
-
-
-
-Exponential Covariance
-
-
Where did this covariance matrix come from?
Where did this covariance matrix come from?
Covariance Functions
Exponential Covariance
-
-
-
-
-
-
-
-
-
-
-
-
- -
-
-
-
-
-
Basis Function Covariance
-
-
Basis Function Covariance
-from mlai import basis_cov
-from mlai import radial
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Degenerate Covariance Functions
-
-from mlai import basis_covfrom mlai import radialDegenerate Covariance Functions
Bochners Theoerem
-
-Bochners Theoerem
Sinc Covariance
-
-
-from mlai import sinc_cov
-
-
-
-
-
-
-
-
-
-
-
-
-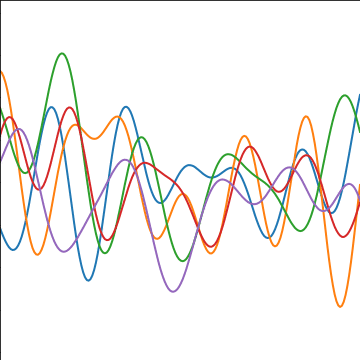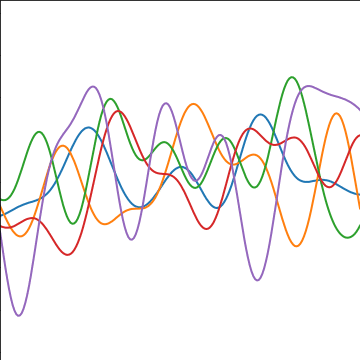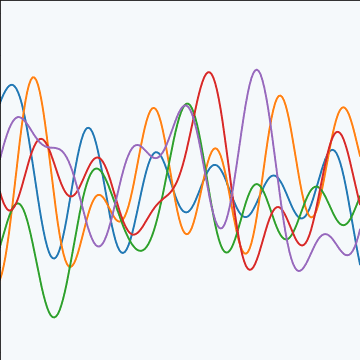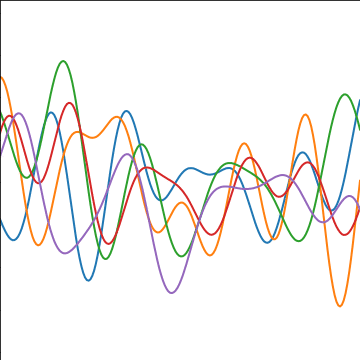 -
-
-
-
-
-
Matérn 3/2 Covariance
-
-Sinc Covariance
from mlai import sinc_cov
Matérn 3/2 Covariance
-
-
-
-
-
-
-
-
-
-
-
-
- -
-
-
-
-
-
Matérn 5/2 Covariance
-
-
Matérn 5/2 Covariance
-
-
-
-
-
-
-
-
-
-
-
-
-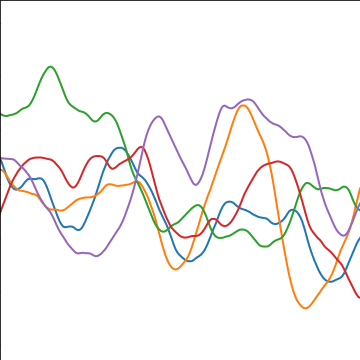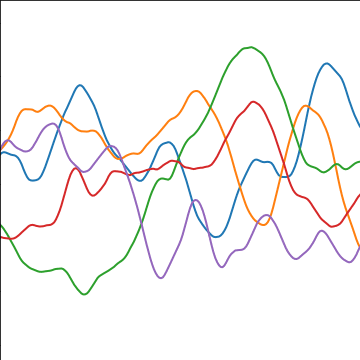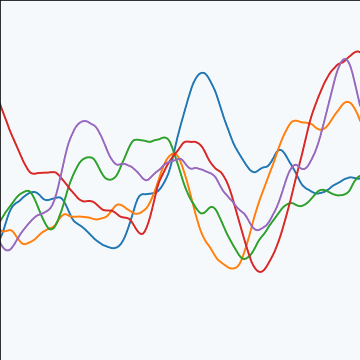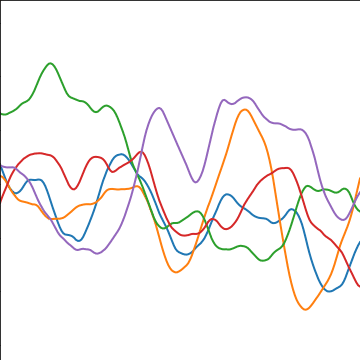 -
-
-
-
-
-
Rational Quadratic Covariance
-
-
Rational Quadratic Covariance
-
-
-
-
-
-
-
-
-
-
-
-
-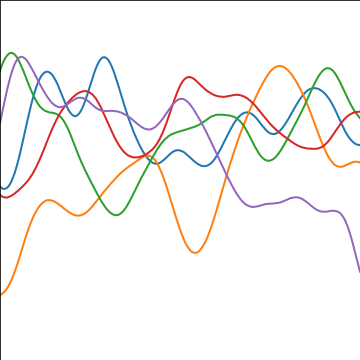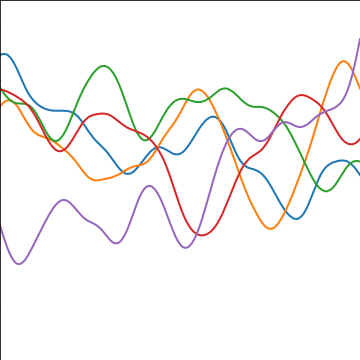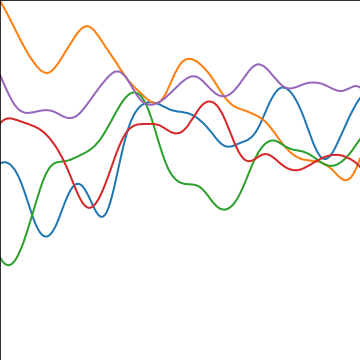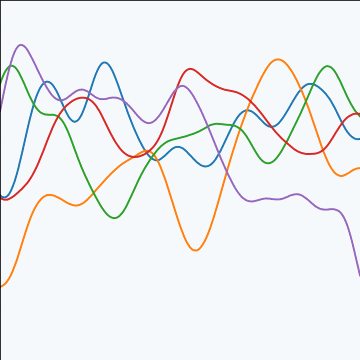 -
-
-
-
-
-
Polynomial Covariance
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Periodic Covariance
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-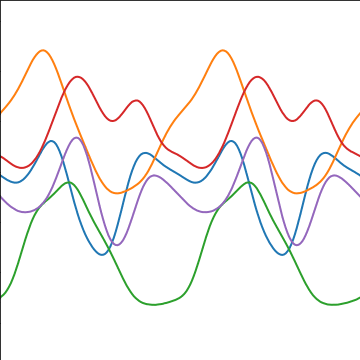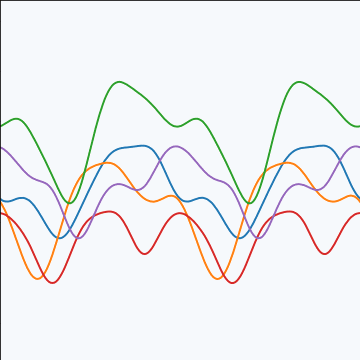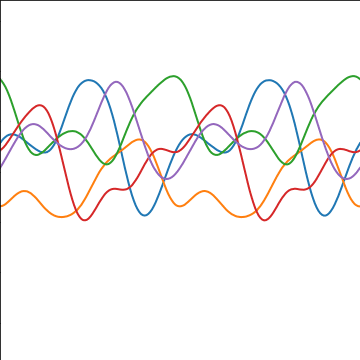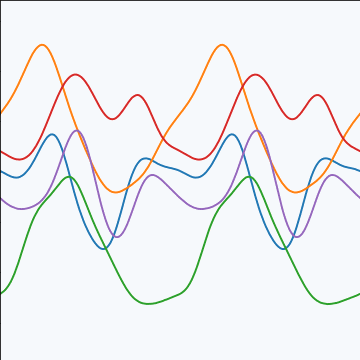 -
-
-
-
-
-
MLP Covariance
-
-
-from mlai import mlp_cov
-
-
-
-
-
-
-
-
-
-
-
-
- -
-
-
-
-
-
RELU Covariance
-
-
-from mlai import relu_cov
-
-
-
-
-
-
-
-
-
-
-
-
- -
-
-
-
-
-
Additive Covariance
-
-
Polynomial Covariance
Periodic Covariance

MLP Covariance
from mlai import mlp_cov
RELU Covariance
from mlai import relu_cov
Additive Covariance
-
-
-
-
-
-
-
-
-
-
-
-
-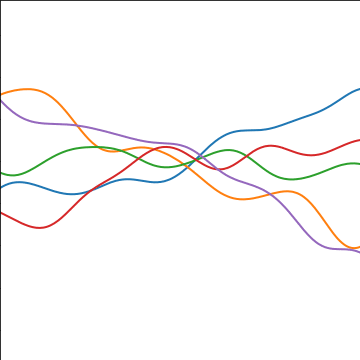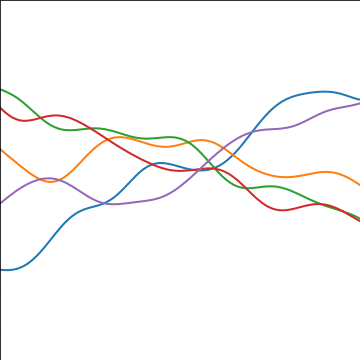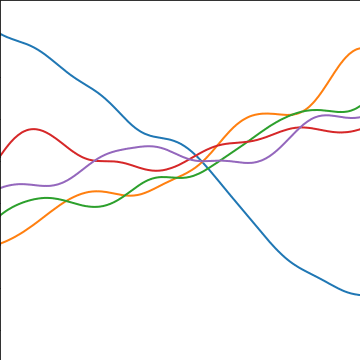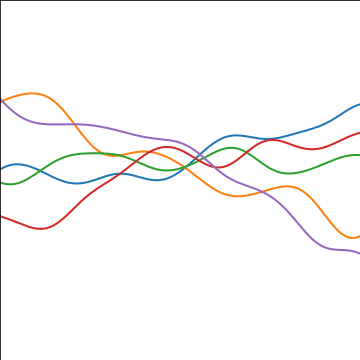 -
-
-
-
-
-
Product Covariance
-
-
Product Covariance
-
-
-
-
-
-
-
-
-
-
-
-
- -
-
-
-
-
-
Mauna Loa Data
-
-
-
-
-cmd = install_command('pods')
-%system {cmd}
-import numpy as np
-import pods
-data = pods.datasets.mauna_loa()refresh_data=True.data = pods.datasets.mauna_loa(refresh_data=True)
+\] Note that if \(g(\cdot)\) and \(h(\cdot)\) are Gaussian processes then \(f(\cdot)\) will not in general be a Gaussian process. So the base processes are (presumably) some (unspecified) non-Gaussian processes.
Mauna Loa Data
cmd = install_command('pods')%system {cmd}import numpy as np
+import podsdata = pods.datasets.mauna_loa()refresh_data=True.
-data = pods.datasets.mauna_loa(refresh_data=True)
x = data['X']
y = data['Y']
offset = y.mean()
-scale = np.sqrt(y.var())
-
-
-
-
-
-
-
-
-
-Xtest and Ytest which provide test data. The number of points considered to be training data is controlled by the argument num_train argument, which defaults to 545. This number is chosen as it matches that used in the Gaussian Processes for Machine Learning book (Rasmussen and Williams, 2006, chap. 5). Below we plot the test and training data.xtest = data['Xtest']
+scale = np.sqrt(y.var())Xtest and Ytest which provide test data. The number of points considered to be training data is controlled by the argument num_train argument, which defaults to 545. This number is chosen as it matches that used in the Gaussian Processes for Machine Learning book (Rasmussen and Williams, 2006, Chapter 5). Below we plot the test and training data.
-xtest = data['Xtest']
ytest = data['Ytest']
-ytesthat = (ytest-offset)/scale
-
-
-
-
-
-
-
-
-
-
-print(data['citation'])info and details.print(data['info'])
+ytesthat = (ytest-offset)/scaleprint(data['citation'])info and details.
-print(data['info'])
print()
-print(data['details'])
-print(data['license'])Gaussian Process Fit
-
-
-import GPykernel1 = GPy.kern.RBF(1, lengthscale=40, variance=300)
+print(data['details'])print(data['license'])Gaussian Process Fit
import GPy
-kernel1 = GPy.kern.RBF(1, lengthscale=40, variance=300)
kernel2 = GPy.kern.PeriodicMatern52(1, variance=4, period=1, lengthscale=0.2)
kernel3 = GPy.kern.RatQuad(1, lengthscale=5, variance=10, power=1)
kernel4 = GPy.kern.RBF(1, lengthscale=0.2, variance=1)
kernel5 = GPy.kern.Bias(1, variance=100)
kernel = kernel1 + kernel2 + kernel3 + kernel4 + kernel5
model = GPy.models.GPRegression(x,yhat, kernel=kernel)
-model.optimize(messages=True) # Optimize parameters of covariance functionmodel.optimize() optimizes the parameters of the covariance function and the noise level of the model. Once the fit is complete, we’ll try creating some test points, and computing the output of the GP model in terms of the mean and standard deviation of the posterior functions between 1870 and 2030. We plot the mean function and the standard deviation at 200 locations. We can obtain the predictions using y_mean, y_var = model.predict(xt)xt = np.linspace(xlim[0],xlim[1],300)[:,np.newaxis]
+model.optimize(messages=True) # Optimize parameters of covariance functionmodel.optimize() optimizes the parameters of the covariance function and the noise level of the model. Once the fit is complete, we’ll try creating some test points, and computing the output of the GP model in terms of the mean and standard deviation of the posterior functions between 1870 and 2030. We plot the mean function and the standard deviation at 200 locations. We can obtain the predictions using y_mean, y_var = model.predict(xt)
-xt = np.linspace(xlim[0],xlim[1],300)[:,np.newaxis]
yt_mean, yt_var = model.predict(xt)
-yt_sd=np.sqrt(yt_var)mlai.plot.
-
-
-
-
-
-
-
-
-
-Box Jenkins Airline Passenger Data
-
-
-import numpy as np
-import podsdata = pods.datasets.boxjenkins_airline()
+yt_sd=np.sqrt(yt_var)mlai.plot.Box Jenkins Airline Passenger Data
import numpy as np
+import pods
-data = pods.datasets.boxjenkins_airline()
x = data['X']
y = data['Y']
xtest = data['Xtest']
ytest = data['Ytest']
offset = y.mean()
-scale = np.sqrt(y.var())
-
-
-
-
-
-
-
-
-
-Gaussian Process Fit
-
-
-import GPykernel1 = GPy.kern.RBF(1, lengthscale=40, variance=300)
+scale = np.sqrt(y.var())Gaussian Process Fit
import GPy
-kernel1 = GPy.kern.RBF(1, lengthscale=40, variance=300)
kernel2 = GPy.kern.PeriodicMatern52(1, variance=4, period=1, lengthscale=0.2)
kernel3 = GPy.kern.RatQuad(1, lengthscale=5, variance=10, power=1)
kernel4 = GPy.kern.RBF(1, lengthscale=0.2, variance=1)
kernel5 = GPy.kern.Bias(1, variance=100)
kernel = kernel1 + kernel2 + kernel3 + kernel4 + kernel5
model = GPy.models.GPRegression(x,yhat, kernel=kernel)
-model.optimize(messages=True) # Optimize parameters of covariance functionmodel.optimize() optimizes the parameters of the covariance function and the noise level of the model. Once the fit is complete, we’ll try creating some test points, and computing the output of the GP model in terms of the mean and standard deviation of the posterior functions between 1948 and 1958. We plot the mean function and the standard deviation at 200 locations. We can obtain the predictions using y_mean, y_var = model.predict(xt)xt = np.linspace(xlim[0],xlim[1],300)[:,np.newaxis]
+model.optimize(messages=True) # Optimize parameters of covariance functionmodel.optimize() optimizes the parameters of the covariance function and the noise level of the model. Once the fit is complete, we’ll try creating some test points, and computing the output of the GP model in terms of the mean and standard deviation of the posterior functions between 1948 and 1958. We plot the mean function and the standard deviation at 200 locations. We can obtain the predictions using y_mean, y_var = model.predict(xt)
-xt = np.linspace(xlim[0],xlim[1],300)[:,np.newaxis]
yt_mean, yt_var = model.predict(xt)
-yt_sd=np.sqrt(yt_var)mlai.plot.
-
-
-
-
-
-
-
-
-
-Spectral Mixture Kernel
-
-Box-Jenkins Airline Spectral Mixture
-
-
-import podsdata = pods.datasets.boxjenkins_airline()
+yt_sd=np.sqrt(yt_var)mlai.plot.Spectral Mixture Kernel
Box-Jenkins Airline Spectral Mixture
import pods
-data = pods.datasets.boxjenkins_airline()
x = data['X']
-y = data['Y']
-import GPynum_comps = 10
+y = data['Y']import GPy
-num_comps = 10
kernel = GPy.kern.ExpQuadCosine(1)
for i in range(num_comps-1):
kernel += GPy.kern.ExpQuadCosine(1)
@@ -1017,33 +152,9 @@ Box-Jenkins Airline Spectral Mixtu
#model['.*lengthscale'] = np.random.uniform(0.0, 6.0, size=model['.*lengthscale'].shape)
#model['.*bandwidth'] = 2./np.sqrt(np.random.gamma(1.0, 0.5*(X.max()-X.min()), size=model['.*bandwidth'].shape))
#model['.*variance'] = 5.0
-display(model)
-model.optimize(messages=True)
-display(model)
-
-
-
-
-
-
-
-
-
-Mauna Loa Spectral Mixture
-
-
-import podsdata = pods.datasets.mauna_loa()
+display(model)model.optimize(messages=True)display(model)Mauna Loa Spectral Mixture
import pods
-data = pods.datasets.mauna_loa()
x = data['X']
-y = data['Y']
-import GPynum_comps = 10
+y = data['Y']import GPy
-num_comps = 10
kernel = GPy.kern.ExpQuadCosine(1)
for i in range(num_comps-1):
kernel += GPy.kern.ExpQuadCosine(1)
@@ -1054,53 +165,5 @@ Mauna Loa Spectral Mixture
#model['.*bandwidth'] = 2./np.sqrt(np.random.gamma(1.0, 0.5*(X.max()-X.min()), size=model['.*bandwidth'].shape))
#model['.*variance'] = 5.0
#model['.*bias_variance'] = 90000
-display(model)
-model.optimize(messages=True)
-display(model)
-
-
-
-
-
-
-
-
-
-Thanks!
-
-
-References
-
-
+display(model)
-Bochner, S., 1959. Lectures on Fourier integrals. Princeton University Press.
-
-
-Box, G.E.P., Jenkins, G.M., 1976. Time series analysis: Forecasting and control. Holden-Day.
-
-
-Keeling, C.D., Bacastow, R.B., Bainbridge, A.E., Ekdahl Jr., C.A., Guenther, P.R., Waterman, L.S., Chin, J.F.S., 1976. Atmospheric carbon dioxide variations at Mauna Loa Observatory, Hawaii. Tellus 28, 538–551. https://doi.org/10.1111/j.2153-3490.1976.tb00701.x
-
-
-Rasmussen, C.E., Williams, C.K.I., 2006. Gaussian processes for machine learning. mit, Cambridge, MA.
-
-
-Stein, M.L., 1999. Interpolation of spatial data: Some theory for Kriging. springer.
-
-
-Thoning, K.W., Tans, P.P., Komhyr, W.D., 1989. Atmospheric carbon dioxide at Mauna Loa Observatory: 2. Analysis of the NOAA GMCC data, 1974–1985. Journal of Geophysical Research: Atmospheres 94, 8549–8565. https://doi.org/10.1029/JD094iD06p08549
-
-model.optimize(messages=True)display(model)Thanks!
References
diff --git a/_lectures/04-optimizing-parameters.html b/_lectures/04-optimizing-parameters.html
index 4c9cf81..61e6517 100644
--- a/_lectures/04-optimizing-parameters.html
+++ b/_lectures/04-optimizing-parameters.html
@@ -15,355 +15,55 @@
-
-
-
-
-
-
-
-
-Bochner, S., 1959. Lectures on Fourier integrals. Princeton University Press.Box, G.E.P., Jenkins, G.M., 1976. Time series analysis: Forecasting and control. Holden-Day.Keeling, C.D., Bacastow, R.B., Bainbridge, A.E., Ekdahl Jr., C.A., Guenther, P.R., Waterman, L.S., Chin, J.F.S., 1976. Atmospheric carbon dioxide variations at Mauna Loa Observatory, Hawaii. Tellus 28, 538–551. https://doi.org/10.1111/j.2153-3490.1976.tb00701.xRasmussen, C.E., Williams, C.K.I., 2006. Gaussian processes for machine learning. mit, Cambridge, MA.Stein, M.L., 1999. Interpolation of spatial data: Some theory for Kriging. springer.Thoning, K.W., Tans, P.P., Komhyr, W.D., 1989. Atmospheric carbon dioxide at Mauna Loa Observatory: 2. Analysis of the NOAA GMCC data, 1974–1985. Journal of Geophysical Research: Atmospheres 94, 8549–8565. https://doi.org/10.1029/JD094iD06p08549Gaussian Process Summer School notebook setup
-
-
-import importlib.util
-cmd = install_command('pods')
-%system {cmd}
-cmd = install_command('notutils')
-%system {cmd}
-cmd = install_command('mlai')
-%system {cmd}Gaussian Process Summer School notebook setup
import importlib.utilcmd = install_command('pods')%system {cmd}cmd = install_command('notutils')%system {cmd}cmd = install_command('mlai')
-%system {cmd}
-cmd = install_command('GPy')
-%system {cmd}GPy: A Gaussian Process Framework in Python
-
-
-
-
-
-
-
-
-
-
-
-
-
-Improving the Numerics
-
-
-import scipy.linalg as la
-from mlai import GP
-from mlai import update_inverse
-# Bind the updated inverse to our GP model
-GP.update_inverse = update_inverseCapacity Control
-cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python
Improving the Numerics
import scipy.linalg as lafrom mlai import GPfrom mlai import update_inverse# Bind the updated inverse to our GP model
+GP.update_inverse = update_inverseCapacity Control
Gradients of the Likelihood
-Overall Process Scale
-Capacity Control and Data Fit
-Learning Covariance Parameters
-
-Gradients of the Likelihood
Overall Process Scale
Capacity Control and Data Fit
Learning Covariance Parameters
Capacity Control through the Determinant
-
-
-
-
-
-
-
-
-
-\(\boldsymbol{ \Lambda}\) represents distance on axes. \(\mathbf{R}\) gives rotation.
-
-
-
-
-
-
-
-
-
-
-
-
-
-Quadratic Data Fit
-
-
-
-
-
-
-
-
-
-
-
-Data Fit Term
-
-x = np.linspace(-1, 1, 6)[:, np.newaxis]
+\]Capacity Control through the Determinant
\(\boldsymbol{ \Lambda}\) represents distance on axes. \(\mathbf{R}\) gives rotation.Quadratic Data Fit
Data Fit Term
-x = np.linspace(-1, 1, 6)[:, np.newaxis]
xtest = np.linspace(x_lim[0], x_lim[1], 200)[:, np.newaxis]
# True data
true_kernel = Kernel(eq_cov, name='Exponentiated Quadratic', shortname='eq', lengthscale=1)
K = true_kernel.K(x) + np.eye(6)*0.01
-y = np.random.multivariate_normal(np.zeros((6,)), K, 1).T
+y = np.random.multivariate_normal(np.zeros((6,)), K, 1).T
-
# Fitted model
kernel = Kernel(eq_cov, name='Exponentiated Quadratic', shortname='eq', lengthscale=1)
-gp = GP(x, y, sigma2=0.01, kernel=kernel)
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Gene Expression Example
-
-Della Gatta Gene Data
-
-
-
-
-import numpy as np
-import podsdata = pods.datasets.della_gatta_TRP63_gene_expression(data_set='della_gatta',gene_number=937)
+gp = GP(x, y, sigma2=0.01, kernel=kernel)Gene Expression Example
Della Gatta Gene Data
import numpy as np
+import pods
-data = pods.datasets.della_gatta_TRP63_gene_expression(data_set='della_gatta',gene_number=937)
x = data['X']
y = data['Y']
offset = y.mean()
-scale = np.sqrt(y.var())
-
-
-
-
-
-
-
-
-
-
-
-
-\freddieKalaitzisPicture{15%}
-
-
-
-
-
-
-
-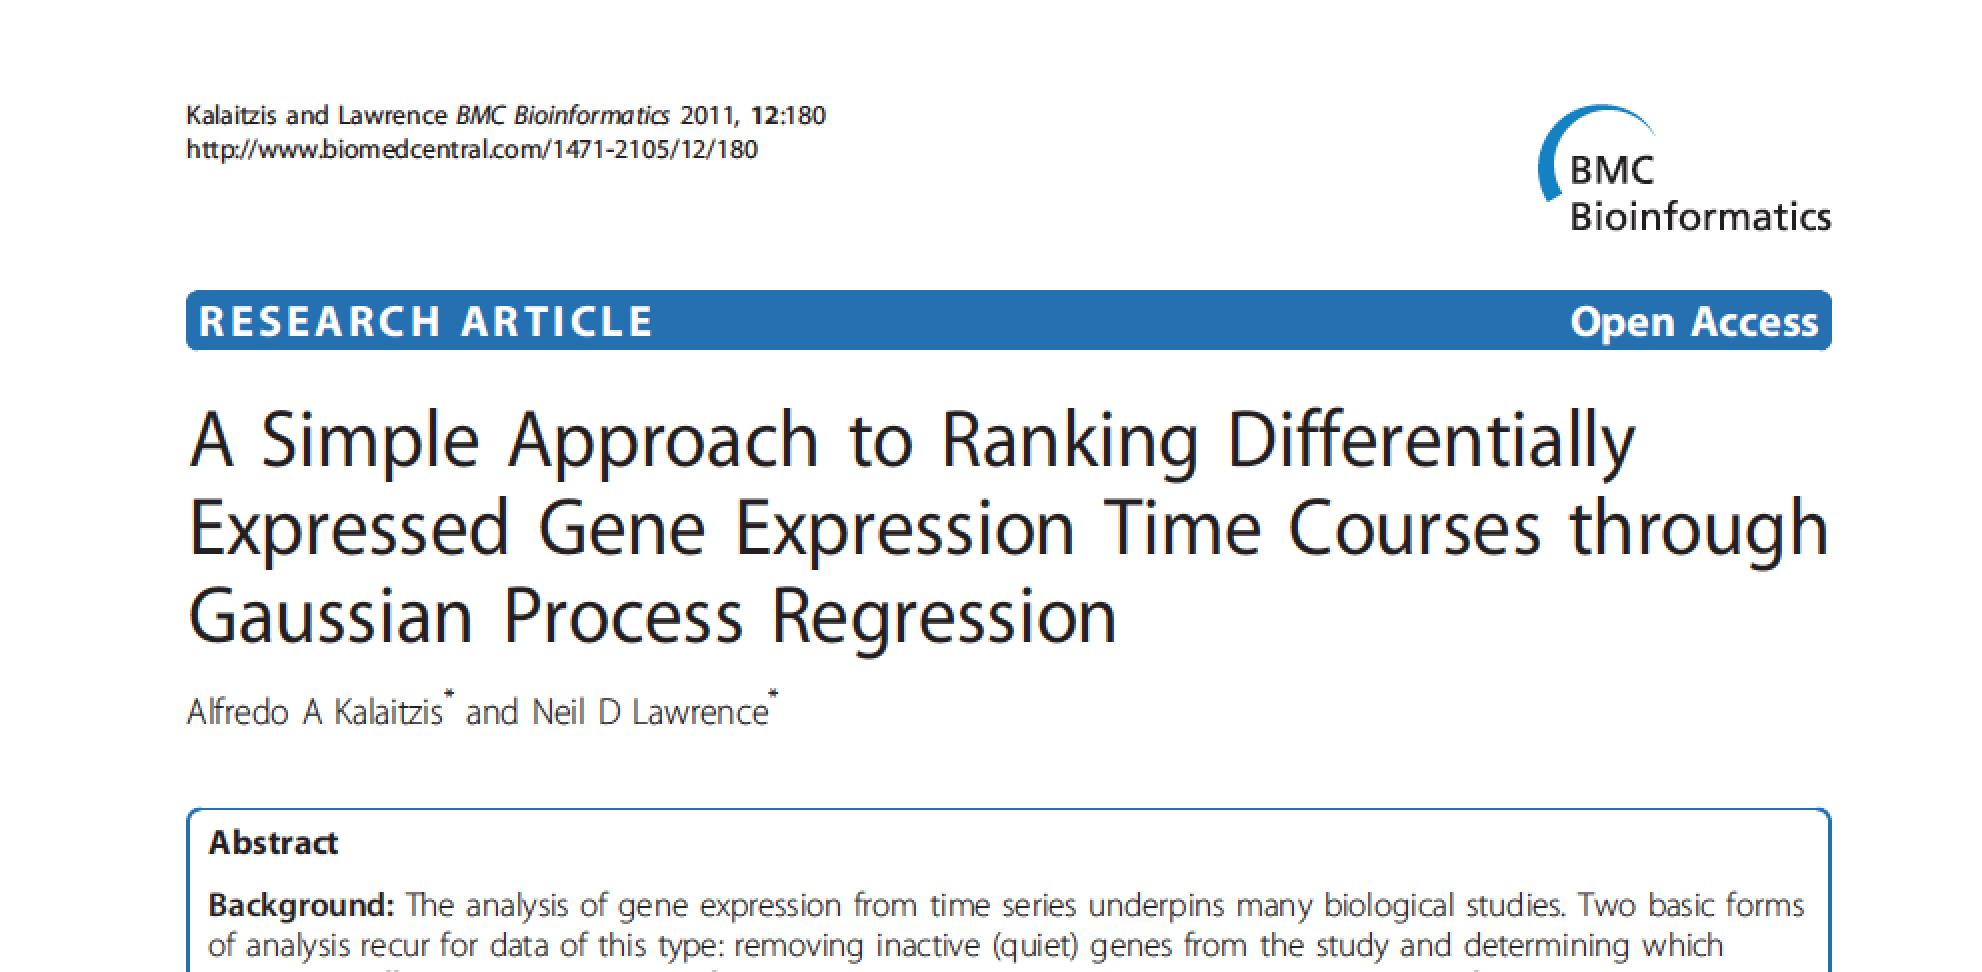 -
-
-
-
-
-
-
import GPym_full = GPy.models.GPRegression(x,yhat)
+scale = np.sqrt(y.var())\freddieKalaitzisPicture{15%}
import GPy
-m_full = GPy.models.GPRegression(x,yhat)
m_full.kern.lengthscale=50
-_ = m_full.optimize() # Optimize parameters of covariance functionxt = np.linspace(-20,260,200)[:,np.newaxis]
+_ = m_full.optimize() # Optimize parameters of covariance function
-xt = np.linspace(-20,260,200)[:,np.newaxis]
yt_mean, yt_var = m_full.predict(xt)
-yt_sd=np.sqrt(yt_var)mlai.plot.
-
-
-
-
-
-
-
-
-
-m_full2 = GPy.models.GPRegression(x,yhat)
+yt_sd=np.sqrt(yt_var)mlai.plot.
-m_full2 = GPy.models.GPRegression(x,yhat)
m_full2.kern.lengthscale=2000
-_ = m_full2.optimize() # Optimize parameters of covariance function
-
-
-
-
-
-
-
-
-
-m_full3 = GPy.models.GPRegression(x,yhat)
+_ = m_full2.optimize() # Optimize parameters of covariance function
-m_full3 = GPy.models.GPRegression(x,yhat)
m_full3.kern.lengthscale=20
m_full3.likelihood.variance=0.001
-_ = m_full3.optimize() # Optimize parameters of covariance function
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Thanks!
-
-
-References
-
-
+-->
-Della Gatta, G., Bansal, M., Ambesi-Impiombato, A., Antonini, D., Missero, C., Bernardo, D. di, 2008. Direct targets of the TRP63 transcription factor revealed by a combination of gene expression profiling and reverse engineering. Genome Research 18, 939–948. https://doi.org/10.1101/gr.073601.107
-
-
-Kalaitzis, A.A., Lawrence, N.D., 2011. A simple approach to ranking differentially expressed gene expression time courses through Gaussian process regression. BMC Bioinformatics 12. https://doi.org/10.1186/1471-2105-12-180
-
-Thanks!
References
diff --git a/_lectures/05-multi-output-gps.html b/_lectures/05-multi-output-gps.html
index 9df10f0..63d3cd9 100644
--- a/_lectures/05-multi-output-gps.html
+++ b/_lectures/05-multi-output-gps.html
@@ -7,7 +7,6 @@
featured_image: slides/diagrams//kern/kronecker_KI.svg
reveal: 05-multi-output-gps.slides.html
ipynb: 05-multi-output-gps.ipynb
-pptx: 05-multi-output-gps.pptx
youtube: "MkkeBmEZ8LE"
layout: lecture
categories:
@@ -16,13 +15,13 @@
-Della Gatta, G., Bansal, M., Ambesi-Impiombato, A., Antonini, D., Missero, C., Bernardo, D. di, 2008. Direct targets of the TRP63 transcription factor revealed by a combination of gene expression profiling and reverse engineering. Genome Research 18, 939–948. https://doi.org/10.1101/gr.073601.107Kalaitzis, A.A., Lawrence, N.D., 2011. A simple approach to ranking differentially expressed gene expression time courses through Gaussian process regression. BMC Bioinformatics 12. https://doi.org/10.1186/1471-2105-12-180Gaussian Process Summer School notebook setup
import importlib.utilcmd = install_command('pods')%system {cmd}cmd = install_command('notutils')%system {cmd}cmd = install_command('mlai')%system {cmd}cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python
Simple Kalman Filter
cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python
Simple Kalman Filter
Kronecker Product
Stacking and Kronecker Products
Kronecker Product
Stacking and Kronecker Products
Column Stacking
Two Ways of Stacking
Column Stacking
Two Ways of Stacking
Row Stacking
Mapping from Latent Process to Observed
Observed Process
Row Stacking
Mapping from Latent Process to Observed
Observed Process
Output Covariance
Output Covariance
Intrinsic Coregionalization Model Covariance
from mlai import icm_cov
Intrinsic Coregionalization Model
Intrinsic Coregionalization Model Covariance
from mlai import icm_cov
Intrinsic Coregionalization Model
Gaussian processes for Multi-task, Multi-output and Multi-class
Multitask Classification
Computer Emulation
Modelling Multiple Outputs
Running Example
Olympic Sprint Data
cmd = install_command('pods')%system {cmd}import pods
+\]Gaussian processes for Multi-task, Multi-output and Multi-class
Multitask Classification
Computer Emulation
Modelling Multiple Outputs
Running Example
Olympic Sprint Data

cmd = install_command('pods')%system {cmd}import pods
import numpy as npdata = pods.datasets.olympic_sprints()
X = data['X']
y = data['Y']
print(data['info'], data['details'])data['citation']print(data['citation'])data['output_info']print(data['output_info'])GPy we deal with multiple output data in a particular way. We specify the output we are interested in for modelling as an additional input. So whilst for this data, normally, the only input would be the year of the event. We additionally have an input giving the index of the output we are modelling. This can be seen from examining data['X'].print('First column of X contains the olympic years.')
print(data['X'][:, 0])
print('Second column of X contains the event index.')
-print(data['X'][:, 1])Gaussian Process Fit
cmd = install_command('GPy')%system {cmd}** operator. Stricly speaking this operator means to the power of (like ^ in MATLAB). But for covariance functions we’ve used it to indicate a tensor product. The linear models of coregionalization we introduced in the lecture were all based on combining a matrix with a standard covariance function. We can think of the matrix as a particular type of covariance function, whose elements are referenced using the event indices. I.e. \(k(0, 0)\) references the first row and column of the coregionalization matrix. \(k(1, 0)\) references the second row and first column of the coregionalization matrix. Under this set up, we want to build a covariance where the first column from the features (the years) is passed to a covariance function, and the second column from the features (the event number) is passed to the coregionalisation matrix. Let’s start by trying a intrinsic coregionalisation model (sometimes known as multitask Gaussian processes). Let’s start by checking the help for the Coregionalize covariance.import GPyGPy.kern.Coregionalize?kern = GPy.kern.RBF(1, lengthscale=80)**GPy.kern.Coregionalize(1,output_dim=6, rank=5)model = GPy.models.GPRegression(X, y, kern)
-model.optimize()model.plot() function. We can specify that column 1 should be fixed to event number 2 by passing fixed_inputs = [(1, 2)] to the model. To plot the results for all events on the same figure we also specify fignum=1 in the loop as below.kern1 = GPy.kern.RBF(1, lengthscale=80)**GPy.kern.Coregionalize(1, output_dim=6, rank=1)
+print(data['X'][:, 1])Gaussian Process Fit
cmd = install_command('GPy')%system {cmd}** operator. Stricly speaking this operator means to the power of (like ^ in MATLAB). But for covariance functions we’ve used it to indicate a tensor product. The linear models of coregionalization we introduced in the lecture were all based on combining a matrix with a standard covariance function. We can think of the matrix as a particular type of covariance function, whose elements are referenced using the event indices. I.e. \(k(0, 0)\) references the first row and column of the coregionalization matrix. \(k(1, 0)\) references the second row and first column of the coregionalization matrix. Under this set up, we want to build a covariance where the first column from the features (the years) is passed to a covariance function, and the second column from the features (the event number) is passed to the coregionalisation matrix. Let’s start by trying a intrinsic coregionalisation model (sometimes known as multitask Gaussian processes). Let’s start by checking the help for the Coregionalize covariance.import GPyGPy.kern.Coregionalize?kern = GPy.kern.RBF(1, lengthscale=80)**GPy.kern.Coregionalize(1,output_dim=6, rank=5)model = GPy.models.GPRegression(X, y, kern)
+model.optimize()model.plot() function. We can specify that column 1 should be fixed to event number 2 by passing fixed_inputs = [(1, 2)] to the model. To plot the results for all events on the same figure we also specify fignum=1 in the loop as below.kern1 = GPy.kern.RBF(1, lengthscale=80)**GPy.kern.Coregionalize(1, output_dim=6, rank=1)
kern2 = GPy.kern.Bias(1)**GPy.kern.Coregionalize(1,output_dim=6, rank=1)
kern = kern1 + kern2model = GPy.models.GPRegression(X, y, kern)
-model.optimize()kern1 = GPy.kern.RBF(1, lengthscale=80) + GPy.kern.Bias(1)
+model.optimize()kern1 = GPy.kern.RBF(1, lengthscale=80) + GPy.kern.Bias(1)
kern2 = GPy.kern.Coregionalize(1, output_dim=6, rank=5)
kern = kern1**kern2model = GPy.models.GPRegression(X, y, kern)
-model.optimize()Thanks!
References
+model.optimize()Bonilla, E.V., Chai, K.M., Williams, C.K.I., n.d. Multi-task Gaussian process prediction.Conti, S., O’Hagan, A., 2009. Bayesian emulation of complex multi-output and dynamic computer models. Journal of Statistical Planning and Inference 140, 640–651. https://doi.org/doi:10.1016/j.jspi.2009.08.006Goovaerts, P., 1997. Geostatistics For Natural Resources Evaluation. Oxford University Press.Helterbrand, J.D., Cressie, N.A.C., 1994. Universal cokriging under intrinsic coregionalization. Mathematical Geology 26, 205–226.Higdon, D.M., Gattiker, J., Williams, B., Rightley, M., 2008. Computer model calibration using high dimensional output. Journal of the American Statistical Association 103, 570–583.Journel, A.G., Huijbregts, C.J., 1978. Mining geostatistics. Academic Press, London.Lawrence, N.D., Platt, J.C., 2004. Learning to learn with the informative vector machine. pp. 512–519. https://doi.org/10.1145/1015330.1015382Minka, T.P., Picard, R.W., 1997. Learning how to learn is learning with point sets.Rasmussen, C.E., Williams, C.K.I., 2006. Gaussian processes for machine learning. mit, Cambridge, MA.Rogers, S., Girolami, M., 2011. A first course in machine learning. CRC Press.Seeger, M., Jordan, M.I., 2004. Sparse Gaussian Process classification with multiple classes (No. 661). Department of Statistics, University of California at Berkeley.Skolidis, G., Sanguinetti, G., 2011. Bayesian multitask classification with Gaussian process priors. IEEE Transactions on Neural Networks 22, 2011–2021.Teh, Y.W., Seeger, M., Jordan, M.I., n.d. Semiparametric latent factor models. pp. 333–340.Wackernagel, H., 2003. Multivariate geostatistics: An introduction with applications, 3rd ed. springer.Williams, C.K.I., Barber, D., 1998. Bayesian Classification with Gaussian processes. IEEE Transactions on Pattern Analysis and Machine Intelligence 20, 1342–1351.Woodward, I., Lomas, M.R., Betts, R.A., 1998. Vegetation-climate feedbacks in a greenhouse world. Philosophical Transactions: Biological Sciences 353, 29–39.Yu, K., Tresp, V., Schwaighofer, A., 2005. Learning Gaussian processes from multiple tasks, in: Proceedings of the 22nd International Conference on Machine Learning (ICML 2005). pp. 1012–1019.Thanks!
References
diff --git a/_lectures/06-approximate-gps.html b/_lectures/06-approximate-gps.html
index f8ea63f..322b629 100644
--- a/_lectures/06-approximate-gps.html
+++ b/_lectures/06-approximate-gps.html
@@ -7,7 +7,6 @@
featured_image: slides/diagrams/gp/sparse-demo-unconstrained-inducing-6-gp.svg
reveal: 06-approximate-gps.slides.html
ipynb: 06-approximate-gps.ipynb
-pptx: 06-approximate-gps.pptx
youtube: "b635kuSqLww"
layout: lecture
categories:
@@ -16,13 +15,13 @@
-Bonilla, E.V., Chai, K.M., Williams, C.K.I., n.d. Multi-task Gaussian process prediction.Conti, S., O’Hagan, A., 2009. Bayesian emulation of complex multi-output and dynamic computer models. Journal of Statistical Planning and Inference 140, 640–651. https://doi.org/doi:10.1016/j.jspi.2009.08.006Goovaerts, P., 1997. Geostatistics For Natural Resources Evaluation. Oxford University Press.Helterbrand, J.D., Cressie, N.A.C., 1994. Universal cokriging under intrinsic coregionalization. Mathematical Geology 26, 205–226.Higdon, D.M., Gattiker, J., Williams, B., Rightley, M., 2008. Computer model calibration using high dimensional output. Journal of the American Statistical Association 103, 570–583.Journel, A.G., Huijbregts, C.J., 1978. Mining geostatistics. Academic Press, London.Lawrence, N.D., Platt, J.C., 2004. Learning to learn with the informative vector machine. pp. 512–519. https://doi.org/10.1145/1015330.1015382Minka, T.P., Picard, R.W., 1997. Learning how to learn is learning with point sets.Rasmussen, C.E., Williams, C.K.I., 2006. Gaussian processes for machine learning. mit, Cambridge, MA.Rogers, S., Girolami, M., 2011. A first course in machine learning. CRC Press.Seeger, M., Jordan, M.I., 2004. Sparse Gaussian Process classification with multiple classes (No. 661). Department of Statistics, University of California at Berkeley.Skolidis, G., Sanguinetti, G., 2011. Bayesian multitask classification with Gaussian process priors. IEEE Transactions on Neural Networks 22, 2011–2021.Teh, Y.W., Seeger, M., Jordan, M.I., n.d. Semiparametric latent factor models. pp. 333–340.Wackernagel, H., 2003. Multivariate geostatistics: An introduction with applications, 3rd ed. springer.Williams, C.K.I., Barber, D., 1998. Bayesian Classification with Gaussian processes. IEEE Transactions on Pattern Analysis and Machine Intelligence 20, 1342–1351.Woodward, I., Lomas, M.R., Betts, R.A., 1998. Vegetation-climate feedbacks in a greenhouse world. Philosophical Transactions: Biological Sciences 353, 29–39.Yu, K., Tresp, V., Schwaighofer, A., 2005. Learning Gaussian processes from multiple tasks, in: Proceedings of the 22nd International Conference on Machine Learning (ICML 2005). pp. 1012–1019.Gaussian Process Summer School notebook setup
import importlib.utilcmd = install_command('pods')%system {cmd}cmd = install_command('notutils')%system {cmd}cmd = install_command('mlai')%system {cmd}cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python
Variational Compression
Variational Compression II
cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python

Variational Compression
Variational Compression II
 Figure: Figure originally from presentation by Ed Snelson at NIPS
 Figure: Figure originally from presentation by Ed Snelson at NIPS\[\mathbf{X},\,\mathbf{ y}\]
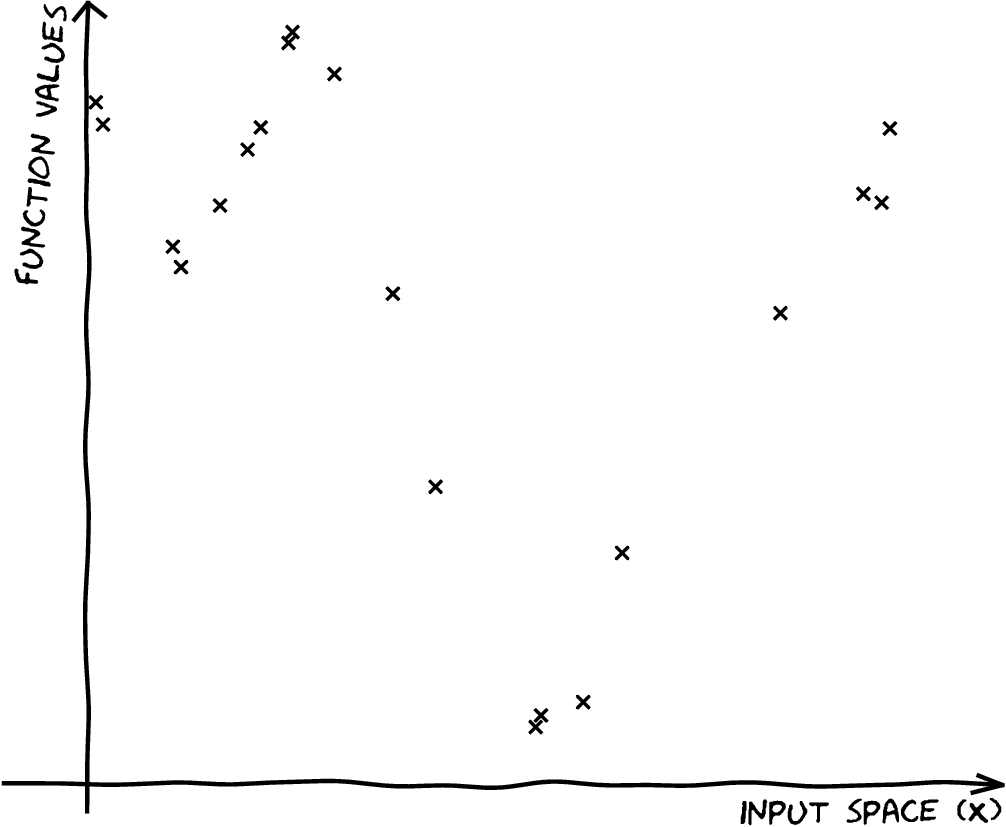 \[\mathbf{X},\,\mathbf{ y}\] \[{\color{blue} f(\mathbf{ x})} \sim {\mathcal GP}\]
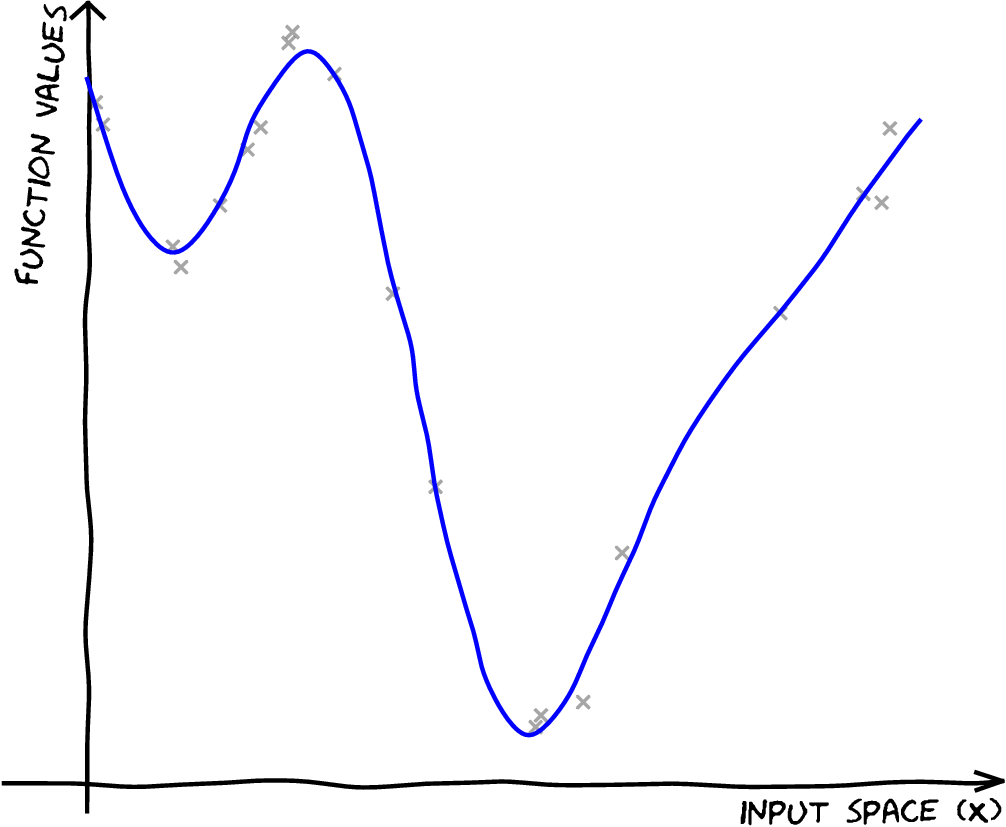 \[\mathbf{X},\,\mathbf{ y}\] \[f(\mathbf{ x}) \sim {\mathcal GP}\]\[p({\color{blue} \mathbf{ f}}) = \mathscr{N}\left(\mathbf{0},\mathbf{K}_{\mathbf{ f}\mathbf{ f}}\right)\]
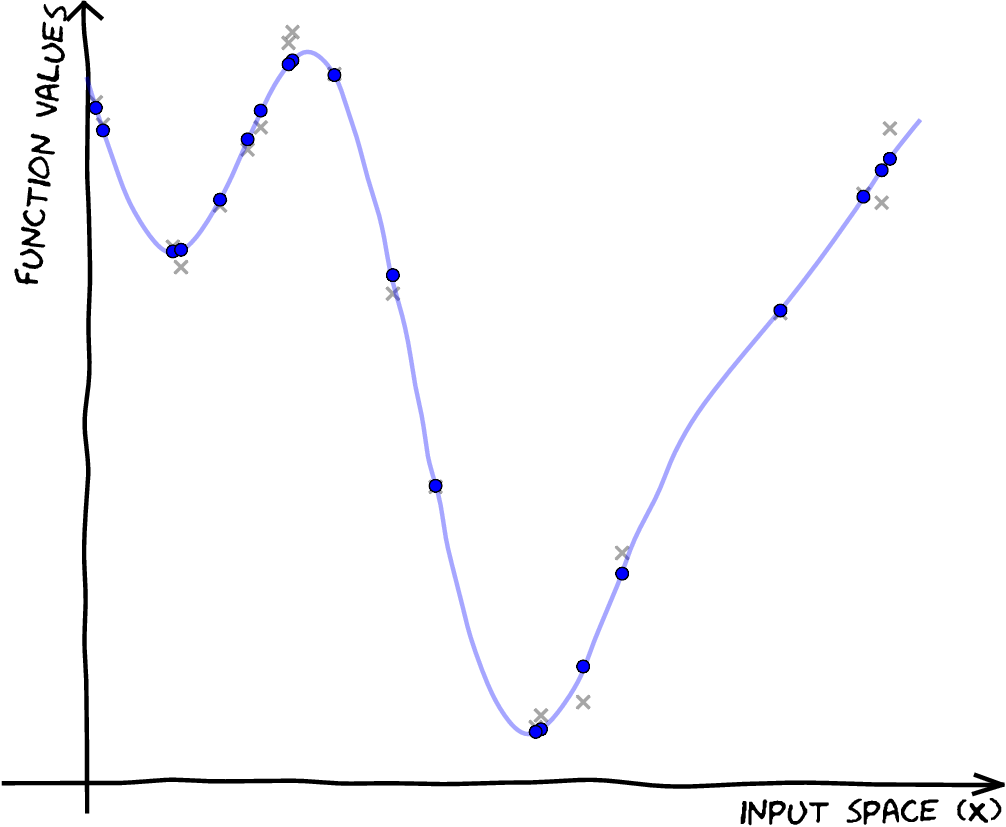 \[
+\] The idea is that instead of inverting \(\mathbf{K}_{\mathbf{ f}\mathbf{ f}}\), we make a low rank (or Nyström) approximation, and invert \(\mathbf{K}_{\mathbf{ u}\mathbf{ u}}\) instead.\[\mathbf{X},\,\mathbf{ y}\]
 \[\mathbf{X},\,\mathbf{ y}\] \[{\color{blue} f(\mathbf{ x})} \sim {\mathcal GP}\]
 \[\mathbf{X},\,\mathbf{ y}\] \[f(\mathbf{ x}) \sim {\mathcal GP}\]\[p({\color{blue} \mathbf{ f}}) = \mathscr{N}\left(\mathbf{0},\mathbf{K}_{\mathbf{ f}\mathbf{ f}}\right)\]
 \[
\mathbf{X},\,\mathbf{ y}\] \[f(\mathbf{ x}) \sim {\mathcal GP}
\] \[
p(\mathbf{ f}) = \mathscr{N}\left(\mathbf{0},\mathbf{K}_{\mathbf{ f}\mathbf{ f}}\right)
\] \[p( \mathbf{ f}|\mathbf{ y},\mathbf{X})
-\]
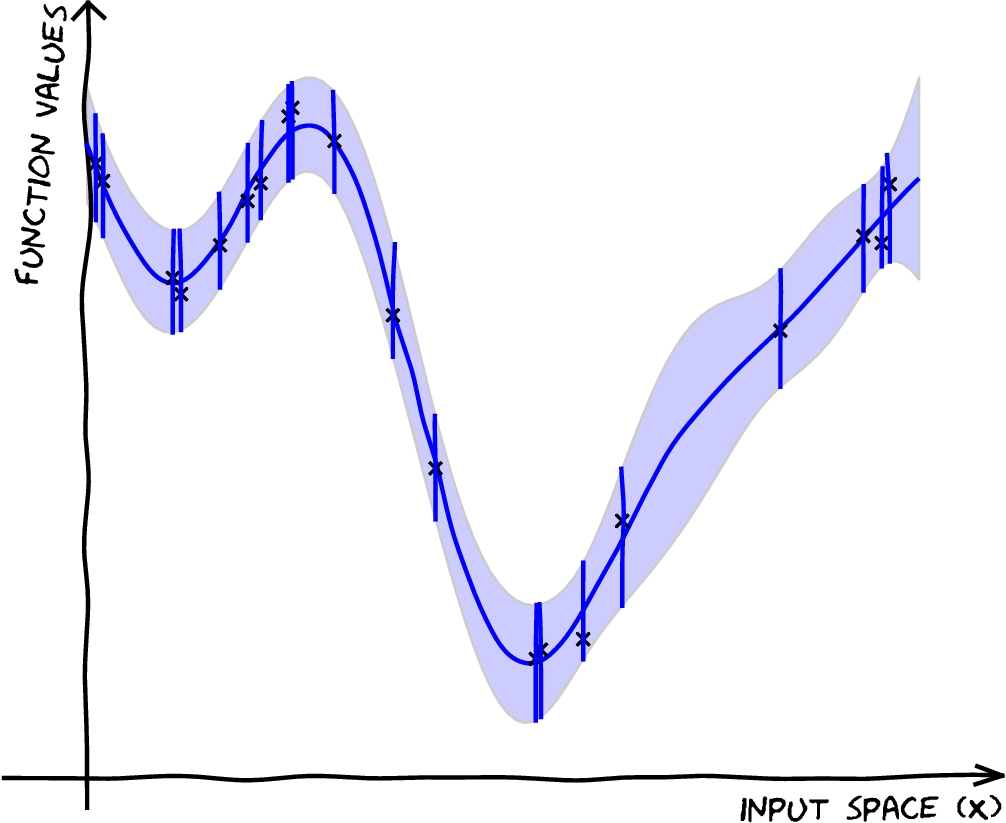


Variational Compression II
Titsias (n.d.)
+\]Titsias (n.d.)
Subset selectionLawrence et al. (n.d.)Quiñonero Candela and Rasmussen (2005)Snelson and Ghahramani (n.d.) \only<1->{\begin{tikzpicture}
% Define nodes
@@ -224,20 +223,20 @@
# Sample response variables from a Gaussian process with exponentiated quadratic covariance.
k = GPy.kern.RBF(1)
y = np.random.multivariate_normal(np.zeros(N),k.K(X)+np.eye(N)*np.sqrt(noise_var)).reshape(-1,1)m_full, and fit it to the data, plotting the resulting fit.m_full = GPy.models.GPRegression(X,y)
-_ = m_full.optimize(messages=True) # Optimize parameters of covariance functionkern = GPy.kern.RBF(1)
+_ = m_full.optimize(messages=True) # Optimize parameters of covariance functionkern = GPy.kern.RBF(1)
Z = np.hstack(
(np.linspace(2.5,4.,3),
np.linspace(7,8.5,3)))[:,None]
m = GPy.models.SparseGPRegression(X,y,kernel=kern,Z=Z)
m.noise_var = noise_var
m.inducing_inputs.constrain_fixed()
-display(m)_ = m.optimize(messages=True)
-display(m)m.randomize()
+display(m)_ = m.optimize(messages=True)
+display(m)m.randomize()
m.inducing_inputs.unconstrain()
-_ = m.optimize(messages=True)m.num_inducing=8
+_ = m.optimize(messages=True)m.num_inducing=8
m.randomize()
M = 8
m.set_Z(np.random.rand(M,1)*12)
-_ = m.optimize(messages=True)print(m.log_likelihood(), m_full.log_likelihood())Thanks!
References
+_ = m.optimize(messages=True)Álvarez, M.A., Luengo, D., Titsias, M.K., Lawrence, N.D., 2010. Efficient multioutput Gaussian processes through variational inducing kernels. pp. 25–32.Bui, T.D., Yan, J., Turner, R.E., 2017. A unifying framework for Gaussian process pseudo-point approximations using power expectation propagation. Journal of Machine Learning Research 18, 1–72.Csató, L., 2002. Gaussian processes — iterative sparse approximations (PhD thesis). Aston University.Csató, L., Opper, M., 2002. Sparse on-line Gaussian processes. Neural Computation 14, 641–668.Dai, Z., Damianou, A., Hensman, J., Lawrence, N.D., 2014. Gaussian process models with parallelization and GPU acceleration.Damianou, A., 2015. Deep Gaussian processes and variational propagation of uncertainty (PhD thesis). University of Sheffield.Damianou, A., Lawrence, N.D., 2013. Deep Gaussian processes. pp. 207–215.Damianou, A., Titsias, M.K., Lawrence, N.D., 2016. Variational inference for latent variables and uncertain inputs in Gaussian processes. Journal of Machine Learning Research 17, 1–62.Gal, Y., Wilk, M. van der, Rasmussen, C.E., n.d. Distributed variational inference in sparse Gaussian process regression and latent variable models.Hensman, J., Fusi, N., Lawrence, N.D., n.d. Gaussian processes for big data.Hensman, J., Lawrence, N.D., 2014. Nested variational compression in deep Gaussian processes. University of Sheffield.Hensman, J., Rattray, M., Lawrence, N.D., 2012. Fast variational inference in the conjugate exponential family.Hoffman, M., Blei, D.M., Wang, C., Paisley, J., 2012. Stochastic variational inference, arXiv preprint arXiv:1206.7051.King, N.J., Lawrence, N.D., n.d. Fast variational inference for Gaussian Process models through KL-correction. pp. 270–281.Lawrence, N.D., n.d. Learning for larger datasets with the Gaussian process latent variable model. pp. 243–250.Lawrence, N.D., Seeger, M., Herbrich, R., n.d. Fast sparse Gaussian process methods: The informative vector machine. pp. 625–632.Lázaro-Gredilla, M., Quiñonero-Candela, J., Rasmussen, C.E., 2010. Sparse spectrum gaussian processes. Journal of Machine Learning Research 11, 1865–1881.Quiñonero Candela, J., Rasmussen, C.E., 2005. A unifying view of sparse approximate Gaussian process regression. Journal of Machine Learning Research 6, 1939–1959.Salimbeni, H., Deisenroth, M., 2017. Doubly stochastic variational inference for deep Gaussian processes, in: Guyon, I., Luxburg, U.V., Bengio, S., Wallach, H., Fergus, R., Vishwanathan, S., Garnett, R. (Eds.), Advances in Neural Information Processing Systems 30. Curran Associates, Inc., pp. 4591–4602.Seeger, M.W., Hetzel, A., Dai, Z., Lawrence, N.D., 2017. Auto-differentiating linear algebra. CoRR abs/1710.08717.Seeger, M., Williams, C.K.I., Lawrence, N.D., n.d. Fast forward selection to speed up sparse Gaussian process regression.Smola, A.J., Bartlett, P.L., n.d. Sparse greedy Gaussian process regression. pp. 619–625.Snelson, E., Ghahramani, Z., n.d. Sparse Gaussian processes using pseudo-inputs.Titsias, M.K., n.d. Variational learning of inducing variables in sparse Gaussian processes. pp. 567–574.Williams, C.K.I., Seeger, M., n.d. Using the Nyström method to speed up kernel machines. pp. 682–688.print(m.log_likelihood(), m_full.log_likelihood())Thanks!
References
diff --git a/_lectures/07-non-gaussian-likelihoods.html b/_lectures/07-non-gaussian-likelihoods.html
index e4391f0..53681d7 100644
--- a/_lectures/07-non-gaussian-likelihoods.html
+++ b/_lectures/07-non-gaussian-likelihoods.html
@@ -1,5 +1,7 @@
---
title: "Non Gaussian Likelihoods"
+abstract: |-
+ null
edit_url: https://github.com/mlatcl/gpss/edit/gh-pages/_lamd/non-gaussian-likelihoods.md
week: 7
reveal: 07-non-gaussian-likelihoods.slides.html
@@ -11,227 +13,38 @@
-
-
-
-
-
-
-
-
-Álvarez, M.A., Luengo, D., Titsias, M.K., Lawrence, N.D., 2010. Efficient multioutput Gaussian processes through variational inducing kernels. pp. 25–32.Bui, T.D., Yan, J., Turner, R.E., 2017. A unifying framework for Gaussian process pseudo-point approximations using power expectation propagation. Journal of Machine Learning Research 18, 1–72.Csató, L., 2002. Gaussian processes — iterative sparse approximations (PhD thesis). Aston University.Csató, L., Opper, M., 2002. Sparse on-line Gaussian processes. Neural Computation 14, 641–668.Dai, Z., Damianou, A., Hensman, J., Lawrence, N.D., 2014. Gaussian process models with parallelization and GPU acceleration.Damianou, A., 2015. Deep Gaussian processes and variational propagation of uncertainty (PhD thesis). University of Sheffield.Damianou, A., Lawrence, N.D., 2013. Deep Gaussian processes. pp. 207–215.Damianou, A., Titsias, M.K., Lawrence, N.D., 2016. Variational inference for latent variables and uncertain inputs in Gaussian processes. Journal of Machine Learning Research 17, 1–62.Gal, Y., Wilk, M. van der, Rasmussen, C.E., n.d. Distributed variational inference in sparse Gaussian process regression and latent variable models.Hensman, J., Fusi, N., Lawrence, N.D., n.d. Gaussian processes for big data.Hensman, J., Lawrence, N.D., 2014. Nested variational compression in deep Gaussian processes. University of Sheffield.Hensman, J., Rattray, M., Lawrence, N.D., 2012. Fast variational inference in the conjugate exponential family.Hoffman, M., Blei, D.M., Wang, C., Paisley, J., 2012. Stochastic variational inference, arXiv preprint arXiv:1206.7051.King, N.J., Lawrence, N.D., n.d. Fast variational inference for Gaussian Process models through KL-correction. pp. 270–281.Lawrence, N.D., n.d. Learning for larger datasets with the Gaussian process latent variable model. pp. 243–250.Lawrence, N.D., Seeger, M., Herbrich, R., n.d. Fast sparse Gaussian process methods: The informative vector machine. pp. 625–632.Lázaro-Gredilla, M., Quiñonero-Candela, J., Rasmussen, C.E., 2010. Sparse spectrum gaussian processes. Journal of Machine Learning Research 11, 1865–1881.Quiñonero Candela, J., Rasmussen, C.E., 2005. A unifying view of sparse approximate Gaussian process regression. Journal of Machine Learning Research 6, 1939–1959.Salimbeni, H., Deisenroth, M., 2017. Doubly stochastic variational inference for deep Gaussian processes, in: Guyon, I., Luxburg, U.V., Bengio, S., Wallach, H., Fergus, R., Vishwanathan, S., Garnett, R. (Eds.), Advances in Neural Information Processing Systems 30. Curran Associates, Inc., pp. 4591–4602.Seeger, M.W., Hetzel, A., Dai, Z., Lawrence, N.D., 2017. Auto-differentiating linear algebra. CoRR abs/1710.08717.Seeger, M., Williams, C.K.I., Lawrence, N.D., n.d. Fast forward selection to speed up sparse Gaussian process regression.Smola, A.J., Bartlett, P.L., n.d. Sparse greedy Gaussian process regression. pp. 619–625.Snelson, E., Ghahramani, Z., n.d. Sparse Gaussian processes using pseudo-inputs.Titsias, M.K., n.d. Variational learning of inducing variables in sparse Gaussian processes. pp. 567–574.Williams, C.K.I., Seeger, M., n.d. Using the Nyström method to speed up kernel machines. pp. 682–688.Gaussian Process Summer School notebook setup
-
-
-import importlib.util
-cmd = install_command('pods')
-%system {cmd}
-cmd = install_command('notutils')
-%system {cmd}
-cmd = install_command('mlai')
-%system {cmd}Gaussian Process Summer School notebook setup
import importlib.utilcmd = install_command('pods')%system {cmd}cmd = install_command('notutils')%system {cmd}cmd = install_command('mlai')
-%system {cmd}
-cmd = install_command('GPy')
-%system {cmd}GPy: A Gaussian Process Framework in Python
-
-
-
-
-
-
-
-
-
-
-
-
-
-Non Gaussian Likelihoods
-
-from matplotlib.patches import Polygon
+sns.set_palette('colorblind')}-->cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python
Non Gaussian Likelihoods
-from matplotlib.patches import Polygon
from matplotlib.collections import PatchCollection
-from pathlib import Path
-import pickle
-import urllib.request
-# Load East Timor language regions (local copy preferred; remote host is unreliable)
-data_path = Path('data/EastTimor2.pickle')
-if not data_path.exists():
- data_path = Path('EastTimor2.pickle')
-if not data_path.exists():
- url = 'http://staffwww.dcs.shef.ac.uk/people/M.Zwiessele/gpss/lab2/EastTimor.pickle'
- urllib.request.urlretrieve(url, 'EastTimor2.pickle')
- data_path = Path('EastTimor2.pickle')
-
-with open(data_path, 'rb') as f:
- try:
- X, y, polygons = pickle.load(f, encoding='latin1')
- except TypeError:
- X, y, polygons = pickle.load(f)GPy.models.GPClassification. However, once we’ve define the model, we also need to update the approximation to the likelihood. This runs the Expectation propagation updates.
-import GPy#Define the model
+import podsdata = pods.datasets.east_timor()
+X = data['X']
+y = data['Y']
+polygons = data['polygons']GPy.models.GPClassification. However, once we’ve define the model, we also need to update the approximation to the likelihood. This runs the Expectation propagation updates.import GPy
-#Define the model
kern = GPy.kern.RBF(2)
m = GPy.models.GPClassification(X,y, kernel=kern)
-print(m)
-m.optimize()
-print(m)Olympic Marathon Data
-
-
-
-
-
-
-
-
-
-
-
-
-
-cmd = install_command('pods')
-%system {cmd}
-import numpy as np
-import podsdata = pods.datasets.olympic_marathon_men()
+print(m)m.optimize()
+print(m)Olympic Marathon Data
cmd = install_command('pods')%system {cmd}import numpy as np
+import pods
-data = pods.datasets.olympic_marathon_men()
x = data['X']
y = data['Y']
offset = y.mean()
scale = np.sqrt(y.var())
-yhat = (y - offset)/scale
-
-
-
-
-
-
-
-
-
-Alan Turing
-
-
-
-
-
-
-
-
-
-
-
- -
-
-
-
-
 -
-
-
-
-
-
Alan Turing


Gaussian Process Fit
-
-
-import GPy
-m_full = GPy.models.GPRegression(x,yhat)
-_ = m_full.optimize() # Optimize parameters of covariance functionm_full.optimize() optimizes the parameters of the covariance function and the noise level of the model. Once the fit is complete, we’ll try creating some test points, and computing the output of the GP model in terms of the mean and standard deviation of the posterior functions between 1870 and 2030. We plot the mean function and the standard deviation at 200 locations. We can obtain the predictions using y_mean, y_var = m_full.predict(xt)xt = np.linspace(1870,2030,200)[:,np.newaxis]
+\] then we see that without a model we can’t generalise: we only have data. Data is fine for answering very specific questions, like “Who won the Olympic Marathon in 2012?” because we have that answer stored, however, we are not given the answer to many other questions. For example, Alan Turing was a formidable marathon runner, in 1946 he ran a time 2 hours 46 minutes (just under four minutes per kilometer, faster than I and most of the other Endcliffe Park Run runners can do 5 km). What is the probability he would have won an Olympics if one had been held in 1946?Gaussian Process Fit
import GPym_full = GPy.models.GPRegression(x,yhat)
+_ = m_full.optimize() # Optimize parameters of covariance functionm_full.optimize() optimizes the parameters of the covariance function and the noise level of the model. Once the fit is complete, we’ll try creating some test points, and computing the output of the GP model in terms of the mean and standard deviation of the posterior functions between 1870 and 2030. We plot the mean function and the standard deviation at 200 locations. We can obtain the predictions using y_mean, y_var = m_full.predict(xt)
-xt = np.linspace(1870,2030,200)[:,np.newaxis]
yt_mean, yt_var = m_full.predict(xt)
-yt_sd=np.sqrt(yt_var)mlai.plot.
-
-
-
-
-
-
-
-
-
-Fit Quality
-m_clean, where that point is removed.x_clean=np.vstack((x[0:2, :], x[3:, :]))
+yt_sd=np.sqrt(yt_var)mlai.plot.Fit Quality
m_clean, where that point is removed.
-x_clean=np.vstack((x[0:2, :], x[3:, :]))
y_clean=np.vstack((yhat[0:2, :], yhat[3:, :]))
m_clean = GPy.models.GPRegression(x_clean,y_clean)
-_ = m_clean.optimize()
-
-
-
-
-
-
-
-
-
-Robust Regression: A Running Example
-
-
-GPy.likelihoods.StudentT?# make a student t likelihood with standard parameters
+_ = m_clean.optimize()Robust Regression: A Running Example
GPy.likelihoods.StudentT?
-# make a student t likelihood with standard parameters
t_distribution = GPy.likelihoods.StudentT(deg_free=3, sigma2=2)
laplace = GPy.inference.latent_function_inference.Laplace()
@@ -240,89 +53,17 @@ Robust Regression: A Running Exampl
model.constrain_positive('t_noise')
model.optimize(messages=True)
-display(model)
-
-
-
-
-
-
-
-
-
-Sparse GP Classification
-
-from scipy import io
-import podsdata = pods.datasets.olivetti_glasses()
+display(model)Sparse GP Classification
from scipy import ioimport pods
-data = pods.datasets.olivetti_glasses()
X = data['X']
y = data['Y']
Xtest = data['Xtest']
ytest = data['Ytest']
-print(data['info'], data['details'], data['citation'])
-
-
-
-
-
- -
-
-
-
-
-
X.shape
+print(data['info'], data['details'], data['citation']) -
X.shape
y.shape
-print(X)
-from scipy import clusterM = 8
+print(X)from scipy import cluster
-M = 8
X = (X - X.mean(0)[np.newaxis,:])/X.std(0)[np.newaxis,:]
-Z = np.random.permutation(X)[:M]kern = GPy.kern.RBF(X.shape[1],lengthscale=20) + GPy.kern.White(X.shape[1],0.001)
+Z = np.random.permutation(X)[:M]
-kern = GPy.kern.RBF(X.shape[1],lengthscale=20) + GPy.kern.White(X.shape[1],0.001)
model = GPy.models.SparseGPClassification(X, y, kernel=kern, Z=Z)
model.optimize(messages=True)
-display(model)
-
-
-
-
-
- -
-
-
-
-
-
Thanks!
-
-
-
-References
+display(model)
Thanks!
References
diff --git a/_lectures/08-unsupervised-learning-with-gps.html b/_lectures/08-unsupervised-learning-with-gps.html
index 78a651b..617b829 100644
--- a/_lectures/08-unsupervised-learning-with-gps.html
+++ b/_lectures/08-unsupervised-learning-with-gps.html
@@ -1,5 +1,7 @@
---
title: "Unsupervised Learning with Gaussian Processes"
+abstract: |-
+ null
edit_url: https://github.com/mlatcl/gpss/edit/gh-pages/_lamd/unsupervised-learning-with-gps.md
week: 8
featured_image: slides/diagrams//dimred/nonlinear-mapping-3d-plot.svg
@@ -12,65 +14,13 @@
-
-
-
-
-
-
-
-
-Gaussian Process Summer School notebook setup
-
-
-import importlib.util
-cmd = install_command('pods')
-%system {cmd}
-cmd = install_command('notutils')
-%system {cmd}
-cmd = install_command('mlai')
-%system {cmd}Gaussian Process Summer School notebook setup
import importlib.utilcmd = install_command('pods')%system {cmd}cmd = install_command('notutils')%system {cmd}cmd = install_command('mlai')
-%system {cmd}
-cmd = install_command('GPy')
-%system {cmd}GPy: A Gaussian Process Framework in Python
-
-
-
-
-
-
-
-
-
-
-
-
-
-Probabilistic PCA
-
-cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python
Probabilistic PCA
Probabilistic PCA
p(\mathbf{ y}_{i,:}|\mathbf{ z}_{i,:},\mathbf{W}) = \mathscr{N}\left(\mathbf{ y}_{i,:}|\mathbf{W}\mathbf{ z}_{i,:},\sigma^2\mathbf{I}\right)
\] By integrating out the latent variables, we obtain the marginal likelihood of the data: \[
p(\mathbf{ y}_{i,:}|\mathbf{W}) = \mathscr{N}\left(\mathbf{ y}_{i,:}|\mathbf{0},\mathbf{W}\mathbf{W}^{\top}+\sigma^{2}\mathbf{I}\right)
-\] This probabilistic formulation, developed by Tipping and Bishop (Tipping and Bishop, 1999a), provides a principled framework that not only recovers classical PCA as a special case when \(\sigma^2 \to 0\), but also enables extensions like handling missing data and mixture models.
-cmd = install_command('daft')
-%system {cmd}
-
-
-
-
-
-
-
-
-
-Probabilistic PCA
-cmd = install_command('daft')%system {cmd}Probabilistic PCA
Probabilistic PCA
\mathbf{S}= \sum_{i=1}^n(\mathbf{ y}_{i, :} - \boldsymbol{ \mu})(\mathbf{ y}_{i,:} - \boldsymbol{ \mu})^\top,
\] which can be written \(\mathbf{S}= \frac{1}{n} \mathbf{Y}^\top\mathbf{Y}\) if the data is zero mean. The matrix \(\mathbf{L}\) is diagonal and is dependent on the eigenvalues of \(\mathbf{S}\), \(\boldsymbol{\Lambda}\). If the \(i\)th diagonal element of this matrix is given by \(\lambda_i\) then the corresponding element of \(\mathbf{L}\) is \[
\ell_i = \sqrt{\lambda_i - \sigma^2}
-\] where \(\sigma^2\) is the noise variance. Note that if \(\sigma^2\) is larger than any particular eigenvalue, then that eigenvalue (along with its corresponding eigenvector) is discarded from the solution.PPCA as Manifold Learning
-
-
-Python Implementation of Probabilistic PCA
-
-import numpy as np
-from mlai import ppca_eig
-ppca = ppca_eigPosterior for Principal Component Analysis
-PPCA as Manifold Learning
Python Implementation of Probabilistic PCA
import numpy as npfrom mlai import ppca_eigppca = ppca_eigPosterior for Principal Component Analysis
Posterior for Principal Comp
-\frac{1}{2\sigma^2} (\mathbf{ y}_{i, :} - \mathbf{W}\mathbf{ z}_{i,
:})^\top(\mathbf{ y}_{i, :} - \mathbf{W}\mathbf{ z}_{i, :}) - \frac{1}{2}
\mathbf{ z}_{i, :}^\top \mathbf{ z}_{i, :} + \text{const}
-\]
Exercise 1
-Exercise 1
Python Implementation of the Posterior
-Exercise 2
-
-mu_x, C_x = posterior(Y, W, sigma2)mu_x and C_x are the posterior mean and posterior covariance for the given \(\mathbf{Y}\).Y inside your function before computing the posterior: remember we assumed at the beginning of our analysis that the data had been centred (i.e. the mean was removed).Numerically Stable and Efficient Version
-Python Implementation of the Posterior
Exercise 2
mu_x, C_x = posterior(Y, W, sigma2)mu_x and C_x are the posterior mean and posterior covariance for the given \(\mathbf{Y}\).Y inside your function before computing the posterior: remember we assumed at the beginning of our analysis that the data had been centred (i.e. the mean was removed).Numerically Stable and Efficient Version
Solution for \(\mathbf{W}\)
-Solution for \(\mathbf{W}\)
Solution for \(\mathbf{W
\mathbf{I}]^{-1} \mathbf{L} \mathbf{U}^\top \mathbf{ y}_{i, :}
\] \[
\boldsymbol{ \mu}_x = \mathbf{D}\mathbf{U}^\top \mathbf{ y}_{i, :}
-\] where \(\mathbf{D}\) is a diagonal matrix with diagonal elements given by \(d_{i} = \frac{\ell_i}{\sigma^2 + \ell_i^2}\).
-import scipy as sp
-import numpy as np
-from mlai import ppca_svd
-from mlai import ppca_posterior
-ppca = ppca_svd
-posterior = ppca_posteriorScikit-learn implementation PCA
-
-scikit-learn implementation. Let’s try it on the oil flow data.Oil Flow Data
-
-
-import pods
-data = pods.datasets.oil()# Convert data["Y"] from [1, -1, -1] in each row to rows of 0 or 1 or 2
+\] where \(\mathbf{D}\) is a diagonal matrix with diagonal elements given by \(d_{i} = \frac{\ell_i}{\sigma^2 + \ell_i^2}\).import scipy as sp
+import numpy as npfrom mlai import ppca_svdfrom mlai import ppca_posteriorppca = ppca_svd
+posterior = ppca_posteriorScikit-learn implementation PCA
scikit-learn implementation. Let’s try it on the oil flow data.Oil Flow Data
import podsdata = pods.datasets.oil()
-# Convert data["Y"] from [1, -1, -1] in each row to rows of 0 or 1 or 2
Y = data["Y"]
# Find rows with 1 in first column (class 0)
class0 = (Y[:, 0] == 1).astype(int) * 0
@@ -204,257 +89,37 @@ Oil Flow Data
# Find rows with 1 in third column (class 2)
class2 = (Y[:, 2] == 1).astype(int) * 2
# Combine into single array of class labels 0,1,2
-labels = class0 + class1 + class2
-
-
-
-
-
-
-
-
-
-
-print(data['citation'])info and details.
-print(data['details'])
-X = data['X']
-Y = data['Y']
-cmd = install_command('scikit-learn')
-%system {cmd}
-from sklearn.decomposition import PCApca = PCA(n_components=2)
+labels = class0 + class1 + class2print(data['citation'])info and details.print(data['details'])X = data['X']
+Y = data['Y']cmd = install_command('scikit-learn')%system {cmd}from sklearn.decomposition import PCA
-pca = PCA(n_components=2)
pca.fit(X)
-X_pca = pca.transform(X)# Find rows with 1 in first column (class 0)
+X_pca = pca.transform(X)
-# Find rows with 1 in first column (class 0)
class0 = (Y[:, 0] == 1).astype(int) * 0
# Find rows with 1 in second column (class 1)
class1 = (Y[:, 1] == 1).astype(int) * 1
# Find rows with 1 in third column (class 2)
class2 = (Y[:, 2] == 1).astype(int) * 2
# Combine into single array of class labels 0,1,2
-lbls = class0 + class1 + class2
-
-
-
-
-
-
-
-
-
-Difficulty for Probabilistic Approaches
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-cmd = install_command('daft')
-%system {cmd}
-
-
-
-
-
-
-
-
-
-Getting Started and Downloading Data
-
-import numpy as np
+lbls = class0 + class1 + class2Difficulty for Probabilistic Approaches
cmd = install_command('daft')%system {cmd}Getting Started and Downloading Data
-import numpy as np
import GPy
-import stringwhich = [0,1,2,6,7,9] # which digits to work on
+import string
-which = [0,1,2,6,7,9] # which digits to work on
data = pods.datasets.decampos_digits(which_digits=which)
Y = data['Y']
-labels = data['str_lbls']plt.matshow (the digit images have size 16x16).Principal Component Analysis
-
-
-
-
-Yn = Y#Y-Y.mean()
-from GPy.util import pca
-p = pca.PCA(Y) # create PCA class with digits datasetGaussian Process Latent Variable Model
-input_dim = 4 # How many latent dimensions to use
+labels = data['str_lbls']plt.matshow (the digit images have size 16x16).Principal Component Analysis
Yn = Y#Y-Y.mean()from GPy.util import pca
+p = pca.PCA(Y) # create PCA class with digits datasetGaussian Process Latent Variable Model
-input_dim = 4 # How many latent dimensions to use
kernel = GPy.kern.Linear(input_dim, ARD=True) # ARD kernel
m = GPy.models.GPLVM(Yn, input_dim=input_dim, kernel=kernel)
-m.optimize(messages=1, max_iters=1000) # optimize for 1000 iterationsCMU Mocap Database
-
-
-import pods01 from subject 35.
-subject='35'
-motion=['01']
-data = pods.datasets.cmu_mocap(subject, motion)
-data['Y'].shape
-print(data['citation'])info and details.print(data['info'])
+m.optimize(messages=1, max_iters=1000) # optimize for 1000 iterationsCMU Mocap Database
import pods01 from subject 35.subject='35'
+motion=['01']data = pods.datasets.cmu_mocap(subject, motion)data['Y'].shapeprint(data['citation'])info and details.
-print(data['info'])
print()
-print(data['details'])CMU Motion Capture GP-LVM
-
-
-# Make figure move in place.
-data['Y'][:, 0:3] = 0.0
-Y = data['Y']
-import GPy
-model = GPy.models.GPLVM(Y, 2, normalizer=True)
-model.optimize(messages=True, max_f_eval=10000)
-
-
-
-
-
-
-
-
-
-Example: Latent Doodle Space
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-(Baxter and Anjyo, 2006)
-
-Example: Continuous Character Control
-
-
-
CMU Motion Capture GP-LVM
# Make figure move in place.
+data['Y'][:, 0:3] = 0.0Y = data['Y']import GPymodel = GPy.models.GPLVM(Y, 2, normalizer=True)model.optimize(messages=True, max_f_eval=10000)Example: Latent Doodle Space
(Baxter and Anjyo, 2006)Example: Continuous Character Control
-
-Levine et al. (2012)
-
-Character Control: Results
-
-
-
-
-
-
-
-
-
-
-Data for Blastocyst Development in Mice: Single Cell TaqMan Arrays
-pods. It is loaded in as a pandas DataFrame. This allows us to summarize it with the describe attribute.
-import podsdata = pods.datasets.singlecell()
+\end{cases}\] and \(w(\mathbf{ x}_i,\mathbf{ x}_j) = || \mathbf{ x}_i - \mathbf{ x}_j||^{-p}\) measures similarity.Levine et al. (2012)Character Control: Results
Data for Blastocyst Development in Mice: Single Cell TaqMan Arrays
pods. It is loaded in as a pandas DataFrame. This allows us to summarize it with the describe attribute.import pods
-data = pods.datasets.singlecell()
Y = data['Y']
-Y.describePrincipal Component Analysis
-
-import numpy as np# obtain a centred version of data.
+Y.describePrincipal Component Analysis
import numpy as np
-# obtain a centred version of data.
centredY = Y - Y.mean()
# compute inner product matrix
C = np.dot(centredY,centredY.T)
@@ -463,165 +128,11 @@ Principal Component Analysis
# sort eigenvalues and vectors according to size
ind = V.argsort()
ev = V[ind[::-1]]
-U = U[:, ind[::-1]]PCA Result
-
-
-
-
-
-
-
-
-
-
-GP-LVM on the Data
-
-
-\maxZwiesselePicture{15%}\oliverSteglePicture{15%}
-
-
-import GPykernel = GPy.kern.RBF(2)+GPy.kern.Bias(2)
+U = U[:, ind[::-1]]PCA Result
GP-LVM on the Data
\maxZwiesselePicture{15%}\oliverSteglePicture{15%}import GPy
-kernel = GPy.kern.RBF(2)+GPy.kern.Bias(2)
model = GPy.models.GPLVM(Y.values, 2, kernel=kernel)
-model.optimize(messages=True)
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Blastocyst Data: Isomap
-
-
-import sklearn.manifoldn_neighbors = 10
+model.optimize(messages=True)Blastocyst Data: Isomap
import sklearn.manifold
-n_neighbors = 10
model = sklearn.manifold.Isomap(n_neighbors=n_neighbors, n_components=2)
-X = model.fit_transform(Y)
-
-
-
-
-
-
-
-
-
-Blastocyst Data: Locally Linear Embedding
-
-
-import sklearn.manifoldn_neighbors = 50
+X = model.fit_transform(Y)Blastocyst Data: Locally Linear Embedding
import sklearn.manifold
-n_neighbors = 50
model = sklearn.manifold.LocallyLinearEmbedding(n_neighbors=n_neighbors, n_components=2)
-X = model.fit_transform(Y)
-
-
-
-
-
-
-
-
-
-Thanks!
-
-
-References
-
-
+X = model.fit_transform(Y)
-Baxter, W.V., Anjyo, K.-I., 2006. Latent doodle space, in: EUROGRAPHICS. Vienna, Austria, pp. 477–485. https://doi.org/10.1111/j.1467-8659.2006.00967.x
-
-
-Bishop, C.M., 2006. Pattern recognition and machine learning. springer.
-
-
-Bishop, C.M., James, G.D., 1993. Analysis of multiphase flows using dual-energy gamma densitometry and neural networks. Nuclear Instruments and Methods in Physics Research A327, 580–593. https://doi.org/10.1016/0168-9002(93)90728-Z
-
-
-Buettner, F., Theis, F.J., 2012. A novel approach for resolving differences in single-cell gene expression patterns from zygote to blastocyst. Bioinformatics 28, i626–i632. https://doi.org/10.1093/bioinformatics/bts385
-
-
-CMU Motion Capture Lab, 2003. The CMU mocap database.
-
-
-Damianou, A., Lawrence, N.D., 2013. Deep Gaussian processes. pp. 207–215.
-
-
-de Campos, T.E., Babu, B.R., Varma, M., 2009. Character recognition in natural images, in: Proceedings of the Fourth International Conference on Computer Vision Theory and Applications - Volume 2: VISAPP, (VISIGRAPP 2009). INSTICC; SciTePress, pp. 273–280. https://doi.org/10.5220/0001770102730280
-
-
-Guo, G., Huss, M., Tong, G.Q., Wang, C., Sun, L.L., Clarke, N.D., Robsonemail, P., 2010. Resolution of cell fate decisions revealed by single-cell gene expression analysis from zygote to blastocyst. Developmental Cell 18, 675–685. https://doi.org/10.1016/j.devcel.2010.02.012
-
-
-Lawrence, N.D., 2005. Probabilistic non-linear principal component analysis with Gaussian process latent variable models. Journal of Machine Learning Research 6, 1783–1816.
-
-
-Lawrence, N.D., Moore, A.J., 2007. Hierarchical Gaussian process latent variable models. pp. 481–488.
-
-
-Levine, S., Wang, J.M., Haraux, A., Popović, Z., Koltun, V., 2012. Continuous character control with low-dimensional embeddings. ACM Transactions on Graphics (SIGGRAPH 2012) 31.
-
-
-Roweis, S.T., n.d. EM algorithms for PCA and SPCA. pp. 626–632.
-
-
-Tipping, M.E., Bishop, C.M., 1999b. Mixtures of probabilistic principal component analysers. Neural Computation 11, 443–482.
-
-
-Tipping, M.E., Bishop, C.M., 1999a. Probabilistic principal component analysis. Journal of the Royal Statistical Society, B 6, 611–622. https://doi.org/doi:10.1111/1467-9868.00196
-
-Thanks!
References
diff --git a/_lectures/09-latent-force-models.html b/_lectures/09-latent-force-models.html
index 06219c7..3e0b001 100644
--- a/_lectures/09-latent-force-models.html
+++ b/_lectures/09-latent-force-models.html
@@ -6,7 +6,6 @@
week: 9
reveal: 09-latent-force-models.slides.html
ipynb: 09-latent-force-models.ipynb
-pptx: 09-latent-force-models.pptx
layout: lecture
categories:
- notes
@@ -14,11 +13,11 @@
-Baxter, W.V., Anjyo, K.-I., 2006. Latent doodle space, in: EUROGRAPHICS. Vienna, Austria, pp. 477–485. https://doi.org/10.1111/j.1467-8659.2006.00967.xBishop, C.M., 2006. Pattern recognition and machine learning. springer.Bishop, C.M., James, G.D., 1993. Analysis of multiphase flows using dual-energy gamma densitometry and neural networks. Nuclear Instruments and Methods in Physics Research A327, 580–593. https://doi.org/10.1016/0168-9002(93)90728-ZBuettner, F., Theis, F.J., 2012. A novel approach for resolving differences in single-cell gene expression patterns from zygote to blastocyst. Bioinformatics 28, i626–i632. https://doi.org/10.1093/bioinformatics/bts385CMU Motion Capture Lab, 2003. The CMU mocap database.Damianou, A., Lawrence, N.D., 2013. Deep Gaussian processes. pp. 207–215.de Campos, T.E., Babu, B.R., Varma, M., 2009. Character recognition in natural images, in: Proceedings of the Fourth International Conference on Computer Vision Theory and Applications - Volume 2: VISAPP, (VISIGRAPP 2009). INSTICC; SciTePress, pp. 273–280. https://doi.org/10.5220/0001770102730280Guo, G., Huss, M., Tong, G.Q., Wang, C., Sun, L.L., Clarke, N.D., Robsonemail, P., 2010. Resolution of cell fate decisions revealed by single-cell gene expression analysis from zygote to blastocyst. Developmental Cell 18, 675–685. https://doi.org/10.1016/j.devcel.2010.02.012Lawrence, N.D., 2005. Probabilistic non-linear principal component analysis with Gaussian process latent variable models. Journal of Machine Learning Research 6, 1783–1816.Lawrence, N.D., Moore, A.J., 2007. Hierarchical Gaussian process latent variable models. pp. 481–488.Levine, S., Wang, J.M., Haraux, A., Popović, Z., Koltun, V., 2012. Continuous character control with low-dimensional embeddings. ACM Transactions on Graphics (SIGGRAPH 2012) 31.Roweis, S.T., n.d. EM algorithms for PCA and SPCA. pp. 626–632.Tipping, M.E., Bishop, C.M., 1999b. Mixtures of probabilistic principal component analysers. Neural Computation 11, 443–482.Tipping, M.E., Bishop, C.M., 1999a. Probabilistic principal component analysis. Journal of the Royal Statistical Society, B 6, 611–622. https://doi.org/doi:10.1111/1467-9868.00196Gaussian Process Summer School notebook setup
import importlib.utilcmd = install_command('pods')%system {cmd}cmd = install_command('notutils')%system {cmd}cmd = install_command('mlai')%system {cmd}cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python
Thanks!
References
+sns.set_palette('colorblind')}-->cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python
Thanks!
References
diff --git a/_lectures/10-bayesian-learning-gplvm.html b/_lectures/10-bayesian-learning-gplvm.html
index 4a03d94..8c316a2 100644
--- a/_lectures/10-bayesian-learning-gplvm.html
+++ b/_lectures/10-bayesian-learning-gplvm.html
@@ -7,7 +7,6 @@
featured_image: slides/diagrams/gplvm/singlecell-bayes-gplvm.svg
reveal: 10-bayesian-learning-gplvm.slides.html
ipynb: 10-bayesian-learning-gplvm.ipynb
-pptx: 10-bayesian-learning-gplvm.pptx
layout: lecture
categories:
- notes
@@ -15,13 +14,13 @@
-Gaussian Process Summer School notebook setup
import importlib.utilcmd = install_command('pods')%system {cmd}cmd = install_command('notutils')%system {cmd}cmd = install_command('mlai')%system {cmd}cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python
\only<1->{\begin{tikzpicture}
+sns.set_palette('colorblind')}-->cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python
\only<1->{\begin{tikzpicture}
% Define nodes
\node[obs] (Y) {$\dataMatrix$};
@@ -113,5 +112,64 @@
% Annotate the layers
\node[annot,left of=X-1, node distance=1cm] (ls) {Latent space};
-\node[annot,left of=Y-1, node distance=1cm] (ds) {Data space};Manifold Relevance Determination Results
+\node[annot,left of=Y-1, node distance=1cm] (ds) {Data space};Damianou, A., 2015. Deep Gaussian processes and variational propagation of uncertainty (PhD thesis). University of Sheffield.Damianou, A., Titsias, M.K., Lawrence, N.D., 2016. Variational inference for latent variables and uncertain inputs in Gaussian processes. Journal of Machine Learning Research 17, 1–62.Ek, C.H., Rihan, J., Torr, P.H.S., Rogez, G., Lawrence, N.D., 2008a. Ambiguity modeling in latent spaces, in: Popescu-Belis, A., Stiefelhagen, R. (Eds.), Machine Learning for Multimodal Interaction (MLMI 2008), LNCS. Springer-Verlag, pp. 62–73.Ek, C.H., Torr, P.H.S., Lawrence, N.D., 2008b. Gaussian process latent variable models for human pose estimation, in: Popescu-Belis, A., Renals, S., Bourlard, H. (Eds.), Machine Learning for Multimodal Interaction (MLMI 2007), LNCS. Springer-Verlag, Brno, Czech Republic, pp. 132–143. https://doi.org/10.1007/978-3-540-78155-4_12Klami, A., Kaski, S., n.d. Local dependent components analysis.Klami, A., Kaski, S., 2008. Probabilistic approach to detecting dependencies between data sets. Neurocomputing 72, 39–46.Leen, G., Fyfe, C., 2006. A Gaussian process latent variable model formulation of canonical correlation analysis, in: European Symposium on Artificial Neural Networks. Bruges (Belgium).Salimbeni, H., Deisenroth, M., 2017. Doubly stochastic variational inference for deep Gaussian processes, in: Guyon, I., Luxburg, U.V., Bengio, S., Wallach, H., Fergus, R., Vishwanathan, S., Garnett, R. (Eds.), Advances in Neural Information Processing Systems 30. Curran Associates, Inc., pp. 4591–4602.Shon, A.P., Grochow, K., Hertzmann, A., Rao, R.P.N., n.d. Learning shared latent structure for image synthesis and robotic imitation.Tucker, L.R., 1958. An inter-battery method of factor analysis. Psychometrika 23, 111–136.Virtanen, S., Klami, A., Kaski, S., n.d. Bayesian CCA via group sparsity.Manifold Relevance Determination Results


Getting Started and Downloading Data
import numpy as np
+import GPy
+import stringwhich = [0,1,2,6,7,9] # which digits to work on
+data = pods.datasets.decampos_digits(which_digits=which)
+Y = data['Y']
+labels = data['str_lbls']plt.matshow (the digit images have size 16x16).Bayesian GPLVM
+# Model optimization
+input_dim = 5 # How many latent dimensions to use
+kern = GPy.kern.RBF(input_dim,ARD=True) # ARD kernel
+m = GPy.models.BayesianGPLVM(Yn, input_dim=input_dim, kernel=kern, num_inducing=25)
+
+# initialize noise as 1% of variance in data
+#m.likelihood.variance = m.Y.var()/100.
+m.optimize(messages=1)Kernel->Interupt from the notepad menu. This will leave you with the model, m in the current state and you can plot and look into the model parameters.Preoptimized Model
Multiview Learning: Manifold Relevance Determination
m = GPy.examples.dimensionality_reduction.mrd_simulation(optimize = False, plot=False)
+m.optimize(messages = True, max_iters=3e3, optimizer = 'bfgs')Interactive Demo: For Use Outside the Notepad
import urllib2, os, sysmodel_path = 'digit_bgplvm_demo.pickle' # local name for model file
+status = ""
+
+re = 0
+if len(sys.argv) == 2:
+ re = 1
+
+if re or not os.path.exists(model_path): # only download the model new, if it was not already
+ url = 'http://staffwww.dcs.sheffield.ac.uk/people/M.Zwiessele/gpss/lab3/digit_bgplvm_demo.pickle'
+ with open(model_path, 'wb') as f:
+ u = urllib2.urlopen(url)
+ meta = u.info()
+ file_size = int(meta.getheaders("Content-Length")[0])
+ print "Downloading: %s" % (model_path)
+
+ file_size_dl = 0
+ block_sz = 8192
+ while True:
+ buff = u.read(block_sz)
+ if not buff:
+ break
+ file_size_dl += len(buff)
+ f.write(buff)
+ sys.stdout.write(" "*(len(status)) + "\r")
+ status = r"{:7.3f}/{:.3f}MB [{: >7.2%}]".format(file_size_dl/(1.*1e6), file_size/(1.*1e6), float(file_size_dl)/file_size)
+ sys.stdout.write(status)
+ sys.stdout.flush()
+ sys.stdout.write(" "*(len(status)) + "\r")
+ print status
+else:
+ print("Already cached, to reload run with 'reload' as the only argument")import cPickle as pickle
+with open('./digit_bgplvm_demo.pickle', 'rb') as f:
+ m = pickle.load(f)Observations
GPy.examples.dimensionality_reduction.bgplvm_simulation()Questions
Data for Blastocyst Development in Mice: Single Cell TaqMan Arrays
pods. It is loaded in as a pandas DataFrame. This allows us to summarize it with the describe attribute.import podsdata = pods.datasets.singlecell()
+Y = data['Y']
+Y.describePrincipal Component Analysis
import numpy as np# obtain a centred version of data.
+centredY = Y - Y.mean()
+# compute inner product matrix
+C = np.dot(centredY,centredY.T)
+# perform eigendecomposition
+V, U = np.linalg.eig(C)
+# sort eigenvalues and vectors according to size
+ind = V.argsort()
+ev = V[ind[::-1]]
+U = U[:, ind[::-1]]PCA Result
Bayesian GP-LVM
import GPykernel=GPy.kern.RBF(5,ARD=1)+GPy.kern.Bias(5)
+model = GPy.models.BayesianGPLVM(Y.values, 5, num_inducing=15, kernel=kernel)
+model.optimize(messages=True)Thanks!
References
diff --git a/_lectures/11-deep-gps-I.html b/_lectures/11-deep-gps-I.html
index d9e04d6..09f129f 100644
--- a/_lectures/11-deep-gps-I.html
+++ b/_lectures/11-deep-gps-I.html
@@ -1,5 +1,7 @@
---
title: "Deep Gaussian Processes I"
+abstract: |-
+ null
edit_url: https://github.com/mlatcl/gpss/edit/gh-pages/_lamd/deep-gps-I.md
week: 11
featured_image: slides/diagrams//deepgp/deep-nn-bottleneck2.svg
@@ -12,152 +14,24 @@
-
-
-
-
-
-
-
-
-Damianou, A., 2015. Deep Gaussian processes and variational propagation of uncertainty (PhD thesis). University of Sheffield.Damianou, A., Titsias, M.K., Lawrence, N.D., 2016. Variational inference for latent variables and uncertain inputs in Gaussian processes. Journal of Machine Learning Research 17, 1–62.de Campos, T.E., Babu, B.R., Varma, M., 2009. Character recognition in natural images, in: Proceedings of the Fourth International Conference on Computer Vision Theory and Applications - Volume 2: VISAPP, (VISIGRAPP 2009). INSTICC; SciTePress, pp. 273–280. https://doi.org/10.5220/0001770102730280Ek, C.H., Rihan, J., Torr, P.H.S., Rogez, G., Lawrence, N.D., 2008a. Ambiguity modeling in latent spaces, in: Popescu-Belis, A., Stiefelhagen, R. (Eds.), Machine Learning for Multimodal Interaction (MLMI 2008), LNCS. Springer-Verlag, pp. 62–73.Ek, C.H., Torr, P.H.S., Lawrence, N.D., 2008b. Gaussian process latent variable models for human pose estimation, in: Popescu-Belis, A., Renals, S., Bourlard, H. (Eds.), Machine Learning for Multimodal Interaction (MLMI 2007), LNCS. Springer-Verlag, Brno, Czech Republic, pp. 132–143. https://doi.org/10.1007/978-3-540-78155-4_12Guo, G., Huss, M., Tong, G.Q., Wang, C., Sun, L.L., Clarke, N.D., Robsonemail, P., 2010. Resolution of cell fate decisions revealed by single-cell gene expression analysis from zygote to blastocyst. Developmental Cell 18, 675–685. https://doi.org/10.1016/j.devcel.2010.02.012Klami, A., Kaski, S., n.d. Local dependent components analysis.Klami, A., Kaski, S., 2008. Probabilistic approach to detecting dependencies between data sets. Neurocomputing 72, 39–46.Leen, G., Fyfe, C., 2006. A Gaussian process latent variable model formulation of canonical correlation analysis, in: European Symposium on Artificial Neural Networks. Bruges (Belgium).Salimbeni, H., Deisenroth, M., 2017. Doubly stochastic variational inference for deep Gaussian processes, in: Guyon, I., Luxburg, U.V., Bengio, S., Wallach, H., Fergus, R., Vishwanathan, S., Garnett, R. (Eds.), Advances in Neural Information Processing Systems 30. Curran Associates, Inc., pp. 4591–4602.Shon, A.P., Grochow, K., Hertzmann, A., Rao, R.P.N., n.d. Learning shared latent structure for image synthesis and robotic imitation.Titsias, M.K., Lawrence, N.D., 2010. Bayesian Gaussian process latent variable model. pp. 844–851.Tucker, L.R., 1958. An inter-battery method of factor analysis. Psychometrika 23, 111–136.Virtanen, S., Klami, A., Kaski, S., n.d. Bayesian CCA via group sparsity.Gaussian Process Summer School notebook setup
-
-
-import importlib.util
-cmd = install_command('pods')
-%system {cmd}
-cmd = install_command('notutils')
-%system {cmd}
-cmd = install_command('mlai')
-%system {cmd}Gaussian Process Summer School notebook setup
import importlib.utilcmd = install_command('pods')%system {cmd}cmd = install_command('notutils')%system {cmd}cmd = install_command('mlai')
-%system {cmd}
-cmd = install_command('GPy')
-%system {cmd}GPy: A Gaussian Process Framework in Python
-
-
-
-
-
-
-
-
-
-
-
-
-
-Structure of Priors
-
-
-
-Deep Neural Network
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python
Structure of Priors
Deep Neural Network
Overfitting
-
-Overfitting
-
-
-
-
-
-
-
-
-
-Bottleneck Layers in Deep Neural Networks
-
-
-
-
-
-
-
-
-
-
-
-Bottleneck Layers in Deep Neural Networks
Bottleneck Layers in Deep Neu
\mathbf{ h}_{3} &= \phi\left(\mathbf{U}_3 \mathbf{ z}_{3}\right)\\
\mathbf{ y}&= \mathbf{ w}_4^\top\mathbf{ h}_{3}.
\end{align}
-\]
Cascade of Gaussian Processes
-
-Cascade of Gaussian Processes
Deep Learning
-
-
-DeepFace
-
-
-
-
-
-
-
-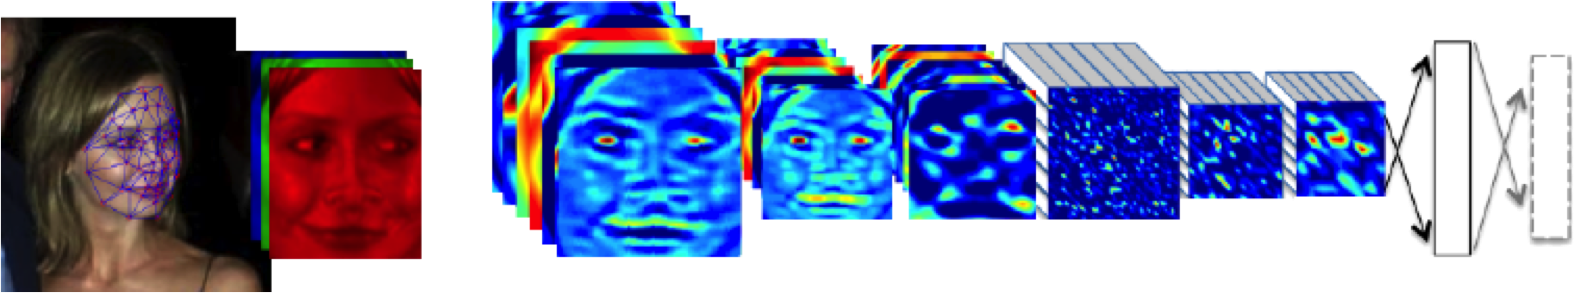 -
-
-
-
-
-
Deep Learning as Pinball
-
-
-
-
-
-
-
- -
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
Deep Learning
DeepFace

Deep Learning as Pinball
 -
cmd = install_command('daft')
-%system {cmd}cmd = install_command('daft')%system {cmd}
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Why Composition?
-
-Stochastic Process Composition
-
-
-
-
-
-
-
-
-
-
-Difficulty for Probabilistic Approaches
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-cmd = install_command('daft')
-%system {cmd}
-
-
-
-
-
-
-
-
-
-Standard Variational Approach Fails
-
-
-
Why Composition?
Stochastic Process Composition
Difficulty for Probabilistic Approaches
cmd = install_command('daft')%system {cmd}Standard Variational Approach Fails
-Variational Bayesian GP-LVM
-Variational Bayesian GP-LVM
-
-
-
-
-
-
-
- -
-
-
-
-
-
Stacked PCA
-
-
-
-
-
-
-
-
-
-
-
-
Stacked PCA
Stacked PCA
\mathbf{W}_2 \mathbf{W}_1 & \mathbf{W}_2 \mathbf{W}_1 \mathbf{W}_1^\top & \mathbf{W}_2 \mathbf{W}_1 \mathbf{W}_1^\top \mathbf{W}_2^\top & \dots & \mathbf{W}_2 \mathbf{W}_1 \mathbf{V}^\top \\
\vdots & \vdots & \vdots & \ddots & \vdots \\
\mathbf{V}& \mathbf{V}\mathbf{W}_1^\top & \mathbf{V}\mathbf{W}_1^\top \mathbf{W}_2^\top& \dots & \mathbf{V}\mathbf{V}^\top
-\end{bmatrix}\right)\] which is a highly structured Gaussian covariance with hierarchical dependencies between the variables \(\mathbf{Z}_i\).Stacked GP
-
-
-
-
-
-
-
-
-
-
-
-Stacked GPs (video by David Duvenaud)
-
-
-
-
-
-
-
-
-
-
-
-
-cmd = install_command('PyDeepGP')
-%system {cmd}
-cmd = install_command('mlai')
-%system {cmd}# Late bind setup methods to DeepGP object
+\end{bmatrix}\right)\] which is a highly structured Gaussian covariance with hierarchical dependencies between the variables \(\mathbf{Z}_i\).Stacked GP
Stacked GPs (video by David Duvenaud)
cmd = install_command('PyDeepGP')%system {cmd}cmd = install_command('mlai')%system {cmd}
-# Late bind setup methods to DeepGP object
from mlai.deepgp_tutorial import initialize
from mlai.deepgp_tutorial import staged_optimize
from mlai.deepgp_tutorial import posterior_sample
@@ -534,387 +116,49 @@ Stacked GPs (video by David Duvenau
deepgp.DeepGP.staged_optimize=staged_optimize
deepgp.DeepGP.posterior_sample=posterior_sample
deepgp.DeepGP.visualize=visualize
-deepgp.DeepGP.visualize_pinball=visualize_pinball
Olympic Marathon Data
-
-
-
-
-
-
-
-
-
-
-
-
-
-cmd = install_command('pods')
-%system {cmd}
-import numpy as np
-import podsdata = pods.datasets.olympic_marathon_men()
+deepgp.DeepGP.visualize_pinball=visualize_pinballOlympic Marathon Data
cmd = install_command('pods')%system {cmd}import numpy as np
+import pods
-data = pods.datasets.olympic_marathon_men()
x = data['X']
y = data['Y']
offset = y.mean()
scale = np.sqrt(y.var())
-yhat = (y - offset)/scale
-
-
-
-
-
-
-
-
-
-Alan Turing
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Alan Turing
Gaussian Process Fit
-
-
-import GPy
-m_full = GPy.models.GPRegression(x,yhat)
-_ = m_full.optimize() # Optimize parameters of covariance functionm_full.optimize() optimizes the parameters of the covariance function and the noise level of the model. Once the fit is complete, we’ll try creating some test points, and computing the output of the GP model in terms of the mean and standard deviation of the posterior functions between 1870 and 2030. We plot the mean function and the standard deviation at 200 locations. We can obtain the predictions using y_mean, y_var = m_full.predict(xt)
diff --git a/slides/02-gaussian-distributions-to-processes.slides.html b/slides/02-gaussian-distributions-to-processes.slides.html
index 5cbfaf8..cce56e5 100644
--- a/slides/02-gaussian-distributions-to-processes.slides.html
+++ b/slides/02-gaussian-distributions-to-processes.slides.html
@@ -26,7 +26,7 @@
}
-
+
@@ -129,6 +129,8 @@ xt = np.linspace(1870,2030,200)[:,np.newaxis]
+\] then we see that without a model we can’t generalise: we only have data. Data is fine for answering very specific questions, like “Who won the Olympic Marathon in 2012?” because we have that answer stored, however, we are not given the answer to many other questions. For example, Alan Turing was a formidable marathon runner, in 1946 he ran a time 2 hours 46 minutes (just under four minutes per kilometer, faster than I and most of the other Endcliffe Park Run runners can do 5 km). What is the probability he would have won an Olympics if one had been held in 1946?Gaussian Process Fit
import GPym_full = GPy.models.GPRegression(x,yhat)
+_ = m_full.optimize() # Optimize parameters of covariance functionm_full.optimize() optimizes the parameters of the covariance function and the noise level of the model. Once the fit is complete, we’ll try creating some test points, and computing the output of the GP model in terms of the mean and standard deviation of the posterior functions between 1870 and 2030. We plot the mean function and the standard deviation at 200 locations. We can obtain the predictions using y_mean, y_var = m_full.predict(xt)
-xt = np.linspace(1870,2030,200)[:,np.newaxis]
yt_mean, yt_var = m_full.predict(xt)
-yt_sd=np.sqrt(yt_var)mlai.plot.
-
-
-
-
-
-
-
-
-
-Fit Quality
-m_clean, where that point is removed.x_clean=np.vstack((x[0:2, :], x[3:, :]))
+yt_sd=np.sqrt(yt_var)mlai.plot.Fit Quality
m_clean, where that point is removed.
-x_clean=np.vstack((x[0:2, :], x[3:, :]))
y_clean=np.vstack((yhat[0:2, :], yhat[3:, :]))
m_clean = GPy.models.GPRegression(x_clean,y_clean)
-_ = m_clean.optimize()
-
-
-
-
-
-
-
-
-
-Deep GP Fit
-
-
-import GPy
-import deepgphidden = 1
+_ = m_clean.optimize()Deep GP Fit
import GPy
+import deepgp
-hidden = 1
m = deepgp.DeepGP([y.shape[1],hidden,x.shape[1]],Y=yhat, X=x, inits=['PCA','PCA'],
kernels=[GPy.kern.RBF(hidden,ARD=True),
GPy.kern.RBF(x.shape[1],ARD=True)], # the kernels for each layer
- num_inducing=50, back_constraint=False)
-# Call the initalization
-m.initialize()for layer in m.layers:
+ num_inducing=50, back_constraint=False)# Call the initalization
+m.initialize()
-for layer in m.layers:
layer.likelihood.variance.constrain_positive(warning=False)
-m.optimize(messages=True,max_iters=10000)
-m.staged_optimize(messages=(True,True,True))Olympic Marathon Data Deep GP
-
-
-
-
-
-
-
-
-
-
-Olympic Marathon Data Deep GP
-
-
-
-
-
-
-
-
-
-
-Fitted GP for each layer
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Olympic Marathon Pinball Plot
-
-
-
-
-
-
-
-
-
-
-Gene Expression Example
-
-Della Gatta Gene Data
-
-
-
-
-import numpy as np
-import podsdata = pods.datasets.della_gatta_TRP63_gene_expression(data_set='della_gatta',gene_number=937)
+m.optimize(messages=True,max_iters=10000)m.staged_optimize(messages=(True,True,True))Olympic Marathon Data Deep GP
Olympic Marathon Data Deep GP
Fitted GP for each layer
Olympic Marathon Pinball Plot
Gene Expression Example
Della Gatta Gene Data
import numpy as np
+import pods
-data = pods.datasets.della_gatta_TRP63_gene_expression(data_set='della_gatta',gene_number=937)
x = data['X']
y = data['Y']
offset = y.mean()
-scale = np.sqrt(y.var())
-
-
-
-
-
-
-
-
-
-
-
-
-\freddieKalaitzisPicture{15%}
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-import GPym_full = GPy.models.GPRegression(x,yhat)
+scale = np.sqrt(y.var())\freddieKalaitzisPicture{15%}import GPy
-m_full = GPy.models.GPRegression(x,yhat)
m_full.kern.lengthscale=50
-_ = m_full.optimize() # Optimize parameters of covariance functionxt = np.linspace(-20,260,200)[:,np.newaxis]
+_ = m_full.optimize() # Optimize parameters of covariance function
-xt = np.linspace(-20,260,200)[:,np.newaxis]
yt_mean, yt_var = m_full.predict(xt)
-yt_sd=np.sqrt(yt_var)mlai.plot.
-
-
-
-
-
-
-
-
-
-m_full2 = GPy.models.GPRegression(x,yhat)
+yt_sd=np.sqrt(yt_var)mlai.plot.
-m_full2 = GPy.models.GPRegression(x,yhat)
m_full2.kern.lengthscale=2000
-_ = m_full2.optimize() # Optimize parameters of covariance function
-
-
-
-
-
-
-
-
-
-m_full3 = GPy.models.GPRegression(x,yhat)
+_ = m_full2.optimize() # Optimize parameters of covariance function
-m_full3 = GPy.models.GPRegression(x,yhat)
m_full3.kern.lengthscale=20
m_full3.likelihood.variance=0.001
-_ = m_full3.optimize() # Optimize parameters of covariance function
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-mlai.deepgp_tutorial module.
-cmd = install_command('mlai')
-%system {cmd}
-from mlai.deepgp_tutorial import initialize
-from mlai.deepgp_tutorial import staged_optimize
-from mlai.deepgp_tutorial import visualize
-from mlai.deepgp_tutorial import visualize_pinballposterior_sample code allows us to see the output sample locations for a given input. This is useful for visualizing the non-Gaussian nature of the output density.
-from mlai.deepgp_tutorial import posterior_samplelayers = [y.shape[1], 1,x.shape[1]]
+-->mlai.deepgp_tutorial module.cmd = install_command('mlai')%system {cmd}from mlai.deepgp_tutorial import initializefrom mlai.deepgp_tutorial import staged_optimizefrom mlai.deepgp_tutorial import visualizefrom mlai.deepgp_tutorial import visualize_pinballposterior_sample code allows us to see the output sample locations for a given input. This is useful for visualizing the non-Gaussian nature of the output density.from mlai.deepgp_tutorial import posterior_sample
-layers = [y.shape[1], 1,x.shape[1]]
inits = ['PCA']*(len(layers)-1)
kernels = []
for i in layers[1:]:
@@ -922,93 +166,8 @@ Della Gatta Gene Data
m = deepgp.DeepGP(layers,Y=yhat, X=x,
inits=inits,
kernels=kernels, # the kernels for each layer
- num_inducing=20, back_constraint=False)
-m.initialize()
-m.staged_optimize()Della Gatta Gene Data Deep GP
-
-
-
-
-
-
-
-
-
-
-
-Della Gatta Gene Data Deep GP
-
-
-
-
-
-
-
-
-
-
-Della Gatta Gene Data Latent 1
-
-
-
-
-
-
-
-
-
-
-Della Gatta Gene Data Latent 2
-
-
-
-
-
-
-
-
-
-
-TP53 Gene Pinball Plot
-
-
-
-
-
-
-
-
-
-
-Step Function
-
-num_low=25
+ num_inducing=20, back_constraint=False)m.initialize()
+m.staged_optimize()Della Gatta Gene Data Deep GP
Della Gatta Gene Data Deep GP
Della Gatta Gene Data Latent 1
Della Gatta Gene Data Latent 2
TP53 Gene Pinball Plot
Step Function
-num_low=25
num_high=25
gap = -.1
noise=0.0001
@@ -1017,50 +176,8 @@ Step Function
y = np.vstack((np.zeros((num_low, 1)), np.ones((num_high,1))))
scale = np.sqrt(y.var())
offset = y.mean()
-yhat = (y-offset)/scaleStep Function Data
-
-
-
-
-
-
-
-
-
-
-Step Function Data GP
-GPy as follows.
-m_full = GPy.models.GPRegression(x,yhat)
-_ = m_full.optimize() # Optimize parameters of covariance functionGPy.models.GPRegression() gives us a standard GP regression model with exponentiated quadratic covariance function.m_full.optimize() which calls an L-BGFS gradient based solver in python.
-
-
-
-
-
-
-
-
-
-Step Function Data Deep GP
-
-GPy.kern.RBF).layers = [y.shape[1], 1, 1, 1,x.shape[1]]
+yhat = (y-offset)/scaleStep Function Data
Step Function Data GP
GPy as follows.m_full = GPy.models.GPRegression(x,yhat)
+_ = m_full.optimize() # Optimize parameters of covariance functionGPy.models.GPRegression() gives us a standard GP regression model with exponentiated quadratic covariance function.m_full.optimize() which calls an L-BGFS gradient based solver in python.Step Function Data Deep GP
GPy.kern.RBF).
-layers = [y.shape[1], 1, 1, 1,x.shape[1]]
inits = ['PCA']*(len(layers)-1)
kernels = []
for i in layers[1:]:
@@ -1069,130 +186,14 @@ Step Function Data Deep GP
m = deepgp.DeepGP(layers,Y=yhat, X=x,
inits=inits,
kernels=kernels, # the kernels for each layer
- num_inducing=20, back_constraint=False)
-m.initialize()
-m.staged_optimize()
-
-
-
-
-
-
-
-
-
-Step Function Data Deep GP
-mlai.plot, model_sample
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-import podsdata = pods.datasets.mcycle()
+ num_inducing=20, back_constraint=False)m.initialize()
+m.staged_optimize()Step Function Data Deep GP
mlai.plot, model_sampleimport pods
-data = pods.datasets.mcycle()
x = data['X']
y = data['Y']
scale=np.sqrt(y.var())
offset=y.mean()
-yhat = (y - offset)/scaleMotorcycle Helmet Data
-
-
-
-
-
-
-
-
-
-
-
-
-m_full = GPy.models.GPRegression(x,yhat)
-_ = m_full.optimize() # Optimize parameters of covariance functionMotorcycle Helmet Data GP
-
-
-
-
-
-
-
-
-
-
-
-Motorcycle Helmet Data Deep GP
-
-
-import deepgplayers = [y.shape[1], 1, x.shape[1]]
+yhat = (y - offset)/scaleMotorcycle Helmet Data
m_full = GPy.models.GPRegression(x,yhat)
+_ = m_full.optimize() # Optimize parameters of covariance functionMotorcycle Helmet Data GP
Motorcycle Helmet Data Deep GP
import deepgp
-layers = [y.shape[1], 1, x.shape[1]]
inits = ['PCA']*(len(layers)-1)
kernels = []
for i in layers[1:]:
@@ -1204,141 +205,5 @@ Motorcycle Helmet Data Deep GP
-m.initialize()
-m.staged_optimize(iters=(1000,1000,10000), messages=(True, True, True))
-
-
-
-
-
-
-
-
-
-Motorcycle Helmet Data Deep GP
-
-
-
-
-
-
-
-
-
-
-Motorcycle Helmet Data Latent 1
-
-
-
-
-
-
-
-
-
-
-Motorcycle Helmet Data Latent 2
-
-
-
-
-
-
-
-
-
-
-Motorcycle Helmet Pinball Plot
-
-
-
-
-
-
-
-
-
-
-Thanks!
-
-
-References
-
-
+m.initialize()
-Arora, S., Cohen, N., Golowich, N., Hu, W., 2019. A convergence analysis of gradient descent for deep linear neural networks, in: International Conference on Learning Representations.
-
-
-Bui, T., Hernandez-Lobato, D., Hernandez-Lobato, J., Li, Y., Turner, R., 2016. Deep Gaussian processes for regression using approximate expectation propagation, in: Balcan, M.F., Weinberger, K.Q. (Eds.), Proceedings of the 33rd International Conference on Machine Learning, Proceedings of Machine Learning Research. PMLR, New York, New York, USA, pp. 1472–1481.
-
-
-Cho, Y., Saul, L.K., 2009. Kernel methods for deep learning, in: Bengio, Y., Schuurmans, D., Lafferty, J.D., Williams, C.K.I., Culotta, A. (Eds.), Advances in Neural Information Processing Systems 22. Curran Associates, Inc., pp. 342–350.
-
-
-Damianou, A., 2015. Deep Gaussian processes and variational propagation of uncertainty (PhD thesis). University of Sheffield.
-
-
-Damianou, A., Titsias, M.K., Lawrence, N.D., 2016. Variational inference for latent variables and uncertain inputs in Gaussian processes. Journal of Machine Learning Research 17, 1–62.
-
-
-Della Gatta, G., Bansal, M., Ambesi-Impiombato, A., Antonini, D., Missero, C., Bernardo, D. di, 2008. Direct targets of the TRP63 transcription factor revealed by a combination of gene expression profiling and reverse engineering. Genome Research 18, 939–948. https://doi.org/10.1101/gr.073601.107
-
-
-Dunlop, M.M., Girolami, M.A., Stuart, A.M., Teckentrup, A.L., n.d. How deep are deep Gaussian processes? Journal of Machine Learning Research 19, 1–46.
-
-
-Duvenaud, D., Rippel, O., Adams, R., Ghahramani, Z., 2014. Avoiding pathologies in very deep networks.
-
-
-Havasi, M., Hernández-Lobato, J.M., Murillo-Fuentes, J.J., 2018. Inference in deep Gaussian processes using stochastic gradient Hamiltonian Monte Carlo, in: Bengio, S., Wallach, H., Larochelle, H., Grauman, K., Cesa-Bianchi, N., Garnett, R. (Eds.), Advances in Neural Information Processing Systems 31. Curran Associates, Inc., pp. 7506–7516.
-
-
-Izmailov, P., Maddox, W.J., Kirichenko, P., Garipov, T., Vetrov, D.P., Wilson, A.G., 2019. Subspace inference for bayesian deep learning. CoRR abs/1907.07504.
-
-
-Jacot, A., Ged, F., Gabriel, F., Şimşek, B., Hongler, C., 2021. Deep linear networks dynamics: Low-rank biases induced by initialization scale and L2 regularization.
-
-
-Kalaitzis, A.A., Lawrence, N.D., 2011. A simple approach to ranking differentially expressed gene expression time courses through Gaussian process regression. BMC Bioinformatics 12. https://doi.org/10.1186/1471-2105-12-180
-
-
-Lawrence, N.D., Moore, A.J., 2007. Hierarchical Gaussian process latent variable models. pp. 481–488.
-
-
-MacKay, D.J.C., n.d. Introduction to Gaussian processes. pp. 133–166.
-
-
-Salimbeni, H., Deisenroth, M., 2017. Doubly stochastic variational inference for deep Gaussian processes, in: Guyon, I., Luxburg, U.V., Bengio, S., Wallach, H., Fergus, R., Vishwanathan, S., Garnett, R. (Eds.), Advances in Neural Information Processing Systems 30. Curran Associates, Inc., pp. 4591–4602.
-
-
-Taigman, Y., Yang, M., Ranzato, M., Wolf, L., 2014. DeepFace: Closing the gap to human-level performance in face verification, in: Proceedings of the IEEE Computer Society Conference on Computer Vision and Pattern Recognition. https://doi.org/10.1109/CVPR.2014.220
-
-m.staged_optimize(iters=(1000,1000,10000), messages=(True, True, True))Motorcycle Helmet Data Deep GP
Motorcycle Helmet Data Latent 1
Motorcycle Helmet Data Latent 2
Motorcycle Helmet Pinball Plot
Thanks!
References
diff --git a/_lectures/12-deep-gps-II.html b/_lectures/12-deep-gps-II.html
index 96203ef..d8a21ee 100644
--- a/_lectures/12-deep-gps-II.html
+++ b/_lectures/12-deep-gps-II.html
@@ -1,5 +1,7 @@
---
title: "Deep Gaussian Processes II"
+abstract: |-
+ null
edit_url: https://github.com/mlatcl/gpss/edit/gh-pages/_lamd/deep-gps-II.md
week: 12
featured_image: slides/diagrams/deepgp/olympic-marathon-deep-gp-pinball.svg
@@ -12,207 +14,26 @@
-
-
-
-
-
-
-
-
-Arora, S., Cohen, N., Golowich, N., Hu, W., 2019. A convergence analysis of gradient descent for deep linear neural networks, in: International Conference on Learning Representations.Bui, T., Hernandez-Lobato, D., Hernandez-Lobato, J., Li, Y., Turner, R., 2016. Deep Gaussian processes for regression using approximate expectation propagation, in: Balcan, M.F., Weinberger, K.Q. (Eds.), Proceedings of the 33rd International Conference on Machine Learning, Proceedings of Machine Learning Research. PMLR, New York, New York, USA, pp. 1472–1481.Cho, Y., Saul, L.K., 2009. Kernel methods for deep learning, in: Bengio, Y., Schuurmans, D., Lafferty, J.D., Williams, C.K.I., Culotta, A. (Eds.), Advances in Neural Information Processing Systems 22. Curran Associates, Inc., pp. 342–350.Damianou, A., 2015. Deep Gaussian processes and variational propagation of uncertainty (PhD thesis). University of Sheffield.Damianou, A., Titsias, M.K., Lawrence, N.D., 2016. Variational inference for latent variables and uncertain inputs in Gaussian processes. Journal of Machine Learning Research 17, 1–62.Della Gatta, G., Bansal, M., Ambesi-Impiombato, A., Antonini, D., Missero, C., Bernardo, D. di, 2008. Direct targets of the TRP63 transcription factor revealed by a combination of gene expression profiling and reverse engineering. Genome Research 18, 939–948. https://doi.org/10.1101/gr.073601.107Dunlop, M.M., Girolami, M.A., Stuart, A.M., Teckentrup, A.L., n.d. How deep are deep Gaussian processes? Journal of Machine Learning Research 19, 1–46.Duvenaud, D., Rippel, O., Adams, R., Ghahramani, Z., 2014. Avoiding pathologies in very deep networks.Havasi, M., Hernández-Lobato, J.M., Murillo-Fuentes, J.J., 2018. Inference in deep Gaussian processes using stochastic gradient Hamiltonian Monte Carlo, in: Bengio, S., Wallach, H., Larochelle, H., Grauman, K., Cesa-Bianchi, N., Garnett, R. (Eds.), Advances in Neural Information Processing Systems 31. Curran Associates, Inc., pp. 7506–7516.Izmailov, P., Maddox, W.J., Kirichenko, P., Garipov, T., Vetrov, D.P., Wilson, A.G., 2019. Subspace inference for bayesian deep learning. CoRR abs/1907.07504.Jacot, A., Ged, F., Gabriel, F., Şimşek, B., Hongler, C., 2021. Deep linear networks dynamics: Low-rank biases induced by initialization scale and L2 regularization.Kalaitzis, A.A., Lawrence, N.D., 2011. A simple approach to ranking differentially expressed gene expression time courses through Gaussian process regression. BMC Bioinformatics 12. https://doi.org/10.1186/1471-2105-12-180Lawrence, N.D., Moore, A.J., 2007. Hierarchical Gaussian process latent variable models. pp. 481–488.MacKay, D.J.C., n.d. Introduction to Gaussian processes. pp. 133–166.Salimbeni, H., Deisenroth, M., 2017. Doubly stochastic variational inference for deep Gaussian processes, in: Guyon, I., Luxburg, U.V., Bengio, S., Wallach, H., Fergus, R., Vishwanathan, S., Garnett, R. (Eds.), Advances in Neural Information Processing Systems 30. Curran Associates, Inc., pp. 4591–4602.Taigman, Y., Yang, M., Ranzato, M., Wolf, L., 2014. DeepFace: Closing the gap to human-level performance in face verification, in: Proceedings of the IEEE Computer Society Conference on Computer Vision and Pattern Recognition. https://doi.org/10.1109/CVPR.2014.220Gaussian Process Summer School notebook setup
-
-
-import importlib.util
-cmd = install_command('pods')
-%system {cmd}
-cmd = install_command('notutils')
-%system {cmd}
-cmd = install_command('mlai')
-%system {cmd}Gaussian Process Summer School notebook setup
import importlib.utilcmd = install_command('pods')%system {cmd}cmd = install_command('notutils')%system {cmd}cmd = install_command('mlai')
-%system {cmd}
-cmd = install_command('GPy')
-%system {cmd}GPy: A Gaussian Process Framework in Python
-
-
-
-
-
-
-
-
-
-
-
-
-
-Robot Wireless Data
-
-
-import pods
-import numpy as np
-data=pods.datasets.robot_wireless()Robot Wireless Ground Truth
-
-
-
-
-
-
-
-
-
-
-x = np.linspace(0, 1, data['Y'].shape[0])[:, np.newaxis]
+sns.set_palette('colorblind')}-->cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python
Robot Wireless Data
import pods
+import numpy as npdata=pods.datasets.robot_wireless()Robot Wireless Ground Truth
-x = np.linspace(0, 1, data['Y'].shape[0])[:, np.newaxis]
y = data['Y'][:, output_dim:output_dim+1]
offset = y.mean()
scale = np.sqrt(y.var())
-yhat = (y - offset)/scaleRobot WiFi Data
-
-
-
-
-
-
-
-
-
-
-Gaussian Process Fit to Robot Wireless Data
-
-m_full = GPy.models.GPRegression(x,yhat)
-_ = m_full.optimize() # Optimize parameters of covariance functionRobot WiFi Data GP
-
-
-
-
-
-
-
-
-
-
-mlai.deepgp_tutorial module.
-cmd = install_command('mlai')
-%system {cmd}
-from mlai.deepgp_tutorial import initialize
-from mlai.deepgp_tutorial import staged_optimize
-from mlai.deepgp_tutorial import visualize
-from mlai.deepgp_tutorial import visualize_pinballposterior_sample code allows us to see the output sample locations for a given input. This is useful for visualizing the non-Gaussian nature of the output density.
-from mlai.deepgp_tutorial import posterior_samplelayers = [y.shape[1], 10, 5, 2, 2, x.shape[1]]
+yhat = (y - offset)/scaleRobot WiFi Data
Gaussian Process Fit to Robot Wireless Data
m_full = GPy.models.GPRegression(x,yhat)
+_ = m_full.optimize() # Optimize parameters of covariance functionRobot WiFi Data GP
mlai.deepgp_tutorial module.cmd = install_command('mlai')%system {cmd}from mlai.deepgp_tutorial import initializefrom mlai.deepgp_tutorial import staged_optimizefrom mlai.deepgp_tutorial import visualizefrom mlai.deepgp_tutorial import visualize_pinballposterior_sample code allows us to see the output sample locations for a given input. This is useful for visualizing the non-Gaussian nature of the output density.from mlai.deepgp_tutorial import posterior_sample
-layers = [y.shape[1], 10, 5, 2, 2, x.shape[1]]
inits = ['PCA']*(len(layers)-1)
kernels = []
for i in layers[1:]:
- kernels += [GPy.kern.RBF(i, ARD=True)]m = deepgp.DeepGP(layers,Y=y, X=x, inits=inits,
+ kernels += [GPy.kern.RBF(i, ARD=True)]
-m = deepgp.DeepGP(layers,Y=y, X=x, inits=inits,
kernels=kernels,
num_inducing=50, back_constraint=False)
-m.initialize()
-m.staged_optimize(messages=(True,True,True))Robot WiFi Data Deep GP
-
-
-
-
-
-
-
-
-
-
-
-Robot WiFi Data Deep GP
-
-
-
-
-
-
-
-
-
-
-Robot WiFi Data Latent Space
-
-
-
-
-
-
-
-
-
-
-
-cmd = install_command('PyDeepGP')
-%system {cmd}
-cmd = install_command('mlai')
-%system {cmd}# Late bind setup methods to DeepGP object
+m.initialize()m.staged_optimize(messages=(True,True,True))Robot WiFi Data Deep GP
Robot WiFi Data Deep GP
Robot WiFi Data Latent Space
cmd = install_command('PyDeepGP')%system {cmd}cmd = install_command('mlai')%system {cmd}
-# Late bind setup methods to DeepGP object
from mlai.deepgp_tutorial import initialize
from mlai.deepgp_tutorial import staged_optimize
from mlai.deepgp_tutorial import posterior_sample
@@ -224,368 +45,49 @@ Robot WiFi Data Latent Space
deepgp.DeepGP.staged_optimize=staged_optimize
deepgp.DeepGP.posterior_sample=posterior_sample
deepgp.DeepGP.visualize=visualize
-deepgp.DeepGP.visualize_pinball=visualize_pinballOlympic Marathon Data
-
-
-
-
-
-
-
-
-
-
-
-
-
-cmd = install_command('pods')
-%system {cmd}
-import numpy as np
-import podsdata = pods.datasets.olympic_marathon_men()
+deepgp.DeepGP.visualize_pinball=visualize_pinballOlympic Marathon Data
cmd = install_command('pods')%system {cmd}import numpy as np
+import pods
-data = pods.datasets.olympic_marathon_men()
x = data['X']
y = data['Y']
offset = y.mean()
scale = np.sqrt(y.var())
-yhat = (y - offset)/scale
-
-
-
-
-
-
-
-
-
-Alan Turing
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Alan Turing
Gaussian Process Fit
-
-
-import GPy
-m_full = GPy.models.GPRegression(x,yhat)
-_ = m_full.optimize() # Optimize parameters of covariance functionm_full.optimize() optimizes the parameters of the covariance function and the noise level of the model. Once the fit is complete, we’ll try creating some test points, and computing the output of the GP model in terms of the mean and standard deviation of the posterior functions between 1870 and 2030. We plot the mean function and the standard deviation at 200 locations. We can obtain the predictions using y_mean, y_var = m_full.predict(xt)
@@ -764,15 +766,15 @@ xt = np.linspace(1870,2030,200)[:,np.newaxis]
+\] then we see that without a model we can’t generalise: we only have data. Data is fine for answering very specific questions, like “Who won the Olympic Marathon in 2012?” because we have that answer stored, however, we are not given the answer to many other questions. For example, Alan Turing was a formidable marathon runner, in 1946 he ran a time 2 hours 46 minutes (just under four minutes per kilometer, faster than I and most of the other Endcliffe Park Run runners can do 5 km). What is the probability he would have won an Olympics if one had been held in 1946?Gaussian Process Fit
import GPym_full = GPy.models.GPRegression(x,yhat)
+_ = m_full.optimize() # Optimize parameters of covariance functionm_full.optimize() optimizes the parameters of the covariance function and the noise level of the model. Once the fit is complete, we’ll try creating some test points, and computing the output of the GP model in terms of the mean and standard deviation of the posterior functions between 1870 and 2030. We plot the mean function and the standard deviation at 200 locations. We can obtain the predictions using y_mean, y_var = m_full.predict(xt)
-xt = np.linspace(1870,2030,200)[:,np.newaxis]
yt_mean, yt_var = m_full.predict(xt)
-yt_sd=np.sqrt(yt_var)mlai.plot.
-
-
-
-
-
-
-
-
-
-Fit Quality
-m_clean, where that point is removed.x_clean=np.vstack((x[0:2, :], x[3:, :]))
+yt_sd=np.sqrt(yt_var)mlai.plot.Fit Quality
m_clean, where that point is removed.
-x_clean=np.vstack((x[0:2, :], x[3:, :]))
y_clean=np.vstack((yhat[0:2, :], yhat[3:, :]))
m_clean = GPy.models.GPRegression(x_clean,y_clean)
-_ = m_clean.optimize()
-
-
-
-
-
-
-
-
-
-Deep GP Fit
-
-
-import GPy
-import deepgphidden = 1
+_ = m_clean.optimize()Deep GP Fit
import GPy
+import deepgp
-hidden = 1
m = deepgp.DeepGP([y.shape[1],hidden,x.shape[1]],Y=yhat, X=x, inits=['PCA','PCA'],
kernels=[GPy.kern.RBF(hidden,ARD=True),
GPy.kern.RBF(x.shape[1],ARD=True)], # the kernels for each layer
- num_inducing=50, back_constraint=False)
-# Call the initalization
-m.initialize()for layer in m.layers:
+ num_inducing=50, back_constraint=False)# Call the initalization
+m.initialize()
-for layer in m.layers:
layer.likelihood.variance.constrain_positive(warning=False)
-m.optimize(messages=True,max_iters=10000)
-m.staged_optimize(messages=(True,True,True))Olympic Marathon Data Deep GP
-
-
-
-
-
-
-
-
-
-
-Olympic Marathon Data Deep GP
-
-
-
-
-
-
-
-
-
-
-Fitted GP for each layer
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Olympic Marathon Pinball Plot
-
-
-
-
-
-
-
-
-
-
-Gene Expression Example
-
-Della Gatta Gene Data
-
-
-
-
-import numpy as np
-import podsdata = pods.datasets.della_gatta_TRP63_gene_expression(data_set='della_gatta',gene_number=937)
+m.optimize(messages=True,max_iters=10000)m.staged_optimize(messages=(True,True,True))Olympic Marathon Data Deep GP
Olympic Marathon Data Deep GP
Fitted GP for each layer
Olympic Marathon Pinball Plot
Gene Expression Example
Della Gatta Gene Data
import numpy as np
+import pods
-data = pods.datasets.della_gatta_TRP63_gene_expression(data_set='della_gatta',gene_number=937)
x = data['X']
y = data['Y']
offset = y.mean()
-scale = np.sqrt(y.var())
-
-
-
-
-
-
-
-
-
-
-
-
-\freddieKalaitzisPicture{15%}
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-import GPym_full = GPy.models.GPRegression(x,yhat)
+scale = np.sqrt(y.var())\freddieKalaitzisPicture{15%}import GPy
-m_full = GPy.models.GPRegression(x,yhat)
m_full.kern.lengthscale=50
-_ = m_full.optimize() # Optimize parameters of covariance functionxt = np.linspace(-20,260,200)[:,np.newaxis]
+_ = m_full.optimize() # Optimize parameters of covariance function
-xt = np.linspace(-20,260,200)[:,np.newaxis]
yt_mean, yt_var = m_full.predict(xt)
-yt_sd=np.sqrt(yt_var)mlai.plot.
-
-
-
-
-
-
-
-
-
-m_full2 = GPy.models.GPRegression(x,yhat)
+yt_sd=np.sqrt(yt_var)mlai.plot.
-m_full2 = GPy.models.GPRegression(x,yhat)
m_full2.kern.lengthscale=2000
-_ = m_full2.optimize() # Optimize parameters of covariance function
-
-
-
-
-
-
-
-
-
-m_full3 = GPy.models.GPRegression(x,yhat)
+_ = m_full2.optimize() # Optimize parameters of covariance function
-m_full3 = GPy.models.GPRegression(x,yhat)
m_full3.kern.lengthscale=20
m_full3.likelihood.variance=0.001
-_ = m_full3.optimize() # Optimize parameters of covariance function
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-layers = [y.shape[1], 1,x.shape[1]]
+-->
-layers = [y.shape[1], 1,x.shape[1]]
inits = ['PCA']*(len(layers)-1)
kernels = []
for i in layers[1:]:
@@ -593,93 +95,8 @@ Della Gatta Gene Data
m = deepgp.DeepGP(layers,Y=yhat, X=x,
inits=inits,
kernels=kernels, # the kernels for each layer
- num_inducing=20, back_constraint=False)
-m.initialize()
-m.staged_optimize()Della Gatta Gene Data Deep GP
-
-
-
-
-
-
-
-
-
-
-
-Della Gatta Gene Data Deep GP
-
-
-
-
-
-
-
-
-
-
-Della Gatta Gene Data Latent 1
-
-
-
-
-
-
-
-
-
-
-Della Gatta Gene Data Latent 2
-
-
-
-
-
-
-
-
-
-
-TP53 Gene Pinball Plot
-
-
-
-
-
-
-
-
-
-
-Step Function
-
-num_low=25
+ num_inducing=20, back_constraint=False)m.initialize()
+m.staged_optimize()Della Gatta Gene Data Deep GP
Della Gatta Gene Data Deep GP
Della Gatta Gene Data Latent 1
Della Gatta Gene Data Latent 2
TP53 Gene Pinball Plot
Step Function
-num_low=25
num_high=25
gap = -.1
noise=0.0001
@@ -688,50 +105,8 @@ Step Function
y = np.vstack((np.zeros((num_low, 1)), np.ones((num_high,1))))
scale = np.sqrt(y.var())
offset = y.mean()
-yhat = (y-offset)/scaleStep Function Data
-
-
-
-
-
-
-
-
-
-
-Step Function Data GP
-GPy as follows.
-m_full = GPy.models.GPRegression(x,yhat)
-_ = m_full.optimize() # Optimize parameters of covariance functionGPy.models.GPRegression() gives us a standard GP regression model with exponentiated quadratic covariance function.m_full.optimize() which calls an L-BGFS gradient based solver in python.
-
-
-
-
-
-
-
-
-
-Step Function Data Deep GP
-
-GPy.kern.RBF).layers = [y.shape[1], 1, 1, 1,x.shape[1]]
+yhat = (y-offset)/scaleStep Function Data
Step Function Data GP
GPy as follows.m_full = GPy.models.GPRegression(x,yhat)
+_ = m_full.optimize() # Optimize parameters of covariance functionGPy.models.GPRegression() gives us a standard GP regression model with exponentiated quadratic covariance function.m_full.optimize() which calls an L-BGFS gradient based solver in python.Step Function Data Deep GP
GPy.kern.RBF).
-layers = [y.shape[1], 1, 1, 1,x.shape[1]]
inits = ['PCA']*(len(layers)-1)
kernels = []
for i in layers[1:]:
@@ -740,130 +115,14 @@ Step Function Data Deep GP
m = deepgp.DeepGP(layers,Y=yhat, X=x,
inits=inits,
kernels=kernels, # the kernels for each layer
- num_inducing=20, back_constraint=False)
-m.initialize()
-m.staged_optimize()
-
-
-
-
-
-
-
-
-
-Step Function Data Deep GP
-mlai.plot, model_sample
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-import podsdata = pods.datasets.mcycle()
+ num_inducing=20, back_constraint=False)m.initialize()
+m.staged_optimize()Step Function Data Deep GP
mlai.plot, model_sampleimport pods
-data = pods.datasets.mcycle()
x = data['X']
y = data['Y']
scale=np.sqrt(y.var())
offset=y.mean()
-yhat = (y - offset)/scaleMotorcycle Helmet Data
-
-
-
-
-
-
-
-
-
-
-
-
-m_full = GPy.models.GPRegression(x,yhat)
-_ = m_full.optimize() # Optimize parameters of covariance functionMotorcycle Helmet Data GP
-
-
-
-
-
-
-
-
-
-
-
-Motorcycle Helmet Data Deep GP
-
-
-import deepgplayers = [y.shape[1], 1, x.shape[1]]
+yhat = (y - offset)/scaleMotorcycle Helmet Data
m_full = GPy.models.GPRegression(x,yhat)
+_ = m_full.optimize() # Optimize parameters of covariance functionMotorcycle Helmet Data GP
Motorcycle Helmet Data Deep GP
import deepgp
-layers = [y.shape[1], 1, x.shape[1]]
inits = ['PCA']*(len(layers)-1)
kernels = []
for i in layers[1:]:
@@ -875,355 +134,42 @@ Motorcycle Helmet Data Deep GP
-m.initialize()
-m.staged_optimize(iters=(1000,1000,10000), messages=(True, True, True))
-
-
-
-
-
-
-
-
-
-Motorcycle Helmet Data Deep GP
-
-
-
-
-
-
-
-
-
-
-Motorcycle Helmet Data Latent 1
-
-
-
-
-
-
-
-
-
-
-Motorcycle Helmet Data Latent 2
-
-
-
-
-
-
-
-
-
-
-Motorcycle Helmet Pinball Plot
-
-
-
-
-
-
-
-
-
-
-‘High Five’ Motion Capture Data
-
-
-import pods
-data = pods.datasets.cmu_mocap_high_five()
-data['Y1'].shape
-data['Y2'].shape
-print(data['citation'])info and details.print(data['info'])
+m.initialize()m.staged_optimize(iters=(1000,1000,10000), messages=(True, True, True))Motorcycle Helmet Data Deep GP
Motorcycle Helmet Data Latent 1
Motorcycle Helmet Data Latent 2
Motorcycle Helmet Pinball Plot
‘High Five’ Motion Capture Data
import podsdata = pods.datasets.cmu_mocap_high_five()data['Y1'].shape
+data['Y2'].shapeprint(data['citation'])info and details.
-print(data['info'])
print()
-print(data['details'])Shared LVM
-
-
-
-
-
-
-
-
-
-
- -
-
-
-
-
Subsample of the MNIST Data
-
-
-from sklearn.datasets import fetch_openml
-mnist = fetch_openml('mnist_784')
-import numpy as npnp.random.seed(0)
+print(data['details'])Shared LVM

Subsample of the MNIST Data
from sklearn.datasets import fetch_openmlmnist = fetch_openml('mnist_784', version=1, as_frame=False, parser='liac-arff')import numpy as np
-np.random.seed(0)
digits = [0,1,2,3,4]
N_per_digit = 100
Y = []
labels = []
-for d in digits:
- imgs = mnist['data'][mnist['target']==str(d)]
- Y.append(imgs.loc[np.random.permutation(imgs.index)[:N_per_digit]])
- labels.append(np.ones(N_per_digit)*d)
-Y = np.vstack(Y).astype(np.float64)
-labels = np.hstack(labels)
-Y /= 255MNIST Digit Examples
-
-
-
-
-
-
-
-
-
-
-
-Fitting a Deep GP to a the MNIST Digits Subsample
-
-
-\zhenwenDaiPicture{15%}\andreasDamianouPicture{15%}
-
-Fit a Deep GP
-
-import deepgp
-import GPynum_latent = 2
+data = np.asarray(mnist.data)
+target = np.asarray(mnist.target).astype(str)
+for d in digits:
+ imgs = data[target == str(d)]
+ Y.append(imgs[np.random.permutation(len(imgs))[:N_per_digit]])
+ labels.append(np.ones(N_per_digit)*d)
+Y = np.vstack(Y).astype(np.float64)
+labels = np.hstack(labels)
+Y /= 255MNIST Digit Examples
Fitting a Deep GP to a the MNIST Digits Subsample
\zhenwenDaiPicture{15%}\andreasDamianouPicture{15%}Fit a Deep GP
import deepgp
+import GPy
-num_latent = 2
num_hidden_2 = 5
m = deepgp.DeepGP([Y.shape[1],num_hidden_2,num_latent],
Y,
kernels=[GPy.kern.RBF(num_hidden_2,ARD=True),
GPy.kern.RBF(num_latent,ARD=False)],
num_inducing=50, back_constraint=False,
- encoder_dims=[[200],[200]])Initialization
-m.obslayer.likelihood.variance[:] = Y.var()*0.01
+ encoder_dims=[[200],[200]])Initialization
-m.obslayer.likelihood.variance[:] = Y.var()*0.01
for layer in m.layers:
layer.kern.variance.fix(warning=False)
- layer.likelihood.variance.fix(warning=False)
-m.optimize(messages=False,max_iters=100)for layer in m.layers:
+ layer.likelihood.variance.fix(warning=False)m.optimize(messages=False,max_iters=100)
-for layer in m.layers:
layer.kern.variance.constrain_positive(warning=False)
-m.optimize(messages=False,max_iters=100)for layer in m.layers:
+m.optimize(messages=False,max_iters=100)
-for layer in m.layers:
layer.likelihood.variance.constrain_positive(warning=False)
-m.optimize(messages=True,max_iters=10000)Visualize the latent space of the top layer
-
-
-
-
-
-
-
-
-
-
-Visualize the latent space of the intermediate layer
-
-m.obslayer.kern.lengthscale
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Generate From Model
-
+m.optimize(messages=True,max_iters=10000)Visualize the latent space of the top layer
Visualize the latent space of the intermediate layer
m.obslayer.kern.lengthscaleGenerate From Model
-
rows = 10
cols = 20
t=np.linspace(-1, 1, rows*cols)[:, None]
kern = GPy.kern.RBF(1,lengthscale=0.05)
cov = kern.K(t, t)
-x = np.random.multivariate_normal(np.zeros(rows*cols), cov, num_latent).T
-
-
-
-
-
-
-
-
-
-Deep Health
-
-
-
-
-
-
-
-
-
-
-
-Thanks!
-
-
-References
-
-
+x = np.random.multivariate_normal(np.zeros(rows*cols), cov, num_latent).T
-CMU Motion Capture Lab, 2003. The CMU mocap database.
-
-
-Damianou, A., Lawrence, N.D., 2013. Deep Gaussian processes. pp. 207–215.
-
-
-Della Gatta, G., Bansal, M., Ambesi-Impiombato, A., Antonini, D., Missero, C., Bernardo, D. di, 2008. Direct targets of the TRP63 transcription factor revealed by a combination of gene expression profiling and reverse engineering. Genome Research 18, 939–948. https://doi.org/10.1101/gr.073601.107
-
-
-Ferris, B.D., Fox, D., Lawrence, N.D., 2007. WiFi-SLAM using Gaussian process latent variable models, in: Veloso, M.M. (Ed.), Proceedings of the 20th International Joint Conference on Artificial Intelligence (IJCAI 2007). pp. 2480–2485.
-
-
-Kalaitzis, A.A., Lawrence, N.D., 2011. A simple approach to ranking differentially expressed gene expression time courses through Gaussian process regression. BMC Bioinformatics 12. https://doi.org/10.1186/1471-2105-12-180
-
-
-Lawrence, N.D., Moore, A.J., 2007. Hierarchical Gaussian process latent variable models. pp. 481–488.
-
-Deep Health
Thanks!
References
diff --git a/_lectures/13-emulation.html b/_lectures/13-emulation.html
index 3585b0a..ef9b08a 100644
--- a/_lectures/13-emulation.html
+++ b/_lectures/13-emulation.html
@@ -24,595 +24,22 @@
-
-
-
-
-
-
-
-
-CMU Motion Capture Lab, 2003. The CMU mocap database.Damianou, A., Lawrence, N.D., 2013. Deep Gaussian processes. pp. 207–215.Della Gatta, G., Bansal, M., Ambesi-Impiombato, A., Antonini, D., Missero, C., Bernardo, D. di, 2008. Direct targets of the TRP63 transcription factor revealed by a combination of gene expression profiling and reverse engineering. Genome Research 18, 939–948. https://doi.org/10.1101/gr.073601.107Ferris, B.D., Fox, D., Lawrence, N.D., 2007. WiFi-SLAM using Gaussian process latent variable models, in: Veloso, M.M. (Ed.), Proceedings of the 20th International Joint Conference on Artificial Intelligence (IJCAI 2007). pp. 2480–2485.Kalaitzis, A.A., Lawrence, N.D., 2011. A simple approach to ranking differentially expressed gene expression time courses through Gaussian process regression. BMC Bioinformatics 12. https://doi.org/10.1186/1471-2105-12-180Lawrence, N.D., Moore, A.J., 2007. Hierarchical Gaussian process latent variable models. pp. 481–488.Gaussian Process Summer School notebook setup
-
-
-import importlib.util
-cmd = install_command('pods')
-%system {cmd}
-cmd = install_command('notutils')
-%system {cmd}
-cmd = install_command('mlai')
-%system {cmd}Gaussian Process Summer School notebook setup
import importlib.utilcmd = install_command('pods')%system {cmd}cmd = install_command('notutils')%system {cmd}cmd = install_command('mlai')
-%system {cmd}
-cmd = install_command('GPy')
-%system {cmd}GPy: A Gaussian Process Framework in Python
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Game of Life
-
-Cellular Automata
-
-
-
-
-
-Life Rules
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
- -
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
Game of Life Implementation
-
-
-
-
-
-
-
-
-
-
-
-Spaceships, oscillators and static patterns
-
-Pattern Analysis
-
-import matplotlib.pyplot as plt
-from matplotlib.animation import FuncAnimation
-John Horton Conway, as the creator of the game of life, could be seen somehow as the god of this small universe. He created the rules. The rules are so simple that in many senses he, and we, are all-knowing in this space. But despite our knowledge, this world can still ‘surprise’ us. From the simple rules, emergent patterns of behaviour arise.
-
-
-
-
-
-
-
-
-
- -
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
 -
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
 -
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
 -
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
cmd = install_command('GPy')%system {cmd}GPy: A Gaussian Process Framework in Python
Game of Life
Cellular Automata
Life Rules

Game of Life Implementation
Spaceships, oscillators and static patterns
Pattern Analysis
import matplotlib.pyplot as plt
+from matplotlib.animation import FuncAnimation
+John Horton Conway, as the creator of the game of life, could be seen somehow as the god of this small universe. He created the rules. The rules are so simple that in many senses he, and we, are all-knowing in this space. But despite our knowledge, this world can still ‘surprise’ us. From the simple rules, emergent patterns of behaviour arise.


Laplace’s Gremlin
-
-
-
-
-
-
-
-
-
-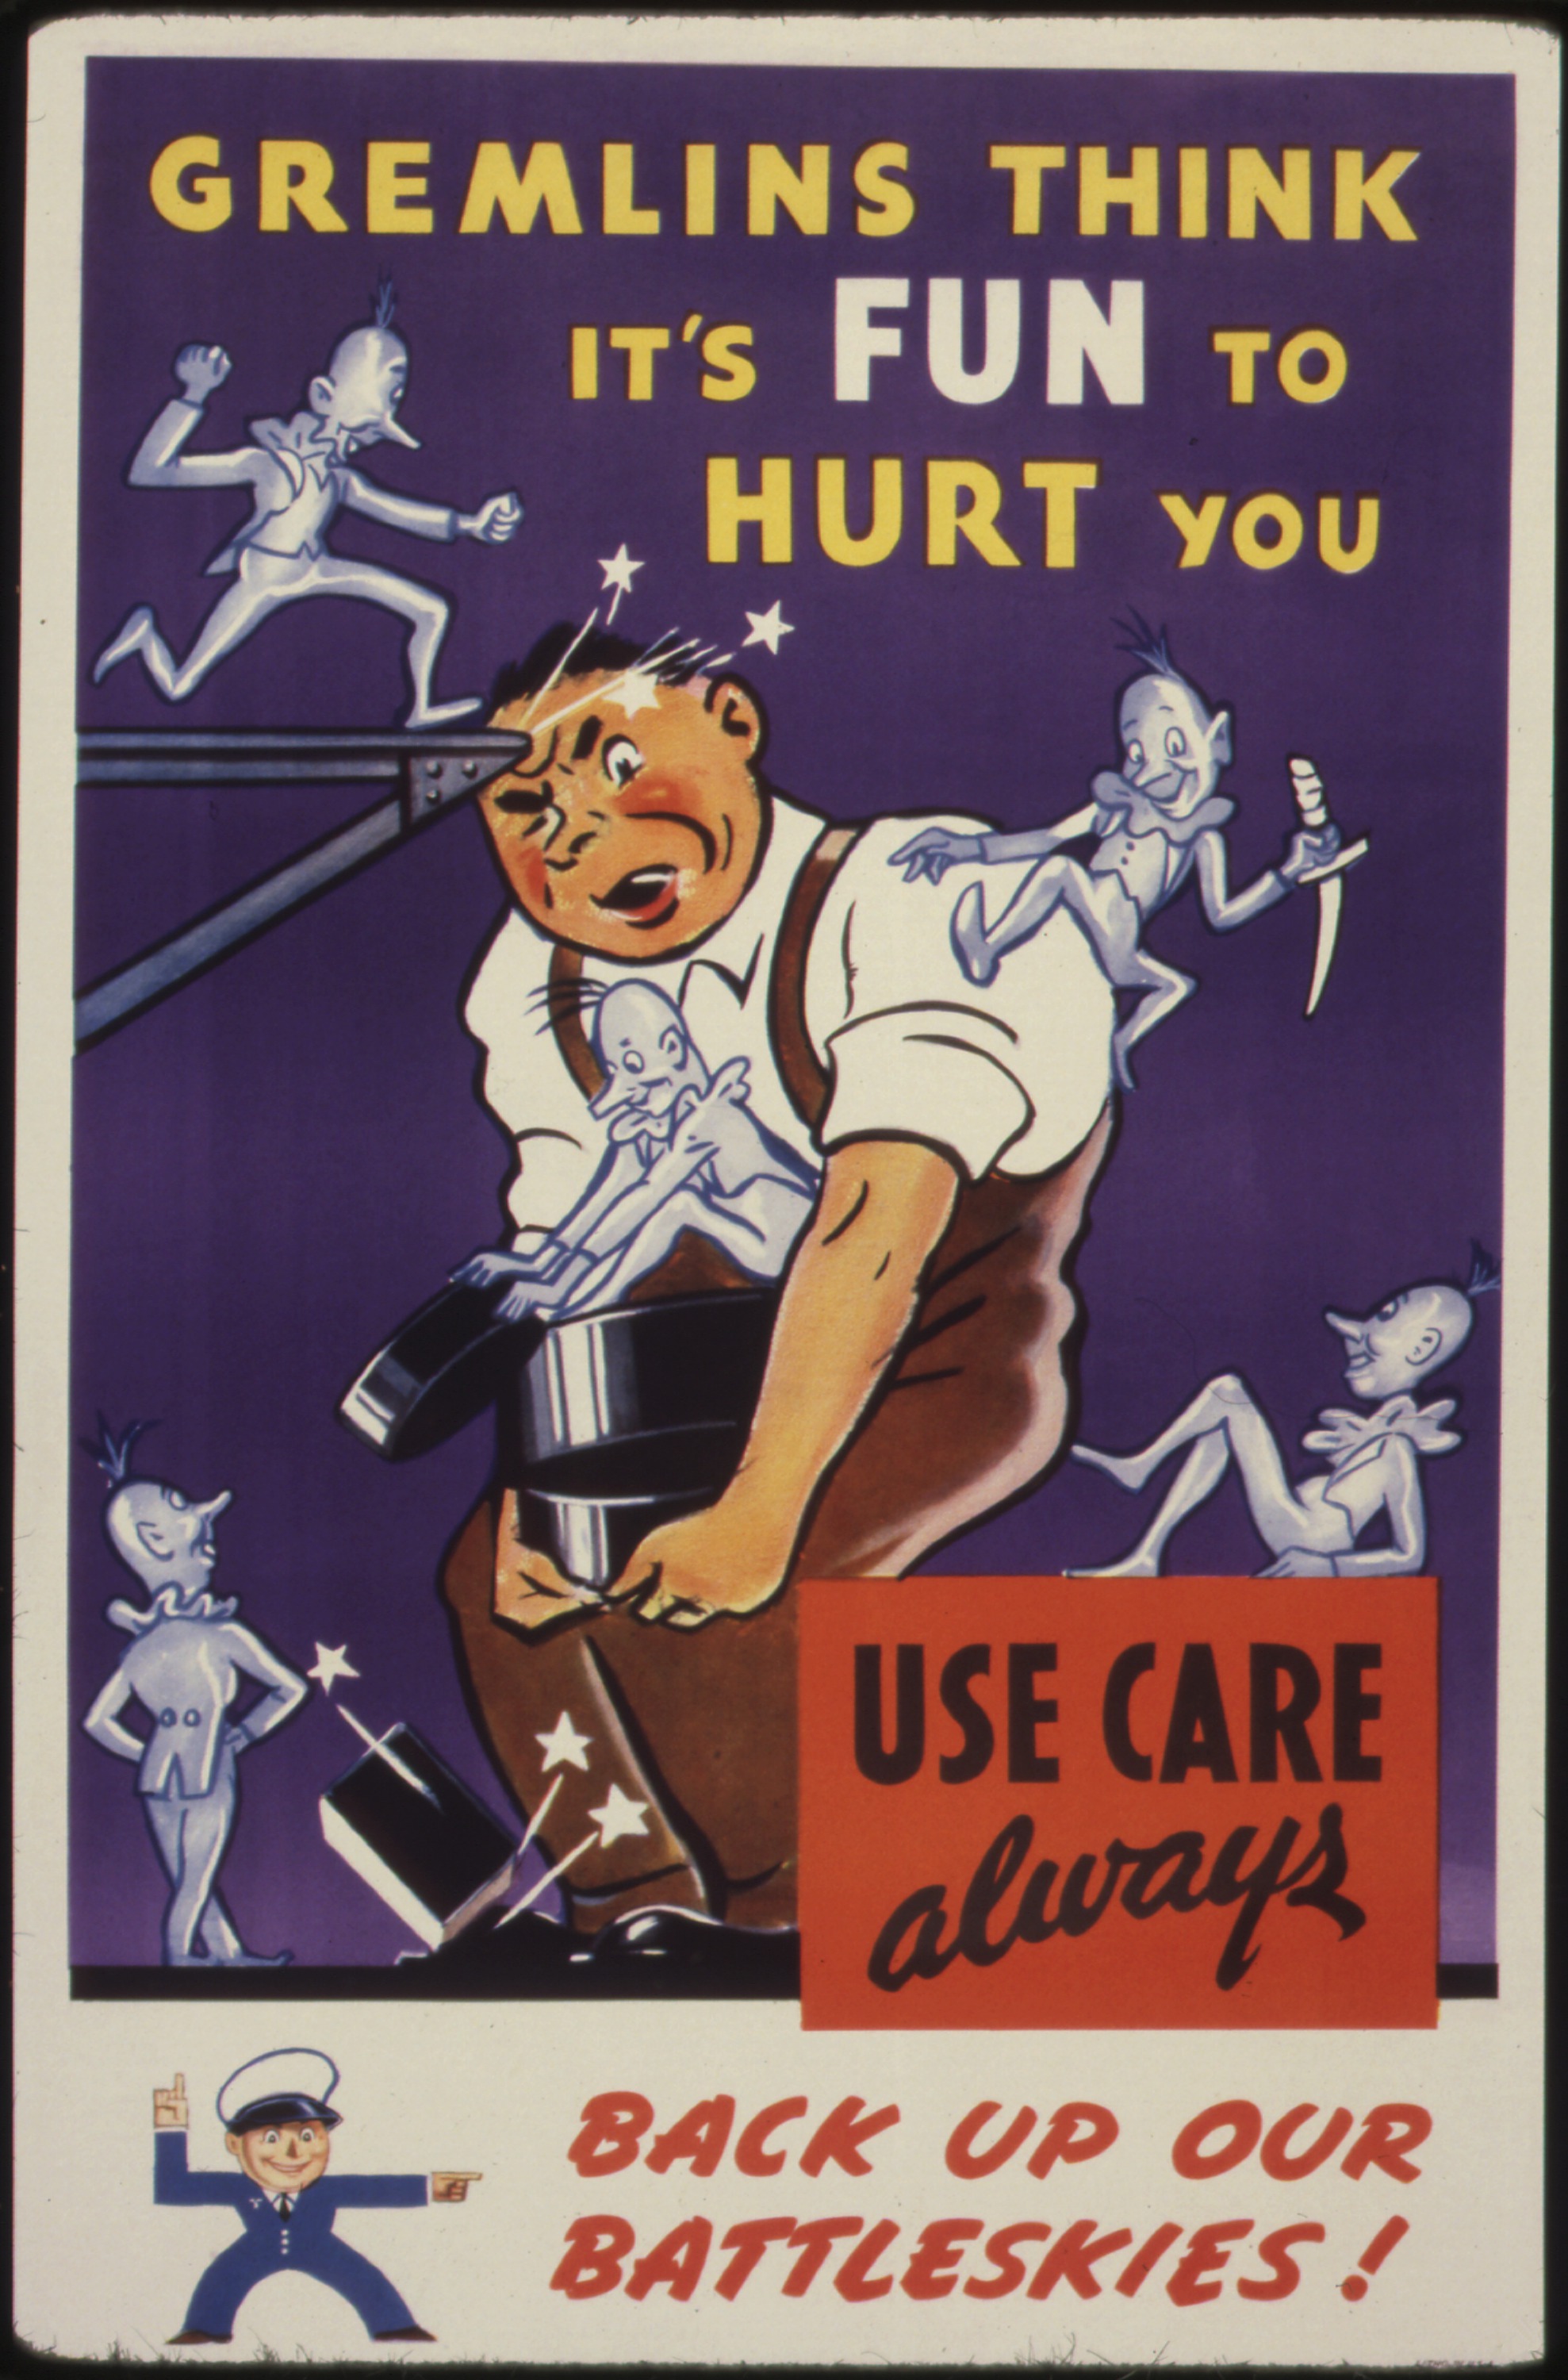 -
-
-
-
-
-
Simulation System
-
-
-
-
-
-
-
-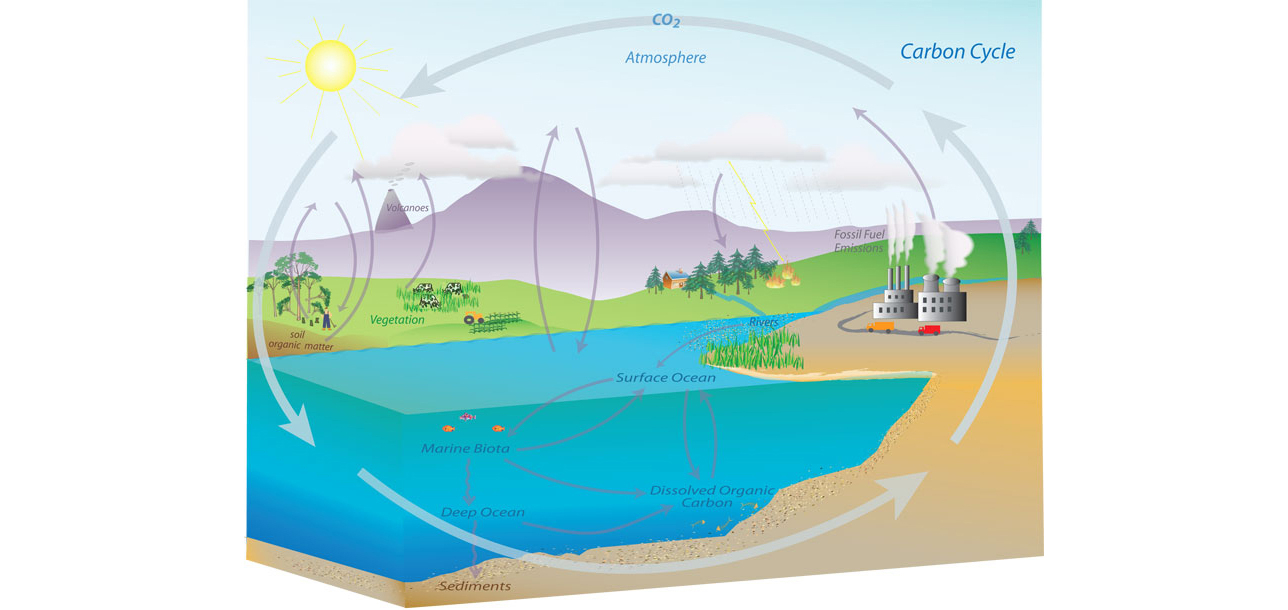 -
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
Monolithic System
-
-
-
-
-
-
-
-
-
-
-Service Oriented Architecture
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Statistical Emulation
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-GPy and Emulation
-
-Laplace’s Gremlin

Simulation System

Monolithic System
Service Oriented Architecture
Statistical Emulation
GPy and Emulation
-import numpy as npdef branin(X):
+\] where we are setting \(a=1\), \(b=5.1/(4\pi^2)\), \(c=5/\pi\), \(r=6\), \(s=10\) and \(t=1/(8\pi)\).import numpy as np
-def branin(X):
y = ((X[:,1]-5.1/(4*np.pi**2)*X[:,0]**2+5*X[:,0]/np.pi-6)**2
+ 10*(1-1/(8*np.pi))*np.cos(X[:,0])+10)
- return(y)# Training set defined as a 5*5 grid:
+ return(y)
-# Training set defined as a 5*5 grid:
xg1 = np.linspace(-5,10,5)
xg2 = np.linspace(0,15,5)
X = np.zeros((xg1.size * xg2.size,2))
@@ -620,273 +47,33 @@ GPy and Emulation
for j,x2 in enumerate(xg2):
X[i+xg1.size*j,:] = [x1,x2]
-Y = branin(X)[:,np.newaxis]Computation of \(\left\langle f(U)\right\rangle\)
-np.mean(Y). Since the points are distributed on a grid, this can be seen as the approximation of the integral by a rough Riemann sum.
-print('Estimate of the expectation is given by: {mean}'.format(mean=Y.mean()))
-import GPy# Create an exponentiated quadratic plus bias covariance function
+Y = branin(X)[:,np.newaxis]Computation of \(\left\langle f(U)\right\rangle\)
np.mean(Y). Since the points are distributed on a grid, this can be seen as the approximation of the integral by a rough Riemann sum.print('Estimate of the expectation is given by: {mean}'.format(mean=Y.mean()))import GPy
-# Create an exponentiated quadratic plus bias covariance function
kern_eq = GPy.kern.RBF(input_dim=2, ARD = True)
kern_bias = GPy.kern.Bias(input_dim=2)
-kern = kern_eq + kern_bias
-# Build a GP model
-model = GPy.models.GPRegression(X,Y,kern)
-# fix the noise variance
-model.likelihood.variance.fix(1e-5)
-kern.rbf.lengthscale = np.asarray([3, 3])
-# Randomize the model and optimize
-model.optimize(messages=True)
-
-
-
-
-
-
-
-
-
-# Compute the mean of model prediction on 1e5 Monte Carlo samples
+kern = kern_eq + kern_bias# Build a GP model
+model = GPy.models.GPRegression(X,Y,kern)# fix the noise variance
+model.likelihood.variance.fix(1e-5)kern.rbf.lengthscale = np.asarray([3, 3])# Randomize the model and optimize
+model.optimize(messages=True)
-# Compute the mean of model prediction on 1e5 Monte Carlo samples
Xp = np.random.uniform(size=(int(1e5),2))
Xp[:,0] = Xp[:,0]*15-5
Xp[:,1] = Xp[:,1]*15
mu, var = model.predict(Xp)
-print('The estimate of the mean of the Branin function is {mean}'.format(mean=np.mean(mu)))Exercise 1
-Exercise 2
-Uncertainty Quantification and Design of Experiments
-
-
-
-
-
-
-
-Emukit
-
-
-\javierGonzalezPicture{10%}\andreiPaleyesPicture{10%}\markPullinPicture{10%}\marenMahsereciPicture{10%}
-
-GPyOpt worked with the SheffieldML software GPy for performing Bayesian optimization.GPyOpt had a modular design that allows the user to provide their own surrogate models, the package was built with GPy as a surrogate model in mind, but other surrogate models could also be wrapped and integrated.GPyOpt didn’t allow the full flexibility of surrogate modelling for domains like experimental design, sensitivity analysis etc.GPyOpt, the aim with Emukit was to use the modularisation ideas embedded in GPyOpt, but to extend them beyond the modularisation of the surrogate models to modularisation of the acquisition function.
-
-
-
-
-
- -
-
-
-
-
-
GPy.
-cmd = install_command('GPy')
-%system {cmd}pyDOE package.
-cmd = install_command('pyDOE')
-%system {cmd}
-cmd = install_command('EmuKit')
-%system {cmd}
-\javierGonzalezPicture{10%}\andreiPaleyesPicture{10%}\markPullinPicture{10%}\marenMahsereciPicture{10%}
-
-Emukit Vision
-
-Emulation in Emukit
-
-
-Emukit and Emulation
-
-
-
-
-
-
-
-
-
-
-Methods
-Models
-Tasks
-while stopping condition is not met:
+print('The estimate of the mean of the Branin function is {mean}'.format(mean=np.mean(mu)))Exercise 1
Exercise 2
Uncertainty Quantification and Design of Experiments
Emukit
\javierGonzalezPicture{10%}\andreiPaleyesPicture{10%}\markPullinPicture{10%}\marenMahsereciPicture{10%}GPyOpt worked with the SheffieldML software GPy for performing Bayesian optimization.GPyOpt had a modular design that allows the user to provide their own surrogate models, the package was built with GPy as a surrogate model in mind, but other surrogate models could also be wrapped and integrated.GPyOpt didn’t allow the full flexibility of surrogate modelling for domains like experimental design, sensitivity analysis etc.GPyOpt, the aim with Emukit was to use the modularisation ideas embedded in GPyOpt, but to extend them beyond the modularisation of the surrogate models to modularisation of the acquisition function.
GPy.cmd = install_command('GPy')%system {cmd}pyDOE package.cmd = install_command('pyDOE')%system {cmd}cmd = install_command('EmuKit')%system {cmd}\javierGonzalezPicture{10%}\andreiPaleyesPicture{10%}\markPullinPicture{10%}\marenMahsereciPicture{10%}Emukit Vision
Emulation in Emukit
Emukit and Emulation
Methods
Models
Tasks
-while stopping condition is not met:
optimize acquisition function
evaluate user function
- update model with new observationLoop
-emukit.core.loop.OuterLoop class is the abstract loop where the different components come together. There are more specific loops for Bayesian optimization and experimental design that construct some of the component parts for you.Model
-Emukit loops need a probabilistic model of the underlying system. Emukit does not provide functionality to build models as there are already many good modelling frameworks available in python. Instead, we provide a way of interfacing third part modelling libraries with Emukit. We already provide a wrapper for using a model created with GPy. For instructions on how to include your own model please see this notebook.IModel, which implements functionality to make predictions and update the model but a model may implement any number of other interfaces such as IDifferentiable which indicates a model has prediction derivatives available.Candidate Point Calculator
-SequentialPointCalculator, collects one point at a time by finding where the acquisition is a maximum by applying the acquisition optimizer to the acquisition function. More complex implementations will enable batches of points to be collected so that the user function can be evaluated in parallel.Acquisition
-Acquisition Optimizer
-AcquisitionOptimizer optimizes the acquisition function to find the point at which the acquisition is a maximum. This will use the acquisition function gradients if they are available. If gradients of the acquisition function are not available, it will either estimate them numerically or use a gradient free optimizer.User Function
-Model Updater
-ModelUpdater class updates the model with new training data after a new point is observed and optimizes any hyper-parameters of the model. It can decide whether hyper-parameters need updating based on some internal logic.Stopping Condition
-StoppingCondition class chooses when we should stop collecting points. The most commonly used example is to stop when a set number of iterations have been reached.Emukit Playground
-
-
-\leahHirstPicture{15%}\cliffMcCollumPicture{15%}
-
-
-
-
-
-
-
-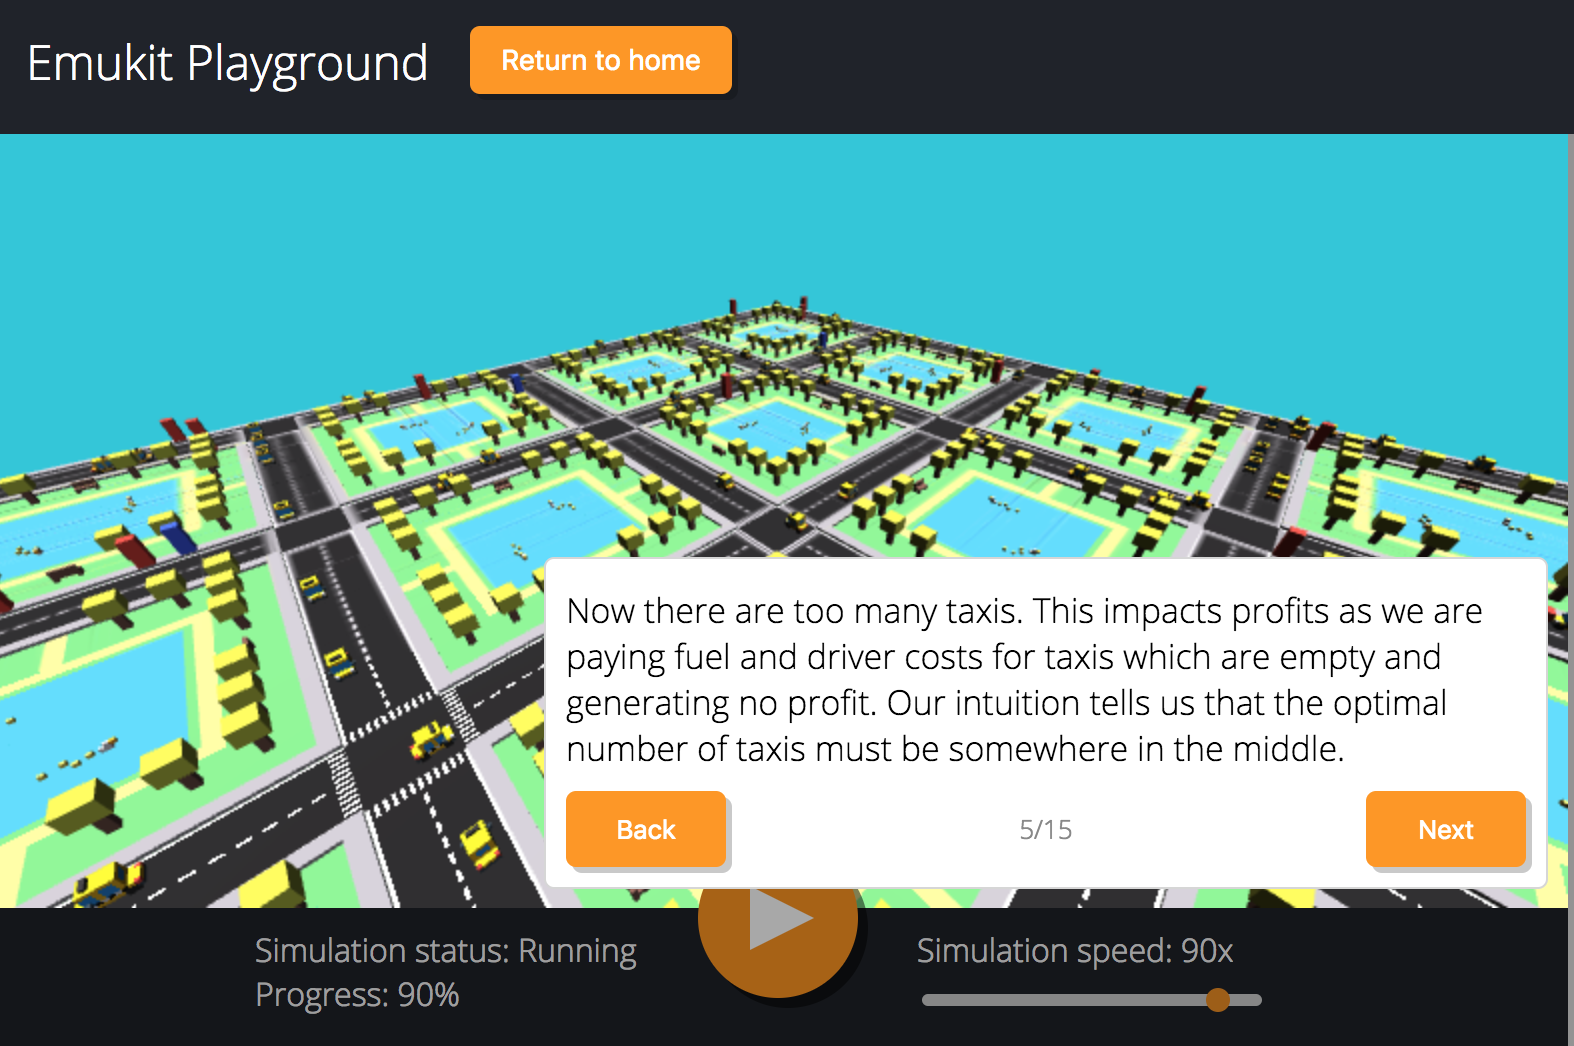 -
-
-
-
-
-
-
-
-
-
-
-
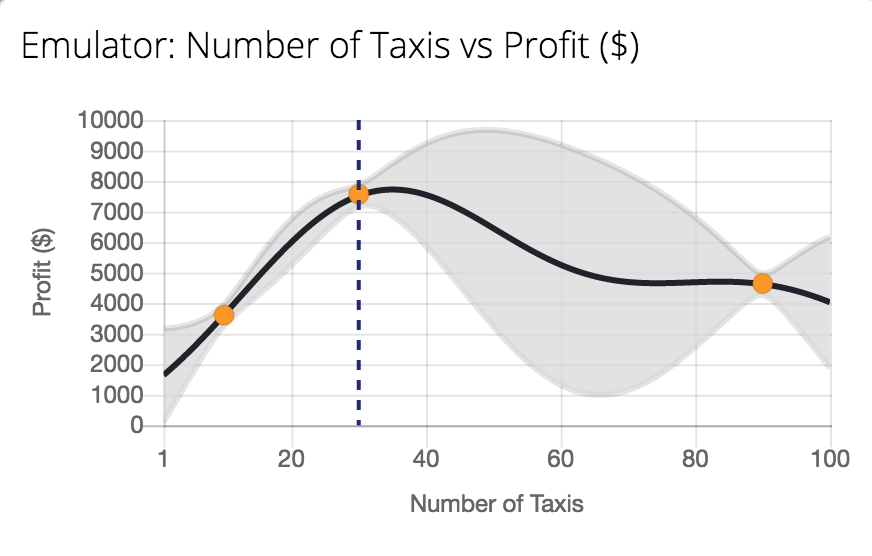 -
-
-
-
-
-
Emukit Tutorial
-
-
-cmd = install_command('GPy')
-%system {cmd}
-cmd = install_command('EmuKit')
-%system {cmd}
-cmd = install_command('mlai')
-%system {cmd}
-import numpy as np
-import GPy
-from emukit.experimental_design.experimental_design_loop import ExperimentalDesignLoop
-ExperimentalDesignLoop?
-from emukit.model_wrappers import SimpleGaussianProcessModel
-SimpleGaussianProcessModel?x_min = -30.0
+ update model with new observationLoop
emukit.core.loop.OuterLoop class is the abstract loop where the different components come together. There are more specific loops for Bayesian optimization and experimental design that construct some of the component parts for you.Model
Emukit loops need a probabilistic model of the underlying system. Emukit does not provide functionality to build models as there are already many good modelling frameworks available in python. Instead, we provide a way of interfacing third part modelling libraries with Emukit. We already provide a wrapper for using a model created with GPy. For instructions on how to include your own model please see this notebook.IModel, which implements functionality to make predictions and update the model but a model may implement any number of other interfaces such as IDifferentiable which indicates a model has prediction derivatives available.Candidate Point Calculator
SequentialPointCalculator, collects one point at a time by finding where the acquisition is a maximum by applying the acquisition optimizer to the acquisition function. More complex implementations will enable batches of points to be collected so that the user function can be evaluated in parallel.Acquisition
Acquisition Optimizer
AcquisitionOptimizer optimizes the acquisition function to find the point at which the acquisition is a maximum. This will use the acquisition function gradients if they are available. If gradients of the acquisition function are not available, it will either estimate them numerically or use a gradient free optimizer.User Function
Model Updater
ModelUpdater class updates the model with new training data after a new point is observed and optimizes any hyper-parameters of the model. It can decide whether hyper-parameters need updating based on some internal logic.Stopping Condition
StoppingCondition class chooses when we should stop collecting points. The most commonly used example is to stop when a set number of iterations have been reached.Emukit Playground
\leahHirstPicture{15%}\cliffMcCollumPicture{15%}

Emukit Tutorial
cmd = install_command('GPy')%system {cmd}cmd = install_command('EmuKit')%system {cmd}cmd = install_command('mlai')%system {cmd}import numpy as np
+import GPyfrom emukit.experimental_design.experimental_design_loop import ExperimentalDesignLoopExperimentalDesignLoop?from emukit.model_wrappers import SimpleGaussianProcessModelSimpleGaussianProcessModel?
-x_min = -30.0
x_max = 30.0
x = np.random.uniform(x_min, x_max, (10, 1))
-y = np.sin(x) + np.random.randn(10, 1) * 0.05sklearn GP model.
-emukit_model = SimpleGaussianProcessModel(x, y)
-from emukit.core import ParameterSpace, ContinuousParameter
-from emukit.core.loop import UserFunctionWrapper
-p = ContinuousParameter('c', x_min, x_max)
-space = ParameterSpace([p])
-loop = ExperimentalDesignLoop(space, emukit_model)
-loop.run_loop(np.sin, 30)plot_min = -40.0
+y = np.sin(x) + np.random.randn(10, 1) * 0.05sklearn GP model.emukit_model = SimpleGaussianProcessModel(x, y)from emukit.core import ParameterSpace, ContinuousParameter
+from emukit.core.loop import UserFunctionWrapperp = ContinuousParameter('c', x_min, x_max)
+space = ParameterSpace([p])loop = ExperimentalDesignLoop(space, emukit_model)
+loop.run_loop(np.sin, 30)
-plot_min = -40.0
plot_max = 40.0
real_x = np.arange(plot_min, plot_max, 0.2)
-real_y = np.sin(real_x)
-
-
-
-
-
-
-
-
-
-ExperimentalDesignLoop: learning function \(\sin(x)\) with Emukit.predicted_y = []
+real_y = np.sin(real_x)ExperimentalDesignLoop: learning function \(\sin(x)\) with Emukit.
-predicted_y = []
predicted_std = []
for x in real_x:
y, var = emukit_model.predict(np.array([[x]]))
@@ -895,65 +82,18 @@ Emukit Tutorial
predicted_std.append(std)
predicted_y = np.array(predicted_y).flatten()
-predicted_std = np.array(predicted_std).flatten()
-
-
-
-
-
-
-
-
-
-ExperimentalDesignLoop.Exercise 3
-sklearn. You can see step by step instructions on how to do this in this notebook.Emukit Overview Summary
-Emukit Sensitivity Analysis
-
-
-
-import numpy as np
+predicted_std = np.array(predicted_std).flatten()ExperimentalDesignLoop.Exercise 3
sklearn. You can see step by step instructions on how to do this in this notebook.Emukit Overview Summary
Emukit Sensitivity Analysis
-import numpy as np
import matplotlib.pyplot as plt
from matplotlib import colors as mcolors
-from matplotlib import cm
-cmd = install_command('mlai')
-%system {cmd}
-cmd = install_command('GPy')
-%system {cmd}
-cmd = install_command('pyDOE')
-%system {cmd}
-cmd = install_command('EmuKit')
-%system {cmd}
-import mlai
-import mlai.plot as plotLocal Sensitivity Analysis
-cmd = install_command('mlai')%system {cmd}cmd = install_command('GPy')%system {cmd}cmd = install_command('pyDOE')%system {cmd}cmd = install_command('EmuKit')%system {cmd}import mlai
+import mlai.plot as plotLocal Sensitivity Analysis
Global Sensitivity Analysis
-Global Sensitivity Analysis
Hoeffding-Sobol Decomposition
-Hoeffding-Sobol Decomposition
Hoeffding-Sobol Decomposition
p(\mathbf{ x}_{\sim i}) = \int p(\mathbf{ x}) \text{d}x_i
\] Higher order terms in the decomposition represent interactions between inputs, \[
g_{i,j}(x_i, x_j) = \left\langle g(\mathbf{ x}) \right\rangle _{p(\mathbf{ x}_{\sim i,j})} - g_i(x_i) - g_j(x_j) - g_0
-\] and similar expressions can be written for higher order terms up to \(g_{1,2,\dots,d}(\mathbf{ x})\).}Example: the Ishigami function
-Ishigami Function
-
-
-from emukit.test_functions.sensitivity import Ishigami
-ishigami = Ishigami(a=5, b=0.1)
-target_function = ishigami.fidelity1
-import numpy as np
-from emukit.core import ContinuousParameter, ParameterSpacevariable_domain = (-np.pi,np.pi)
+\] where the \(\ell\) represents the relevent set of indices for the different combinations of inputs.Example: the Ishigami function
Ishigami Function
from emukit.test_functions.sensitivity import Ishigamiishigami = Ishigami(a=5, b=0.1)
+target_function = ishigami.fidelity1import numpy as np
+from emukit.core import ContinuousParameter, ParameterSpace
-variable_domain = (-np.pi,np.pi)
space = ParameterSpace(
[ContinuousParameter('x1', *variable_domain),
ContinuousParameter('x2', *variable_domain),
- ContinuousParameter('x3', *variable_domain)])x_grid = np.linspace(*variable_domain,100)
+\]
-x_grid = np.linspace(*variable_domain,100)
target_simulator = ishigami.fidelity1
f1 = ishigami.f1(x_grid)
f2 = ishigami.f2(x_grid)
-F13 = ishigami.f13(np.array([x_grid,x_grid]).T)[:,np.newaxis]
-
-
-
-
-
-
-
-
-
-Total Variance
-
-print(ishigami.variance_total)
-print(ishigami.variance_x1, ishigami.variance_x2, ishigami.variance_x13)
-print(ishigami.variance_x1 + ishigami.variance_x2 + ishigami.variance_x13)First Order Sobol Indices using Monte Carlo
-Total Variance
print(ishigami.variance_total)print(ishigami.variance_x1, ishigami.variance_x2, ishigami.variance_x13)
+print(ishigami.variance_x1 + ishigami.variance_x2 + ishigami.variance_x13)First Order Sobol Indices using Monte Carlo
EmuKit you can extract these values with the code.
-ishigami.main_effects
-from emukit.sensitivity.monte_carlo import ModelFreeMonteCarloSensitivitynp.random.seed(10) # for reproducibility
+\] This value is standardized using the total variance, so it is possible to account for a fractional contribution of each variable to the total variance of the output.EmuKit you can extract these values with the code.ishigami.main_effectsfrom emukit.sensitivity.monte_carlo import ModelFreeMonteCarloSensitivity
-np.random.seed(10) # for reproducibility
num_monte_carlo_points = 10000 # Number of MC samples
senstivity_ishigami = ModelFreeMonteCarloSensitivity(target_simulator, space)
main_effects, total_effects, _ = senstivity_ishigami.compute_effects(num_monte_carlo_points = num_monte_carlo_points)
-print(main_effects)
-
-
-
-
-
-
-
-
-
-Total Effects Using Monte Carlo
-Total Effects Using Monte Carlo
-ishigami.total_effects
-
-
-
-
-
-
-
-
-
-Computing the Sensitivity Indices Using the Output of a Model
-
-from emukit.core.initial_designs import RandomDesigndesign = RandomDesign(space)
+\]ishigami.total_effectsComputing the Sensitivity Indices Using the Output of a Model
from emukit.core.initial_designs import RandomDesign
-design = RandomDesign(space)
x = design.get_samples(500)
-y = ishigami.fidelity1(x)[:,np.newaxis]from GPy.models import GPRegression
+y = ishigami.fidelity1(x)[:,np.newaxis]
-from GPy.models import GPRegression
from emukit.model_wrappers import GPyModelWrapper
-from emukit.sensitivity.monte_carlo import MonteCarloSensitivitymodel_gpy = GPRegression(x,y)
+from emukit.sensitivity.monte_carlo import MonteCarloSensitivity
-model_gpy = GPRegression(x,y)
model_emukit = GPyModelWrapper(model_gpy)
-model_emukit.optimize()ModelBasedMonteCarloSensitivity which directly calls the model and uses its predictive mean to compute the Monte Carlo estimates of the Sobol indices. We plot the true estimates, those computed using 10000 direct evaluations of the object using Monte Carlo and those computed using a Gaussian process model trained on 100 evaluations.num_mc = 10000
+model_emukit.optimize()ModelBasedMonteCarloSensitivity which directly calls the model and uses its predictive mean to compute the Monte Carlo estimates of the Sobol indices. We plot the true estimates, those computed using 10000 direct evaluations of the object using Monte Carlo and those computed using a Gaussian process model trained on 100 evaluations.
-num_mc = 10000
senstivity_ishigami_gpbased = MonteCarloSensitivity(model = model_emukit, input_domain = space)
-main_effects_gp, total_effects_gp, _ = senstivity_ishigami_gpbased.compute_effects(num_monte_carlo_points = num_mc)
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Conclusions
-Catapult Simulation
-
-
-
-
-
-
-
- -
-
-
-
-
-
roation_axis, the position of the arm stop, arm_stop, and the location of the two bindings of the catapult’s spring, spring_binding_1 and spring_binding_2.Conclusions
Catapult Simulation

roation_axis, the position of the arm stop, arm_stop, and the location of the two bindings of the catapult’s spring, spring_binding_1 and spring_binding_2.
-from emukit.core import ContinuousParameter, ParameterSpacevariable_domain = [0,1]
+\]from emukit.core import ContinuousParameter, ParameterSpace
-variable_domain = [0,1]
space = ParameterSpace(
[ContinuousParameter('rotation_axis', *variable_domain),
ContinuousParameter('arm_stop', *variable_domain),
ContinuousParameter('spring_binding_1', *variable_domain),
- ContinuousParameter('spring_binding_2', *variable_domain)])Experimental Design for the Catapult
-
-
-from emukit.core.initial_designs import RandomDesigndesign = RandomDesign(space)
+ ContinuousParameter('spring_binding_2', *variable_domain)])Experimental Design for the Catapult
from emukit.core.initial_designs import RandomDesign
-design = RandomDesign(space)
x = design.get_samples(5)
-y = catapult_distance(x)from GPy.models import GPRegression
+y = catapult_distance(x)
-from GPy.models import GPRegression
from emukit.model_wrappers import GPyModelWrapper
-from emukit.sensitivity.monte_carlo import MonteCarloSensitivitymodel_gpy = GPRegression(x,y)
+from emukit.sensitivity.monte_carlo import MonteCarloSensitivity
-model_gpy = GPRegression(x,y)
model_gpy.kern.variance = 150**2
model_gpy.likelihood.variance.fix(1e-5)
-display(model_gpy)
-model_emukit = GPyModelWrapper(model_gpy)
-model_emukit.optimize()
-display(model_gpy)colab than on a local machine.
-from emukit.experimental_design.experimental_design_loop import ExperimentalDesignLoop
-from emukit.experimental_design.acquisitions import IntegratedVarianceReduction, ModelVarianceintegrated_variance = IntegratedVarianceReduction(space=space,
+display(model_gpy)model_emukit = GPyModelWrapper(model_gpy)
+model_emukit.optimize()display(model_gpy)colab than on a local machine.from emukit.experimental_design.experimental_design_loop import ExperimentalDesignLoopfrom emukit.experimental_design.acquisitions import IntegratedVarianceReduction, ModelVariance
-integrated_variance = IntegratedVarianceReduction(space=space,
model=model_emukit)
ed = ExperimentalDesignLoop(space=space,
model=model_emukit,
acquisition = integrated_variance)
-ed.run_loop(catapult_distance, 10)Sensitivity Analysis of a Catapult Simulation
-ModelBasedMonteCarloSensitivity which directly calls the model and uses its predictive mean to compute the Monte Carlo estimates of the Sobol indices. We plot the estimates of the Sobol indices computed using a Gaussian process model trained on the observations we’ve acquired.num_mc = 10000
+ed.run_loop(catapult_distance, 10)Sensitivity Analysis of a Catapult Simulation
ModelBasedMonteCarloSensitivity which directly calls the model and uses its predictive mean to compute the Monte Carlo estimates of the Sobol indices. We plot the estimates of the Sobol indices computed using a Gaussian process model trained on the observations we’ve acquired.
-num_mc = 10000
senstivity = MonteCarloSensitivity(model = model_emukit, input_domain = space)
-main_effects_gp, total_effects_gp, _ = senstivity.compute_effects(num_monte_carlo_points = num_mc)
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-
-Thanks!
-
-
-References
-
-
+main_effects_gp, total_effects_gp, _ = senstivity.compute_effects(num_monte_carlo_points = num_mc)
-Borchert, T., 2020. Milan: An evolution of data-oriented programming.
-
-
-Cabrera, C., Paleyes, A., Thodoroff, P., Lawrence, N.D., 2023. Real-world machine learning systems: A survey from a data-oriented architecture perspective.
-
-
-Durrande, N., Ginsbourger, D., Olivier, Carraro, L., 2013. ANOVA kernels and RKHS of zero mean functions for model-based sensitivity analysis. Journal of Multivariate Analysis 115, 57–67. https://doi.org/https://doi.org/10.1016/j.jmva.2012.08.016
-
-
-Ishigami, T., Homma, T., 1989. An importance quantification technique in uncertainty analysis for computer models. [1990] Proceedings. First International Symposium on Uncertainty Modeling and Analysis 398–403.
-
-
-Joshi, R., 2007. A loosely-coupled real-time SOA. Real-Time Innovations Inc.
-
-
-Kennedy, M.C., O’Hagan, A., 2001. Bayesian calibration of computer models. Journal of the Royal Statistical Society: Series B (Statistical Methodology) 63, 425–464. https://doi.org/10.1111/1467-9868.00294
-
-
-Kennedy, M.C., O’Hagan, A., 2000. Predicting the output from a complex computer code when fast approximations are available. Biometrika 87, 1–13.
-
-
-Laplace, P.S., 1814. Essai philosophique sur les probabilités, 2nd ed. Courcier, Paris.
-
-
-Lawrence, N.D., 2019. Modern data oriented programming.
-
-
-Lawrence, N.D., 2017. Data readiness levels. ArXiv.
-
-
-Lawrence, N.D., Montgomery, J., Paquet, U., 2020. Organisational data maturity. The Royal Society.
-
-
-Marrel, A., Iooss, B., Laurent, B., Roustant, O., 2009. Calculations of Sobol indices for the Gaussian process metamodel. Reliability Engineering & System Safety 94, 742–751. https://doi.org/https://doi.org/10.1016/j.ress.2008.07.008
-
-
-McKay, M.D., Beckman, R.J., Conover, W.J., 1979. A comparison of three methods for selecting values of input variables in the analysis of output from a computer code. Technometrics 21, 239–245.
-
-
-Paleyes, A., Cabrera, C., Lawrence, N.D., 2022a. An empirical evaluation of flow based programming in the machine learning deployment context, in: 1st International Conference on AI Engineering – Software Engineering for AI.
-
-
-Paleyes, A., Pullin, M., Mahsereci, M., McCollum, C., Lawrence, N.D., Gonzalez, J., 2019. Emulation of physical processes with emukit, in: Second Workshop on Machine Learning and the Physical Sciences, NeuRIPS 2019.
-
-
-Paleyes, A., Urma, R.-G., Lawrence, N.D., 2022b. Challenges in machine learning deployment: A survey of case studies. ACM Comput. Surv.
-
-
-Saltelli, A., Annoni, P., Azzini, I., Campolongo, F., Ratto, M., Tarantola, S., 2010. Variance based sensitivity analysis of model output. Design and estimator for the total sensitivity index. Computer Physics Communications 181, 259–270. https://doi.org/10.1016/j.cpc.2009.09.018
-
-
-Saltelli, A., Ratto, M., Andres, T., Campolongo, F., Cariboni, J., Gatelli, D., Saisana, M., Tarantola, S., 2008. Global sensitivity analysis: The primer. wiley.
-
-
-Saltelli, A., Tarantola, S., Campolongo, F., Ratto, M., 2004. Sensitivity analysis in practice: A guide to assessing scientific methods. wiley.
-
-
-Sobol, I.M., 2001. Global sensitivity indices for nonlinear mathematical models and their Monte Carlo estimates. Mathematics and Computers in Simulation 55, 271–280. https://doi.org/10.1016/S0378-4754(00)00270-6
-
-
-Sobol, I.M., 1990. On sensitivity estimation for nonlinear mathematical models. Matematicheskoe Modelirovanie 2, 112–118.
-
-
-Sobol, I.M., Levitan, Y.L., 1999. On the use of variance reducing multipliers in Monte Carlo computations of a global sensitivity index. Computer Physics Communications 117, 52–61. https://doi.org/10.1016/S0010-4655(98)00156-8
-
-
-The DELVE Initiative, 2020. Data readiness: Lessons from an emergency. The Royal Society.
-
-
-Vorhemus, C., Schikuta, E., 2017. A data-oriented architecture for loosely coupled real-time information systems, in: Proceedings of the 19th International Conference on Information Integration and Web-Based Applications & Services, iiWAS ’17. Association for Computing Machinery, New York, NY, USA, pp. 472–481. https://doi.org/10.1145/3151759.3151770
-
-Thanks!
References
diff --git a/_notebooks/01-uncertainty-and-modelling.ipynb b/_notebooks/01-uncertainty-and-modelling.ipynb
index 2805753..a9a40ed 100644
--- a/_notebooks/01-uncertainty-and-modelling.ipynb
+++ b/_notebooks/01-uncertainty-and-modelling.ipynb
@@ -32,6 +32,8 @@
"metadata": {},
"source": [
"\n",
+ "\n",
+ "\n",
"\n",
"\n",
"\n",
@@ -44,7 +46,7 @@
"\n",
"-->\n",
"\n",
- "Borchert, T., 2020. Milan: An evolution of data-oriented programming.Cabrera, C., Paleyes, A., Thodoroff, P., Lawrence, N.D., 2023. Real-world machine learning systems: A survey from a data-oriented architecture perspective.Durrande, N., Ginsbourger, D., Olivier, Carraro, L., 2013. ANOVA kernels and RKHS of zero mean functions for model-based sensitivity analysis. Journal of Multivariate Analysis 115, 57–67. https://doi.org/https://doi.org/10.1016/j.jmva.2012.08.016Ishigami, T., Homma, T., 1989. An importance quantification technique in uncertainty analysis for computer models. [1990] Proceedings. First International Symposium on Uncertainty Modeling and Analysis 398–403.Joshi, R., 2007. A loosely-coupled real-time SOA. Real-Time Innovations Inc.Kennedy, M.C., O’Hagan, A., 2001. Bayesian calibration of computer models. Journal of the Royal Statistical Society: Series B (Statistical Methodology) 63, 425–464. https://doi.org/10.1111/1467-9868.00294Kennedy, M.C., O’Hagan, A., 2000. Predicting the output from a complex computer code when fast approximations are available. Biometrika 87, 1–13.Laplace, P.S., 1814. Essai philosophique sur les probabilités, 2nd ed. Courcier, Paris.Lawrence, N.D., 2019. Modern data oriented programming.Lawrence, N.D., 2017. Data readiness levels. ArXiv.Lawrence, N.D., Montgomery, J., Paquet, U., 2020. Organisational data maturity. The Royal Society.Marrel, A., Iooss, B., Laurent, B., Roustant, O., 2009. Calculations of Sobol indices for the Gaussian process metamodel. Reliability Engineering & System Safety 94, 742–751. https://doi.org/https://doi.org/10.1016/j.ress.2008.07.008McKay, M.D., Beckman, R.J., Conover, W.J., 1979. A comparison of three methods for selecting values of input variables in the analysis of output from a computer code. Technometrics 21, 239–245.Paleyes, A., Cabrera, C., Lawrence, N.D., 2022a. An empirical evaluation of flow based programming in the machine learning deployment context, in: 1st International Conference on AI Engineering – Software Engineering for AI.Paleyes, A., Pullin, M., Mahsereci, M., McCollum, C., Lawrence, N.D., Gonzalez, J., 2019. Emulation of physical processes with emukit, in: Second Workshop on Machine Learning and the Physical Sciences, NeuRIPS 2019.Paleyes, A., Urma, R.-G., Lawrence, N.D., 2022b. Challenges in machine learning deployment: A survey of case studies. ACM Comput. Surv.Saltelli, A., Annoni, P., Azzini, I., Campolongo, F., Ratto, M., Tarantola, S., 2010. Variance based sensitivity analysis of model output. Design and estimator for the total sensitivity index. Computer Physics Communications 181, 259–270. https://doi.org/10.1016/j.cpc.2009.09.018Saltelli, A., Ratto, M., Andres, T., Campolongo, F., Cariboni, J., Gatelli, D., Saisana, M., Tarantola, S., 2008. Global sensitivity analysis: The primer. wiley.Saltelli, A., Tarantola, S., Campolongo, F., Ratto, M., 2004. Sensitivity analysis in practice: A guide to assessing scientific methods. wiley.Sobol, I.M., 2001. Global sensitivity indices for nonlinear mathematical models and their Monte Carlo estimates. Mathematics and Computers in Simulation 55, 271–280. https://doi.org/10.1016/S0378-4754(00)00270-6Sobol, I.M., 1990. On sensitivity estimation for nonlinear mathematical models. Matematicheskoe Modelirovanie 2, 112–118.Sobol, I.M., Levitan, Y.L., 1999. On the use of variance reducing multipliers in Monte Carlo computations of a global sensitivity index. Computer Physics Communications 117, 52–61. https://doi.org/10.1016/S0010-4655(98)00156-8The DELVE Initiative, 2020. Data readiness: Lessons from an emergency. The Royal Society.Vorhemus, C., Schikuta, E., 2017. A data-oriented architecture for loosely coupled real-time information systems, in: Proceedings of the 19th International Conference on Information Integration and Web-Based Applications & Services, iiWAS ’17. Association for Computing Machinery, New York, NY, USA, pp. 472–481. https://doi.org/10.1145/3151759.3151770 \n",
+ "
 \n",
"\n",
"Figure: A key reference for Gaussian process models remains the\n",
"excellent book “Gaussian Processes for Machine Learning” (Rasmussen and\n",
@@ -282,7 +284,7 @@
"to use interface to GPs. One which allowed the user to focus on the\n",
"modelling rather than the mathematics.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: GPy is a BSD licensed software code base for implementing\n",
"Gaussian process models in Python. It is designed for teaching and\n",
@@ -322,7 +324,7 @@
"- Present results using pace per km.\n",
"- In 1904 Marathon was badly organized leading to very slow times.\n",
"\n",
- "
 \n",
+ "
 \n",
"Image from [Wikimedia\n",
"Commons](https://commons.wikimedia.org/wiki/File:Eliud_Kipchoge_in_Berlin_-_2015_(cropped).jpg)\n",
"\n",
@@ -410,7 +412,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Olympic marathon pace times since 1896.\n",
"\n",
@@ -447,7 +449,7 @@
"The solution to these two simultaneous equations can be represented\n",
"graphically as\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: The solution of two linear equations represented as the fit\n",
"of a straight line through two data\n",
@@ -459,14 +461,14 @@
"2.5 = 2m + c\n",
"$$\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: A third observation of data is inconsistent with the solution\n",
"dictated by the first two observations\n",
"\n",
"Now there are three candidate lines, each consistent with our data.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Three solutions to the problem, each consistent with two\n",
"points of the three observations\n",
@@ -542,7 +544,7 @@
"class=\"editsection\"\n",
"style=\"\">edit\\]\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Pierre-Simon Laplace 1749-1827."
]
@@ -591,7 +593,7 @@
"\n",
"This notion is known as *Laplace’s demon* or *Laplace’s superman*.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Laplace’s determinsim in English translation."
]
@@ -631,7 +633,7 @@
"source": [
"Figure: Laplace’s gremlin in the original French.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: To Laplace, determinism is a strawman. Ignorance of mechanism\n",
"and data leads to uncertainty which should be dealt with through\n",
@@ -745,7 +747,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: The Gaussian PDF with ${\\mu}=1.7$ and variance\n",
"${\\sigma}^2=0.0225$. Mean shown as red line. It could represent the\n",
@@ -933,7 +935,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: An underdetermined system can be fit by considering\n",
"uncertainty. Multiple solutions are consistent with one specified\n",
@@ -1087,7 +1089,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Combining a Gaussian likelihood with a Gaussian prior to form\n",
"a Gaussian posterior\n",
diff --git a/_notebooks/02-gaussian-distributions-to-processes.ipynb b/_notebooks/02-gaussian-distributions-to-processes.ipynb
index d3f6c7d..d2976ca 100644
--- a/_notebooks/02-gaussian-distributions-to-processes.ipynb
+++ b/_notebooks/02-gaussian-distributions-to-processes.ipynb
@@ -5,8 +5,7 @@
"metadata": {},
"source": [
"# Gaussian Distributions to Processes"
- ],
- "id": "f1a5e2cf-e71e-409d-b8a9-39ce788a416f"
+ ]
},
{
"cell_type": "markdown",
@@ -15,8 +14,7 @@
"**Abstract**: In this sesson we go from the Gaussian distribution to the\n",
"Gaussian process and in doing so we move from a finite system to an\n",
"infinite system."
- ],
- "id": "186cffab-da37-4974-83c2-5ed857a91233"
+ ]
},
{
"cell_type": "markdown",
@@ -24,14 +22,15 @@
"source": [
"$$\n",
"$$"
- ],
- "id": "d9a937ba-ccb8-43eb-b2e3-0dc96a33b5e6"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"\n",
+ "\n",
+ "\n",
"\n",
"\n",
"\n",
@@ -43,8 +42,7 @@
""
- ],
- "id": "fde19928-cd99-4119-a942-a370de1c3552"
+ ]
},
{
"cell_type": "markdown",
@@ -52,14 +50,13 @@
"source": [
"## Gaussian Process Summer School notebook setup\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: GPy is a BSD licensed software code base for implementing\n",
"Gaussian process models in Python. It is designed for teaching and\n",
@@ -250,8 +235,7 @@
"\n",
"The documentation for GPy can be found\n",
"[here](https://gpy.readthedocs.io/en/latest/)."
- ],
- "id": "ae2a2cd2-a387-443b-9267-9ee52d9f9871"
+ ]
},
{
"cell_type": "markdown",
@@ -259,8 +243,8 @@
"source": [
"## Two Dimensional Gaussian\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian distributions for height and weight."
- ],
- "id": "1d911b95-ff36-4cbb-b7f5-d8bcd1f224f0"
+ ]
},
{
"cell_type": "markdown",
@@ -320,8 +300,7 @@
" p(w, h) = p(w)p(h).\n",
" $$ Given this assumption we can sample from the joint distribution by\n",
"independently sampling weights and heights."
- ],
- "id": "f46d3dde-aea8-41b0-8b7a-407f2f31d825"
+ ]
},
{
"cell_type": "code",
@@ -330,8 +309,7 @@
"outputs": [],
"source": [
"import mlai.plot as plot"
- ],
- "id": "3ece6e25-89cf-4723-95fb-3a59bdd071de"
+ ]
},
{
"cell_type": "code",
@@ -345,8 +323,7 @@
" xlabel='$h/m$', ylabel='$w/kg$',\n",
" filestub=\"independent_height_weight\",\n",
" diagrams='./ml')"
- ],
- "id": "aa504e42-b5fd-4183-8782-525b4ec2ef73"
+ ]
},
{
"cell_type": "code",
@@ -356,18 +333,17 @@
"source": [
"import notutils as nu\n",
"from ipywidgets import IntSlider"
- ],
- "id": "30d4cd89-5ff4-473b-a562-f9ec1d581b11"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
" \n",
- "displaycode{nu.display_plots(‘independent_height_weight{fig:0\\>3}.svg’,\n",
- "directory=‘./ml’, fig=IntSlider(0, 0, 7, 1))}\n",
+ "displaycode{nu.display_plots(‘independent_height_weight{fig:0\\>3}.svg,’\n",
+ "directory=‘./ml,’ fig=IntSlider(0, 0, 7, 1))}\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Samples from independent Gaussian variables that might\n",
"represent heights and weights.\n",
@@ -381,8 +357,7 @@
"\\text{BMI} = \\frac{w}{h^2}\n",
"$$To deal with this dependence we now introduce the notion of\n",
"*correlation* to the multivariate Gaussian density."
- ],
- "id": "1345164c-d8a9-44f2-88d1-b87b90cca6d1"
+ ]
},
{
"cell_type": "markdown",
@@ -390,11 +365,10 @@
"source": [
"## Sampling Two Dimensional Variables\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Samples from *correlated* Gaussian variables that might\n",
"represent heights and weights."
- ],
- "id": "ba9d50df-d259-431d-ab16-a646a9b48344"
+ ]
},
{
"cell_type": "markdown",
@@ -461,8 +430,8 @@
"source": [
"## Independent Gaussians\n",
"\n",
- "\\[\\[
 \n",
- "
 \n",
- "
 \n",
+ "
 \n",
+ "
 \n",
+ "
 \n",
"\n",
"Figure: One view of Bayesian inference is we have a machine for\n",
"generating samples (the *prior*), and we discard all samples\n",
@@ -795,8 +748,7 @@
"*posterior*). This is a rejection sampling view of Bayesian inference.\n",
"The Gaussian process allows us to do this analytically by multiplying\n",
"the *prior* by the *likelihood*."
- ],
- "id": "e9bf12d2-fe92-4f52-953f-e11b6c78ffdf"
+ ]
},
{
"cell_type": "markdown",
@@ -804,8 +756,8 @@
"source": [
"## Sampling a Function\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: The joint Gaussian over $f_1$ and $f_2$ along with the\n",
"conditional distribution of $f_2$ given $f_1$"
- ],
- "id": "2ddd4aa4-dc9b-43ce-a052-c7a042b6fad5"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"### Joint Density of $f_1$ and $f_2$"
- ],
- "id": "49b321f6-dbad-4f20-8fed-dfd936d1fd38"
+ ]
},
{
"cell_type": "code",
@@ -985,8 +921,7 @@
"source": [
"import notutils as nu\n",
"from ipywidgets import IntSlider"
- ],
- "id": "de10b509-4871-46a7-995f-9655215b062b"
+ ]
},
{
"cell_type": "code",
@@ -995,8 +930,7 @@
"outputs": [],
"source": [
"import notutils as nu"
- ],
- "id": "087ad74a-f787-4be7-968b-36d866b1def7"
+ ]
},
{
"cell_type": "code",
@@ -1007,19 +941,17 @@
"nu.display_plots('two_point_sample{sample:0>3}.svg', \n",
" './gp', \n",
" sample=IntSlider(9, 9, 12, 1))"
- ],
- "id": "363ac359-2702-4e33-9fcf-0b56335d2a90"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: The joint Gaussian over $f_1$ and $f_2$ along with the\n",
"conditional distribution of $f_2$ given $f_1$"
- ],
- "id": "6433bd79-7fb3-4626-86ce-fc82951f8ff5"
+ ]
},
{
"cell_type": "markdown",
@@ -1027,7 +959,7 @@
"source": [
"## Uluru\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Uluru, the sacred rock in Australia. If we think of it as a\n",
"probability density, viewing it from this side gives us one *marginal*\n",
@@ -1048,8 +980,7 @@
"point). This would give a profile of the rock, which when renormalized,\n",
"would give us the conditional distribution, the value of conditioning\n",
"would be the location of the slice in the direction we are facing."
- ],
- "id": "8d3aee9f-93d7-4e7e-8517-363fcfac6339"
+ ]
},
{
"cell_type": "markdown",
@@ -1075,8 +1006,7 @@
"the elements of our vector $\\mathbf{ f}$. For example, the variable\n",
"$f_8$ is less correlated with $f_1$ than $f_2$. If we consider this\n",
"variable we see the conditional density is more diffuse."
- ],
- "id": "7a4cedc1-beed-4837-90b2-787b7ceb63c5"
+ ]
},
{
"cell_type": "markdown",
@@ -1084,11 +1014,10 @@
"source": [
"### Joint Density of $f_1$ and $f_8$\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Sample from the joint Gaussian model, points indexed by 1 and\n",
"8 highlighted."
- ],
- "id": "0f43ae1f-1d82-4106-9a76-0790dd9da5f0"
+ ]
},
{
"cell_type": "markdown",
@@ -1140,7 +1065,7 @@
"source": [
"### Prediction of $f_{8}$ from $f_{1}$\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: The joint Gaussian over $f_1$ and $f_8$ along with the\n",
"conditional distribution of $f_8$ given $f_1$\n",
@@ -1179,8 +1104,7 @@
"- Here covariance of joint density is given by $$\n",
" \\mathbf{K}= \\begin{bmatrix} \\mathbf{K}_{\\mathbf{ f}, \\mathbf{ f}} & \\mathbf{K}_{*, \\mathbf{ f}}\\\\ \\mathbf{K}_{\\mathbf{ f}, *} & \\mathbf{K}_{*, *}\\end{bmatrix}\n",
" $$"
- ],
- "id": "8b3f9b3e-8378-4126-a58c-7b75c9380dc4"
+ ]
},
{
"cell_type": "markdown",
@@ -1188,14 +1112,13 @@
"source": [
"## Where Did This Covariance Matrix Come From?\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Entrywise fill in of the covariance matrix from the\n",
"covariance function."
- ],
- "id": "09cc2dde-f3d7-461b-83e6-feca4a62a3db"
+ ]
},
{
"cell_type": "code",
@@ -1321,8 +1234,7 @@
"import numpy as np\n",
"from mlai import Kernel\n",
"import mlai.plot as plot"
- ],
- "id": "d0a3d970-b19c-47ba-a5e2-02337886fdc9"
+ ]
},
{
"cell_type": "code",
@@ -1336,8 +1248,7 @@
" formula=formula,\n",
" stub='eq_four',\n",
" diagrams='./kern')"
- ],
- "id": "671b41b7-2395-46e6-bc5d-d9ff0c3a0234"
+ ]
},
{
"cell_type": "code",
@@ -1347,8 +1258,7 @@
"source": [
"import notutils as nu\n",
"from ipywidgets import IntSlider"
- ],
- "id": "9758948f-15a7-42fb-a2c6-300b1f83aab2"
+ ]
},
{
"cell_type": "code",
@@ -1357,8 +1267,7 @@
"outputs": [],
"source": [
"import notutils as nu"
- ],
- "id": "caea62c7-d5c8-4a1e-86b2-3d2f9857e156"
+ ]
},
{
"cell_type": "code",
@@ -1369,19 +1278,17 @@
"nu.display_plots('computing_eq_four_covariance{sample:0>3}.svg', \n",
" directory='./kern', \n",
" sample=IntSlider(0, 0, 27, 1))"
- ],
- "id": "d95c8477-a758-4ecb-92a3-ace69f68fb0e"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Entrywise fill in of the covariance matrix from the\n",
"covariance function."
- ],
- "id": "7f7413dd-c571-4a6c-ba93-e58f5d280b2f"
+ ]
},
{
"cell_type": "code",
@@ -1392,8 +1299,7 @@
"import numpy as np\n",
"from mlai import Kernel\n",
"import mlai.plot as plot"
- ],
- "id": "ebc8a90f-262c-49bb-bf90-0ee4f375b3f5"
+ ]
},
{
"cell_type": "code",
@@ -1407,8 +1313,7 @@
" formula=formula,\n",
" stub='eq_three_2',\n",
" diagrams='./kern')"
- ],
- "id": "f79b79df-3e33-4aa8-8c74-370ca369f622"
+ ]
},
{
"cell_type": "code",
@@ -1418,8 +1323,7 @@
"source": [
"import notutils as nu\n",
"from ipywidgets import IntSlider"
- ],
- "id": "edb0b16f-e87d-41be-99c3-207cfbe7a98d"
+ ]
},
{
"cell_type": "code",
@@ -1428,8 +1332,7 @@
"outputs": [],
"source": [
"import notutils as nu"
- ],
- "id": "e0798274-9387-46e7-a07e-ce7062adcfd3"
+ ]
},
{
"cell_type": "code",
@@ -1440,19 +1343,17 @@
"nu.display_plots('computing_eq_three_2_covariance{sample:0>3}.svg', \n",
" directory='./kern', \n",
" sample=IntSlider(0, 0, 16, 1))"
- ],
- "id": "7ceb3485-89ab-4f50-b0a1-e2093d178084"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Entrywise fill in of the covariance matrix from the\n",
"covariance function."
- ],
- "id": "47e73b31-d620-4cd6-a3ff-c062384d91bd"
+ ]
},
{
"cell_type": "markdown",
@@ -1460,11 +1361,10 @@
"source": [
"## Polynomial Covariance\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Polynomial covariance function."
- ],
- "id": "8d142d92-6292-4d94-952a-71fedddad125"
+ ]
},
{
"cell_type": "markdown",
@@ -1540,8 +1435,8 @@
"source": [
"## Degenerate Covariance Functions\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: A covariance function based on a non-linear basis given by\n",
"$\\boldsymbol{ \\phi}(\\mathbf{ x})$.\n",
@@ -1742,8 +1628,7 @@
"process with the exponentiated quadratic covariance function\n",
"$$k\\left(x_i,x_j\\right) = \\alpha \\exp\\left(\n",
" -\\frac{\\left(x_i-x_j\\right)^2}{4\\ell^2}\\right).$$"
- ],
- "id": "1cb13c4e-eabd-4e1f-a8c3-2ce81ff7c34d"
+ ]
},
{
"cell_type": "markdown",
@@ -1763,8 +1648,7 @@
" Page](http://www.theguardian.com/profile/neil-lawrence)\n",
"- blog:\n",
" [http://inverseprobability.com](http://inverseprobability.com/blog.html)"
- ],
- "id": "60e1f8a6-79b1-46a8-ba09-b0263e415182"
+ ]
},
{
"cell_type": "markdown",
@@ -1772,30 +1656,26 @@
"source": [
"## References\n",
"\n",
- "Cho, Y., Saul, L.K., 2009. [Kernel methods for deep\n",
- "learning](http://papers.nips.cc/paper/3628-kernel-methods-for-deep-learning.pdf),\n",
- "in: Bengio, Y., Schuurmans, D., Lafferty, J.D., Williams, C.K.I.,\n",
- "Culotta, A. (Eds.), Advances in Neural Information Processing Systems\n",
- "22. Curran Associates, Inc., pp. 342–350.\n",
+ "Cho, Y., Saul, L.K., 2009. Kernel methods for deep learning, in: Bengio,\n",
+ "Y., Schuurmans, D., Lafferty, J.D., Williams, C.K.I., Culotta, A.\n",
+ "(Eds.), Advances in Neural Information Processing Systems 22. Curran\n",
+ "Associates, Inc., pp. 342–350.\n",
"\n",
- "Ioffe, S., Szegedy, C., 2015. [Batch normalization: Accelerating deep\n",
- "network training by reducing internal covariate\n",
- "shift](http://proceedings.mlr.press/v37/ioffe15.html), in: Bach, F.,\n",
+ "Ioffe, S., Szegedy, C., 2015. Batch normalization: Accelerating deep\n",
+ "network training by reducing internal covariate shift, in: Bach, F.,\n",
"Blei, D. (Eds.), Proceedings of the 32nd International Conference on\n",
"Machine Learning, Proceedings of Machine Learning Research. PMLR, Lille,\n",
"France, pp. 448–456.\n",
"\n",
- "Neal, R.M., 1994. [Bayesian learning for neural\n",
- "networks](http://citeseerx.ist.psu.edu/viewdoc/download?doi=10.1.1.446.9306&rep=rep1&type=pdf)\n",
- "(PhD thesis). University of Toronto, Canada.\n",
+ "Neal, R.M., 1994. Bayesian learning for neural networks (PhD thesis).\n",
+ "University of Toronto, Canada.\n",
"\n",
"Tipping, M.E., Bishop, C.M., 1999. Probabilistic principal component\n",
"analysis. Journal of the Royal Statistical Society, B 6, 611–622.\n",
"\n",
+ "\n",
"\n",
"Figure: GPy is a BSD licensed software code base for implementing\n",
"Gaussian process models in Python. It is designed for teaching and\n",
@@ -252,8 +237,7 @@
"\n",
"The documentation for GPy can be found\n",
"[here](https://gpy.readthedocs.io/en/latest/)."
- ],
- "id": "1226baa8-18b0-45c3-8b73-8c5c2a9fbc67"
+ ]
},
{
"cell_type": "markdown",
@@ -261,8 +245,8 @@
"source": [
"## The Importance of the Covariance Function\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"$\\boldsymbol{ \\Lambda}$ represents distance on axes. $\\mathbf{R}$ gives\n",
"rotation.\n",
@@ -517,8 +486,7 @@
" $\\mathbf{R}^\\top\\mathbf{R}= \\mathbf{I}$.\n",
"- Useful representation since\n",
" $\\det{\\mathbf{K}} = \\det{\\boldsymbol{ \\Lambda}^2} = \\det{\\boldsymbol{ \\Lambda}}^2$."
- ],
- "id": "17206c18-a30c-48b7-b371-18ecfd488068"
+ ]
},
{
"cell_type": "code",
@@ -530,8 +498,7 @@
"import numpy as np\n",
"import mlai\n",
"import mlai.plot as plot"
- ],
- "id": "35c63e78-dccf-4914-847b-d98d855d6b54"
+ ]
},
{
"cell_type": "code",
@@ -540,8 +507,7 @@
"outputs": [],
"source": [
"plot.covariance_capacity(rotate_angle=np.pi/4, lambda1 = 0.5, lambda2 = 0.3, diagrams = './gp/')"
- ],
- "id": "abf596c3-eab8-43e5-bb74-cfe82d36939d"
+ ]
},
{
"cell_type": "code",
@@ -551,8 +517,7 @@
"source": [
"import notutils as nu\n",
"from ipywidgets import IntSlider"
- ],
- "id": "40ee5f3b-93ed-48f2-bbf2-630c92b39213"
+ ]
},
{
"cell_type": "code",
@@ -563,19 +528,17 @@
"nu.display_plots('gp-optimise-determinant{sample:0>3}.svg', \n",
" directory='./gp', \n",
" sample=IntSlider(0, 0, 9, 1))"
- ],
- "id": "2c3454eb-8e85-40b8-9705-a867eb11ba7c"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: The determinant of the covariance is dependent only on the\n",
"eigenvalues. It represents the ‘footprint’ of the Gaussian."
- ],
- "id": "ca7fd269-e05f-4e83-8bba-cc0efbeb1f27"
+ ]
},
{
"cell_type": "markdown",
@@ -583,11 +546,10 @@
"source": [
"## Quadratic Data Fit\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: The data fit term of the Gaussian process is a quadratic loss\n",
"centered around zero. This has eliptical contours, the principal axes of\n",
"which are given by the covariance matrix."
- ],
- "id": "62aa5f88-ab77-4254-9f5d-35a4eded231b"
+ ]
},
{
"cell_type": "markdown",
@@ -657,11 +614,10 @@
"source": [
"## Data Fit Term\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Variation in the data fit term, the capacity term and the\n",
"negative log likelihood for different lengthscales."
- ],
- "id": "750c036f-7d10-4158-9149-3a0946d654e1"
+ ]
},
{
"cell_type": "markdown",
@@ -874,11 +819,10 @@
"source": [
"## Exponentiated Quadratic Covariance\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: The exponentiated quadratic covariance function."
- ],
- "id": "8983fd52-4392-4a59-9343-99a89bfbf662"
+ ]
},
{
"cell_type": "markdown",
@@ -996,14 +932,13 @@
"source": [
"## Where Did This Covariance Matrix Come From?\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: Entrywise fill in of the covariance matrix from the\n",
"covariance function."
- ],
- "id": "9204a57b-b6b4-4d6b-989a-c79421b3d259"
+ ]
},
{
"cell_type": "code",
@@ -1129,8 +1054,7 @@
"import numpy as np\n",
"from mlai import Kernel\n",
"import mlai.plot as plot"
- ],
- "id": "e5ee859e-6ec3-4333-bc8d-af6238547a6d"
+ ]
},
{
"cell_type": "code",
@@ -1144,8 +1068,7 @@
" formula=formula,\n",
" stub='eq_four',\n",
" diagrams='./kern')"
- ],
- "id": "a3a7bb6d-a377-41d0-9c6e-57d82f6d97fc"
+ ]
},
{
"cell_type": "code",
@@ -1155,8 +1078,7 @@
"source": [
"import notutils as nu\n",
"from ipywidgets import IntSlider"
- ],
- "id": "6a130515-1400-4503-b26f-c7023b905bb1"
+ ]
},
{
"cell_type": "code",
@@ -1165,8 +1087,7 @@
"outputs": [],
"source": [
"import notutils as nu"
- ],
- "id": "efa197c4-2aae-40f7-8e78-0e0be015b5cd"
+ ]
},
{
"cell_type": "code",
@@ -1177,19 +1098,17 @@
"nu.display_plots('computing_eq_four_covariance{sample:0>3}.svg', \n",
" directory='./kern', \n",
" sample=IntSlider(0, 0, 27, 1))"
- ],
- "id": "5affda88-bcc2-416b-9ba7-d4a7380a6ee6"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Entrywise fill in of the covariance matrix from the\n",
"covariance function."
- ],
- "id": "e6ffc0bb-991c-4983-9274-7d163d730503"
+ ]
},
{
"cell_type": "code",
@@ -1200,8 +1119,7 @@
"import numpy as np\n",
"from mlai import Kernel\n",
"import mlai.plot as plot"
- ],
- "id": "304e7473-c2c6-42b7-b8b4-49b133ec71e9"
+ ]
},
{
"cell_type": "code",
@@ -1215,8 +1133,7 @@
" formula=formula,\n",
" stub='eq_three_2',\n",
" diagrams='./kern')"
- ],
- "id": "24b1ae79-fa1f-4df4-b1b0-6524e41f4c08"
+ ]
},
{
"cell_type": "code",
@@ -1226,8 +1143,7 @@
"source": [
"import notutils as nu\n",
"from ipywidgets import IntSlider"
- ],
- "id": "7bfefbe3-710d-4c27-b22c-84bf213d45be"
+ ]
},
{
"cell_type": "code",
@@ -1236,8 +1152,7 @@
"outputs": [],
"source": [
"import notutils as nu"
- ],
- "id": "3862a0f5-c96c-48ca-885c-629e1378056b"
+ ]
},
{
"cell_type": "code",
@@ -1248,19 +1163,17 @@
"nu.display_plots('computing_eq_three_2_covariance{sample:0>3}.svg', \n",
" directory='./kern', \n",
" sample=IntSlider(0, 0, 16, 1))"
- ],
- "id": "437bb46d-9288-4ffb-b09e-a59aadeb9e92"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Entrywise fill in of the covariance matrix from the\n",
"covariance function."
- ],
- "id": "b90b55fa-7f8c-4764-86a8-d245fae4b3c5"
+ ]
},
{
"cell_type": "markdown",
@@ -1268,11 +1181,10 @@
"source": [
"## Brownian Covariance\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Brownian motion covariance function."
- ],
- "id": "c6db5b71-907e-4b2c-885c-751797285238"
+ ]
},
{
"cell_type": "markdown",
@@ -1354,8 +1261,8 @@
"source": [
"## Where did this covariance matrix come from?\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: The exponential covariance function."
- ],
- "id": "b7b141d5-c42e-4a44-a8e8-e4a22eed3a1f"
+ ]
},
{
"cell_type": "markdown",
@@ -1533,8 +1428,8 @@
"source": [
"## Basis Function Covariance\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: A covariance function based on a non-linear basis given by\n",
"$\\boldsymbol{ \\phi}(\\mathbf{ x})$."
- ],
- "id": "d36ac3c0-eef5-463f-bb1a-502ec8f7c4cf"
+ ]
},
{
"cell_type": "markdown",
@@ -1655,8 +1541,8 @@
"source": [
"## Degenerate Covariance Functions\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Sinc covariance function."
- ],
- "id": "74e1a5a3-8f37-468c-89fc-985861ade15f"
+ ]
},
{
"cell_type": "markdown",
@@ -1854,11 +1731,10 @@
"source": [
"## Matérn 3/2 Covariance\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: The Matérn 3/2 covariance function."
- ],
- "id": "105db1f7-4691-4fe4-878c-90aecc3df300"
+ ]
},
{
"cell_type": "markdown",
@@ -1971,11 +1839,10 @@
"source": [
"## Matérn 5/2 Covariance\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: The Matérn 5/2 covariance function."
- ],
- "id": "d5acd61d-1d76-48e7-90a7-690ced776540"
+ ]
},
{
"cell_type": "markdown",
@@ -2088,11 +1947,10 @@
"source": [
"## Rational Quadratic Covariance\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: The rational quadratic covariance function."
- ],
- "id": "6f3d4b86-1b30-4a8e-89fd-bc3bcde1ff5b"
+ ]
},
{
"cell_type": "markdown",
@@ -2210,11 +2060,10 @@
"source": [
"## Polynomial Covariance\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: Polynomial covariance function."
- ],
- "id": "b09704d8-c5e5-4c12-9962-67ce187353f4"
+ ]
},
{
"cell_type": "markdown",
@@ -2290,11 +2134,10 @@
"source": [
"## Periodic Covariance\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Periodic covariance function."
- ],
- "id": "9abae2be-d5bb-46ef-8f9d-c493f96ca98c"
+ ]
},
{
"cell_type": "markdown",
@@ -2370,11 +2208,10 @@
"source": [
"## MLP Covariance\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: The multi-layer perceptron covariance function. This is\n",
"derived by considering the infinite limit of a neural network with\n",
"probit activation functions."
- ],
- "id": "be159e5f-d12b-4669-ae32-6edb1addcae6"
+ ]
},
{
"cell_type": "markdown",
@@ -2456,11 +2288,10 @@
"source": [
"## RELU Covariance\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Rectified linear unit covariance function."
- ],
- "id": "f76a7a79-6d6e-4209-8b30-df30489c038b"
+ ]
},
{
"cell_type": "markdown",
@@ -2537,11 +2363,10 @@
"source": [
"## Additive Covariance\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: An additive covariance function formed by combining a linear\n",
"and an exponentiated quadratic covariance functions."
- ],
- "id": "53acbbae-af64-4c70-9ca2-24145c38201f"
+ ]
},
{
"cell_type": "markdown",
@@ -2701,11 +2514,10 @@
"source": [
"## Product Covariance\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: An product covariance function formed by combining a linear\n",
"and an exponentiated quadratic covariance functions."
- ],
- "id": "055ed3c0-8bd6-4f82-ba52-d1cfa86a349c"
+ ]
},
{
"cell_type": "markdown",
@@ -2866,8 +2666,8 @@
"source": [
"## Mauna Loa Data\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Mauna Loa data shows carbon dioxide monthly average\n",
"measurements from the Mauna Loa Observatory in Hawaii.\n",
@@ -3006,10 +2796,9 @@
"the argument `num_train` argument, which defaults to 545. This number is\n",
"chosen as it matches that used in the [Gaussian Processes for Machine\n",
"Learning](http://www.gaussianprocess.org/gpml/chapters/RW5.pdf) book\n",
- "(Rasmussen and Williams, 2006, chap. 5). Below we plot the test and\n",
+ "(Rasmussen and Williams, 2006, Chapter 5). Below we plot the test and\n",
"training data."
- ],
- "id": "654f2ebf-988c-41d4-bcd4-805618796844"
+ ]
},
{
"cell_type": "code",
@@ -3020,8 +2809,7 @@
"xtest = data['Xtest']\n",
"ytest = data['Ytest']\n",
"ytesthat = (ytest-offset)/scale"
- ],
- "id": "e8ecb3b9-0db0-4153-99aa-272d2e0e2593"
+ ]
},
{
"cell_type": "code",
@@ -3039,21 +2827,19 @@
"\n",
"mlai.write_figure(filename='mauna-loa-test.svg', \n",
" directory='./datasets')"
- ],
- "id": "e5250406-49e9-4fc9-96bf-4741a7abb152"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Mauna Loa test data shows carbon dioxide monthly average\n",
"measurements from the Mauna Loa Observatory in Hawaii.\n",
"\n",
"Of course we have included the citation information for the data."
- ],
- "id": "6d2ccbbf-206c-4a1f-9105-7a22b44dbcbe"
+ ]
},
{
"cell_type": "code",
@@ -3062,8 +2848,7 @@
"outputs": [],
"source": [
"print(data['citation'])"
- ],
- "id": "f2553526-2b6d-43fe-bd6d-82b255c0f7be"
+ ]
},
{
"cell_type": "markdown",
@@ -3071,8 +2856,7 @@
"source": [
"And extra information about the data is included, as standard, under the\n",
"keys `info` and `details`."
- ],
- "id": "616eec83-b3bf-42a5-880d-12ed027d2cd7"
+ ]
},
{
"cell_type": "code",
@@ -3083,8 +2867,7 @@
"print(data['info'])\n",
"print()\n",
"print(data['details'])"
- ],
- "id": "40625916-60a0-4620-a725-b7aed248b8a5"
+ ]
},
{
"cell_type": "markdown",
@@ -3092,8 +2875,7 @@
"source": [
"And, importantly, for reference you can also check the license for the\n",
"data:"
- ],
- "id": "ff35f04f-8942-4ef2-8bdf-cf86ce07ad61"
+ ]
},
{
"cell_type": "code",
@@ -3102,8 +2884,7 @@
"outputs": [],
"source": [
"print(data['license'])"
- ],
- "id": "49b3176a-f2f2-4dc4-acaf-7f75e8044b41"
+ ]
},
{
"cell_type": "markdown",
@@ -3111,8 +2892,8 @@
"source": [
"## Gaussian Process Fit\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process fit to the Mauna Loa Observatory data on CO2\n",
"concentrations."
- ],
- "id": "a5ad957b-69c3-4b06-a6eb-226865a57709"
+ ]
},
{
"cell_type": "markdown",
@@ -3232,14 +3004,13 @@
"source": [
"## Box Jenkins Airline Passenger Data\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Box-Jenkins data set on airline passenger numbers."
- ],
- "id": "0383062a-0f19-481d-af17-3e5998d728fd"
+ ]
},
{
"cell_type": "markdown",
@@ -3322,15 +3088,14 @@
"source": [
"## Gaussian Process Fit\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process fit to the Box-Jenkins airline passenger\n",
"data."
- ],
- "id": "3d8d8b74-0c6a-4bb9-a1b0-10c02f1ef13f"
+ ]
},
{
"cell_type": "markdown",
@@ -3443,11 +3200,10 @@
"source": [
"## Spectral Mixture Kernel\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Spectral mixture GP as applied to the Box-Jenkins airline\n",
"data."
- ],
- "id": "a229068e-8f52-4844-ab89-cc391d530291"
+ ]
},
{
"cell_type": "markdown",
@@ -3577,11 +3323,10 @@
"source": [
"## Mauna Loa Spectral Mixture\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Spectral mixture GP as applied to the Mauna Loa Observatory\n",
"carbon dioxide concentration data."
- ],
- "id": "0469f699-d189-46e3-9c8e-74c1931c1dbb"
+ ]
},
{
"cell_type": "markdown",
@@ -3727,8 +3461,7 @@
" Page](http://www.theguardian.com/profile/neil-lawrence)\n",
"- blog:\n",
" [http://inverseprobability.com](http://inverseprobability.com/blog.html)"
- ],
- "id": "0dbaf88b-97a0-409e-8121-b9422da50604"
+ ]
},
{
"cell_type": "markdown",
@@ -3736,9 +3469,8 @@
"source": [
"## References\n",
"\n",
- "Bochner, S., 1959. [Lectures on Fourier\n",
- "integrals](http://books.google.co.uk/books?id=-vU02QewWK8C). Princeton\n",
- "University Press.\n",
+ "Bochner, S., 1959. Lectures on Fourier integrals. Princeton University\n",
+ "Press.\n",
"\n",
"Box, G.E.P., Jenkins, G.M., 1976. Time series analysis: Forecasting and\n",
"control. Holden-Day.\n",
@@ -3758,8 +3490,7 @@
"dioxide at Mauna Loa Observatory: 2. Analysis of the NOAA GMCC data,\n",
"1974–1985. Journal of Geophysical Research: Atmospheres 94, 8549–8565.\n",
"\n",
+ "\n",
"\n",
"Figure: GPy is a BSD licensed software code base for implementing\n",
"Gaussian process models in Python. It is designed for teaching and\n",
@@ -249,8 +234,7 @@
"\n",
"The documentation for GPy can be found\n",
"[here](https://gpy.readthedocs.io/en/latest/)."
- ],
- "id": "b0651556-f875-42e1-9843-c819243c6a47"
+ ]
},
{
"cell_type": "markdown",
@@ -258,16 +242,15 @@
"source": [
"## Improving the Numerics\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"$\\boldsymbol{ \\Lambda}$ represents distance on axes. $\\mathbf{R}$ gives\n",
"rotation.\n",
@@ -463,8 +435,7 @@
" $\\mathbf{R}^\\top\\mathbf{R}= \\mathbf{I}$.\n",
"- Useful representation since\n",
" $\\det{\\mathbf{K}} = \\det{\\boldsymbol{ \\Lambda}^2} = \\det{\\boldsymbol{ \\Lambda}}^2$."
- ],
- "id": "377f6f29-1d7c-462a-a3ec-99b9abe3437e"
+ ]
},
{
"cell_type": "code",
@@ -476,8 +447,7 @@
"import numpy as np\n",
"import mlai\n",
"import mlai.plot as plot"
- ],
- "id": "bf636fd4-0e47-4b3c-aeb9-95dc59ebf5f9"
+ ]
},
{
"cell_type": "code",
@@ -486,8 +456,7 @@
"outputs": [],
"source": [
"plot.covariance_capacity(rotate_angle=np.pi/4, lambda1 = 0.5, lambda2 = 0.3, diagrams = './gp/')"
- ],
- "id": "f0933810-9e05-4150-a38b-28bc9f2172b9"
+ ]
},
{
"cell_type": "code",
@@ -497,8 +466,7 @@
"source": [
"import notutils as nu\n",
"from ipywidgets import IntSlider"
- ],
- "id": "176bbf44-e6bb-40f9-a2b1-773004a48c47"
+ ]
},
{
"cell_type": "code",
@@ -509,19 +477,17 @@
"nu.display_plots('gp-optimise-determinant{sample:0>3}.svg', \n",
" directory='./gp', \n",
" sample=IntSlider(0, 0, 9, 1))"
- ],
- "id": "0770644c-19fa-412d-a247-d7533299b3db"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: The determinant of the covariance is dependent only on the\n",
"eigenvalues. It represents the ‘footprint’ of the Gaussian."
- ],
- "id": "d7245379-a5f8-45aa-b3d9-76700a84ac81"
+ ]
},
{
"cell_type": "markdown",
@@ -529,11 +495,10 @@
"source": [
"## Quadratic Data Fit\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: The data fit term of the Gaussian process is a quadratic loss\n",
"centered around zero. This has eliptical contours, the principal axes of\n",
"which are given by the covariance matrix."
- ],
- "id": "1498b43e-8ba9-42c3-90ab-c6569db4bad8"
+ ]
},
{
"cell_type": "markdown",
@@ -603,11 +563,10 @@
"source": [
"## Data Fit Term\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
- "\n",
+ "\n",
"\n",
- "\n",
+ "\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: Variation in the data fit term, the capacity term and the\n",
"negative log likelihood for different lengthscales."
- ],
- "id": "936c2152-0a3d-430b-8f04-d4b5d61dc308"
+ ]
},
{
"cell_type": "markdown",
@@ -820,8 +768,8 @@
"source": [
"## Gene Expression Example\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Gene expression levels over time for a gene from data\n",
"provided by Della Gatta et al. (2008). We would like to understand\n",
@@ -924,9 +865,9 @@
"- Want to detect if a gene is expressed or not, fit a GP to each gene\n",
" Kalaitzis and Lawrence (2011).\n",
"\n",
- "\\freddieKalaitzisPicture{15%}\n",
+ "\\\\freddieKalaitzisPicture{15%}\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: The example is taken from the paper “A Simple Approach to\n",
"Ranking Differentially Expressed Gene Expression Time Courses through\n",
@@ -941,8 +882,7 @@
"Our first objective will be to perform a Gaussian process fit to the\n",
"data, we’ll do this using the [GPy\n",
"software](https://github.com/SheffieldML/GPy)."
- ],
- "id": "084264ef-c773-4181-9b00-1e968dc09828"
+ ]
},
{
"cell_type": "code",
@@ -951,8 +891,7 @@
"outputs": [],
"source": [
"import GPy"
- ],
- "id": "b7d192cd-dd25-4308-ad42-0f29f6b623d5"
+ ]
},
{
"cell_type": "code",
@@ -963,8 +902,7 @@
"m_full = GPy.models.GPRegression(x,yhat)\n",
"m_full.kern.lengthscale=50\n",
"_ = m_full.optimize() # Optimize parameters of covariance function"
- ],
- "id": "8992ead5-bd7a-4bce-a7a1-75da4cb2a217"
+ ]
},
{
"cell_type": "markdown",
@@ -974,8 +912,7 @@
"*time scale* of the covariance function) to a reasonable value. Default\n",
"would be 1, but here we set it to 50 minutes, given points are arriving\n",
"across zero to 250 minutes."
- ],
- "id": "04057cfe-0235-4cf5-b793-d628212f7cb9"
+ ]
},
{
"cell_type": "code",
@@ -986,16 +923,14 @@
"xt = np.linspace(-20,260,200)[:,np.newaxis]\n",
"yt_mean, yt_var = m_full.predict(xt)\n",
"yt_sd=np.sqrt(yt_var)"
- ],
- "id": "a61f7509-c7a1-4813-b3d0-3b0ee8ca170c"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"Now we plot the results using the helper function in `mlai.plot`."
- ],
- "id": "37e8f451-f2eb-4702-9122-4026f06b9a01"
+ ]
},
{
"cell_type": "code",
@@ -1004,8 +939,7 @@
"outputs": [],
"source": [
"import mlai.plot as plot"
- ],
- "id": "d9da7d10-6ea4-4914-b07c-20e22d4ce8e0"
+ ]
},
{
"cell_type": "code",
@@ -1021,21 +955,19 @@
"mlai.write_figure(figure=fig,\n",
" filename='./gp/della-gatta-gene-gp.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "b9eab43c-b2cd-4cce-8060-8d2ffcf68b34"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Result of the fit of the Gaussian process model with the time\n",
"scale parameter initialized to 50 minutes.\n",
"\n",
"Now we try a model initialized with a longer length scale."
- ],
- "id": "dbb04ab1-74cc-4fa8-a827-b5253de4c2ce"
+ ]
},
{
"cell_type": "code",
@@ -1046,8 +978,7 @@
"m_full2 = GPy.models.GPRegression(x,yhat)\n",
"m_full2.kern.lengthscale=2000\n",
"_ = m_full2.optimize() # Optimize parameters of covariance function"
- ],
- "id": "9f61da55-d3b8-40b2-94ee-e606bf74126b"
+ ]
},
{
"cell_type": "code",
@@ -1056,8 +987,7 @@
"outputs": [],
"source": [
"import mlai.plot as plot"
- ],
- "id": "dbe2cf38-6e7c-452d-a740-76a0bbe41570"
+ ]
},
{
"cell_type": "code",
@@ -1073,21 +1003,19 @@
"mlai.write_figure(figure=fig,\n",
" filename='./gp/della-gatta-gene-gp2.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "e4971d7b-e826-4268-b597-8ecfc9703d7e"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Result of the fit of the Gaussian process model with the time\n",
"scale parameter initialized to 2000 minutes.\n",
"\n",
"Now we try a model initialized with a lower noise."
- ],
- "id": "5785fb2a-e844-4746-bfa6-607905c3cff0"
+ ]
},
{
"cell_type": "code",
@@ -1099,8 +1027,7 @@
"m_full3.kern.lengthscale=20\n",
"m_full3.likelihood.variance=0.001\n",
"_ = m_full3.optimize() # Optimize parameters of covariance function"
- ],
- "id": "b22f34cd-530f-4779-9a5c-cd856f232bee"
+ ]
},
{
"cell_type": "code",
@@ -1109,8 +1036,7 @@
"outputs": [],
"source": [
"import mlai.plot as plot"
- ],
- "id": "8c2bbb42-ec8a-4a53-9d5b-a73bb5ba8af0"
+ ]
},
{
"cell_type": "code",
@@ -1126,20 +1052,18 @@
"mlai.write_figure(figure=fig,\n",
" filename='./gp/della-gatta-gene-gp3.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "3a20bd79-1874-4b1a-9713-81291e06183c"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Result of the fit of the Gaussian process model with the\n",
"noise initialized low (standard deviation 0.1) and the time scale\n",
"parameter initialized to 20 minutes."
- ],
- "id": "deb1b97d-40d5-4efa-8c89-877182f95905"
+ ]
},
{
"cell_type": "code",
@@ -1148,8 +1072,7 @@
"outputs": [],
"source": [
"import mlai.plot as plot"
- ],
- "id": "a24ee53e-da8c-4e53-876f-dd861b7c74a9"
+ ]
},
{
"cell_type": "code",
@@ -1158,22 +1081,20 @@
"outputs": [],
"source": [
"plot.multiple_optima(directory='./gp')"
- ],
- "id": "710237d6-f4d7-4bf7-885c-eed9d51fe3ce"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: \n",
"\n",
""
- ],
- "id": "c0cfdeae-59d0-4f93-a413-9a57dcb4c4f0"
+ "
 -->"
+ ]
},
{
"cell_type": "markdown",
@@ -1193,8 +1114,7 @@
" Page](http://www.theguardian.com/profile/neil-lawrence)\n",
"- blog:\n",
" [http://inverseprobability.com](http://inverseprobability.com/blog.html)"
- ],
- "id": "1a5f4a44-28c2-4850-a1bc-b549c0a4b785"
+ ]
},
{
"cell_type": "markdown",
@@ -1212,8 +1132,7 @@
"differentially expressed gene expression time courses through Gaussian\n",
"process regression. BMC Bioinformatics 12.\n",
"\n",
+ "\n",
"\n",
"Figure: GPy is a BSD licensed software code base for implementing\n",
"Gaussian process models in Python. It is designed for teaching and\n",
@@ -307,7 +309,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Illustration of the Kronecker product."
]
@@ -325,7 +327,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Kronecker product between two matrices."
]
@@ -400,7 +402,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: The marginal distribution for the first three variables\n",
"(highlighted) is givne by $\\mathbf{K}$ when the form of stacking is\n",
@@ -473,7 +475,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: The marginal distribution for the first three variables\n",
"(highlighted) is independent when the form of stacking is\n",
@@ -486,7 +488,7 @@
"source": [
"## Mapping from Latent Process to Observed\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Mapping from latent process to observed"
]
@@ -527,7 +529,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: "
]
@@ -793,9 +795,9 @@
"\n",
"\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Intrinsic coregionalization model covariance function."
]
@@ -1033,7 +1035,7 @@
"- 100m, 200m, 400m\n",
"- In early years of olympics not all events run.\n",
"\n",
- "
 \n",
+ "
 \n",
"Image from Wikimedia Commons
 \n",
+ "
 \n",
"\n",
"Figure: Olympic sprint gold medal winning times from Rogers and\n",
"Girolami (2011).\n",
@@ -1359,7 +1361,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process fit to the Olympic Sprint data.\n",
"\n",
@@ -1410,7 +1412,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process fit to the Olympic Sprint data.\n",
"\n",
@@ -1464,7 +1466,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process fit to the Olympic Sprint data.\n",
"\n",
diff --git a/_notebooks/06-approximate-gps.ipynb b/_notebooks/06-approximate-gps.ipynb
index 2d73016..853a6de 100644
--- a/_notebooks/06-approximate-gps.ipynb
+++ b/_notebooks/06-approximate-gps.ipynb
@@ -27,6 +27,8 @@
"metadata": {},
"source": [
"\n",
+ "\n",
+ "\n",
"\n",
"\n",
"\n",
@@ -208,7 +210,7 @@
"to use interface to GPs. One which allowed the user to focus on the\n",
"modelling rather than the mathematics.\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: GPy is a BSD licensed software code base for implementing\n",
"Gaussian process models in Python. It is designed for teaching and\n",
@@ -232,7 +234,7 @@
"The documentation for GPy can be found\n",
"[here](https://gpy.readthedocs.io/en/latest/).\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: In recent years, approximations for Gaussian process models\n",
"haven’t been the most fashionable approach to machine learning. Image\n",
@@ -350,7 +352,7 @@
"- The posterior of $\\mathbf{ f}$ is the central object. This means\n",
" inverting $\\mathbf{K}_{\\mathbf{ f}\\mathbf{ f}}$.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Figure originally from presentation by Ed Snelson at NIPS\n",
"\n",
@@ -367,17 +369,17 @@
"\n",
"$$\\mathbf{X},\\,\\mathbf{ y}$$\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"$$\\mathbf{X},\\,\\mathbf{ y}$$\n",
"$${\\color{blue} f(\\mathbf{ x})} \\sim {\\mathcal GP}$$\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"$$\\mathbf{X},\\,\\mathbf{ y}$$\n",
"$$f(\\mathbf{ x}) \\sim {\\mathcal GP}$$$$p({\\color{blue} \\mathbf{ f}}) = \\mathscr{N}\\left(\\mathbf{0},\\mathbf{K}_{\\mathbf{ f}\\mathbf{ f}}\\right)$$\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"$$\n",
"\\mathbf{X},\\,\\mathbf{ y}$$ $$f(\\mathbf{ x}) \\sim {\\mathcal GP}\n",
@@ -386,12 +388,12 @@
"$$ $$p( \\mathbf{ f}|\\mathbf{ y},\\mathbf{X})\n",
"$$\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Take an extra $m$ points on the function, $\\mathbf{ u}= f(\\mathbf{Z})$.\n",
"$$p(\\mathbf{ y},\\mathbf{ f},\\mathbf{ u}) = p(\\mathbf{ y}|\\mathbf{ f}) p(\\mathbf{ f}|\\mathbf{ u}) p(\\mathbf{ u})$$\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Take and extra $M$ points on the function, $\\mathbf{ u}= f(\\mathbf{Z})$.\n",
"$$p(\\mathbf{ y},\\mathbf{ f},\\mathbf{ u}) = p(\\mathbf{ y}|\\mathbf{ f}) p(\\mathbf{ f}|\\mathbf{ u}) p(\\mathbf{ u})$$\n",
@@ -405,7 +407,7 @@
"$$p(\\mathbf{ f}) = \\mathscr{N}\\left(\\mathbf{0},\\mathbf{K}_{\\mathbf{ f}\\mathbf{ f}}\\right)$$\n",
"$$p(\\mathbf{ f}|\\mathbf{ y},\\mathbf{X})$$\n",
"\n",
- "
\n",
+ "
\n",
"\n",
"$$\n",
"\\begin{align}\n",
@@ -417,7 +419,7 @@
"$$p(\\mathbf{ f}|\\mathbf{ y},\\mathbf{X})$$\n",
"$$p(\\mathbf{ u}) = \\mathscr{N}\\left(\\mathbf{0},\\mathbf{K}_{\\mathbf{ u}\\mathbf{ u}}\\right)$$\n",
"$$\\widetilde p({\\color{red}\\mathbf{ u}}|\\mathbf{ y},\\mathbf{X})$$ }{\n",
- "
 \n",
+ "
 \n",
"\n",
"Instead of doing $$\n",
"p(\\mathbf{ f}|\\mathbf{ y},\\mathbf{X}) = \\frac{p(\\mathbf{ y}|\\mathbf{ f})p(\\mathbf{ f}|\\mathbf{X})}{\\int p(\\mathbf{ y}|\\mathbf{ f})p(\\mathbf{ f}|\\mathbf{X}){\\text{d}\\mathbf{ f}}}\n",
@@ -618,41 +620,41 @@
"\n",
" $$p(\\mathbf{ y})$$\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"- Prior density over $\\mathbf{ f}$. Likelihood relates data,\n",
" $\\mathbf{ y}$, to $\\mathbf{ f}$.\n",
"\n",
" $$p(\\mathbf{ y})=\\int p(\\mathbf{ y}|\\mathbf{ f})p(\\mathbf{ f})\\text{d}\\mathbf{ f}$$\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"- Prior density over $\\mathbf{ f}$. Likelihood relates data,\n",
" $\\mathbf{ y}$, to $\\mathbf{ f}$.\n",
"\n",
" $$p(\\mathbf{ y})=\\int p(\\mathbf{ y}|\\mathbf{ f})p(\\mathbf{ u}|\\mathbf{ f})p(\\mathbf{ f})\\text{d}\\mathbf{ f}\\text{d}\\mathbf{ u}$$\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"$$p(\\mathbf{ y})=\\int \\int p(\\mathbf{ y}|\\mathbf{ f})p(\\mathbf{ f}|\\mathbf{ u})\\text{d}\\mathbf{ f}p(\\mathbf{ u})\\text{d}\\mathbf{ u}$$\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"$$p(\\mathbf{ y})=\\int \\int p(\\mathbf{ y}|\\mathbf{ f})p(\\mathbf{ f}|\\mathbf{ u})\\text{d}\\mathbf{ f}p(\\mathbf{ u})\\text{d}\\mathbf{ u}$$\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"$$p(\\mathbf{ y}|\\mathbf{ u})=\\int p(\\mathbf{ y}|\\mathbf{ f})p(\\mathbf{ f}|\\mathbf{ u})\\text{d}\\mathbf{ f}$$\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"$$p(\\mathbf{ y}|\\mathbf{ u})$$\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"$$p(\\mathbf{ y}|\\boldsymbol{ \\theta})$$\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"- Replace true $p(\\mathbf{ u}|\\mathbf{ y})$ with approximation\n",
" $q(\\mathbf{ u}|\\mathbf{ y})$.\n",
@@ -1122,7 +1124,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Full Gaussian process fitted to the data set.\n",
"\n",
@@ -1165,7 +1167,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Sparse Gaussian process fitted with six inducing variables,\n",
"no optimization of parameters or inducing variables."
@@ -1198,7 +1200,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process fitted with inducing variables fixed and\n",
"parameters optimized"
@@ -1232,7 +1234,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process fitted with location of inducing variables\n",
"and parameters both optimized\n",
@@ -1272,8 +1274,8 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
- "\n",
+ "
 \n",
+ "\n",
"\n",
"Figure: Comparison of the full Gaussian process fit with a sparse\n",
"Gaussian process using eight inducing varibles. Both inducing variables\n",
diff --git a/_notebooks/07-non-gaussian-likelihoods.ipynb b/_notebooks/07-non-gaussian-likelihoods.ipynb
index a2419e8..7f45a5c 100644
--- a/_notebooks/07-non-gaussian-likelihoods.ipynb
+++ b/_notebooks/07-non-gaussian-likelihoods.ipynb
@@ -5,14 +5,14 @@
"metadata": {},
"source": [
"# Non Gaussian Likelihoods"
- ],
- "id": "44206cfb-bdc7-4fe8-811e-53e93d479087"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
- "source": [],
- "id": "829c644e-6a1b-4af2-9aea-bc36b313c070"
+ "source": [
+ "**Abstract**: null"
+ ]
},
{
"cell_type": "markdown",
@@ -20,14 +20,15 @@
"source": [
"$$\n",
"$$"
- ],
- "id": "f439fdd2-ea4f-40f3-96f2-cce27322ad5d"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"\n",
+ "\n",
+ "\n",
"\n",
"\n",
"\n",
@@ -39,8 +40,7 @@
""
- ],
- "id": "e2515b93-757b-4c02-bdd9-d74c7725d6a3"
+ ]
},
{
"cell_type": "markdown",
@@ -48,14 +48,13 @@
"source": [
"## Gaussian Process Summer School notebook setup\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: GPy is a BSD licensed software code base for implementing\n",
"Gaussian process models in Python. It is designed for teaching and\n",
@@ -246,8 +233,7 @@
"\n",
"The documentation for GPy can be found\n",
"[here](https://gpy.readthedocs.io/en/latest/)."
- ],
- "id": "ea868cd9-b9f3-455d-985f-ca7ade5efbf8"
+ ]
},
{
"cell_type": "markdown",
@@ -255,8 +241,8 @@
"source": [
"# Non Gaussian Likelihoods\n",
"\n",
- "\\[\\[\n",
+ "\n",
"Image from [Wikimedia\n",
"Commons](https://commons.wikimedia.org/wiki/File:Eliud_Kipchoge_in_Berlin_-_2015_(cropped).jpg)\n",
"\n",
@@ -436,8 +398,7 @@
"modelling. The data consists of the pace of Olympic Gold Medal Marathon\n",
"winners for the Olympics from 1896 to present. Let’s load in the data\n",
"and plot."
- ],
- "id": "a704c4f8-1fd2-48ab-a3af-6a6623c26d8f"
+ ]
},
{
"cell_type": "code",
@@ -446,8 +407,7 @@
"outputs": [],
"source": [
"cmd = install_command('pods')"
- ],
- "id": "f605e870-10fd-4de4-a29e-a0a9a1321a30"
+ ]
},
{
"cell_type": "code",
@@ -456,8 +416,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "24ae42e1-6a80-4b52-9e95-0da9623ea3bf"
+ ]
},
{
"cell_type": "code",
@@ -467,8 +426,7 @@
"source": [
"import numpy as np\n",
"import pods"
- ],
- "id": "470e1c3b-34c9-4638-b7ff-d8ead3555191"
+ ]
},
{
"cell_type": "code",
@@ -483,8 +441,7 @@
"offset = y.mean()\n",
"scale = np.sqrt(y.var())\n",
"yhat = (y - offset)/scale"
- ],
- "id": "89a8e821-cbb0-4cfa-817b-7cd7f0fc1870"
+ ]
},
{
"cell_type": "code",
@@ -495,8 +452,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "5cd9cbe4-a25b-4339-89e4-649360e5b9e0"
+ ]
},
{
"cell_type": "code",
@@ -504,7 +460,6 @@
"metadata": {},
"outputs": [],
"source": [
- "\n",
"xlim = (1876,2044)\n",
"ylim = (2.5, 6.5)\n",
"\n",
@@ -517,14 +472,13 @@
"\n",
"mlai.write_figure(filename='olympic-marathon.svg', \n",
" directory='./datasets')"
- ],
- "id": "f201625c-e753-4077-a70b-8772108b30d8"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Olympic marathon pace times since 1896.\n",
"\n",
@@ -533,8 +487,7 @@
"challenges with dust kicked up by the cars following the race meant that\n",
"participants got lost, and only very few participants completed. More\n",
"recent years see more consistently quick marathons."
- ],
- "id": "e06c1f3f-86d8-4c7a-b1c5-6c319ee338ff"
+ ]
},
{
"cell_type": "markdown",
@@ -542,13 +495,13 @@
"source": [
"## Alan Turing\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Alan Turing, in 1946 he was only 11 minutes slower than the\n",
"winner of the 1948 games. Would he have won a hypothetical games held in\n",
@@ -565,7 +518,7 @@
"\\text{data} + \\text{model} \\stackrel{\\text{compute}}{\\rightarrow} \\text{prediction}\n",
"$$ then we see that without a model we can’t generalise: we only have\n",
"data. Data is fine for answering very specific questions, like “Who won\n",
- "the Olympic Marathon in 2012?”, because we have that answer stored,\n",
+ "the Olympic Marathon in 2012?” because we have that answer stored,\n",
"however, we are not given the answer to many other questions. For\n",
"example, Alan Turing was a formidable marathon runner, in 1946 he ran a\n",
"time 2 hours 46 minutes (just under four minutes per kilometer, faster\n",
@@ -577,8 +530,7 @@
"To answer this question we need to generalize, but before we formalize\n",
"the concept of generalization let’s introduce some formal representation\n",
"of what it means to generalize in machine learning."
- ],
- "id": "aad8a4a1-fc44-41f1-85d3-ce88ab57e133"
+ ]
},
{
"cell_type": "markdown",
@@ -586,15 +538,14 @@
"source": [
"## Gaussian Process Fit\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process fit to the Olympic Marathon data. The error\n",
"bars are too large, perhaps due to the outlier from 1904."
- ],
- "id": "869fabc2-bd5c-4e0d-bcf9-2a3d52368bdd"
+ ]
},
{
"cell_type": "markdown",
@@ -702,8 +645,7 @@
"1904, ignoring that point we can see that a tighter fit is obtained. To\n",
"see this make a version of the model, `m_clean`, where that point is\n",
"removed."
- ],
- "id": "25a61508-cbd6-41ff-9b0c-fcefd0ad5b51"
+ ]
},
{
"cell_type": "code",
@@ -716,8 +658,7 @@
"\n",
"m_clean = GPy.models.GPRegression(x_clean,y_clean)\n",
"_ = m_clean.optimize()"
- ],
- "id": "29457f07-098b-42f5-ae8d-c67a645ff3c8"
+ ]
},
{
"cell_type": "code",
@@ -728,8 +669,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "f37841dc-2c2e-4b2b-8e89-22eba312e7cb"
+ ]
},
{
"cell_type": "code",
@@ -744,19 +684,17 @@
"mlai.write_figure(figure=fig,\n",
" filename='./gp/olympic-marathon-gp-outlier-removed.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "861569a5-b76a-4d2d-9dfc-7bf85f7f66e4"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process fit to the Olympic Marathon data. Here we’ve\n",
"removed the outlier from 1904."
- ],
- "id": "fbd786a6-cbcc-4a8a-8eb1-54ae3a27df2a"
+ ]
},
{
"cell_type": "markdown",
@@ -764,8 +702,8 @@
"source": [
"## Robust Regression: A Running Example\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Fit to the Olympic marathon data using the Student-$t$\n",
"likelihood and the Laplace approximation."
- ],
- "id": "20af4a33-a62b-42d2-b32e-1c9b5361c29d"
+ ]
},
{
"cell_type": "markdown",
@@ -845,8 +778,7 @@
"\n",
"Correspond to whether the subject of the image is wearing glasses. Set\n",
"up the ipython environment and download the data:"
- ],
- "id": "8b1c06ce-a34d-4a7b-85af-9fbdf72950a8"
+ ]
},
{
"cell_type": "code",
@@ -855,8 +787,7 @@
"outputs": [],
"source": [
"from scipy import io"
- ],
- "id": "ac46c453-fcf7-425f-abb3-7f661e40ade8"
+ ]
},
{
"cell_type": "markdown",
@@ -868,8 +799,7 @@
"\n",
"Here’s a simple way to visualise the data. Each pixel in the image will\n",
"become an input to the GP."
- ],
- "id": "a2adaf43-a4f8-4042-b688-5cd36d7ad77d"
+ ]
},
{
"cell_type": "code",
@@ -878,8 +808,7 @@
"outputs": [],
"source": [
"import pods"
- ],
- "id": "35c6dcc3-3847-481d-84f0-c4cc77a534b6"
+ ]
},
{
"cell_type": "code",
@@ -893,8 +822,7 @@
"Xtest = data['Xtest']\n",
"ytest = data['Ytest']\n",
"print(data['info'], data['details'], data['citation'])"
- ],
- "id": "c29175bd-5b11-4519-8fc6-c5b202b3c971"
+ ]
},
{
"cell_type": "code",
@@ -905,8 +833,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "1aa53114-1079-4d4f-80e6-3dc8d0c6f369"
+ ]
},
{
"cell_type": "code",
@@ -921,14 +848,13 @@
"\n",
"mlai.write_figure(\"olivetti-glasses-image.png\", \n",
" directory=\"./datasets\")"
- ],
- "id": "74b9adb0-fded-4892-a963-556f7b59122a"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Image from the Oivetti glasses data sets.\n",
"\n",
@@ -936,8 +862,7 @@
"by applying k-means clustering to the training data. Think about whether\n",
"this is a good scheme for choosing the inputs? Can you devise a better\n",
"one?"
- ],
- "id": "07edea87-ce9c-416d-a7a7-4da918d2d428"
+ ]
},
{
"cell_type": "code",
@@ -948,8 +873,7 @@
"X.shape\n",
"y.shape\n",
"print(X)"
- ],
- "id": "8d1372ea-a6e3-4264-855a-1823da670b82"
+ ]
},
{
"cell_type": "code",
@@ -958,8 +882,7 @@
"outputs": [],
"source": [
"from scipy import cluster"
- ],
- "id": "864056d4-49f1-4e2d-a7e5-8ec029a1ee24"
+ ]
},
{
"cell_type": "code",
@@ -970,16 +893,14 @@
"M = 8\n",
"X = (X - X.mean(0)[np.newaxis,:])/X.std(0)[np.newaxis,:]\n",
"Z = np.random.permutation(X)[:M]"
- ],
- "id": "4169faaf-e876-4d82-b7b3-4a0fd040562e"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"Finally, we’re ready to build the classifier object."
- ],
- "id": "5e6cac1c-4e43-4226-a917-4a8619ae7edf"
+ ]
},
{
"cell_type": "code",
@@ -991,14 +912,12 @@
"model = GPy.models.SparseGPClassification(X, y, kernel=kern, Z=Z)\n",
"model.optimize(messages=True)\n",
"display(model)"
- ],
- "id": "dfaedb2d-6f64-4670-8d2d-0cfe28a50cca"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
- "source": [],
- "id": "70c68d3b-947c-49c3-a66b-6f841821c004"
+ "source": []
},
{
"cell_type": "code",
@@ -1009,8 +928,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "4db11dd2-01e3-40e8-aa75-de5aca6713a4"
+ ]
},
{
"cell_type": "code",
@@ -1022,18 +940,16 @@
"ax.imshow(model.Z.gradient[0].reshape(64,64,order='F'),interpolation='nearest',cmap=plt.cm.gray)\n",
"\n",
"mlai.write_figure('olivetti-inducing-variable-gradients.png', directory='./gp')"
- ],
- "id": "55a362fb-b2f0-420b-9eb1-3981136c7747"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: The gradients of the inducing variable."
- ],
- "id": "9563bcde-0120-4ca5-9d91-c0ac462f9417"
+ ]
},
{
"cell_type": "markdown",
@@ -1041,8 +957,8 @@
"source": [
"## Thanks!\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: GPy is a BSD licensed software code base for implementing\n",
"Gaussian process models in Python. It is designed for teaching and\n",
@@ -246,8 +233,7 @@
"\n",
"The documentation for GPy can be found\n",
"[here](https://gpy.readthedocs.io/en/latest/)."
- ],
- "id": "28fe3de2-0228-4483-b0b9-1ec1c6690330"
+ ]
},
{
"cell_type": "markdown",
@@ -255,8 +241,8 @@
"source": [
"## Probabilistic PCA\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Graphical model representing probabilistic PCA."
- ],
- "id": "e6eebd55-d26d-4e0d-b824-81c02726074d"
+ ]
},
{
"cell_type": "markdown",
@@ -382,8 +362,7 @@
"$$ where $\\sigma^2$ is the noise variance. Note that if $\\sigma^2$ is\n",
"larger than any particular eigenvalue, then that eigenvalue (along with\n",
"its corresponding eigenvector) is *discarded* from the solution."
- ],
- "id": "a13d78df-e26c-4144-a815-5d3779ea4b41"
+ ]
},
{
"cell_type": "markdown",
@@ -404,8 +383,7 @@
"holds and the manifold is approximately linear. When the manifold is\n",
"nonlinear, we need more sophisticated methods like kernel PCA or neural\n",
"network-based approaches."
- ],
- "id": "8e482b2f-adaf-4664-b020-08253a9961f3"
+ ]
},
{
"cell_type": "markdown",
@@ -414,8 +392,7 @@
"## Python Implementation of Probabilistic PCA\n",
"\n",
"We will now implement this algorithm in python."
- ],
- "id": "ea8a2f6d-16af-4b67-b55a-5e353dffb0c0"
+ ]
},
{
"cell_type": "code",
@@ -424,8 +401,7 @@
"outputs": [],
"source": [
"import numpy as np"
- ],
- "id": "652514e6-327e-4821-8347-53c4b2f6d353"
+ ]
},
{
"cell_type": "code",
@@ -436,8 +412,7 @@
"from mlai import ppca_eig\n",
"import inspect\n",
"file_path = inspect.getfile(ppca_eig)"
- ],
- "id": "75aa1721-fb16-489d-bb5d-3dd56a39d370"
+ ]
},
{
"cell_type": "code",
@@ -446,8 +421,7 @@
"outputs": [],
"source": [
"%load -s ppca_eig {file_path}"
- ],
- "id": "8fbef982-cfa9-46fb-921c-c60709eb2964"
+ ]
},
{
"cell_type": "code",
@@ -456,8 +430,7 @@
"outputs": [],
"source": [
"ppca = ppca_eig"
- ],
- "id": "59983195-023c-4939-aace-0d0bcefd16f2"
+ ]
},
{
"cell_type": "markdown",
@@ -474,8 +447,7 @@
"We saw a similar issue arise when , where we also wished to avoid\n",
"computation of $\\mathbf{Z}^\\top\\mathbf{Z}$ (or in the case of\n",
"$\\boldsymbol{\\Phi}^\\top\\boldsymbol{\\Phi}$)."
- ],
- "id": "8f8ca1d0-2dd3-4086-9cc7-65ae97e569c8"
+ ]
},
{
"cell_type": "markdown",
@@ -506,8 +478,7 @@
":})^\\top(\\mathbf{ y}_{i, :} - \\mathbf{W}\\mathbf{ z}_{i, :}) - \\frac{1}{2}\n",
"\\mathbf{ z}_{i, :}^\\top \\mathbf{ z}_{i, :} + \\text{const}\n",
"$$"
- ],
- "id": "195eeba2-1709-4803-ac2d-93e68b0a21a0"
+ ]
},
{
"cell_type": "markdown",
@@ -526,8 +497,7 @@
"= \\mathbf{C}_x \\sigma^{-2}\\mathbf{W}^\\top \\mathbf{ y}_{i, :} \n",
"$$ Compare this to the posterior for the Bayesian linear regression from\n",
"last week, do they have similar forms? What matches and what differs?"
- ],
- "id": "5f8d8c63-37a4-417c-b913-615300cb930f"
+ ]
},
{
"cell_type": "markdown",
@@ -536,8 +506,7 @@
"### Exercise 1 Answer\n",
"\n",
"Write your answer to Exercise 1 here"
- ],
- "id": "bc12348c-aaec-4bf5-889f-0277f0ff0c91"
+ ]
},
{
"cell_type": "markdown",
@@ -546,8 +515,7 @@
"## Python Implementation of the Posterior\n",
"\n",
"Now let’s implement the system in code."
- ],
- "id": "bfadfd3e-0ece-4f64-a1e5-aa16a4aa715e"
+ ]
},
{
"cell_type": "markdown",
@@ -569,8 +537,7 @@
"Don’t forget to subtract the mean of the data `Y` inside your function\n",
"before computing the posterior: remember we assumed at the beginning of\n",
"our analysis that the data had been centred (i.e. the mean was removed)."
- ],
- "id": "4d43055a-e349-4ce9-9f86-ee7d47f7c1ee"
+ ]
},
{
"cell_type": "code",
@@ -594,8 +561,7 @@
" mu_x = \n",
" return mu_x, C_x\n",
"\n"
- ],
- "id": "17304bf6-a206-4df0-859c-314577ff418d"
+ ]
},
{
"cell_type": "markdown",
@@ -623,8 +589,7 @@
"The eigenvalues of the matrix $\\mathbf{Y}^\\top\\mathbf{Y}$ are then given\n",
"by the singular values of the matrix $\\mathbf{Y}^\\top$ squared and the\n",
"eigenvectors are given by $\\mathbf{U}$."
- ],
- "id": "f4a4f91d-a9f7-4083-9908-8069b9060ff6"
+ ]
},
{
"cell_type": "markdown",
@@ -654,8 +619,7 @@
"\\boldsymbol{ \\mu}_x = \\mathbf{D}\\mathbf{U}^\\top \\mathbf{ y}_{i, :}\n",
"$$ where $\\mathbf{D}$ is a diagonal matrix with diagonal elements given\n",
"by $d_{i} = \\frac{\\ell_i}{\\sigma^2 + \\ell_i^2}$."
- ],
- "id": "000e5490-67df-42da-98ce-2b9f7aad1a79"
+ ]
},
{
"cell_type": "code",
@@ -665,8 +629,7 @@
"source": [
"import scipy as sp\n",
"import numpy as np"
- ],
- "id": "840b0eed-95de-4c27-831b-723cd5af9044"
+ ]
},
{
"cell_type": "code",
@@ -677,8 +640,7 @@
"from mlai import ppca_svd\n",
"import inspect\n",
"file_path = inspect.getfile(ppca_svd)"
- ],
- "id": "d69da568-44da-43a4-a4cb-cf99f60f3974"
+ ]
},
{
"cell_type": "code",
@@ -687,8 +649,7 @@
"outputs": [],
"source": [
"%load -s ppca_svd {file_path}"
- ],
- "id": "5db6386b-c902-4ec0-aae3-be58307c421d"
+ ]
},
{
"cell_type": "code",
@@ -699,8 +660,7 @@
"from mlai import ppca_posterior\n",
"import inspect\n",
"file_path = inspect.getfile(ppca_posterior)"
- ],
- "id": "8cbbae05-e0f3-42c2-a2ba-8790c03ac70b"
+ ]
},
{
"cell_type": "code",
@@ -709,8 +669,7 @@
"outputs": [],
"source": [
"%load -s ppca_posterior {file_path}"
- ],
- "id": "580efecd-0993-45df-a611-02d9895dc1bb"
+ ]
},
{
"cell_type": "code",
@@ -720,8 +679,7 @@
"source": [
"ppca = ppca_svd\n",
"posterior = ppca_posterior"
- ],
- "id": "30041ccb-8d60-417f-aef3-7dda260157b4"
+ ]
},
{
"cell_type": "markdown",
@@ -729,15 +687,14 @@
"source": [
"## Scikit-learn implementation PCA\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Visualization of the first two dimensions of the oil flow\n",
"data from Bishop and James (1993)\n",
"\n",
"As normal we include the citation information for the data."
- ],
- "id": "1ad9ed34-981a-43bf-89c0-65ea8e8674aa"
+ ]
},
{
"cell_type": "code",
@@ -871,8 +819,7 @@
"outputs": [],
"source": [
"print(data['citation'])"
- ],
- "id": "4777438a-6475-4769-8949-9d2aeb049b28"
+ ]
},
{
"cell_type": "markdown",
@@ -880,8 +827,7 @@
"source": [
"And extra information about the data is included, as standard, under the\n",
"keys `info` and `details`."
- ],
- "id": "0288351f-b3ad-4435-811a-5ba8e12a031f"
+ ]
},
{
"cell_type": "code",
@@ -890,8 +836,7 @@
"outputs": [],
"source": [
"print(data['details'])"
- ],
- "id": "59e3ff16-fcc9-49ab-80fb-f641071b3ff3"
+ ]
},
{
"cell_type": "code",
@@ -901,8 +846,7 @@
"source": [
"X = data['X']\n",
"Y = data['Y']"
- ],
- "id": "08b88d2c-7530-47a4-bf9b-1dd47210262c"
+ ]
},
{
"cell_type": "code",
@@ -911,8 +855,7 @@
"outputs": [],
"source": [
"cmd = install_command('scikit-learn')"
- ],
- "id": "caf1ee2e-32cc-4378-8d7d-16e45b2ea999"
+ ]
},
{
"cell_type": "code",
@@ -921,8 +864,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "cdaaaa57-59d7-41a0-9c76-6056c405d6c5"
+ ]
},
{
"cell_type": "code",
@@ -931,8 +873,7 @@
"outputs": [],
"source": [
"from sklearn.decomposition import PCA"
- ],
- "id": "d1862fc2-5b5e-4284-ad8a-13bcbfc315d8"
+ ]
},
{
"cell_type": "code",
@@ -943,8 +884,7 @@
"pca = PCA(n_components=2)\n",
"pca.fit(X)\n",
"X_pca = pca.transform(X)"
- ],
- "id": "aec31e5d-8ad2-454b-b7ec-c621855ea124"
+ ]
},
{
"cell_type": "code",
@@ -960,8 +900,7 @@
"class2 = (Y[:, 2] == 1).astype(int) * 2\n",
"# Combine into single array of class labels 0,1,2\n",
"lbls = class0 + class1 + class2"
- ],
- "id": "6357254c-4136-4092-9791-dacf85098578"
+ ]
},
{
"cell_type": "code",
@@ -972,8 +911,7 @@
"from matplotlib import pyplot as plt\n",
"import mlai\n",
"from mlai import plot"
- ],
- "id": "4f521da7-fea9-4e3f-abe2-fe82ed66e114"
+ ]
},
{
"cell_type": "code",
@@ -990,19 +928,17 @@
"ax.set_ylabel('Second principal component')\n",
"\n",
"mlai.write_figure(\"oil-flow-pca-sklearn.svg\", directory='./dimred')"
- ],
- "id": "775554b4-2ab9-44b9-86e7-75d9e5b6207e"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: PCA of the oil flow data. The flow is homogeneous, annular\n",
"and stratified."
- ],
- "id": "fd86083f-df45-458f-a49e-0a6bc2886e8e"
+ ]
},
{
"cell_type": "markdown",
@@ -1010,11 +946,10 @@
"source": [
"## Difficulty for Probabilistic Approaches\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: A two dimensional grid mapped into three dimensions to form a\n",
"two dimensional manifold."
- ],
- "id": "02412e76-d084-442d-a607-27532300ddf9"
+ ]
},
{
"cell_type": "code",
@@ -1059,20 +991,18 @@
"outputs": [],
"source": [
"plot.non_linear_difficulty_plot_2(diagrams='./dimred/')"
- ],
- "id": "628609ec-dddd-4efd-9831-13380989b411"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: A one dimensional line mapped into two dimensions by two\n",
"separate independent functions. Each point can be mapped exactly through\n",
"the mappings."
- ],
- "id": "d218c0a5-2224-4404-a525-981e2a661940"
+ ]
},
{
"cell_type": "code",
@@ -1081,8 +1011,7 @@
"outputs": [],
"source": [
"cmd = install_command('daft')"
- ],
- "id": "86220e84-0781-462e-90f9-848fade58041"
+ ]
},
{
"cell_type": "code",
@@ -1091,8 +1020,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "03e7affe-99f5-486d-a89a-514e4d3c5234"
+ ]
},
{
"cell_type": "code",
@@ -1101,19 +1029,17 @@
"outputs": [],
"source": [
"plot.non_linear_difficulty_plot_1(diagrams='./dimred')"
- ],
- "id": "b3123f47-a132-4f2f-b087-4f13fd5f67b5"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: A Gaussian density over the input of a non linear function\n",
"leads to a very non Gaussian output. Here the output is multimodal."
- ],
- "id": "242b5f60-4bbe-457c-b735-41aa2878356b"
+ ]
},
{
"cell_type": "markdown",
@@ -1121,11 +1047,10 @@
"source": [
"## Getting Started and Downloading Data\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process latent variable model visualisation of CMU\n",
"motion capture data set."
- ],
- "id": "02eef5d8-f42b-4f6e-8ab8-a3899d63d748"
+ ]
},
{
"cell_type": "markdown",
@@ -1648,8 +1529,8 @@
"source": [
"## Example: Latent Doodle Space\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: First two principal compoents of the Guo et al. (2010)\n",
"blastocyst development data."
- ],
- "id": "cb180b8e-0d98-4e4b-9a31-45f69a70c4ef"
+ ]
},
{
"cell_type": "markdown",
@@ -1929,11 +1792,11 @@
"source": [
"## GP-LVM on the Data\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Visualisation of the Guo et al. (2010) blastocyst development\n",
"data with the GP-LVM."
- ],
- "id": "e6ac4dfe-dfb8-43f3-a393-41f99ddc9c95"
+ ]
},
{
"cell_type": "code",
@@ -2018,19 +1875,17 @@
"model.kern.plot_ARD(ax=ax)\n",
"\n",
"mlai.write_figure('singlecell-gplvm-ard.svg', directory='./gplvm')"
- ],
- "id": "2dfbebe7-e5d3-474b-a650-433b7a62c877"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: The ARD parameters of the GP-LVM for the Guo et al. (2010)\n",
"blastocyst development data."
- ],
- "id": "1ea16f3e-8b8a-4b92-9c7f-ce838d8e81d3"
+ ]
},
{
"cell_type": "markdown",
@@ -2038,8 +1893,8 @@
"source": [
"## Blastocyst Data: Isomap\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Visualisation of the Guo et al. (2010) blastocyst development\n",
"data with Isomap."
- ],
- "id": "98ae65bb-869f-4389-8ea9-611449e404d8"
+ ]
},
{
"cell_type": "markdown",
@@ -2118,8 +1967,8 @@
"source": [
"## Blastocyst Data: Locally Linear Embedding\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Visualisation of the Guo et al. (2010) blastocyst development\n",
"data with a locally linear embedding."
- ],
- "id": "9de37d2a-46bc-4b26-aa33-8f6d5162d396"
+ ]
},
{
"cell_type": "markdown",
@@ -2212,8 +2055,7 @@
" Page](http://www.theguardian.com/profile/neil-lawrence)\n",
"- blog:\n",
" [http://inverseprobability.com](http://inverseprobability.com/blog.html)"
- ],
- "id": "5ef2a144-c3b5-4cd2-89bc-1bca493f9701"
+ ]
},
{
"cell_type": "markdown",
@@ -2273,8 +2115,7 @@
"Tipping, M.E., Bishop, C.M., 1999a. Probabilistic principal component\n",
"analysis. Journal of the Royal Statistical Society, B 6, 611–622.\n",
"\n",
+ "\n",
"\n",
"Figure: GPy is a BSD licensed software code base for implementing\n",
"Gaussian process models in Python. It is designed for teaching and\n",
diff --git a/_notebooks/10-bayesian-learning-gplvm.ipynb b/_notebooks/10-bayesian-learning-gplvm.ipynb
index a73605d..e8ca1c1 100644
--- a/_notebooks/10-bayesian-learning-gplvm.ipynb
+++ b/_notebooks/10-bayesian-learning-gplvm.ipynb
@@ -27,6 +27,8 @@
"metadata": {},
"source": [
"\n",
+ "\n",
+ "\n",
"\n",
"\n",
"\n",
@@ -208,7 +210,7 @@
"to use interface to GPs. One which allowed the user to focus on the\n",
"modelling rather than the mathematics.\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: GPy is a BSD licensed software code base for implementing\n",
"Gaussian process models in Python. It is designed for teaching and\n",
@@ -491,16 +493,16 @@
"class=\"editsection\"\n",
"style=\"\">edit\\]\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: The Yale Faces data set shows different people under\n",
"different lighting conditions\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: ARD Demonstrates not all of the latent space is used.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Other applications include inferring pose from silhouette"
]
@@ -520,9 +522,699 @@
"metadata": {},
"source": [
"Figure: A short video description of the Manifold Relevance\n",
- "Determination method as published at ICML 2012\n",
+ "Determination method as published at ICML 2012"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {},
+ "source": [
+ "## Getting Started and Downloading Data\n",
+ "\n",
+ "\\[\n",
"\n",
- "\n",
+ "Figure: First two principal compoents of the Guo et al. (2010)\n",
+ "blastocyst development data."
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {},
+ "source": [
+ "## Bayesian GP-LVM\n",
+ "\n",
+ "\\[
 \n",
+ "\n",
+ "Figure: Visualisation of the Guo et al. (2010) blastocyst development\n",
+ "data with the Bayesian GP-LVM."
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "fig, ax = plt.subplots(figsize=plot.big_wide_figsize)\n",
+ "model.kern.plot_ARD(ax=ax)\n",
+ "\n",
+ "mlai.write_figure('singlecell-bayes-gplvm-ard.svg', directory='./gplvm')"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {},
+ "source": [
+ "
 \n",
+ "\n",
+ "Figure: The ARD parameters of the Bayesian GP-LVM for the Guo et al.\n",
+ "(2010) blastocyst development data.\n",
+ "\n",
+ "This gives a really nice result. Broadly speaking two latent dimensions\n",
+ "dominate the representation. When we visualize using these two\n",
+ "dimensions we can see the entire cell phylogeny laid out nicely in the\n",
+ "two dimensions."
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {},
+ "source": [
+ "## Thanks!\n",
+ "\n",
+ "For more information on these subjects and more you might want to check\n",
+ "the following resources.\n",
+ "\n",
+ "- company: [Trent AI](https://trent.ai)\n",
+ "- book: [The Atomic\n",
+ " Human](https://www.penguin.co.uk/books/455130/the-atomic-human-by-lawrence-neil-d/9780241625248)\n",
+ "- twitter: [@lawrennd](https://twitter.com/lawrennd)\n",
+ "- podcast: [The Talking Machines](http://thetalkingmachines.com)\n",
+ "- newspaper: [Guardian Profile\n",
+ " Page](http://www.theguardian.com/profile/neil-lawrence)\n",
+ "- blog:\n",
+ " [http://inverseprobability.com](http://inverseprobability.com/blog.html)"
+ ]
+ },
+ {
+ "cell_type": "markdown",
+ "metadata": {},
+ "source": [
+ "## References\n",
"\n",
"Damianou, A., 2015. Deep Gaussian processes and variational propagation\n",
"of uncertainty (PhD thesis). University of Sheffield.\n",
@@ -531,6 +1223,12 @@
"for latent variables and uncertain inputs in Gaussian processes. Journal\n",
"of Machine Learning Research 17, 1–62.\n",
"\n",
+ "de Campos, T.E., Babu, B.R., Varma, M., 2009. Character recognition in\n",
+ "natural images, in: Proceedings of the Fourth International Conference\n",
+ "on Computer Vision Theory and Applications - Volume 2: VISAPP,\n",
+ "(VISIGRAPP 2009). INSTICC; SciTePress, pp. 273–280.\n",
+ "\n",
+ "\n",
"\n",
"Figure: GPy is a BSD licensed software code base for implementing\n",
"Gaussian process models in Python. It is designed for teaching and\n",
@@ -246,8 +233,7 @@
"\n",
"The documentation for GPy can be found\n",
"[here](https://gpy.readthedocs.io/en/latest/)."
- ],
- "id": "aea1782a-8ea6-4f9f-a761-fbcc0a3ed0f9"
+ ]
},
{
"cell_type": "markdown",
@@ -255,15 +241,15 @@
"source": [
"## Structure of Priors\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: A deep neural network\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: A deep neural network. Input nodes are shown at the bottom.\n",
"Each hidden layer is the result of applying an affine transformation to\n",
@@ -351,8 +332,7 @@
" f&= \\mathbf{ w}_4 ^\\top\\mathbf{ h}_{3}\n",
"\\end{align*}\n",
"$$"
- ],
- "id": "b25c5cf2-5ced-4dc5-9e2a-da856d610e6b"
+ ]
},
{
"cell_type": "markdown",
@@ -360,8 +340,8 @@
"source": [
"## Overfitting\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Pictorial representation of the low rank form of the matrix\n",
"$\\mathbf{W}$.\n",
@@ -416,8 +393,7 @@
"In practice there is evidence that deep models seek these low rank\n",
"solutions where we expect better generalisation. See e.g. Arora et al.\n",
"(2019);Jacot et al. (2021)."
- ],
- "id": "ae59ddc6-77cc-40c7-a598-423f5e8318a3"
+ ]
},
{
"cell_type": "markdown",
@@ -425,11 +401,10 @@
"source": [
"## Bottleneck Layers in Deep Neural Networks\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Inserting the bottleneck layers introduces a new set of\n",
"variables.\n",
@@ -484,8 +457,7 @@
" \\mathbf{ y}&= \\mathbf{ w}_4 ^\\top \\mathbf{ z}_{3}\n",
"\\end{align}\n",
"$$"
- ],
- "id": "6f2035ce-4d14-41f5-9f03-d677f17ff588"
+ ]
},
{
"cell_type": "markdown",
@@ -493,8 +465,8 @@
"source": [
"## Cascade of Gaussian Processes\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: The DeepFace architecture (Taigman et al., 2014), visualized\n",
"through colors to represent the functional mappings at each layer. There\n",
@@ -548,8 +518,7 @@
"fully-connected layers. Color illustrates feature maps produced at each\n",
"layer. The neural network includes more than 120 million parameters,\n",
"where more than 95% come from the local and fully connected layers."
- ],
- "id": "5c530ef0-00a7-470d-800a-44aa4e40e273"
+ ]
},
{
"cell_type": "markdown",
@@ -557,11 +526,11 @@
"source": [
"### Deep Learning as Pinball\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Deep learning models are composition of simple functions. We\n",
"can think of a pinball machine as an analogy. Each layer of pins\n",
@@ -581,7 +550,7 @@
"Think of the location of the ball on the left-right axis as a single\n",
"number. Our simple pinball machine can only take one number at a time.\n",
"As the ball falls through the machine, each layer of pins can be thought\n",
- "of as a different layer of ‘neurons’. Each layer acts to move the ball\n",
+ "of as a different layer of ‘neurons.’ Each layer acts to move the ball\n",
"from left to right.\n",
"\n",
"In a pinball machine, when the ball gets to the bottom it might fall\n",
@@ -591,13 +560,13 @@
"An image has more than one number associated with it, so it is like\n",
"playing pinball in a *hyper-space*.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: At initialization, the pins, which represent the parameters\n",
"of the function, aren’t in the right place to bring the balls to the\n",
"correct decisions.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: After learning the pins are now in the right place to bring\n",
"the balls to the correct decisions.\n",
@@ -629,8 +598,7 @@
" $$ Or if we view it from the probabilistic perspective we can see that\n",
"a deep Gaussian process is specifying a factorization of the joint\n",
"density, the standard deep model takes the form of a Markov chain."
- ],
- "id": "6370fa9c-2dec-4932-8623-56f19386df1b"
+ ]
},
{
"cell_type": "code",
@@ -639,8 +607,7 @@
"outputs": [],
"source": [
"cmd = install_command('daft')"
- ],
- "id": "8c3509a7-fc80-4d06-9e2f-bca30d94dc73"
+ ]
},
{
"cell_type": "code",
@@ -649,8 +616,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "c60479b2-58f9-4481-81e5-ce619e6dd5e0"
+ ]
},
{
"cell_type": "code",
@@ -659,11 +625,11 @@
"outputs": [],
"source": [
"from matplotlib import rc\n",
+ "from mlai import plot\n",
+ "import mlai\n",
"\n",
- "rc(\"font\", **{'family':'sans-serif','sans-serif':['Helvetica'],'size':30})\n",
- "rc(\"text\", usetex=True)"
- ],
- "id": "b4899adc-c510-4ced-bf32-adf9da122d91"
+ "rc(\"font\", **{'family':'sans-serif','sans-serif':['Helvetica'],'size':30})"
+ ]
},
{
"cell_type": "code",
@@ -672,9 +638,10 @@
"outputs": [],
"source": [
"pgm = plot.horizontal_chain(depth=5)\n",
- "pgm.render().figure.savefig(\"./deepgp/deep-markov.svg\", transparent=True)"
- ],
- "id": "e1f06e27-f3e2-4ebc-92ce-67e9c5f3ab1a"
+ "mlai.write_figure('deep-markov.svg',\n",
+ " figure=pgm.render().figure,\n",
+ " directory='./deepgp')"
+ ]
},
{
"cell_type": "markdown",
@@ -684,13 +651,12 @@
" p(\\mathbf{ y}|\\mathbf{ x})= p(\\mathbf{ y}|\\mathbf{ f}_5)p(\\mathbf{ f}_5|\\mathbf{ f}_4)p(\\mathbf{ f}_4|\\mathbf{ f}_3)p(\\mathbf{ f}_3|\\mathbf{ f}_2)p(\\mathbf{ f}_2|\\mathbf{ f}_1)p(\\mathbf{ f}_1|\\mathbf{ x})\n",
" $$\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Probabilistically the deep Gaussian process can be\n",
"represented as a Markov chain. Indeed they can even be analyzed in this\n",
"way (Dunlop et al., n.d.)."
- ],
- "id": "9b916746-21bc-448a-aea1-ea04593fad69"
+ ]
},
{
"cell_type": "code",
@@ -699,10 +665,11 @@
"outputs": [],
"source": [
"from matplotlib import rc\n",
- "rc(\"font\", **{'family':'sans-serif','sans-serif':['Helvetica'], 'size':15})\n",
- "rc(\"text\", usetex=True)"
- ],
- "id": "e0db8165-a2d6-4ae6-9182-88ad41625848"
+ "from mlai import plot\n",
+ "import mlai\n",
+ "\n",
+ "rc(\"font\", **{'family':'sans-serif','sans-serif':['Helvetica'], 'size':15})"
+ ]
},
{
"cell_type": "code",
@@ -711,20 +678,20 @@
"outputs": [],
"source": [
"pgm = plot.vertical_chain(depth=5)\n",
- "pgm.render().figure.savefig(\"./deepgp/deep-markov-vertical.svg\", transparent=True)"
- ],
- "id": "0c6d23c5-f13e-49aa-9708-48d8bfac81d9"
+ "mlai.write_figure('deep-markov-vertical.svg',\n",
+ " figure=pgm.render().figure,\n",
+ " directory='./deepgp')"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: More usually deep probabilistic models are written vertically\n",
"rather than horizontally as in the Markov chain."
- ],
- "id": "75c06df4-889c-4c4c-b9e4-c31cba84a7c5"
+ ]
},
{
"cell_type": "markdown",
@@ -732,8 +699,8 @@
"source": [
"## Why Composition?\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: More generally we aren’t constrained by the Markov chain. We\n",
"can design structures that respect our belief about the underlying\n",
"conditional dependencies. Here we are adding a side note from the\n",
"chain."
- ],
- "id": "e0ba3c6e-a7d9-4a1e-adbe-5331386c2e19"
+ ]
},
{
"cell_type": "markdown",
@@ -823,11 +789,10 @@
"source": [
"## Difficulty for Probabilistic Approaches\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: A two dimensional grid mapped into three dimensions to form a\n",
"two dimensional manifold."
- ],
- "id": "c041a2e8-1394-4123-a382-3bb64b0fae2a"
+ ]
},
{
"cell_type": "code",
@@ -872,20 +834,18 @@
"outputs": [],
"source": [
"plot.non_linear_difficulty_plot_2(diagrams='./dimred/')"
- ],
- "id": "fe740c2f-9ceb-45c6-891d-699b62d0016f"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: A one dimensional line mapped into two dimensions by two\n",
"separate independent functions. Each point can be mapped exactly through\n",
"the mappings."
- ],
- "id": "22d09af0-06a9-4fc4-a7b8-f832b0cc2e22"
+ ]
},
{
"cell_type": "code",
@@ -894,8 +854,7 @@
"outputs": [],
"source": [
"cmd = install_command('daft')"
- ],
- "id": "6c0d7d3d-e6de-4764-8893-86ee5857e1bf"
+ ]
},
{
"cell_type": "code",
@@ -904,8 +863,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "d9206cc2-ce84-4d81-aa91-5f5f4f338084"
+ ]
},
{
"cell_type": "code",
@@ -914,19 +872,17 @@
"outputs": [],
"source": [
"plot.non_linear_difficulty_plot_1(diagrams='./dimred')"
- ],
- "id": "0450f425-e467-42d8-8ca6-fe32056894bc"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: A Gaussian density over the input of a non linear function\n",
"leads to a very non Gaussian output. Here the output is multimodal."
- ],
- "id": "3fd488d0-46fd-45fe-b23e-bfe95fcbf3fa"
+ ]
},
{
"cell_type": "markdown",
@@ -934,8 +890,8 @@
"source": [
"## Standard Variational Approach Fails\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Even the latest work on Bayesian neural networks has severe\n",
"problems handling uncertainty. In this example, (Izmailov et al., 2019),\n",
@@ -1011,8 +966,7 @@
"composition. Composing Gaussian processes is analytically intractable.\n",
"To form deep Gaussian processes we use a variational approach to stack\n",
"the models."
- ],
- "id": "5a7ba7fb-fc9f-4ef7-b357-fa96d6908176"
+ ]
},
{
"cell_type": "markdown",
@@ -1020,11 +974,10 @@
"source": [
"## Stacked PCA\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Composition of linear functions just leads to a new linear\n",
"function. Here you see the result of multiple affine transformations\n",
@@ -1124,8 +1072,7 @@
"\\mathbf{V}& \\mathbf{V}\\mathbf{W}_1^\\top & \\mathbf{V}\\mathbf{W}_1^\\top \\mathbf{W}_2^\\top& \\dots & \\mathbf{V}\\mathbf{V}^\\top\n",
"\\end{bmatrix}\\right)$$ which is a highly structured Gaussian covariance\n",
"with hierarchical dependencies between the variables $\\mathbf{Z}_i$."
- ],
- "id": "f432877e-7e35-4541-a226-a1767e9c66c2"
+ ]
},
{
"cell_type": "markdown",
@@ -1133,11 +1080,10 @@
"source": [
"## Stacked GP\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Stacking Gaussian process models leads to non linear mappings\n",
"at each stage. Here we are mapping from two dimensions to two dimensions\n",
@@ -1210,8 +1153,7 @@
"each layer). In practice, the form of this covariance can be learnt and\n",
"the densities described by the deep GP are more general than those\n",
"mentioned in either of these papers."
- ],
- "id": "71e6456f-6dc9-497e-afa9-d34d9bd07f02"
+ ]
},
{
"cell_type": "markdown",
@@ -1219,11 +1161,10 @@
"source": [
"## Stacked GPs (video by David Duvenaud)\n",
"\n",
- "\\[\\[\n",
+ "\n",
"Image from [Wikimedia\n",
"Commons](https://commons.wikimedia.org/wiki/File:Eliud_Kipchoge_in_Berlin_-_2015_(cropped).jpg)\n",
"\n",
@@ -1336,8 +1270,7 @@
"modelling. The data consists of the pace of Olympic Gold Medal Marathon\n",
"winners for the Olympics from 1896 to present. Let’s load in the data\n",
"and plot."
- ],
- "id": "6a4416b3-cd58-4ad7-bab2-554643cd7bbe"
+ ]
},
{
"cell_type": "code",
@@ -1346,8 +1279,7 @@
"outputs": [],
"source": [
"cmd = install_command('pods')"
- ],
- "id": "ff2b3b10-7d2e-4f7f-8c5f-77c0b322a748"
+ ]
},
{
"cell_type": "code",
@@ -1356,8 +1288,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "8d701eba-68b5-48cf-8771-fe90c9bd4d49"
+ ]
},
{
"cell_type": "code",
@@ -1367,8 +1298,7 @@
"source": [
"import numpy as np\n",
"import pods"
- ],
- "id": "29951349-44f6-41a3-9b25-7988fcc8ad47"
+ ]
},
{
"cell_type": "code",
@@ -1383,8 +1313,7 @@
"offset = y.mean()\n",
"scale = np.sqrt(y.var())\n",
"yhat = (y - offset)/scale"
- ],
- "id": "24a56a6d-68f1-48ed-b302-8d8928019780"
+ ]
},
{
"cell_type": "code",
@@ -1395,8 +1324,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "343f202c-29ff-4547-8b61-59abc69e0806"
+ ]
},
{
"cell_type": "code",
@@ -1404,7 +1332,6 @@
"metadata": {},
"outputs": [],
"source": [
- "\n",
"xlim = (1876,2044)\n",
"ylim = (2.5, 6.5)\n",
"\n",
@@ -1417,14 +1344,13 @@
"\n",
"mlai.write_figure(filename='olympic-marathon.svg', \n",
" directory='./datasets')"
- ],
- "id": "4da3c973-8276-4bfa-adb2-f18ae6b78761"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Olympic marathon pace times since 1896.\n",
"\n",
@@ -1433,8 +1359,7 @@
"challenges with dust kicked up by the cars following the race meant that\n",
"participants got lost, and only very few participants completed. More\n",
"recent years see more consistently quick marathons."
- ],
- "id": "750c4085-39ac-4840-9a86-a8b97478109d"
+ ]
},
{
"cell_type": "markdown",
@@ -1442,13 +1367,13 @@
"source": [
"## Alan Turing\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: Alan Turing, in 1946 he was only 11 minutes slower than the\n",
"winner of the 1948 games. Would he have won a hypothetical games held in\n",
@@ -1465,7 +1390,7 @@
"\\text{data} + \\text{model} \\stackrel{\\text{compute}}{\\rightarrow} \\text{prediction}\n",
"$$ then we see that without a model we can’t generalise: we only have\n",
"data. Data is fine for answering very specific questions, like “Who won\n",
- "the Olympic Marathon in 2012?”, because we have that answer stored,\n",
+ "the Olympic Marathon in 2012?” because we have that answer stored,\n",
"however, we are not given the answer to many other questions. For\n",
"example, Alan Turing was a formidable marathon runner, in 1946 he ran a\n",
"time 2 hours 46 minutes (just under four minutes per kilometer, faster\n",
@@ -1477,8 +1402,7 @@
"To answer this question we need to generalize, but before we formalize\n",
"the concept of generalization let’s introduce some formal representation\n",
"of what it means to generalize in machine learning."
- ],
- "id": "99ad44be-3e6a-4310-aca5-40dc92f44dac"
+ ]
},
{
"cell_type": "markdown",
@@ -1486,15 +1410,14 @@
"source": [
"## Gaussian Process Fit\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: Gaussian process fit to the Olympic Marathon data. The error\n",
"bars are too large, perhaps due to the outlier from 1904."
- ],
- "id": "55f478ea-ff3c-41b9-a3e7-487481a7dbd6"
+ ]
},
{
"cell_type": "markdown",
@@ -1602,8 +1517,7 @@
"1904, ignoring that point we can see that a tighter fit is obtained. To\n",
"see this make a version of the model, `m_clean`, where that point is\n",
"removed."
- ],
- "id": "ff1db227-7e10-4ef0-8a3d-aa24a306da3a"
+ ]
},
{
"cell_type": "code",
@@ -1616,8 +1530,7 @@
"\n",
"m_clean = GPy.models.GPRegression(x_clean,y_clean)\n",
"_ = m_clean.optimize()"
- ],
- "id": "e82790a8-b167-4175-b457-58b916feb6ce"
+ ]
},
{
"cell_type": "code",
@@ -1628,8 +1541,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "4f161831-b799-49ba-8b38-d00c7a3f97ec"
+ ]
},
{
"cell_type": "code",
@@ -1644,19 +1556,17 @@
"mlai.write_figure(figure=fig,\n",
" filename='./gp/olympic-marathon-gp-outlier-removed.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "76433dcb-a6fb-49ef-b143-a30472b969cb"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Gaussian process fit to the Olympic Marathon data. Here we’ve\n",
"removed the outlier from 1904."
- ],
- "id": "77b449f4-75b2-446a-a4c8-8eddac4abffb"
+ ]
},
{
"cell_type": "markdown",
@@ -1664,8 +1574,8 @@
"source": [
"## Deep GP Fit\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Deep GP fit to the Olympic marathon data. Error bars now\n",
"change as the prediction evolves."
- ],
- "id": "1e7c8857-4584-4579-ae46-7b5ddd115b9e"
+ ]
},
{
"cell_type": "code",
@@ -1798,8 +1698,7 @@
"ax.set_ylim(ylim)\n",
"mlai.write_figure(figure=fig, filename='./deepgp/olympic-marathon-deep-gp-samples.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "8ba86de9-3108-472b-b656-043e7ef7ba83"
+ ]
},
{
"cell_type": "markdown",
@@ -1807,12 +1706,11 @@
"source": [
"## Olympic Marathon Data Deep GP\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Point samples run through the deep Gaussian process show the\n",
"distribution of output locations."
- ],
- "id": "88e64f98-8540-4bc2-a62e-6545fa9edae1"
+ ]
},
{
"cell_type": "markdown",
@@ -1822,8 +1720,7 @@
"\n",
"Now we explore the GPs the model has used to fit each layer. First of\n",
"all, we look at the hidden layer."
- ],
- "id": "f26edeaf-b0cd-4feb-9302-27e727204675"
+ ]
},
{
"cell_type": "code",
@@ -1835,8 +1732,7 @@
" ylabel='pace min/km',xlim=xlim, ylim=ylim,\n",
" dataset='olympic-marathon',\n",
" diagrams='./deepgp')"
- ],
- "id": "42941b81-fa31-433e-88ce-613dba3e4b09"
+ ]
},
{
"cell_type": "code",
@@ -1845,8 +1741,7 @@
"outputs": [],
"source": [
"import notutils as nu"
- ],
- "id": "6ba20e39-3eb5-4905-9a17-a5d7cbc78077"
+ ]
},
{
"cell_type": "code",
@@ -1856,24 +1751,22 @@
"source": [
"nu.display_plots('olympic-marathon-deep-gp-layer-{sample:0>1}.svg', \n",
" './deepgp', sample=(0,1))"
- ],
- "id": "54442225-b7ba-4887-8f23-3cf9fc66d872"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: The mapping from input to the latent layer is broadly, with\n",
"some flattening as time goes on. Variance is high across the input\n",
"range.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: The mapping from the latent layer to the output layer."
- ],
- "id": "2675a69f-3519-462d-bd5b-78daede3d16c"
+ ]
},
{
"cell_type": "code",
@@ -1886,8 +1779,7 @@
" xlabel='year', ylabel='pace km/min', vertical=True)\n",
"mlai.write_figure(figure=fig, filename='./deepgp/olympic-marathon-deep-gp-pinball.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "121cb1e0-cfff-47ce-b5c2-ebd3f416c905"
+ ]
},
{
"cell_type": "markdown",
@@ -1895,7 +1787,7 @@
"source": [
"## Olympic Marathon Pinball Plot\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: A pinball plot shows the movement of the ‘ball’ as it passes\n",
"through each layer of the Gaussian processes. Mean directions of\n",
@@ -1916,8 +1808,7 @@
"inputs more strongly to the right. This input layer of uncertainty,\n",
"followed by a layer that pushes inputs to the right is what gives the\n",
"heteroschedastic noise."
- ],
- "id": "bb5155b5-d8ce-49f3-8985-5d7bc92f7add"
+ ]
},
{
"cell_type": "markdown",
@@ -1925,8 +1816,8 @@
"source": [
"## Gene Expression Example\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: Gene expression levels over time for a gene from data\n",
"provided by Della Gatta et al. (2008). We would like to understand\n",
@@ -2029,9 +1913,9 @@
"- Want to detect if a gene is expressed or not, fit a GP to each gene\n",
" Kalaitzis and Lawrence (2011).\n",
"\n",
- "\\freddieKalaitzisPicture{15%}\n",
+ "\\\\freddieKalaitzisPicture{15%}\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: The example is taken from the paper “A Simple Approach to\n",
"Ranking Differentially Expressed Gene Expression Time Courses through\n",
@@ -2046,8 +1930,7 @@
"Our first objective will be to perform a Gaussian process fit to the\n",
"data, we’ll do this using the [GPy\n",
"software](https://github.com/SheffieldML/GPy)."
- ],
- "id": "1ad95f78-d57e-4194-ac26-aa2e20afd1bc"
+ ]
},
{
"cell_type": "code",
@@ -2056,8 +1939,7 @@
"outputs": [],
"source": [
"import GPy"
- ],
- "id": "099c281c-2e30-44d0-acce-4c4c3e6a6f31"
+ ]
},
{
"cell_type": "code",
@@ -2068,8 +1950,7 @@
"m_full = GPy.models.GPRegression(x,yhat)\n",
"m_full.kern.lengthscale=50\n",
"_ = m_full.optimize() # Optimize parameters of covariance function"
- ],
- "id": "a0183d6e-36ad-46cb-9e2a-1a0b5529ba2c"
+ ]
},
{
"cell_type": "markdown",
@@ -2079,8 +1960,7 @@
"*time scale* of the covariance function) to a reasonable value. Default\n",
"would be 1, but here we set it to 50 minutes, given points are arriving\n",
"across zero to 250 minutes."
- ],
- "id": "7a6be17c-6a96-4900-a122-45911dc7c891"
+ ]
},
{
"cell_type": "code",
@@ -2091,16 +1971,14 @@
"xt = np.linspace(-20,260,200)[:,np.newaxis]\n",
"yt_mean, yt_var = m_full.predict(xt)\n",
"yt_sd=np.sqrt(yt_var)"
- ],
- "id": "02e049be-a866-477f-b94d-5ecfe0c554e2"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"Now we plot the results using the helper function in `mlai.plot`."
- ],
- "id": "4b31ecd4-6c0c-4717-8bc3-3ed6d413b866"
+ ]
},
{
"cell_type": "code",
@@ -2109,8 +1987,7 @@
"outputs": [],
"source": [
"import mlai.plot as plot"
- ],
- "id": "b9749f08-4745-41ad-80aa-798782abd223"
+ ]
},
{
"cell_type": "code",
@@ -2126,21 +2003,19 @@
"mlai.write_figure(figure=fig,\n",
" filename='./gp/della-gatta-gene-gp.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "476840c9-af75-4b9c-b16d-c1e332e881fc"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Result of the fit of the Gaussian process model with the time\n",
"scale parameter initialized to 50 minutes.\n",
"\n",
"Now we try a model initialized with a longer length scale."
- ],
- "id": "465741ce-f28a-4215-a821-073147ab1611"
+ ]
},
{
"cell_type": "code",
@@ -2151,8 +2026,7 @@
"m_full2 = GPy.models.GPRegression(x,yhat)\n",
"m_full2.kern.lengthscale=2000\n",
"_ = m_full2.optimize() # Optimize parameters of covariance function"
- ],
- "id": "6d6c7383-799f-498b-831b-dc7379d9235b"
+ ]
},
{
"cell_type": "code",
@@ -2161,8 +2035,7 @@
"outputs": [],
"source": [
"import mlai.plot as plot"
- ],
- "id": "5ceef475-70b0-442a-982d-43d77bd8d7ba"
+ ]
},
{
"cell_type": "code",
@@ -2178,21 +2051,19 @@
"mlai.write_figure(figure=fig,\n",
" filename='./gp/della-gatta-gene-gp2.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "6c4b152a-70f3-4bc9-b4e7-96f6d5ae1456"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Result of the fit of the Gaussian process model with the time\n",
"scale parameter initialized to 2000 minutes.\n",
"\n",
"Now we try a model initialized with a lower noise."
- ],
- "id": "0d93476d-e868-4d7a-a911-1942e82d26c4"
+ ]
},
{
"cell_type": "code",
@@ -2204,8 +2075,7 @@
"m_full3.kern.lengthscale=20\n",
"m_full3.likelihood.variance=0.001\n",
"_ = m_full3.optimize() # Optimize parameters of covariance function"
- ],
- "id": "3d9dd0fc-436c-4a56-a48e-6ebe50b533a5"
+ ]
},
{
"cell_type": "code",
@@ -2214,8 +2084,7 @@
"outputs": [],
"source": [
"import mlai.plot as plot"
- ],
- "id": "83f54671-76ef-41b3-9f25-c3a8dc390d5d"
+ ]
},
{
"cell_type": "code",
@@ -2231,20 +2100,18 @@
"mlai.write_figure(figure=fig,\n",
" filename='./gp/della-gatta-gene-gp3.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "c956c5f6-5925-4e38-b996-ed6eb821564a"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Result of the fit of the Gaussian process model with the\n",
"noise initialized low (standard deviation 0.1) and the time scale\n",
"parameter initialized to 20 minutes."
- ],
- "id": "08ea45fb-18a6-4e0a-9848-d2be466d68a9"
+ ]
},
{
"cell_type": "code",
@@ -2253,8 +2120,7 @@
"outputs": [],
"source": [
"import mlai.plot as plot"
- ],
- "id": "796b269b-2c38-4bc5-90d8-7951895e975a"
+ ]
},
{
"cell_type": "code",
@@ -2263,20 +2129,19 @@
"outputs": [],
"source": [
"plot.multiple_optima(directory='./gp')"
- ],
- "id": "d4439daf-393c-4382-9b9d-7387e141f286"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: \n",
"\n",
"\n",
+ "-->\n",
"\n",
"The deep Gaussian process code we are using is research code by Andreas\n",
"Damianou.\n",
@@ -2284,8 +2149,7 @@
"To extend the research code we introduce some approaches to\n",
"initialization and optimization that we’ll use in examples. These\n",
"approaches live in the `mlai.deepgp_tutorial` module."
- ],
- "id": "aa454782-06fe-4eb4-b3c1-8d6d0da87043"
+ ]
},
{
"cell_type": "code",
@@ -2294,8 +2158,7 @@
"outputs": [],
"source": [
"cmd = install_command('mlai')"
- ],
- "id": "8d67ae50-39d3-433f-b5bc-8a00242c8e0f"
+ ]
},
{
"cell_type": "code",
@@ -2304,8 +2167,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "3f1ee49c-f166-43f0-8f87-3d875b6b03fe"
+ ]
},
{
"cell_type": "markdown",
@@ -2314,8 +2176,7 @@
"Deep Gaussian process models also can require some thought in the\n",
"initialization. Here we choose to start by setting the noise variance to\n",
"be one percent of the data variance."
- ],
- "id": "e7b7d690-97d3-457e-a523-d29dd4cd7275"
+ ]
},
{
"cell_type": "code",
@@ -2326,8 +2187,7 @@
"from mlai.deepgp_tutorial import initialize\n",
"import inspect\n",
"file_path = inspect.getfile(initialize)"
- ],
- "id": "3224213c-be05-45fa-9a19-2de597bb859b"
+ ]
},
{
"cell_type": "code",
@@ -2336,8 +2196,7 @@
"outputs": [],
"source": [
"%load -s initialize {file_path}"
- ],
- "id": "f4f0c6dd-865d-4131-b1a7-8c6e1be7604e"
+ ]
},
{
"cell_type": "markdown",
@@ -2366,8 +2225,7 @@
"data-fit.\n",
"\n",
"Finally, all parameters of the model are optimized together."
- ],
- "id": "d1dc8408-bbd2-4287-8c7c-8fc805701f3c"
+ ]
},
{
"cell_type": "code",
@@ -2378,8 +2236,7 @@
"from mlai.deepgp_tutorial import staged_optimize\n",
"import inspect\n",
"file_path = inspect.getfile(staged_optimize)"
- ],
- "id": "03cc2c58-7e11-4943-b3d8-32c80042b214"
+ ]
},
{
"cell_type": "code",
@@ -2388,8 +2245,7 @@
"outputs": [],
"source": [
"%load -s staged_optimize {file_path}"
- ],
- "id": "3cd899e7-2c38-4ff3-86f3-064ae907f350"
+ ]
},
{
"cell_type": "markdown",
@@ -2398,8 +2254,7 @@
"The next code is for visualizing the intermediate layers of the deep\n",
"model. This visualization is only appropriate for models with\n",
"intermediate layers containing a single latent variable."
- ],
- "id": "50e92999-f67b-4fef-b486-a4d681604298"
+ ]
},
{
"cell_type": "code",
@@ -2410,8 +2265,7 @@
"from mlai.deepgp_tutorial import visualize\n",
"import inspect\n",
"file_path = inspect.getfile(visualize)"
- ],
- "id": "e59c1ebf-c6e2-4324-89d0-e16f07622af0"
+ ]
},
{
"cell_type": "code",
@@ -2420,8 +2274,7 @@
"outputs": [],
"source": [
"%load -s visualize {file_path}"
- ],
- "id": "2a1ed0ba-40f0-4f14-ba03-a9afcdaf0913"
+ ]
},
{
"cell_type": "markdown",
@@ -2431,8 +2284,7 @@
"model. It shows how a ball would fall through the model to end up in the\n",
"right pbosition. This visualization is only appropriate for models with\n",
"intermediate layers containing a single latent variable."
- ],
- "id": "20731e8c-efd1-4f19-a505-ce156cba5d21"
+ ]
},
{
"cell_type": "code",
@@ -2443,8 +2295,7 @@
"from mlai.deepgp_tutorial import visualize_pinball\n",
"import inspect\n",
"file_path = inspect.getfile(visualize_pinball)"
- ],
- "id": "8a0f9035-b48a-4d10-84bd-dd171e82ed62"
+ ]
},
{
"cell_type": "code",
@@ -2453,8 +2304,7 @@
"outputs": [],
"source": [
"%load -s visualize_pinball {file_path}"
- ],
- "id": "202d7e52-6c25-4871-a703-0acd6402dba7"
+ ]
},
{
"cell_type": "markdown",
@@ -2463,8 +2313,7 @@
"The `posterior_sample` code allows us to see the output sample locations\n",
"for a given input. This is useful for visualizing the non-Gaussian\n",
"nature of the output density."
- ],
- "id": "ccf3b6f3-4c9b-48df-bbbe-55ad623772ec"
+ ]
},
{
"cell_type": "code",
@@ -2475,8 +2324,7 @@
"from mlai.deepgp_tutorial import posterior_sample\n",
"import inspect\n",
"file_path = inspect.getfile(posterior_sample)"
- ],
- "id": "07988277-a518-45ca-9371-f02f934fabad"
+ ]
},
{
"cell_type": "code",
@@ -2485,16 +2333,14 @@
"outputs": [],
"source": [
"%load -s posterior_sample {file_path}"
- ],
- "id": "a591dfb0-d343-46d9-a4ff-ba363ff88f1b"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"Finally, we bind these methods to the DeepGP object for ease of calling."
- ],
- "id": "67f72c22-c41b-400a-a37c-070f4bfcbb93"
+ ]
},
{
"cell_type": "code",
@@ -2507,8 +2353,7 @@
"deepgp.DeepGP.posterior_sample = posterior_sample\n",
"deepgp.DeepGP.visualize=visualize\n",
"deepgp.DeepGP.visualize_pinball=visualize_pinball"
- ],
- "id": "38be9116-4909-4067-b21e-414ae2f0f7be"
+ ]
},
{
"cell_type": "code",
@@ -2525,8 +2370,7 @@
" inits=inits, \n",
" kernels=kernels, # the kernels for each layer\n",
" num_inducing=20, back_constraint=False)"
- ],
- "id": "aacf67ac-3483-44be-ad14-d6a6f6132725"
+ ]
},
{
"cell_type": "code",
@@ -2536,8 +2380,7 @@
"source": [
"m.initialize()\n",
"m.staged_optimize()"
- ],
- "id": "deb78dd7-726f-43ec-9d2b-19e7757f9725"
+ ]
},
{
"cell_type": "code",
@@ -2551,8 +2394,7 @@
"ax.set_xlim(xlim)\n",
"mlai.write_figure(filename=\"./deepgp/della-gatta-gene-deep-gp.svg\", \n",
" transparent=True, frameon=True)"
- ],
- "id": "814d18a0-2d35-4140-91ba-2ccb1551bd96"
+ ]
},
{
"cell_type": "markdown",
@@ -2560,16 +2402,15 @@
"source": [
"## Della Gatta Gene Data Deep GP\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Deep Gaussian process fit to the Della Gatta gene expression\n",
"data."
- ],
- "id": "6a33c4ce-d8d7-45c9-a8f0-079231b8270e"
+ ]
},
{
"cell_type": "code",
@@ -2583,8 +2424,7 @@
"ax.set_xlim(xlim)\n",
"mlai.write_figure(figure=fig, filename='./deepgp/della-gatta-gene-deep-gp-samples.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "2c6eadbd-1218-4e36-96ab-4c1a114e4c0d"
+ ]
},
{
"cell_type": "markdown",
@@ -2592,12 +2432,11 @@
"source": [
"## Della Gatta Gene Data Deep GP\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Deep Gaussian process samples fitted to the Della Gatta gene\n",
"expression data."
- ],
- "id": "2e9b75c8-2eb1-4097-a6a8-7cb35cd2ac44"
+ ]
},
{
"cell_type": "code",
@@ -2608,8 +2447,7 @@
"m.visualize(offset=offset, scale=scale, xlim=xlim, ylim=ylim,\n",
" dataset=\"della-gatta-gene\",\n",
" diagrams=\"./deepgp\")"
- ],
- "id": "e38c888b-38db-4cbc-a852-07694dd8e4bc"
+ ]
},
{
"cell_type": "markdown",
@@ -2617,12 +2455,11 @@
"source": [
"## Della Gatta Gene Data Latent 1\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process mapping from input to latent layer for the\n",
"della Gatta gene expression data."
- ],
- "id": "09d67b70-9a0a-499c-a6e6-4b28868ed4fb"
+ ]
},
{
"cell_type": "markdown",
@@ -2630,12 +2467,11 @@
"source": [
"## Della Gatta Gene Data Latent 2\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process mapping from latent to output layer for the\n",
"della Gatta gene expression data."
- ],
- "id": "4e6c5fac-7e7b-4100-b7be-6f4947daf90c"
+ ]
},
{
"cell_type": "code",
@@ -2647,8 +2483,7 @@
"m.visualize_pinball(offset=offset, ax=ax, scale=scale, xlim=xlim, ylim=ylim, portion=0.1, points=50)\n",
"mlai.write_figure(figure=fig, filename=\"./deepgp/della-gatta-gene-deep-gp-pinball.svg\", \n",
" transparent=True, frameon=True, ax=ax)"
- ],
- "id": "c6c61602-8d84-42d3-9b8e-13a950ca958d"
+ ]
},
{
"cell_type": "markdown",
@@ -2656,7 +2491,7 @@
"source": [
"## TP53 Gene Pinball Plot\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: A pinball plot shows the movement of the ‘ball’ as it passes\n",
"through each layer of the Gaussian processes. Mean directions of\n",
@@ -2664,8 +2499,7 @@
"movement position. At each layer, the uncertainty is reset. The overal\n",
"uncertainty is the cumulative uncertainty from all the layers. Pinball\n",
"plot of the della Gatta gene expression data."
- ],
- "id": "f872ac4d-69ed-4b65-9dd1-d1f3eef3221a"
+ ]
},
{
"cell_type": "markdown",
@@ -2673,13 +2507,12 @@
"source": [
"## Step Function\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Simulation study of step function data artificially\n",
"generated. Here there is a small overlap between the two lines."
- ],
- "id": "c70f632a-6cba-4441-acaf-941b155c5db7"
+ ]
},
{
"cell_type": "markdown",
@@ -2740,8 +2570,7 @@
"\n",
"We can fit a Gaussian process to the step function data using `GPy` as\n",
"follows."
- ],
- "id": "23404983-d93e-45f5-95b6-c652c8a2da05"
+ ]
},
{
"cell_type": "code",
@@ -2751,8 +2580,7 @@
"source": [
"m_full = GPy.models.GPRegression(x,yhat)\n",
"_ = m_full.optimize() # Optimize parameters of covariance function"
- ],
- "id": "04d8c6aa-eb79-40ea-8309-204f67972854"
+ ]
},
{
"cell_type": "markdown",
@@ -2763,8 +2591,7 @@
"\n",
"The model is optimized using `m_full.optimize()` which calls an L-BGFS\n",
"gradient based solver in python."
- ],
- "id": "a4e04e49-d5bc-4246-a8fa-16d0f47e1951"
+ ]
},
{
"cell_type": "code",
@@ -2779,14 +2606,13 @@
"\n",
"mlai.write_figure(figure=fig,filename='./gp/step-function-gp.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "1e3a5467-7f3d-4b08-9050-3362b99c7c87"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process fit to the step function data. Note the\n",
"large error bars and the over-smoothing of the discontinuity. Error bars\n",
@@ -2800,8 +2626,7 @@
"They can be optimized as part of the model fit. But if new, unforeseen,\n",
"discontinuities arise when the model is being deployed in practice,\n",
"these won’t be accounted for in the predictions."
- ],
- "id": "e2cdc2b4-b170-483a-a10e-c2cb61da1a0a"
+ ]
},
{
"cell_type": "markdown",
@@ -2809,8 +2634,8 @@
"source": [
"## Step Function Data Deep GP\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Deep Gaussian process fit to the step function data."
- ],
- "id": "6f99964c-5c11-4bdb-b6f7-ed4e491fd773"
+ ]
},
{
"cell_type": "markdown",
@@ -2908,8 +2726,7 @@
"\n",
"The samples of the model can be plotted with the helper function from\n",
"`mlai.plot`, `model_sample`"
- ],
- "id": "afdbd3cc-0ef3-40c6-8d4a-c0a1cc38053c"
+ ]
},
{
"cell_type": "code",
@@ -2918,8 +2735,7 @@
"outputs": [],
"source": [
"import mlai.plot as plot"
- ],
- "id": "fe59753e-6ad3-43ab-bf33-615790037d73"
+ ]
},
{
"cell_type": "code",
@@ -2934,8 +2750,7 @@
"ax.set_xlim(xlim)\n",
"mlai.write_figure(figure=fig, filename='./deepgp/step-function-deep-gp-samples.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "4c59b091-0e4d-40a2-8c65-d9d7c6081fe2"
+ ]
},
{
"cell_type": "markdown",
@@ -2946,15 +2761,14 @@
"They make clear that the data points lie, in output mainly at 0 or 1, or\n",
"occasionally in between.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Samples from the deep Gaussian process model for the step\n",
"function fit.\n",
"\n",
"The visualize code allows us to inspect the intermediate layers in the\n",
"deep GP model to understand how it has reconstructed the step function."
- ],
- "id": "41fa988d-6e59-4b3b-8661-1ef29da9ec40"
+ ]
},
{
"cell_type": "code",
@@ -2965,25 +2779,23 @@
"m.visualize(offset=offset, scale=scale, xlim=xlim, ylim=ylim,\n",
" dataset='step-function',\n",
" diagrams='./deepgp')"
- ],
- "id": "6afd9d8f-92a2-4f16-a764-f493c5fec0a7"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
- "
 \n",
- "
 \n",
- "
 \n",
+ "
 \n",
+ "
 \n",
+ "
 \n",
+ "
 \n",
"\n",
"Figure: From top to bottom, the Gaussian process mapping function\n",
"that makes up each layer of the resulting deep Gaussian process.\n",
"\n",
"A pinball plot can be created for the resulting model to understand how\n",
"the input is being translated to the output across the different layers."
- ],
- "id": "1d7e4813-86f3-46bb-8189-32d3e855e03e"
+ ]
},
{
"cell_type": "code",
@@ -2994,8 +2806,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "d875c48a-332d-43d8-a506-4bef8e318aa9"
+ ]
},
{
"cell_type": "code",
@@ -3007,22 +2818,20 @@
"m.visualize_pinball(offset=offset, ax=ax, scale=scale, xlim=xlim, ylim=ylim, portion=0.1, points=50)\n",
"mlai.write_figure(figure=fig, filename='./deepgp/step-function-deep-gp-pinball.svg', \n",
" transparent=True, frameon=True, ax=ax)"
- ],
- "id": "d392a0ac-aae2-4841-b71b-cd9d2bf69e02"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Pinball plot of the deep GP fitted to the step function data.\n",
"Each layer of the model pushes the ‘ball’ towards the left or right,\n",
"saturating at 1 and 0. This causes the final density to be be peaked at\n",
"0 and 1. Transitions occur driven by the uncertainty of the mapping in\n",
"each layer."
- ],
- "id": "84bb88d0-3957-4d4d-b03a-7dd664ea38fc"
+ ]
},
{
"cell_type": "code",
@@ -3031,8 +2840,7 @@
"outputs": [],
"source": [
"import pods"
- ],
- "id": "d6e738fb-c95b-423b-81fa-8db383f6bb68"
+ ]
},
{
"cell_type": "code",
@@ -3046,8 +2854,7 @@
"scale=np.sqrt(y.var())\n",
"offset=y.mean()\n",
"yhat = (y - offset)/scale"
- ],
- "id": "ad52692d-c2de-4b16-9fe8-cb7982d12c75"
+ ]
},
{
"cell_type": "code",
@@ -3058,8 +2865,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai\n",
"import mlai.plot as plot"
- ],
- "id": "9308d373-ec69-4caa-a7c4-f107851c016c"
+ ]
},
{
"cell_type": "code",
@@ -3077,8 +2883,7 @@
"ax.set_ylim(ylim)\n",
"mlai.write_figure(filename='motorcycle-helmet.svg', directory='./datasets/',\n",
" transparent=True, frameon=True)"
- ],
- "id": "45db3de5-ec05-4afa-a0c5-395005688724"
+ ]
},
{
"cell_type": "markdown",
@@ -3086,18 +2891,17 @@
"source": [
"## Motorcycle Helmet Data\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Motorcycle helmet data. The data consists of acceleration\n",
"readings on a motorcycle helmet undergoing a collision. The data\n",
"exhibits heteroschedastic (time varying) noise levles and\n",
"non-stationarity."
- ],
- "id": "3b0432bc-7751-42fe-9f98-fb1509fb7477"
+ ]
},
{
"cell_type": "code",
@@ -3107,8 +2911,7 @@
"source": [
"m_full = GPy.models.GPRegression(x,yhat)\n",
"_ = m_full.optimize() # Optimize parameters of covariance function"
- ],
- "id": "5586c47f-1bef-4297-b8f1-7e77cb827daf"
+ ]
},
{
"cell_type": "code",
@@ -3119,8 +2922,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "795e4d54-7e55-4be3-a6fb-8b38c8f517af"
+ ]
},
{
"cell_type": "code",
@@ -3136,8 +2938,7 @@
"ax.set_xlim(xlim)\n",
"mlai.write_figure(figure=fig,filename='./gp/motorcycle-helmet-gp.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "ba6fbc4a-2c7b-4de9-b632-9ede8f497f20"
+ ]
},
{
"cell_type": "markdown",
@@ -3145,16 +2946,15 @@
"source": [
"## Motorcycle Helmet Data GP\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process fit to the motorcycle helmet accelerometer\n",
"data."
- ],
- "id": "e3601938-c3e8-44d6-a99a-b292a99d9636"
+ ]
},
{
"cell_type": "markdown",
@@ -3162,11 +2962,10 @@
"source": [
"## Motorcycle Helmet Data Deep GP\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Deep Gaussian process fit to the motorcycle helmet\n",
"accelerometer data."
- ],
- "id": "e5934fdb-8422-438e-a2af-97044a4cafd4"
+ ]
},
{
"cell_type": "code",
@@ -3256,8 +3049,7 @@
"source": [
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "dbae2058-04da-40f0-bfb9-73599e113f66"
+ ]
},
{
"cell_type": "code",
@@ -3272,8 +3064,7 @@
"\n",
"mlai.write_figure(figure=fig, filename='./deepgp/motorcycle-helmet-deep-gp-samples.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "737d0f67-a5c6-4265-9fd7-b6c962919bfa"
+ ]
},
{
"cell_type": "markdown",
@@ -3281,12 +3072,11 @@
"source": [
"## Motorcycle Helmet Data Deep GP\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Samples from the deep Gaussian process as fitted to the\n",
"motorcycle helmet accelerometer data."
- ],
- "id": "640a2c4a-818b-4ff2-abbf-16d938e51723"
+ ]
},
{
"cell_type": "code",
@@ -3298,8 +3088,7 @@
" xlabel=\"time\", ylabel=\"acceleration/$g$\", portion=0.5,\n",
" dataset='motorcycle-helmet',\n",
" diagrams='./deepgp')"
- ],
- "id": "a0895caa-81ba-4629-a629-019b1d47e89c"
+ ]
},
{
"cell_type": "markdown",
@@ -3307,12 +3096,11 @@
"source": [
"## Motorcycle Helmet Data Latent 1\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Mappings from the input to the latent layer for the\n",
"motorcycle helmet accelerometer data."
- ],
- "id": "3b3c6ed8-f8dc-4d0f-8597-b1b38240438b"
+ ]
},
{
"cell_type": "markdown",
@@ -3320,12 +3108,11 @@
"source": [
"## Motorcycle Helmet Data Latent 2\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Mappings from the latent layer to the output layer for the\n",
"motorcycle helmet accelerometer data."
- ],
- "id": "c474cd7e-fb16-478a-a410-5de3849dd4b7"
+ ]
},
{
"cell_type": "code",
@@ -3338,8 +3125,7 @@
" points=50, scale=scale, offset=offset, portion=0.1)\n",
"mlai.write_figure(figure=fig, filename='./deepgp/motorcycle-helmet-deep-gp-pinball.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "97993576-0ba6-404a-8344-2a4adb978ad3"
+ ]
},
{
"cell_type": "markdown",
@@ -3347,12 +3133,11 @@
"source": [
"## Motorcycle Helmet Pinball Plot\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Pinball plot for the mapping from input to output layer for\n",
"the motorcycle helmet accelerometer data."
- ],
- "id": "59a77a50-1dbf-4581-985b-c84953932a28"
+ ]
},
{
"cell_type": "markdown",
@@ -3372,8 +3157,7 @@
" Page](http://www.theguardian.com/profile/neil-lawrence)\n",
"- blog:\n",
" [http://inverseprobability.com](http://inverseprobability.com/blog.html)"
- ],
- "id": "5501eb03-0495-484a-be33-ad472176c42e"
+ ]
},
{
"cell_type": "markdown",
@@ -3381,23 +3165,21 @@
"source": [
"## References\n",
"\n",
- "Arora, S., Cohen, N., Golowich, N., Hu, W., 2019. [A convergence\n",
- "analysis of gradient descent for deep linear neural\n",
- "networks](https://openreview.net/forum?id=SkMQg3C5K7), in: International\n",
+ "Arora, S., Cohen, N., Golowich, N., Hu, W., 2019. A convergence analysis\n",
+ "of gradient descent for deep linear neural networks, in: International\n",
"Conference on Learning Representations.\n",
"\n",
"Bui, T., Hernandez-Lobato, D., Hernandez-Lobato, J., Li, Y., Turner, R.,\n",
- "2016. [Deep Gaussian processes for regression using approximate\n",
- "expectation propagation](http://proceedings.mlr.press/v48/bui16.html),\n",
- "in: Balcan, M.F., Weinberger, K.Q. (Eds.), Proceedings of the 33rd\n",
- "International Conference on Machine Learning, Proceedings of Machine\n",
- "Learning Research. PMLR, New York, New York, USA, pp. 1472–1481.\n",
- "\n",
- "Cho, Y., Saul, L.K., 2009. [Kernel methods for deep\n",
- "learning](http://papers.nips.cc/paper/3628-kernel-methods-for-deep-learning.pdf),\n",
- "in: Bengio, Y., Schuurmans, D., Lafferty, J.D., Williams, C.K.I.,\n",
- "Culotta, A. (Eds.), Advances in Neural Information Processing Systems\n",
- "22. Curran Associates, Inc., pp. 342–350.\n",
+ "2016. Deep Gaussian processes for regression using approximate\n",
+ "expectation propagation, in: Balcan, M.F., Weinberger, K.Q. (Eds.),\n",
+ "Proceedings of the 33rd International Conference on Machine Learning,\n",
+ "Proceedings of Machine Learning Research. PMLR, New York, New York, USA,\n",
+ "pp. 1472–1481.\n",
+ "\n",
+ "Cho, Y., Saul, L.K., 2009. Kernel methods for deep learning, in: Bengio,\n",
+ "Y., Schuurmans, D., Lafferty, J.D., Williams, C.K.I., Culotta, A.\n",
+ "(Eds.), Advances in Neural Information Processing Systems 22. Curran\n",
+ "Associates, Inc., pp. 342–350.\n",
"\n",
"Damianou, A., 2015. Deep Gaussian processes and variational propagation\n",
"of uncertainty (PhD thesis). University of Sheffield.\n",
@@ -3412,29 +3194,27 @@
"profiling and reverse engineering. Genome Research 18, 939–948.\n",
"\n",
+ "\n",
"\n",
"Figure: GPy is a BSD licensed software code base for implementing\n",
"Gaussian process models in Python. It is designed for teaching and\n",
@@ -246,8 +233,7 @@
"\n",
"The documentation for GPy can be found\n",
"[here](https://gpy.readthedocs.io/en/latest/)."
- ],
- "id": "e4019974-573d-443d-bb4b-cacb696f68c7"
+ ]
},
{
"cell_type": "markdown",
@@ -255,16 +241,15 @@
"source": [
"## Robot Wireless Data\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Ground truth movement for the position taken while recording\n",
"the multivariate time-course of wireless access point signal\n",
@@ -338,8 +318,7 @@
"\n",
"We will ignore this ground truth in making our predictions, but see if\n",
"the model can recover something similar in one of the latent layers."
- ],
- "id": "374ccf9d-9346-4909-8487-ea6328ff0862"
+ ]
},
{
"cell_type": "code",
@@ -350,8 +329,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai\n",
"import mlai.plot"
- ],
- "id": "fd7d3cdd-ebf6-4789-9575-e1d918b379dc"
+ ]
},
{
"cell_type": "code",
@@ -376,8 +354,7 @@
"mlai.write_figure(figure=fig, \n",
" filename='robot-wireless-dim-' + str(output_dim) + '.svg', \n",
" directory='./datasets')"
- ],
- "id": "def50d0c-c053-4ec0-85e0-6e3494aaaa0b"
+ ]
},
{
"cell_type": "code",
@@ -390,8 +367,7 @@
"offset = y.mean()\n",
"scale = np.sqrt(y.var())\n",
"yhat = (y - offset)/scale"
- ],
- "id": "0905128e-9984-4fc7-a021-d5da9da52287"
+ ]
},
{
"cell_type": "markdown",
@@ -399,7 +375,7 @@
"source": [
"## Robot WiFi Data\n",
"\n",
- "One challenge with the data is that the signal strength ‘drops out’.\n",
+ "One challenge with the data is that the signal strength ‘drops out.’\n",
"This is because the device only tracks a limited number of wifi access\n",
"points, when one of the access points falls outside the track, the value\n",
"disappears (in the plot below it reads -0.5). The data is missing, but\n",
@@ -407,12 +383,11 @@
"access point must be weak to have dropped from the list of those that\n",
"are tracked.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Output dimension 1 from the robot wireless data. This plot\n",
"shows signal strength changing over time."
- ],
- "id": "ecd06ada-cb0d-432a-83ea-5bd074ab5e0b"
+ ]
},
{
"cell_type": "markdown",
@@ -421,8 +396,7 @@
"## Gaussian Process Fit to Robot Wireless Data\n",
"\n",
"Perform a Gaussian process fit on the data using GPy."
- ],
- "id": "5f82fad9-f6ce-4382-91aa-e455fc3f301c"
+ ]
},
{
"cell_type": "code",
@@ -432,16 +406,14 @@
"source": [
"m_full = GPy.models.GPRegression(x,yhat)\n",
"_ = m_full.optimize() # Optimize parameters of covariance function"
- ],
- "id": "e3f0a44d-f6c0-48fe-9142-c34172c5999b"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"## Robot WiFi Data GP"
- ],
- "id": "18b01024-ce8d-458f-99d4-e3816031088a"
+ ]
},
{
"cell_type": "code",
@@ -452,14 +424,13 @@
"from matplotlib import pyplot as plt\n",
"import mlai\n",
"import mlai.plot as plot"
- ],
- "id": "e113e8f4-059f-4e41-a53a-08d6abd2e9b8"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process fit to the Robot Wireless dimension 1.\n",
"\n",
@@ -469,8 +440,7 @@
"To extend the research code we introduce some approaches to\n",
"initialization and optimization that we’ll use in examples. These\n",
"approaches live in the `mlai.deepgp_tutorial` module."
- ],
- "id": "42549c6a-c9c9-4158-8d48-b30daf6f33fd"
+ ]
},
{
"cell_type": "code",
@@ -479,8 +449,7 @@
"outputs": [],
"source": [
"cmd = install_command('mlai')"
- ],
- "id": "ed4064a5-45cd-416d-962d-0740c580301f"
+ ]
},
{
"cell_type": "code",
@@ -489,8 +458,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "b5649f80-bc57-4f16-933e-b5c5c35fa2c8"
+ ]
},
{
"cell_type": "markdown",
@@ -499,8 +467,7 @@
"Deep Gaussian process models also can require some thought in the\n",
"initialization. Here we choose to start by setting the noise variance to\n",
"be one percent of the data variance."
- ],
- "id": "257c845b-6750-4cf0-9496-a8cbd2c0eb45"
+ ]
},
{
"cell_type": "code",
@@ -511,8 +478,7 @@
"from mlai.deepgp_tutorial import initialize\n",
"import inspect\n",
"file_path = inspect.getfile(initialize)"
- ],
- "id": "56987f30-afdf-430e-8937-9f068095ba5e"
+ ]
},
{
"cell_type": "code",
@@ -521,8 +487,7 @@
"outputs": [],
"source": [
"%load -s initialize {file_path}"
- ],
- "id": "c7884225-fa7b-4e93-a794-adb8ecb846b6"
+ ]
},
{
"cell_type": "markdown",
@@ -551,8 +516,7 @@
"data-fit.\n",
"\n",
"Finally, all parameters of the model are optimized together."
- ],
- "id": "0621052f-85fd-4554-85d7-f1cc6f5d035a"
+ ]
},
{
"cell_type": "code",
@@ -563,8 +527,7 @@
"from mlai.deepgp_tutorial import staged_optimize\n",
"import inspect\n",
"file_path = inspect.getfile(staged_optimize)"
- ],
- "id": "3ad8afa7-e7bf-4448-982c-e191a48c0644"
+ ]
},
{
"cell_type": "code",
@@ -573,8 +536,7 @@
"outputs": [],
"source": [
"%load -s staged_optimize {file_path}"
- ],
- "id": "a8b89bca-e47c-4659-ade1-d1561c72079a"
+ ]
},
{
"cell_type": "markdown",
@@ -583,8 +545,7 @@
"The next code is for visualizing the intermediate layers of the deep\n",
"model. This visualization is only appropriate for models with\n",
"intermediate layers containing a single latent variable."
- ],
- "id": "90847798-3072-4de4-8e04-1df05900a5ea"
+ ]
},
{
"cell_type": "code",
@@ -595,8 +556,7 @@
"from mlai.deepgp_tutorial import visualize\n",
"import inspect\n",
"file_path = inspect.getfile(visualize)"
- ],
- "id": "5727d340-2d7c-49d2-a9ff-6789f016c68a"
+ ]
},
{
"cell_type": "code",
@@ -605,8 +565,7 @@
"outputs": [],
"source": [
"%load -s visualize {file_path}"
- ],
- "id": "81ab6225-3997-4597-b735-a6894d4304bd"
+ ]
},
{
"cell_type": "markdown",
@@ -616,8 +575,7 @@
"model. It shows how a ball would fall through the model to end up in the\n",
"right pbosition. This visualization is only appropriate for models with\n",
"intermediate layers containing a single latent variable."
- ],
- "id": "8ca4fb0b-2c0a-4a8b-a02e-62c7adae98a3"
+ ]
},
{
"cell_type": "code",
@@ -628,8 +586,7 @@
"from mlai.deepgp_tutorial import visualize_pinball\n",
"import inspect\n",
"file_path = inspect.getfile(visualize_pinball)"
- ],
- "id": "d6c59d23-94c2-4f40-8794-9a4cb044a7b9"
+ ]
},
{
"cell_type": "code",
@@ -638,8 +595,7 @@
"outputs": [],
"source": [
"%load -s visualize_pinball {file_path}"
- ],
- "id": "b334c041-9438-4172-866a-f2378ec33283"
+ ]
},
{
"cell_type": "markdown",
@@ -648,8 +604,7 @@
"The `posterior_sample` code allows us to see the output sample locations\n",
"for a given input. This is useful for visualizing the non-Gaussian\n",
"nature of the output density."
- ],
- "id": "0a708b94-f870-4d88-bdc5-03b6ed8eae97"
+ ]
},
{
"cell_type": "code",
@@ -660,8 +615,7 @@
"from mlai.deepgp_tutorial import posterior_sample\n",
"import inspect\n",
"file_path = inspect.getfile(posterior_sample)"
- ],
- "id": "66f2e75f-a93d-44e1-be38-bec09f2d26f8"
+ ]
},
{
"cell_type": "code",
@@ -670,16 +624,14 @@
"outputs": [],
"source": [
"%load -s posterior_sample {file_path}"
- ],
- "id": "c5eb6895-f5b6-48ad-9923-0ef68759637c"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"Finally, we bind these methods to the DeepGP object for ease of calling."
- ],
- "id": "3dcfdcb6-1184-47c5-89f9-e12e00a630ed"
+ ]
},
{
"cell_type": "code",
@@ -692,8 +644,7 @@
"deepgp.DeepGP.posterior_sample = posterior_sample\n",
"deepgp.DeepGP.visualize=visualize\n",
"deepgp.DeepGP.visualize_pinball=visualize_pinball"
- ],
- "id": "1d85dc55-8a8e-4f59-9e05-e59906acd4f1"
+ ]
},
{
"cell_type": "code",
@@ -706,8 +657,7 @@
"kernels = []\n",
"for i in layers[1:]:\n",
" kernels += [GPy.kern.RBF(i, ARD=True)]"
- ],
- "id": "d45958cc-b0bc-46e5-967c-191f80de046b"
+ ]
},
{
"cell_type": "code",
@@ -719,8 +669,7 @@
" kernels=kernels,\n",
" num_inducing=50, back_constraint=False)\n",
"m.initialize()"
- ],
- "id": "5f1f785b-f5ca-4264-9677-9338a07e0e8d"
+ ]
},
{
"cell_type": "code",
@@ -729,8 +678,7 @@
"outputs": [],
"source": [
"m.staged_optimize(messages=(True,True,True))"
- ],
- "id": "3e967873-9239-4a09-a1be-db1673193737"
+ ]
},
{
"cell_type": "code",
@@ -745,8 +693,7 @@
"ax.set_xlim(xlim)\n",
"mlai.write_figure(figure=fig, filename='./deepgp/robot-wireless-deep-gp-dim-' + str(output_dim)+ '.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "08cf1dee-9d2c-4ddd-8932-0492a00c060e"
+ ]
},
{
"cell_type": "markdown",
@@ -754,16 +701,15 @@
"source": [
"## Robot WiFi Data Deep GP\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Fit of the deep Gaussian process to dimension 1 of the robot\n",
"wireless data."
- ],
- "id": "0de5577e-a1bf-43d0-8504-a1b4b23447a8"
+ ]
},
{
"cell_type": "code",
@@ -778,8 +724,7 @@
"ax.set_xlim(xlim)\n",
"mlai.write_figure(figure=fig, filename='./deepgp/robot-wireless-deep-gp-samples-dim-' + str(output_dim)+ '.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "cfc9cc3e-feb3-4420-9634-74b84e5eb599"
+ ]
},
{
"cell_type": "markdown",
@@ -787,20 +732,18 @@
"source": [
"## Robot WiFi Data Deep GP\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Samples from the deep Gaussian process fit to dimension 1 of\n",
"the robot wireless data."
- ],
- "id": "0d83dd32-4d07-41a6-aec8-1ebf75eb433f"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"## Robot WiFi Data Latent Space"
- ],
- "id": "c17714a1-4688-4494-85b9-47d3faf2d148"
+ ]
},
{
"cell_type": "code",
@@ -818,22 +761,20 @@
"\n",
"mlai.write_figure(figure=fig, filename='./deepgp/robot-wireless-latent-space.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "21745973-cfe7-40fc-8865-80da2f3b9a7c"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Inferred two dimensional latent space from the model for the\n",
"robot wireless data.\n",
"\n",
"This notebook depends on PyDeepGP. This library can be installed via\n",
"pip."
- ],
- "id": "f60af9ad-b60d-479a-bbf2-038c128439cd"
+ ]
},
{
"cell_type": "code",
@@ -842,8 +783,7 @@
"outputs": [],
"source": [
"cmd = install_command('PyDeepGP')"
- ],
- "id": "3ac9cb69-a3f4-4905-a69e-d59b36105bb7"
+ ]
},
{
"cell_type": "code",
@@ -852,8 +792,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "fdc4db58-7fac-4316-8c3f-63b533b4095b"
+ ]
},
{
"cell_type": "code",
@@ -862,8 +801,7 @@
"outputs": [],
"source": [
"cmd = install_command('mlai')"
- ],
- "id": "2e0e4a25-c073-43e2-a0fc-8308fc1218ae"
+ ]
},
{
"cell_type": "code",
@@ -872,8 +810,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "99cb95a1-e7af-4cef-b357-132ff8e77d92"
+ ]
},
{
"cell_type": "code",
@@ -894,8 +831,7 @@
"deepgp.DeepGP.posterior_sample=posterior_sample\n",
"deepgp.DeepGP.visualize=visualize\n",
"deepgp.DeepGP.visualize_pinball=visualize_pinball"
- ],
- "id": "a821b8f7-26d4-455d-ae9c-f41fb01cd3ba"
+ ]
},
{
"cell_type": "markdown",
@@ -903,8 +839,8 @@
"source": [
"## Olympic Marathon Data\n",
"\n",
- "\\[\\[\n",
+ "\n",
"Image from [Wikimedia\n",
"Commons](https://commons.wikimedia.org/wiki/File:Eliud_Kipchoge_in_Berlin_-_2015_(cropped).jpg)\n",
"\n",
@@ -920,8 +856,7 @@
"modelling. The data consists of the pace of Olympic Gold Medal Marathon\n",
"winners for the Olympics from 1896 to present. Let’s load in the data\n",
"and plot."
- ],
- "id": "ac9e1f8e-53ee-4665-aa05-7d39d13ccd15"
+ ]
},
{
"cell_type": "code",
@@ -930,8 +865,7 @@
"outputs": [],
"source": [
"cmd = install_command('pods')"
- ],
- "id": "e7ce27d0-68b2-462c-8de6-35819c7f54f0"
+ ]
},
{
"cell_type": "code",
@@ -940,8 +874,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "8b7aba73-0cfd-41ca-8457-a8e971c61da5"
+ ]
},
{
"cell_type": "code",
@@ -951,8 +884,7 @@
"source": [
"import numpy as np\n",
"import pods"
- ],
- "id": "fe45c3cb-b279-4a93-9624-09899b1479a2"
+ ]
},
{
"cell_type": "code",
@@ -967,8 +899,7 @@
"offset = y.mean()\n",
"scale = np.sqrt(y.var())\n",
"yhat = (y - offset)/scale"
- ],
- "id": "7ccbc7a8-e0df-4cd4-86f3-3dc9987e87ba"
+ ]
},
{
"cell_type": "code",
@@ -979,8 +910,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "4c07dced-dc71-499a-8207-8512f657d843"
+ ]
},
{
"cell_type": "code",
@@ -988,7 +918,6 @@
"metadata": {},
"outputs": [],
"source": [
- "\n",
"xlim = (1876,2044)\n",
"ylim = (2.5, 6.5)\n",
"\n",
@@ -1001,14 +930,13 @@
"\n",
"mlai.write_figure(filename='olympic-marathon.svg', \n",
" directory='./datasets')"
- ],
- "id": "34b71cbe-b24a-4ff5-956c-34feda17f0cb"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Olympic marathon pace times since 1896.\n",
"\n",
@@ -1017,8 +945,7 @@
"challenges with dust kicked up by the cars following the race meant that\n",
"participants got lost, and only very few participants completed. More\n",
"recent years see more consistently quick marathons."
- ],
- "id": "e6fa578a-8de0-44e9-91d5-88b75ca73786"
+ ]
},
{
"cell_type": "markdown",
@@ -1026,13 +953,13 @@
"source": [
"## Alan Turing\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: Alan Turing, in 1946 he was only 11 minutes slower than the\n",
"winner of the 1948 games. Would he have won a hypothetical games held in\n",
@@ -1049,7 +976,7 @@
"\\text{data} + \\text{model} \\stackrel{\\text{compute}}{\\rightarrow} \\text{prediction}\n",
"$$ then we see that without a model we can’t generalise: we only have\n",
"data. Data is fine for answering very specific questions, like “Who won\n",
- "the Olympic Marathon in 2012?”, because we have that answer stored,\n",
+ "the Olympic Marathon in 2012?” because we have that answer stored,\n",
"however, we are not given the answer to many other questions. For\n",
"example, Alan Turing was a formidable marathon runner, in 1946 he ran a\n",
"time 2 hours 46 minutes (just under four minutes per kilometer, faster\n",
@@ -1061,8 +988,7 @@
"To answer this question we need to generalize, but before we formalize\n",
"the concept of generalization let’s introduce some formal representation\n",
"of what it means to generalize in machine learning."
- ],
- "id": "11cca185-aae9-4683-98f5-e0097a82ff1f"
+ ]
},
{
"cell_type": "markdown",
@@ -1070,15 +996,14 @@
"source": [
"## Gaussian Process Fit\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: Gaussian process fit to the Olympic Marathon data. The error\n",
"bars are too large, perhaps due to the outlier from 1904."
- ],
- "id": "79a66aa2-18d0-4213-b7a9-320509cc8e7b"
+ ]
},
{
"cell_type": "markdown",
@@ -1186,8 +1103,7 @@
"1904, ignoring that point we can see that a tighter fit is obtained. To\n",
"see this make a version of the model, `m_clean`, where that point is\n",
"removed."
- ],
- "id": "1a855c90-c9aa-43d5-a7c2-6378d0a258d9"
+ ]
},
{
"cell_type": "code",
@@ -1200,8 +1116,7 @@
"\n",
"m_clean = GPy.models.GPRegression(x_clean,y_clean)\n",
"_ = m_clean.optimize()"
- ],
- "id": "0910925b-663c-46d9-95a9-11966c271e02"
+ ]
},
{
"cell_type": "code",
@@ -1212,8 +1127,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "a73d90a6-24be-4555-ae2d-a7534e8afaeb"
+ ]
},
{
"cell_type": "code",
@@ -1228,19 +1142,17 @@
"mlai.write_figure(figure=fig,\n",
" filename='./gp/olympic-marathon-gp-outlier-removed.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "380d9f65-e7db-4b8d-92aa-3e33ba834cab"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Gaussian process fit to the Olympic Marathon data. Here we’ve\n",
"removed the outlier from 1904."
- ],
- "id": "c16df283-2f11-46da-b53c-a458ef65d881"
+ ]
},
{
"cell_type": "markdown",
@@ -1248,8 +1160,8 @@
"source": [
"## Deep GP Fit\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: Deep GP fit to the Olympic marathon data. Error bars now\n",
"change as the prediction evolves."
- ],
- "id": "cd9f0949-6edc-4b4f-9098-b0e791267cdf"
+ ]
},
{
"cell_type": "code",
@@ -1382,8 +1284,7 @@
"ax.set_ylim(ylim)\n",
"mlai.write_figure(figure=fig, filename='./deepgp/olympic-marathon-deep-gp-samples.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "92fc08e7-c9cd-4c96-8b83-70cd3180b575"
+ ]
},
{
"cell_type": "markdown",
@@ -1391,12 +1292,11 @@
"source": [
"## Olympic Marathon Data Deep GP\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: Point samples run through the deep Gaussian process show the\n",
"distribution of output locations."
- ],
- "id": "85440d05-7ede-49a8-9685-59ea6555cb58"
+ ]
},
{
"cell_type": "markdown",
@@ -1406,8 +1306,7 @@
"\n",
"Now we explore the GPs the model has used to fit each layer. First of\n",
"all, we look at the hidden layer."
- ],
- "id": "6a28347c-8c15-457f-b5a4-8225cfc7ab55"
+ ]
},
{
"cell_type": "code",
@@ -1419,8 +1318,7 @@
" ylabel='pace min/km',xlim=xlim, ylim=ylim,\n",
" dataset='olympic-marathon',\n",
" diagrams='./deepgp')"
- ],
- "id": "f8c5b3c5-5f7e-4b25-8e87-dd9232a4fce9"
+ ]
},
{
"cell_type": "code",
@@ -1429,8 +1327,7 @@
"outputs": [],
"source": [
"import notutils as nu"
- ],
- "id": "11ef1edf-709c-48ad-9d3f-b6eda8585d72"
+ ]
},
{
"cell_type": "code",
@@ -1440,24 +1337,22 @@
"source": [
"nu.display_plots('olympic-marathon-deep-gp-layer-{sample:0>1}.svg', \n",
" './deepgp', sample=(0,1))"
- ],
- "id": "8bf17935-c35a-4d17-89ea-a628e680d155"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: The mapping from input to the latent layer is broadly, with\n",
"some flattening as time goes on. Variance is high across the input\n",
"range.\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: The mapping from the latent layer to the output layer."
- ],
- "id": "b1958960-333b-4135-a3b8-83aaacbdb587"
+ ]
},
{
"cell_type": "code",
@@ -1470,8 +1365,7 @@
" xlabel='year', ylabel='pace km/min', vertical=True)\n",
"mlai.write_figure(figure=fig, filename='./deepgp/olympic-marathon-deep-gp-pinball.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "2dbabebf-c398-44d5-ae2c-03e1fd7dc864"
+ ]
},
{
"cell_type": "markdown",
@@ -1479,7 +1373,7 @@
"source": [
"## Olympic Marathon Pinball Plot\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: A pinball plot shows the movement of the ‘ball’ as it passes\n",
"through each layer of the Gaussian processes. Mean directions of\n",
@@ -1500,8 +1394,7 @@
"inputs more strongly to the right. This input layer of uncertainty,\n",
"followed by a layer that pushes inputs to the right is what gives the\n",
"heteroschedastic noise."
- ],
- "id": "a60e8005-d0d7-4f80-8dfb-2c8c3b1393b9"
+ ]
},
{
"cell_type": "markdown",
@@ -1509,8 +1402,8 @@
"source": [
"## Gene Expression Example\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: Gene expression levels over time for a gene from data\n",
"provided by Della Gatta et al. (2008). We would like to understand\n",
@@ -1613,9 +1499,9 @@
"- Want to detect if a gene is expressed or not, fit a GP to each gene\n",
" Kalaitzis and Lawrence (2011).\n",
"\n",
- "\\freddieKalaitzisPicture{15%}\n",
+ "\\\\freddieKalaitzisPicture{15%}\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: The example is taken from the paper “A Simple Approach to\n",
"Ranking Differentially Expressed Gene Expression Time Courses through\n",
@@ -1630,8 +1516,7 @@
"Our first objective will be to perform a Gaussian process fit to the\n",
"data, we’ll do this using the [GPy\n",
"software](https://github.com/SheffieldML/GPy)."
- ],
- "id": "ee366c20-23e1-47f2-a798-8144343ecaa4"
+ ]
},
{
"cell_type": "code",
@@ -1640,8 +1525,7 @@
"outputs": [],
"source": [
"import GPy"
- ],
- "id": "ef7a41a6-b2a0-420c-b91a-663a5cdab4bb"
+ ]
},
{
"cell_type": "code",
@@ -1652,8 +1536,7 @@
"m_full = GPy.models.GPRegression(x,yhat)\n",
"m_full.kern.lengthscale=50\n",
"_ = m_full.optimize() # Optimize parameters of covariance function"
- ],
- "id": "d1a29311-59f3-45d5-9de3-880b9aa4be74"
+ ]
},
{
"cell_type": "markdown",
@@ -1663,8 +1546,7 @@
"*time scale* of the covariance function) to a reasonable value. Default\n",
"would be 1, but here we set it to 50 minutes, given points are arriving\n",
"across zero to 250 minutes."
- ],
- "id": "33380760-1518-4c0b-8920-fab7215c047f"
+ ]
},
{
"cell_type": "code",
@@ -1675,16 +1557,14 @@
"xt = np.linspace(-20,260,200)[:,np.newaxis]\n",
"yt_mean, yt_var = m_full.predict(xt)\n",
"yt_sd=np.sqrt(yt_var)"
- ],
- "id": "bc02c938-4f71-4530-ad8e-a369ae04789a"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"Now we plot the results using the helper function in `mlai.plot`."
- ],
- "id": "651d7155-3053-47fa-bd00-eb997ff2891d"
+ ]
},
{
"cell_type": "code",
@@ -1693,8 +1573,7 @@
"outputs": [],
"source": [
"import mlai.plot as plot"
- ],
- "id": "5cec07a5-4ec7-44f1-bccb-f5c7b2ad2164"
+ ]
},
{
"cell_type": "code",
@@ -1710,21 +1589,19 @@
"mlai.write_figure(figure=fig,\n",
" filename='./gp/della-gatta-gene-gp.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "e6b3e186-5185-4801-8b45-43969c66b2cc"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Result of the fit of the Gaussian process model with the time\n",
"scale parameter initialized to 50 minutes.\n",
"\n",
"Now we try a model initialized with a longer length scale."
- ],
- "id": "aa5604a1-e94e-4682-bfc6-1f010de4280a"
+ ]
},
{
"cell_type": "code",
@@ -1735,8 +1612,7 @@
"m_full2 = GPy.models.GPRegression(x,yhat)\n",
"m_full2.kern.lengthscale=2000\n",
"_ = m_full2.optimize() # Optimize parameters of covariance function"
- ],
- "id": "6b2c7d7e-6f5d-45bc-857c-33cfdb7aa779"
+ ]
},
{
"cell_type": "code",
@@ -1745,8 +1621,7 @@
"outputs": [],
"source": [
"import mlai.plot as plot"
- ],
- "id": "65a128df-0053-43a0-bed2-a25846008341"
+ ]
},
{
"cell_type": "code",
@@ -1762,21 +1637,19 @@
"mlai.write_figure(figure=fig,\n",
" filename='./gp/della-gatta-gene-gp2.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "0b9cc20c-c51e-4f8e-a5a5-3250a9060e1d"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Result of the fit of the Gaussian process model with the time\n",
"scale parameter initialized to 2000 minutes.\n",
"\n",
"Now we try a model initialized with a lower noise."
- ],
- "id": "431e2a18-ccf9-43a1-92c7-179798d8ae62"
+ ]
},
{
"cell_type": "code",
@@ -1788,8 +1661,7 @@
"m_full3.kern.lengthscale=20\n",
"m_full3.likelihood.variance=0.001\n",
"_ = m_full3.optimize() # Optimize parameters of covariance function"
- ],
- "id": "9c680aa9-f629-4fb7-9943-6874b6cc2392"
+ ]
},
{
"cell_type": "code",
@@ -1798,8 +1670,7 @@
"outputs": [],
"source": [
"import mlai.plot as plot"
- ],
- "id": "576fa519-3c15-470b-b632-fff6c5e8c8e9"
+ ]
},
{
"cell_type": "code",
@@ -1815,20 +1686,18 @@
"mlai.write_figure(figure=fig,\n",
" filename='./gp/della-gatta-gene-gp3.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "53bcea19-82f5-4672-81ff-e23e814924e9"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Result of the fit of the Gaussian process model with the\n",
"noise initialized low (standard deviation 0.1) and the time scale\n",
"parameter initialized to 20 minutes."
- ],
- "id": "3fec7245-054d-44bd-a782-7e20cb80b18e"
+ ]
},
{
"cell_type": "code",
@@ -1837,8 +1706,7 @@
"outputs": [],
"source": [
"import mlai.plot as plot"
- ],
- "id": "04fa827d-caea-452f-bbed-3582a95f1db6"
+ ]
},
{
"cell_type": "code",
@@ -1847,22 +1715,20 @@
"outputs": [],
"source": [
"plot.multiple_optima(directory='./gp')"
- ],
- "id": "4fda449a-e97b-448c-8841-f9f866d12060"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: \n",
"\n",
""
- ],
- "id": "51d937fd-a359-45bb-bfee-3b333ceec3dd"
+ "-->"
+ ]
},
{
"cell_type": "code",
@@ -1879,8 +1745,7 @@
" inits=inits, \n",
" kernels=kernels, # the kernels for each layer\n",
" num_inducing=20, back_constraint=False)"
- ],
- "id": "48e3ef60-d69f-4942-a450-81a6e9bdd3a5"
+ ]
},
{
"cell_type": "code",
@@ -1890,8 +1755,7 @@
"source": [
"m.initialize()\n",
"m.staged_optimize()"
- ],
- "id": "2dfe6d42-6cf5-45b6-b569-b2d5f0767095"
+ ]
},
{
"cell_type": "code",
@@ -1905,8 +1769,7 @@
"ax.set_xlim(xlim)\n",
"mlai.write_figure(filename=\"./deepgp/della-gatta-gene-deep-gp.svg\", \n",
" transparent=True, frameon=True)"
- ],
- "id": "d0f6243f-1696-4bb6-920d-3fed88be1111"
+ ]
},
{
"cell_type": "markdown",
@@ -1914,16 +1777,15 @@
"source": [
"## Della Gatta Gene Data Deep GP\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: Deep Gaussian process fit to the Della Gatta gene expression\n",
"data."
- ],
- "id": "4331e866-2219-47b6-8e49-d7d1a409e601"
+ ]
},
{
"cell_type": "code",
@@ -1937,8 +1799,7 @@
"ax.set_xlim(xlim)\n",
"mlai.write_figure(figure=fig, filename='./deepgp/della-gatta-gene-deep-gp-samples.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "cde013bc-6af6-4e72-a9a5-d1161fcd5f97"
+ ]
},
{
"cell_type": "markdown",
@@ -1946,12 +1807,11 @@
"source": [
"## Della Gatta Gene Data Deep GP\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: Deep Gaussian process samples fitted to the Della Gatta gene\n",
"expression data."
- ],
- "id": "741f4bd9-c71c-45dc-bd7f-6ab8c4fddbd2"
+ ]
},
{
"cell_type": "code",
@@ -1962,8 +1822,7 @@
"m.visualize(offset=offset, scale=scale, xlim=xlim, ylim=ylim,\n",
" dataset=\"della-gatta-gene\",\n",
" diagrams=\"./deepgp\")"
- ],
- "id": "f74837a9-6835-42ff-89fb-ba48b3eb49b4"
+ ]
},
{
"cell_type": "markdown",
@@ -1971,12 +1830,11 @@
"source": [
"## Della Gatta Gene Data Latent 1\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: Gaussian process mapping from input to latent layer for the\n",
"della Gatta gene expression data."
- ],
- "id": "725c37ce-4c9d-4040-a350-4b6c24358831"
+ ]
},
{
"cell_type": "markdown",
@@ -1984,12 +1842,11 @@
"source": [
"## Della Gatta Gene Data Latent 2\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: Gaussian process mapping from latent to output layer for the\n",
"della Gatta gene expression data."
- ],
- "id": "3f4ee6b3-5ca4-43cb-b639-81b898ffc9a4"
+ ]
},
{
"cell_type": "code",
@@ -2001,8 +1858,7 @@
"m.visualize_pinball(offset=offset, ax=ax, scale=scale, xlim=xlim, ylim=ylim, portion=0.1, points=50)\n",
"mlai.write_figure(figure=fig, filename=\"./deepgp/della-gatta-gene-deep-gp-pinball.svg\", \n",
" transparent=True, frameon=True, ax=ax)"
- ],
- "id": "06a89547-44ba-44d4-82c6-43bd8c7f7f0c"
+ ]
},
{
"cell_type": "markdown",
@@ -2010,7 +1866,7 @@
"source": [
"## TP53 Gene Pinball Plot\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: A pinball plot shows the movement of the ‘ball’ as it passes\n",
"through each layer of the Gaussian processes. Mean directions of\n",
@@ -2018,8 +1874,7 @@
"movement position. At each layer, the uncertainty is reset. The overal\n",
"uncertainty is the cumulative uncertainty from all the layers. Pinball\n",
"plot of the della Gatta gene expression data."
- ],
- "id": "d2980c57-01ac-4c3b-9ae2-aa5897dce6be"
+ ]
},
{
"cell_type": "markdown",
@@ -2027,13 +1882,12 @@
"source": [
"## Step Function\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: Simulation study of step function data artificially\n",
"generated. Here there is a small overlap between the two lines."
- ],
- "id": "4714629b-00a1-400d-8ce2-172edfa21714"
+ ]
},
{
"cell_type": "markdown",
@@ -2094,8 +1945,7 @@
"\n",
"We can fit a Gaussian process to the step function data using `GPy` as\n",
"follows."
- ],
- "id": "ace006f4-6aba-42f6-b1d4-6a6b52c1ff1d"
+ ]
},
{
"cell_type": "code",
@@ -2105,8 +1955,7 @@
"source": [
"m_full = GPy.models.GPRegression(x,yhat)\n",
"_ = m_full.optimize() # Optimize parameters of covariance function"
- ],
- "id": "18f93f98-ad0d-4e0a-a0f5-8386f6cf6344"
+ ]
},
{
"cell_type": "markdown",
@@ -2117,8 +1966,7 @@
"\n",
"The model is optimized using `m_full.optimize()` which calls an L-BGFS\n",
"gradient based solver in python."
- ],
- "id": "b77df233-8781-4fbf-99fe-03797970041f"
+ ]
},
{
"cell_type": "code",
@@ -2133,14 +1981,13 @@
"\n",
"mlai.write_figure(figure=fig,filename='./gp/step-function-gp.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "b4aa2997-b7ef-4b54-adbf-471a1825dbeb"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Gaussian process fit to the step function data. Note the\n",
"large error bars and the over-smoothing of the discontinuity. Error bars\n",
@@ -2154,8 +2001,7 @@
"They can be optimized as part of the model fit. But if new, unforeseen,\n",
"discontinuities arise when the model is being deployed in practice,\n",
"these won’t be accounted for in the predictions."
- ],
- "id": "1ef3198c-cb82-4bf1-b7ea-b2a6e4bf3012"
+ ]
},
{
"cell_type": "markdown",
@@ -2163,8 +2009,8 @@
"source": [
"## Step Function Data Deep GP\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: Deep Gaussian process fit to the step function data."
- ],
- "id": "28f7c270-b604-4c09-86fe-602df5fb5c6b"
+ ]
},
{
"cell_type": "markdown",
@@ -2262,8 +2101,7 @@
"\n",
"The samples of the model can be plotted with the helper function from\n",
"`mlai.plot`, `model_sample`"
- ],
- "id": "989ea7ba-6163-4977-9a44-05be98b2347b"
+ ]
},
{
"cell_type": "code",
@@ -2272,8 +2110,7 @@
"outputs": [],
"source": [
"import mlai.plot as plot"
- ],
- "id": "a797c9ad-7bff-408b-92dc-bcd418d6673e"
+ ]
},
{
"cell_type": "code",
@@ -2288,8 +2125,7 @@
"ax.set_xlim(xlim)\n",
"mlai.write_figure(figure=fig, filename='./deepgp/step-function-deep-gp-samples.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "bdecc472-3cba-4285-87c1-8611dab09993"
+ ]
},
{
"cell_type": "markdown",
@@ -2300,15 +2136,14 @@
"They make clear that the data points lie, in output mainly at 0 or 1, or\n",
"occasionally in between.\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: Samples from the deep Gaussian process model for the step\n",
"function fit.\n",
"\n",
"The visualize code allows us to inspect the intermediate layers in the\n",
"deep GP model to understand how it has reconstructed the step function."
- ],
- "id": "d6d41d9b-7bad-4cef-af57-6c3c007c5dc5"
+ ]
},
{
"cell_type": "code",
@@ -2319,25 +2154,23 @@
"m.visualize(offset=offset, scale=scale, xlim=xlim, ylim=ylim,\n",
" dataset='step-function',\n",
" diagrams='./deepgp')"
- ],
- "id": "dc183202-0c6c-4565-943c-2d7cffe191ae"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
- "\n",
- "\n",
- "\n",
+ "\n",
+ "\n",
+ "\n",
+ "\n",
"\n",
"Figure: From top to bottom, the Gaussian process mapping function\n",
"that makes up each layer of the resulting deep Gaussian process.\n",
"\n",
"A pinball plot can be created for the resulting model to understand how\n",
"the input is being translated to the output across the different layers."
- ],
- "id": "b76da6bd-5de6-4ebf-a8b8-276790259514"
+ ]
},
{
"cell_type": "code",
@@ -2348,8 +2181,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "310e525f-0353-43b5-bbdb-3eab9b226b76"
+ ]
},
{
"cell_type": "code",
@@ -2361,22 +2193,20 @@
"m.visualize_pinball(offset=offset, ax=ax, scale=scale, xlim=xlim, ylim=ylim, portion=0.1, points=50)\n",
"mlai.write_figure(figure=fig, filename='./deepgp/step-function-deep-gp-pinball.svg', \n",
" transparent=True, frameon=True, ax=ax)"
- ],
- "id": "c84ab19c-bd53-46ef-82a8-4611f8996c3f"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Pinball plot of the deep GP fitted to the step function data.\n",
"Each layer of the model pushes the ‘ball’ towards the left or right,\n",
"saturating at 1 and 0. This causes the final density to be be peaked at\n",
"0 and 1. Transitions occur driven by the uncertainty of the mapping in\n",
"each layer."
- ],
- "id": "2f8f6cdd-688d-424c-b2e5-a134a0e38e8d"
+ ]
},
{
"cell_type": "code",
@@ -2385,8 +2215,7 @@
"outputs": [],
"source": [
"import pods"
- ],
- "id": "194b0b70-a8a1-4db0-aa53-87b0d81f17d8"
+ ]
},
{
"cell_type": "code",
@@ -2400,8 +2229,7 @@
"scale=np.sqrt(y.var())\n",
"offset=y.mean()\n",
"yhat = (y - offset)/scale"
- ],
- "id": "8979895d-e4b1-40ae-b4dd-82d69fcbc46c"
+ ]
},
{
"cell_type": "code",
@@ -2412,8 +2240,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai\n",
"import mlai.plot as plot"
- ],
- "id": "cdfb108d-a52f-46a0-97dc-93246b75ff2e"
+ ]
},
{
"cell_type": "code",
@@ -2431,8 +2258,7 @@
"ax.set_ylim(ylim)\n",
"mlai.write_figure(filename='motorcycle-helmet.svg', directory='./datasets/',\n",
" transparent=True, frameon=True)"
- ],
- "id": "47b6bb55-0869-4d9a-90d0-ae5de586b2ec"
+ ]
},
{
"cell_type": "markdown",
@@ -2440,18 +2266,17 @@
"source": [
"## Motorcycle Helmet Data\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: Motorcycle helmet data. The data consists of acceleration\n",
"readings on a motorcycle helmet undergoing a collision. The data\n",
"exhibits heteroschedastic (time varying) noise levles and\n",
"non-stationarity."
- ],
- "id": "d237072a-af8b-4fdb-af11-4d4935c9f981"
+ ]
},
{
"cell_type": "code",
@@ -2461,8 +2286,7 @@
"source": [
"m_full = GPy.models.GPRegression(x,yhat)\n",
"_ = m_full.optimize() # Optimize parameters of covariance function"
- ],
- "id": "aaf5f256-cdca-45ec-9edf-f9984d36f545"
+ ]
},
{
"cell_type": "code",
@@ -2473,8 +2297,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "a3ec7ce9-8082-46b2-b5b6-a3b1bdd7b144"
+ ]
},
{
"cell_type": "code",
@@ -2490,8 +2313,7 @@
"ax.set_xlim(xlim)\n",
"mlai.write_figure(figure=fig,filename='./gp/motorcycle-helmet-gp.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "319b40f4-62c3-423e-b133-38395f722a5b"
+ ]
},
{
"cell_type": "markdown",
@@ -2499,16 +2321,15 @@
"source": [
"## Motorcycle Helmet Data GP\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: Gaussian process fit to the motorcycle helmet accelerometer\n",
"data."
- ],
- "id": "7ec11207-2b6c-4eb2-857b-c9260bcdc388"
+ ]
},
{
"cell_type": "markdown",
@@ -2516,11 +2337,10 @@
"source": [
"## Motorcycle Helmet Data Deep GP\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: Deep Gaussian process fit to the motorcycle helmet\n",
"accelerometer data."
- ],
- "id": "b2a19dd8-e434-4d2f-adf8-5b97d6078222"
+ ]
},
{
"cell_type": "code",
@@ -2610,8 +2424,7 @@
"source": [
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "c9d2d02b-da58-4aea-a6e1-dac70bfeb792"
+ ]
},
{
"cell_type": "code",
@@ -2626,8 +2439,7 @@
"\n",
"mlai.write_figure(figure=fig, filename='./deepgp/motorcycle-helmet-deep-gp-samples.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "47989ee5-40f5-447a-acb5-1f1733e0820e"
+ ]
},
{
"cell_type": "markdown",
@@ -2635,12 +2447,11 @@
"source": [
"## Motorcycle Helmet Data Deep GP\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: Samples from the deep Gaussian process as fitted to the\n",
"motorcycle helmet accelerometer data."
- ],
- "id": "37f8d34c-569d-464c-9d60-5424cd40cced"
+ ]
},
{
"cell_type": "code",
@@ -2652,8 +2463,7 @@
" xlabel=\"time\", ylabel=\"acceleration/$g$\", portion=0.5,\n",
" dataset='motorcycle-helmet',\n",
" diagrams='./deepgp')"
- ],
- "id": "3b8a0340-a6b8-4d73-8fdd-a944138f88e3"
+ ]
},
{
"cell_type": "markdown",
@@ -2661,12 +2471,11 @@
"source": [
"## Motorcycle Helmet Data Latent 1\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: Mappings from the input to the latent layer for the\n",
"motorcycle helmet accelerometer data."
- ],
- "id": "d15241dd-e9f8-4d65-8deb-d857b3d2fbe9"
+ ]
},
{
"cell_type": "markdown",
@@ -2674,12 +2483,11 @@
"source": [
"## Motorcycle Helmet Data Latent 2\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: Mappings from the latent layer to the output layer for the\n",
"motorcycle helmet accelerometer data."
- ],
- "id": "32879b25-3bc8-44cf-811e-2b36b6aaaba6"
+ ]
},
{
"cell_type": "code",
@@ -2692,8 +2500,7 @@
" points=50, scale=scale, offset=offset, portion=0.1)\n",
"mlai.write_figure(figure=fig, filename='./deepgp/motorcycle-helmet-deep-gp-pinball.svg', \n",
" transparent=True, frameon=True)"
- ],
- "id": "a4f1ee43-b355-417e-85e8-a0e4df7f7519"
+ ]
},
{
"cell_type": "markdown",
@@ -2701,12 +2508,11 @@
"source": [
"## Motorcycle Helmet Pinball Plot\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: Pinball plot for the mapping from input to output layer for\n",
"the motorcycle helmet accelerometer data."
- ],
- "id": "ff665346-0668-4cb8-bcac-768a1b1e7c00"
+ ]
},
{
"cell_type": "markdown",
@@ -2714,16 +2520,15 @@
"source": [
"## ‘High Five’ Motion Capture Data\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Shared latent variable model structure. Here two related data\n",
"sets are brought together with a set of latent variables that are\n",
"partially shared and partially specific to one of the data sets.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Latent spaces of the ‘high five’ data. The structure of the\n",
"model is automatically learnt. One of the latent spaces is coordinating\n",
"how the two figures walk together, the other latent spaces contain\n",
"latent variables that are specific to each of the figures\n",
"separately."
- ],
- "id": "6567eb3c-711d-464f-81a3-71f9d34a7a8c"
+ ]
},
{
"cell_type": "markdown",
@@ -2839,8 +2635,8 @@
"source": [
"## Subsample of the MNIST Data\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Examples of MNIST digits 0-4 from our subsampled dataset,\n",
"showing 5 examples of each digit.\n",
@@ -2990,8 +2778,7 @@
"The visualization shows the variety in handwritten digits even within\n",
"the same class. Each row represents a different digit (0 through 4), and\n",
"each column shows a different example of that digit."
- ],
- "id": "db18144d-f930-4484-b4e8-03f639bd6fd5"
+ ]
},
{
"cell_type": "markdown",
@@ -2999,16 +2786,15 @@
"source": [
"## Fitting a Deep GP to a the MNIST Digits Subsample\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Latent space for the deep Gaussian process learned through\n",
"unsupervised learning and fitted to a subset of the MNIST digits\n",
"subsample."
- ],
- "id": "957ccd9e-3723-4ea2-8c36-bfd7514804d6"
+ ]
},
{
"cell_type": "markdown",
@@ -3208,8 +2978,7 @@
"\n",
"We can also visualize dimensions of the intermediate layer. First the\n",
"lengthscale of those dimensions is given by"
- ],
- "id": "77370ace-1249-48b2-80fd-9e065eb7b335"
+ ]
},
{
"cell_type": "code",
@@ -3218,8 +2987,7 @@
"outputs": [],
"source": [
"m.obslayer.kern.lengthscale"
- ],
- "id": "ed1c42fe-c77e-4cd5-863d-1a21cdeafbf4"
+ ]
},
{
"cell_type": "code",
@@ -3230,8 +2998,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "e1ce17fd-7615-4b2c-89f8-4f05b9cb7ee1"
+ ]
},
{
"cell_type": "code",
@@ -3252,34 +3019,32 @@
" plt.xlabel('dimension ' + str(dims[0]))\n",
" plt.ylabel('dimension ' + str(dims[1]))\n",
" mlai.write_figure(figure=fig, filename=\"./deepgp/mnist-digits-subsample-hidden-\" + str(dims[0]) + '-' + str(dims[1]) + '.svg', transparent=True)"
- ],
- "id": "3179be4e-c791-43cb-8df9-98dc03ab3128"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Visualisation of the intermediate layer, plot of dimension 1\n",
"vs dimension 0.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Visualisation of the intermediate layer, plot of dimension 1\n",
"vs dimension 0.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Visualisation of the intermediate layer, plot of dimension 1\n",
"vs dimension 0.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Visualisation of the intermediate layer, plot of dimension 1\n",
"vs dimension 0."
- ],
- "id": "c962a414-cc28-45c2-b0b0-c8a9ee49794c"
+ ]
},
{
"cell_type": "markdown",
@@ -3289,8 +3054,7 @@
"\n",
"Now we can take a look at a sample from the model, by drawing a Gaussian\n",
"random sample in the latent space and propagating it through the model."
- ],
- "id": "46ec9886-4597-42e0-99ff-445205cc6480"
+ ]
},
{
"cell_type": "code",
@@ -3298,15 +3062,13 @@
"metadata": {},
"outputs": [],
"source": [
- "\n",
"rows = 10\n",
"cols = 20\n",
"t=np.linspace(-1, 1, rows*cols)[:, None]\n",
"kern = GPy.kern.RBF(1,lengthscale=0.05)\n",
"cov = kern.K(t, t)\n",
"x = np.random.multivariate_normal(np.zeros(rows*cols), cov, num_latent).T"
- ],
- "id": "b6b49150-f15b-42a6-9d8f-c769cd3ad0c7"
+ ]
},
{
"cell_type": "code",
@@ -3317,8 +3079,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "bf39f823-d30f-468d-ac08-18478d0de74d"
+ ]
},
{
"cell_type": "code",
@@ -3337,21 +3098,19 @@
" aspect='equal')\n",
" axs[i,j].set_axis_off()\n",
"mlai.write_figure(figure=fig, filename=\"./deepgp/digit-samples-deep-gp.svg\", transparent=True)"
- ],
- "id": "5f9c9e7f-a93f-49c5-a48d-1b9e69e66376"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: These digits are produced by taking a tour of the two\n",
"dimensional latent space (as described by a Gaussian process sample) and\n",
"mapping the tour into the data space. We visualize the mean of the\n",
"mapping in the images."
- ],
- "id": "3acfc735-490a-499e-8cb4-50ecc2cd5884"
+ ]
},
{
"cell_type": "markdown",
@@ -3359,11 +3118,11 @@
"source": [
"## Deep Health\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: The deep health model uses different layers of abstraction in\n",
"the deep Gaussian process to represent information about diagnostics and\n",
@@ -3376,8 +3135,7 @@
"appearing at the more abstract levels, as we descend the model, we\n",
"express relationships between the more abstract concept, that sits\n",
"within the physician’s mind, and the data we can measure."
- ],
- "id": "892b4aa4-926b-44ba-8698-b3e681f9e65a"
+ ]
},
{
"cell_type": "markdown",
@@ -3397,8 +3155,7 @@
" Page](http://www.theguardian.com/profile/neil-lawrence)\n",
"- blog:\n",
" [http://inverseprobability.com](http://inverseprobability.com/blog.html)"
- ],
- "id": "95f1ff4c-0964-438c-8404-27bd5f4797dc"
+ ]
},
{
"cell_type": "markdown",
@@ -3429,8 +3186,7 @@
"\n",
"Lawrence, N.D., Moore, A.J., 2007. Hierarchical Gaussian process latent\n",
"variable models. pp. 481–488."
- ],
- "id": "8a87e1fe-af80-4abd-8402-6bb815f4ff6e"
+ ]
}
],
"nbformat": 4,
diff --git a/_notebooks/13-emulation.ipynb b/_notebooks/13-emulation.ipynb
index 87f07aa..caab20a 100644
--- a/_notebooks/13-emulation.ipynb
+++ b/_notebooks/13-emulation.ipynb
@@ -11,8 +11,7 @@
"Cambridge\n",
"\n",
"### 2021-09-15"
- ],
- "id": "f03d72ec-85c0-4265-9c62-cdbec1b03b3a"
+ ]
},
{
"cell_type": "markdown",
@@ -20,8 +19,7 @@
"source": [
"**Abstract**: In this session we introduce the notion of emulation and\n",
"systems modeling with Gaussian processes."
- ],
- "id": "ef907f69-a6a7-44e0-86df-d393c93ac7b3"
+ ]
},
{
"cell_type": "markdown",
@@ -29,14 +27,15 @@
"source": [
"$$\n",
"$$"
- ],
- "id": "af1044d3-034e-49bc-88fe-cf242982854f"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"\n",
+ "\n",
+ "\n",
"\n",
"\n",
"\n",
@@ -48,8 +47,7 @@
""
- ],
- "id": "b4ac664b-7852-41fc-8eb3-66dfd40ffe5d"
+ ]
},
{
"cell_type": "markdown",
@@ -57,14 +55,13 @@
"source": [
"## Gaussian Process Summer School notebook setup\n",
"\n",
- "\\[\\[\n",
+ "\n",
"\n",
"Figure: GPy is a BSD licensed software code base for implementing\n",
"Gaussian process models in Python. It is designed for teaching and\n",
@@ -268,8 +253,7 @@
"> the past would be present before its eyes.\n",
">\n",
"> — Pierre Simon Laplace (Laplace, 1814)"
- ],
- "id": "1292be86-3c7b-4036-ab77-9a77e286ca3d"
+ ]
},
{
"cell_type": "markdown",
@@ -277,8 +261,8 @@
"source": [
"## Game of Life\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"
 \n",
+ "
 \n",
"\n",
"
 \n",
+ "
 \n",
"\n",
"
 \n",
+ "
 \n",
"\n",
"
 \n",
+ "
 \n",
"\n",
"\n",
+ "\n",
"\n",
"
 \n",
+ "
 \n",
"\n",
"\n",
+ "\n",
"\n",
"
 \n",
+ "
 \n",
"\n",
"\n",
+ "\n",
"\n",
"
 \n",
+ "
 \n",
"\n",
"\n",
+ "\n",
"\n",
"
 \n",
+ "
 \n",
"\n",
"Figure: Evolution of a simple oscillator (blinker) in the Game of\n",
"Life.\n",
@@ -1117,8 +1071,7 @@
"Life patterns and ultimately for our hybrid system combining Life with\n",
"Wolfram automata. The key is the flexibility in boundary conditions,\n",
"which will allow us to interface with Wolfram rules at the edges."
- ],
- "id": "263bb7d5-c118-458a-9354-f180ac2352b5"
+ ]
},
{
"cell_type": "markdown",
@@ -1126,8 +1079,8 @@
"source": [
"## Spaceships, oscillators and static patterns\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"\n",
+ "\n",
"\n",
"Figure: *Left* A Glider pattern discovered 1969 by Richard K. Guy.\n",
"*Right*. John Horton Conway, creator of *Life* (1937-2020). The glider\n",
@@ -1360,8 +1305,7 @@
"rules being deterministic, we are not ‘omniscient’ in any simplistic\n",
"sense. It requires computation to ‘discover’ what can exist in this\n",
"universe once it’s been defined."
- ],
- "id": "9636371e-71a5-45c6-ab1e-85a12148d06b"
+ ]
},
{
"cell_type": "code",
@@ -1371,14 +1315,13 @@
"source": [
"# Generate Gosper Glider Gun animation\n",
"create_pattern_animation(GOSPER_GLIDER_GUN, steps=50, size=50)"
- ],
- "id": "4f4acead-8c78-41f6-b0d4-da7461b2044b"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: The Gosper glider gun is a configuration that creates\n",
"gliders. A new glider is released after every 30 turns.\n",
@@ -1388,8 +1331,7 @@
"Gosper glider gun was [discovered by Bill Gosper in\n",
"1970](https://conwaylife.com/wiki/Bill_Gosper). It is a pattern that\n",
"creates a new glider every 30 turns of the game."
- ],
- "id": "e80e6959-138f-4727-9268-6642f68b98c7"
+ ]
},
{
"cell_type": "code",
@@ -1399,8 +1341,7 @@
"source": [
"# Generate Loafer animation\n",
"create_pattern_animation(LOAFER, steps=28)"
- ],
- "id": "0aee5263-d2b1-4f39-ac92-63f4fd8de4d0"
+ ]
},
{
"cell_type": "markdown",
@@ -1413,11 +1354,11 @@
"\n",
"
 \n",
+ "
 \n",
"\n",
"\n",
+ "\n",
"\n",
"Figure: *Left* A Loafer pattern discovered by Josh Ball in 2013.\n",
"*Right*. John Horton Conway, creator of *Life* (1937-2020).\n",
@@ -1432,7 +1373,7 @@
"there’s a life pattern that runs a Turing machine, or more remarkably\n",
"there’s a Life pattern that runs Life itself.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: The Game of Life running in Life. The video is drawing out\n",
"recursively showing pixels that are being formed by filling cells with\n",
@@ -1443,8 +1384,7 @@
"To find out more about the Game of Life you can watch this video by Alan\n",
"Zucconi or read his [associated blog\n",
"post](https://www.alanzucconi.com/2020/10/13/conways-game-of-life/)."
- ],
- "id": "f2c63aa1-7e3b-47fc-b6cc-2f6522c32446"
+ ]
},
{
"cell_type": "code",
@@ -1454,8 +1394,7 @@
"source": [
"from IPython.lib.display import YouTubeVideo\n",
"YouTubeVideo('Kk2MH9O4pXY')"
- ],
- "id": "b89415f2-b33b-43e3-b79b-81f876c136bc"
+ ]
},
{
"cell_type": "markdown",
@@ -1475,11 +1414,10 @@
"We summarize this notion as $$\n",
"\\text{data} + \\text{model} \\stackrel{\\text{compute}}{\\rightarrow} \\text{prediction}\n",
"$$ As we pointed out, there is an irony in Laplace’s demon forming the\n",
- "cornerstone of a movement known as ‘determinism’, because Laplace wrote\n",
+ "cornerstone of a movement known as ‘determinism,’ because Laplace wrote\n",
"about this idea in an essay on probabilities. The more important quote\n",
"in the essay was"
- ],
- "id": "0d30a847-47b3-442b-b784-733af1c61bde"
+ ]
},
{
"cell_type": "markdown",
@@ -1487,8 +1425,8 @@
"source": [
"## Laplace’s Gremlin\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Gremlins are seen as the cause of a number of challenges in\n",
"this World War II poster."
- ],
- "id": "4928e826-b853-4104-8c05-11575a2a2f06"
+ ]
},
{
"cell_type": "markdown",
@@ -1548,8 +1485,8 @@
"source": [
"## Simulation System\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Representation of the Carbon Cycle from the US National\n",
"Oceanic and Atmospheric Administration. While everything is\n",
@@ -1570,12 +1507,11 @@
"modelled so we can make judgments about how to mitigate the effects of\n",
"global warming.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: The components of a simulation system for climate\n",
"modelling."
- ],
- "id": "7ca27ff1-98e3-4bce-b717-eb0b24bd5de6"
+ ]
},
{
"cell_type": "markdown",
@@ -1584,7 +1520,7 @@
"## Monolithic System\n",
"\n",
"The classical approach to building these systems was a ‘monolithic\n",
- "system’. Built in a similar way to the successful applications software\n",
+ "system.’ Built in a similar way to the successful applications software\n",
"such as Excel or Word, or large operating systems, a single code base\n",
"was constructed. The complexity of such code bases run to many lines.\n",
"\n",
@@ -1593,11 +1529,10 @@
"millions of lines of code. For example, the Microsoft Office suite is\n",
"said to contain over 30 million lines of code.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: A potential path of models in a machine learning system."
- ],
- "id": "90672d0c-225b-4104-94d1-f5d64762ce2e"
+ ]
},
{
"cell_type": "markdown",
@@ -1611,7 +1546,7 @@
"design](https://en.wikipedia.org/wiki/Obidos_(software)) but by the\n",
"early noughties it was becoming difficult to sustain and maintain. The\n",
"software was phased out in 2006 to be replaced by a modularized software\n",
- "known as a ‘service-oriented architecture’.\n",
+ "known as a ‘service-oriented architecture.’\n",
"\n",
"In Service Oriented Architecture, or “Software as a Service” the idea is\n",
"that code bases are modularized and communicate with one another using\n",
@@ -1623,7 +1558,7 @@
"The simulation software is turned inside out to expose the individual\n",
"components to the operator.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: A potential path of models in a machine learning system.\n",
"\n",
@@ -1640,7 +1575,7 @@
"separated and often run independently. But those components themselves\n",
"are made up of other sub-components that could also be exposed in a\n",
"similar manner to software-as-a-service, giving us the notion of\n",
- "“simulation as a service”.\n",
+ "“simulation as a service.”\n",
"\n",
"One thing about working in an industrial environment, is the way that\n",
"short-term thinking actions become important. For example, in Formula\n",
@@ -1701,7 +1636,7 @@
"\n",
"\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Experiment, analyze and design is a flywheel of knowledge\n",
"that is the dual of the model, data and compute. By running through this\n",
@@ -1736,8 +1671,7 @@
"blog post on [Data Readiness\n",
"Levels](http://inverseprobability.com/2017/01/12/data-readiness-levels).\n",
"and Lawrence (2017);The DELVE Initiative (2020))"
- ],
- "id": "f984aad7-6e7f-4768-ab90-221d4c52b253"
+ ]
},
{
"cell_type": "markdown",
@@ -1745,11 +1679,11 @@
"source": [
"## Statistical Emulation\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: The UK Met office runs a shared code base for its simulations\n",
"of climate and the weather. This plot shows the different spatial and\n",
@@ -1764,24 +1698,24 @@
"but they operate climate simulations at greater spatial and temporal\n",
"resolutions.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Real world systems consist of simulators that capture our\n",
"domain knowledge about how our systems operate. Different simulators run\n",
"at different speeds and granularities.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: A statistical emulator is a system that reconstructs the\n",
"simulation with a statistical model.\n",
"\n",
"A statistical emulator is a data-driven model that learns about the\n",
"underlying simulation. Importantly, learns with uncertainty, so it\n",
- "‘knows what it doesn’t know’. In practice, we can call the emulator in\n",
- "place of the simulator. If the emulator ‘doesn’t know’, it can call the\n",
+ "‘knows what it doesn’t know.’ In practice, we can call the emulator in\n",
+ "place of the simulator. If the emulator ‘doesn’t know,’ it can call the\n",
"simulator for the answer.\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: A statistical emulator is a system that reconstructs the\n",
"simulation with a statistical model. As well as reconstructing the\n",
@@ -1803,8 +1737,7 @@
"deciding what experiment should be run next to aid a decision: should we\n",
"run a simulator, in which case which one, or should we attempt to\n",
"acquire data from a real-world intervention."
- ],
- "id": "72eec09e-b698-4e78-b529-47e3f25cc658"
+ ]
},
{
"cell_type": "markdown",
@@ -1812,8 +1745,8 @@
"source": [
"## GPy and Emulation\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: A Gaussian process fit to the Branin test function, used to\n",
"assess the mean of the function by emulation.\n",
@@ -2093,8 +2005,7 @@
"results of a complex computational fluid dynamics simulation, where each\n",
"run of the simulation (which is equivalent to our test function) took\n",
"many hours. In that case the advantage of the emulator is clear."
- ],
- "id": "655e942b-73c1-460c-9ecc-ce88682c415d"
+ ]
},
{
"cell_type": "code",
@@ -2108,8 +2019,7 @@
"Xp[:,1] = Xp[:,1]*15\n",
"mu, var = model.predict(Xp)\n",
"print('The estimate of the mean of the Branin function is {mean}'.format(mean=np.mean(mu)))"
- ],
- "id": "6f1b0751-3de9-4119-a3ac-b6a499f60bfc"
+ ]
},
{
"cell_type": "markdown",
@@ -2119,8 +2029,7 @@
"\n",
"Now think about how to make use of the variance estimation from the\n",
"Gaussian process to obtain error bars around your estimate."
- ],
- "id": "6c225976-c79a-41e7-90f5-4c62271fb2b2"
+ ]
},
{
"cell_type": "code",
@@ -2133,8 +2042,7 @@
"\n",
"\n",
"\n"
- ],
- "id": "da58fad7-d066-4d63-b341-d31756a7f187"
+ ]
},
{
"cell_type": "markdown",
@@ -2145,8 +2053,7 @@
"You’ve seen how the Monte Carlo estimates work with the Gaussian\n",
"process. Now make your estimate of the probability that the Branin\n",
"function is greater than 200 with the uniform random inputs."
- ],
- "id": "8a064d2f-69ae-477c-81b0-0acbf3c0acfc"
+ ]
},
{
"cell_type": "code",
@@ -2159,8 +2066,7 @@
"\n",
"\n",
"\n"
- ],
- "id": "bd08d252-df3c-4bce-94dd-07cbbc9c2b6b"
+ ]
},
{
"cell_type": "markdown",
@@ -2168,8 +2074,8 @@
"source": [
"## Uncertainty Quantification and Design of Experiments\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: The Emukit software is a set of software tools for emulation\n",
"and surrogate modeling.
 \n",
+ "
 \n",
"\n",
"Figure: The emukit approach to the three parts of emulation."
- ],
- "id": "30b23de3-8c4d-465b-9c48-93087f9004d2"
+ ]
},
{
"cell_type": "markdown",
@@ -2471,8 +2364,7 @@
"design. In addition to provide a framework for decision making Emukit\n",
"provide other tools, like sensitivity analysis, that help to debug and\n",
"interpret emulators. All methods in Emukit are model agnostic."
- ],
- "id": "2c0eede8-b206-462e-8b4d-1a2d7e32a8a2"
+ ]
},
{
"cell_type": "markdown",
@@ -2491,8 +2383,7 @@
"which are designed to help adapting models in particular modelling\n",
"frameworks to Emukit interfaces. - Multi-fidelity models, implemented\n",
"based on GPy."
- ],
- "id": "39fc514d-db1f-4d51-9e2d-f00559e9c4ac"
+ ]
},
{
"cell_type": "markdown",
@@ -2514,8 +2405,7 @@
"machine learnings, statisticians can swap out the relevant part of their\n",
"method and build on the underlying structure. You just need to pick out\n",
"the part that requires implementation."
- ],
- "id": "f1849096-ab7f-4580-8640-76275ccfa087"
+ ]
},
{
"cell_type": "markdown",
@@ -2527,8 +2417,7 @@
"different components come together. There are more specific loops for\n",
"Bayesian optimization and experimental design that construct some of the\n",
"component parts for you."
- ],
- "id": "4bfd4d9d-5102-436f-ba40-4a507d12a1ad"
+ ]
},
{
"cell_type": "markdown",
@@ -2553,8 +2442,7 @@
"predictions and update the model but a model may implement any number of\n",
"other interfaces such as `IDifferentiable` which indicates a model has\n",
"prediction derivatives available."
- ],
- "id": "ef1df50b-141f-4e2f-890c-04f6b36b8281"
+ ]
},
{
"cell_type": "markdown",
@@ -2568,8 +2456,7 @@
"acquisition optimizer to the acquisition function. More complex\n",
"implementations will enable batches of points to be collected so that\n",
"the user function can be evaluated in parallel."
- ],
- "id": "1c03f9d9-1b04-4c93-8bfb-de1eb3475e39"
+ ]
},
{
"cell_type": "markdown",
@@ -2580,8 +2467,7 @@
"The acquisition is a heuristic quantification of how valuable collecting\n",
"a future point might be. It is used by the candidate point calculator to\n",
"decide which point(s) to collect next."
- ],
- "id": "5463ac12-71fc-452b-8956-1d965fdaa468"
+ ]
},
{
"cell_type": "markdown",
@@ -2594,8 +2480,7 @@
"acquisition function gradients if they are available. If gradients of\n",
"the acquisition function are not available, it will either estimate them\n",
"numerically or use a gradient free optimizer."
- ],
- "id": "8f05b3b6-5d0b-4296-a8ef-5112bdd6811f"
+ ]
},
{
"cell_type": "markdown",
@@ -2606,8 +2491,7 @@
"This is the function that we are trying to reason about. It can be\n",
"either evaluated by the user or it can be passed into the loop and\n",
"evaluated by Emukit."
- ],
- "id": "239d9bd9-2479-495b-b09c-c2bb4948df53"
+ ]
},
{
"cell_type": "markdown",
@@ -2619,8 +2503,7 @@
"a new point is observed and optimizes any hyper-parameters of the model.\n",
"It can decide whether hyper-parameters need updating based on some\n",
"internal logic."
- ],
- "id": "a60e4972-1d15-4a2f-832f-8f512370d606"
+ ]
},
{
"cell_type": "markdown",
@@ -2635,8 +2518,7 @@
"You can see more of Emukit being put into practice in [this case study\n",
"on Machine Learning in the Multiverse by Sam\n",
"Bell](https://mlatcl.github.io/mlphysical/casestudies/machine-learning-multiverse.html)."
- ],
- "id": "e0e6525f-aae8-4aff-bfce-59d690727d78"
+ ]
},
{
"cell_type": "markdown",
@@ -2644,11 +2526,11 @@
"source": [
"## Emukit Playground\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: Emukit playground is a tutorial for understanding the\n",
"simulation/emulation relationship.\n",
"
 \n",
+ "
 \n",
"\n",
"Figure: Tutorial on Bayesian optimization of the number of taxis\n",
"deployed from Emukit playground.\n",
"
 \n",
+ "
 \n",
"\n",
"Figure: Experimental design in Emukit using the\n",
"`ExperimentalDesignLoop`: learning function $\\sin(x)$ with Emukit.\n",
"\n",
"Computer the predictions from the Emukit model."
- ],
- "id": "5741600e-cbc5-404f-8271-056b1dd24778"
+ ]
},
{
"cell_type": "code",
@@ -2990,8 +2843,7 @@
"\n",
"predicted_y = np.array(predicted_y).flatten()\n",
"predicted_std = np.array(predicted_std).flatten()"
- ],
- "id": "474a1c07-c4b6-4315-af37-48a4e7d70c63"
+ ]
},
{
"cell_type": "code",
@@ -3014,19 +2866,17 @@
"ax.legend(['true function', 'estimated function'], loc='lower right')\n",
"\n",
"mlai.write_figure('emukit-sine-function-fit.svg', directory='./uq')"
- ],
- "id": "6a2cd2a4-e1aa-483a-a2b1-c0f0426cad99"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: The fit to the sine function after runnning the Emukit\n",
"`ExperimentalDesignLoop`."
- ],
- "id": "8a81943b-2858-416a-ad5c-468b6b48d462"
+ ]
},
{
"cell_type": "markdown",
@@ -3038,8 +2888,7 @@
"`sklearn`. You can see step by step instructions on how to do this in\n",
"[this\n",
"notebook](https://github.com/EmuKit/emukit/blob/master/notebooks/Emukit-tutorial-custom-model.ipynb)."
- ],
- "id": "47811ac9-aef0-4427-9424-57424e5d165e"
+ ]
},
{
"cell_type": "code",
@@ -3052,8 +2901,7 @@
"\n",
"\n",
"\n"
- ],
- "id": "b4aaf9e3-70fc-49bc-8525-10904c2b9b8e"
+ ]
},
{
"cell_type": "markdown",
@@ -3073,8 +2921,7 @@
"of inputs on the outputs of a given system; and *Bayesian quadrature*:\n",
"efficiently compute the integrals of functions that are expensive to\n",
"evaluate. But it’s easy to extend."
- ],
- "id": "17474e99-2651-4ffb-844b-4f60ed678bd9"
+ ]
},
{
"cell_type": "markdown",
@@ -3082,8 +2929,8 @@
"source": [
"## Emukit Sensitivity Analysis\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: The non-zero components of the Ishigami function."
- ],
- "id": "7b0762dd-15d9-4843-b514-f91df1fbd275"
+ ]
},
{
"cell_type": "markdown",
@@ -3542,8 +3362,7 @@
"## Total Variance\n",
"\n",
"The total variance $\\text{var}(y)$ in this example is"
- ],
- "id": "819cd002-5ec1-4df3-a13a-704b0da205a9"
+ ]
},
{
"cell_type": "code",
@@ -3552,8 +3371,7 @@
"outputs": [],
"source": [
"print(ishigami.variance_total)"
- ],
- "id": "5ffc66c7-8b81-4520-acfa-37b9b0a24059"
+ ]
},
{
"cell_type": "markdown",
@@ -3562,8 +3380,7 @@
"which is the sum of the variance of $\\text{var}\\left(g_1(x_1)\\right)$,\n",
"$\\text{var}\\left(g_2(x_2)\\right)$ and\n",
"$\\text{var}\\left(g_{1,3}(x_{1,3})\\right)$"
- ],
- "id": "42201e02-b7b3-45b3-97b0-822bf0a3eccd"
+ ]
},
{
"cell_type": "code",
@@ -3573,8 +3390,7 @@
"source": [
"print(ishigami.variance_x1, ishigami.variance_x2, ishigami.variance_x13)\n",
"print(ishigami.variance_x1 + ishigami.variance_x2 + ishigami.variance_x13)"
- ],
- "id": "0223ff28-73a5-4dfc-bc05-d0b62dae692a"
+ ]
},
{
"cell_type": "markdown",
@@ -3599,8 +3415,7 @@
"In most cases we are interested in the first order indices. The Ishigami\n",
"function has the benefit that these can be computed analytically. In\n",
"`EmuKit` you can extract these values with the code."
- ],
- "id": "64d9ca88-028b-4f25-945b-6c5d57297065"
+ ]
},
{
"cell_type": "code",
@@ -3609,8 +3424,7 @@
"outputs": [],
"source": [
"ishigami.main_effects"
- ],
- "id": "d72f0474-5026-4c99-8c5f-c073f95adb52"
+ ]
},
{
"cell_type": "markdown",
@@ -3622,8 +3436,7 @@
"\n",
"With Emukit, the first-order Sobol indices can be easily computed. We\n",
"first need to define the space where the target simulator is analyzed."
- ],
- "id": "dbf64e6c-6a94-4b85-b788-459886cc5ad6"
+ ]
},
{
"cell_type": "code",
@@ -3632,8 +3445,7 @@
"outputs": [],
"source": [
"from emukit.sensitivity.monte_carlo import ModelFreeMonteCarloSensitivity"
- ],
- "id": "98669bfe-6280-4697-8a4e-7224ca9719f1"
+ ]
},
{
"cell_type": "code",
@@ -3647,8 +3459,7 @@
"senstivity_ishigami = ModelFreeMonteCarloSensitivity(target_simulator, space)\n",
"main_effects, total_effects, _ = senstivity_ishigami.compute_effects(num_monte_carlo_points = num_monte_carlo_points)\n",
"print(main_effects)"
- ],
- "id": "2168955f-bf78-4097-ac35-c7e7d3411cb6"
+ ]
},
{
"cell_type": "markdown",
@@ -3656,8 +3467,7 @@
"source": [
"We compare the true effects with the Monte Carlo effects in a bar-plot.\n",
"The total effects are discussed later."
- ],
- "id": "8168b484-5dc4-429f-827b-4f540f0501c7"
+ ]
},
{
"cell_type": "code",
@@ -3666,8 +3476,7 @@
"outputs": [],
"source": [
"import pandas as pd"
- ],
- "id": "c638f989-5c92-4e72-a522-7e30b150b621"
+ ]
},
{
"cell_type": "code",
@@ -3685,18 +3494,16 @@
"ax.set_ylabel('% of explained output variance')\n",
"\n",
"mlai.write_figure(filename='first-order-sobol-indices-ishigami.svg', directory='./uq')"
- ],
- "id": "1df633d9-a4b8-4dc7-bea5-23ca6582530a"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: The non-zero components of the Ishigami function."
- ],
- "id": "3564fad4-c3a0-468a-9cc8-289f052141fb"
+ ]
},
{
"cell_type": "markdown",
@@ -3718,8 +3525,7 @@
"Note that the sum of $S_{Ti}$ is not necessarily one in this case unless\n",
"the model is additive. In the Ishigami example the value of the total\n",
"effects is"
- ],
- "id": "75d49e09-b203-4147-8c22-97b82930995a"
+ ]
},
{
"cell_type": "code",
@@ -3728,8 +3534,7 @@
"outputs": [],
"source": [
"ishigami.total_effects"
- ],
- "id": "ec5aa7c9-21c3-4ef4-bd29-ca307e1fad05"
+ ]
},
{
"cell_type": "markdown",
@@ -3738,8 +3543,7 @@
"As in the previous example, the total effects can be computed with Monte\n",
"Carlo. In the next plot we show the comparison with the true total\n",
"effects."
- ],
- "id": "47ee8ff3-e611-4f19-aa6b-f4e60dde9bc6"
+ ]
},
{
"cell_type": "code",
@@ -3757,20 +3561,18 @@
"ax.set_ylabel('Effects value')\n",
"\n",
"mlai.write_figure(filename='total-effects-ishigami.svg', directory='./uq')"
- ],
- "id": "c5a5768c-17c7-4e3e-b456-3eac6354a15d"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: The total effects from the Ishigami function as computed via\n",
"Monte Carlo estimate alongside the true total effects for the Ishigami\n",
"function."
- ],
- "id": "d5d54521-cf27-45b1-9900-f48f59912506"
+ ]
},
{
"cell_type": "markdown",
@@ -3796,8 +3598,7 @@
"We start by generating 100 samples in the input domain. Note that this a\n",
"just 1% of the number of samples that we used to compute the Sobol\n",
"coefficients using Monte Carlo."
- ],
- "id": "d791ec10-f78e-481d-9e51-0a8b61e41d93"
+ ]
},
{
"cell_type": "code",
@@ -3806,8 +3607,7 @@
"outputs": [],
"source": [
"from emukit.core.initial_designs import RandomDesign"
- ],
- "id": "affa80ae-7f24-4dca-b85a-8fbcedbbc59b"
+ ]
},
{
"cell_type": "code",
@@ -3818,8 +3618,7 @@
"design = RandomDesign(space)\n",
"x = design.get_samples(500)\n",
"y = ishigami.fidelity1(x)[:,np.newaxis]"
- ],
- "id": "1288ff5d-6cea-40ae-bd49-04ffd3697d11"
+ ]
},
{
"cell_type": "markdown",
@@ -3827,8 +3626,7 @@
"source": [
"Now, we fit a standard Gaussian process to the samples, and we wrap it\n",
"as an Emukit model."
- ],
- "id": "32cf32ea-9b86-4541-bba3-ed82c3c147ec"
+ ]
},
{
"cell_type": "code",
@@ -3839,8 +3637,7 @@
"from GPy.models import GPRegression\n",
"from emukit.model_wrappers import GPyModelWrapper\n",
"from emukit.sensitivity.monte_carlo import MonteCarloSensitivity"
- ],
- "id": "4aa2f700-05bc-48c7-b632-5d3db203f12f"
+ ]
},
{
"cell_type": "code",
@@ -3851,8 +3648,7 @@
"model_gpy = GPRegression(x,y)\n",
"model_emukit = GPyModelWrapper(model_gpy)\n",
"model_emukit.optimize()"
- ],
- "id": "e2552ce1-d12f-4d15-845c-802b70ee522f"
+ ]
},
{
"cell_type": "markdown",
@@ -3864,8 +3660,7 @@
"Sobol indices. We plot the true estimates, those computed using 10000\n",
"direct evaluations of the object using Monte Carlo and those computed\n",
"using a Gaussian process model trained on 100 evaluations."
- ],
- "id": "7af10634-84dc-4787-8b19-0e915bc9e5d9"
+ ]
},
{
"cell_type": "code",
@@ -3876,8 +3671,7 @@
"num_mc = 10000\n",
"senstivity_ishigami_gpbased = MonteCarloSensitivity(model = model_emukit, input_domain = space)\n",
"main_effects_gp, total_effects_gp, _ = senstivity_ishigami_gpbased.compute_effects(num_monte_carlo_points = num_mc)"
- ],
- "id": "986c6d19-d7c1-4ad7-b125-7cc7f3d08c0b"
+ ]
},
{
"cell_type": "code",
@@ -3898,19 +3692,17 @@
"plt.ylabel('% of explained output variance')\n",
"\n",
"mlai.write_figure(filename='first-order-sobol-indices-gp-ishigami.svg', directory='./uq')"
- ],
- "id": "ab7fe8c7-9180-46a4-ace3-fce0a174c1bb"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: First order Sobol indices as estimated by Monte Carlo and\n",
"GP-emulator based Monte Carlo."
- ],
- "id": "fbd88ae4-6855-4bc7-ac47-555686a80cc9"
+ ]
},
{
"cell_type": "code",
@@ -3931,14 +3723,13 @@
"ax.set_ylabel('% of explained output variance')\n",
"\n",
"mlai.write_figure(filename='total-effects-sobol-indices-gp-ishigami.svg', directory='./uq')"
- ],
- "id": "4511387b-f63d-4453-b85c-17b66c033589"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Total effects as estimated by Monte Carlo and GP based Monte\n",
"Carlo.\n",
@@ -3947,8 +3738,7 @@
"Sobol index when using the Gaussian process, but we get a fairly good\n",
"approximation with a very reduced number of evaluations of the original\n",
"target function."
- ],
- "id": "b06eed0f-5293-4fce-9be4-f20de39be4a9"
+ ]
},
{
"cell_type": "markdown",
@@ -3961,8 +3751,7 @@
"approach for computing these indices if the function is cheap to\n",
"evaluate. Other approaches are needed when $g(\\cdot)$ is expensive to\n",
"compute."
- ],
- "id": "8a4a0f79-a996-4feb-b842-7c4fbefd2c9e"
+ ]
},
{
"cell_type": "markdown",
@@ -3970,16 +3759,16 @@
"source": [
"## Catapult Simulation\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: A catapult simulation for experimenting with surrogate\n",
"models, kindly provided by Nicolas Durrande\n",
@@ -4003,8 +3792,7 @@
"\n",
"Because you will need to operate the catapult yourself, we’ll create a\n",
"function to query you about the result of an individual firing."
- ],
- "id": "8d9b5108-a968-4fbd-92ac-81f8673560fe"
+ ]
},
{
"cell_type": "code",
@@ -4013,8 +3801,7 @@
"outputs": [],
"source": [
"import numpy as np"
- ],
- "id": "5814c32a-06e7-4682-94f0-a9838cbf89fc"
+ ]
},
{
"cell_type": "code",
@@ -4038,8 +3825,7 @@
" print('x_4 = {spring_binding_2:.2f} (spring binding 2)'.format(spring_binding_2=spring_binding_2))\n",
" y[i, 0] = float(input('What is the distance? '))\n",
" return y"
- ],
- "id": "9a30fb9f-59d8-4eb3-b967-a190d2c631bf"
+ ]
},
{
"cell_type": "markdown",
@@ -4047,8 +3833,7 @@
"source": [
"We can also set the parameter space for the model. Each of these\n",
"variables is scaled to operate $\\in [0, 1]$."
- ],
- "id": "0ccb0de7-c450-49de-8e64-84103e58faea"
+ ]
},
{
"cell_type": "code",
@@ -4057,8 +3842,7 @@
"outputs": [],
"source": [
"from emukit.core import ContinuousParameter, ParameterSpace"
- ],
- "id": "b0997f45-84e3-4374-b8d6-cb67456a31db"
+ ]
},
{
"cell_type": "code",
@@ -4073,8 +3857,7 @@
" ContinuousParameter('arm_stop', *variable_domain),\n",
" ContinuousParameter('spring_binding_1', *variable_domain),\n",
" ContinuousParameter('spring_binding_2', *variable_domain)])"
- ],
- "id": "a3d97f61-fde8-4e4d-9368-3a4699cdef5c"
+ ]
},
{
"cell_type": "markdown",
@@ -4082,8 +3865,7 @@
"source": [
"Before we perform sensitivity analysis, we need to build an emulator of\n",
"the catapulter, which we do using our experimental design process."
- ],
- "id": "7159cd23-535d-4bfe-a88e-984f5417b6a1"
+ ]
},
{
"cell_type": "markdown",
@@ -4091,8 +3873,8 @@
"source": [
"## Experimental Design for the Catapult\n",
"\n",
- "\\[\\[
 \n",
+ "
 \n",
"\n",
"Figure: First Order sobol indices as estimated by GP-emulator based\n",
"Monte Carlo on the catapult."
- ],
- "id": "7f1efe52-0090-4885-8902-a01836664d5e"
+ ]
},
{
"cell_type": "code",
@@ -4336,19 +4098,17 @@
"ax.set_ylabel('% of explained output variance')\n",
"\n",
"mlai.write_figure(filename='total-effects-sobol-indices-gp-catapult.svg', directory='./uq')"
- ],
- "id": "d82f7d6b-3b0a-4a52-86da-388b71064746"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Total effects as estimated by GP based Monte Carlo on the\n",
"catapult."
- ],
- "id": "7a18421b-941a-48a1-a4ff-7b2cb3cc5ae5"
+ ]
},
{
"cell_type": "markdown",
@@ -4368,8 +4128,7 @@
" Page](http://www.theguardian.com/profile/neil-lawrence)\n",
"- blog:\n",
" [http://inverseprobability.com](http://inverseprobability.com/blog.html)"
- ],
- "id": "fb1e30cb-6a5c-4f42-943f-945b65b14e3a"
+ ]
},
{
"cell_type": "markdown",
@@ -4377,12 +4136,11 @@
"source": [
"## References\n",
"\n",
- "Borchert, T., 2020. [Milan: An evolution of data-oriented\n",
- "programming](https://tborchertblog.wordpress.com/2020/02/13/28/).\n",
+ "Borchert, T., 2020. Milan: An evolution of data-oriented programming.\n",
"\n",
"Cabrera, C., Paleyes, A., Thodoroff, P., Lawrence, N.D., 2023.\n",
- "[Real-world machine learning systems: A survey from a data-oriented\n",
- "architecture perspective](https://arxiv.org/abs/2302.04810).\n",
+ "Real-world machine learning systems: A survey from a data-oriented\n",
+ "architecture perspective.\n",
"\n",
"Durrande, N., Ginsbourger, D., Olivier, Carraro, L., 2013. ANOVA kernels\n",
"and RKHS of zero mean functions for model-based sensitivity analysis.\n",
@@ -4393,55 +4151,48 @@
"uncertainty analysis for computer models. \\[1990\\] Proceedings. First\n",
"International Symposium on Uncertainty Modeling and Analysis 398–403.\n",
"\n",
- "Joshi, R., 2007. [A loosely-coupled real-time\n",
- "SOA](http://community.rti.com/sites/default/files/archive/Data-Oriented_Architecture.pdf).\n",
- "Real-Time Innovations Inc.\n",
+ "Joshi, R., 2007. A loosely-coupled real-time SOA. Real-Time Innovations\n",
+ "Inc.\n",
"\n",
"Kennedy, M.C., O’Hagan, A., 2001. Bayesian calibration of computer\n",
"models. Journal of the Royal Statistical Society: Series B (Statistical\n",
"Methodology) 63, 425–464.
Uncertainty and Modelling
@@ -405,7 +407,7 @@
@@ -418,7 +420,7 @@
-
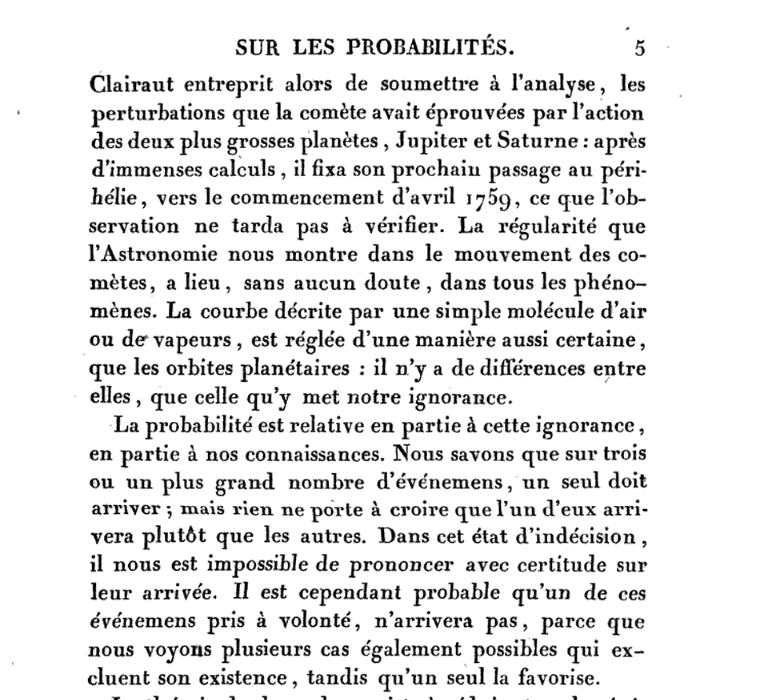 +
 @@ -431,15 +433,15 @@
-
+
-
@@ -494,7 +496,7 @@
-
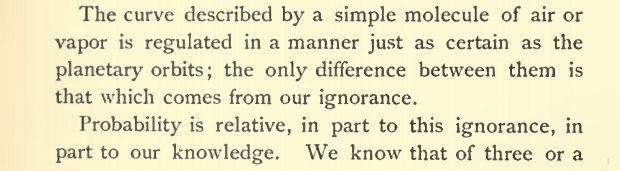 +

The Gaussian Density
Gaussian Density
@@ -600,43 +602,43 @@
-
Underdetermined System
});
-
-
-
-
-
-
-
-
-
-
Bayes Update
});
-
-
-
Gaussian Distributions to Processes
-GPy: A Gaussian Process Framework in Python
-
+
