Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics.
Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy
GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries.
The software itself is available on GitHub and the team welcomes contributions.
The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets.
We have state vector \(\mathbf{X}= \left[\mathbf{ x}_1 \dots \mathbf{ x}_q\right] \in \mathbb{R}^{T \times q}\) and if each state evolves independently we have \[
+sns.set_palette('colorblind')}-->
Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics.
Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy
GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries.
The software itself is available on GitHub and the team welcomes contributions.
The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets.
We have state vector \(\mathbf{X}= \left[\mathbf{ x}_1 \dots \mathbf{ x}_q\right] \in \mathbb{R}^{T \times q}\) and if each state evolves independently we have \[
\begin{align*}
p(\mathbf{X}) &= \prod_{i=1}^qp(\mathbf{ x}_{:, i}) \\
p(\mathbf{ x}_{:, i}) &= \mathscr{N}\left(\mathbf{ x}_{:, i}|\mathbf{0},\mathbf{K}\right).
@@ -38,7 +37,7 @@
\vdots\\
\mathbf{ x}_{:, q}
\end{bmatrix}
-\]
Kronecker Product
Figure: Illustration of the Kronecker product.
Figure: Kronecker product between two matrices.
Stacking and Kronecker Products
Represent with a ‘stacked’ system: \[p
+\]
Kronecker Product
Figure: Illustration of the Kronecker product.
Figure: Kronecker product between two matrices.
Stacking and Kronecker Products
Represent with a ‘stacked’ system: \[p
(\mathbf{ x}) = \mathscr{N}\left(\mathbf{ x}|\mathbf{0},\mathbf{I}\otimes \mathbf{K}\right)
\] where the stacking is placing each column of \(\mathbf{X}\) one on top of another as \[
\mathbf{ x}= \begin{bmatrix}
@@ -47,16 +46,16 @@
\vdots\\
\mathbf{ x}_{:, q}
\end{bmatrix}
- \]
Column Stacking
For this stacking the marginal distribution over time is given by the block diagonals.
Figure: The marginal distribution for the first three variables (highlighted) is givne by \(\mathbf{K}\) when the form of stacking is \(\mathbf{I}\otimes \mathbf{K}\). This is the ‘column stacking’ case.
Two Ways of Stacking
Can also stack each row of \(\mathbf{X}\) to form column vector: \[\mathbf{ x}= \begin{bmatrix}
+ \]
Column Stacking
For this stacking the marginal distribution over time is given by the block diagonals.
Figure: The marginal distribution for the first three variables (highlighted) is givne by \(\mathbf{K}\) when the form of stacking is \(\mathbf{I}\otimes \mathbf{K}\). This is the ‘column stacking’ case.
Two Ways of Stacking
Can also stack each row of \(\mathbf{X}\) to form column vector: \[\mathbf{ x}= \begin{bmatrix}
\mathbf{ x}_{1, :}\\
\mathbf{ x}_{2, :}\\
\vdots\\
\mathbf{ x}_{T, :}
- \end{bmatrix}\]\[p(\mathbf{ x}) = \mathscr{N}\left(\mathbf{ x}|\mathbf{0},\mathbf{K}\otimes \mathbf{I}\right)\]
Row Stacking
For this stacking the marginal distribution over the latent dimensions is given by the block diagonals.
Figure: The marginal distribution for the first three variables (highlighted) is independent when the form of stacking is \(\mathbf{K}\otimes \mathbf{I}\). This is the ‘row stacking’ case.
Mapping from Latent Process to Observed
Figure: Mapping from latent process to observed
Observed Process
The observations are related to the latent points by a linear mapping matrix, \[
+ \end{bmatrix}\]\[p(\mathbf{ x}) = \mathscr{N}\left(\mathbf{ x}|\mathbf{0},\mathbf{K}\otimes \mathbf{I}\right)\]
Row Stacking
For this stacking the marginal distribution over the latent dimensions is given by the block diagonals.
Figure: The marginal distribution for the first three variables (highlighted) is independent when the form of stacking is \(\mathbf{K}\otimes \mathbf{I}\). This is the ‘row stacking’ case.
Mapping from Latent Process to Observed
Figure: Mapping from latent process to observed
Observed Process
The observations are related to the latent points by a linear mapping matrix, \[
\mathbf{ y}_{i, :} = \mathbf{W}\mathbf{ x}_{i, :} + \boldsymbol{ \epsilon}_{i, :}
\]\[
\boldsymbol{ \epsilon}\sim \mathscr{N}\left(\mathbf{0},\sigma^2\mathbf{I}\right)
-\]
Figure:
Output Covariance
This leads to a covariance of the form \[
+\]
Figure:
Output Covariance
This leads to a covariance of the form \[
(\mathbf{I}\otimes \mathbf{W}) (\mathbf{K}\otimes \mathbf{I}) (\mathbf{I}\otimes \mathbf{W}^\top) + \mathbf{I}\sigma^2
\] Using \((\mathbf{A}\otimes\mathbf{B}) (\mathbf{C}\otimes\mathbf{D}) = \mathbf{A}\mathbf{C} \otimes \mathbf{B}\mathbf{D}\) This leads to \[
\mathbf{K}\otimes {\mathbf{W}}{\mathbf{W}}^\top + \mathbf{I}\sigma^2
@@ -72,7 +71,7 @@
\mathbf{ w}= \begin{bmatrix} 1 \\ 5\end{bmatrix}
\]\[
\mathbf{B}= \begin{bmatrix} 1 & 5\\ 5&25\end{bmatrix}
-\]
Gaussian processes for Multi-task, Multi-output and Multi-class
Bonilla et al. (n.d.) suggest ICM for multitask learning.
Use a PPCA form for \(\mathbf{B}\): similar to our Kalman filter example.
Refer to the autokrigeability effect as the cancellation of inter-task transfer.
Also discuss the similarities between the multi-task GP and the ICM, and its relationship to the SLFM and the LMC.
Multitask Classification
Mostly restricted to the case where the outputs are conditionally independent given the hyperparameters \(\boldsymbol{\phi}\)(Lawrence and Platt, 2004; Minka and Picard, 1997; Rasmussen and Williams, 2006; Seeger and Jordan, 2004; Williams and Barber, 1998; Yu et al., 2005).
Intrinsic coregionalization model has been used in the multiclass scenario. Skolidis and Sanguinetti (2011) use the intrinsic coregionalization model for classification, by introducing a probit noise model as the likelihood.
Posterior distribution is no longer analytically tractable: approximate inference is required.
Computer Emulation
A statistical model used as a surrogate for a computationally expensive computer model.
Higdon et al. (2008) use the linear model of coregionalization to model images representing the evolution of the implosion of steel cylinders.
In Conti and O’Hagan (2009) use the ICM to model a vegetation model: called the Sheffield Dynamic Global Vegetation Model Woodward et al. (1998).
The first think we will look at is a multiple output model. Our aim is to jointly model all sprinting events from olympics since 1896. Data is provided by Rogers & Girolami’s “First Course in Machine Learning.” Firstly, let’s load in the data.
import pods
+\]
Gaussian processes for Multi-task, Multi-output and Multi-class
Bonilla et al. (n.d.) suggest ICM for multitask learning.
Use a PPCA form for \(\mathbf{B}\): similar to our Kalman filter example.
Refer to the autokrigeability effect as the cancellation of inter-task transfer.
Also discuss the similarities between the multi-task GP and the ICM, and its relationship to the SLFM and the LMC.
Multitask Classification
Mostly restricted to the case where the outputs are conditionally independent given the hyperparameters \(\boldsymbol{\phi}\)(Lawrence and Platt, 2004; Minka and Picard, 1997; Rasmussen and Williams, 2006; Seeger and Jordan, 2004; Williams and Barber, 1998; Yu et al., 2005).
Intrinsic coregionalization model has been used in the multiclass scenario. Skolidis and Sanguinetti (2011) use the intrinsic coregionalization model for classification, by introducing a probit noise model as the likelihood.
Posterior distribution is no longer analytically tractable: approximate inference is required.
Computer Emulation
A statistical model used as a surrogate for a computationally expensive computer model.
Higdon et al. (2008) use the linear model of coregionalization to model images representing the evolution of the implosion of steel cylinders.
In Conti and O’Hagan (2009) use the ICM to model a vegetation model: called the Sheffield Dynamic Global Vegetation Model Woodward et al. (1998).
The first think we will look at is a multiple output model. Our aim is to jointly model all sprinting events from olympics since 1896. Data is provided by Rogers & Girolami’s “First Course in Machine Learning.” Firstly, let’s load in the data.
import podsimport numpy as np
data = pods.datasets.olympic_sprints()X = data['X']y = data['Y']print(data['info'], data['details'])
When using data sets it’s good practice to cite the originators of the data, you can get information about the source of the data from data['citation']
print(data['citation'])
The data consists of all the male and female sprinting data for 100m, 200m and 400m since 1896 (six outputs in total). The output information can be found from: data['output_info']
print(data['output_info'])
In GPy we deal with multiple output data in a particular way. We specify the output we are interested in for modelling as an additional input. So whilst for this data, normally, the only input would be the year of the event. We additionally have an input giving the index of the output we are modelling. This can be seen from examining data['X'].
print('First column of X contains the olympic years.')print(data['X'][:, 0])print('Second column of X contains the event index.')
-print(data['X'][:, 1])
Now let’s plot the data
Figure: Olympic sprint gold medal winning times from Rogers and Girolami (2011).
In the plot above red is women’s events, blue is men’s. Squares are 400 m, crosses 200m and circles 100m. Not all events were run in all years, for example the women’s 400 m only started in 1964.
We will perform a multi-output Gaussian process fit to the data, we’ll do this using the GPy software.
cmd = install_command('GPy')
%system {cmd}
We will look at modelling the data using coregionalization approaches described in this morning’s lecture. We introduced these approaches through the Kronecker product. To indicate we want to construct a covariance function of this type in GPy we’ve overloaded the ** operator. Stricly speaking this operator means to the power of (like ^ in MATLAB). But for covariance functions we’ve used it to indicate a tensor product. The linear models of coregionalization we introduced in the lecture were all based on combining a matrix with a standard covariance function. We can think of the matrix as a particular type of covariance function, whose elements are referenced using the event indices. I.e. \(k(0, 0)\) references the first row and column of the coregionalization matrix. \(k(1, 0)\) references the second row and first column of the coregionalization matrix. Under this set up, we want to build a covariance where the first column from the features (the years) is passed to a covariance function, and the second column from the features (the event number) is passed to the coregionalisation matrix. Let’s start by trying a intrinsic coregionalisation model (sometimes known as multitask Gaussian processes). Let’s start by checking the help for the Coregionalize covariance.
import GPy
GPy.kern.Coregionalize?
The coregionalize matrix, \(\mathbf{B}\), is itself is constructed from two other matrices, \(\mathbf{B} = \mathbf{W}\mathbf{W}^\top + \text{diag}(\boldsymbol{\kappa})\). This allows us to specify a low rank form for the coregionalization matrix. However, for our first example we want to specify that the matrix \(\mathbf{B}\) is not constrained to have a low rank form.
Note here that the rank we specify is that of the \(\mathbf{W}\mathbf{W}^\top\) part. When this part is combined with the diagonal matrix from \(\mathbf{\kappa}\) the matrix \(\mathbf{B}\) is totally general. This covariance function can now be used in a standard Gaussian process regression model. Let’s build the model and optimize it.
model = GPy.models.GPRegression(X, y, kern)
-model.optimize()
We can plot the results using the ability to ‘fix inputs’ in the model.plot() function. We can specify that column 1 should be fixed to event number 2 by passing fixed_inputs = [(1, 2)] to the model. To plot the results for all events on the same figure we also specify fignum=1 in the loop as below.
Figure: Gaussian process fit to the Olympic Sprint data.
There is a lot we can do with this model. First of all, each of the races is a different length, so the series have a different mean. We can include another coregionalization term to deal with the mean. Below we do this and reduce the rank of the coregionalization matrix to 1.
model = GPy.models.GPRegression(X, y, kern)
-model.optimize()
Figure: Gaussian process fit to the Olympic Sprint data.
This is a simple form of the linear model of coregionalization. Note how confident the model is about what the women’s 400 m performance would have been. You might feel that the model is being over confident in this region. Perhaps we are forcing too much sharing of information between the sprints. We could return to the intrinsic coregionalization model and force the two base covariance functions to share the same coregionalization matrix.
model = GPy.models.GPRegression(X, y, kern)
-model.optimize()
Figure: Gaussian process fit to the Olympic Sprint data.
Predictions in the multioutput case can be very effected by our covariance function design. This reflects the themes we saw on the first day where the importance of covariance function choice was emphasized at design time.
Thanks!
For more information on these subjects and more you might want to check the following resources.
Conti, S., O’Hagan, A., 2009. Bayesian emulation of complex multi-output and dynamic computer models. Journal of Statistical Planning and Inference 140, 640–651. https://doi.org/doi:10.1016/j.jspi.2009.08.006
Goovaerts, P., 1997. Geostatistics For Natural Resources Evaluation. Oxford University Press.
Higdon, D.M., Gattiker, J., Williams, B., Rightley, M., 2008. Computer model calibration using high dimensional output. Journal of the American Statistical Association 103, 570–583.
Rogers, S., Girolami, M., 2011. A first course in machine learning. CRC Press.
Seeger, M., Jordan, M.I., 2004. Sparse Gaussian Process classification with multiple classes (No. 661). Department of Statistics, University of California at Berkeley.
Skolidis, G., Sanguinetti, G., 2011. Bayesian multitask classification with Gaussian process priors. IEEE Transactions on Neural Networks 22, 2011–2021.
Teh, Y.W., Seeger, M., Jordan, M.I., n.d. Semiparametric latent factor models. pp. 333–340.
Wackernagel, H., 2003. Multivariate geostatistics: An introduction with applications, 3rd ed. springer.
Williams, C.K.I., Barber, D., 1998. Bayesian Classification with Gaussian processes. IEEE Transactions on Pattern Analysis and Machine Intelligence 20, 1342–1351.
Woodward, I., Lomas, M.R., Betts, R.A., 1998. Vegetation-climate feedbacks in a greenhouse world. Philosophical Transactions: Biological Sciences 353, 29–39.
Yu, K., Tresp, V., Schwaighofer, A., 2005. Learning Gaussian processes from multiple tasks, in: Proceedings of the 22nd International Conference on Machine Learning (ICML 2005). pp. 1012–1019.
+print(data['X'][:, 1])
Now let’s plot the data
Figure: Olympic sprint gold medal winning times from Rogers and Girolami (2011).
In the plot above red is women’s events, blue is men’s. Squares are 400 m, crosses 200m and circles 100m. Not all events were run in all years, for example the women’s 400 m only started in 1964.
import pods
+import numpy as np
data = pods.datasets.olympic_sprints()
+X = data['X']
+y = data['Y']
We will perform a multi-output Gaussian process fit to the data, we’ll do this using the GPy software.
cmd = install_command('GPy')
%system {cmd}
We will look at modelling the data using coregionalization approaches described in this morning’s lecture. We introduced these approaches through the Kronecker product. To indicate we want to construct a covariance function of this type in GPy we’ve overloaded the ** operator. Stricly speaking this operator means to the power of (like ^ in MATLAB). But for covariance functions we’ve used it to indicate a tensor product. The linear models of coregionalization we introduced in the lecture were all based on combining a matrix with a standard covariance function. We can think of the matrix as a particular type of covariance function, whose elements are referenced using the event indices. I.e. \(k(0, 0)\) references the first row and column of the coregionalization matrix. \(k(1, 0)\) references the second row and first column of the coregionalization matrix. Under this set up, we want to build a covariance where the first column from the features (the years) is passed to a covariance function, and the second column from the features (the event number) is passed to the coregionalisation matrix. Let’s start by trying a intrinsic coregionalisation model (sometimes known as multitask Gaussian processes). Let’s start by checking the help for the Coregionalize covariance.
import GPy
GPy.kern.Coregionalize?
The coregionalize matrix, \(\mathbf{B}\), is itself is constructed from two other matrices, \(\mathbf{B} = \mathbf{W}\mathbf{W}^\top + \text{diag}(\boldsymbol{\kappa})\). This allows us to specify a low rank form for the coregionalization matrix. However, for our first example we want to specify that the matrix \(\mathbf{B}\) is not constrained to have a low rank form.
Note here that the rank we specify is that of the \(\mathbf{W}\mathbf{W}^\top\) part. When this part is combined with the diagonal matrix from \(\mathbf{\kappa}\) the matrix \(\mathbf{B}\) is totally general. This covariance function can now be used in a standard Gaussian process regression model. Let’s build the model and optimize it.
model = GPy.models.GPRegression(X, y, kern)
+model.optimize()
We can plot the results using the ability to ‘fix inputs’ in the model.plot() function. We can specify that column 1 should be fixed to event number 2 by passing fixed_inputs = [(1, 2)] to the model. To plot the results for all events on the same figure we also specify fignum=1 in the loop as below.
Figure: Gaussian process fit to the Olympic Sprint data.
There is a lot we can do with this model. First of all, each of the races is a different length, so the series have a different mean. We can include another coregionalization term to deal with the mean. Below we do this and reduce the rank of the coregionalization matrix to 1.
model = GPy.models.GPRegression(X, y, kern)
+model.optimize()
Figure: Gaussian process fit to the Olympic Sprint data.
This is a simple form of the linear model of coregionalization. Note how confident the model is about what the women’s 400 m performance would have been. You might feel that the model is being over confident in this region. Perhaps we are forcing too much sharing of information between the sprints. We could return to the intrinsic coregionalization model and force the two base covariance functions to share the same coregionalization matrix.
model = GPy.models.GPRegression(X, y, kern)
+model.optimize()
Figure: Gaussian process fit to the Olympic Sprint data.
Predictions in the multioutput case can be very effected by our covariance function design. This reflects the themes we saw on the first day where the importance of covariance function choice was emphasized at design time.
Thanks!
For more information on these subjects and more you might want to check the following resources.
Conti, S., O’Hagan, A., 2009. Bayesian emulation of complex multi-output and dynamic computer models. Journal of Statistical Planning and Inference 140, 640–651. https://doi.org/doi:10.1016/j.jspi.2009.08.006
Goovaerts, P., 1997. Geostatistics For Natural Resources Evaluation. Oxford University Press.
Higdon, D.M., Gattiker, J., Williams, B., Rightley, M., 2008. Computer model calibration using high dimensional output. Journal of the American Statistical Association 103, 570–583.
Rogers, S., Girolami, M., 2011. A first course in machine learning. CRC Press.
Seeger, M., Jordan, M.I., 2004. Sparse Gaussian Process classification with multiple classes (No. 661). Department of Statistics, University of California at Berkeley.
Skolidis, G., Sanguinetti, G., 2011. Bayesian multitask classification with Gaussian process priors. IEEE Transactions on Neural Networks 22, 2011–2021.
Teh, Y.W., Seeger, M., Jordan, M.I., n.d. Semiparametric latent factor models. pp. 333–340.
Wackernagel, H., 2003. Multivariate geostatistics: An introduction with applications, 3rd ed. springer.
Williams, C.K.I., Barber, D., 1998. Bayesian Classification with Gaussian processes. IEEE Transactions on Pattern Analysis and Machine Intelligence 20, 1342–1351.
Woodward, I., Lomas, M.R., Betts, R.A., 1998. Vegetation-climate feedbacks in a greenhouse world. Philosophical Transactions: Biological Sciences 353, 29–39.
Yu, K., Tresp, V., Schwaighofer, A., 2005. Learning Gaussian processes from multiple tasks, in: Proceedings of the 22nd International Conference on Machine Learning (ICML 2005). pp. 1012–1019.
Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics.
-
-
-
-
-
-
-
-
-
-
-
Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy
-
-
-
GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries.
-
The software itself is available on GitHub and the team welcomes contributions.
-
The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets.
This linear relationship between the observed data and the latent variables is at the heart of Hotelling’s original formulation of PCA. It explicitly models the idea that the observed high-dimensional data is generated from a lower-dimensional set of latent variables, with some added noise. This perspective aligns PCA more closely with factor analysis and highlights its nature as a latent variable model.
-
Probabilistic PCA (PPCA) provides a probabilistic interpretation of PCA by explicitly modeling the generative process that creates the observed data. The model assumes that each high-dimensional data point \(\mathbf{ y}_{i,:}\) is generated from a lower-dimensional latent variable \(\mathbf{ z}_{i,:}\) through a linear transformation with added Gaussian noise: \[
+sns.set_palette('colorblind')}-->
Gaussian processes are a flexible tool for non-parametric analysis with uncertainty. The GPy software was started in Sheffield to provide a easy to use interface to GPs. One which allowed the user to focus on the modelling rather than the mathematics.
Figure: GPy is a BSD licensed software code base for implementing Gaussian process models in Python. It is designed for teaching and modelling. We welcome contributions which can be made through the GitHub repository https://github.com/SheffieldML/GPy
GPy is a BSD licensed software code base for implementing Gaussian process models in python. This allows GPs to be combined with a wide variety of software libraries.
The software itself is available on GitHub and the team welcomes contributions.
The aim for GPy is to be a probabilistic-style programming language, i.e., you specify the model rather than the algorithm. As well as a large range of covariance functions the software allows for non-Gaussian likelihoods, multivariate outputs, dimensionality reduction and approximations for larger data sets.
This linear relationship between the observed data and the latent variables is at the heart of Hotelling’s original formulation of PCA. It explicitly models the idea that the observed high-dimensional data is generated from a lower-dimensional set of latent variables, with some added noise. This perspective aligns PCA more closely with factor analysis and highlights its nature as a latent variable model.
Probabilistic PCA (PPCA) provides a probabilistic interpretation of PCA by explicitly modeling the generative process that creates the observed data. The model assumes that each high-dimensional data point \(\mathbf{ y}_{i,:}\) is generated from a lower-dimensional latent variable \(\mathbf{ z}_{i,:}\) through a linear transformation with added Gaussian noise: \[
\mathbf{ y}_{i,:} = \mathbf{W}\mathbf{ z}_{i,:} + \boldsymbol{ \epsilon}_{i,:}
\] where \(\boldsymbol{ \epsilon}_{i,:} \sim \mathscr{N}\left(\mathbf{0},\sigma^2\mathbf{I}\right)\) represents isotropic Gaussian noise. The model places a standard Gaussian prior over the latent variables: \[
p(\mathbf{ z}_{i,:}) = \mathscr{N}\left(\mathbf{ z}_{i,:}|\mathbf{0},\mathbf{I}\right)
@@ -78,25 +28,7 @@
Probabilistic PCA
p(\mathbf{ y}_{i,:}|\mathbf{ z}_{i,:},\mathbf{W}) = \mathscr{N}\left(\mathbf{ y}_{i,:}|\mathbf{W}\mathbf{ z}_{i,:},\sigma^2\mathbf{I}\right)
\] By integrating out the latent variables, we obtain the marginal likelihood of the data: \[
p(\mathbf{ y}_{i,:}|\mathbf{W}) = \mathscr{N}\left(\mathbf{ y}_{i,:}|\mathbf{0},\mathbf{W}\mathbf{W}^{\top}+\sigma^{2}\mathbf{I}\right)
-\] This probabilistic formulation, developed by Tipping and Bishop (Tipping and Bishop, 1999a), provides a principled framework that not only recovers classical PCA as a special case when \(\sigma^2 \to 0\), but also enables extensions like handling missing data and mixture models.
-
cmd = install_command('daft')
-
%system {cmd}
-
-
-
-
-
-
-
-
-
Figure: Graphical model representing probabilistic PCA.
-
-
-
Probabilistic PCA
-
In 1997 Tipping and Bishop(Tipping and Bishop, 1999b) and Roweis(Roweis, n.d.) independently revisited Hotelling’s model and considered the case where the noise variance was finite, but shared across all output dimensons. Their model can be thought of as a factor analysis where \[
+\] This probabilistic formulation, developed by Tipping and Bishop (Tipping and Bishop, 1999a), provides a principled framework that not only recovers classical PCA as a special case when \(\sigma^2 \to 0\), but also enables extensions like handling missing data and mixture models.
cmd = install_command('daft')
%system {cmd}
Figure: Graphical model representing probabilistic PCA.
Probabilistic PCA
In 1997 Tipping and Bishop(Tipping and Bishop, 1999b) and Roweis(Roweis, n.d.) independently revisited Hotelling’s model and considered the case where the noise variance was finite, but shared across all output dimensons. Their model can be thought of as a factor analysis where \[
\boldsymbol{\Sigma} = \sigma^2 \mathbf{I}.
\] This leads to a marginal likelihood of the form \[
p(\mathbf{Y}|\mathbf{W}, \sigma^2)
@@ -107,23 +39,7 @@
Probabilistic PCA
\mathbf{S}= \sum_{i=1}^n(\mathbf{ y}_{i, :} - \boldsymbol{ \mu})(\mathbf{ y}_{i,:} - \boldsymbol{ \mu})^\top,
\] which can be written \(\mathbf{S}= \frac{1}{n} \mathbf{Y}^\top\mathbf{Y}\) if the data is zero mean. The matrix \(\mathbf{L}\) is diagonal and is dependent on the eigenvalues of \(\mathbf{S}\), \(\boldsymbol{\Lambda}\). If the \(i\)th diagonal element of this matrix is given by \(\lambda_i\) then the corresponding element of \(\mathbf{L}\) is \[
\ell_i = \sqrt{\lambda_i - \sigma^2}
-\] where \(\sigma^2\) is the noise variance. Note that if \(\sigma^2\) is larger than any particular eigenvalue, then that eigenvalue (along with its corresponding eigenvector) is discarded from the solution.
-
PPCA as Manifold Learning
-
Probabilistic PCA can be viewed as a simple manifold learning algorithm. It assumes that:
-
-
The data lies near a linear manifold (subspace) of the high-dimensional space
-
The deviation from this manifold is Gaussian noise
-
The intrinsic dimensionality is specified by the number of retained components
-
-
This view helps explain why PPCA works well when the manifold hypothesis holds and the manifold is approximately linear. When the manifold is nonlinear, we need more sophisticated methods like kernel PCA or neural network-based approaches.
-
Python Implementation of Probabilistic PCA
-
We will now implement this algorithm in python.
-
import numpy as np
-
from mlai import ppca_eig
-
ppca = ppca_eig
-
In practice we may not wish to compute the eigenvectors of the covariance matrix directly. This is because it requires us to estimate the covariance, which involves a sum of squares term, before estimating the eigenvectors. We can estimate the eigenvectors directly either through QR decomposition or singular value decomposition. We saw a similar issue arise when , where we also wished to avoid computation of \(\mathbf{Z}^\top\mathbf{Z}\) (or in the case of \(\boldsymbol{\Phi}^\top\boldsymbol{\Phi}\)).
-
Posterior for Principal Component Analysis
-
Under the latent variable model justification for principal component analysis, we are normally interested in inferring something about the latent variables given the data. This is the distribution, \[
+\] where \(\sigma^2\) is the noise variance. Note that if \(\sigma^2\) is larger than any particular eigenvalue, then that eigenvalue (along with its corresponding eigenvector) is discarded from the solution.
PPCA as Manifold Learning
Probabilistic PCA can be viewed as a simple manifold learning algorithm. It assumes that:
The data lies near a linear manifold (subspace) of the high-dimensional space
The deviation from this manifold is Gaussian noise
The intrinsic dimensionality is specified by the number of retained components
This view helps explain why PPCA works well when the manifold hypothesis holds and the manifold is approximately linear. When the manifold is nonlinear, we need more sophisticated methods like kernel PCA or neural network-based approaches.
Python Implementation of Probabilistic PCA
We will now implement this algorithm in python.
import numpy as np
from mlai import ppca_eig
ppca = ppca_eig
In practice we may not wish to compute the eigenvectors of the covariance matrix directly. This is because it requires us to estimate the covariance, which involves a sum of squares term, before estimating the eigenvectors. We can estimate the eigenvectors directly either through QR decomposition or singular value decomposition. We saw a similar issue arise when , where we also wished to avoid computation of \(\mathbf{Z}^\top\mathbf{Z}\) (or in the case of \(\boldsymbol{\Phi}^\top\boldsymbol{\Phi}\)).
Posterior for Principal Component Analysis
Under the latent variable model justification for principal component analysis, we are normally interested in inferring something about the latent variables given the data. This is the distribution, \[
p(\mathbf{ z}_{i, :} | \mathbf{ y}_{i, :})
\] for any given data point. Determining this density turns out to be very similar to the approach for determining the Bayesian posterior of \(\mathbf{ w}\) in Bayesian linear regression, only this time we place the prior density over \(\mathbf{ z}_{i, :}\) instead of \(\mathbf{ w}\). The posterior is proportional to the joint density as follows, \[
p(\mathbf{ z}_{i, :} | \mathbf{ y}_{i, :}) \propto p(\mathbf{ y}_{i,
@@ -136,30 +52,17 @@
Multiply out the terms in the brackets. Then collect the quadratic term and the linear terms together. Show that the posterior has the form \[
+\]
Exercise 1
Multiply out the terms in the brackets. Then collect the quadratic term and the linear terms together. Show that the posterior has the form \[
\mathbf{ z}_{i, :} | \mathbf{W}\sim \mathscr{N}\left(\boldsymbol{ \mu}_x,\mathbf{C}_x\right)
\] where \[
\mathbf{C}_x = \left(\sigma^{-2}
\mathbf{W}^\top\mathbf{W}+ \mathbf{I}\right)^{-1}
\] and \[
\boldsymbol{ \mu}_x
-= \mathbf{C}_x \sigma^{-2}\mathbf{W}^\top \mathbf{ y}_{i, :}
-\] Compare this to the posterior for the Bayesian linear regression from last week, do they have similar forms? What matches and what differs?
-
Python Implementation of the Posterior
-
Now let’s implement the system in code.
-
Exercise 2
-
Use the values for \(\mathbf{W}\) and \(\sigma^2\) you have computed, along with the data set \(\mathbf{Y}\) to compute the posterior density over \(\mathbf{Z}\). Write a function of the form
-
mu_x, C_x = posterior(Y, W, sigma2)
-
where mu_x and C_x are the posterior mean and posterior covariance for the given \(\mathbf{Y}\).
-
Don’t forget to subtract the mean of the data Y inside your function before computing the posterior: remember we assumed at the beginning of our analysis that the data had been centred (i.e. the mean was removed).
-
Numerically Stable and Efficient Version
-
Just as we saw for and computation of a matrix such as \(\mathbf{Y}^\top\mathbf{Y}\) (or its centred version) can be a bad idea in terms of loss of numerical accuracy. Fortunately, we can find the eigenvalues and eigenvectors of the matrix \(\mathbf{Y}^\top\mathbf{Y}\) without direct computation of the matrix. This can be done with the singular value decomposition. The singular value decompsition takes a matrix, \(\mathbf{Z}\) and represents it in the form, \[
+= \mathbf{C}_x \sigma^{-2}\mathbf{W}^\top \mathbf{ y}_{i, :}
+\] Compare this to the posterior for the Bayesian linear regression from last week, do they have similar forms? What matches and what differs?
Python Implementation of the Posterior
Now let’s implement the system in code.
Exercise 2
Use the values for \(\mathbf{W}\) and \(\sigma^2\) you have computed, along with the data set \(\mathbf{Y}\) to compute the posterior density over \(\mathbf{Z}\). Write a function of the form
mu_x, C_x = posterior(Y, W, sigma2)
where mu_x and C_x are the posterior mean and posterior covariance for the given \(\mathbf{Y}\).
Don’t forget to subtract the mean of the data Y inside your function before computing the posterior: remember we assumed at the beginning of our analysis that the data had been centred (i.e. the mean was removed).
Numerically Stable and Efficient Version
Just as we saw for and computation of a matrix such as \(\mathbf{Y}^\top\mathbf{Y}\) (or its centred version) can be a bad idea in terms of loss of numerical accuracy. Fortunately, we can find the eigenvalues and eigenvectors of the matrix \(\mathbf{Y}^\top\mathbf{Y}\) without direct computation of the matrix. This can be done with the singular value decomposition. The singular value decompsition takes a matrix, \(\mathbf{Z}\) and represents it in the form, \[
\mathbf{Z} = \mathbf{U}\boldsymbol{\Lambda}\mathbf{V}^\top
-\] where \(\mathbf{U}\) is a matrix of orthogonal vectors in the columns, meaning \(\mathbf{U}^\top\mathbf{U} = \mathbf{I}\). It has the same number of rows and columns as \(\mathbf{Z}\). The matrices \(\mathbf{\Lambda}\) and \(\mathbf{V}\) are both square with dimensionality given by the number of columns of \(\mathbf{Z}\). The matrix \(\mathbf{\Lambda}\) is diagonal and \(\mathbf{V}\) is an orthogonal matrix so \(\mathbf{V}^\top\mathbf{V} = \mathbf{V}\mathbf{V}^\top = \mathbf{I}\). The eigenvalues of the matrix \(\mathbf{Y}^\top\mathbf{Y}\) are then given by the singular values of the matrix \(\mathbf{Y}^\top\) squared and the eigenvectors are given by \(\mathbf{U}\).
-
Solution for \(\mathbf{W}\)
-
Given the singular value decomposition of \(\mathbf{Y}\) then we have \[
+\] where \(\mathbf{U}\) is a matrix of orthogonal vectors in the columns, meaning \(\mathbf{U}^\top\mathbf{U} = \mathbf{I}\). It has the same number of rows and columns as \(\mathbf{Z}\). The matrices \(\mathbf{\Lambda}\) and \(\mathbf{V}\) are both square with dimensionality given by the number of columns of \(\mathbf{Z}\). The matrix \(\mathbf{\Lambda}\) is diagonal and \(\mathbf{V}\) is an orthogonal matrix so \(\mathbf{V}^\top\mathbf{V} = \mathbf{V}\mathbf{V}^\top = \mathbf{I}\). The eigenvalues of the matrix \(\mathbf{Y}^\top\mathbf{Y}\) are then given by the singular values of the matrix \(\mathbf{Y}^\top\) squared and the eigenvectors are given by \(\mathbf{U}\).
Solution for \(\mathbf{W}\)
Given the singular value decomposition of \(\mathbf{Y}\) then we have \[
\mathbf{W}=
\mathbf{U}\mathbf{L}\mathbf{R}^\top
\] where \(\mathbf{R}\) is an arbitrary rotation matrix. This implies that the posterior is given by \[
@@ -175,27 +78,9 @@
Solution for \(\mathbf{W
\mathbf{I}]^{-1} \mathbf{L} \mathbf{U}^\top \mathbf{ y}_{i, :}
\]\[
\boldsymbol{ \mu}_x = \mathbf{D}\mathbf{U}^\top \mathbf{ y}_{i, :}
-\] where \(\mathbf{D}\) is a diagonal matrix with diagonal elements given by \(d_{i} = \frac{\ell_i}{\sigma^2 + \ell_i^2}\).
We’ve implemented PCA as part of supporting the learning process, but in practice we can use the scikit-learn implementation. Let’s try it on the oil flow data.
This data set is from a physics-based simulation of oil flow in a pipeline. The data was generated as part of a project to determine the fraction of oil, water and gas in North Sea oil pipes (Bishop and James, 1993).
-
import pods
-
data = pods.datasets.oil()
-
The data consists of 1000 12-dimensional observations of simulated oil flow in a pipeline. Each observation is labelled according to the multi-phase flow configuration (homogeneous, annular or laminar).
-
# Convert data["Y"] from [1, -1, -1] in each row to rows of 0 or 1 or 2
+\] where \(\mathbf{D}\) is a diagonal matrix with diagonal elements given by \(d_{i} = \frac{\ell_i}{\sigma^2 + \ell_i^2}\).
We’ve implemented PCA as part of supporting the learning process, but in practice we can use the scikit-learn implementation. Let’s try it on the oil flow data.
This data set is from a physics-based simulation of oil flow in a pipeline. The data was generated as part of a project to determine the fraction of oil, water and gas in North Sea oil pipes (Bishop and James, 1993).
import pods
data = pods.datasets.oil()
The data consists of 1000 12-dimensional observations of simulated oil flow in a pipeline. Each observation is labelled according to the multi-phase flow configuration (homogeneous, annular or laminar).
# Convert data["Y"] from [1, -1, -1] in each row to rows of 0 or 1 or 2Y = data["Y"]# Find rows with 1 in first column (class 0)class0 = (Y[:, 0] ==1).astype(int) *0
@@ -204,257 +89,37 @@
Oil Flow Data
# Find rows with 1 in third column (class 2)class2 = (Y[:, 2] ==1).astype(int) *2# Combine into single array of class labels 0,1,2
-labels = class0 + class1 + class2
-
The data is returned as a dictionary containing training and test inputs (‘X’, ‘Xtst’), training and test labels (‘Y’, ‘Ytst’), and the names of the features.
-
-
-
-
-
-
-
-
-
Figure: Visualization of the first two dimensions of the oil flow data from Bishop and James (1993)
-
-
-
As normal we include the citation information for the data.
-
print(data['citation'])
-
And extra information about the data is included, as standard, under the keys info and details.
The data is returned as a dictionary containing training and test inputs (‘X,’ ‘Xtst’), training and test labels (‘Y,’ ‘Ytst’), and the names of the features.
Figure: Visualization of the first two dimensions of the oil flow data from Bishop and James (1993)
As normal we include the citation information for the data.
print(data['citation'])
And extra information about the data is included, as standard, under the keys info and details.
# Find rows with 1 in first column (class 0)
+X_pca = pca.transform(X)
# Find rows with 1 in first column (class 0)class0 = (Y[:, 0] ==1).astype(int) *0# Find rows with 1 in second column (class 1) class1 = (Y[:, 1] ==1).astype(int) *1# Find rows with 1 in third column (class 2)class2 = (Y[:, 2] ==1).astype(int) *2# Combine into single array of class labels 0,1,2
-lbls = class0 + class1 + class2
-
-
-
-
-
-
-
-
-
Figure: PCA of the oil flow data. The flow is homogeneous, annular and stratified.
The challenge for composition of probabilistic models is that you need to propagate a probability densities through non linear mappings. This allows you to create broader classes of probability density. Unfortunately it renders the resulting densities intractable.
-
-
-
-
-
-
-
-
-
Figure: A two dimensional grid mapped into three dimensions to form a two dimensional manifold.
-
-
-
-
-
-
-
-
-
-
-
Figure: A one dimensional line mapped into two dimensions by two separate independent functions. Each point can be mapped exactly through the mappings.
-
-
-
cmd = install_command('daft')
-
%system {cmd}
-
-
-
-
-
-
-
-
-
Figure: A Gaussian density over the input of a non linear function leads to a very non Gaussian output. Here the output is multimodal.
The challenge for composition of probabilistic models is that you need to propagate a probability densities through non linear mappings. This allows you to create broader classes of probability density. Unfortunately it renders the resulting densities intractable.
Figure: A two dimensional grid mapped into three dimensions to form a two dimensional manifold.
Figure: A one dimensional line mapped into two dimensions by two separate independent functions. Each point can be mapped exactly through the mappings.
cmd = install_command('daft')
%system {cmd}
Figure: A Gaussian density over the input of a non linear function leads to a very non Gaussian output. Here the output is multimodal.
The following code is for plotting and to prepare the bigger models for later useage. If you are interested, you can have a look, but this is not essential.
-
For this lab, we’ll use a data set containing all handwritten digits from \(0 \cdots 9\) handwritten, provided by de Campos et al. (2009). We will only use some of the digits for the demonstrations in this lab class, but you can edit the code below to select different subsets of the digit data as you wish.
-
which = [0,1,2,6,7,9] # which digits to work on
+import string
The following code is for plotting and to prepare the bigger models for later useage. If you are interested, you can have a look, but this is not essential.
For this lab, we’ll use a data set containing all handwritten digits from \(0 \cdots 9\) handwritten, provided by de Campos et al. (2009). We will only use some of the digits for the demonstrations in this lab class, but you can edit the code below to select different subsets of the digit data as you wish.
which = [0,1,2,6,7,9] # which digits to work ondata = pods.datasets.decampos_digits(which_digits=which)Y = data['Y']
-labels = data['str_lbls']
-
You can try to plot some of the digits using plt.matshow (the digit images have size 16x16).
Principal component analysis (PCA) finds a rotation of the observed outputs, such that the rotated principal component (PC) space maximizes the variance of the data observed, sorted from most to least important (most to least variable in the corresponding PC).
-
In order to apply PCA in an easy way, we have included a PCA module in pca.py. You can import the module by import <path.to.pca> (without the ending .py!). To run PCA on the digits we have to reshape (Hint: np.reshape ) digits .
-
-
What is the right shape \(n\times d\) to use?
-
-
We will call the reshaped observed outputs \(\mathbf{Y}\) in the following.
-
Yn = Y#Y-Y.mean()
-
Now let’s run PCA on the reshaped dataset \(\mathbf{Y}\):
-
from GPy.util import pca
-p = pca.PCA(Y) # create PCA class with digits dataset
-
The resulting plot will show the lower dimensional representation of the digits in 2 dimensions.
-
Gaussian Process Latent Variable Model
-
The Gaussian Process Latent Variable Model (GP-LVM) (Lawrence, 2005) embeds PCA into a Gaussian process framework, where the latent inputs \(\mathbf{Z}\) are learnt as hyperparameters and the mapping variables \(\mathbf{W}\) are integrated out. The advantage of this interpretation is it allows PCA to be generalized in a non linear way by replacing the resulting linear covariance witha non linear covariance. But first, let’s see how GPLVM is equivalent to PCA using an automatic relevance determination (ARD, see e.g. Bishop (2006)) linear kernel:
-
input_dim =4# How many latent dimensions to use
+labels = data['str_lbls']
You can try to plot some of the digits using plt.matshow (the digit images have size 16x16).
Principal component analysis (PCA) finds a rotation of the observed outputs, such that the rotated principal component (PC) space maximizes the variance of the data observed, sorted from most to least important (most to least variable in the corresponding PC).
In order to apply PCA in an easy way, we have included a PCA module in pca.py. You can import the module by import <path.to.pca> (without the ending .py!). To run PCA on the digits we have to reshape (Hint: np.reshape ) digits .
What is the right shape \(n\times d\) to use?
We will call the reshaped observed outputs \(\mathbf{Y}\) in the following.
Yn = Y#Y-Y.mean()
Now let’s run PCA on the reshaped dataset \(\mathbf{Y}\):
from GPy.util import pca
+p = pca.PCA(Y) # create PCA class with digits dataset
The resulting plot will show the lower dimensional representation of the digits in 2 dimensions.
Gaussian Process Latent Variable Model
The Gaussian Process Latent Variable Model (GP-LVM) (Lawrence, 2005) embeds PCA into a Gaussian process framework, where the latent inputs \(\mathbf{Z}\) are learnt as hyperparameters and the mapping variables \(\mathbf{W}\) are integrated out. The advantage of this interpretation is it allows PCA to be generalized in a non linear way by replacing the resulting linear covariance witha non linear covariance. But first, let’s see how GPLVM is equivalent to PCA using an automatic relevance determination (ARD, see e.g. Bishop (2006)) linear kernel:
input_dim =4# How many latent dimensions to usekernel = GPy.kern.Linear(input_dim, ARD=True) # ARD kernelm = GPy.models.GPLVM(Yn, input_dim=input_dim, kernel=kernel)
-m.optimize(messages=1, max_iters=1000) # optimize for 1000 iterations
-
As you can see the solution with a linear kernel is the same as the PCA solution with the exception of rotational changes and axis flips.
-
For the sake of time, the solution you see was only running for 1000 iterations, thus it might not be converged fully yet. The GP-LVM proceeds by iterative optimization of the inputs to the covariance. As we saw in the lecture earlier, for the linear covariance, these latent points can be optimized with an eigenvalue problem, but generally, for non-linear covariance functions, we are obliged to use gradient based optimization.
Motion capture data from the CMU motion capture data base (CMU Motion Capture Lab, 2003).
-
import pods
-
You can download any subject and motion from the data set. Here we will download motion 01 from subject 35.
-
subject='35'
-motion=['01']
-
data = pods.datasets.cmu_mocap(subject, motion)
-
The data dictionary contains the keys ‘Y’ and ‘skel’, which represent the data and the skeleton..
-
data['Y'].shape
-
The data was used in the hierarchical GP-LVM paper (Lawrence and Moore, 2007) in an experiment that was also recreated in the Deep Gaussian process paper (Damianou and Lawrence, 2013).
-
print(data['citation'])
-
And extra information about the data is included, as standard, under the keys info and details.
-
print(data['info'])
+m.optimize(messages=1, max_iters=1000) # optimize for 1000 iterations
As you can see the solution with a linear kernel is the same as the PCA solution with the exception of rotational changes and axis flips.
For the sake of time, the solution you see was only running for 1000 iterations, thus it might not be converged fully yet. The GP-LVM proceeds by iterative optimization of the inputs to the covariance. As we saw in the lecture earlier, for the linear covariance, these latent points can be optimized with an eigenvalue problem, but generally, for non-linear covariance functions, we are obliged to use gradient based optimization.
Motion capture data from the CMU motion capture data base (CMU Motion Capture Lab, 2003).
import pods
You can download any subject and motion from the data set. Here we will download motion 01 from subject 35.
subject='35'
+motion=['01']
data = pods.datasets.cmu_mocap(subject, motion)
The data dictionary contains the keys ‘Y’ and ‘skel,’ which represent the data and the skeleton..
data['Y'].shape
The data was used in the hierarchical GP-LVM paper (Lawrence and Moore, 2007) in an experiment that was also recreated in the Deep Gaussian process paper (Damianou and Lawrence, 2013).
print(data['citation'])
And extra information about the data is included, as standard, under the keys info and details.
The original data has the figure moving across the floor during the motion capture sequence. We can make the figure walk ‘in place’, by setting the x, y, z positions of the root node to zero. This makes it easier to visualize the result.
-
# Make figure move in place.
-data['Y'][:, 0:3] =0.0
-
We can also remove the mean of the data.
-
Y = data['Y']
-
Now we create the GP-LVM model.
-
import GPy
-
model = GPy.models.GPLVM(Y, 2, normalizer=True)
-
Now we optimize the model.
-
model.optimize(messages=True, max_f_eval=10000)
-
-
-
-
-
-
-
-
-
Figure: Gaussian process latent variable model visualisation of CMU motion capture data set.
The original data has the figure moving across the floor during the motion capture sequence. We can make the figure walk ‘in place,’ by setting the x, y, z positions of the root node to zero. This makes it easier to visualize the result.
# Make figure move in place.
+data['Y'][:, 0:3] =0.0
We can also remove the mean of the data.
Y = data['Y']
Now we create the GP-LVM model.
import GPy
model = GPy.models.GPLVM(Y, 2, normalizer=True)
Now we optimize the model.
model.optimize(messages=True, max_f_eval=10000)
Figure: Gaussian process latent variable model visualisation of CMU motion capture data set.
Graph diffusion prior for enforcing connectivity between motions. \[\log p(\mathbf{X}) = w_c \sum_{i,j} \log K_{ij}^d\] with the graph diffusion kernel \(\mathbf{K}^d\) obtain from \[K_{ij}^d = \exp(\beta \mathbf{H})
\qquad \text{with} \qquad \mathbf{H} = -\mathbf{T}^{-1/2} \mathbf{L} \mathbf{T}^{-1/2}\] the graph Laplacian, and \(\mathbf{T}\) is a diagonal matrix with \(T_{ii} = \sum_j w(\mathbf{ x}_i, \mathbf{ x}_j)\), \[L_{ij} = \begin{cases} \sum_k w(\mathbf{ x}_i,\mathbf{ x}_k) & \text{if $i=j$}
\\
-w(\mathbf{ x}_i,\mathbf{ x}_j) &\text{otherwise.}
-\end{cases}\] and \(w(\mathbf{ x}_i,\mathbf{ x}_j) = || \mathbf{ x}_i - \mathbf{ x}_j||^{-p}\) measures similarity.
-
-
-Levine et al. (2012)
-
-
Character Control: Results
-
-
-
-
-
-
-
-
-
Figure: Character control in the latent space described the the GP-LVM Levine et al. (2012).
-
-
-
Data for Blastocyst Development in Mice: Single Cell TaqMan Arrays
-
Now we analyze some single cell data from Guo et al. (2010). Tey performed qPCR TaqMan array on single cells from the developing blastocyst in mouse. The data is taken from the early stages of development when the Blastocyst is forming. At the 32 cell stage the data is already separated into the trophectoderm (TE) which goes onto form the placenta and the inner cellular mass (ICM). The ICM further differentiates into the epiblast (EPI)—which gives rise to the endoderm, mesoderm and ectoderm—and the primitive endoderm (PE) which develops into the amniotic sack. Guo et al. (2010) selected 48 genes for expression measurement. They labelled the resulting cells and their labels are included as an aide to visualization.
-
They first visualized their data using principal component analysis. In the first two principal components this fails to separate the domains. This is perhaps because the principal components are dominated by the variation in the 64 cell systems. This in turn may be because there are more cells from the data set in that regime, and may be because the natural variation is greater. We first recreate their visualization using principal component analysis.
-
In this notebook we will perform PCA on the original data, showing that the different regimes do not separate.
-
Next we load in the data. We’ve provided a convenience function for loading in the data with pods. It is loaded in as a pandas DataFrame. This allows us to summarize it with the describe attribute.
-
import pods
-
data = pods.datasets.singlecell()
+\end{cases}\] and \(w(\mathbf{ x}_i,\mathbf{ x}_j) = || \mathbf{ x}_i - \mathbf{ x}_j||^{-p}\) measures similarity.
Levine et al. (2012)
Character Control: Results
Figure: Character control in the latent space described the the GP-LVM Levine et al. (2012).
Data for Blastocyst Development in Mice: Single Cell TaqMan Arrays
Now we analyze some single cell data from Guo et al. (2010). Tey performed qPCR TaqMan array on single cells from the developing blastocyst in mouse. The data is taken from the early stages of development when the Blastocyst is forming. At the 32 cell stage the data is already separated into the trophectoderm (TE) which goes onto form the placenta and the inner cellular mass (ICM). The ICM further differentiates into the epiblast (EPI)—which gives rise to the endoderm, mesoderm and ectoderm—and the primitive endoderm (PE) which develops into the amniotic sack. Guo et al. (2010) selected 48 genes for expression measurement. They labelled the resulting cells and their labels are included as an aide to visualization.
They first visualized their data using principal component analysis. In the first two principal components this fails to separate the domains. This is perhaps because the principal components are dominated by the variation in the 64 cell systems. This in turn may be because there are more cells from the data set in that regime, and may be because the natural variation is greater. We first recreate their visualization using principal component analysis.
In this notebook we will perform PCA on the original data, showing that the different regimes do not separate.
Next we load in the data. We’ve provided a convenience function for loading in the data with pods. It is loaded in as a pandas DataFrame. This allows us to summarize it with the describe attribute.
import pods
data = pods.datasets.singlecell()Y = data['Y']
-Y.describe
-
Principal Component Analysis
-
Now we follow Guo et al. (2010) in performing PCA on the data. Rather than calling a ‘PCA routine’, here we break the algorithm down into its steps: compute the data covariance, compute the eigenvalues and eigenvectors and sort according to magnitude of eigenvalue. Because we want to visualize the data, we’ve chose to compute the eigenvectors of the inner product matrix rather than the covariance matrix. This allows us to plot the eigenvalues directly. However, this is less efficient (in this case because the number of genes is smaller than the number of data) than computing the eigendecomposition of the covariance matrix.
-
import numpy as np
-
# obtain a centred version of data.
+Y.describe
Principal Component Analysis
Now we follow Guo et al. (2010) in performing PCA on the data. Rather than calling a ‘PCA routine,’ here we break the algorithm down into its steps: compute the data covariance, compute the eigenvalues and eigenvectors and sort according to magnitude of eigenvalue. Because we want to visualize the data, we’ve chose to compute the eigenvectors of the inner product matrix rather than the covariance matrix. This allows us to plot the eigenvalues directly. However, this is less efficient (in this case because the number of genes is smaller than the number of data) than computing the eigendecomposition of the covariance matrix.
import numpy as np
# obtain a centred version of data.centredY = Y - Y.mean()# compute inner product matrixC = np.dot(centredY,centredY.T)
@@ -463,165 +128,13 @@
Principal Component Analysis
# sort eigenvalues and vectors according to sizeind = V.argsort()ev = V[ind[::-1]]
-U = U[:, ind[::-1]]
-
To visualize the result, we now construct a simple helper function. This will ensure that the plots have the same legends as the GP-LVM plots we use below.
-
PCA Result
-
Now, using the helper function we can plot the results with appropriate labels.
-
-
-
-
-
-
-
-
-
Figure: First two principal compoents of the Guo et al. (2010) blastocyst development data.
Work done as a collaboration between Max Zwiessele, Oliver Stegle and Neil D. Lawrence.
-
Then, we follow Buettner and Theis (2012) in applying the GP-LVM to the data. There is a slight pathology in the result, one which they fixed by using priors that were dependent on the developmental stage. We then show how the Bayesian GP-LVM doesn’t exhibit those pathologies and gives a nice results that seems to show the lineage of the cells.
-
They used modified prior to ensure that small differences between cells at the same differential stage were preserved. Here we apply a standard GP-LVM (no modified prior) to the data.
To visualize the result, we now construct a simple helper function. This will ensure that the plots have the same legends as the GP-LVM plots we use below.
PCA Result
Now, using the helper function we can plot the results with appropriate labels.
Figure: First two principal compoents of the Guo et al. (2010) blastocyst development data.
Work done as a collaboration between Max Zwiessele, Oliver Stegle and Neil D. Lawrence.
Then, we follow Buettner and Theis (2012) in applying the GP-LVM to the data. There is a slight pathology in the result, one which they fixed by using priors that were dependent on the developmental stage. We then show how the Bayesian GP-LVM doesn’t exhibit those pathologies and gives a nice results that seems to show the lineage of the cells.
They used modified prior to ensure that small differences between cells at the same differential stage were preserved. Here we apply a standard GP-LVM (no modified prior) to the data.
Isomap first builds a neighbourhood graph, and then uses distances along this graph to approximate the geodesic distance between points. These distances are then visualized by performing classical multidimensional scaling (which involves computing the eigendecomposition of the centred distance matrix). As the neighborhood size is increased to match the data, principal component analysis is recovered (or strictly speaking, principal coordinate analysis). The fewer the neighbors, the more ‘non-linear’ the isomap embeddings are.
Next we try locally linear embedding. In locally linear embedding a neighborhood is also computed. Each point is then reconstructed by it’s neighbors using a linear weighting. This implies a locally linear patch is being fitted to the data in that region. These patches are assimilated into a large \(n\times n\) matrix and a lower dimensional data set which reflects the same relationships is then sought. Quite a large number of neighbours needs to be selected for the data to not collapse in on itself. When a large number of neighbours is selected the embedding is more linear and begins to look like PCA. However, the algorithm does not converge to PCA in the limit as the number of neighbors approaches \(n\).
-Bishop, C.M., 2006. Pattern recognition and machine learning. springer.
-
-
-Bishop, C.M., James, G.D., 1993. Analysis of multiphase flows using dual-energy gamma densitometry and neural networks. Nuclear Instruments and Methods in Physics Research A327, 580–593. https://doi.org/10.1016/0168-9002(93)90728-Z
-
-
-Buettner, F., Theis, F.J., 2012. A novel approach for resolving differences in single-cell gene expression patterns from zygote to blastocyst. Bioinformatics 28, i626–i632. https://doi.org/10.1093/bioinformatics/bts385
-
-
-CMU Motion Capture Lab, 2003. The CMU mocap database.
-
-
-Damianou, A., Lawrence, N.D., 2013. Deep Gaussian processes. pp. 207–215.
-
-
-de Campos, T.E., Babu, B.R., Varma, M., 2009. Character recognition in natural images, in: Proceedings of the Fourth International Conference on Computer Vision Theory and Applications - Volume 2: VISAPP, (VISIGRAPP 2009). INSTICC; SciTePress, pp. 273–280. https://doi.org/10.5220/0001770102730280
-
-
-Guo, G., Huss, M., Tong, G.Q., Wang, C., Sun, L.L., Clarke, N.D., Robsonemail, P., 2010. Resolution of cell fate decisions revealed by single-cell gene expression analysis from zygote to blastocyst. Developmental Cell 18, 675–685. https://doi.org/10.1016/j.devcel.2010.02.012
-
-
-Lawrence, N.D., 2005. Probabilistic non-linear principal component analysis with Gaussian process latent variable models. Journal of Machine Learning Research 6, 1783–1816.
-
-
-Lawrence, N.D., Moore, A.J., 2007. Hierarchical Gaussian process latent variable models. pp. 481–488.
-
-
-Levine, S., Wang, J.M., Haraux, A., Popović, Z., Koltun, V., 2012. Continuous character control with low-dimensional embeddings. ACM Transactions on Graphics (SIGGRAPH 2012) 31.
-
-
-Roweis, S.T., n.d. EM algorithms for PCA and SPCA. pp. 626–632.
-
-
-Tipping, M.E., Bishop, C.M., 1999b. Mixtures of probabilistic principal component analysers. Neural Computation 11, 443–482.
-
-
-Tipping, M.E., Bishop, C.M., 1999a. Probabilistic principal component analysis. Journal of the Royal Statistical Society, B 6, 611–622. https://doi.org/doi:10.1111/1467-9868.00196
-
-
+model.optimize(messages=True)
Figure: Visualisation of the Guo et al. (2010) blastocyst development data with the GP-LVM.
Figure: The ARD parameters of the GP-LVM for the Guo et al. (2010) blastocyst development data.
Isomap first builds a neighbourhood graph, and then uses distances along this graph to approximate the geodesic distance between points. These distances are then visualized by performing classical multidimensional scaling (which involves computing the eigendecomposition of the centred distance matrix). As the neighborhood size is increased to match the data, principal component analysis is recovered (or strictly speaking, principal coordinate analysis). The fewer the neighbors, the more ‘non-linear’ the isomap embeddings are.
Next we try locally linear embedding. In locally linear embedding a neighborhood is also computed. Each point is then reconstructed by it’s neighbors using a linear weighting. This implies a locally linear patch is being fitted to the data in that region. These patches are assimilated into a large \(n\times n\) matrix and a lower dimensional data set which reflects the same relationships is then sought. Quite a large number of neighbours needs to be selected for the data to not collapse in on itself. When a large number of neighbours is selected the embedding is more linear and begins to look like PCA. However, the algorithm does not converge to PCA in the limit as the number of neighbors approaches \(n\).
Bishop, C.M., 2006. Pattern recognition and machine learning. springer.
Bishop, C.M., James, G.D., 1993. Analysis of multiphase flows using dual-energy gamma densitometry and neural networks. Nuclear Instruments and Methods in Physics Research A327, 580–593. https://doi.org/10.1016/0168-9002(93)90728-Z
Buettner, F., Theis, F.J., 2012. A novel approach for resolving differences in single-cell gene expression patterns from zygote to blastocyst. Bioinformatics 28, i626–i632. https://doi.org/10.1093/bioinformatics/bts385
CMU Motion Capture Lab, 2003. The CMU mocap database.
Damianou, A., Lawrence, N.D., 2013. Deep Gaussian processes. pp. 207–215.
de Campos, T.E., Babu, B.R., Varma, M., 2009. Character recognition in natural images, in: Proceedings of the Fourth International Conference on Computer Vision Theory and Applications - Volume 2: VISAPP, (VISIGRAPP 2009). INSTICC; SciTePress, pp. 273–280. https://doi.org/10.5220/0001770102730280
Guo, G., Huss, M., Tong, G.Q., Wang, C., Sun, L.L., Clarke, N.D., Robsonemail, P., 2010. Resolution of cell fate decisions revealed by single-cell gene expression analysis from zygote to blastocyst. Developmental Cell 18, 675–685. https://doi.org/10.1016/j.devcel.2010.02.012
Lawrence, N.D., 2005. Probabilistic non-linear principal component analysis with Gaussian process latent variable models. Journal of Machine Learning Research 6, 1783–1816.
Lawrence, N.D., Moore, A.J., 2007. Hierarchical Gaussian process latent variable models. pp. 481–488.
Levine, S., Wang, J.M., Haraux, A., Popović, Z., Koltun, V., 2012. Continuous character control with low-dimensional embeddings. ACM Transactions on Graphics (SIGGRAPH 2012) 31.
Roweis, S.T., n.d. EM algorithms for PCA and SPCA. pp. 626–632.
Tipping, M.E., Bishop, C.M., 1999b. Mixtures of probabilistic principal component analysers. Neural Computation 11, 443–482.
Tipping, M.E., Bishop, C.M., 1999a. Probabilistic principal component analysis. Journal of the Royal Statistical Society, B 6, 611–622. https://doi.org/doi:10.1111/1467-9868.00196
diff --git a/_notebooks/05-multi-output-gps.ipynb b/_notebooks/05-multi-output-gps.ipynb
index 990a573..4299705 100644
--- a/_notebooks/05-multi-output-gps.ipynb
+++ b/_notebooks/05-multi-output-gps.ipynb
@@ -29,6 +29,8 @@
"metadata": {},
"source": [
"\n",
+ "\n",
+ "\n",
"\n",
"\n",
"\n",
@@ -210,7 +212,7 @@
"to use interface to GPs. One which allowed the user to focus on the\n",
"modelling rather than the mathematics.\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: GPy is a BSD licensed software code base for implementing\n",
"Gaussian process models in Python. It is designed for teaching and\n",
@@ -307,7 +309,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Illustration of the Kronecker product."
]
@@ -325,7 +327,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Kronecker product between two matrices."
]
@@ -400,7 +402,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: The marginal distribution for the first three variables\n",
"(highlighted) is givne by $\\mathbf{K}$ when the form of stacking is\n",
@@ -473,7 +475,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: The marginal distribution for the first three variables\n",
"(highlighted) is independent when the form of stacking is\n",
@@ -486,7 +488,7 @@
"source": [
"## Mapping from Latent Process to Observed\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: Mapping from latent process to observed"
]
@@ -527,7 +529,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: "
]
@@ -793,9 +795,9 @@
"\n",
"\n",
"\n",
- "\n",
+ "\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: Intrinsic coregionalization model covariance function."
]
@@ -1033,7 +1035,7 @@
"- 100m, 200m, 400m\n",
"- In early years of olympics not all events run.\n",
"\n",
- "\n",
+ "\n",
"Image from Wikimedia Commons by [Darren\n",
"Wilkinson](https://www.staff.ncl.ac.uk/d.j.wilkinson/)"
]
@@ -1189,7 +1191,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Olympic sprint gold medal winning times from Rogers and\n",
"Girolami (2011).\n",
@@ -1199,6 +1201,27 @@
"for example the women’s 400 m only started in 1964."
]
},
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "import pods\n",
+ "import numpy as np"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "data = pods.datasets.olympic_sprints()\n",
+ "X = data['X']\n",
+ "y = data['Y']"
+ ]
+ },
{
"cell_type": "markdown",
"metadata": {},
@@ -1359,7 +1382,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Gaussian process fit to the Olympic Sprint data.\n",
"\n",
@@ -1410,7 +1433,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Gaussian process fit to the Olympic Sprint data.\n",
"\n",
@@ -1464,7 +1487,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Gaussian process fit to the Olympic Sprint data.\n",
"\n",
diff --git a/_notebooks/08-unsupervised-learning-with-gps.ipynb b/_notebooks/08-unsupervised-learning-with-gps.ipynb
index b7e07f7..f6d927c 100644
--- a/_notebooks/08-unsupervised-learning-with-gps.ipynb
+++ b/_notebooks/08-unsupervised-learning-with-gps.ipynb
@@ -5,14 +5,14 @@
"metadata": {},
"source": [
"# Unsupervised Learning with Gaussian Processes"
- ],
- "id": "7c1f8f7a-7300-49f2-98ed-7eb32a0cd1e4"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
- "source": [],
- "id": "027b2e68-9f59-4684-8cc1-b12d8f8e706a"
+ "source": [
+ "**Abstract**: null"
+ ]
},
{
"cell_type": "markdown",
@@ -20,14 +20,15 @@
"source": [
"$$\n",
"$$"
- ],
- "id": "3f4a9a6d-9656-425b-8615-e68da893bd07"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"\n",
+ "\n",
+ "\n",
"\n",
"\n",
"\n",
@@ -39,8 +40,7 @@
""
- ],
- "id": "02543def-6f70-4604-931d-2315f793f1ad"
+ ]
},
{
"cell_type": "markdown",
@@ -48,14 +48,13 @@
"source": [
"## Gaussian Process Summer School notebook setup\n",
"\n",
- "\\[\\[edit\\]\n",
"\n",
"We install packages used across the notebooks for data loading, plotting\n",
"helpers, and Gaussian process modelling."
- ],
- "id": "dbebf481-b505-4233-aeb1-8cc978d4bc45"
+ ]
},
{
"cell_type": "code",
@@ -64,8 +63,7 @@
"outputs": [],
"source": [
"import importlib.util"
- ],
- "id": "d69cb5db-a2e7-40c2-977b-c611681bc4c9"
+ ]
},
{
"cell_type": "code",
@@ -93,8 +91,7 @@
" return f'pip install {imp}'\n",
" else:\n",
" return f'echo \"Package {imp} is already installed.\"'"
- ],
- "id": "15677609-3132-4e5e-99c7-e86b725ed280"
+ ]
},
{
"cell_type": "code",
@@ -103,8 +100,7 @@
"outputs": [],
"source": [
"cmd = install_command('pods')"
- ],
- "id": "38635e29-cdc2-4745-8bd5-b994abb72ad6"
+ ]
},
{
"cell_type": "code",
@@ -113,8 +109,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "4debb966-4a96-4fd9-b176-d670d8e4e55f"
+ ]
},
{
"cell_type": "code",
@@ -123,8 +118,7 @@
"outputs": [],
"source": [
"cmd = install_command('notutils')"
- ],
- "id": "7580196e-a72f-41d8-b38b-b41402d619a9"
+ ]
},
{
"cell_type": "code",
@@ -133,8 +127,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "be7f44e9-433d-488c-ad45-adf725d3f05d"
+ ]
},
{
"cell_type": "code",
@@ -143,8 +136,7 @@
"outputs": [],
"source": [
"cmd = install_command('mlai')"
- ],
- "id": "243fa963-dc73-4b17-a642-ab0a28bd5d51"
+ ]
},
{
"cell_type": "code",
@@ -153,8 +145,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "2c995b24-de59-4012-a106-fff657f0c2f4"
+ ]
},
{
"cell_type": "code",
@@ -174,8 +165,7 @@
" )\n",
"\n",
"plt.rcParams.update({'font.size': 22})"
- ],
- "id": "9600b520-1df3-4eeb-a33a-9c0284aeb300"
+ ]
},
{
"cell_type": "markdown",
@@ -185,8 +175,7 @@
"sns.set_style('darkgrid')\n",
"sns.set_context('paper')\n",
"sns.set_palette('colorblind')}-->"
- ],
- "id": "886103e6-91ab-4075-a5d6-365976969b49"
+ ]
},
{
"cell_type": "code",
@@ -195,8 +184,7 @@
"outputs": [],
"source": [
"cmd = install_command('GPy')"
- ],
- "id": "04c151b3-3927-4d8f-b1e0-3882fbe89bd3"
+ ]
},
{
"cell_type": "code",
@@ -205,8 +193,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "ff33df91-9d99-43cc-8c08-780bd37f20f4"
+ ]
},
{
"cell_type": "markdown",
@@ -214,8 +201,8 @@
"source": [
"## GPy: A Gaussian Process Framework in Python\n",
"\n",
- "\\[\\[edit\\]\n",
"\n",
"Gaussian processes are a flexible tool for non-parametric analysis with\n",
@@ -223,7 +210,7 @@
"to use interface to GPs. One which allowed the user to focus on the\n",
"modelling rather than the mathematics.\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: GPy is a BSD licensed software code base for implementing\n",
"Gaussian process models in Python. It is designed for teaching and\n",
@@ -246,8 +233,7 @@
"\n",
"The documentation for GPy can be found\n",
"[here](https://gpy.readthedocs.io/en/latest/)."
- ],
- "id": "28fe3de2-0228-4483-b0b9-1ec1c6690330"
+ ]
},
{
"cell_type": "markdown",
@@ -255,8 +241,8 @@
"source": [
"## Probabilistic PCA\n",
"\n",
- "\\[\\[edit\\]\n",
"\n",
"This linear relationship between the observed data and the latent\n",
@@ -288,8 +274,7 @@
"(Tipping and Bishop, 1999a), provides a principled framework that not\n",
"only recovers classical PCA as a special case when $\\sigma^2 \\to 0$, but\n",
"also enables extensions like handling missing data and mixture models."
- ],
- "id": "5d5ab328-0d20-4777-aa88-e15130daac8c"
+ ]
},
{
"cell_type": "code",
@@ -298,8 +283,7 @@
"outputs": [],
"source": [
"cmd = install_command('daft')"
- ],
- "id": "7de34a1b-639e-4d4c-a0db-c3be2ce26561"
+ ]
},
{
"cell_type": "code",
@@ -308,8 +292,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "f1a8d677-98ad-48ea-b7ed-c0e0138590bf"
+ ]
},
{
"cell_type": "code",
@@ -320,8 +303,7 @@
"from mlai import plot\n",
"import mlai\n",
"from matplotlib import pyplot as plt"
- ],
- "id": "c72a9eee-b20c-4eb3-8b0e-0815feaf8cf1"
+ ]
},
{
"cell_type": "code",
@@ -332,18 +314,16 @@
"pgm = plot.ppca_graphical_model()\n",
"filename = mlai.filename_join('ppca_graphical_model.svg', directory='./dimred')\n",
"pgm.render().figure.savefig(filename, transparent=True)"
- ],
- "id": "342ded95-87c8-43b3-8d71-caf4d87ab6f1"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Graphical model representing probabilistic PCA."
- ],
- "id": "e6eebd55-d26d-4e0d-b824-81c02726074d"
+ ]
},
{
"cell_type": "markdown",
@@ -382,8 +362,7 @@
"$$ where $\\sigma^2$ is the noise variance. Note that if $\\sigma^2$ is\n",
"larger than any particular eigenvalue, then that eigenvalue (along with\n",
"its corresponding eigenvector) is *discarded* from the solution."
- ],
- "id": "a13d78df-e26c-4144-a815-5d3779ea4b41"
+ ]
},
{
"cell_type": "markdown",
@@ -404,8 +383,7 @@
"holds and the manifold is approximately linear. When the manifold is\n",
"nonlinear, we need more sophisticated methods like kernel PCA or neural\n",
"network-based approaches."
- ],
- "id": "8e482b2f-adaf-4664-b020-08253a9961f3"
+ ]
},
{
"cell_type": "markdown",
@@ -414,8 +392,7 @@
"## Python Implementation of Probabilistic PCA\n",
"\n",
"We will now implement this algorithm in python."
- ],
- "id": "ea8a2f6d-16af-4b67-b55a-5e353dffb0c0"
+ ]
},
{
"cell_type": "code",
@@ -424,8 +401,7 @@
"outputs": [],
"source": [
"import numpy as np"
- ],
- "id": "652514e6-327e-4821-8347-53c4b2f6d353"
+ ]
},
{
"cell_type": "code",
@@ -436,8 +412,7 @@
"from mlai import ppca_eig\n",
"import inspect\n",
"file_path = inspect.getfile(ppca_eig)"
- ],
- "id": "75aa1721-fb16-489d-bb5d-3dd56a39d370"
+ ]
},
{
"cell_type": "code",
@@ -446,8 +421,7 @@
"outputs": [],
"source": [
"%load -s ppca_eig {file_path}"
- ],
- "id": "8fbef982-cfa9-46fb-921c-c60709eb2964"
+ ]
},
{
"cell_type": "code",
@@ -456,8 +430,7 @@
"outputs": [],
"source": [
"ppca = ppca_eig"
- ],
- "id": "59983195-023c-4939-aace-0d0bcefd16f2"
+ ]
},
{
"cell_type": "markdown",
@@ -474,8 +447,7 @@
"We saw a similar issue arise when , where we also wished to avoid\n",
"computation of $\\mathbf{Z}^\\top\\mathbf{Z}$ (or in the case of\n",
"$\\boldsymbol{\\Phi}^\\top\\boldsymbol{\\Phi}$)."
- ],
- "id": "8f8ca1d0-2dd3-4086-9cc7-65ae97e569c8"
+ ]
},
{
"cell_type": "markdown",
@@ -506,8 +478,7 @@
":})^\\top(\\mathbf{ y}_{i, :} - \\mathbf{W}\\mathbf{ z}_{i, :}) - \\frac{1}{2}\n",
"\\mathbf{ z}_{i, :}^\\top \\mathbf{ z}_{i, :} + \\text{const}\n",
"$$"
- ],
- "id": "195eeba2-1709-4803-ac2d-93e68b0a21a0"
+ ]
},
{
"cell_type": "markdown",
@@ -526,8 +497,7 @@
"= \\mathbf{C}_x \\sigma^{-2}\\mathbf{W}^\\top \\mathbf{ y}_{i, :} \n",
"$$ Compare this to the posterior for the Bayesian linear regression from\n",
"last week, do they have similar forms? What matches and what differs?"
- ],
- "id": "5f8d8c63-37a4-417c-b913-615300cb930f"
+ ]
},
{
"cell_type": "markdown",
@@ -536,8 +506,7 @@
"### Exercise 1 Answer\n",
"\n",
"Write your answer to Exercise 1 here"
- ],
- "id": "bc12348c-aaec-4bf5-889f-0277f0ff0c91"
+ ]
},
{
"cell_type": "markdown",
@@ -546,8 +515,7 @@
"## Python Implementation of the Posterior\n",
"\n",
"Now let’s implement the system in code."
- ],
- "id": "bfadfd3e-0ece-4f64-a1e5-aa16a4aa715e"
+ ]
},
{
"cell_type": "markdown",
@@ -569,8 +537,7 @@
"Don’t forget to subtract the mean of the data `Y` inside your function\n",
"before computing the posterior: remember we assumed at the beginning of\n",
"our analysis that the data had been centred (i.e. the mean was removed)."
- ],
- "id": "4d43055a-e349-4ce9-9f86-ee7d47f7c1ee"
+ ]
},
{
"cell_type": "code",
@@ -594,8 +561,7 @@
" mu_x = \n",
" return mu_x, C_x\n",
"\n"
- ],
- "id": "17304bf6-a206-4df0-859c-314577ff418d"
+ ]
},
{
"cell_type": "markdown",
@@ -623,8 +589,7 @@
"The eigenvalues of the matrix $\\mathbf{Y}^\\top\\mathbf{Y}$ are then given\n",
"by the singular values of the matrix $\\mathbf{Y}^\\top$ squared and the\n",
"eigenvectors are given by $\\mathbf{U}$."
- ],
- "id": "f4a4f91d-a9f7-4083-9908-8069b9060ff6"
+ ]
},
{
"cell_type": "markdown",
@@ -654,8 +619,7 @@
"\\boldsymbol{ \\mu}_x = \\mathbf{D}\\mathbf{U}^\\top \\mathbf{ y}_{i, :}\n",
"$$ where $\\mathbf{D}$ is a diagonal matrix with diagonal elements given\n",
"by $d_{i} = \\frac{\\ell_i}{\\sigma^2 + \\ell_i^2}$."
- ],
- "id": "000e5490-67df-42da-98ce-2b9f7aad1a79"
+ ]
},
{
"cell_type": "code",
@@ -665,8 +629,7 @@
"source": [
"import scipy as sp\n",
"import numpy as np"
- ],
- "id": "840b0eed-95de-4c27-831b-723cd5af9044"
+ ]
},
{
"cell_type": "code",
@@ -677,8 +640,7 @@
"from mlai import ppca_svd\n",
"import inspect\n",
"file_path = inspect.getfile(ppca_svd)"
- ],
- "id": "d69da568-44da-43a4-a4cb-cf99f60f3974"
+ ]
},
{
"cell_type": "code",
@@ -687,8 +649,7 @@
"outputs": [],
"source": [
"%load -s ppca_svd {file_path}"
- ],
- "id": "5db6386b-c902-4ec0-aae3-be58307c421d"
+ ]
},
{
"cell_type": "code",
@@ -699,8 +660,7 @@
"from mlai import ppca_posterior\n",
"import inspect\n",
"file_path = inspect.getfile(ppca_posterior)"
- ],
- "id": "8cbbae05-e0f3-42c2-a2ba-8790c03ac70b"
+ ]
},
{
"cell_type": "code",
@@ -709,8 +669,7 @@
"outputs": [],
"source": [
"%load -s ppca_posterior {file_path}"
- ],
- "id": "580efecd-0993-45df-a611-02d9895dc1bb"
+ ]
},
{
"cell_type": "code",
@@ -720,8 +679,7 @@
"source": [
"ppca = ppca_svd\n",
"posterior = ppca_posterior"
- ],
- "id": "30041ccb-8d60-417f-aef3-7dda260157b4"
+ ]
},
{
"cell_type": "markdown",
@@ -729,15 +687,14 @@
"source": [
"## Scikit-learn implementation PCA\n",
"\n",
- "\\[\\[edit\\]\n",
"\n",
"We’ve implemented PCA as part of supporting the learning process, but in\n",
"practice we can use the `scikit-learn` implementation. Let’s try it on\n",
"the oil flow data."
- ],
- "id": "96d4c027-a882-480c-8b09-fe86911f5b78"
+ ]
},
{
"cell_type": "markdown",
@@ -745,16 +702,15 @@
"source": [
"## Oil Flow Data\n",
"\n",
- "\\[\\[edit\\]\n",
"\n",
"This data set is from a physics-based simulation of oil flow in a\n",
"pipeline. The data was generated as part of a project to determine the\n",
"fraction of oil, water and gas in North Sea oil pipes (Bishop and James,\n",
"1993)."
- ],
- "id": "fe6bdb82-3eea-4fa2-a283-4ac012c55299"
+ ]
},
{
"cell_type": "code",
@@ -763,8 +719,7 @@
"outputs": [],
"source": [
"import pods"
- ],
- "id": "6c029649-b8a9-4495-ae03-5f2c93144261"
+ ]
},
{
"cell_type": "code",
@@ -773,8 +728,7 @@
"outputs": [],
"source": [
"data = pods.datasets.oil()"
- ],
- "id": "7cf658c5-49d1-47b2-bb3d-7b8c4a5bbf61"
+ ]
},
{
"cell_type": "markdown",
@@ -783,8 +737,7 @@
"The data consists of 1000 12-dimensional observations of simulated oil\n",
"flow in a pipeline. Each observation is labelled according to the\n",
"multi-phase flow configuration (homogeneous, annular or laminar)."
- ],
- "id": "07b12d43-879c-4f80-8cdc-4c5992366789"
+ ]
},
{
"cell_type": "code",
@@ -802,18 +755,16 @@
"class2 = (Y[:, 2] == 1).astype(int) * 2\n",
"# Combine into single array of class labels 0,1,2\n",
"labels = class0 + class1 + class2"
- ],
- "id": "963579fc-c3ae-4902-a6f4-f5249aa562e7"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"The data is returned as a dictionary containing training and test inputs\n",
- "(‘X’, ‘Xtst’), training and test labels (‘Y’, ‘Ytst’), and the names of\n",
+ "(‘X,’ ‘Xtst’), training and test labels (‘Y,’ ‘Ytst’), and the names of\n",
"the features."
- ],
- "id": "c080f204-f542-46ae-a909-a8e1bed5f577"
+ ]
},
{
"cell_type": "code",
@@ -825,8 +776,7 @@
"import mlai.plot as plot\n",
"import mlai\n",
"import numpy as np"
- ],
- "id": "5cd3e840-b694-4e77-bf92-3fa949b17dba"
+ ]
},
{
"cell_type": "code",
@@ -848,21 +798,19 @@
"ax.legend()\n",
"\n",
"mlai.write_figure('oil-flow-data.svg', directory='./datasets')"
- ],
- "id": "47052661-7d7f-433e-8935-11c5d7d230df"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Visualization of the first two dimensions of the oil flow\n",
"data from Bishop and James (1993)\n",
"\n",
"As normal we include the citation information for the data."
- ],
- "id": "1ad9ed34-981a-43bf-89c0-65ea8e8674aa"
+ ]
},
{
"cell_type": "code",
@@ -871,8 +819,7 @@
"outputs": [],
"source": [
"print(data['citation'])"
- ],
- "id": "4777438a-6475-4769-8949-9d2aeb049b28"
+ ]
},
{
"cell_type": "markdown",
@@ -880,8 +827,7 @@
"source": [
"And extra information about the data is included, as standard, under the\n",
"keys `info` and `details`."
- ],
- "id": "0288351f-b3ad-4435-811a-5ba8e12a031f"
+ ]
},
{
"cell_type": "code",
@@ -890,8 +836,7 @@
"outputs": [],
"source": [
"print(data['details'])"
- ],
- "id": "59e3ff16-fcc9-49ab-80fb-f641071b3ff3"
+ ]
},
{
"cell_type": "code",
@@ -901,8 +846,7 @@
"source": [
"X = data['X']\n",
"Y = data['Y']"
- ],
- "id": "08b88d2c-7530-47a4-bf9b-1dd47210262c"
+ ]
},
{
"cell_type": "code",
@@ -911,8 +855,7 @@
"outputs": [],
"source": [
"cmd = install_command('scikit-learn')"
- ],
- "id": "caf1ee2e-32cc-4378-8d7d-16e45b2ea999"
+ ]
},
{
"cell_type": "code",
@@ -921,8 +864,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "cdaaaa57-59d7-41a0-9c76-6056c405d6c5"
+ ]
},
{
"cell_type": "code",
@@ -931,8 +873,7 @@
"outputs": [],
"source": [
"from sklearn.decomposition import PCA"
- ],
- "id": "d1862fc2-5b5e-4284-ad8a-13bcbfc315d8"
+ ]
},
{
"cell_type": "code",
@@ -943,8 +884,7 @@
"pca = PCA(n_components=2)\n",
"pca.fit(X)\n",
"X_pca = pca.transform(X)"
- ],
- "id": "aec31e5d-8ad2-454b-b7ec-c621855ea124"
+ ]
},
{
"cell_type": "code",
@@ -960,8 +900,7 @@
"class2 = (Y[:, 2] == 1).astype(int) * 2\n",
"# Combine into single array of class labels 0,1,2\n",
"lbls = class0 + class1 + class2"
- ],
- "id": "6357254c-4136-4092-9791-dacf85098578"
+ ]
},
{
"cell_type": "code",
@@ -972,8 +911,7 @@
"from matplotlib import pyplot as plt\n",
"import mlai\n",
"from mlai import plot"
- ],
- "id": "4f521da7-fea9-4e3f-abe2-fe82ed66e114"
+ ]
},
{
"cell_type": "code",
@@ -990,19 +928,17 @@
"ax.set_ylabel('Second principal component')\n",
"\n",
"mlai.write_figure(\"oil-flow-pca-sklearn.svg\", directory='./dimred')"
- ],
- "id": "775554b4-2ab9-44b9-86e7-75d9e5b6207e"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: PCA of the oil flow data. The flow is homogeneous, annular\n",
"and stratified."
- ],
- "id": "fd86083f-df45-458f-a49e-0a6bc2886e8e"
+ ]
},
{
"cell_type": "markdown",
@@ -1010,11 +946,10 @@
"source": [
"## Difficulty for Probabilistic Approaches\n",
"\n",
- "\\[\\[edit\\]"
- ],
- "id": "dc86e337-82c2-48b4-b553-227ee41cfdcf"
+ ]
},
{
"cell_type": "code",
@@ -1023,8 +958,7 @@
"outputs": [],
"source": [
"import mlai.plot as plot"
- ],
- "id": "5cd3ff95-540f-49de-9c65-f7840c4c5249"
+ ]
},
{
"cell_type": "code",
@@ -1033,8 +967,7 @@
"outputs": [],
"source": [
"plot.non_linear_difficulty_plot_3(diagrams='./dimred/')"
- ],
- "id": "e93d0af5-c5ed-4deb-99b7-dc42479020ef"
+ ]
},
{
"cell_type": "markdown",
@@ -1045,12 +978,11 @@
"allows you to create broader classes of probability density.\n",
"Unfortunately it renders the resulting densities *intractable*.\n",
"\n",
- "\n",
+ "\n",
"\n",
"Figure: A two dimensional grid mapped into three dimensions to form a\n",
"two dimensional manifold."
- ],
- "id": "02412e76-d084-442d-a607-27532300ddf9"
+ ]
},
{
"cell_type": "code",
@@ -1059,20 +991,18 @@
"outputs": [],
"source": [
"plot.non_linear_difficulty_plot_2(diagrams='./dimred/')"
- ],
- "id": "628609ec-dddd-4efd-9831-13380989b411"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: A one dimensional line mapped into two dimensions by two\n",
"separate independent functions. Each point can be mapped exactly through\n",
"the mappings."
- ],
- "id": "d218c0a5-2224-4404-a525-981e2a661940"
+ ]
},
{
"cell_type": "code",
@@ -1081,8 +1011,7 @@
"outputs": [],
"source": [
"cmd = install_command('daft')"
- ],
- "id": "86220e84-0781-462e-90f9-848fade58041"
+ ]
},
{
"cell_type": "code",
@@ -1091,8 +1020,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "03e7affe-99f5-486d-a89a-514e4d3c5234"
+ ]
},
{
"cell_type": "code",
@@ -1101,19 +1029,17 @@
"outputs": [],
"source": [
"plot.non_linear_difficulty_plot_1(diagrams='./dimred')"
- ],
- "id": "b3123f47-a132-4f2f-b087-4f13fd5f67b5"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: A Gaussian density over the input of a non linear function\n",
"leads to a very non Gaussian output. Here the output is multimodal."
- ],
- "id": "242b5f60-4bbe-457c-b735-41aa2878356b"
+ ]
},
{
"cell_type": "markdown",
@@ -1121,11 +1047,10 @@
"source": [
"## Getting Started and Downloading Data\n",
"\n",
- "\\[\\[edit\\]"
- ],
- "id": "4ac8a5b2-600f-46e0-b83e-3b36194f659e"
+ ]
},
{
"cell_type": "code",
@@ -1136,8 +1061,7 @@
"import numpy as np\n",
"import GPy\n",
"import string"
- ],
- "id": "1ad418e0-9654-432b-b072-e0bd3d226c56"
+ ]
},
{
"cell_type": "markdown",
@@ -1146,8 +1070,7 @@
"The following code is for plotting and to prepare the bigger models for\n",
"later useage. If you are interested, you can have a look, but this is\n",
"not essential."
- ],
- "id": "0e51f9af-c523-419e-b740-4163ff6902ba"
+ ]
},
{
"cell_type": "code",
@@ -1158,8 +1081,7 @@
"from matplotlib import pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "d3eed91e-e8c5-4bb8-bd9f-26ba55901e5a"
+ ]
},
{
"cell_type": "code",
@@ -1170,8 +1092,7 @@
"colors = [\"#3FCC94\", \"#DD4F23\", \"#C6D63B\", \"#D44271\", \n",
" \"#E4A42C\", \"#4F9139\", \"#6DDA4C\", \"#85831F\", \n",
" \"#B36A29\", \"#CF4E4A\"]"
- ],
- "id": "41526c1b-2efd-4697-88f0-7dfcb1752a07"
+ ]
},
{
"cell_type": "code",
@@ -1192,8 +1113,7 @@
" ax.scatter(*X[labels==lab].T,marker='o',color=colors[i],label=lab)\n",
" pass\n",
" pass"
- ],
- "id": "99427dc1-413f-4d0b-bf5b-c598148deeed"
+ ]
},
{
"cell_type": "markdown",
@@ -1204,8 +1124,7 @@
"will only use some of the digits for the demonstrations in this lab\n",
"class, but you can edit the code below to select different subsets of\n",
"the digit data as you wish."
- ],
- "id": "b15ac992-1fd4-40e9-a0e8-4460dfe601c2"
+ ]
},
{
"cell_type": "code",
@@ -1217,8 +1136,7 @@
"data = pods.datasets.decampos_digits(which_digits=which)\n",
"Y = data['Y']\n",
"labels = data['str_lbls']"
- ],
- "id": "1f47f5ee-b70c-454f-b25c-c46fb0529ad8"
+ ]
},
{
"cell_type": "markdown",
@@ -1226,8 +1144,7 @@
"source": [
"You can try to plot some of the digits using `plt.matshow` (the digit\n",
"images have size `16x16`)."
- ],
- "id": "063c7d71-8c67-416b-996e-cab92c413762"
+ ]
},
{
"cell_type": "markdown",
@@ -1235,8 +1152,8 @@
"source": [
"## Principal Component Analysis\n",
"\n",
- "\\[\\[edit\\]\n",
"\n",
"Principal component analysis (PCA) finds a rotation of the observed\n",
@@ -1253,8 +1170,7 @@
"\n",
"We will call the reshaped observed outputs $\\mathbf{Y}$ in the\n",
"following."
- ],
- "id": "a7ebae19-6d19-4768-8996-5958882841b2"
+ ]
},
{
"cell_type": "code",
@@ -1263,16 +1179,14 @@
"outputs": [],
"source": [
"Yn = Y#Y-Y.mean()"
- ],
- "id": "ba7585b0-e083-4912-8973-b2a2cea3be85"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"Now let’s run PCA on the reshaped dataset $\\mathbf{Y}$:"
- ],
- "id": "1b10463a-6887-48c7-8bb6-581025069e8d"
+ ]
},
{
"cell_type": "code",
@@ -1282,8 +1196,7 @@
"source": [
"from GPy.util import pca\n",
"p = pca.PCA(Y) # create PCA class with digits dataset"
- ],
- "id": "3dfe3b9c-537e-467a-a48a-0002ccf2d5ae"
+ ]
},
{
"cell_type": "markdown",
@@ -1291,8 +1204,7 @@
"source": [
"The resulting plot will show the lower dimensional representation of the\n",
"digits in 2 dimensions."
- ],
- "id": "d5b63794-2912-44fc-af39-113f217335df"
+ ]
},
{
"cell_type": "code",
@@ -1300,12 +1212,10 @@
"metadata": {},
"outputs": [],
"source": [
- "\n",
"p.plot_fracs(20) # plot first 20 eigenvalue fractions\n",
"p.plot_2d(Y,labels=labels.flatten(), colors=colors)\n",
"plt.legend()"
- ],
- "id": "769851f0-9b89-4186-9ca9-bcf68944cb5b"
+ ]
},
{
"cell_type": "markdown",
@@ -1321,8 +1231,7 @@
"resulting *linear* covariance witha non linear covariance. But first,\n",
"let’s see how GPLVM is equivalent to PCA using an automatic relevance\n",
"determination (ARD, see e.g. Bishop (2006)) linear kernel:"
- ],
- "id": "c02fe661-6c68-4c1a-888c-6e76ea3a7404"
+ ]
},
{
"cell_type": "code",
@@ -1335,8 +1244,7 @@
"m = GPy.models.GPLVM(Yn, input_dim=input_dim, kernel=kernel)\n",
"\n",
"m.optimize(messages=1, max_iters=1000) # optimize for 1000 iterations"
- ],
- "id": "de6fdca3-4fd8-4677-a1c2-b7b3fe2d5402"
+ ]
},
{
"cell_type": "code",
@@ -1347,8 +1255,7 @@
"m.kern.plot_ARD()\n",
"plot_model(m.X, m.linear.variances.argsort()[-2:], labels.flatten())\n",
"plt.legend()"
- ],
- "id": "bc5033cd-133d-4118-9ff4-4d74173849a8"
+ ]
},
{
"cell_type": "markdown",
@@ -1364,8 +1271,7 @@
"points can be optimized with an eigenvalue problem, but generally, for\n",
"non-linear covariance functions, we are obliged to use gradient based\n",
"optimization."
- ],
- "id": "c50d31e1-beae-4051-9383-1bf17ec3c051"
+ ]
},
{
"cell_type": "markdown",
@@ -1373,14 +1279,13 @@
"source": [
"## CMU Mocap Database\n",
"\n",
- "\\[\\[edit\\]\n",
"\n",
"Motion capture data from the CMU motion capture data base (CMU Motion\n",
"Capture Lab, 2003)."
- ],
- "id": "4be50ab8-2964-4ed7-aca1-7e420dcf78ad"
+ ]
},
{
"cell_type": "code",
@@ -1389,8 +1294,7 @@
"outputs": [],
"source": [
"import pods"
- ],
- "id": "6a084063-ce5b-42c3-846b-b5e3676b52f9"
+ ]
},
{
"cell_type": "markdown",
@@ -1398,8 +1302,7 @@
"source": [
"You can download any subject and motion from the data set. Here we will\n",
"download motion `01` from subject `35`."
- ],
- "id": "44a25c2b-901f-4d22-9fa6-9b16f64b2943"
+ ]
},
{
"cell_type": "code",
@@ -1409,8 +1312,7 @@
"source": [
"subject='35' \n",
"motion=['01']"
- ],
- "id": "8fea5bb7-de48-428e-aa66-6f5245d721a4"
+ ]
},
{
"cell_type": "code",
@@ -1419,17 +1321,15 @@
"outputs": [],
"source": [
"data = pods.datasets.cmu_mocap(subject, motion)"
- ],
- "id": "d4ae51cf-4c5e-438d-a288-2f576409c2de"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "The data dictionary contains the keys ‘Y’ and ‘skel’, which represent\n",
+ "The data dictionary contains the keys ‘Y’ and ‘skel,’ which represent\n",
"the data and the skeleton.."
- ],
- "id": "b00e22b8-f5aa-4bec-887a-aab30d82299a"
+ ]
},
{
"cell_type": "code",
@@ -1438,8 +1338,7 @@
"outputs": [],
"source": [
"data['Y'].shape"
- ],
- "id": "4cf22178-e0e7-41c7-95cc-3a0e20d82d37"
+ ]
},
{
"cell_type": "markdown",
@@ -1448,8 +1347,7 @@
"The data was used in the hierarchical GP-LVM paper (Lawrence and Moore,\n",
"2007) in an experiment that was also recreated in the Deep Gaussian\n",
"process paper (Damianou and Lawrence, 2013)."
- ],
- "id": "ea0580e4-1f7e-4d8a-a62a-9214d22e0d52"
+ ]
},
{
"cell_type": "code",
@@ -1458,8 +1356,7 @@
"outputs": [],
"source": [
"print(data['citation'])"
- ],
- "id": "c9cf89b1-d711-4ade-9552-201ddac785f2"
+ ]
},
{
"cell_type": "markdown",
@@ -1467,8 +1364,7 @@
"source": [
"And extra information about the data is included, as standard, under the\n",
"keys `info` and `details`."
- ],
- "id": "680cc0e4-6b2c-48c4-b23b-3ca78553c272"
+ ]
},
{
"cell_type": "code",
@@ -1479,8 +1375,7 @@
"print(data['info'])\n",
"print()\n",
"print(data['details'])"
- ],
- "id": "73f7d056-0017-4a09-82bd-10c4f07009b3"
+ ]
},
{
"cell_type": "markdown",
@@ -1488,16 +1383,15 @@
"source": [
"## CMU Motion Capture GP-LVM\n",
"\n",
- "\\[\\[edit\\]\n",
"\n",
"The original data has the figure moving across the floor during the\n",
- "motion capture sequence. We can make the figure walk ‘in place’, by\n",
+ "motion capture sequence. We can make the figure walk ‘in place,’ by\n",
"setting the x, y, z positions of the root node to zero. This makes it\n",
"easier to visualize the result."
- ],
- "id": "6026f21f-e83c-4df5-a1e1-d35ddf690745"
+ ]
},
{
"cell_type": "code",
@@ -1507,16 +1401,14 @@
"source": [
"# Make figure move in place.\n",
"data['Y'][:, 0:3] = 0.0"
- ],
- "id": "25f15178-19e3-41b2-b978-1e5c58e3341b"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"We can also remove the mean of the data."
- ],
- "id": "4f667bd2-9168-45b0-b20b-38c616671a73"
+ ]
},
{
"cell_type": "code",
@@ -1525,16 +1417,14 @@
"outputs": [],
"source": [
"Y = data['Y']"
- ],
- "id": "012903a6-f37e-4f0f-988f-7518009dde5b"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"Now we create the GP-LVM model."
- ],
- "id": "b17f89ac-180f-4418-a717-12bb0dd8daae"
+ ]
},
{
"cell_type": "code",
@@ -1543,8 +1433,7 @@
"outputs": [],
"source": [
"import GPy"
- ],
- "id": "06c309d3-e4b7-473f-93ca-cd2671433671"
+ ]
},
{
"cell_type": "code",
@@ -1553,16 +1442,14 @@
"outputs": [],
"source": [
"model = GPy.models.GPLVM(Y, 2, normalizer=True)"
- ],
- "id": "6ae8f0d3-7141-4630-8b9c-99dc0da466da"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"Now we optimize the model."
- ],
- "id": "5481a9af-ab27-4af8-bd37-2ad05f7e2170"
+ ]
},
{
"cell_type": "code",
@@ -1571,8 +1458,7 @@
"outputs": [],
"source": [
"model.optimize(messages=True, max_f_eval=10000)"
- ],
- "id": "e2b9e2c5-b27c-4b12-811d-2a5569668425"
+ ]
},
{
"cell_type": "code",
@@ -1583,8 +1469,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai\n",
"import mlai.plot as plot"
- ],
- "id": "be466f08-23bd-4a2c-bcec-1bd27d66984e"
+ ]
},
{
"cell_type": "code",
@@ -1593,8 +1478,7 @@
"outputs": [],
"source": [
"%matplotlib notebook"
- ],
- "id": "e59b62d0-edc7-4d79-9eef-9d1a932da3ef"
+ ]
},
{
"cell_type": "code",
@@ -1603,8 +1487,7 @@
"outputs": [],
"source": [
"import numpy as np"
- ],
- "id": "6d3193cf-a857-4a0d-b31f-09b3c5158cf2"
+ ]
},
{
"cell_type": "code",
@@ -1628,19 +1511,17 @@
"mlai.write_figure(figure=fig,\n",
" filename='cmu-mocap-gplvm.svg', \n",
" directory = './gplvm')"
- ],
- "id": "7c6762a0-a5e1-4c6a-8f37-758b6317b8fa"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Gaussian process latent variable model visualisation of CMU\n",
"motion capture data set."
- ],
- "id": "02eef5d8-f42b-4f6e-8ab8-a3899d63d748"
+ ]
},
{
"cell_type": "markdown",
@@ -1648,8 +1529,8 @@
"source": [
"## Example: Latent Doodle Space\n",
"\n",
- "\\[\\[edit\\]\n",
"\n",
"[](https://vimeo.com/3235882#t=)\n",
@@ -1670,8 +1551,7 @@
"https://i.vimeocdn.com/video/\\id_640x480.jpg": {
"application/octet-stream": "NDA0IE5vdCBGb3VuZA==\n"
}
- },
- "id": "c77420e4-3bbf-47d5-b488-4aba1d208e4b"
+ }
},
{
"cell_type": "markdown",
@@ -1679,8 +1559,8 @@
"source": [
"## Example: Continuous Character Control\n",
"\n",
- "\\[\\[edit\\]\n",
"\n",
"- Graph diffusion prior for enforcing connectivity between motions.\n",
@@ -1698,16 +1578,14 @@
" measures similarity.\n",
"\n",
"Levine et al. (2012)"
- ],
- "id": "e2ac5130-9af7-4904-8e5a-50690117a779"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"## Character Control: Results"
- ],
- "id": "3e30f8a4-1196-4193-8b3a-242e712a727e"
+ ]
},
{
"cell_type": "code",
@@ -1717,8 +1595,7 @@
"source": [
"from IPython.lib.display import YouTubeVideo\n",
"YouTubeVideo('hr3pdDl5IAg')"
- ],
- "id": "06d79387-91af-4539-8c5f-a3451ee8d73f"
+ ]
},
{
"cell_type": "markdown",
@@ -1726,8 +1603,7 @@
"source": [
"Figure: Character control in the latent space described the the\n",
"GP-LVM Levine et al. (2012)."
- ],
- "id": "ba8efc23-5278-4a07-a8a6-f6f3c84076f8"
+ ]
},
{
"cell_type": "markdown",
@@ -1761,8 +1637,7 @@
"Next we load in the data. We’ve provided a convenience function for\n",
"loading in the data with `pods`. It is loaded in as a `pandas`\n",
"DataFrame. This allows us to summarize it with the `describe` attribute."
- ],
- "id": "468ea0e2-de5f-4eb1-817d-e0ef324c14db"
+ ]
},
{
"cell_type": "code",
@@ -1771,8 +1646,7 @@
"outputs": [],
"source": [
"import pods"
- ],
- "id": "a336e659-b5e8-435d-b878-44d57e037d20"
+ ]
},
{
"cell_type": "code",
@@ -1783,8 +1657,7 @@
"data = pods.datasets.singlecell()\n",
"Y = data['Y']\n",
"Y.describe"
- ],
- "id": "705d0f9f-802b-4acd-8820-703f90d457b1"
+ ]
},
{
"cell_type": "markdown",
@@ -1793,7 +1666,7 @@
"## Principal Component Analysis\n",
"\n",
"Now we follow Guo et al. (2010) in performing PCA on the data. Rather\n",
- "than calling a ‘PCA routine’, here we break the algorithm down into its\n",
+ "than calling a ‘PCA routine,’ here we break the algorithm down into its\n",
"steps: compute the data covariance, compute the eigenvalues and\n",
"eigenvectors and sort according to magnitude of eigenvalue. Because we\n",
"want to visualize the data, we’ve chose to compute the eigenvectors of\n",
@@ -1802,8 +1675,7 @@
"efficient (in this case because the number of genes is smaller than the\n",
"number of data) than computing the eigendecomposition of the covariance\n",
"matrix."
- ],
- "id": "21dc5a38-ab22-4c68-864f-a8ad282de9d8"
+ ]
},
{
"cell_type": "code",
@@ -1812,8 +1684,7 @@
"outputs": [],
"source": [
"import numpy as np"
- ],
- "id": "c1fa9a64-3990-47ee-b6b5-852034690f3b"
+ ]
},
{
"cell_type": "code",
@@ -1831,8 +1702,7 @@
"ind = V.argsort()\n",
"ev = V[ind[::-1]]\n",
"U = U[:, ind[::-1]]"
- ],
- "id": "a5555ffb-dfff-4d49-851d-48afb3cfe7f1"
+ ]
},
{
"cell_type": "markdown",
@@ -1841,8 +1711,7 @@
"To visualize the result, we now construct a simple helper function. This\n",
"will ensure that the plots have the same legends as the GP-LVM plots we\n",
"use below."
- ],
- "id": "618885dc-5bd2-4876-8e67-cfb0aba8a657"
+ ]
},
{
"cell_type": "code",
@@ -1852,8 +1721,7 @@
"source": [
"import GPy\n",
"import matplotlib.pyplot as plt"
- ],
- "id": "d2d84326-47f5-4cd2-b3c7-c54824a5facf"
+ ]
},
{
"cell_type": "code",
@@ -1873,8 +1741,7 @@
" ind = labels == label\n",
" ax.plot(x[ind], y[ind], symbol)\n",
" ax.legend(ulabels)"
- ],
- "id": "044b48a9-bf57-4ac2-a662-d74fe4660024"
+ ]
},
{
"cell_type": "markdown",
@@ -1884,8 +1751,7 @@
"\n",
"Now, using the helper function we can plot the results with appropriate\n",
"labels."
- ],
- "id": "a356311a-1ddc-4ad9-92cf-591c71fec7b0"
+ ]
},
{
"cell_type": "code",
@@ -1896,8 +1762,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "8612dd75-bf85-43bb-b623-62416a78ccf1"
+ ]
},
{
"cell_type": "code",
@@ -1909,19 +1774,17 @@
"plot_labels(ax, U[:, 0], U[:, 1], data['labels'], '<>^vsd')\n",
"\n",
"mlai.write_figure('singlecell-data-pca.svg', directory='./datasets')"
- ],
- "id": "51e38441-3f50-4e58-b6ec-9ce770368e9c"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: First two principal compoents of the Guo et al. (2010)\n",
"blastocyst development data."
- ],
- "id": "cb180b8e-0d98-4e4b-9a31-45f69a70c4ef"
+ ]
},
{
"cell_type": "markdown",
@@ -1929,11 +1792,11 @@
"source": [
"## GP-LVM on the Data\n",
"\n",
- "\\[\\[edit\\]\n",
"\n",
- "\\maxZwiesselePicture{15%}\\oliverSteglePicture{15%}\n",
+ "\\\\maxZwiesselePicture{15%}\\\\oliverSteglePicture{15%}\n",
"\n",
"Work done as a collaboration between Max Zwiessele, Oliver Stegle and\n",
"Neil D. Lawrence.\n",
@@ -1947,8 +1810,7 @@
"They used modified prior to ensure that small differences between cells\n",
"at the same differential stage were preserved. Here we apply a standard\n",
"GP-LVM (no modified prior) to the data."
- ],
- "id": "389479e4-1d38-4397-ac72-7bf1c404da7b"
+ ]
},
{
"cell_type": "code",
@@ -1957,8 +1819,7 @@
"outputs": [],
"source": [
"import GPy"
- ],
- "id": "a5e284b1-5733-4de4-8b72-13fc4cc9081e"
+ ]
},
{
"cell_type": "code",
@@ -1969,8 +1830,7 @@
"kernel = GPy.kern.RBF(2)+GPy.kern.Bias(2)\n",
"model = GPy.models.GPLVM(Y.values, 2, kernel=kernel)\n",
"model.optimize(messages=True)"
- ],
- "id": "12cd7264-e40e-4a6d-b456-dcfed3d6a365"
+ ]
},
{
"cell_type": "code",
@@ -1981,8 +1841,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "24198294-4097-44a0-b29a-2fd03ed155c5"
+ ]
},
{
"cell_type": "code",
@@ -1994,19 +1853,17 @@
"model.plot_latent(ax=ax, labels=data['labels'], marker='<>^vsd')\n",
"\n",
"mlai.write_figure('singlecell-gplvm.svg', directory='./gplvm')"
- ],
- "id": "76027369-c51c-4509-818b-962e3372ee1a"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Visualisation of the Guo et al. (2010) blastocyst development\n",
"data with the GP-LVM."
- ],
- "id": "e6ac4dfe-dfb8-43f3-a393-41f99ddc9c95"
+ ]
},
{
"cell_type": "code",
@@ -2018,19 +1875,36 @@
"model.kern.plot_ARD(ax=ax)\n",
"\n",
"mlai.write_figure('singlecell-gplvm-ard.svg', directory='./gplvm')"
- ],
- "id": "2dfbebe7-e5d3-474b-a650-433b7a62c877"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: The ARD parameters of the GP-LVM for the Guo et al. (2010)\n",
"blastocyst development data."
- ],
- "id": "1ea16f3e-8b8a-4b92-9c7f-ce838d8e81d3"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "import pods"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "data = pods.datasets.singlecell()\n",
+ "Y = data['Y']"
+ ]
},
{
"cell_type": "markdown",
@@ -2038,8 +1912,8 @@
"source": [
"## Blastocyst Data: Isomap\n",
"\n",
- "\\[\\[edit\\]\n",
"\n",
"Isomap first builds a neighbourhood graph, and then uses distances along\n",
@@ -2050,8 +1924,7 @@
"data, principal component analysis is recovered (or strictly speaking,\n",
"principal coordinate analysis). The fewer the neighbors, the more\n",
"‘non-linear’ the isomap embeddings are."
- ],
- "id": "6889dc80-fc85-4e93-955a-038fe4826dbd"
+ ]
},
{
"cell_type": "code",
@@ -2060,8 +1933,7 @@
"outputs": [],
"source": [
"import sklearn.manifold"
- ],
- "id": "cfb48ad3-cebe-4f24-a96b-27edff5e6aa0"
+ ]
},
{
"cell_type": "code",
@@ -2072,8 +1944,7 @@
"n_neighbors = 10\n",
"model = sklearn.manifold.Isomap(n_neighbors=n_neighbors, n_components=2)\n",
"X = model.fit_transform(Y)"
- ],
- "id": "4db1d217-57d4-402a-ac47-779c68e048eb"
+ ]
},
{
"cell_type": "code",
@@ -2084,8 +1955,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "809f07f8-0737-47da-8c39-ecaf8abb1178"
+ ]
},
{
"cell_type": "code",
@@ -2098,19 +1968,36 @@
"\n",
"\n",
"mlai.write_figure('singlecell-isomap.svg', directory='./dimred')"
- ],
- "id": "ddefc6d7-bcac-4063-9c15-a415e6555891"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Visualisation of the Guo et al. (2010) blastocyst development\n",
"data with Isomap."
- ],
- "id": "98ae65bb-869f-4389-8ea9-611449e404d8"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "import pods"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "data = pods.datasets.singlecell()\n",
+ "Y = data['Y']"
+ ]
},
{
"cell_type": "markdown",
@@ -2118,8 +2005,8 @@
"source": [
"## Blastocyst Data: Locally Linear Embedding\n",
"\n",
- "\\[\\[edit\\]\n",
"\n",
"Next we try locally linear embedding. In locally linear embedding a\n",
@@ -2133,8 +2020,7 @@
"embedding is more linear and begins to look like PCA. However, the\n",
"algorithm does *not* converge to PCA in the limit as the number of\n",
"neighbors approaches $n$."
- ],
- "id": "679e1efb-6f16-4e3a-a0db-2d129e442e42"
+ ]
},
{
"cell_type": "code",
@@ -2143,8 +2029,7 @@
"outputs": [],
"source": [
"import sklearn.manifold"
- ],
- "id": "2292af01-45f5-4fb0-ae77-18b35d8cf859"
+ ]
},
{
"cell_type": "code",
@@ -2155,8 +2040,7 @@
"n_neighbors = 50\n",
"model = sklearn.manifold.LocallyLinearEmbedding(n_neighbors=n_neighbors, n_components=2)\n",
"X = model.fit_transform(Y)"
- ],
- "id": "6e45c76c-1913-4ea8-8060-0d9f4374165d"
+ ]
},
{
"cell_type": "code",
@@ -2167,8 +2051,7 @@
"import matplotlib.pyplot as plt\n",
"import mlai.plot as plot\n",
"import mlai"
- ],
- "id": "8dcc819c-fd3f-4df7-abc1-5d9e84ab1ca0"
+ ]
},
{
"cell_type": "code",
@@ -2180,19 +2063,17 @@
"plot_labels(ax, X[:, 0], X[:, 1], data['labels'], '<>^vsd')\n",
"\n",
"mlai.write_figure('singlecell-lle.svg', directory='./dimred')"
- ],
- "id": "5484a6ae-bf2f-48ab-9a7f-c2e8e0d0e034"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "\n",
+ "\n",
"\n",
"Figure: Visualisation of the Guo et al. (2010) blastocyst development\n",
"data with a locally linear embedding."
- ],
- "id": "9de37d2a-46bc-4b26-aa33-8f6d5162d396"
+ ]
},
{
"cell_type": "markdown",
@@ -2212,8 +2093,7 @@
" Page](http://www.theguardian.com/profile/neil-lawrence)\n",
"- blog:\n",
" [http://inverseprobability.com](http://inverseprobability.com/blog.html)"
- ],
- "id": "5ef2a144-c3b5-4cd2-89bc-1bca493f9701"
+ ]
},
{
"cell_type": "markdown",
@@ -2273,8 +2153,7 @@
"Tipping, M.E., Bishop, C.M., 1999a. Probabilistic principal component\n",
"analysis. Journal of the Royal Statistical Society, B 6, 611–622.\n",
""
- ],
- "id": "42dffa01-b2f0-4b4c-ab54-842a131614cd"
+ ]
}
],
"nbformat": 4,
diff --git a/slides/01-uncertainty-and-modelling.slides.html b/slides/01-uncertainty-and-modelling.slides.html
index ba5c5e7..409da8e 100644
--- a/slides/01-uncertainty-and-modelling.slides.html
+++ b/slides/01-uncertainty-and-modelling.slides.html
@@ -26,7 +26,7 @@
}
-
+
@@ -130,6 +130,8 @@
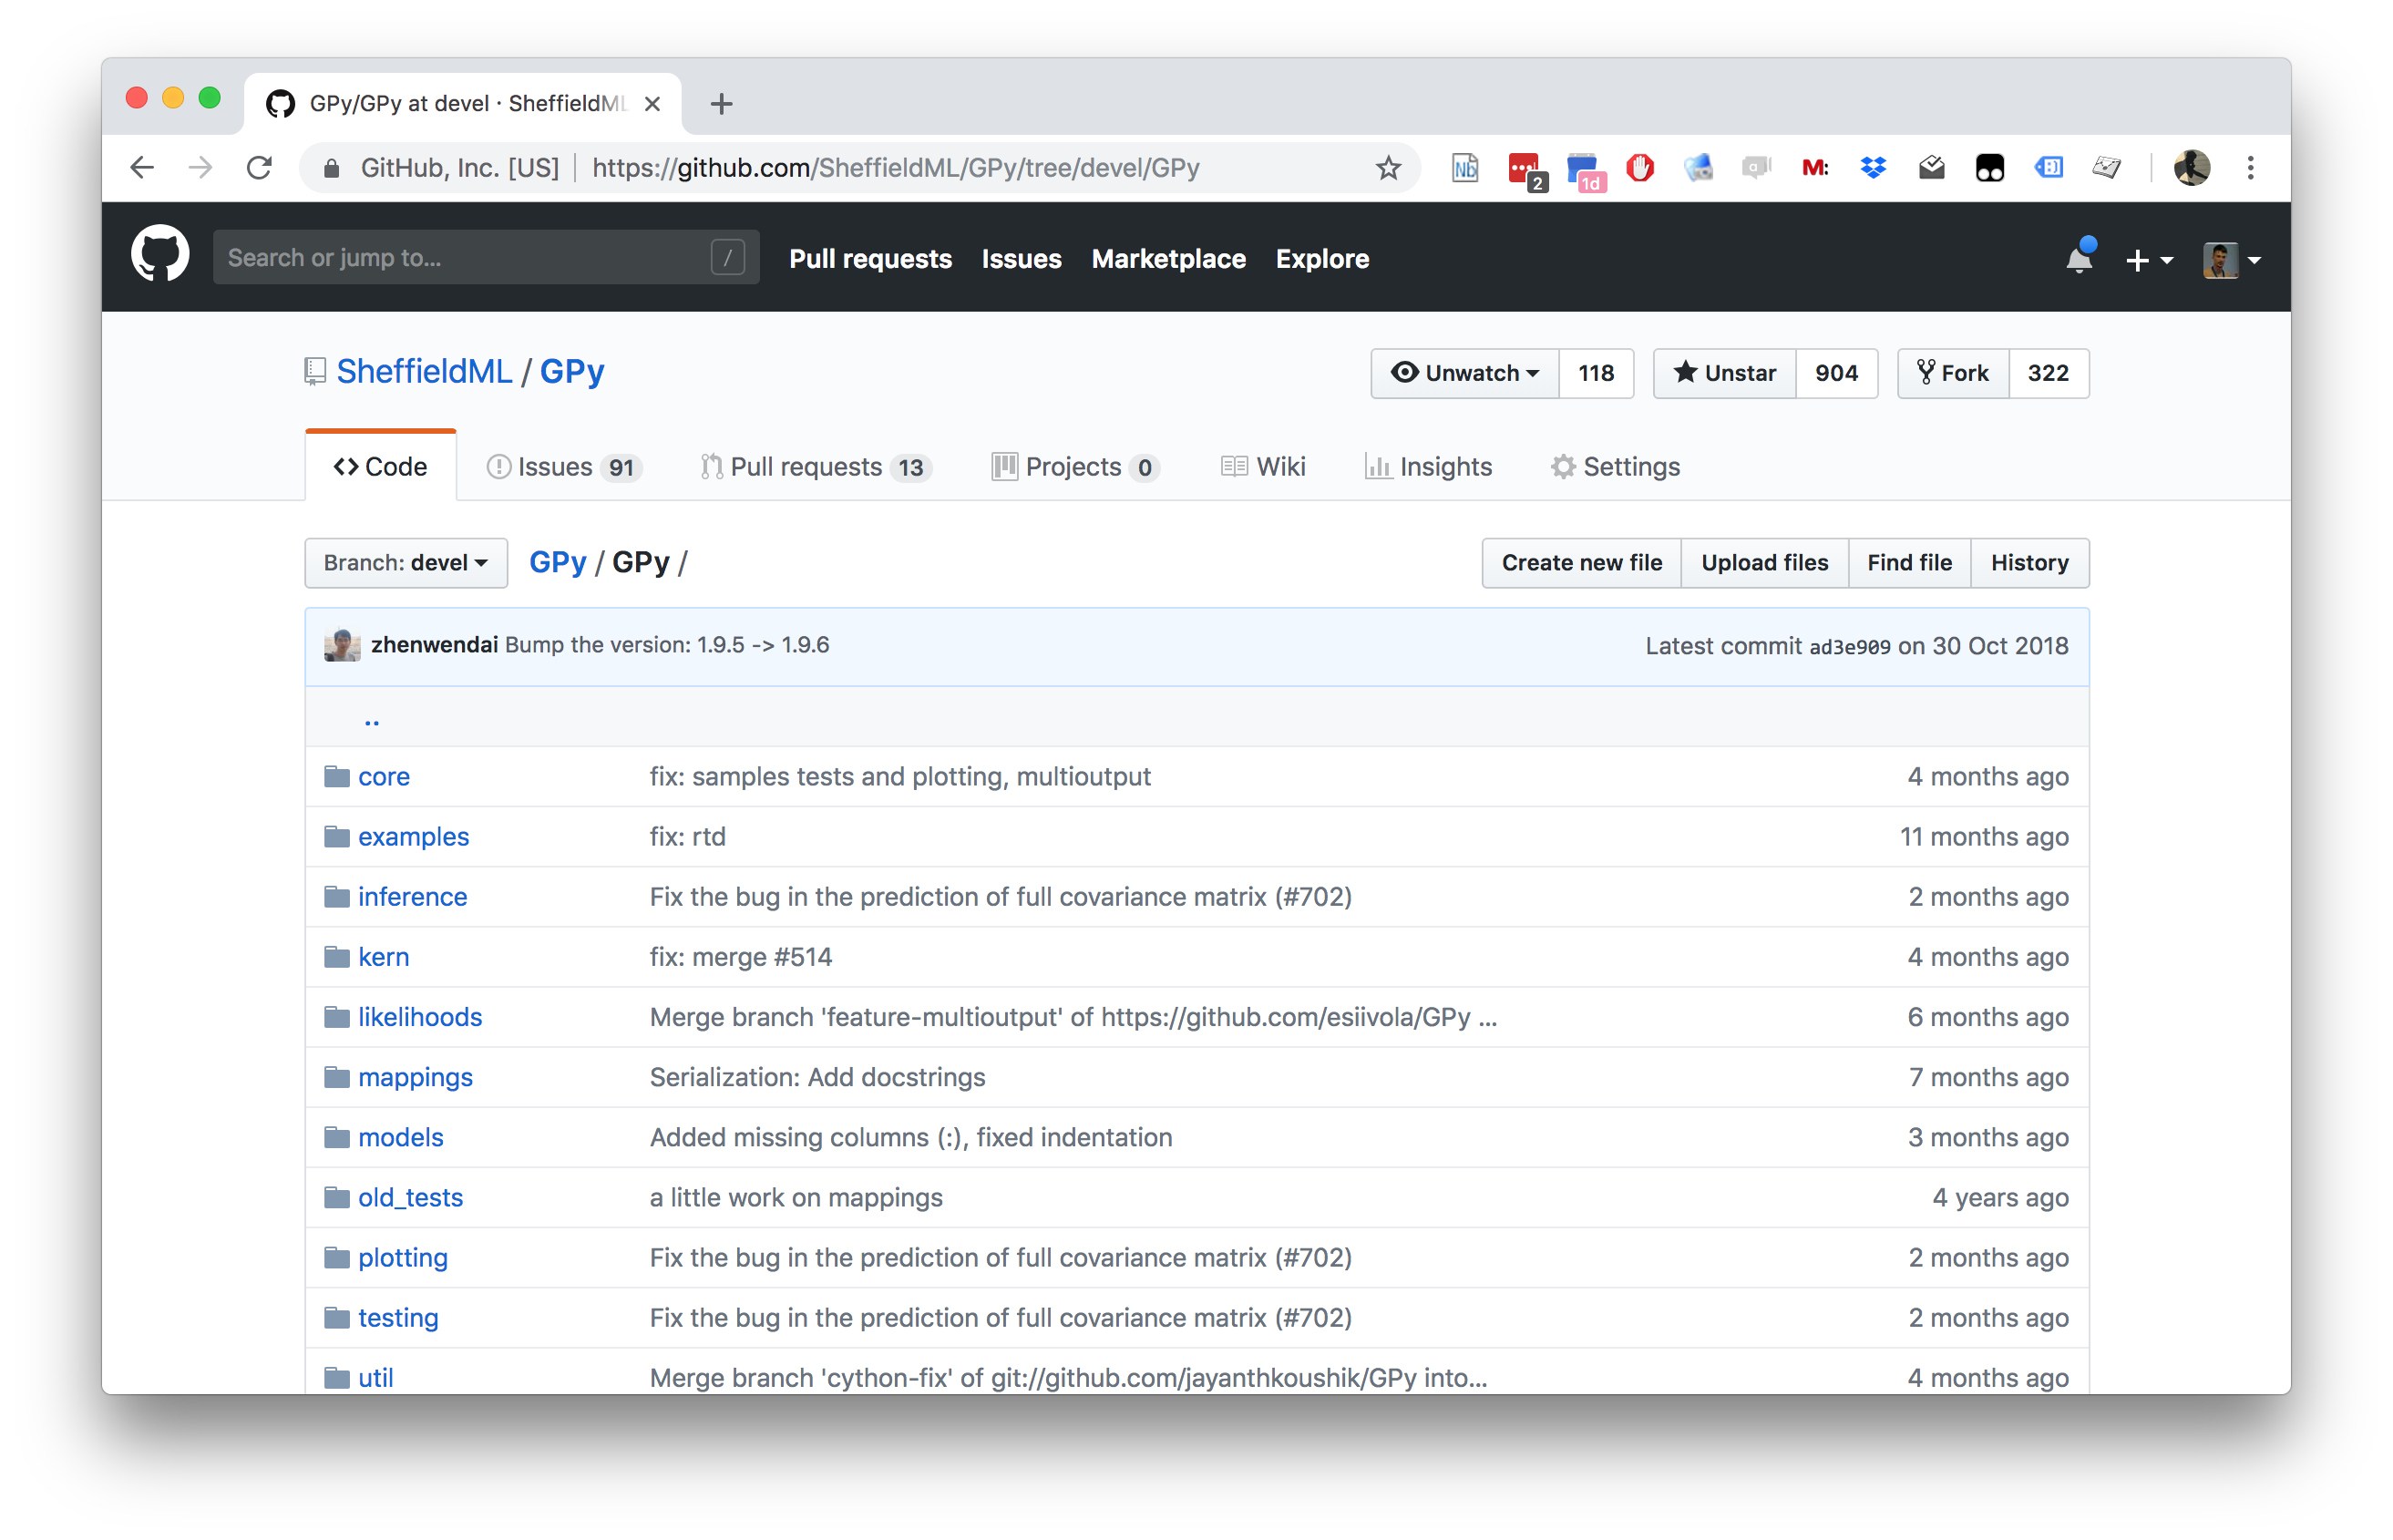


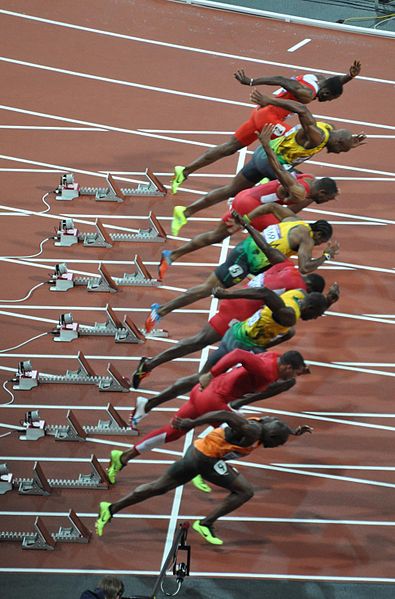

 \n",
+ "
 \n",
"\n",
"Figure: GPy is a BSD licensed software code base for implementing\n",
"Gaussian process models in Python. It is designed for teaching and\n",
@@ -307,7 +309,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Illustration of the Kronecker product."
]
@@ -325,7 +327,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Kronecker product between two matrices."
]
@@ -400,7 +402,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: The marginal distribution for the first three variables\n",
"(highlighted) is givne by $\\mathbf{K}$ when the form of stacking is\n",
@@ -473,7 +475,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: The marginal distribution for the first three variables\n",
"(highlighted) is independent when the form of stacking is\n",
@@ -486,7 +488,7 @@
"source": [
"## Mapping from Latent Process to Observed\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Mapping from latent process to observed"
]
@@ -527,7 +529,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: "
]
@@ -793,9 +795,9 @@
"\n",
"\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Intrinsic coregionalization model covariance function."
]
@@ -1033,7 +1035,7 @@
"- 100m, 200m, 400m\n",
"- In early years of olympics not all events run.\n",
"\n",
- "
 \n",
+ "
 \n",
"Image from Wikimedia Commons
 \n",
+ "
 \n",
"\n",
"Figure: Olympic sprint gold medal winning times from Rogers and\n",
"Girolami (2011).\n",
@@ -1199,6 +1201,27 @@
"for example the women’s 400 m only started in 1964."
]
},
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "import pods\n",
+ "import numpy as np"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "data = pods.datasets.olympic_sprints()\n",
+ "X = data['X']\n",
+ "y = data['Y']"
+ ]
+ },
{
"cell_type": "markdown",
"metadata": {},
@@ -1359,7 +1382,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process fit to the Olympic Sprint data.\n",
"\n",
@@ -1410,7 +1433,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process fit to the Olympic Sprint data.\n",
"\n",
@@ -1464,7 +1487,7 @@
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process fit to the Olympic Sprint data.\n",
"\n",
diff --git a/_notebooks/08-unsupervised-learning-with-gps.ipynb b/_notebooks/08-unsupervised-learning-with-gps.ipynb
index b7e07f7..f6d927c 100644
--- a/_notebooks/08-unsupervised-learning-with-gps.ipynb
+++ b/_notebooks/08-unsupervised-learning-with-gps.ipynb
@@ -5,14 +5,14 @@
"metadata": {},
"source": [
"# Unsupervised Learning with Gaussian Processes"
- ],
- "id": "7c1f8f7a-7300-49f2-98ed-7eb32a0cd1e4"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
- "source": [],
- "id": "027b2e68-9f59-4684-8cc1-b12d8f8e706a"
+ "source": [
+ "**Abstract**: null"
+ ]
},
{
"cell_type": "markdown",
@@ -20,14 +20,15 @@
"source": [
"$$\n",
"$$"
- ],
- "id": "3f4a9a6d-9656-425b-8615-e68da893bd07"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
"\n",
+ "\n",
+ "\n",
"\n",
"\n",
"\n",
@@ -39,8 +40,7 @@
""
- ],
- "id": "02543def-6f70-4604-931d-2315f793f1ad"
+ ]
},
{
"cell_type": "markdown",
@@ -48,14 +48,13 @@
"source": [
"## Gaussian Process Summer School notebook setup\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Graphical model representing probabilistic PCA."
- ],
- "id": "e6eebd55-d26d-4e0d-b824-81c02726074d"
+ ]
},
{
"cell_type": "markdown",
@@ -382,8 +362,7 @@
"$$ where $\\sigma^2$ is the noise variance. Note that if $\\sigma^2$ is\n",
"larger than any particular eigenvalue, then that eigenvalue (along with\n",
"its corresponding eigenvector) is *discarded* from the solution."
- ],
- "id": "a13d78df-e26c-4144-a815-5d3779ea4b41"
+ ]
},
{
"cell_type": "markdown",
@@ -404,8 +383,7 @@
"holds and the manifold is approximately linear. When the manifold is\n",
"nonlinear, we need more sophisticated methods like kernel PCA or neural\n",
"network-based approaches."
- ],
- "id": "8e482b2f-adaf-4664-b020-08253a9961f3"
+ ]
},
{
"cell_type": "markdown",
@@ -414,8 +392,7 @@
"## Python Implementation of Probabilistic PCA\n",
"\n",
"We will now implement this algorithm in python."
- ],
- "id": "ea8a2f6d-16af-4b67-b55a-5e353dffb0c0"
+ ]
},
{
"cell_type": "code",
@@ -424,8 +401,7 @@
"outputs": [],
"source": [
"import numpy as np"
- ],
- "id": "652514e6-327e-4821-8347-53c4b2f6d353"
+ ]
},
{
"cell_type": "code",
@@ -436,8 +412,7 @@
"from mlai import ppca_eig\n",
"import inspect\n",
"file_path = inspect.getfile(ppca_eig)"
- ],
- "id": "75aa1721-fb16-489d-bb5d-3dd56a39d370"
+ ]
},
{
"cell_type": "code",
@@ -446,8 +421,7 @@
"outputs": [],
"source": [
"%load -s ppca_eig {file_path}"
- ],
- "id": "8fbef982-cfa9-46fb-921c-c60709eb2964"
+ ]
},
{
"cell_type": "code",
@@ -456,8 +430,7 @@
"outputs": [],
"source": [
"ppca = ppca_eig"
- ],
- "id": "59983195-023c-4939-aace-0d0bcefd16f2"
+ ]
},
{
"cell_type": "markdown",
@@ -474,8 +447,7 @@
"We saw a similar issue arise when , where we also wished to avoid\n",
"computation of $\\mathbf{Z}^\\top\\mathbf{Z}$ (or in the case of\n",
"$\\boldsymbol{\\Phi}^\\top\\boldsymbol{\\Phi}$)."
- ],
- "id": "8f8ca1d0-2dd3-4086-9cc7-65ae97e569c8"
+ ]
},
{
"cell_type": "markdown",
@@ -506,8 +478,7 @@
":})^\\top(\\mathbf{ y}_{i, :} - \\mathbf{W}\\mathbf{ z}_{i, :}) - \\frac{1}{2}\n",
"\\mathbf{ z}_{i, :}^\\top \\mathbf{ z}_{i, :} + \\text{const}\n",
"$$"
- ],
- "id": "195eeba2-1709-4803-ac2d-93e68b0a21a0"
+ ]
},
{
"cell_type": "markdown",
@@ -526,8 +497,7 @@
"= \\mathbf{C}_x \\sigma^{-2}\\mathbf{W}^\\top \\mathbf{ y}_{i, :} \n",
"$$ Compare this to the posterior for the Bayesian linear regression from\n",
"last week, do they have similar forms? What matches and what differs?"
- ],
- "id": "5f8d8c63-37a4-417c-b913-615300cb930f"
+ ]
},
{
"cell_type": "markdown",
@@ -536,8 +506,7 @@
"### Exercise 1 Answer\n",
"\n",
"Write your answer to Exercise 1 here"
- ],
- "id": "bc12348c-aaec-4bf5-889f-0277f0ff0c91"
+ ]
},
{
"cell_type": "markdown",
@@ -546,8 +515,7 @@
"## Python Implementation of the Posterior\n",
"\n",
"Now let’s implement the system in code."
- ],
- "id": "bfadfd3e-0ece-4f64-a1e5-aa16a4aa715e"
+ ]
},
{
"cell_type": "markdown",
@@ -569,8 +537,7 @@
"Don’t forget to subtract the mean of the data `Y` inside your function\n",
"before computing the posterior: remember we assumed at the beginning of\n",
"our analysis that the data had been centred (i.e. the mean was removed)."
- ],
- "id": "4d43055a-e349-4ce9-9f86-ee7d47f7c1ee"
+ ]
},
{
"cell_type": "code",
@@ -594,8 +561,7 @@
" mu_x = \n",
" return mu_x, C_x\n",
"\n"
- ],
- "id": "17304bf6-a206-4df0-859c-314577ff418d"
+ ]
},
{
"cell_type": "markdown",
@@ -623,8 +589,7 @@
"The eigenvalues of the matrix $\\mathbf{Y}^\\top\\mathbf{Y}$ are then given\n",
"by the singular values of the matrix $\\mathbf{Y}^\\top$ squared and the\n",
"eigenvectors are given by $\\mathbf{U}$."
- ],
- "id": "f4a4f91d-a9f7-4083-9908-8069b9060ff6"
+ ]
},
{
"cell_type": "markdown",
@@ -654,8 +619,7 @@
"\\boldsymbol{ \\mu}_x = \\mathbf{D}\\mathbf{U}^\\top \\mathbf{ y}_{i, :}\n",
"$$ where $\\mathbf{D}$ is a diagonal matrix with diagonal elements given\n",
"by $d_{i} = \\frac{\\ell_i}{\\sigma^2 + \\ell_i^2}$."
- ],
- "id": "000e5490-67df-42da-98ce-2b9f7aad1a79"
+ ]
},
{
"cell_type": "code",
@@ -665,8 +629,7 @@
"source": [
"import scipy as sp\n",
"import numpy as np"
- ],
- "id": "840b0eed-95de-4c27-831b-723cd5af9044"
+ ]
},
{
"cell_type": "code",
@@ -677,8 +640,7 @@
"from mlai import ppca_svd\n",
"import inspect\n",
"file_path = inspect.getfile(ppca_svd)"
- ],
- "id": "d69da568-44da-43a4-a4cb-cf99f60f3974"
+ ]
},
{
"cell_type": "code",
@@ -687,8 +649,7 @@
"outputs": [],
"source": [
"%load -s ppca_svd {file_path}"
- ],
- "id": "5db6386b-c902-4ec0-aae3-be58307c421d"
+ ]
},
{
"cell_type": "code",
@@ -699,8 +660,7 @@
"from mlai import ppca_posterior\n",
"import inspect\n",
"file_path = inspect.getfile(ppca_posterior)"
- ],
- "id": "8cbbae05-e0f3-42c2-a2ba-8790c03ac70b"
+ ]
},
{
"cell_type": "code",
@@ -709,8 +669,7 @@
"outputs": [],
"source": [
"%load -s ppca_posterior {file_path}"
- ],
- "id": "580efecd-0993-45df-a611-02d9895dc1bb"
+ ]
},
{
"cell_type": "code",
@@ -720,8 +679,7 @@
"source": [
"ppca = ppca_svd\n",
"posterior = ppca_posterior"
- ],
- "id": "30041ccb-8d60-417f-aef3-7dda260157b4"
+ ]
},
{
"cell_type": "markdown",
@@ -729,15 +687,14 @@
"source": [
"## Scikit-learn implementation PCA\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Visualization of the first two dimensions of the oil flow\n",
"data from Bishop and James (1993)\n",
"\n",
"As normal we include the citation information for the data."
- ],
- "id": "1ad9ed34-981a-43bf-89c0-65ea8e8674aa"
+ ]
},
{
"cell_type": "code",
@@ -871,8 +819,7 @@
"outputs": [],
"source": [
"print(data['citation'])"
- ],
- "id": "4777438a-6475-4769-8949-9d2aeb049b28"
+ ]
},
{
"cell_type": "markdown",
@@ -880,8 +827,7 @@
"source": [
"And extra information about the data is included, as standard, under the\n",
"keys `info` and `details`."
- ],
- "id": "0288351f-b3ad-4435-811a-5ba8e12a031f"
+ ]
},
{
"cell_type": "code",
@@ -890,8 +836,7 @@
"outputs": [],
"source": [
"print(data['details'])"
- ],
- "id": "59e3ff16-fcc9-49ab-80fb-f641071b3ff3"
+ ]
},
{
"cell_type": "code",
@@ -901,8 +846,7 @@
"source": [
"X = data['X']\n",
"Y = data['Y']"
- ],
- "id": "08b88d2c-7530-47a4-bf9b-1dd47210262c"
+ ]
},
{
"cell_type": "code",
@@ -911,8 +855,7 @@
"outputs": [],
"source": [
"cmd = install_command('scikit-learn')"
- ],
- "id": "caf1ee2e-32cc-4378-8d7d-16e45b2ea999"
+ ]
},
{
"cell_type": "code",
@@ -921,8 +864,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "cdaaaa57-59d7-41a0-9c76-6056c405d6c5"
+ ]
},
{
"cell_type": "code",
@@ -931,8 +873,7 @@
"outputs": [],
"source": [
"from sklearn.decomposition import PCA"
- ],
- "id": "d1862fc2-5b5e-4284-ad8a-13bcbfc315d8"
+ ]
},
{
"cell_type": "code",
@@ -943,8 +884,7 @@
"pca = PCA(n_components=2)\n",
"pca.fit(X)\n",
"X_pca = pca.transform(X)"
- ],
- "id": "aec31e5d-8ad2-454b-b7ec-c621855ea124"
+ ]
},
{
"cell_type": "code",
@@ -960,8 +900,7 @@
"class2 = (Y[:, 2] == 1).astype(int) * 2\n",
"# Combine into single array of class labels 0,1,2\n",
"lbls = class0 + class1 + class2"
- ],
- "id": "6357254c-4136-4092-9791-dacf85098578"
+ ]
},
{
"cell_type": "code",
@@ -972,8 +911,7 @@
"from matplotlib import pyplot as plt\n",
"import mlai\n",
"from mlai import plot"
- ],
- "id": "4f521da7-fea9-4e3f-abe2-fe82ed66e114"
+ ]
},
{
"cell_type": "code",
@@ -990,19 +928,17 @@
"ax.set_ylabel('Second principal component')\n",
"\n",
"mlai.write_figure(\"oil-flow-pca-sklearn.svg\", directory='./dimred')"
- ],
- "id": "775554b4-2ab9-44b9-86e7-75d9e5b6207e"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: PCA of the oil flow data. The flow is homogeneous, annular\n",
"and stratified."
- ],
- "id": "fd86083f-df45-458f-a49e-0a6bc2886e8e"
+ ]
},
{
"cell_type": "markdown",
@@ -1010,11 +946,10 @@
"source": [
"## Difficulty for Probabilistic Approaches\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: A two dimensional grid mapped into three dimensions to form a\n",
"two dimensional manifold."
- ],
- "id": "02412e76-d084-442d-a607-27532300ddf9"
+ ]
},
{
"cell_type": "code",
@@ -1059,20 +991,18 @@
"outputs": [],
"source": [
"plot.non_linear_difficulty_plot_2(diagrams='./dimred/')"
- ],
- "id": "628609ec-dddd-4efd-9831-13380989b411"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: A one dimensional line mapped into two dimensions by two\n",
"separate independent functions. Each point can be mapped exactly through\n",
"the mappings."
- ],
- "id": "d218c0a5-2224-4404-a525-981e2a661940"
+ ]
},
{
"cell_type": "code",
@@ -1081,8 +1011,7 @@
"outputs": [],
"source": [
"cmd = install_command('daft')"
- ],
- "id": "86220e84-0781-462e-90f9-848fade58041"
+ ]
},
{
"cell_type": "code",
@@ -1091,8 +1020,7 @@
"outputs": [],
"source": [
"%system {cmd}"
- ],
- "id": "03e7affe-99f5-486d-a89a-514e4d3c5234"
+ ]
},
{
"cell_type": "code",
@@ -1101,19 +1029,17 @@
"outputs": [],
"source": [
"plot.non_linear_difficulty_plot_1(diagrams='./dimred')"
- ],
- "id": "b3123f47-a132-4f2f-b087-4f13fd5f67b5"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: A Gaussian density over the input of a non linear function\n",
"leads to a very non Gaussian output. Here the output is multimodal."
- ],
- "id": "242b5f60-4bbe-457c-b735-41aa2878356b"
+ ]
},
{
"cell_type": "markdown",
@@ -1121,11 +1047,10 @@
"source": [
"## Getting Started and Downloading Data\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Gaussian process latent variable model visualisation of CMU\n",
"motion capture data set."
- ],
- "id": "02eef5d8-f42b-4f6e-8ab8-a3899d63d748"
+ ]
},
{
"cell_type": "markdown",
@@ -1648,8 +1529,8 @@
"source": [
"## Example: Latent Doodle Space\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: First two principal compoents of the Guo et al. (2010)\n",
"blastocyst development data."
- ],
- "id": "cb180b8e-0d98-4e4b-9a31-45f69a70c4ef"
+ ]
},
{
"cell_type": "markdown",
@@ -1929,11 +1792,11 @@
"source": [
"## GP-LVM on the Data\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Visualisation of the Guo et al. (2010) blastocyst development\n",
"data with the GP-LVM."
- ],
- "id": "e6ac4dfe-dfb8-43f3-a393-41f99ddc9c95"
+ ]
},
{
"cell_type": "code",
@@ -2018,19 +1875,36 @@
"model.kern.plot_ARD(ax=ax)\n",
"\n",
"mlai.write_figure('singlecell-gplvm-ard.svg', directory='./gplvm')"
- ],
- "id": "2dfbebe7-e5d3-474b-a650-433b7a62c877"
+ ]
},
{
"cell_type": "markdown",
"metadata": {},
"source": [
- "
 \n",
+ "
 \n",
"\n",
"Figure: The ARD parameters of the GP-LVM for the Guo et al. (2010)\n",
"blastocyst development data."
- ],
- "id": "1ea16f3e-8b8a-4b92-9c7f-ce838d8e81d3"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "import pods"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "data = pods.datasets.singlecell()\n",
+ "Y = data['Y']"
+ ]
},
{
"cell_type": "markdown",
@@ -2038,8 +1912,8 @@
"source": [
"## Blastocyst Data: Isomap\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Visualisation of the Guo et al. (2010) blastocyst development\n",
"data with Isomap."
- ],
- "id": "98ae65bb-869f-4389-8ea9-611449e404d8"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "import pods"
+ ]
+ },
+ {
+ "cell_type": "code",
+ "execution_count": null,
+ "metadata": {},
+ "outputs": [],
+ "source": [
+ "data = pods.datasets.singlecell()\n",
+ "Y = data['Y']"
+ ]
},
{
"cell_type": "markdown",
@@ -2118,8 +2005,8 @@
"source": [
"## Blastocyst Data: Locally Linear Embedding\n",
"\n",
- "
 \n",
+ "
 \n",
"\n",
"Figure: Visualisation of the Guo et al. (2010) blastocyst development\n",
"data with a locally linear embedding."
- ],
- "id": "9de37d2a-46bc-4b26-aa33-8f6d5162d396"
+ ]
},
{
"cell_type": "markdown",
@@ -2212,8 +2093,7 @@
" Page](http://www.theguardian.com/profile/neil-lawrence)\n",
"- blog:\n",
" [http://inverseprobability.com](http://inverseprobability.com/blog.html)"
- ],
- "id": "5ef2a144-c3b5-4cd2-89bc-1bca493f9701"
+ ]
},
{
"cell_type": "markdown",
@@ -2273,8 +2153,7 @@
"Tipping, M.E., Bishop, C.M., 1999a. Probabilistic principal component\n",
"analysis. Journal of the Royal Statistical Society, B 6, 611–622.\n",
"

 +

 +
